
⚡ EMA Lightning
Tiny, fast and accurate Turkish text to speech. 8.6M parameters, about 34 MB, Apache-2.0. It runs on your own GPU or CPU, offline: no text or audio leaves the machine.
- The most accurate on Freya-TR-Eval: 0.92% word error rate, the lowest of every system measured, including ElevenLabs v4, Gemini 3.8 and the 2.38B-parameter Trendyol-TTS.
- Fast: the first audio is ready in about 4 ms. One request runs 440× faster than real time, and batched work 1,316× (RTX 4090).
- Cheap: about $0.0085 per million characters on a rented RTX 4090.
- Takes Turkish as people write it: numbers, dates, times, money, units, abbreviations and symbols are read aloud.
- Streams: audio starts while the rest of the text is still being made.
- One model serves many callers: call it from as many threads as you like. Its built-in scheduler, Playhead, runs everyone's work together on the GPU. No server or queue system to run.
| System | Size | Word error rate | Speed, RTX 4090 |
|---|---|---|---|
| EMA Lightning | 8.6M | 0.92% | 440× real time |
| Trendyol-TTS | 2.38B | 0.98% | 2.8× |
| Gemini 3.8 Flash-Lite | cloud | 1.31% | — |
| ElevenLabs v4 | cloud | 1.43% | — |
| Anka TTS † | 336M | 1.73% | 6.3× |
| XTTS-v2 † | 470M | 3.34% | 7.1× |
| FreyaTTS † | 183M | 12.02% | 8.4× |
Freya-TR-Eval, all 495 sentences, speed 1.0. † Reported on the Anka TTS model card. The full table and how it was measured are on the model card.
Install
python -m pip install ema-lightning
CPython 3.11 to 3.13 with PyTorch 2.1 or newer. The weights (about 34 MB) download from Hugging Face on first use.
Use
Make one EMA and keep it for the whole program. There are two ways to get
speech out of it:
say() |
stream() |
|
|---|---|---|
| Gives you | the whole audio, once it's ready | the audio piece by piece, as it's made |
| Takes | one text, or a list of texts | one text per call |
| Use it for | files, voiceovers, batch jobs | playing as you go: speakers, phone calls, live apps |
say(): a whole text, back when it's ready
from ema_lightning import EMA

tts = EMA()                                     # loads the model, on the GPU if there is one
speech = tts.say("Merhaba, size nasıl yardımcı olabilirim?", path="merhaba.wav")
print(speech.duration, speech.sample_rate)      # seconds of audio, 48000
say() returns a Speech: the audio (a float32 NumPy array, mono, between -1
and 1), its sample_rate, its duration in seconds, and the seed that made it.
With path, it also writes a WAV file. Pass the same seed again to get the same
audio.
Give it a list and every text is made in shared batches, one Speech per text, in
order. With path, the list is written into that folder as 0.wav, 1.wav, …:
speeches = tts.say(["Günaydın.", "Siparişiniz yola çıktı.", "İyi günler dileriz."], path="clips")
stream(): hear it while it's being made
import sounddevice as sd                        # python -m pip install sounddevice

with sd.OutputStream(samplerate=48000, channels=1, dtype="float32") as speaker:
    for chunk in tts.stream("Merhaba! Bu ses siz dinlerken üretiliyor. İlk kelimeyi duyduğunuzda, "
                            "cümlenin geri kalanı çoktan hazır."):
        speaker.write(chunk)
The first chunk is one second of audio and is ready in about 4 ms on a GPU. The
rest follows four seconds at a time, far faster than it plays, so playback never
waits. Each chunk is a float32 NumPy array, so it can go to a speaker, a phone
line or a WebSocket. Leave the loop early and the rest of that text's work is
dropped. Joined together, the chunks are the same audio say() gives.
Streaming many texts at once
stream() takes one text per call, so each stream's chunks belong to one text and
nothing gets mixed up. To stream many texts at the same time, call stream() once
per text, each from its own thread. All the calls share the same model, and
Playhead runs them together on the GPU:
from concurrent.futures import ThreadPoolExecutor

texts = ["Merhaba, size nasıl yardımcı olabilirim?", "Siparişiniz yola çıktı.", "Randevunuz onaylandı, görüşmek üzere."]


def stream_one(text):
    chunks = []
    for chunk in tts.stream(text):
        chunks.append(chunk)                    # in a real app: send it to this caller right away
    return chunks


with ThreadPoolExecutor(max_workers=len(texts)) as pool:
    results = list(pool.map(stream_one, texts))  # one list of chunks per text, in the same order
In a server it's the same idea: one EMA for the whole server, and one stream()
call per connection. With FastAPI, for example:
from fastapi import FastAPI, WebSocket
from starlette.concurrency import iterate_in_threadpool

from ema_lightning import EMA

app = FastAPI()
tts = EMA().lightning()                         # one model for every connection


@app.websocket("/speak")
async def speak(ws: WebSocket):
    await ws.accept()
    text = await ws.receive_text()
    async for chunk in iterate_in_threadpool(tts.stream(text)):
        await ws.send_bytes(chunk.tobytes())    # float32 PCM, 48 kHz, mono
    await ws.close()
If you don't need the audio while it's being made, say() with a list is simpler:
it returns every text's audio at once, in order.
.lightning(): the fast path on NVIDIA GPUs
tts = EMA().lightning()
Call it once at startup. It measures the best batch size for your GPU (once, then cached), compiles the model, records CUDA graphs, checks them against the plain path and prints when it's ready, with its first-audio time. It takes seconds, and everything after is faster. Without it, or on a CPU, everything works the same, just slower.
Options
say() and stream() take the same options; path is for say() only.
| Option | Values | Default |
|---|---|---|
speed |
0.25 to 4 | 1.0 |
seed |
a non-negative integer; the same seed gives the same audio | random, returned in speech.seed |
sample_rate |
48000, 24000, 16000, 8000 | 48000 |
path |
a .wav file for one text, a folder for a list |
none |
Any text is accepted, and text never raises. Invalid settings raise ValueError
before any work starts.
Playhead: how one model serves many callers
Every say() and stream() call goes through Playhead, a scheduler inside EMA.
You never call it yourself. It is what lets one model serve many callers at once.
Why it exists. A GPU making one sentence at a time is mostly idle: it can make many sentences in about the time it takes to make one. So instead of running each call on its own, Playhead collects what every caller needs at that moment and runs it together. Think of one kitchen cooking for every table: orders are taken in the order they arrive, and each round the cooks make as many dishes as fit on the stove, for whichever tables are next.
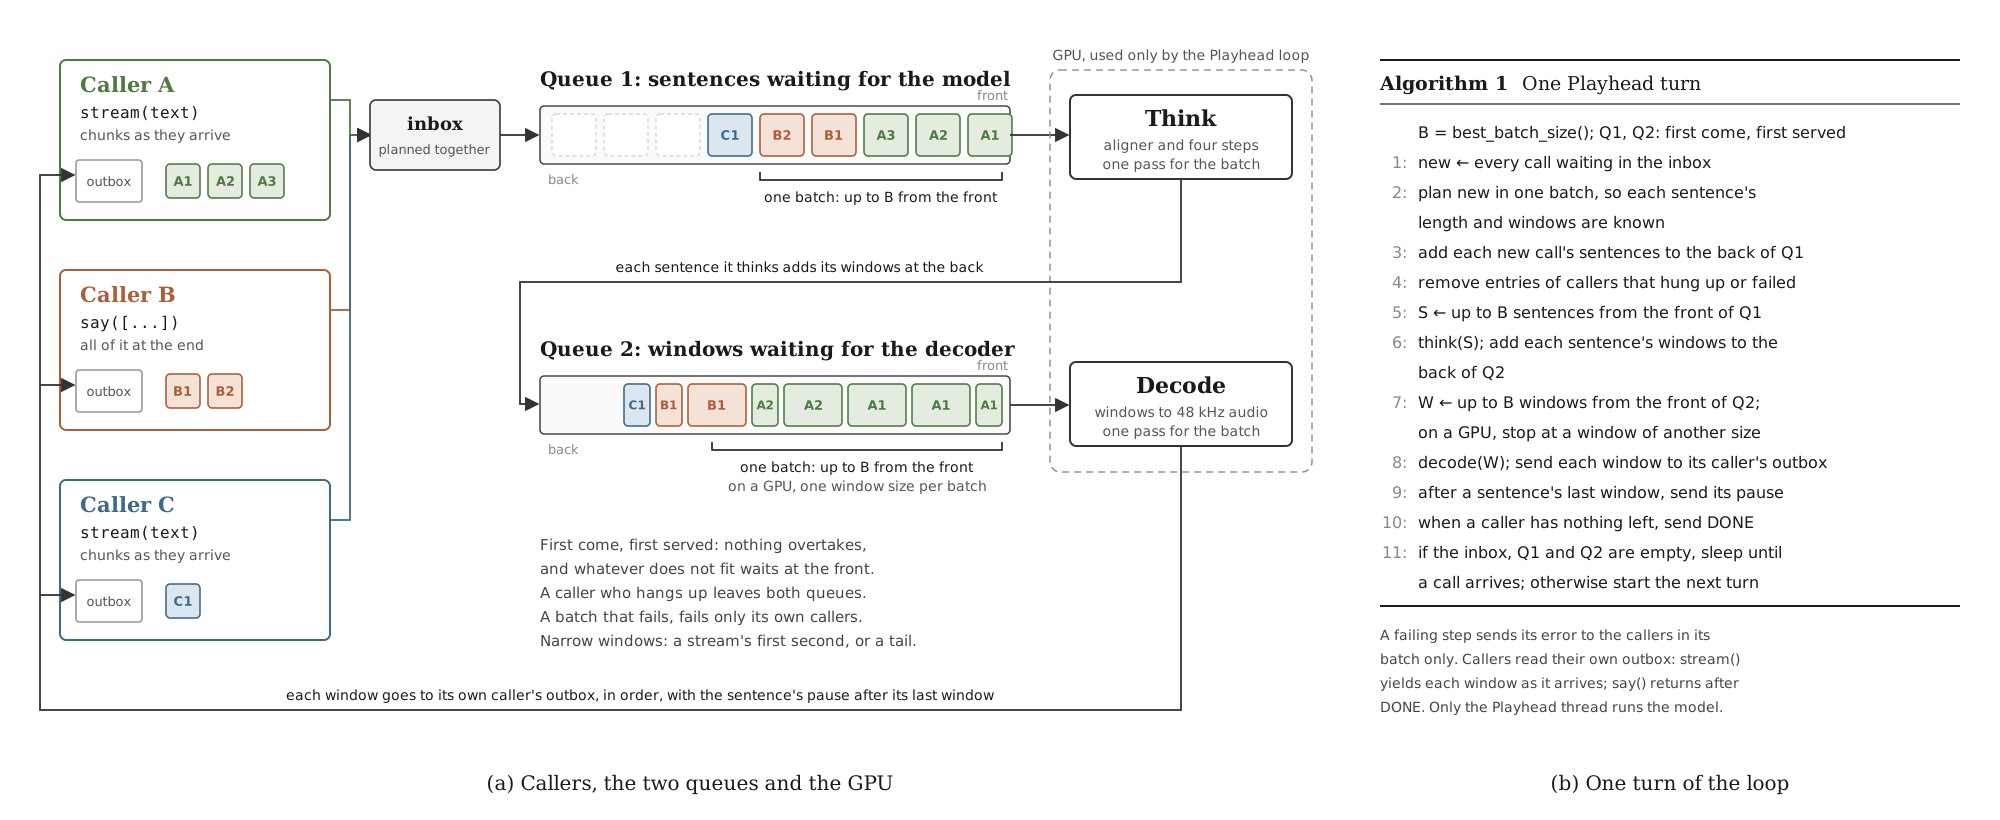
How it works. Your text is cut into sentences, and Playhead keeps two queues, both strictly first come, first served:
- Queue 1, before the model. Your sentences join the back of it, behind everything that arrived before them.
- Each turn, Playhead takes up to one batch of sentences from the front of
queue 1, from any callers, and makes their sound in one pass on the GPU. The
batch size is measured for your GPU by
best_batch_size(), for example 16. - The finished sound waits in queue 2, before the decoder, cut into windows of about four seconds.
- In the same turn, Playhead takes up to one batch of windows from the front of queue 2 and turns them into audio in one pass.
- Each window goes straight back to the call that asked for it, in order.
stream()hands it to you right away;say()returns when the last one is in.
Turns repeat every few milliseconds while there is work. New callers join the queues while the GPU is busy, Playhead never waits for a batch to fill up, and it sleeps when there is nothing to do.
What it means for you.
- Your code stays simple: one
EMA, and as many threads as you have callers. - Fair: nobody's sentences are overtaken, and each caller's audio arrives in order.
- A stream that stops early (a caller hangs up) leaves the queues, and its work is dropped.
- If a batch fails, for example the GPU runs out of memory, only the callers in that batch get the error. Everyone else keeps going.
- A long text queues all of its sentences, so callers behind it wait for them. Cut very long inputs before sending them if that matters to you.
On one RTX PRO 6000, 64 streams started at the same instant made 887 seconds of audio in 0.74 seconds, and every one matched its text said alone. The details are in many callers.
Turkish text, as written
Text goes in as people write it. normalizer-tr,
with its fallback policy, reads numbers, dates, times, amounts, units,
abbreviations and symbols aloud, and spells out anything it cannot resolve instead
of skipping it. Long text is cut at sentence and clause boundaries, with natural
pauses between the pieces.
| Written | Spoken |
|---|---|
5 kişi geldi. |
beş kişi geldi. |
%15 indirim |
yüzde on beş indirim |
12,5 kg un |
on iki virgül beş kilogram un |
Dr. Ayşe geldi. |
doktor ayşe geldi. |
Kod: 00042 |
kod: sıfır sıfır sıfır dört iki |
Words written in all capitals are spelled letter by letter. The text guide has the full pipeline and its known limits.
Speed
| RTX 4090 | Plain PyTorch | .lightning() |
|---|---|---|
| One request | 87× real time | 440× real time |
| Batch of 64 | 952× real time | 1,316× real time |
| First audio, typical sentence | 3.86 ms |
On a CPU it runs about 6× faster than real time. The details, the RTX PRO 6000 numbers and how to measure on your own machine are in PERFORMANCE.md.
Limitations
- One voice. No voice cloning and no emotion control.
- Turkish only. Foreign words are read with Turkish spelling rules.
- Naturalness is good, not the best. UTMOS is about 3.30 on Freya-TR-Eval: level with ElevenLabs v4, below Gemini 3.8 and Trendyol-TTS.
- Word error rate is measured with Whisper, so some of the counted errors are the recognizer's.
Documentation
| Guide | Contents |
|---|---|
| API reference | Every class, method, option and error |
| Text | Normalization, the alphabet, splitting and pauses |
| Many callers | Playhead's two queues, windows and batches |
| Performance | Accuracy and speed, with how they were measured |
| Contributing | Setup, code layout, tests and checks |
| Changelog | Changes by release |
Acknowledgements
Special thanks to Erdem Tuna, who built normalizer-tr, the Turkish text normalizer behind EMA Lightning. Every number, date, amount and symbol you hear read aloud goes through his work.
Thanks also to Freya for the Freya-TR-Eval benchmark, and to the Anka TTS authors for the published baselines marked †.
License
Apache-2.0, for the code and the weights. Commercial use included. normalizer-tr is also Apache-2.0.
Citation
@misc{aslan2026emalightning,
  title        = {EMA Lightning: Tiny, Fast and Accurate Turkish Text to Speech},
  author       = {Aslan, Canberk},
  year         = {2026},
  howpublished = {\url{https://huggingface.co/canberkkkkkk/ema-lightning}}
}
1 maintainer

Metadata
1 maintainer
Release files for ema-lightning 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ema_lightning-1.0.0.tar.gz | 44.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ema_lightning-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 75.2 kB
Release files / ema_lightning-1.0.0.tar.gz
| Download URL | ema_lightning-1.0.0.tar.gz |
|---|---|
| Size | 44.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5be09f3aea716e1098fc54fc6e4a7841f5ae80f06c6d676721cd61d3a18793b1
|
|
BLAKE2b-256 checksum How to use checksums |
50d36d2c2376e283ed54d7f8c8165f037c14633ddcf7c76dfc96b05ecead1382
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency logRelease files / ema_lightning-1.0.0-py3-none-any.whl
| Download URL | ema_lightning-1.0.0-py3-none-any.whl |
|---|---|
| Size | 30.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cd0931a71bb4a06450de267abc92780f6a2e90e623b156cbbc4239e4fcf40e5b
|
|
BLAKE2b-256 checksum How to use checksums |
72195585121735a3250b7d2e3f14701f412c2c5297178137e5bcb51dfa04b223
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency log













