
Engram
Give your model a memory, local or cloud. One process, one SQLite file, zero code changes.



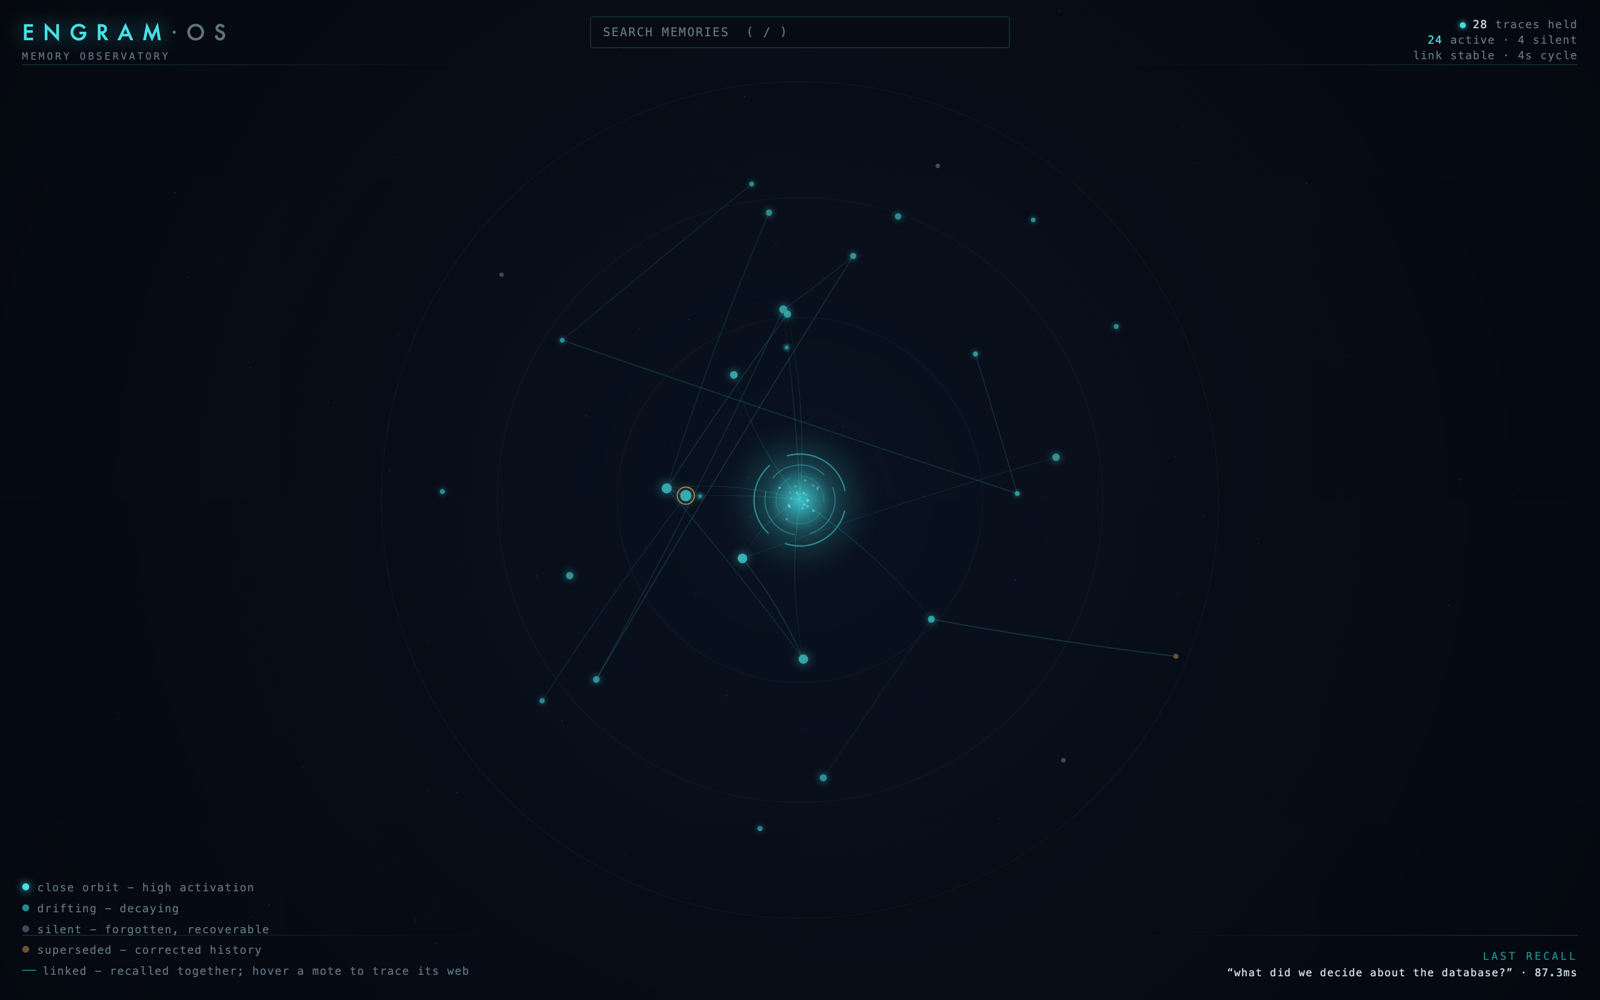
/engram/ui: memories orbit by activation, reinforced ones fall inward, decaying ones drift out.
 |
 |
|---|
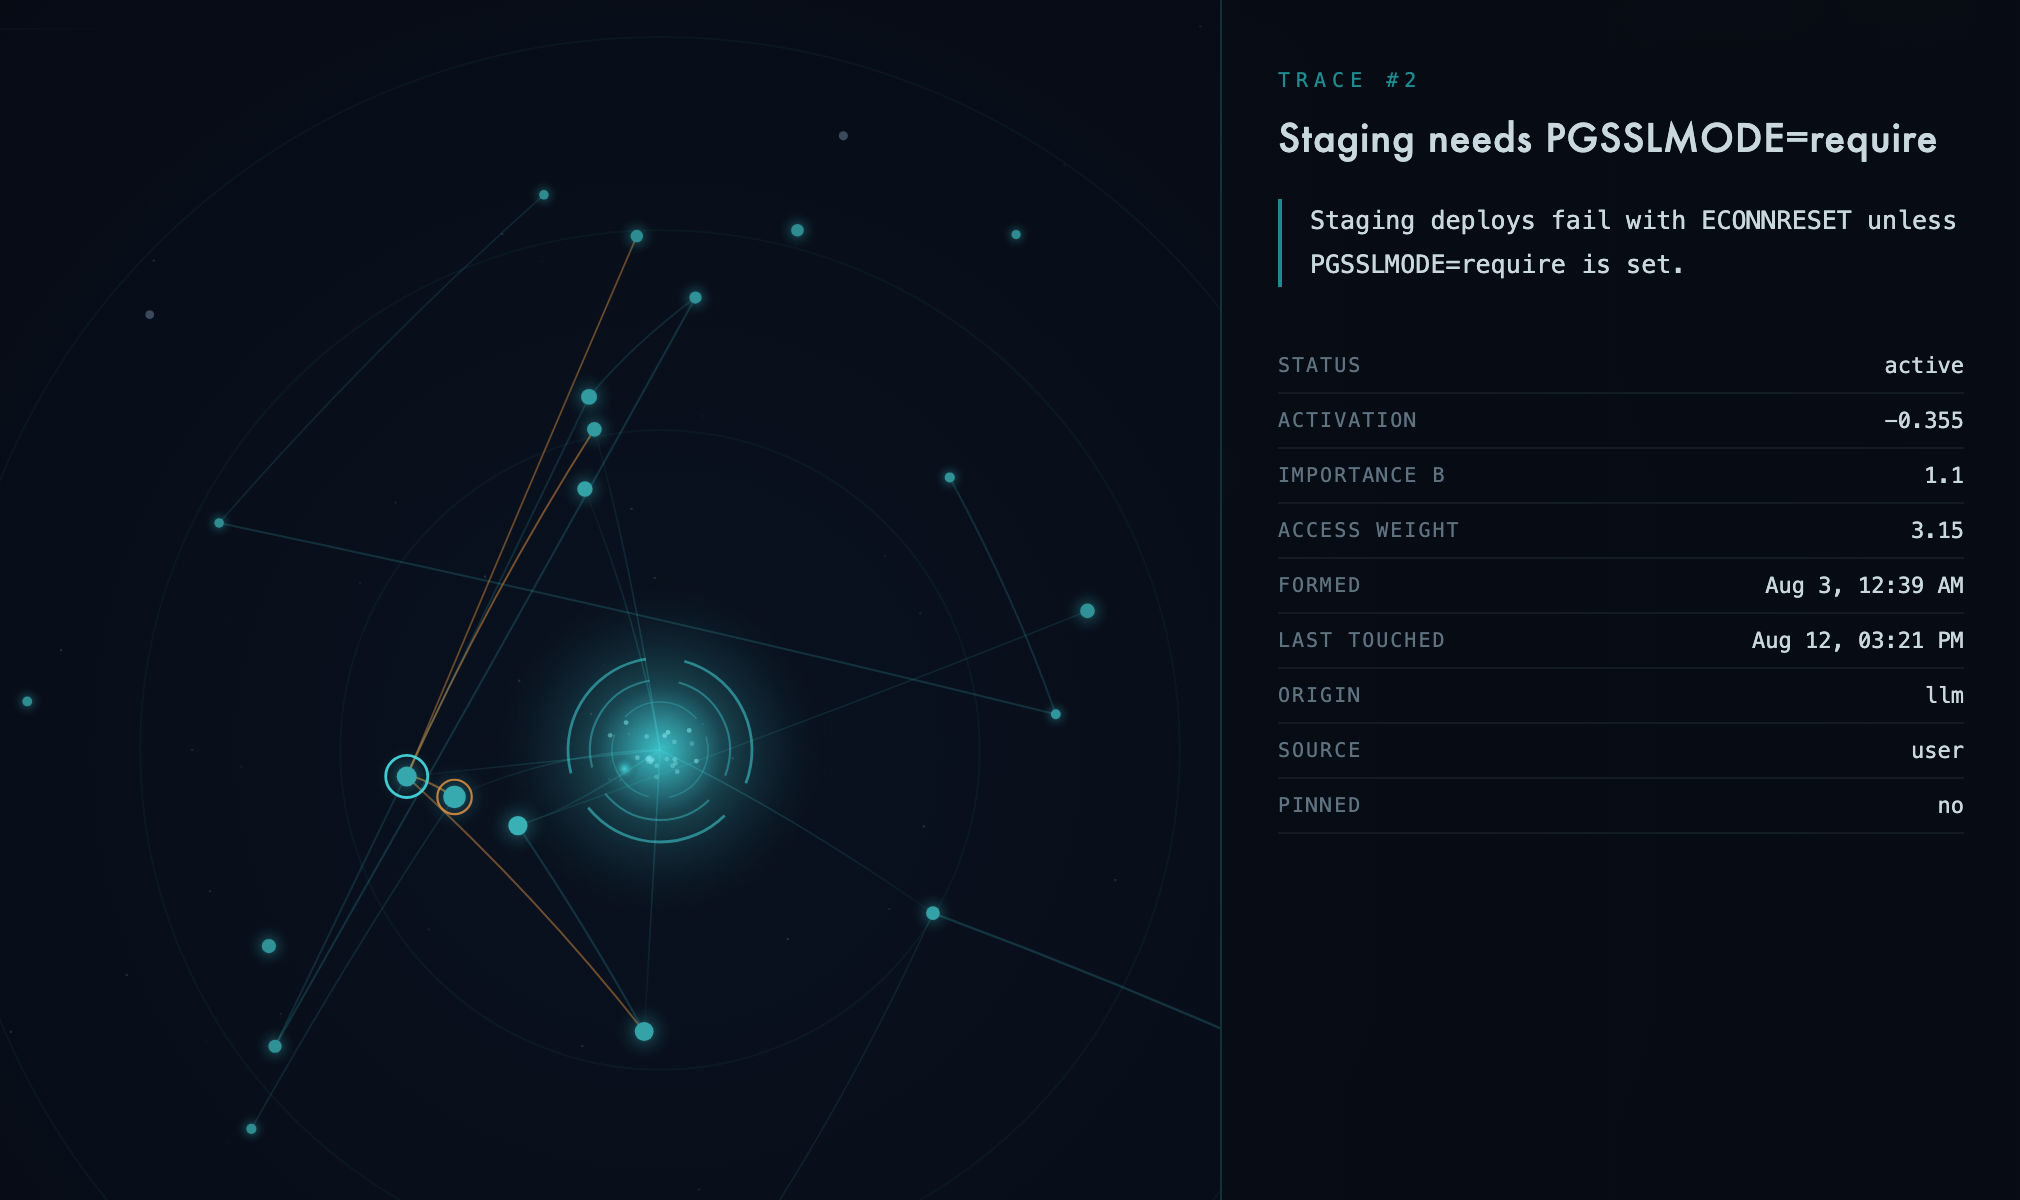
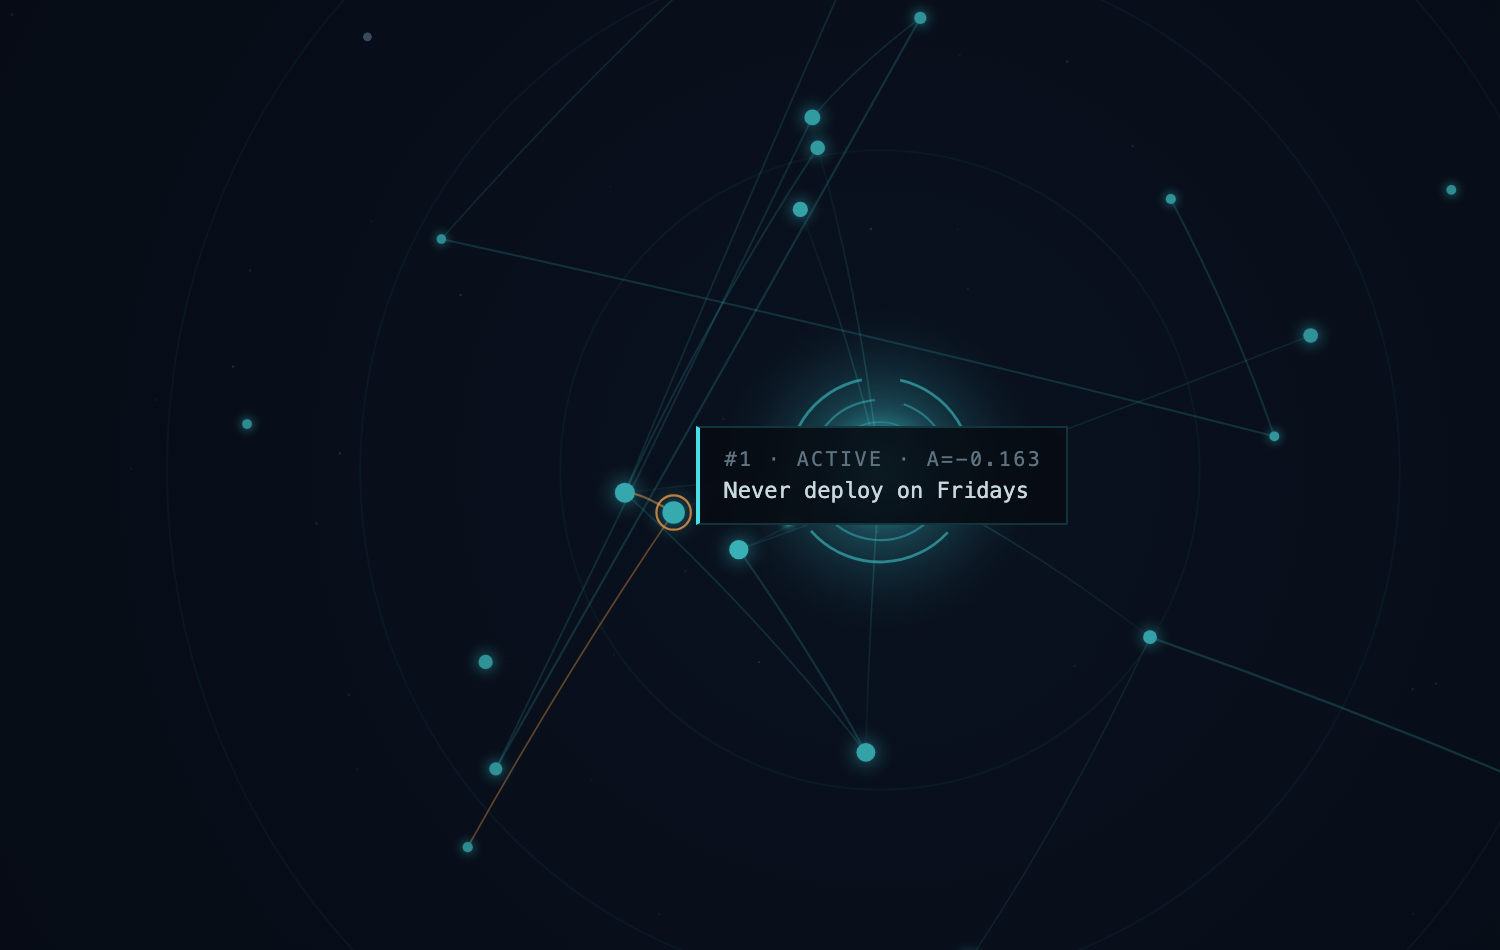
Click a memory and its hebbian web stays lit, dossier alongside; hover any mote for its status, activation, and title.
Engram is a transparent proxy that sits between any client and Ollama. It recalls relevant memories from past sessions and injects them before the model answers (~22 ms overhead, no LLM on the request path), then summarizes each exchange in the background - using the same small model you're chatting with.
                 ┌─────────────────────────────┐
  client ──────► │ engramd :11435              │ ──────► ollama :11434
  (curl,         │  recall → inject → forward  │
   openclaw,     │  response tee → episode log │
   hermes)       │  idle-time summarizer       │
                 └──────────┬──────────────────┘
                            └── engram.db (SQLite: FTS5 + vectors + queue)
Install
pip install engram-proxy    # or: uvx --from engram-proxy engram up
ollama pull qwen3:1.7b qwen3-embedding:0.6b
Quick start
engram up

# in another terminal - stock ollama, now with memory:
export OLLAMA_HOST=127.0.0.1:11435
ollama run qwen3:1.7b "I'm Sam. My cat is Miso and I'm badly allergic to peanuts."
# ... later, in a NEW session:
ollama run qwen3:1.7b "Ordering Thai tonight - anything I should avoid?"
Requires Ollama with qwen3:1.7b (summarizer) and qwen3-embedding:0.6b
(retrieval) - ollama pull qwen3:1.7b qwen3-embedding:0.6b, ~2 GB total.
Field-tested defaults: sub-1B summarizers garble facts, so qwen3:1.7b is the
default; without it, summaries fall back to extractive, which also preserves
facts. Set
ENGRAM_SUMMARIZER_MODEL / ENGRAM_EMBED_MODEL to override
(nomic-embed-text is ~3x faster to embed but measurably worse at admission).
CLI
engram up               run the proxy (default :11435 -> :11434)
engram list             recent traces (title + gist + access stats)
engram recall "query"   dry-run recall with per-candidate scores
engram why              explain the last injection, score by score
engram stats            store counts, queue depth, degraded recalls
engram bench            measure embed + recall latency on your machine
engram lme              LongMemEval-S subset run (dataset auto-detected in .lme/)
Numbers and methodology: BENCHMARKS.md. Headline: LongMemEval-S, all 500 questions: 98.1% evidence retrieval into a 2000-token block against 115k-token haystacks; 62.8% judged answers with a frontier answering model, comparable to published full-context results at a fraction of the tokens. Losing categories and all 9 retrieval misses published.
Design in one paragraph
Every exchange becomes an episode (verbatim, SHA-deduped). A write-behind
worker - running only when the GPU is idle - asks qwen3:1.7b for two plain
lines (TITLE: / GIST:; never JSON, with a deterministic extractive fallback)
and embeds the gist (qwen3-embedding, Matryoshka-truncated to 256d). Recall is
hybrid BM25 + dense with admission on raw thresholds (unrelated turns
inject nothing) - exact search below 50k memories, a pure-numpy IVF index past
it (~86ms p95 at 250k traces, still embed-bound) - ranked by relevance + ACT-R activation
B = ln(Σ w·t^-0.5) - frequent-and-recent memories surface first, unused ones
sink, and injection itself reinforces at only 0.15 weight (capped per session)
so the rich-get-richer loop stays closed. Idle-time consolidation maintains a user profile and topic summaries;
silent memories resurrect on strong cues. Injection is budgeted for small
models: ≤2 gists + 2 titles, ≤350 tokens, placed first in the system message.
Failures fail open: a slow or broken pipeline degrades to a plain proxy.
Full architecture spec: see the published design document.
For coding agents
The repo ships an agent-consumable skill at skills/engram-integration/SKILL.md
(standard SKILL.md format: Claude Code, OpenClaw, and Hermes all read it).
Point your agent at it, or just say "integrate engram into my setup", and it
walks the full recipe: preflight, install, per-client wiring, verification,
and the gotchas that cost us real debugging time.
Cloud models
Engram can give a cloud model the same memory, with background work staying local and free:
# route Anthropic-protocol traffic (/v1/messages) to a cloud endpoint,
# or OpenAI-protocol traffic (/v1/chat/completions) to any OpenAI-compatible
# provider; whichever you skip keeps hitting local Ollama
ENGRAM_ANTHROPIC_UPSTREAM=https://api.minimax.io engram up
ENGRAM_OPENAI_UPSTREAM=https://openrouter.ai/api engram up

# point your client's base_url at Engram:
#   Anthropic protocol (e.g. Hermes + MiniMax): MINIMAX_BASE_URL=http://127.0.0.1:11435/anthropic
#   OpenAI protocol (OpenRouter, DeepSeek, ...): base_url=http://127.0.0.1:11435/v1
Auth headers pass through untouched; embeddings and summarization always run
on local Ollama (ENGRAM_SERVICES, default http://127.0.0.1:11434), so the
only added cloud cost is the injected block itself (≤350 tokens, ~1% of a
typical agent prompt). Big-prompt injection rides the newest message, so
provider prompt caches - and their cache-read discounts - survive.
Endpoints
POST /api/chat- Ollama-native NDJSON, memory-enabledPOST /v1/chat/completions- OpenAI-compatible SSE, memory-enabled (local or cloud upstream)POST [/prefix]/v1/messages- Anthropic Messages (local or cloud upstream), memory-enabled- everything else (
/api/generate,/api/tags,/api/show,/v1/models, embeddings) - byte passthrough GET /engram/stats,GET /engram/why- local introspection- header
X-Engram: offbypasses memory per-request;X-Engram-Sessionpins session identity
1 maintainer

Metadata
1 maintainer
Release files for engram-proxy 0.6.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| engram_proxy-0.6.0.tar.gz | 85.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| engram_proxy-0.6.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 166.4 kB
Release files / engram_proxy-0.6.0.tar.gz
| Download URL | engram_proxy-0.6.0.tar.gz |
|---|---|
| Size | 85.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5544671d70eefd5b0f32404af9d1b8a9dc265876449739d850f30ed520d47ef5
|
|
BLAKE2b-256 checksum How to use checksums |
b253dfd02712ff9954e22e08bba86fc1ed113ba29cdbc39650bfb16a4d8b179b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.7
|
Release files / engram_proxy-0.6.0-py3-none-any.whl
| Download URL | engram_proxy-0.6.0-py3-none-any.whl |
|---|---|
| Size | 80.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1509315045711d5fa5605bcd3a5c0339314f5b736b3653fa67a67112993aae02
|
|
BLAKE2b-256 checksum How to use checksums |
c6c6667a09654c720949f6a5df8a101e43945bd73f6a66844099f1bf51d3a7fd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.7
|














