



EnzyMM - The Enzyme Motif Miner 
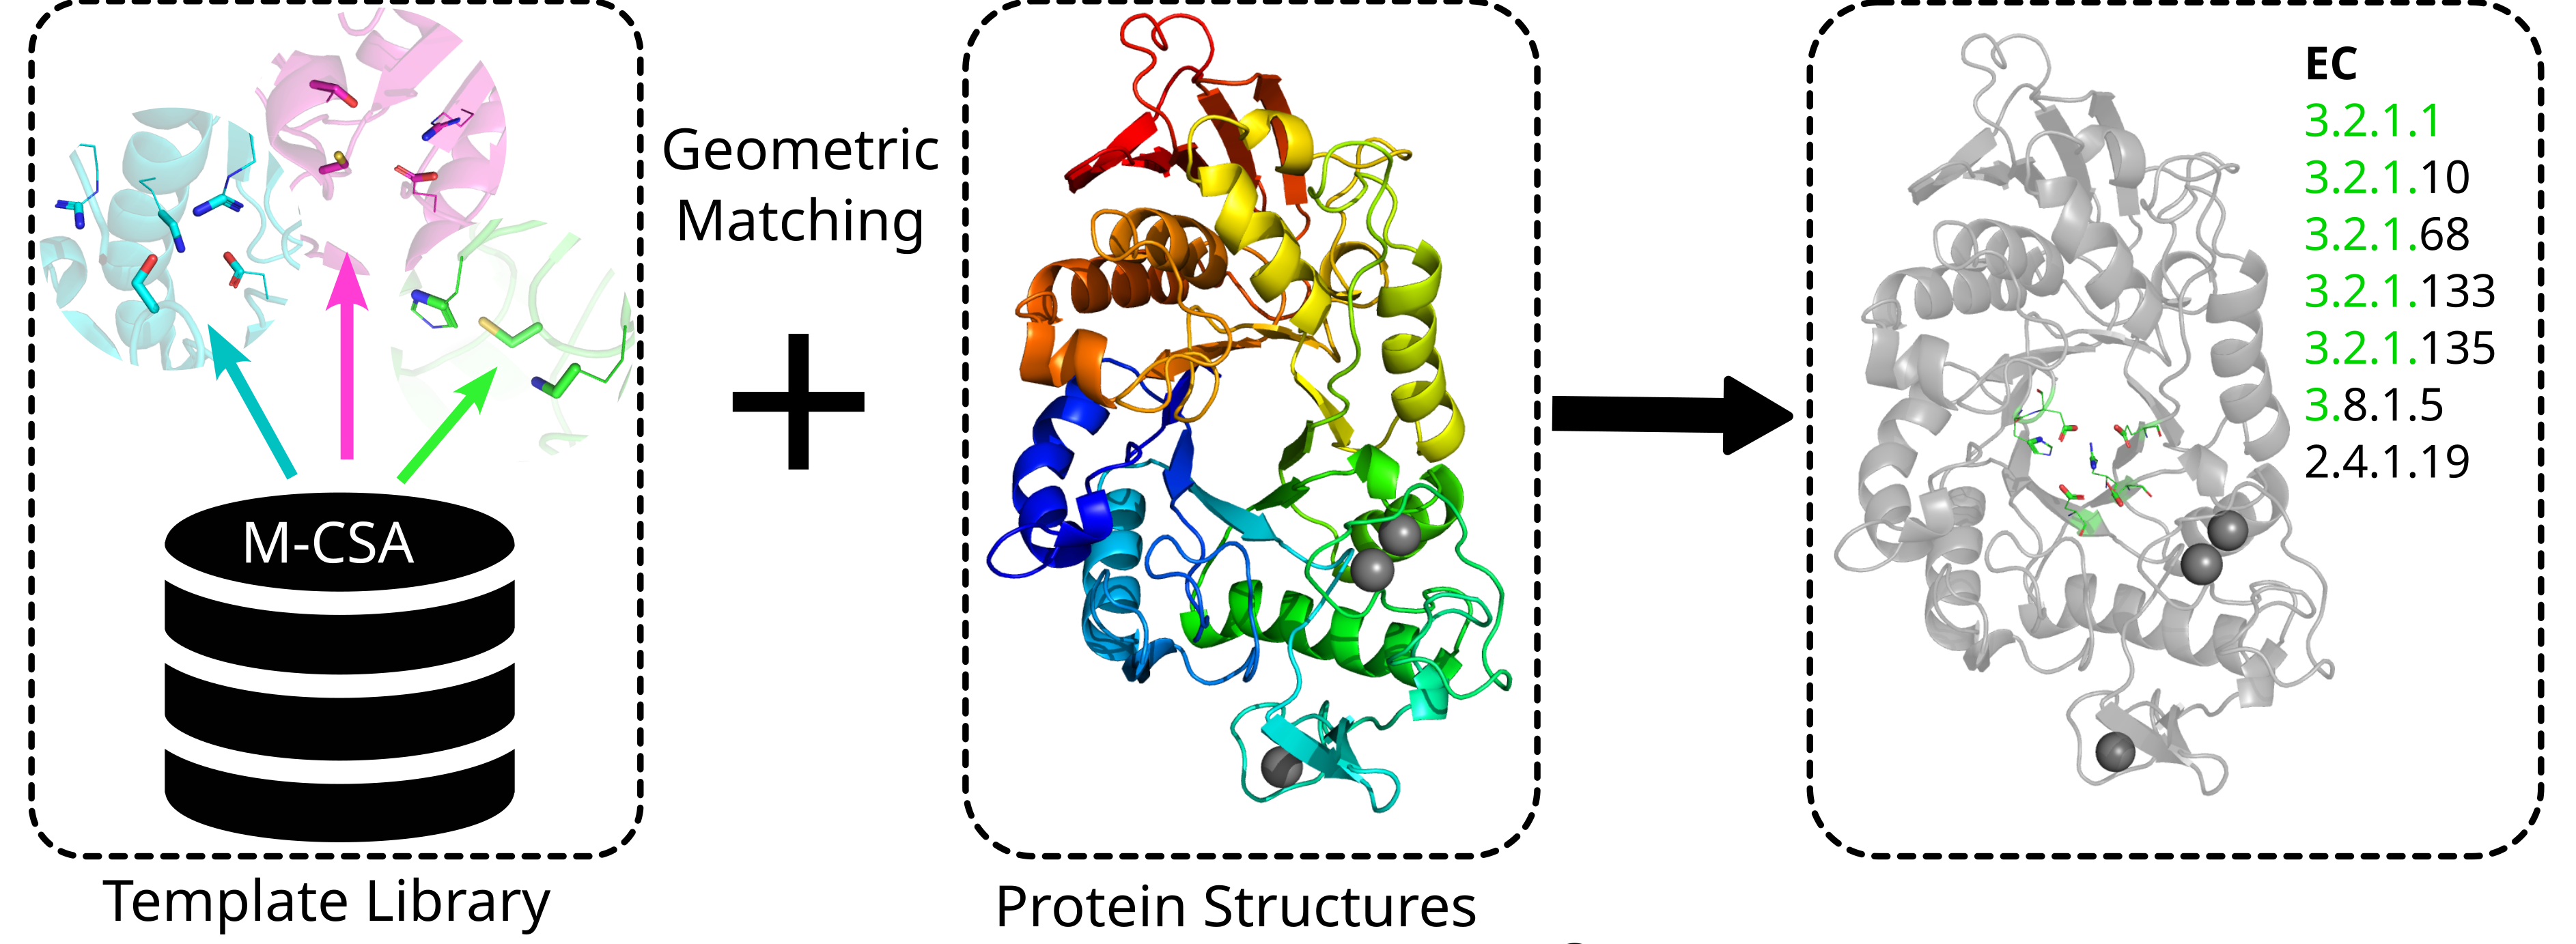
Enzyme Motif Miner uses geometric template matching to identify known arrangements of catalytic residues called templates in protein structures. It searches protein structures provided by the user against a database of templates. EnzyMM ships with a library of catalytic templates derived from the Mechanism and Catalytic Site Atlas (M-CSA) but you can also generate your own. These templates represent consensus arrangements of catalytic sites found in active sites of experimental protein structures.
As catalytic sites are both highly conserved and absolutely critical for the function of a protein, identifying them offers many biological insights. This method has two key advantages. Firstly, as it doesn't rely on sequence or (global) fold similarity, similar catalytic arrangements can be found accross great evolutionary distances offering insights into the divergence or even convergence of enyzmes. Secondly, as geometric matching is very fast, EnzyMM scales along side databases of predicted protein structures. Expect to scan a protein structure in a matter of seconds on consumer laptops.
As a database driven method, EnzyMM is inherently limited by the coverage of residue arrangements in its template library. The provided template library covers nearly the entire M-CSA and thus around 3/4 of enzyme mechanisms classified by the Enzyme Commission to the 3rd level. Catalytic arrangements not found in the PDBe won't be included in the M-CSA. Of course, the user can also provide their own library of templates. While primarily intended for catalytic sites, you are invited to search with your own library of templates.
🌐 Webserver
If you just want to try EnzyMM we provide a webserver at https://www.ebi.ac.uk/thornton-srv/m-csa/enzymm .
📚 Documentation
Full documentation is availabe here: https://enzymm.readthedocs.io/en/latest/
🔧 Installing EnzyMM
EnzyMM is implemented in Python,
and supports all versions from Python 3.7 on Linux and MacOS. It requires
additional libraries that can be installed directly from
PyPI, the Python Package Index.
Use pip to install EnzyMM on your
machine:
$ pip install enzymm
Alternatively, use Anaconda to install EnzyMM. Optionally install gemmi to search CIF files too:
$ conda install -c bioconda enzymm gemmi
This will both install EnzyMM and also download a library of catalytic templates together with important metadata. This requires around 16MB of data to be downloaded.
It should also run on windows (though this is not tested for on release).
🖼️ Images
Lightweight images built from python:3.13-alpine are available:
Pull the latest Docker image from GHCR:
docker pull ghcr.io/rayhackett/enzymm:latest
Pull the latest Apptainer image via ORAS from GHCR:
apptainer pull oras://ghcr.io/rayhackett/enzymm:latest
🔎 Running EnzyMM
Once EnzyMM is installed, you can run it from the terminal. The user can either provide a path to a single protein structure -i or to run multiple queries at once, the path to a text file -l which itself contains a list of paths to protein structures.
Structures are accepted in both CIF/mmCIF and PDB file format.
Optionally, an output directory for PDB structures of the identified matches per query protein can be supplied with the --pdbs flag.
$ enzymm -i some_structure.pdb -o results.tsv --pdbs dir_to_save_matches
Additional parameters of interest are:
--per-residue-results, which will return an additional table mapping each matched residue to its original annotation and catalytic role.--jobsor-j, which controls the number of threads used to parallelize the search. By default, it will use one thread less than available on your system usingos.cpu_count.--unfilteredor-u, which disables filtering of matches by RMSD and residue orientation. By default, filtering is enabled.--skip-smaller-hits, which skips searches with smaller templates on a query if a match to a larger template has already been found.--parametersor-p, which controls the RMSD threshold and pairwise distance threshold applied. By default sensible thresholds are selected. Refer to the Docs for details--template-diror-t, though which the user may supply their own template library. By default, a library of catalytic templates derived from the M-CSA is loaded.--conservation-cutoffor-c, which can be set to exclude atoms with B-factors or pLDDT scores below this threshold from matching. This is not set by default.
Further, EnyzMM is designed with modularity in mind and comes with a fully usable internal API.
Please refer to the Documentation for further reference.
🖹 Results
Tabular results
EnzyMM will create a single output file by default. You can chose between the default full results or a more simple style with fewer columns using the flag --simple-results:
{output}.tsv: A.tsvfile containing a summary of all results. One row is printed per match.
If you pass the --per-residue-results flag, EnzyMM will additionally create a table with one line per matched residue, mapping each residue to its original annotations.
{output}.residues.tsv: A.tsvfile containing one row per residue per match.
Aligned Structures
For visual exploration of matches, you can optionally save an alignment of the template and the matched query residues to a PDB file which can be viewed with any molecular viewer.
To do so, supply an output directory after the --pdbs flag for the .pdb files.
What will get written depends of in the --transform flag is set or not:
{pdbs_dir}/{query_identifier}_matches.pdb: Default: One.pdbfile per query with matched residues in the query written in the query reference frame.{pdbs_dir}/{template_pdb_identifier}_matches.pdb: Default: One.pdbfile per template structure which matches any query written in the template reference frame. In short,--transformforces the output into the template reference frame. Therefore only matches from the same template structure can be aligned which is why we write one file per matched template structure!
Add additional information to each .pdb file with the following flags:
--include-template, which also writes the template structure to the.pdbfile--include-query, which also writes the entire query structure to the.pdbfile
💭 Feedback
⚠️ Issue Tracker
Please report any bugs or feature requests though the GitHub issue tracker.
Please also feel free to ask any questions and I will do my best to answer them.
If reporting a bug, please include as much information as you can about the issue and try to recreate the same bug.
Ideally include a little test example so I can quickly troubleshoot.
🏗️ Contributing
Contributions are more than welcome!
Raise an issue, make a pull request or shoot me an email under r.e.hackett AT lumc.nl
I'm happy to help.
📋 Changelog
This project adheres to Semantic Versioning and provides a changelog in the Keep a Changelog format.
⚖️ License
This software is provided under the open source MIT licence.
Though conceived at the EMBL-EBI in Hinxton, UK in the Thornton Group, EnzyMM is now developed by Raymund Hackett and the Zeller Group at the Leiden University Medical Center in Leiden in the Netherlands with continuing support from the Thornton Group.
🔖 Citations
EnyzMM is academic software but relies on many previous approaches.
We kindly ask you to cite both:
- EnzyMM for instance as:
Hackett RE et al. (2026), Investigating Enzyme Function by Geometric Matching of Catalytic Motifs, Protein Science DOI:10.1002/pro.70744
- Mechanism and Catalytic Site Atlas as:
Ribeiro AJM et al. (2017), Nucleic Acids Res, 46, D618-D623. Mechanism and Catalytic Site Atlas (M-CSA): a database of enzyme reaction mechanisms and active sites. DOI:10.1093/nar/gkx1012. PMID:29106569.
1 maintainer

Metadata
1 maintainer
Release files for enzymm 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| enzymm-0.5.0.tar.gz | 12.8 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| enzymm-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 30.8 MB
Release files / enzymm-0.5.0.tar.gz
| Download URL | enzymm-0.5.0.tar.gz |
|---|---|
| Size | 12.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
55aaaa80a6eb7d64c9c500b02a9f07f07f5603ab076a2053d1f3df51bb57a198
|
|
BLAKE2b-256 checksum How to use checksums |
7dd0cc86a2d7451b85d2655f777937b4820413214008fc8dda2ccfe32048520a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 11, 2026.
Transparency logRelease files / enzymm-0.5.0-py3-none-any.whl
| Download URL | enzymm-0.5.0-py3-none-any.whl |
|---|---|
| Size | 18.0 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e502f49a30fbf80c97ebe1845d2428859b947c622ee52524f8dd59e4b32abda7
|
|
BLAKE2b-256 checksum How to use checksums |
2b6edf521650ae5100e35412d8f3ecbe25dc967dd3428a26b9cf99aea8c5b4fd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 11, 2026.
Transparency log













