
ES-MoE Toolkit


Drop it into a torch model or add it to YOLO in one call, the router loss reaches the optimiser, and every number here has a run record behind it. Try It.
Docs: English · 中文 · Quick start in Colab: notebooks/quickstart.ipynb · Ask questions about the code: DeepWiki.
Install
uv add esmoe            # the block, for any torch model
uv add esmoe[yolo]      # ... and the Ultralytics integration
esmoe[ultralytics] is that extra under its other name, esmoe[keras] adds the Keras 3 backend,
and esmoe[tensorflow] or esmoe[jax] bring Keras with that backend behind it. The distribution,
the import and the command line are all esmoe; the project is written ES-MoE in prose.
In a torch model
import esmoe
from torch import nn

net = nn.Sequential(
    nn.Conv2d(3, 64, 3, 2, 1),
    esmoe.ESMoE(kernels=[3, 5, 7], top_k=1),          # three experts, one per sample
    esmoe.ESMoE(kernels=[(1, 9), (9, 1)], top_k=2),   # two strip experts, both per sample
)

with esmoe.routing(net) as route:
    loss = task_loss(net(x), y) + 0.01 * route.loss()
loss.backward()
kernels gives each expert its receptive field, an int or an (h, w) pair, and with it how many
experts there are. expert gives a branch its structure, one factory for all of them or one each.
top_k says how many run per sample. The block takes its width from the first forward pass, so
nothing has to declare it. To put blocks into a model that already exists:
esmoe.graft(resnet, at="layer3", mode="after", kernels=[3, 5, 7], top_k=1)
at takes a submodule name, several names, or a (name, module) -> bool test; mode is after,
before or replace.
In Ultralytics YOLO
One call registers the block, grafts it into the config, builds the model, and makes the router loss part of the optimised training loss:
model = esmoe.equip("yolo11n.yaml", weight=0.01)
model.train(data="coco8.yaml", epochs=10)
Or take the steps apart when you need control over each one:
from ultralytics import YOLO
import esmoe

esmoe.register()                                             # resolve `ESMoE` in a model.yaml
esmoe.graft("yolov8n.yaml", out="v8-esmoe.yaml", at=[4, 6])  # insert blocks, renumber the head
model = YOLO("v8-esmoe.yaml")
esmoe.attach_aux_loss(model, weight=0.01)                    # the router loss joins the total
From the shell:
esmoe graft yolo11n.yaml -o yolo11n-esmoe.yaml --kernels 3,5,7 -k 1
attach_aux_loss adds an esmoe_aux entry to the trainer's loss table, so a non-zero,
back-propagated auxiliary term shows up in results.csv rather than merely in a config.
Written by hand, a config layer is just:
[-1, 1, ESMoE, [4, 2]]                              # num_experts, top_k
[-1, 1, ESMoE, [{kernels: [3, 5, 7], top_k: 1}]]    # or say what you mean
[-1, 1, ESMoE, [4, 2, null, {out_norm: true}]]      # ... and settings the trainer must keep
[-1, 1, ESMoE, [4, 2, null, {out_channels: 320}]]   # widened ...
[-1, 1, Index, [320, 0]]                            # ... and the official layer that declares it
ESMoE, ES_MoE and ES_MOE all resolve to the block, and a config that already names one is
taken as written: equip grafts nothing into it. The block is channel preserving and infers its
width on the first forward, which is what lets stock parse_model size it without a patch. A
widened block instead hands a one-element list to the official Index layer after it, whose
declared width parse_model does read; graft(out_channels=...) writes both. Settings belong in
the config because the trainer rebuilds the model from it, dropping anything set on the blocks
beforehand.
On tensorflow, jax and keras
The block is written twice: once in torch, once in Keras 3, which runs it on tensorflow, jax or torch. Both read their arguments through the same code, so they take the same ones.
from esmoe.keras import ESMoE

net = keras.Sequential([keras.layers.Conv2D(16, 3, padding="same"), ESMoE(kernels=[3, 5, 7], top_k=1)])
net.compile(optimizer="adam", loss="mse")
net.fit(x, y)            # the balancing term rides along through Keras' own add_loss
One difference: the Keras layer evaluates every expert and weights them by the gate. Skipping an
unrouted expert depends on the data, which a traced jax or tensorflow graph cannot express. The
routing and the balancing term are the torch backend's; only the inference-time saving is torch's
alone. esmoe.backend("jax") and esmoe.backend("tensorflow") both lead here.
Extend
Experts and the balancing objective are plain callables, so a variant is a few lines:
esmoe.ESMoE(kernels=[3, 5], expert=[MyExpert, esmoe.DWExpert], balance=my_balance_fn)
MyExpert(c1, c2, k) -> Module, my_balance_fn(probs, gate) -> scalar. To train with them under
YOLO, pass them to graft or equip: a function or class defined at module level goes into the
config as module:qualname, and every rebuild of the model -- the trainer's, each DDP worker's --
imports it back from that name. A lambda or anything defined in __main__ is refused when grafting.
esmoe.blocks(model) walks every block in a model, esmoe.collect_aux_loss(model) returns the
current step's router loss for custom training loops, and block.spec() reports the settings a
block is holding.
Compatibility
| backend | block | router loss | graft | tested on |
|---|---|---|---|---|
| torch | yes | yes | any nn.Module |
every CI leg, and one with ultralytics absent |
| Keras 3 on tensorflow | yes | through add_loss |
Sequential |
its own CI leg |
| Keras 3 on jax | yes | through add_loss |
Sequential |
its own CI leg |
| Keras 3 on torch | yes | through add_loss |
Sequential |
its own CI leg |
The Ultralytics integration runs on the torch block:
| backbone | build + forward | grafted config | aux loss in training | protocol runs |
|---|---|---|---|---|
| YOLOv5 | yes | yes | yes | yes |
| YOLOv8 | yes | yes | yes | yes |
| YOLOv9 | yes | yes | yes | yes |
| YOLOv10 | yes | yes | yes | yes |
| YOLO11 | yes | yes | yes | yes |
| YOLO12 | yes | yes | yes | yes |
| YOLO26 | yes | yes | yes | yes |
| YOLO-Master (fork) | yes | yes | yes | no |
The fork row has no protocol runs of this package: the same-configuration comparison trains upstream's own blocks on the fork and this package's blocks on official ultralytics.
Verified by tests/test_ultralytics.py on ultralytics 8.4.101 and on the latest release, the two versions in the CI
matrix; they report loss items in different shapes, and both are handled. The training column is backed by real 1-epoch VisDrone
runs on four generations (results/*-compat-*.json) and by the 120-epoch protocol runs on all seven,
each logging a non-zero train/esmoe_aux.
Graft and forward are exercised on every row in CI. The last column separates "the block builds and trains" from
"we ran the full budget-fair protocol on it". The YOLO-Master row runs against the fork's vendored ultralytics: scripts/fork_smoke.py grafts their yolo-master-n.yaml, trains one epoch with a non-zero esmoe_aux, and builds their own ES_MOE config alongside ours.
DDP works: attach_aux_loss routes model.train() through a trainer class that lives in esmoe.yolo.trainer, so the
worker processes ultralytics spawns register the block and the auxiliary loss before they build. Verified by
scripts/verify.py (the real worker file in a fresh interpreter; two gloo ranks with agreeing router gradients).
Inside a process group an expert that no image routed to joins the graph at zero weight, so the settings
ultralytics uses under compile=True (find_unused_parameters=False, static_graph=True) train as well;
tests/test_distributed.py checks that with two gloo ranks, and that the block compiles and agrees with eager.
To compare against YOLO-Master under one configuration, attach_aux_loss(model, weight=1.0, recipe="upstream")
trains the way its trainer trains a routed model. The auxiliary term is normalised by its running magnitude and
capped at 3.0, routers get half the learning rate outside Muon, and experts stay frozen for three epochs.
scripts/train.py --upstream runs the same protocol on the fork itself, and scripts/same_config.py pairs the two.
Default configuration
ESMoE(num_experts=4, top_k=2) with attach_aux_loss(weight=0.01), chosen under one budget over
2/4/8-expert and top-1 variants. Under the repository protocol (VisDrone, imgsz 800, 120 epochs, three seeds)
the matrix runs to seven backbone generations × three arms, three seeds or more per cell (one cross-host replication cell has a single seed), 142 runs, the last twenty-nine of them the same-configuration comparison against YOLO-Master's own fork: twelve in each of two rounds, and five FP32 repeats that measure the noise floor. What separates a positive
cell from a negative one is what the backbone ends in, not how new it is: the default wiring is positive on the
SPPF family (+0.0055 v5n, +0.0025 v8n, +0.0025 v9t), sits on zero once the end is an attention block (−0.0002
v10n, +0.0013 11n), and is negative on area attention and the E2E head (−0.0018 12n, −0.0034 26n). The block
adds 4.5% to 12.5% parameters depending on the backbone (+10.4% on YOLOv8n), and the default arm takes 4% to 10% more card-hours per run.
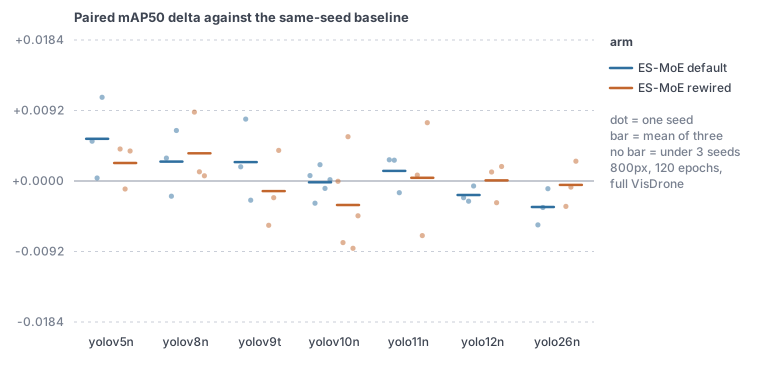
Each dot is one seed, each bar the mean of the seeds (three, five on v10n). The seeds routinely straddle zero even where the mean does not, which is as far as a three-seed protocol can read: an interactive version carries the per-seed values and the second metric. Where the damage lands depends on the backbone: v8n loses large objects (APl −0.010, 0/3), 26n loses small ones (APs −0.0045, 0/3), 12n is direction-unstable.
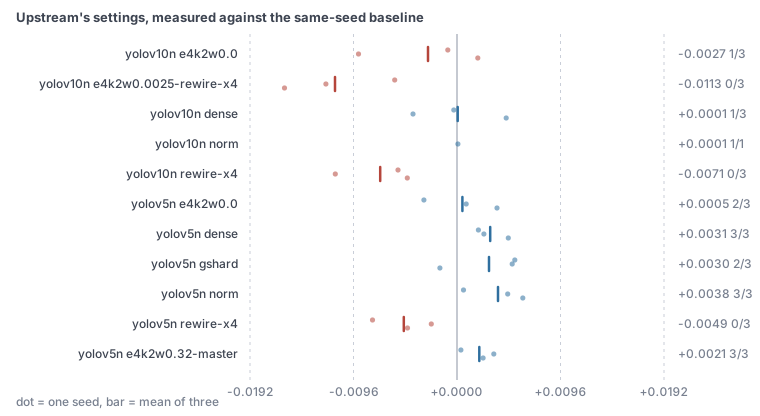
Further arms ask what upstream's own settings are worth. Two of them are internal to the block: on v5n both help (output norm +0.0038, dense training +0.0031, 3/3 each), while dense training is flat on v10n (+0.0001, 1/3). Upstream's layout of four blocks per backbone is negative on both metrics at 0/3 on both backbones it ran on, and on v10n it stays negative with each block's weight cut to a quarter so the auxiliary total matches one block (−0.0113, 0/3) — the count is what costs, not the pressure. That holds under this package's recipe: with upstream's whole recipe the same four blocks are positive on every seed in both frameworks (same-configuration rounds seven and eight).
How concentrated the dispatch is does not predict accuracy: r = +0.044 over the 81 runs that have both a routing analysis and a paired delta. What the balancing term does secure is that no expert dies. Without it all six checkpoints lose two of four experts; the Switch term at 0.01 leaves none dead in 66. The paper's objective and upstream's read the gate, which is renormalised over the top-K and so has no gradient for an expert outside it: five of six such checkpoints have a dead expert, even at more pressure than Switch, and so do all six same-configuration B checkpoints, trained with upstream's recipe.
The default graft leaves consumers that name the old backbone end by index — YOLOv8's P5 lateral among them —
reading the pre-block tensor; graft(..., rewire=True) retargets them. That arm is the only 3/3 one on v8n
(+0.0036) and pulls 12n and 26n back to near parity (+0.0001 and −0.0005); it trails the default on v5n, v9t, v10n and 11n.
Verdicts against the pre-registered lines: docs/JUDGMENT.md. Full tables: docs/SELECTION.en.md,
results/summary.md, results/buckets.md, results/routing.md.
Develop and reproduce
uv sync --group dev
uv run pytest -q
uv run python scripts/capture_env.py                  # freeze environment into results/env/
EPOCHS=20 FRACTION=0.25 SEEDS="0 1 2" uv run bash scripts/sweep.sh
uv run python scripts/report.py                       # results/summary.md
Every run writes one machine-readable record to results/ (config, dataset, hardware, budget, seed,
metrics, artifact, status, limitation). How each number was measured is on the experiments page. The 142
protocol checkpoints, with each run's arguments and per-epoch curve, live on the checkpoints
branch (Git LFS, orphan — main stays small), flat-named to match the run records.
Linked projects
- ultralytics - the official YOLO framework this plugs into.
- keras - the multi-backend framework the second implementation runs on.
- Tencent/YOLO-Master - where ES-MoE comes from (paper).
License
AGPL-3.0-only, matching the Ultralytics ecosystem it builds on.
1 maintainer

Metadata
1 maintainer
Release files for esmoe 2.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| esmoe-2.0.0.tar.gz | 84.7 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| esmoe-2.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 136.0 kB
Release files / esmoe-2.0.0.tar.gz
| Download URL | esmoe-2.0.0.tar.gz |
|---|---|
| Size | 84.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3cb2b592631f058f3ccf2455a3a6e75faa67d60d97721cda86e9c7412bb3ba3c
|
|
BLAKE2b-256 checksum How to use checksums |
5505d53f46c78c8c28962f46e2e5f02e1d62f4a416f0b6bf6a415d63a31fc110
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logRelease files / esmoe-2.0.0-py3-none-any.whl
| Download URL | esmoe-2.0.0-py3-none-any.whl |
|---|---|
| Size | 51.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f9b8fef97123d5f186fd9a8a830ae5b3c7c295b2dc2ee3371dde340989e7b4c5
|
|
BLAKE2b-256 checksum How to use checksums |
6d8c55a8532ae5bf2869e31c0302fb6ee6627c3747456db819456dc014481912
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logSecurity for esmoe 2.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for esmoe-2.0.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














