
This is an unofficial fork of s3prl/s3prl
maintained by the ESPnet project. It is not affiliated with, nor endorsed by,
the S3PRL Team. Upstream calls torchaudio.set_audio_backend at import time,
which no torchaudio since 2.1 provides, so it cannot be imported in an ESPnet
environment. The import name is unchanged. See
FORK_NOTICE.md.


Contact
We prefer to have discussions directly on Github issue page, so that all the information is transparent to all the contributors and is auto-archived on the Github. If you wish to use email, please contact:
We encourage to cite the individual papers most related to the function you are using to give fair credit to the developer of the function. You can find the names in the Change Log. Finally, we would like to thank our advisor, Prof. Hung-yi Lee, for his advice. The project would be impossible without his support.
If you have any question (e.g., about who came up with / developed which ideas / functions or how the project started), feel free to engage in an open and responsible conversation on the GitHub issue page, and we'll be happy to help!
Contribution (pull request)
Guideline
- Starting in 2024, we will only accept new contributions in the form of new upstream models, so we can save bandwidth for developing new techniques (which will not be in S3PRL.)
- S3PRL has transitioned into pure maintenance mode, ensuring the long-term maintenance of all existing functions.
- Reporting bugs or the PR fixing the bugs is always welcome! Thanks!
Tutorials
Environment compatibilities
We support the following environments. The test cases are ran with tox locally and on github action:
| Env | versions |
|---|---|
| os | ubuntu-20.04 |
| python | 3.9, 3.10, 3.11, 3.12 |
| pytorch | 1.13.1 , 2.0.1 , 2.1.2, 2.2.2, 2.3.1, 2.4.0 |
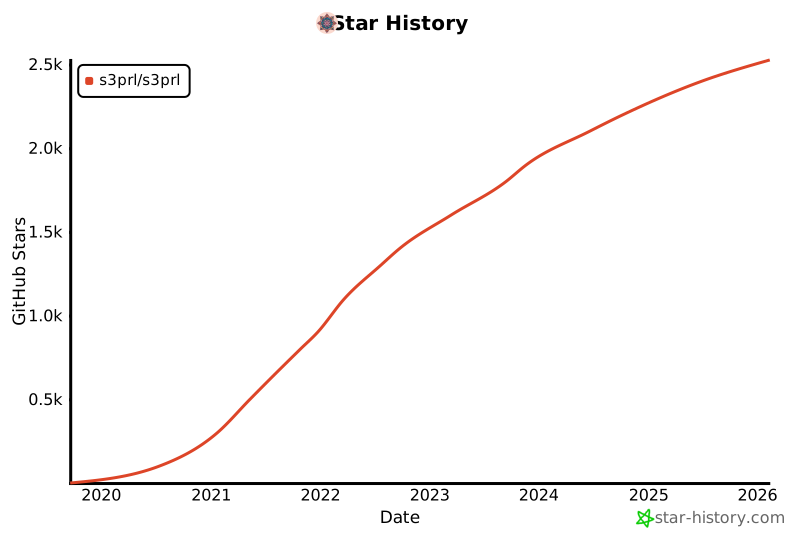
Star History
Change Log
We only list the major contributors here for conciseness. However, we are deeply grateful for all the contributions. Please see the Contributors page for the full list.
- Sep 2024: Support MS-HuBERT (see MS-HuBERT)
- Dec 2023: Support Multi-resolution HuBERT (MR-HuBERT, see Multiresolution HuBERT)
- Oct 2023: Support ESPnet pre-trained upstream models (see ESPnet HuBERT and WavLabLM)
- Sep 2022: In JSALT 2022, We upgrade the codebase to support testing, documentation and a new S3PRL PyPI package for easy installation and usage for upstream models. See our online doc for more information. The package is now used by many open-source projects, including ESPNet. Contributors: Shu-wen Yang (NTU), Andy T. Liu (NTU), Heng-Jui Chang (MIT), Haibin Wu (NTU) and Xuankai Chang (CMU).
- Mar 2022: Introduce SUPERB-SG, see Speech Translation by Hsiang-Sheng Tsai (NTU), Out-of-domain ASR by Heng-Jui Chang (NTU), Voice Conversion by Wen-Chin Huang (Nagoya), Speech Separation and Speech Enhancement by Zili Huang (JHU) for more info.
- Mar 2022: Introduce SSL for SE/SS by Zili Huang (JHU). See SE1 and SS1 folders for more details. Note that the improved performances can be achieved by the later introduced SE2 and SS2. However, for aligning with SUPERB-SG benchmarking, please use the version 1.
- Nov 2021: Introduce S3PRL-VC by Wen-Chin Huang (Nagoya), see Any-to-one for more info. We highly recommend to consider the newly released official repo of S3PRL-VC which is developed and actively maintained by Wen-Chin Huang. The standalone repo contains much more recepies for the VC experiments. In S3PRL we only include the Any-to-one recipe for reproducing the SUPERB results.
- Oct 2021: Support DistilHuBERT by Heng-Jui Chang (NTU), see docs for more info.
- Sep 2021: We host a challenge in AAAI workshop: The 2nd Self-supervised Learning for Audio and Speech Processing! See SUPERB official site for the challenge details and the SUPERB documentation in this toolkit!
- Aug 2021: Andy T. Liu (NTU) and Shu-wen Yang (NTU) introduces the S3PRL toolkit in MLSS 2021, you can also watch it on Youtube!
- Aug 2021: TERA by Andy T. Liu (NTU) is accepted to TASLP!
- July 2021: We are now working on packaging s3prl and reorganizing the file structure in v0.3. Please consider using the stable v0.2.0 for now. We will test and release v0.3 before August.
- June 2021: Support SUPERB: Speech processing Universal PERformance Benchmark, submitted to Interspeech 2021. Use the tag superb-interspeech2021 or v0.2.0. Contributors: Shu-wen Yang (NTU), Pohan Chi (NTU), Yist Lin (NTU), Yung-Sung Chuang (NTU), Jiatong Shi (CMU), Xuankai Chang (CMU), Wei-Cheng Tseng (NTU), Tzu-Hsien Huang (NTU) and Kushal Lakhotia (Meta).
- June 2021: Support extracting multiple hidden states for all the SSL pretrained models by Shu-wen Yang (NTU).
- Jan 2021: Readme updated with detailed instructions on how to use our latest version!
- Dec 2020: We are migrating to a newer version for a more general, flexible, and scalable code. See the introduction below for more information! The legacy version can be accessed the tag v0.1.0.
- Oct 2020: Shu-wen Yang (NTU) and Andy T. Liu (NTU) added varioius classic upstream models, including PASE+, APC, VQ-APC, NPC, wav2vec, vq-wav2vec ...etc.
- Oct 2019: The birth of S3PRL! The repository was created for the Mockingjay development. Andy T. Liu (NTU), Shu-wen Yang (NTU) and Pohan Chi (NTU) implemented the pre-training scripts and several simple downstream evaluation tasks. This work was the very start of the S3PRL project which established lots of foundamental modules and coding styles. Feel free to checkout to the old commits to explore our legacy codebase!
Introduction and Usages
This is an open source toolkit called s3prl, which stands for Self-Supervised Speech Pre-training and Representation Learning. Self-supervised speech pre-trained models are called upstream in this toolkit, and are utilized in various downstream tasks.
The toolkit has three major usages:
Pretrain
- Pretrain upstream models, including Mockingjay, Audio ALBERT and TERA.
- Document: pretrain/README.md
Upstream
- Easily load most of the existing upstream models with pretrained weights in a unified I/O interface.
- Pretrained models are registered through torch.hub, which means you can use these models in your own project by one-line plug-and-play without depending on this toolkit's coding style.
- Document: upstream/README.md
Downstream
- Utilize upstream models in lots of downstream tasks
- Benchmark upstream models with SUPERB Benchmark
- Document: downstream/README.md
Here is a high-level illustration of how S3PRL might help you. We support to leverage numerous SSL representations on numerous speech processing tasks in our GitHub codebase:

We also modularize all the SSL models into a standalone PyPi package so that you can easily install it and use it without depending on our entire codebase. The following shows a simple example and you can find more details in our documentation.
- Install the S3PRL package:
pip install s3prl
- Use it to extract representations for your own audio:
import torch
from s3prl.nn import S3PRLUpstream

model = S3PRLUpstream("hubert")
model.eval()

with torch.no_grad():
    wavs = torch.randn(2, 16000 * 2)
    wavs_len = torch.LongTensor([16000 * 1, 16000 * 2])
    all_hs, all_hs_len = model(wavs, wavs_len)

for hs, hs_len in zip(all_hs, all_hs_len):
    assert isinstance(hs, torch.FloatTensor)
    assert isinstance(hs_len, torch.LongTensor)

    batch_size, max_seq_len, hidden_size = hs.shape
    assert hs_len.dim() == 1
With this modularization, we have achieved close integration with the general speech processing toolkit ESPNet, enabling the use of SSL models for a broader range of speech processing tasks and corpora to achieve state-of-the-art (SOTA) results (kudos to the ESPNet Team):

You can start the journey of SSL with the following entry points:
- S3PRL: A simple SUPERB downstream task
- ESPNet: Levearging S3PRL for ASR
Feel free to use or modify our toolkit in your research. Here is a list of papers using our toolkit. Any question, bug report or improvement suggestion is welcome through opening up a new issue.
If you find this toolkit helpful to your research, please do consider citing our papers, thanks!
Installation
- Python >= 3.6
- Install sox on your OS
- Install s3prl: Read doc or
pip install -e ".[all]" - (Optional) Some upstream models require special dependencies. If you encounter error with a specific upstream model, you can look into the
README.mdunder eachupstreamfolder. E.g.,upstream/pase/README.md=
Reference Repositories
- Pytorch, Pytorch.
- Audio, Pytorch.
- Kaldi, Kaldi-ASR.
- Transformers, Hugging Face.
- PyTorch-Kaldi, Mirco Ravanelli.
- fairseq, Facebook AI Research.
- CPC, Facebook AI Research.
- APC, Yu-An Chung.
- VQ-APC, Yu-An Chung.
- NPC, Alexander-H-Liu.
- End-to-end-ASR-Pytorch, Alexander-H-Liu
- Mockingjay, Andy T. Liu.
- ESPnet, Shinji Watanabe
- speech-representations, aws lab
- PASE, Santiago Pascual and Mirco Ravanelli
- LibriMix, Joris Cosentino and Manuel Pariente
License
The majority of S3PRL Toolkit is licensed under the Apache License version 2.0, however all the files authored by Facebook, Inc. (which have explicit copyright statement on the top) are licensed under CC-BY-NC.
Used by
List of papers that used our toolkit (Feel free to add your own paper by making a pull request)
Self-Supervised Pretraining
- Mockingjay: Unsupervised Speech Representation Learning with Deep Bidirectional Transformer Encoders (Liu et al., 2020)
@article{mockingjay, title={Mockingjay: Unsupervised Speech Representation Learning with Deep Bidirectional Transformer Encoders}, ISBN={9781509066315}, url={http://dx.doi.org/10.1109/ICASSP40776.2020.9054458}, DOI={10.1109/icassp40776.2020.9054458}, journal={ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)}, publisher={IEEE}, author={Liu, Andy T. and Yang, Shu-wen and Chi, Po-Han and Hsu, Po-chun and Lee, Hung-yi}, year={2020}, month={May} } - TERA: Self-Supervised Learning of Transformer Encoder Representation for Speech (Liu et al., 2020)
@misc{tera, title={TERA: Self-Supervised Learning of Transformer Encoder Representation for Speech}, author={Andy T. Liu and Shang-Wen Li and Hung-yi Lee}, year={2020}, eprint={2007.06028}, archivePrefix={arXiv}, primaryClass={eess.AS} } - Audio ALBERT: A Lite BERT for Self-supervised Learning of Audio Representation (Chi et al., 2020)
@inproceedings{audio_albert,
    title={Audio ALBERT: A Lite BERT for Self-supervised Learning of Audio Representation},
    author={Po-Han Chi and Pei-Hung Chung and Tsung-Han Wu and Chun-Cheng Hsieh and Shang-Wen Li and Hung-yi Lee},
    year={2020},
    booktitle={SLT 2020},
}
Explanability
- Understanding Self-Attention of Self-Supervised Audio Transformers (Yang et al., 2020)
@inproceedings{understanding_sat,
    author={Shu-wen Yang and Andy T. Liu and Hung-yi Lee},
    title={{Understanding Self-Attention of Self-Supervised Audio Transformers}},
    year=2020,
    booktitle={Proc. Interspeech 2020},
    pages={3785--3789},
    doi={10.21437/Interspeech.2020-2231},
    url={http://dx.doi.org/10.21437/Interspeech.2020-2231}
}
Adversarial Attack
-
Defense for Black-box Attacks on Anti-spoofing Models by Self-Supervised Learning (Wu et al., 2020), code for computing LNSR: utility/observe_lnsr.py
@inproceedings{mockingjay_defense, author={Haibin Wu and Andy T. Liu and Hung-yi Lee}, title={{Defense for Black-Box Attacks on Anti-Spoofing Models by Self-Supervised Learning}}, year=2020, booktitle={Proc. Interspeech 2020}, pages={3780--3784}, doi={10.21437/Interspeech.2020-2026}, url={http://dx.doi.org/10.21437/Interspeech.2020-2026} } -
@misc{asv_ssl,
    title={Adversarial defense for automatic speaker verification by cascaded self-supervised learning models},
    author={Haibin Wu and Xu Li and Andy T. Liu and Zhiyong Wu and Helen Meng and Hung-yi Lee},
    year={2021},
    eprint={2102.07047},
    archivePrefix={arXiv},
    primaryClass={eess.AS}
Voice Conversion
- S2VC: A Framework for Any-to-Any Voice Conversion with Self-Supervised Pretrained Representations (Lin et al., 2021)
@misc{s2vc,
      title={S2VC: A Framework for Any-to-Any Voice Conversion with Self-Supervised Pretrained Representations},
      author={Jheng-hao Lin and Yist Y. Lin and Chung-Ming Chien and Hung-yi Lee},
      year={2021},
      eprint={2104.02901},
      archivePrefix={arXiv},
      primaryClass={eess.AS}
}
Benchmark and Evaluation
-
SUPERB: Speech processing Universal PERformance Benchmark (Yang et al., 2021)
@misc{superb, title={SUPERB: Speech processing Universal PERformance Benchmark}, author={Shu-wen Yang and Po-Han Chi and Yung-Sung Chuang and Cheng-I Jeff Lai and Kushal Lakhotia and Yist Y. Lin and Andy T. Liu and Jiatong Shi and Xuankai Chang and Guan-Ting Lin and Tzu-Hsien Huang and Wei-Cheng Tseng and Ko-tik Lee and Da-Rong Liu and Zili Huang and Shuyan Dong and Shang-Wen Li and Shinji Watanabe and Abdelrahman Mohamed and Hung-yi Lee}, year={2021}, eprint={2105.01051}, archivePrefix={arXiv}, primaryClass={cs.CL} } -
Utilizing Self-supervised Representations for MOS Prediction (Tseng et al., 2021)
@misc{ssr_mos,
    title={Utilizing Self-supervised Representations for MOS Prediction},
    author={Wei-Cheng Tseng and Chien-yu Huang and Wei-Tsung Kao and Yist Y. Lin and Hung-yi Lee},
    year={2021},
    eprint={2104.03017},
    archivePrefix={arXiv},
    primaryClass={eess.AS}
}
}
Citation
If you find this toolkit useful, please consider citing following papers.
- If you use our pre-training scripts, or the downstream tasks considered in TERA and Mockingjay, please consider citing the following:
@misc{tera,
  title={TERA: Self-Supervised Learning of Transformer Encoder Representation for Speech},
  author={Andy T. Liu and Shang-Wen Li and Hung-yi Lee},
  year={2020},
  eprint={2007.06028},
  archivePrefix={arXiv},
  primaryClass={eess.AS}
}
@article{mockingjay,
   title={Mockingjay: Unsupervised Speech Representation Learning with Deep Bidirectional Transformer Encoders},
   ISBN={9781509066315},
   url={http://dx.doi.org/10.1109/ICASSP40776.2020.9054458},
   DOI={10.1109/icassp40776.2020.9054458},
   journal={ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)},
   publisher={IEEE},
   author={Liu, Andy T. and Yang, Shu-wen and Chi, Po-Han and Hsu, Po-chun and Lee, Hung-yi},
   year={2020},
   month={May}
}
- If you use our organized upstream interface and features, or the SUPERB downstream benchmark, please consider citing the following:
@inproceedings{yang21c_interspeech,
  author={Shu-wen Yang and Po-Han Chi and Yung-Sung Chuang and Cheng-I Jeff Lai and Kushal Lakhotia and Yist Y. Lin and Andy T. Liu and Jiatong Shi and Xuankai Chang and Guan-Ting Lin and Tzu-Hsien Huang and Wei-Cheng Tseng and Ko-tik Lee and Da-Rong Liu and Zili Huang and Shuyan Dong and Shang-Wen Li and Shinji Watanabe and Abdelrahman Mohamed and Hung-yi Lee},
  title={{SUPERB: Speech Processing Universal PERformance Benchmark}},
  year=2021,
  booktitle={Proc. Interspeech 2021},
  pages={1194--1198},
  doi={10.21437/Interspeech.2021-1775}
}
@article{yang2024large,
  title={A Large-Scale Evaluation of Speech Foundation Models},
  author={Yang, Shu-wen and Chang, Heng-Jui and Huang, Zili and Liu, Andy T and Lai, Cheng-I and Wu, Haibin and Shi, Jiatong and Chang, Xuankai and Tsai, Hsiang-Sheng and Huang, Wen-Chin and others},
  journal={IEEE/ACM Transactions on Audio, Speech, and Language Processing},
  year={2024},
  publisher={IEEE}
}
1 maintainer

Metadata
1 maintainer
Release files for espnet-s3prl 2026.5.14
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| espnet_s3prl-2026.5.14.tar.gz | 645.8 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| espnet_s3prl-2026.5.14-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.5 MB
Release files / espnet_s3prl-2026.5.14.tar.gz
| Download URL | espnet_s3prl-2026.5.14.tar.gz |
|---|---|
| Size | 645.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cb281306d1c675477df26b6aa98a1b48b9053df6cbda5a580bdc0335c60e6130
|
|
BLAKE2b-256 checksum How to use checksums |
a28d4819ba54035257568f40239e0252c9ff17eb9f9b97bf36c0691e6315449e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 2, 2026.
Transparency logRelease files / espnet_s3prl-2026.5.14-py3-none-any.whl
| Download URL | espnet_s3prl-2026.5.14-py3-none-any.whl |
|---|---|
| Size | 882.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0aa2ce8ec6e88423f4ca8c9761977a439d93e004ef90fda21c4285a0423b31a3
|
|
BLAKE2b-256 checksum How to use checksums |
1f7102bf907ff39d16d70cc84072fbeb64fd8db9e40240b5ab01652c895c1fa4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 2, 2026.
Transparency logSecurity for espnet-s3prl 2026.5.14
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for espnet_s3prl-2026.5.14.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 2, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.













