
eurlex-builder


Build research-ready datasets from EU legislative data — recitals, articles, points, and the network between them.
eurlex-builder is a configurable Python pipeline that turns the EUR-Lex / Cellar corpus into provision-level Parquet tables for quantitative research. It fetches every directive, regulation, decision, or communication you ask for, extracts text at the granularity you need (whole article, numbered paragraph, or lettered point), collects metadata + inter-document relations, and ships the result as one DuckDB file plus four Parquet tables.
It is, to our knowledge, the first open-source tool to extract EU legislative text at configurable sub-article granularity across EUR-Lex's heterogeneous document formats — from modern HTML to 1970s text-only pages to scanned PDFs.
The package accompanies Seidl and Kosti (2026), "Mapping Europe's Digital Acquis: A Granular History of EU Digital Policymaking" (preprint forthcoming on SocArXiv).
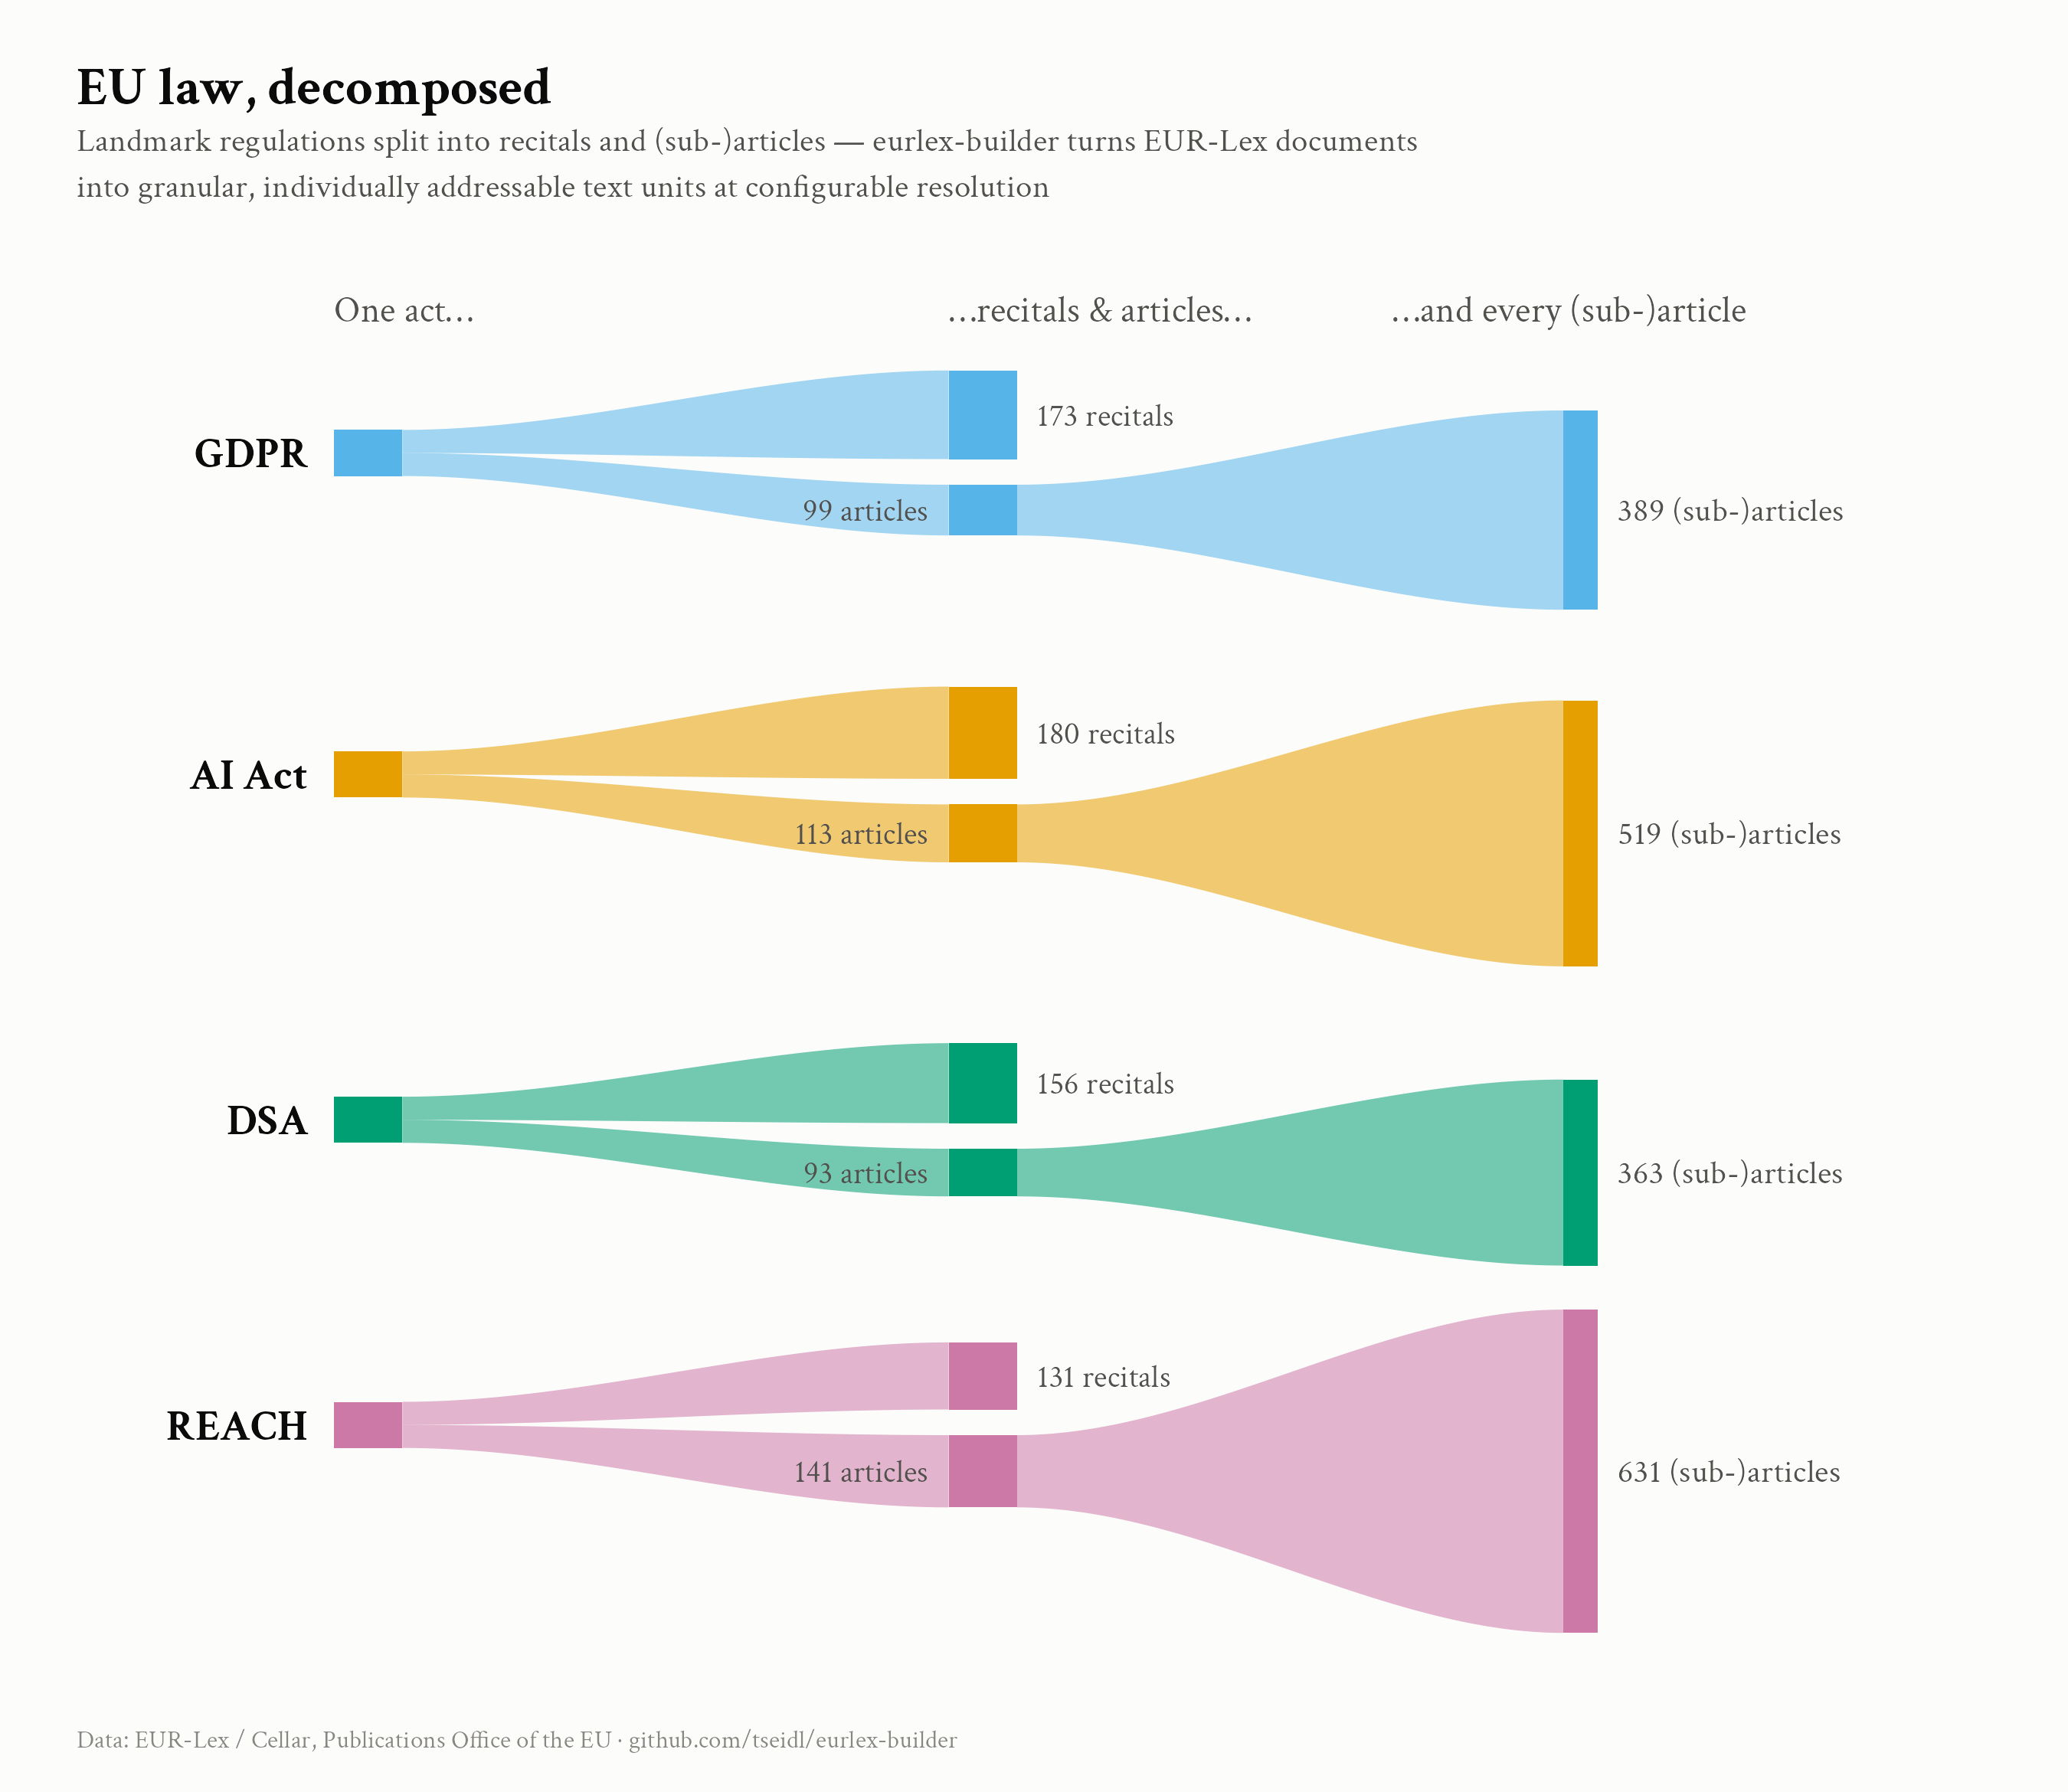
Highlights
- Sub-article granularity. One config switch chooses whether each article is one row, one row per numbered paragraph (
Art. 5(1)), or one row per lettered point (Art. 5(1)(a)) — following the EU Joint Practical Guide. - Six HTML structures + PDF fallback. Automatic detection across EUR-Lex's HTML eras (Standard OJ, Manual CSS, class-based, text-only, consolidated-norm, classless) with Docling/pymupdf for older docs that have no machine-readable HTML.
- Two query modes. Fixed (give us a list of CELEX IDs / procedure numbers) or descriptive (date range + doc types + optional EuroVoc keyword filter).
- Inter-document relations. Citations, amendments, legal basis, repeals, consolidations — all in one table for network analysis.
- Guarded translation built in. Non-English-only documents are translated via pinned Helsinki-NLP Opus-MT revisions, separately at document level (
works.full_text) and per-unit (text_units.text_translated). Token-bounded retries and quality guards reject degenerate output without replacing the source text. - Reproducible + resumable. A single YAML defines the dataset; a checkpoint table in DuckDB makes the pipeline restart-safe and incremental.
- Auditable runs. DuckDB stores every validated config, its SHA-256 hash, runtime versions, and completion status;
validatechecks structural integrity without modifying the database. - Parallel mode. Multi-threaded fetching with
parallel: true; sequential writes keep DuckDB contention-free.
Full-text retrieval works for every document type; granular extraction does not. Whatever the pipeline reaches,
works.full_textis fetched and stored — the caveats here concern the decomposition into text units. Regulations, directives, and decisions are validated against official documents and are what the accompanying paper is built on. Communications extract well but have known gaps; proposals (PC) and staff working documents (SC) lose units to modern templates, and case law (sector 6) yields zero text units — silently (and is reachable only in fixed mode). Read Verification status before running anything outside the validated three.
Quick start
pip install "eurlex-builder[all]"
Create a config.yaml. You can either request specific acts by CELEX ID (fixed mode) or search by date range and document type (descriptive mode):
Fixed mode — specific acts:
metadata:
  project_name: "GDPR + AI Act"

data:
  mode: "fixed"
  celex_ids:
    - "32016R0679"    # GDPR
    - "32024R1689"    # AI Act

processing:
  text_extraction:
    article_granularity: paragraph

output:
  output_directory: "./output"
Descriptive mode — all acts matching a search:
metadata:
  project_name: "EU digital regulations 2020–2025"

data:
  mode: "descriptive"
  document_types:
    - "regulation"
    - "directive"
  start_date: 2020-01-01
  end_date: 2025-12-31
  filter_keywords:           # optional EuroVoc filter
    - "artificial intelligence"
    - "data protection"

processing:
  text_extraction:
    article_granularity: paragraph
  parallel: true
  max_workers: 8

output:
  output_directory: "./output"
Run:
eurlex-builder run config.yaml
You'll get output/eurlex_builder.duckdb plus four Parquet files: works.parquet, text_units.parquet, relations.parquet, eurovoc.parquet. The database filename is always eurlex_builder.duckdb — it's the output_directory that separates projects, so give each config its own (e.g. ./output/digital-regs).
import polars as pl
text_units = pl.read_parquet("output/text_units.parquet")

# All paragraph-1 rows of GDPR Article 5
text_units.filter(
    (pl.col("celex_id") == "32016R0679")
    & (pl.col("type") == "article")
    & (pl.col("number") == "5")
)
Why eurlex-builder
| What it is | Why we built our own | |
|---|---|---|
| {eurlex} (R) | Document retrieval | Handles retrieval but not structured extraction or translation; we provide both at multiple granularities |
| EUPLEX | Complexity indicators | Publishes derived metrics (readability, word counts) without the underlying text |
| EUPROPS | Manually curated text | One-off snapshot; not re-runnable or extendable to new time windows / doc types / granularities |
| eurlex-builder | Configurable pipeline | Reproducible, provision-level output with structured extraction, translation, and inter-document relations — ready for NLP, classification, and network analysis |
Installation
Requires Python 3.11+.
# Core only (HTML extraction + parquet output)
pip install eurlex-builder

# With PDF support (Docling + pymupdf)
pip install "eurlex-builder[pdf]"

# With translation (Opus-MT via Hugging Face)
pip install "eurlex-builder[translate]"

# Everything (recommended for production runs)
pip install "eurlex-builder[all]"
For development, install from a checkout instead:
git clone https://github.com/tseidl/eurlex-builder.git
cd eurlex-builder
python -m venv .venv && source .venv/bin/activate

# Core only (HTML extraction + parquet output)
pip install -e .

# With PDF support (Docling + pymupdf)
pip install -e ".[pdf]"

# With translation (Opus-MT via Hugging Face)
pip install -e ".[translate]"

# Everything (recommended for production runs)
pip install -e ".[all]"

# Plus dev tools (pytest)
pip install -e ".[dev]"
Configuration reference
A single YAML file defines the dataset. Only the data section is required; everything else has sensible defaults. Unknown keys and malformed CELEX IDs are rejected rather than silently ignored.
metadata — stamped onto the output, not used for filtering
| Field | Type | Default | Description |
|---|---|---|---|
project_name |
string | "eurlex-builder Dataset" |
Embedded in output metadata |
author |
string | "" |
Author name |
description |
string | "A dataset built with eurlex-builder." |
Free-text description |
version |
string | "1.0" |
Dataset version |
data (fixed mode) — specific documents
Provide CELEX IDs or interinstitutional procedure numbers. At least one is required.
data:
  mode: "fixed"
  celex_ids:
    - "32016R0679"
  procedure_numbers:
    - "2021/0106"      # resolved to CELEX IDs via SPARQL
| Field | Type | Default | Description |
|---|---|---|---|
mode |
"fixed" |
— | Required |
celex_ids |
list of strings | [] |
CELEX identifiers |
procedure_numbers |
list of strings | [] |
Interinstitutional procedure refs (e.g. "2021/0106") |
data (descriptive mode) — search by date / type / keyword
data:
  mode: "descriptive"
  document_types:
    - "regulation"
    - "directive"
    - "decision"
    - "communication"
  start_date: 1979-01-01
  end_date: 2026-04-30
  filter_keywords:
    - "artificial intelligence"
    - "digital"
  include_corrigenda: false
  include_consolidated_texts: false
| Field | Type | Default | Description |
|---|---|---|---|
mode |
"descriptive" |
— | Required |
document_types |
list of strings | — | Required. At least one. Mapped to CELEX type codes (regulation→R, directive→L, decision→D, communication→DC, proposal→PC, staff working document→SC) |
start_date |
date | — | Required (YYYY-MM-DD) |
end_date |
date | — | Required, must be after start_date |
filter_keywords |
list of strings | [] |
EuroVoc keyword filter. Empty = no filter; no matched or accepted concepts stops discovery with an error |
include_corrigenda |
bool | false |
Include corrigenda |
include_consolidated_texts |
bool | false |
Include consolidated texts (CELEX sector 0) |
processing.text_extraction — structural extraction + granularity
| Field | Type | Default | Description |
|---|---|---|---|
include_recitals |
bool | true |
Extract recitals (preamble "whereas" clauses) |
include_articles |
bool | true |
Extract articles (operative provisions) |
include_annexes |
bool | true |
Extract annexes |
strip_boilerplate |
bool | true |
Strip signature blocks ("Done at Brussels…") and binding clauses from the last article |
store_raw_html |
bool | false |
Store decoded source markup in works.full_text_html, using its declared encoding without rewriting the HTML. Substantially increases DB size; useful for debugging |
article_granularity |
"article" | "paragraph" | "point" |
"article" |
One row per article (default), per numbered paragraph, or per lettered point. See Granularity below |
processing.translation — Opus-MT for non-English docs
| Field | Type | Default | Description |
|---|---|---|---|
translate_full_text |
bool | true |
Translate works.full_text (one big blob per doc) |
translate_text_units |
bool | true |
Translate text_units.text (per recital/article/paragraph) |
max_full_text_chars |
int | 100000 |
Skip full_text translation above this length. 0 disables the cap. text_units are still translated |
processing (top-level) — parallel, relations, EuroVoc
| Field | Type | Default | Description |
|---|---|---|---|
automated_mode |
bool | false |
Skip interactive EuroVoc keyword review |
parallel |
bool | false |
Multi-threaded fetching |
max_workers |
int (1–16) | 4 |
Number of parallel threads. Four is the conservative default because each PDF-processing thread owns a Docling worker. HTML-dominant runs may benefit from 8; benchmark on the target machine rather than assuming more workers are faster |
include_relations |
bool | true |
Fetch + store inter-document relations |
include_eurovoc |
bool | false |
Include EuroVoc descriptors in metadata fetch (also via the enrich command) |
fetch_original_recitals_for_consolidated |
bool | true |
Consolidated texts: fetch recitals from the original act |
fetch_original_relations_for_consolidated |
bool | true |
Consolidated texts: merge relations from original |
output
| Field | Type | Default | Description |
|---|---|---|---|
formats |
list | ["parquet"] |
"parquet" and/or "csv". Parquet is recommended |
output_directory |
string | "./output" |
Output path. Created if missing |
Granularity
EU drafting convention recognises three operative levels (Joint Practical Guide of the Council, Commission, and Parliament):
Article 5
  Paragraph 5(1)
    Point 5(1)(a)
    Point 5(1)(b)
eurlex-builder lets you emit each as a row:
article_granularity |
Row schema | Example: GDPR Art. 3 |
|---|---|---|
"article" (default) |
One row per article. Reproduces the conventional act-level view. paragraph_num and point_letter are NULL |
1 row |
"paragraph" |
One row per numbered paragraph (1., 2., 1a., …). paragraph_num set; point_letter NULL |
3 rows |
"point" |
One row per lettered point ((a), (b), …) when present, else per paragraph. Both columns set when applicable |
5 rows (paragraphs 1 and 3 → 1 row each; paragraph 2 → stem + (a) + (b)) |
A short preamble before paragraph 1. gets its own row with paragraph_num = "0". Articles in amending acts (lists of edits to other regulations) are flagged subtype = 'amendment_item'; substantive replacement text within them stays untagged so downstream classifiers can keep it.
Recitals are emitted identically across all granularity settings.
For legacy HTML, numbered table rows are accepted as recitals only when they
form a credible drafting sequence. Nested numbered tables remain inside their
parent recital, embedded sibling lists are excluded only when the main sequence
resumes, and a table continuation is joined to preceding paragraph recitals
only when every earlier number is present. For legacy PDFs, a
page-break fragment such as (1) of Regulation ... remains part of the active
recital instead of starting a false numbered sequence.
CLI commands
eurlex-builder run <config.yaml>
Run the pipeline.
| Argument | Description |
|---|---|
config |
YAML config file |
--fresh |
Clear checkpoints for the selected documents and re-process them |
--retry-failed |
Re-attempt previously failed docs |
--limit N |
Process only the first N remaining documents; later runs resume the rest |
The pipeline resumes by default, skipping checkpointed docs. After an
interrupted --fresh rebuild, re-run without --fresh to resume the new
rebuild rather than clearing its completed checkpoints again.
--limit is intended for canary runs and cannot be combined with --fresh.
If any document attempted in this invocation fails, the command exits with
status 1 after saving and exporting successful results. Its run manifest
records complete_with_failures. Historical failures outside the attempted
selection do not affect this exit status. Use --retry-failed to retry failures.
A Python call to Pipeline.run() returns RunResult(processed, failed) with
counts for the invocation; discovery and other fatal errors still raise.
Keyword filtering stops with an error if no EuroVoc concepts match or all
matches are rejected. Set filter_keywords: [] explicitly for an unfiltered
date/type search. Failed selection leaves existing checkpoints intact.
eurlex-builder translate <db>
Translate non-English content. Resumable; skips already-translated rows.
| Argument | Description |
|---|---|
db |
Path to the DuckDB file |
--max-full-text-chars |
Cap for works.full_text translation (default 100000) |
--no-full-text |
Skip works.full_text phase |
--no-text-units |
Skip text_units.text phase |
--retry-rejected |
Explicitly retry unchanged rows previously rejected by the translation quality policy |
Translation is interruption-safe at row level. Rejected outputs remain in the
source language and are recorded in _translation_failures; an ordinary resume
skips unchanged current-policy rejections, while --retry-rejected tries them
again. A source-text or policy-version change invalidates the corresponding
ledger entry automatically.
eurlex-builder enrich <db>
Add post-hoc metadata via SPARQL — no re-fetching content. Adds entry-into-force date, ELI, author institutions, subject matter, procedure type/reference/legal basis, EuroVoc descriptors, and repeal relations.
| Argument | Description |
|---|---|
db |
Path to the DuckDB file |
--select |
Categories: metadata, relations, eurovoc. Default: all |
--parallel |
Fetch SPARQL queries in parallel |
--max-workers |
Number of parallel workers (default 4) |
--force |
Re-enrich already-enriched docs |
Completion is tracked separately for metadata, relations, and eurovoc, so categories can be run independently and resumed later. A successful response includes category completion sentinels; only then can an empty refresh remove stale values. Databases enriched by older releases are migrated to all-category checkpoints from enriched_at instead of unexpectedly re-fetching every work.
eurlex-builder status <db>
Print checkpoint summary (processed / failed counts + failure reasons).
eurlex-builder validate <db>
Run read-only integrity checks for checkpoint/work consistency, orphaned rows, stable unit identity, duplicate keys/order, translated-fallback markers, and degenerate stored translations. The command exits non-zero when an error is found and reports expected data gaps and recorded translation rejections as warnings.
Output schema
| File | Description |
|---|---|
eurlex_builder.duckdb |
Working database with data tables, checkpoints, and run manifests |
works.parquet |
One row per document |
text_units.parquet |
One row per recital / article (or paragraph / point at sub-article granularity) / annex |
relations.parquet |
One row per inter-document relation |
eurovoc.parquet |
EuroVoc descriptors per document (populated by enrich) |
pipeline.log |
Full run log |
missing_content.tsv |
Docs with no text in any language (kept in works as empty rows) |
non_english_content.tsv |
Docs with non-English content (candidates for translation) |
works — one row per document
| Column | Type | Description |
|---|---|---|
celex_id |
VARCHAR PK | CELEX identifier (e.g. 32016R0679) |
title |
VARCHAR | English title from SPARQL; falls back to another language when no English title exists |
date_adopted |
DATE | Document adoption date |
document_type |
VARCHAR | Derived from CELEX type code |
language |
VARCHAR | Language of fetched content; NULL when no content could be fetched |
full_text |
VARCHAR | Full document text (translated to English if non-English source) |
full_text_original |
VARCHAR | Original-language text (non-English docs only) |
full_text_html |
VARCHAR | Decoded source HTML markup (only if store_raw_html: true); not an archive of exact response bytes |
content_source |
VARCHAR | Provenance tag (cellar_html_eng, cellar_pdf_fra, …). Suffixes record fallbacks — see below |
date_entry_into_force |
DATE | Populated by enrich |
date_end_of_validity |
DATE | Populated by enrich; 9999-12-31 if still in force |
is_in_force |
BOOLEAN | Populated by enrich |
eli |
VARCHAR | European Legislation Identifier URI |
author |
VARCHAR | Author institution(s) (e.g. EP; CONSIL) |
subject_matter |
VARCHAR | EU subject matter classification(s) |
procedure_type |
VARCHAR | e.g. OLP for ordinary legislative |
procedure_reference |
VARCHAR | e.g. 2012/0011/COD |
procedure_legal_basis |
VARCHAR | Treaty legal basis |
enriched_at |
TIMESTAMP | Most recent enrichment timestamp; category completion is tracked internally in _enrichment_checkpoint |
content_source suffixes. The base tag names the format and language that
supplied the text. Three suffixes record that a fallback path was taken:
__pdf_<lang>_fallback_<structures>— corroborated units of the named structural types were added from a same-language PDF while the HTML text was retained.__pymupdf_<reason>— degraded PDF extraction after a Docling timeout, partial result, crash, conversion error, oversize guard, or empty result.__translated— translate-before-extract output (see the FAQ).
text_units — one row per recital / article / paragraph / point / annex
| Column | Type | Description |
|---|---|---|
id |
INTEGER PK | Internal surrogate key; may change after re-extraction |
celex_id |
VARCHAR FK | Parent document |
unit_order |
INTEGER | Stable one-based order within a document |
unit_key |
VARCHAR | Deterministic key built from CELEX and structural coordinates; duplicate coordinates receive an occurrence suffix |
type |
VARCHAR | recital, article, annex, paragraph (COMs, proposals, staff working documents), footnote, body (fallback) |
subtype |
VARCHAR | "subheading" (short recitals), "table" (COM table paragraphs), "amendment_item" (mechanical edits in amending acts), or NULL |
number |
VARCHAR | Unit number (e.g. "1", "IV", "A") |
paragraph_num |
VARCHAR | "1", "1a", "2", … when article_granularity ≠ "article"; "0" for preamble before paragraph 1. NULL otherwise |
subparagraph_num |
VARCHAR | One-based subparagraph coordinate when point granularity emits structurally separate unnumbered subparagraphs |
point_letter |
VARCHAR | "a", "b", … (or "aa" for amendment-inserted points) when article_granularity = "point". NULL otherwise |
title |
VARCHAR | Article or annex title |
text |
VARCHAR | Extracted text |
text_translated |
VARCHAR | English translation (populated by translate) |
relations — one row per inter-document tie
| Column | Type | Description |
|---|---|---|
id |
INTEGER PK | Auto-increment |
source_celex |
VARCHAR FK | Source CELEX ID |
target_celex |
VARCHAR | Target CELEX ID |
relation_type |
VARCHAR | cites, amends, adopts, based_on, proposes_to_amend, consolidates, repeals, implicitly_repeals |
dataset_runs — reproducibility manifest stored in DuckDB
Each pipeline invocation records its validated configuration JSON and SHA-256 hash, package and Python versions, installed extraction/translation dependency versions, Git revision and dirty-worktree flag when run from a checkout, timestamps, and final status. The pinned translation-model revisions live in the recorded source revision. Run manifests remain in DuckDB and are not duplicated into the four analytical Parquet tables.
FAQ
How do I speed up large runs?
Set parallel: true. The default max_workers: 4 is what the full corpus run
actually used, and it is the right starting point for a mixed HTML/PDF corpus
because each PDF-processing thread owns a Docling worker. Modern HTML-heavy
runs are mainly limited by Cellar requests and may benefit from 8. More workers
help only until CPU, memory, or the shared Cellar request limit is saturated;
16 workers can be slower on a memory-constrained machine. Benchmark on the
target machine rather than assuming more workers are faster. DuckDB writes
remain sequential, so workers do not contend for the database.
For a clean rebuild, use a new output directory and let checkpoints make it
restart-safe. Do not pass --fresh again after an interruption. Source PDFs
and Docling intermediates are not cached, so changing only the output directory
does not reuse extraction from an older dataset.
What's the difference between paragraph and point granularity?
paragraph splits each article on its numbered paragraphs (1., 2., 1a.). Lettered sub-points stay inside the parent paragraph row.
point goes one level deeper: when a paragraph contains lettered points like GDPR Art. 6(1)(a)…(f), each gets its own row. Point markers are validated against the drafting sequence — amendment-inserted points like (aa) get their own rows, while roman sub-points (i), (ii) stay inside their parent point. Articles without lettered points behave identically under either setting.
HTML element boundaries may also expose formally separate unnumbered subparagraphs at point granularity; these receive subparagraph_num. PDF line wrapping alone never creates subparagraph rows.
Use paragraph when each numbered paragraph encodes one obligation and that's the analytical unit you want. Use point when paragraphs sometimes serve as umbrella stems ("processing shall be lawful only if at least one applies:") with the substantive content entirely in the points.
Can I compare the same law across languages?
Yes. The optional multilingual command uses the laws in an existing dataset
to create a separate dataset of official language versions. Shared EUR-Lex HTML
identifiers pair corresponding articles and numbered paragraphs, so you can
compare the same passage side by side across languages.
eurlex-builder multilingual output/eurlex_builder.duckdb --languages eng deu fra
You can select any of the 24 official EU languages; English, German and French are just examples. The original dataset and usual workflow stay unchanged. Missing or unsupported HTML versions are reported, and some consolidated texts support articles only. See the multilingual extraction guide for output details and an example joining matching passages.
Is the data reproducible?
At the analytical level, with caveats. A clean Git revision, validated config,
recorded dependency versions, and unchanged source bytes should reproduce the
same structural content. Use unit_key, not the internal integer id, as the
stable text-unit identity. Important limits are:
- EUR-Lex content can change post-publication (corrigenda, consolidation updates). Re-running later may pick up newer versions.
- Docling conversion deadlines are wall-clock based. Machine load can decide whether a difficult PDF completes or receives a queryable PyMuPDF fallback suffix.
- Parallel completion order can change internal surrogate IDs even when
unit_keyand content are identical.
How do I extend an existing run to newer legislation?
Update end_date in the YAML and re-run without --fresh. The checkpoint table will skip the docs already processed and only fetch the new ones. Run eurlex-builder enrich afterwards to fill enrichment columns for the new docs.
How do I make a clean dataset after extraction changes?
Use a new output_directory for the strongest reproducibility boundary, then
run the current config normally. An empty database is already a fresh run, so
--fresh is only needed when deliberately rebuilding the selected documents in
an existing database. If that rebuild is interrupted, resume without --fresh.
Commit the extraction changes before starting so the run manifest records a
clean, exact Git revision.
Raw HTML is retained only when store_raw_html: true; downloaded PDFs and
Docling's intermediate output are not cached. A clean rebuild therefore
redownloads source documents and re-runs PDF extraction. This is slower, but it
ensures every exported row was produced by the same package version and config.
Run eurlex-builder validate <db> after the build and enrichment steps.
For the one-off migration from the pre-isolation PDF extractor, follow PDF isolation migration and repair. It records the affected CELEX IDs, makes incomplete repair state queryable, and prevents a later unavailable source response from silently preserving suspect PDF output.
What happens to documents the pipeline can't fetch?
They stay in works as rows with empty text columns and an entry in missing_content.tsv. This keeps the dataset transparent — a missing row is worse than a row with NAs, because it silently drops data. Transient request and SPARQL failures are checkpointed as failed instead, so --retry-failed can recover them. If content that was fetched previously later becomes unavailable, the stored content is preserved.
Why DuckDB + Parquet rather than SQLite?
DuckDB writes columnar Parquet natively (no glue code), reads faster than SQLite for the analytical queries researchers actually run, and has direct interop with Polars / Arrow / R. The DuckDB file also acts as a single-file checkpoint store so the pipeline is restart-safe.
How do I cite this in a paper?
See Citation below. If your paper uses the dataset rather than the pipeline directly, please also reference the source: EUR-Lex / Cellar, Publications Office of the European Union.
Can I add a custom data source / extractor?
The sequential extraction core accepts custom DataSource, TextExtractor, Store, and Checkpoint implementations through the protocols in src/eurlex_builder/protocols.py. The default wiring is CellarSource + HtmlExtractor + PdfExtractor + DuckDBStore. Parallel source creation, built-in translation, run manifests, and detailed statistics currently assume the default components; custom implementations should use sequential mode or provide equivalent methods.
Why does descriptive mode miss some documents that the {eurlex} R package finds?
Descriptive mode filters by CELEX type code (D, R, L) and sector. The {eurlex} R package filters by work_has_resource-type URIs, a partially overlapping semantic classification. Documents like merger decisions (CELEX type M), budget acts (B), and sector-5 Parliament documents show up in {eurlex} but not in a CELEX-type query. These are absent by design, not a bug. See Roadmap for planned resource-type support.
Why does a --fresh re-run produce slightly different row counts for PDF-extracted documents?
Docling's PDF layout parser can segment paragraphs differently across versions. Recital and article counts may vary slightly for PDF-sourced documents even when the text content is the same. This is a Docling version sensitivity, not a pipeline bug.
What is the translate-before-extract fallback?
The legislative PDF extractor uses English-only markers (Whereas:, HAS ADOPTED THIS REGULATION:, ANNEX). For non-English PDFs where these markers don't fire, the pipeline translates the Docling markdown to English via Opus-MT and re-parses from there. This fires when a requested structure is conspicuously missing, including fewer than three requested recitals or no requested articles. The translated parse is adopted only when at least one requested structure count improves and none regress. Translation is all-or-nothing under the same quality guards used by the standalone command. Affected rows are marked with content_source ending in __translated and have text_translated pre-filled. The alternative — adding native markers for every EU language — was rejected as a maintenance burden.
Verification status
The configuration accepts six document types plus raw CELEX IDs, but they are not equally validated. A smoke test (July 2026, v0.1.0, 17 documents spanning 1962–2021; full report in docs/doc-type-verification.md) established:
| Document type | Status |
|---|---|
| Regulations, directives, decisions | Validated. Repeated full-corpus runs with structural QA against official documents. This is the path the accompanying paper is built on. |
| Communications (DC) | Verified for single-stream HTML across eras (88–98% text coverage). Known gaps: HTTP-300 annex streams are not merged into the act stream, and long archival PDFs can fall back to coarse page-scale chunks after a Docling timeout. |
| Proposals (PC) | Older samples (1995, 1998) extract nearly completely. Modern legislative-proposal templates (DSA, AI Act era) are broken: recitals, article headings, and points use CSS classes the COM extractor does not handle, and separate annex streams are dropped. |
| Staff working documents (SC) | Older single-stream samples extract at ~97%. Modern multipart impact assessments are broken: the Numbered-Para body class is skipped and the second HTML part is discarded entirely. |
| Case law (sector 6: CJ/CC/CO) | Unsupported. Fixed mode fetches metadata, relations, and full text, but produces zero text units — silently, with exit 0. Descriptive mode cannot discover sector-6 documents at all. |
eurlex-builder validate flags the silent-failure cases: a work with stored full text but zero text units is an error (exit 1), and a document type outside the supported extraction set is a warning; the pipeline also logs a warning at run time when a document has no extractor branch. What validation still cannot measure is extraction coverage — a database whose modern proposals silently lost their recitals to unhandled CSS classes passes, because no source-text baseline is stored. Do not read a passing validation as evidence that an unverified document type extracted completely.
Architecture
config.yaml (Pydantic-validated)
  ├─ EuroVoc keyword resolution (SPARQL, optional interactive review)
  ├─ Procedure number → CELEX resolution (SPARQL)
  ├─ CELEX ID discovery (SPARQL descriptive query)
  ├─ Per-document processing (parallel or sequential):
  │     metadata fetch         — SPARQL: title, date, relations
  │     content fetch           — REST: XHTML / HTML / PDF (six-language fallback)
  │     text extraction         — lxml: 6 HTML structures + paragraph splitting
  │                               PDF: persistent isolated Docling workers, with
  │                               per-document hard timeouts and pymupdf fallback
  │     translate-before-extract — Opus-MT fallback when a non-English legislative
  │                                PDF misses requested structures (English-only
  │                                markers like "Whereas:" wouldn't fire on a French
  │                                or German PDF). Translates the Docling markdown
  │                                and re-parses from English.
  │     storage                 — DuckDB: works, text_units, relations, checkpoint
  ├─ Translation                — Opus-MT, sequential post-processing
  ├─ Enrichment                 — SPARQL: dates, ELI, procedure, EuroVoc, repeals
  ├─ Export                     — Polars → Parquet/CSV
  └─ Reports                    — missing-content TSV, extraction stats
More on how the six HTML structures are detected and parsed: extraction approach.
All data sourced through official EU APIs:
- SPARQL:
https://publications.europa.eu/webapi/rdf/sparql - REST:
https://publications.europa.eu/resource/celex/
No scraping.
Citation
If you use this package, please cite the accompanying paper and the software:
@article{seidl_kosti_2026,
  author  = {Seidl, Timo and Kosti, Nir},
  title   = {Mapping Europe's Digital Acquis: A Granular History of EU Digital Policymaking},
  year    = {2026},
  note    = {Working paper, preprint forthcoming on SocArXiv}
}

@software{eurlex_builder,
  author  = {Seidl, Timo},
  title   = {eurlex-builder: a configurable Python pipeline for EU legislative datasets},
  year    = {2026},
  url     = {https://github.com/tseidl/eurlex-builder},
  doi     = {10.5281/zenodo.21496963}
}
The DOI above is the Zenodo concept DOI, which always points to the latest release. For reproducibility, cite the version DOI of the release you actually used (listed on the Zenodo record) and state the version number. See also CITATION.cff.
Authors
- Timo Seidl — Assistant Professor, Technical University of Munich
- Claude (Anthropic) — Co-author (software design and implementation). Built with Claude Code.
Acknowledgments
- Sebastian Rein (eulex-build) for the initial impetus, the YAML-driven configuration architecture, the fixed-vs-descriptive query mode design, EuroVoc keyword filtering, and the structural-decomposition target schema (recitals / articles / annexes + inter-document relations). The package builds on the foundation of his MA thesis on EU legislative data extraction (TUM, 2026).
- The maintainers of EUR-Lex / Cellar, Docling, Helsinki-NLP Opus-MT, DuckDB, and Polars.
Roadmap
- Discovery by resource-type, not just CELEX-type. Today's descriptive mode filters by CELEX type code (D, R, L) + sector. EUR-Lex also exposes
work_has_resource-typeURIs (DEC,DEC_IMPL,DEC_DEL,REG_FINANC, …) which form a semantic classification overlapping but not identical to the CELEX letter. Addingtype_basis: celex | resource_type | bothto the YAML — with explicit per-doc-typeresource_typeslists — would let researchers opt into broader sets (e.g. merger decisions with CELEX-typeM, budget decisions withB, framework decisions, joint decisions). Default stays CELEX so existing configs reproduce the same corpus. - Modern COM-template support. The July 2026 smoke test (see Verification status) found that current proposal and impact-assessment templates use CSS classes the COM extractor skips (
li ManualConsidrantrecitals,Titrearticlearticle headings,li Point*,li Numbered-Para), and that HTTP-300 multipart representations are truncated to the first stream (annexes and part-2 files are never fetched). Fixing both would make DSA/AI-Act-era proposals and impact assessments extractable. - Case-law extraction (sector 6). CJ/CC/CO documents currently map to
unknownand yield zero text units. Judgments have their own stable structure (grounds, decision on costs, operative part) that a dedicated extractor could target; descriptive mode would also need case-law entries in thedocument_typesmapping. - Dataset linkage layer. Left-join helpers to enrich our
workstable with EUPROPS (manually curated text resource), EUPLEX (complexity indicators), and EUPOL (policy domain coding) via CELEX ID — combining their derived columns with our structured text for the same acts. - Pittsburgh Archive fallback (Archive of European Integration) as a secondary content source for documents that EUR-Lex cannot serve. The Pittsburgh archive holds digitised early-period European Community materials (1950s–1990s) that occasionally fill EUR-Lex gaps.
- Gated OCR/VLM fallback for the residual failure set. Keep OCR disabled by default and consider it only when official HTML is absent or low-information and Docling/PyMuPDF fails to recover the requested structure. Start with a bounded canary, record model/version/input/output hashes and cost, emit faithful Markdown, and accept it only when the existing deterministic parser gains a requested structure without regressions. Benchmark managed Mistral OCR against local GLM-OCR before selecting a backend.
- Incremental update mode — delta runs that fetch only acts adopted since the last completed run.
License
MIT
1 maintainer

Release files for eurlex-builder 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| eurlex_builder-0.2.0.tar.gz | 200.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| eurlex_builder-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 321.4 kB
Release files / eurlex_builder-0.2.0.tar.gz
| Download URL | eurlex_builder-0.2.0.tar.gz |
|---|---|
| Size | 200.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f50688e16ea6a0eaf8e364c8d05c219e4760d0b4ba8e9370438fecb7f4144779
|
|
BLAKE2b-256 checksum How to use checksums |
28b87dd7f28e526266a9fbee1e7e838d630f54d607cd4c63851781d669e9879b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 6, 2026.
Transparency logRelease files / eurlex_builder-0.2.0-py3-none-any.whl
| Download URL | eurlex_builder-0.2.0-py3-none-any.whl |
|---|---|
| Size | 121.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
eee00f65de4eff3875d9e0f2d465d4d8eeba72ac8a61f73c18c518e20914b78c
|
|
BLAKE2b-256 checksum How to use checksums |
f9f2282885546e2b058b2fe10e3aab426c2bfbca96e1779b9c62c57adbbfb1a2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 6, 2026.
Transparency log













