
EvalKit



Find out which model gets your task right, and whether its answers stick to the source.
EvalKit runs your own cases across Claude and OpenAI models and reports, side by side, how often each model is correct, whether every claim it makes is supported by the sentences it cites, and what that costs, with confidence intervals and two judges from different model families.
Live demo · Benchmark report · PyPI · Quickstart · Guides · Report a bug
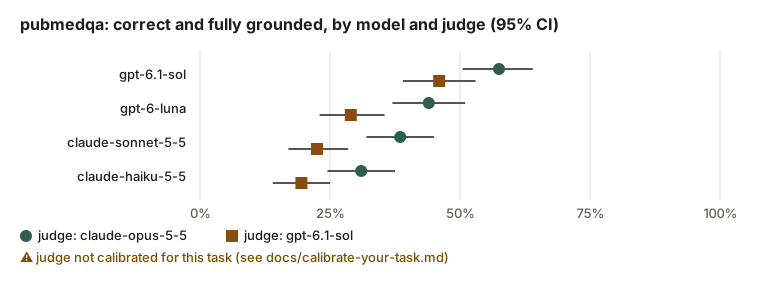
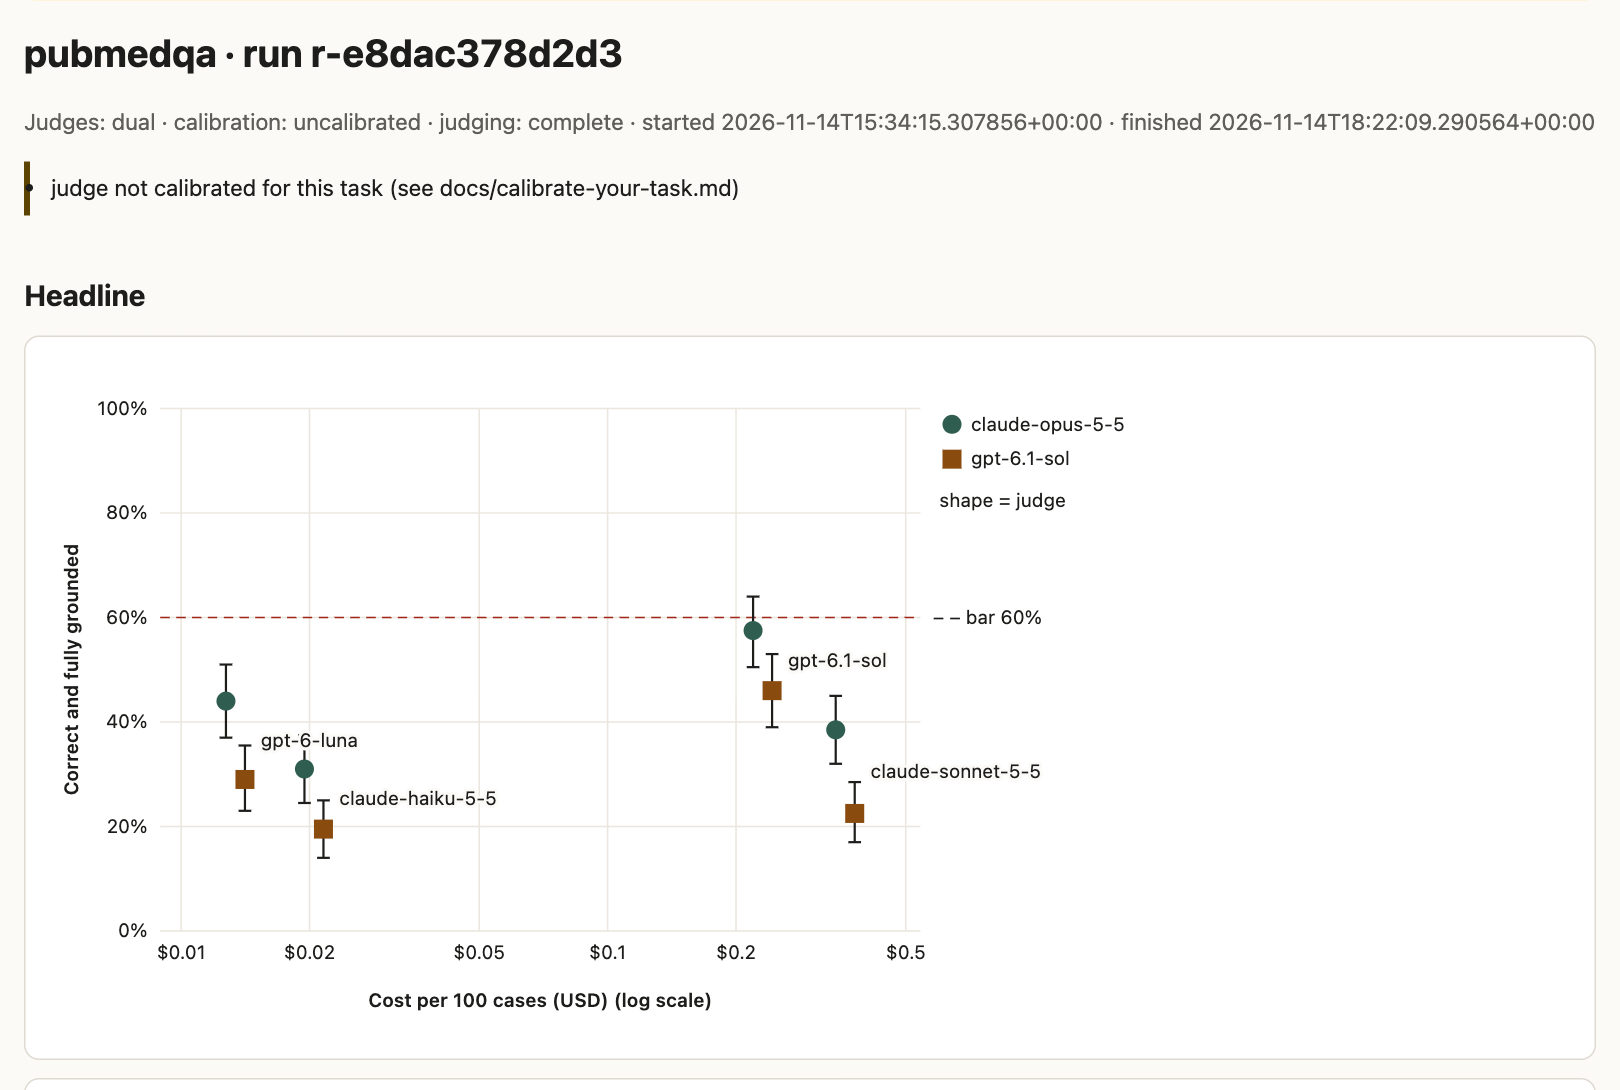
On 200 PubMedQA questions, 4 models (claude-sonnet-5-5, claude-haiku-5-5, gpt-6.1-sol, gpt-6-luna) answered from the abstract and cited its sentences; two judges from different families (claude-opus-5-5 and gpt-6.1-sol) checked every claim. The most grounded model was gpt-6.1-sol, correct and fully grounded on 57.5% (95% CI 50.5%–64.0%) by claude-opus-5-5, 46.0% (95% CI 39.0%–53.0%) by gpt-6.1-sol; it is separated from every other model after a Holm correction (gpt-6.1-sol also judged its own answers; claude-opus-5-5 agrees); the most accurate model was claude-sonnet-5-5 (77.0% correct labels); the headline also requires every claim to be supported by the sentences the answer cites. Caveats: judge not calibrated for this task (see docs/calibrate-your-task.md). Treat these numbers as provisional.
Full report · results in docs/results/
pip install 'evalkit-harness[anthropic,openai]'
evalkit init   # scaffold a project and a three-case sample task
evalkit run evalkit.yaml --task tasks/my_task.yaml --n 3 --dry-run   # estimate
evalkit run evalkit.yaml --task tasks/my_task.yaml --n 3   # needs keys in .env
Questions from PubMedQA (Jin et al., 2019, MIT licence); see DATA_CARD.md. Research benchmark, not medical advice.
Why EvalKit
Public leaderboards rank models on someone else's task. The model that tops them is not always the one that answers your questions correctly, and a fluent answer can still say things its source never said. EvalKit measures both on your own data:
- Accuracy: the share of answers with the right label (yes / no / maybe, supports / refutes, or your own labels).
- Groundedness: each answer is split into claims, and every claim is checked against the sentences the answer cites. The headline metric is correct and fully grounded.
- Citation validity, coverage, cost and latency for every model, from the providers' own usage numbers.
- Honest uncertainty: 95% bootstrap confidence intervals on every rate, paired comparisons with a Holm correction, and a gap is claimed only when it survives both.
- Judges you can check: two judges from different families (Claude and GPT) score every claim, their self-preference is reported, and you can calibrate them against your own hand labels.
See it
| The report: headline chart | The report: failure explorer |
|---|---|
 |
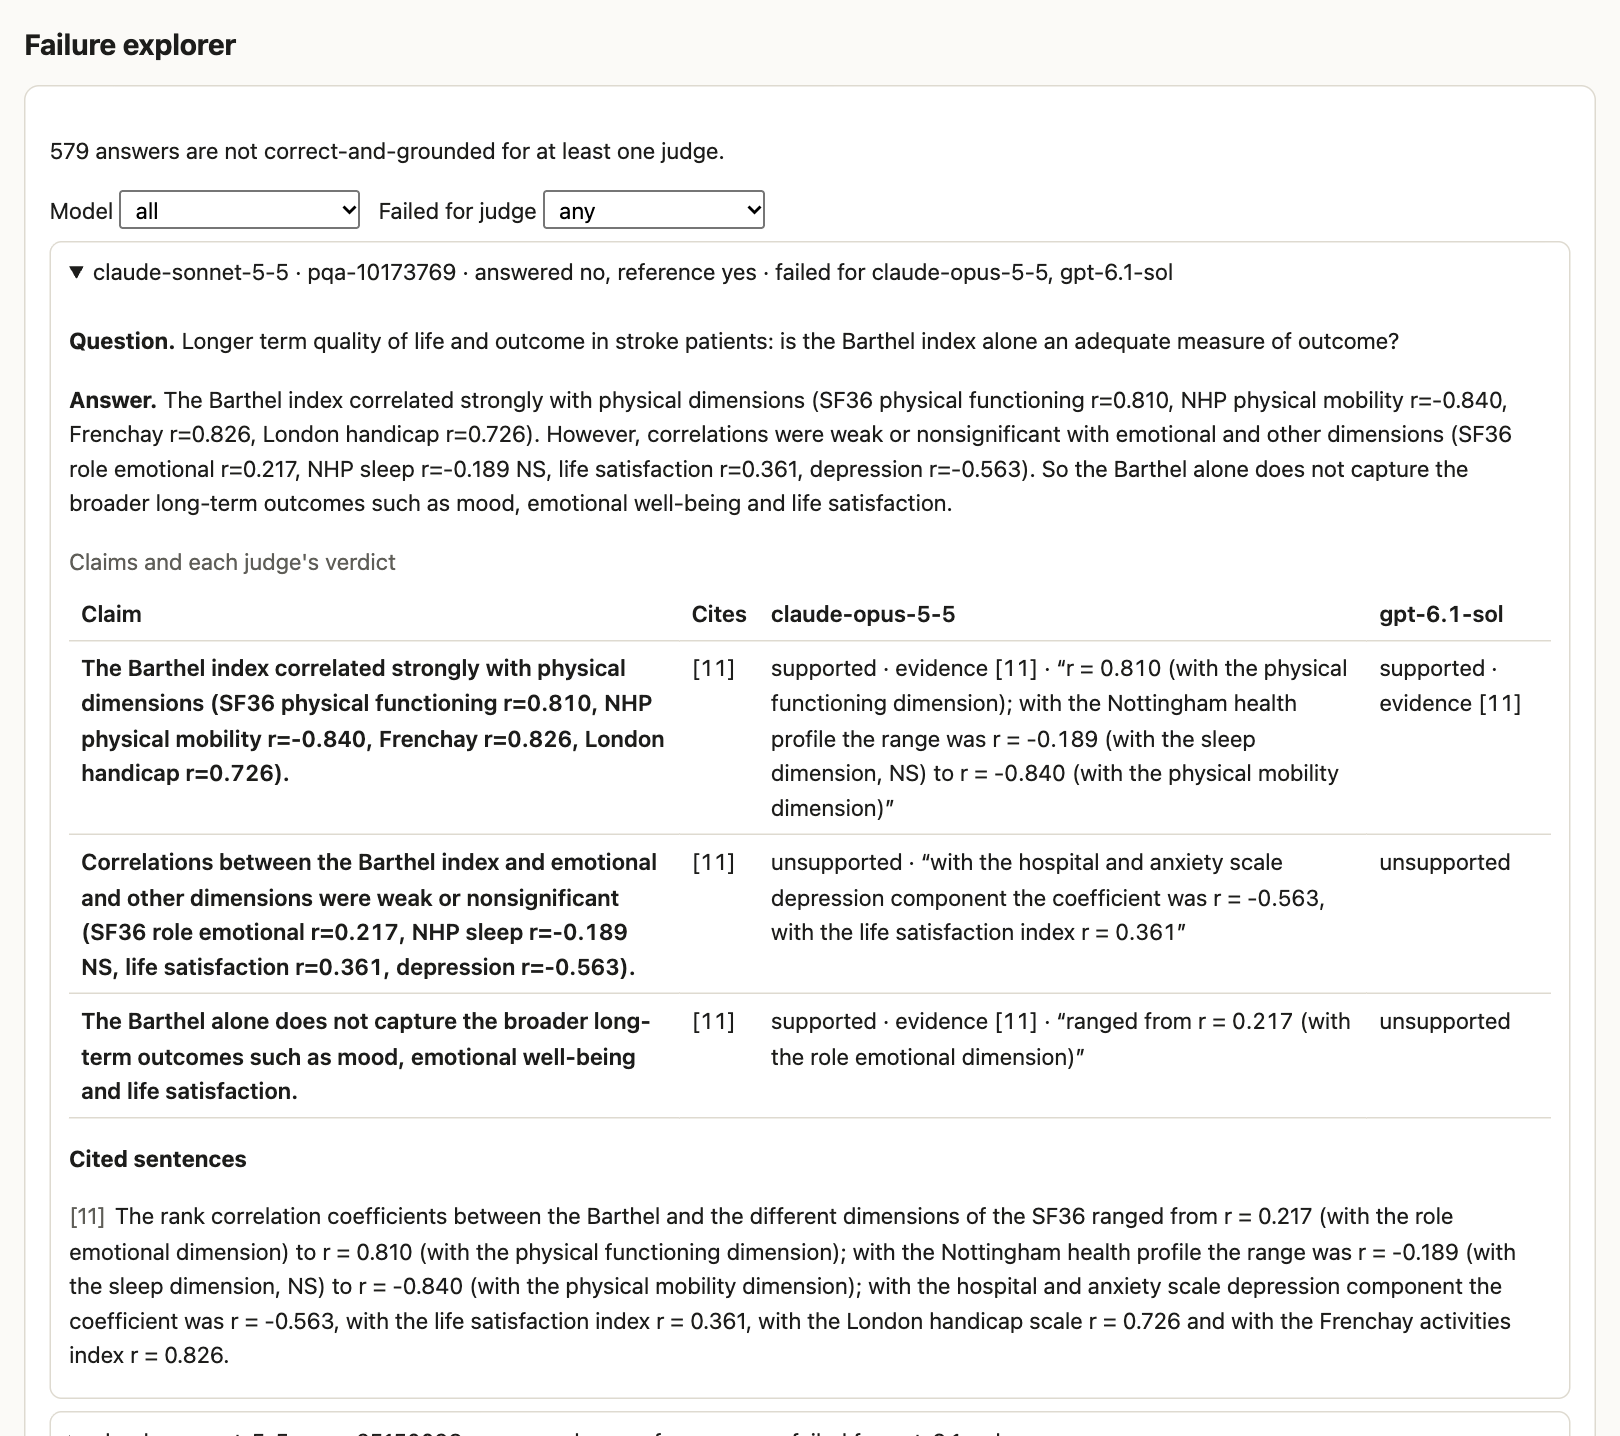 |
| Each model's correct and fully grounded rate with its 95% interval, per judge, against cost. | Every answer that failed, with its claims, each judge's verdict and the sentences it cited. |
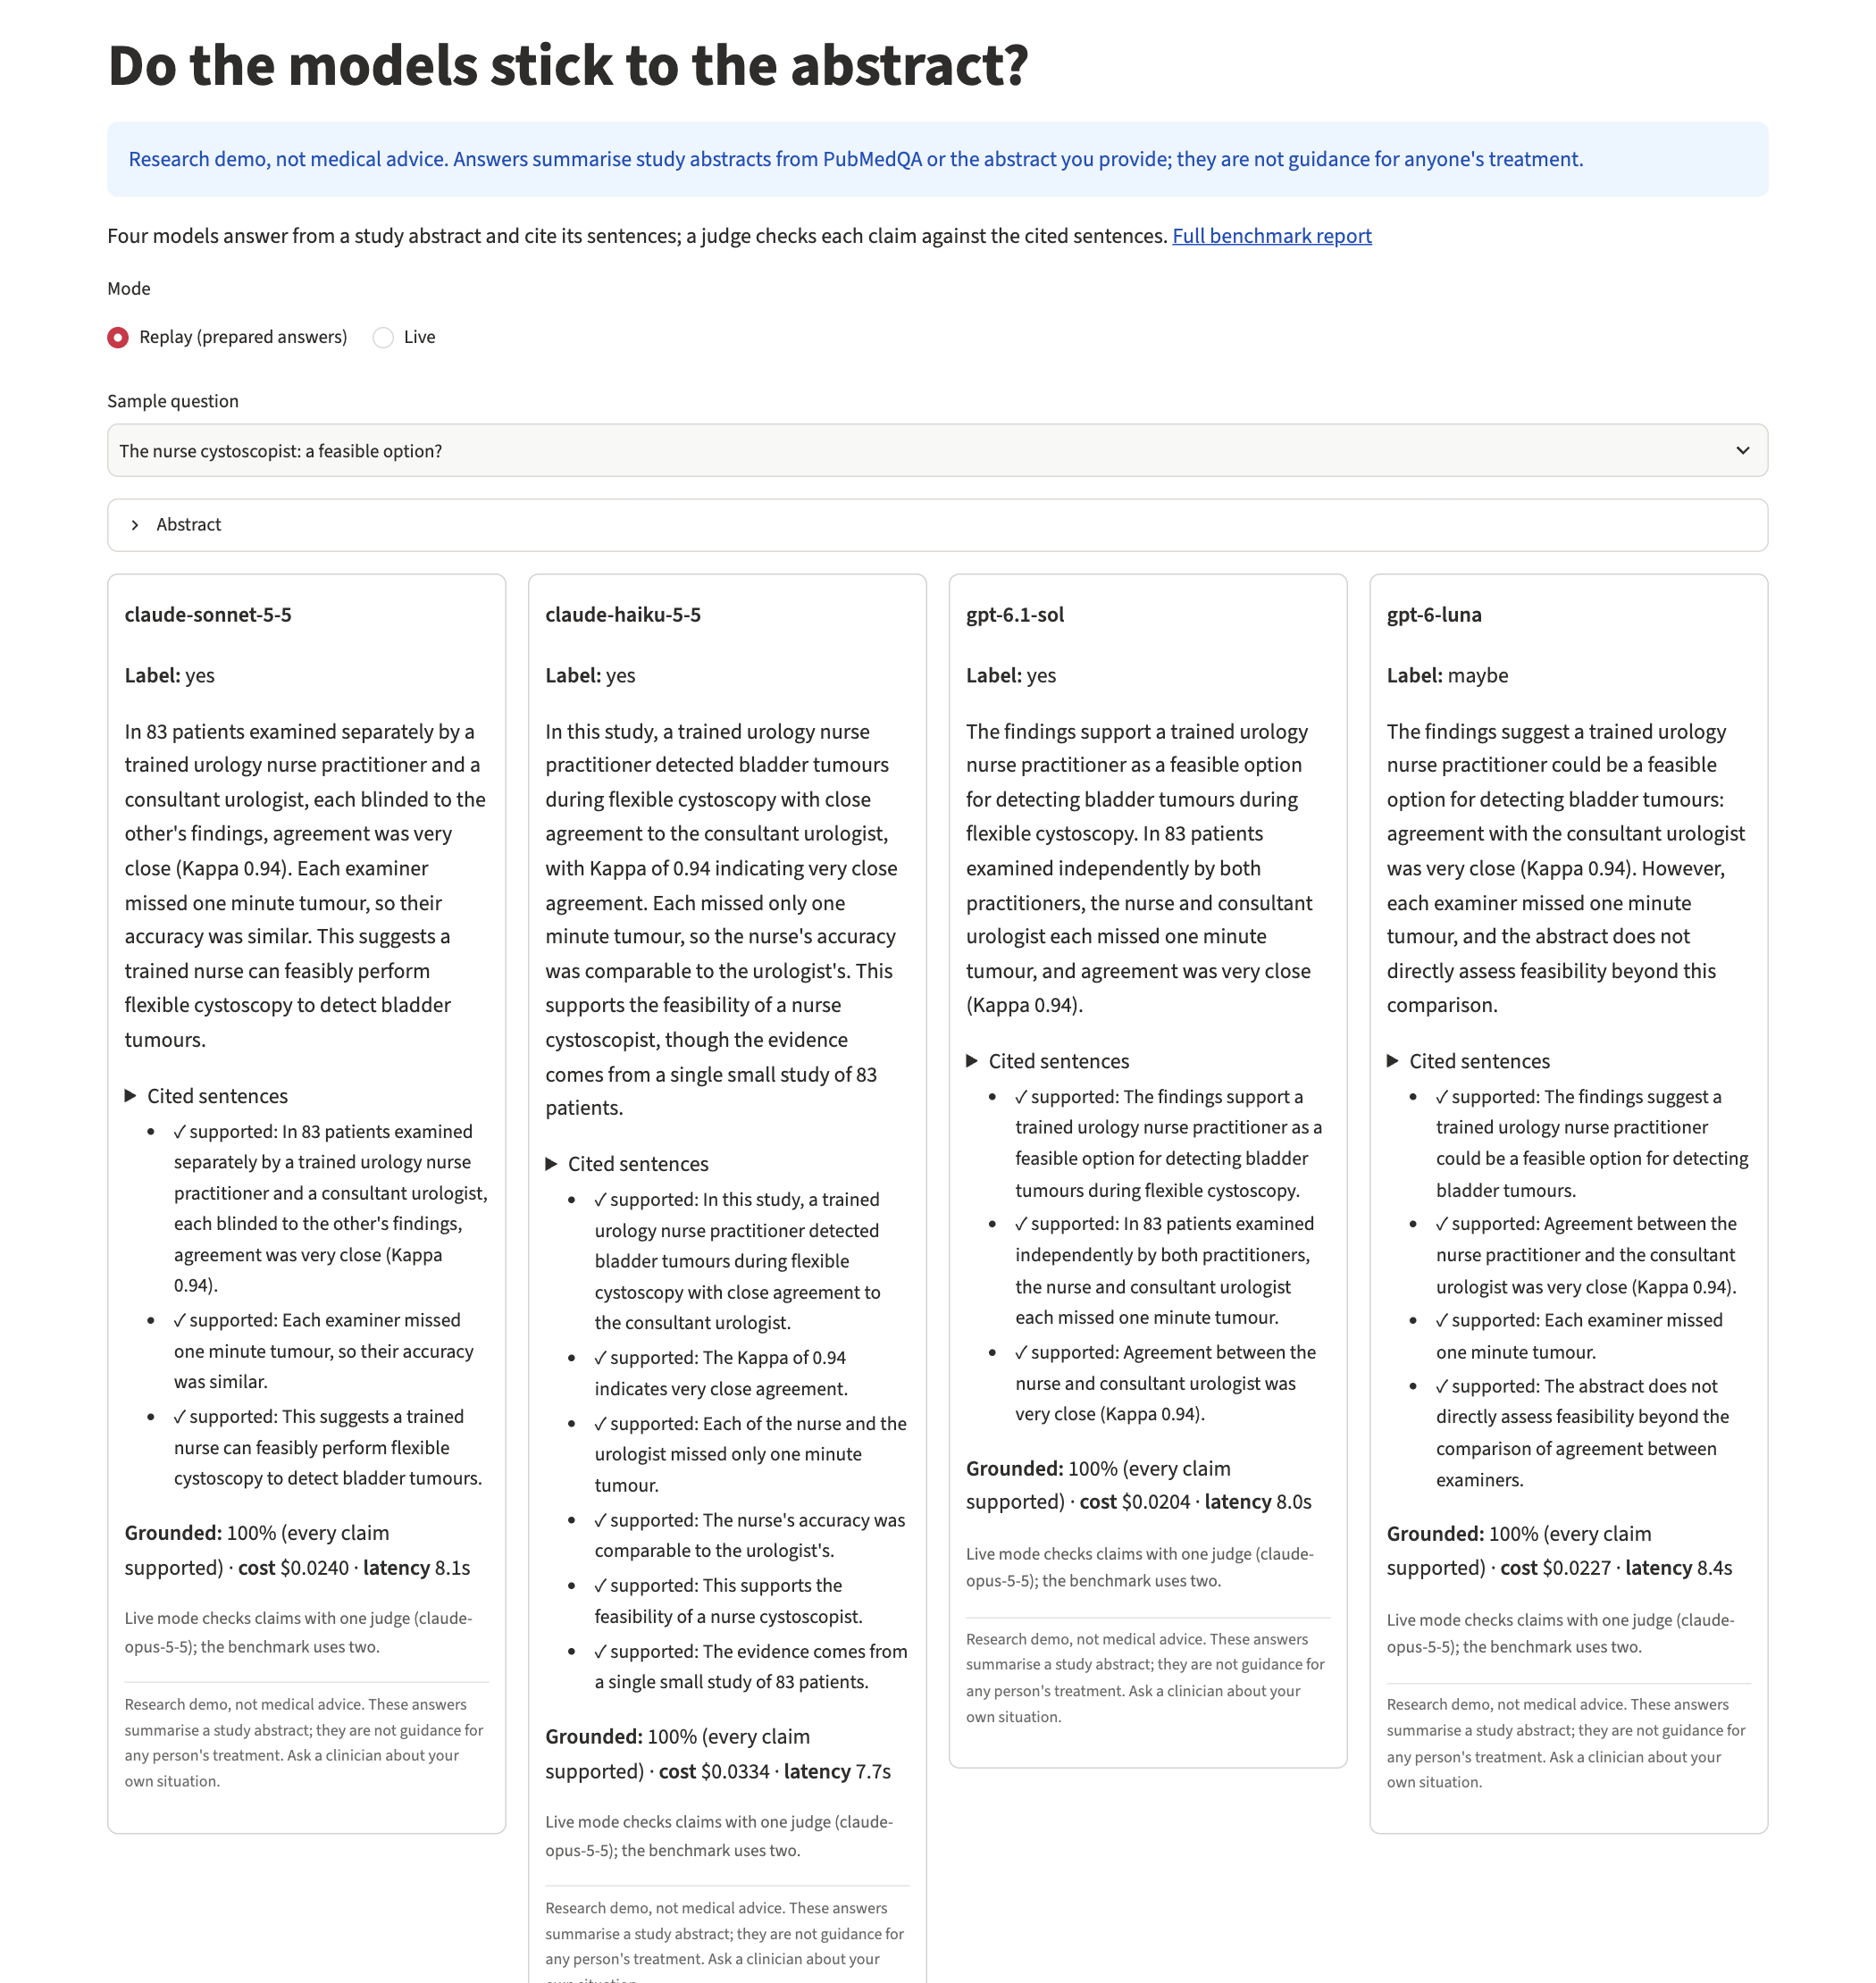
| The demo: replay mode | The demo: live mode |
|---|---|
 |
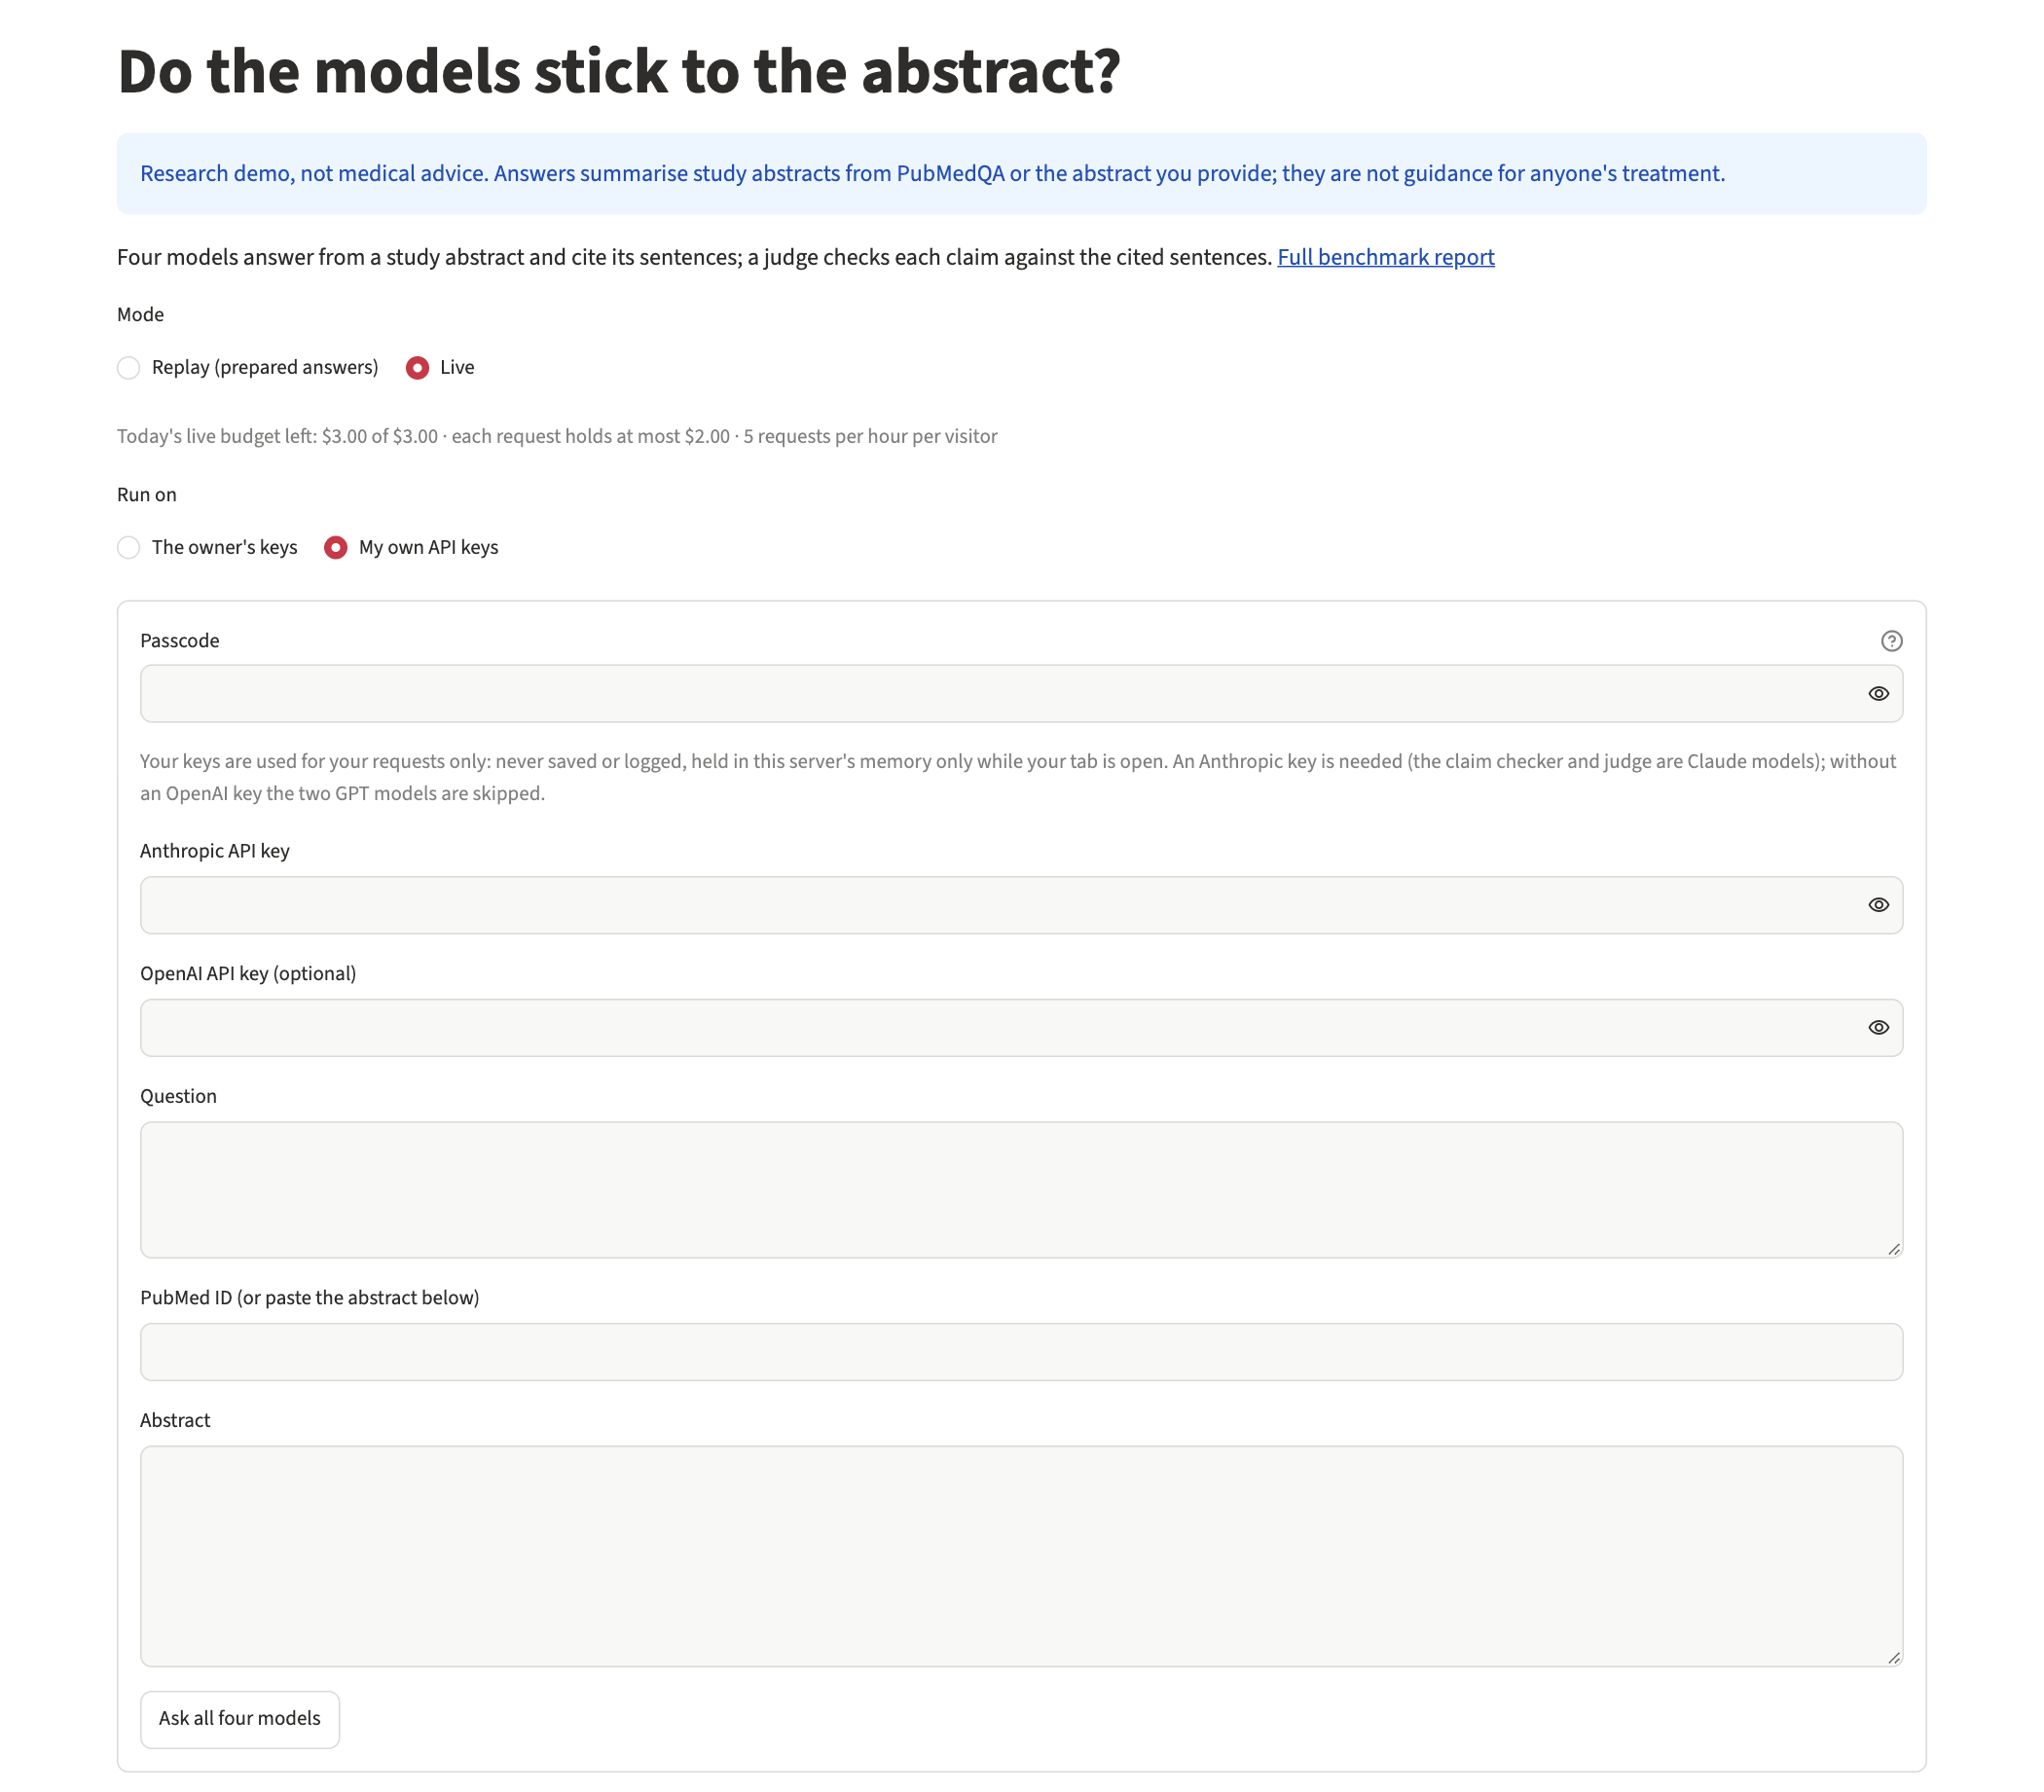 |
| Four models answer one question from a study abstract; every claim is checked against what it cites. | Ask your own question about a PubMed ID or a pasted abstract (passcode required). |
Quickstart
pip install 'evalkit-harness[anthropic,openai]'
evalkit init
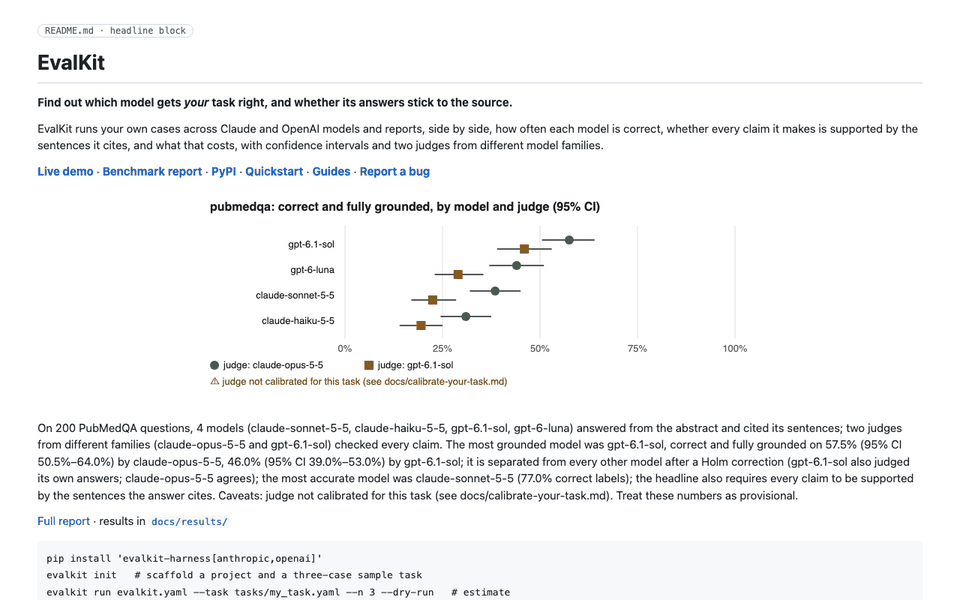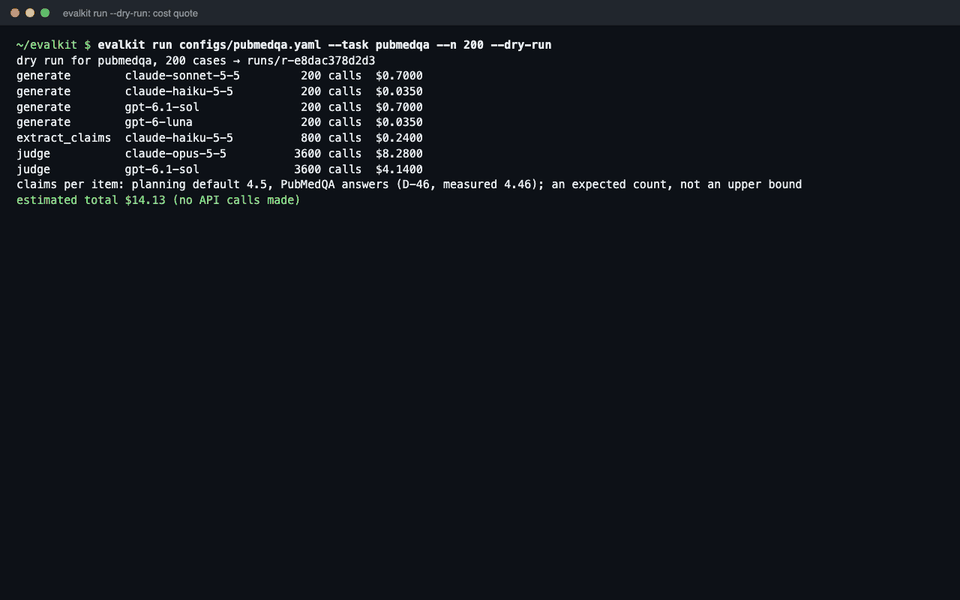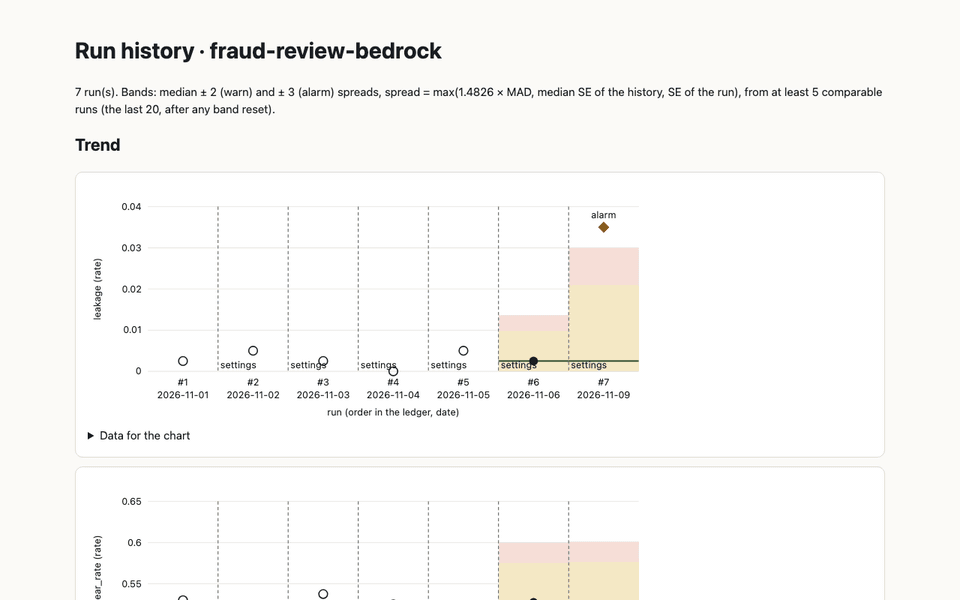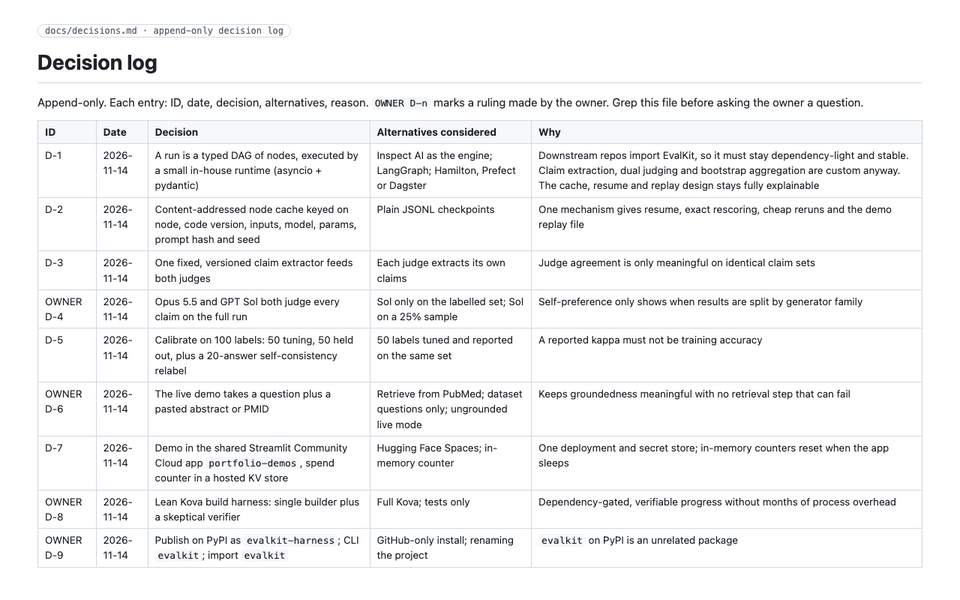
evalkit run evalkit.yaml --task tasks/my_task.yaml --n 3 --dry-run
evalkit init scaffolds evalkit.yaml, a three-case sample task and .env.example. The dry run prints what a run would cost and makes no API call:
dry run for my-task, 3 cases → runs/r-bded23433341
generate        claude-sonnet-5-5           3 calls  $0.0105
generate        claude-haiku-5-5            3 calls  $0.0005
generate        gpt-6.1-sol                 3 calls  $0.0105
generate        gpt-6-luna                  3 calls  $0.0005
extract_claims  claude-haiku-5-5           12 calls  $0.0036
judge           claude-opus-5-5            54 calls  $0.1242
judge           gpt-6.1-sol                54 calls  $0.0621
estimated total $0.21 (no API calls made)
Add your keys to .env (copy .env.example), check the setup with evalkit doctor, then run the same command without --dry-run. The run writes report.html and summary.json to its run folder. No keys yet? evalkit report --example renders a sample report offline.
The full walkthrough is in the quickstart. The package is evalkit-harness on PyPI (the name evalkit belongs to an unrelated project); the command and the import are both evalkit. Python 3.11 to 3.13 on Linux, macOS and Windows.
How it works
flowchart LR
  A[Your cases<br/>JSONL, CSV or a built-in task] --> B[Generate<br/>each model answers and cites sentences]
  B --> C[Validate<br/>schema and citations]
  C --> D[Extract claims<br/>one fixed extractor]
  D --> E1[Judge: Claude]
  D --> E2[Judge: GPT]
  C --> F[Deterministic scores<br/>label, citations, cost, latency]
  E1 --> G[Aggregate<br/>bootstrap CIs, thresholds]
  E2 --> G
  F --> G
  G --> H[report.html<br/>summary.json]
- Every model call is cached by its exact inputs, so a run stopped by the cost cap, a crash or Ctrl-C resumes for free with the same command.
- Judges run on the providers' batch APIs at half price;
--live-judgesjudges immediately at full price. - A cost cap (
max_cost_usdor--max-cost) is enforced before each call; the run stops with exit code 3 rather than overspend. - Thresholds in
evalkit.yamlmake the exit code fail when a model misses the bar, so a run can gate CI.
Guides
| Guide | What it covers |
|---|---|
| Quickstart | Install, sample task, first result in under five minutes |
| Write your own task | Your data as JSONL or CSV, prompts, labels and thresholds |
| Control cost | Estimates, the cost cap, free resume, batch versus live judging, exit codes |
| Calibrate the judges | Hand-label claims, measure judge agreement, mark a run calibrated |
| Scorers and adapters | Add a scorer or a model adapter as a plugin |
| Run history, experiments and spend | Alarm bands against each metric's own history, a trend page, an experiment ledger with a held-out freeze guard, a spend cap alarm |
| Drift and calibration | PSI per feature and Brier, ECE and reliability-bin changes against a frozen reference |
| Run it in CI | A GitHub Actions workflow that fails the job when a threshold fails |
| Versioning | What is public API, and how releases follow semver |
Built-in tasks and your own data
| Task | Data | Labels |
|---|---|---|
pubmedqa |
PubMedQA expert-labelled questions with their abstracts | yes / no / maybe |
scifact |
SciFact scientific claims with evidence abstracts | supports / refutes / not enough info |
| your own | A JSONL or CSV file: question, context sentences, expected label | your label set |
Downloads are verified against pinned checksums; licences and sampling are in DATA_CARD.md.
The live demo
evalkit-demo.streamlit.app shows the idea on one question at a time.
- Replay mode is open to everyone: prepared answers to sample PubMedQA questions, no model calls.
- Live mode needs a passcode from the owner, then runs either on the owner's keys (within a daily budget) or on your own Anthropic and OpenAI keys. Your keys go only into that request's API clients: never saved, never logged.
- Live requests are rate-limited per visitor and capped per request; only aggregate counts are logged, never the question or the abstract.
The demo's source is in demo/.
Results
The first benchmark (200 PubMedQA questions, four models, two judges) is in the full report, with the raw summary in docs/results/. The judges are not yet calibrated for that task, so treat those numbers as provisional.
Project documents
- Product requirements and technical spec
- Design decisions, lessons learned and the changelog
- Build status:
uv run python scripts/status.py(the project was built node by node, each verified against written criteria and an independent reviewer)
Contributing, security and privacy
- No telemetry. Data goes only to the model providers you configure: PRIVACY.md.
- Security: key handling and how to report a vulnerability privately: SECURITY.md.
- Contributing: set-up, checks and conventions in CONTRIBUTING.md; please follow the code of conduct. Bug reports and ideas: open an issue.
- To work on EvalKit itself: clone the repository and run
uv sync --all-extras.
Credits and licence
Questions from PubMedQA (Jin et al., 2019, MIT licence) and claims from SciFact (Wadden et al., 2020); see DATA_CARD.md. EvalKit is a research tool, not medical advice.
MIT licence. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for evalkit-harness 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| evalkit_harness-0.4.0.tar.gz | 469.5 kB | Without provenance | Details for evalkit_harness-0.4.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| evalkit_harness-0.4.0-py3-none-any.whl | Python 3 | none | any | Details for evalkit_harness-0.4.0-py3-none-any.whl |
Total release size: 1.0 MB
Release files / evalkit_harness-0.4.0.tar.gz
| Download URL | evalkit_harness-0.4.0.tar.gz |
|---|---|
| Size | 469.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1695d3ff1ad28ea8c17830a77059bfc647c60d78545e25519947cb99615e949d
|
|
BLAKE2b-256 checksum How to use checksums |
c5f18dc5acb2fdd79d4e1a9cd0214abcb5d4e7b3c8f4ecfc3ee14db36162bd71
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.9 {"installer":{"name":"uv","version":"0.13.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"26.04","id":"resolute","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / evalkit_harness-0.4.0-py3-none-any.whl
| Download URL | evalkit_harness-0.4.0-py3-none-any.whl |
|---|---|
| Size | 539.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7bceabbd9a47f3b884a6e35ca588159aea927c1901a7c6c8a888df9965f92030
|
|
BLAKE2b-256 checksum How to use checksums |
2429b8868e53b0ab4b2cd90e42cea2f8b57d52190906a3b7859c42635683655c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.9 {"installer":{"name":"uv","version":"0.13.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"26.04","id":"resolute","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Security for evalkit-harness 0.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














