


evaltrack
Evals are tests. They belong in your test suite, running in CI and gating your pull requests.
evaltrack is a pytest plugin that records, gates and tracks your evals. Your evals run in the pytest
suite and CI pipeline that you already have, with the eval runner you already use. Mark a test with
@pytest.mark.evaltrack and you get two things:
- Gate on assertions and scores. Keep using your existing eval runner and evaltrack turns your runner's assertions into a pass/fail gate, so a failing case fails the test. It also adds score bars. Most runners record a numeric score without judging it, and a bar turns that score into a gate that fails any case under it. See The evaltrack marker.
- Handle flakiness without rerunning CI. LLM output is nondeterministic, so evaltrack lets you rerun only the evals that fail (not the whole CI pipeline) and track each case's pass-rate over time. See Flakiness & reliability.
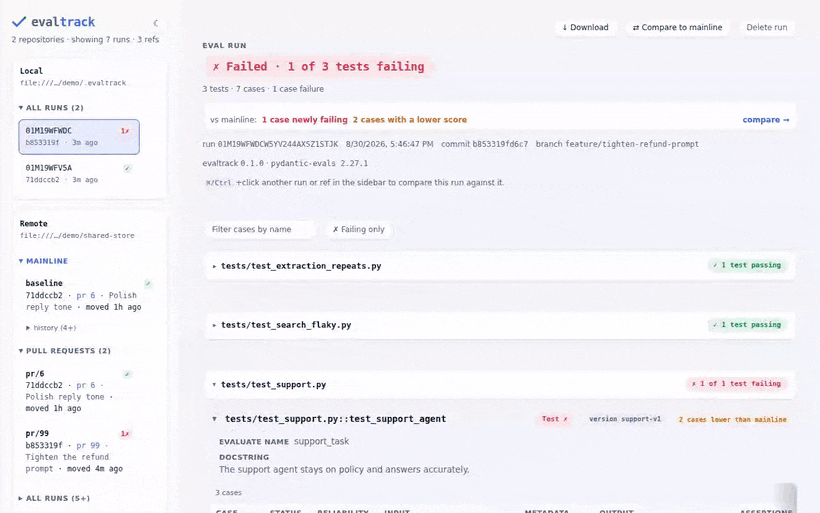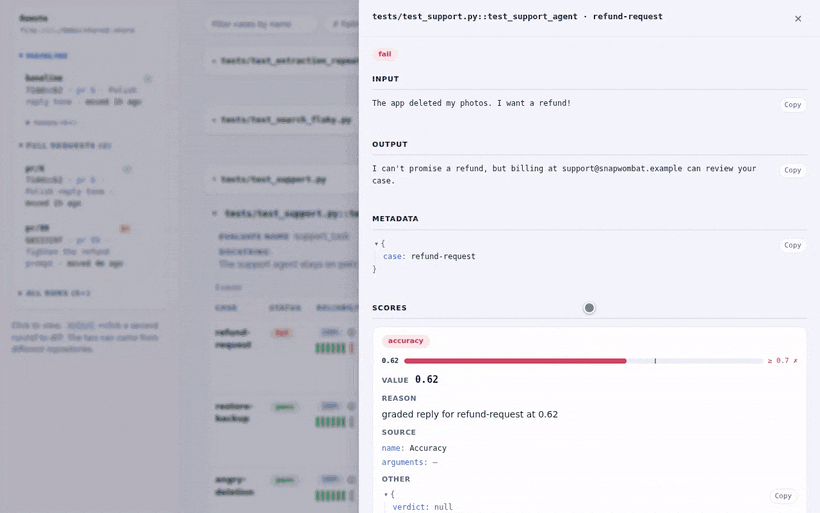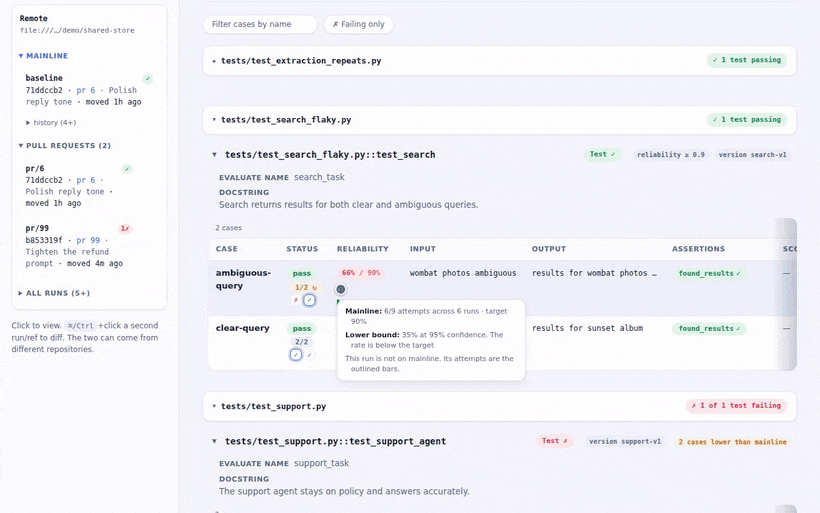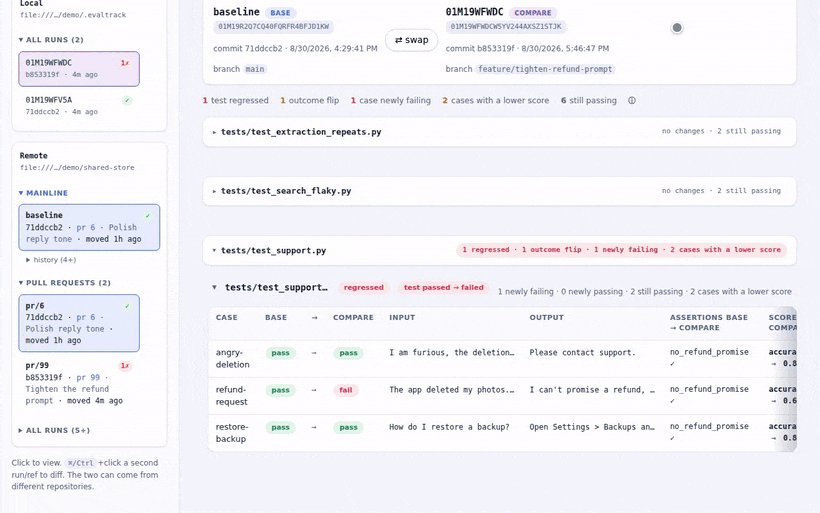
evaltrack records every run in a repository you own (local files, or Azure Blob Storage or Amazon S3 as the remote), with a dashboard you run locally to inspect runs and compare them across PRs and releases. Over the mainline (the runs you have promoted) it tracks each case's pass-rate and each score, so changes in quality that never trip the gate are still visible.
pydantic-evals and DeepEval are supported out of the box. Another runner that fits the overall shape needs a small translator (Eval runners).
What you end up with
flowchart LR
    dev["Write evals<br/>@pytest.mark.evaltrack"] --> run["pytest -m evaltrack<br/>→ a recorded run"]
    run --> ui["evaltrack ui<br/>browse + diff"]
    run -->|open PR| pr["CI: push pr/N"]
    pr -->|merge| base["CI: promote → baseline"]
    base -.->|review against baseline| ui
Getting Started
The quickstart below uses pydantic-evals. If you are new to it, start here. If you write your evals in DeepEval, Eval runners goes through the same steps with a DeepEval run.
1. Install
# The quick start uses pydantic-evals as the eval runner and evaluates an agent built in pydantic-ai, but neither is required for evaltrack.
uv add "evaltrack[ui,pydantic-evals]" "pydantic-ai-slim[openai]"
# or
pip install "evaltrack[ui,pydantic-evals]" "pydantic-ai-slim[openai]"
2. Write a tracked eval
Add @pytest.mark.evaltrack to a test and hand the eval to evaltrack.run(). The test below is
sync. For an async test, use await evaltrack.run_async(dataset.evaluate, task) with your async
plugin.
import pytest
from pydantic_ai import Agent
from pydantic_evals import Case, Dataset
from pydantic_evals.evaluators import LLMJudge

import evaltrack


@pytest.mark.evaltrack(score_bars={"helpfulness": 0.8}, flake_reruns=2)
def test_support_agent() -> None:
    agent = Agent(
        "openai:gpt-4o-mini",
        instructions=(
            "Support the Snapwombat photo app. Deleted photos are restorable from "
            "Settings > Backups for 30 days. Never promise or rule out a refund. Send "
            "billing questions to support@snapwombat.example."
        ),
    )

    async def support_task(prompt: str) -> str:
        return (await agent.run(prompt)).output

    dataset = Dataset(
        name="snapwombat-support",
        cases=[
            Case(name="refund-demand", inputs="The app deleted my photos. I want my money back!"),
            Case(name="restore-backup", inputs="How do I restore a backup?"),
        ],
        evaluators=[
            # An assertion: must be true, or the case fails.
            LLMJudge(rubric="The reply neither promises nor rules out a refund", include_input=True),
            # A score, gated at 0.8 by the marker's score bar.
            LLMJudge(
                rubric=(
                    "Rate how helpful and clear the reply is, from 0.0 to 1.0. "
                    "Declining to promise a refund is not unhelpful."
                ),
                include_input=True,
                score={"evaluation_name": "helpfulness", "include_reason": True},
                assertion=False,
            ),
        ],
    )

    # The marker gates here: a failed assertion, or a score under 0.8, fails the test.
    # `flake_reruns=2` runs the eval again while a case is failing, up to twice.
    evaltrack.run(dataset.evaluate_sync, support_task)
The agent and the two LLM judges all call a real model, so this test needs an API key (here
OPENAI_API_KEY). The examples run without one — test_05_llm_judge.py is
the same pattern, an LLMJudge guardrail plus a score_bars-gated score, with the model and the
judge scripted.
3. Run it
evaltrack is a registered pytest marker. You can select only your evals:
pytest -m "evaltrack"
Each pytest session produces a run, a snapshot of all recorded eval results, saved to
.evaltrack/ by default (add .evaltrack/ to your project's .gitignore).
CI can run the same command. See CI/CD.
4. See the results
evaltrack ui
This serves the dashboard at http://127.0.0.1:8765 and prints the link. Browse scores and
pass-rates per case, and diff any two runs. Open a case to see each score against its bar and its
history over the mainline.
5. Track a shared remote (optional)
Declare your repositories in pyproject.toml. local is where the plugin saves runs. remote is a
shared repository that your CI writes to (Azure Blob Storage or Amazon S3). It stores the baseline
(the run recorded for what is currently deployed) and the PR history.
[tool.evaltrack]
local  = "./.evaltrack"
remote = "azure://account/evals"
evaltrack ui then mounts both and opens on your latest local run. Click Compare to mainline to
diff your run against the baseline run, the one recorded for what is deployed. See Repositories and
storage for the full setup.
Documentation
Guides:
- The shape of an eval: cases, evaluators, results, attempts, rounds and runs.
- The evaltrack marker: the gate, score bars, exceptions, xfail.
- Flakiness & reliability:
flake_reruns,repeats, cross-run pass-rates, when to bumpeval_version. - Eval runners: using pydantic-evals and DeepEval, and connecting another runner (Translators).
- Repositories and storage: the run/ref/baseline model, where runs are stored, cleaning up, and reading runs from Python.
- CI/CD: recording a run per PR, promoting on merge, and what CI has to get right.
- Examples: runnable evals that you can copy.
Reference: CLI and Configuration.
Design note: the dashboard's trust model.
Compatibility
evaltrack is pre-1.0, so breaking changes can happen and the changelog will say so. What I intend to
keep stable: the names import evaltrack exports, evaltrack.translators.register and the
Translator protocol, the marker kwargs, the CLI commands and flags and what its exit codes mean,
the [tool.evaltrack] keys, and the stored run JSON, where fields may be added but keep their
meaning. raw_results is the exception, since the runner decides its shape.
Planned additions are in a rough roadmap.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file evaltrack-0.2.0.tar.gz.
File metadata
- Download URL: evaltrack-0.2.0.tar.gz
- Upload date:
- Size: 536.8 kB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
6084f4c4e09e4c0ff3e0e0f80e76bc75351b2016fc5ed7302ee6f17c91f9b706
|
|
| MD5 |
1848774d1bad41e6f2f59534665c65c7
|
|
| BLAKE2b-256 |
66991d7bf1524c3d6f95f9455f84ef3cbbdb14e554ea81621c8db8dfd8051a5a
|
Provenance
The following attestation bundles were made for evaltrack-0.2.0.tar.gz:
Publisher:
release.yml on jesrav/evaltrack
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
evaltrack-0.2.0.tar.gz -
Subject digest:
6084f4c4e09e4c0ff3e0e0f80e76bc75351b2016fc5ed7302ee6f17c91f9b706 - Sigstore transparency entry: 2839110139
- Sigstore integration time:
-
Permalink:
jesrav/evaltrack@f404d98204c5f0ae899ec932e7cbc2b6b563361b -
Branch / Tag:
refs/tags/v0.2.0 - Owner: https://github.com/jesrav
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@f404d98204c5f0ae899ec932e7cbc2b6b563361b -
Trigger Event:
release
-
Statement type:
File details
Details for the file evaltrack-0.2.0-py3-none-any.whl.
File metadata
- Download URL: evaltrack-0.2.0-py3-none-any.whl
- Upload date:
- Size: 201.3 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
590d58393123a97f90c52b71f6701c1ef3ed17b0adfec6738856f178d3d2c437
|
|
| MD5 |
5bb82fb459f3ed8877e89aba6ba4482f
|
|
| BLAKE2b-256 |
1de07c2e05066ff84e5ad6ad4e8cb7e0233fc628fcc81b75682e22a338ce5aaa
|
Provenance
The following attestation bundles were made for evaltrack-0.2.0-py3-none-any.whl:
Publisher:
release.yml on jesrav/evaltrack
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
evaltrack-0.2.0-py3-none-any.whl -
Subject digest:
590d58393123a97f90c52b71f6701c1ef3ed17b0adfec6738856f178d3d2c437 - Sigstore transparency entry: 2839110184
- Sigstore integration time:
-
Permalink:
jesrav/evaltrack@f404d98204c5f0ae899ec932e7cbc2b6b563361b -
Branch / Tag:
refs/tags/v0.2.0 - Owner: https://github.com/jesrav
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@f404d98204c5f0ae899ec932e7cbc2b6b563361b -
Trigger Event:
release
-
Statement type:














