


Facebook Pages Scraper
Facebook Pages Scraper reads public Facebook page info and the latest post without a browser or an API key. If you find it useful, please support the package by hitting the star on GitHub. Your support helps keep the project going.
Use facebook-pages-scraper for a page name, intro, about text, contact fields, and the latest post. A string returns one result. A list returns one result per page. Works with pip install facebook-pages-scraper or uv add facebook-pages-scraper on Python 3.11+.
Looking for a sponsor
Demo
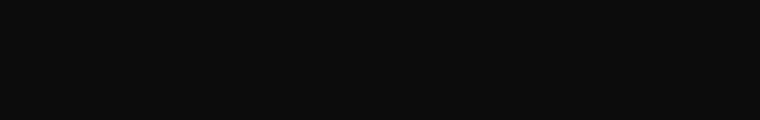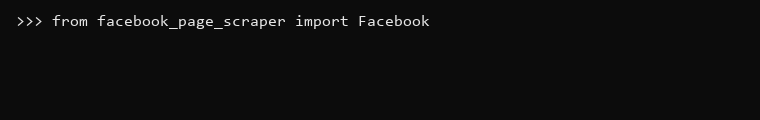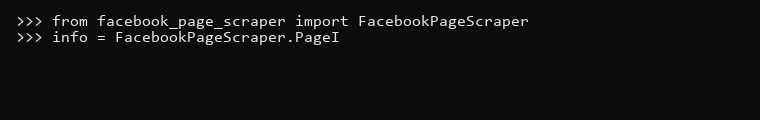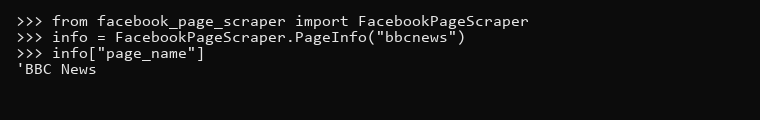
How it works
The package fetches the public page HTML with a Chrome-like client, then reads the JSON Facebook embeds in that document.
Page info comes from the profile header and intro cards. Address, the About paragraph, page id, and creation date come from the About tab. The first HTML document includes only the latest post.
Accepted input:
bbcnewshttps://www.facebook.com/bbcnewshttps://web.facebook.com/bbcnewshttps://m.facebook.com/bbcnews
pizzaburgbd is a public page that fills the About fields: intro, about text, address, phone, email, website, hours, services, Instagram, owner, page id, and creation date. Use it when you want a test run to show a full result. Page likes and the Monday–Sunday hours grid are still absent, because Facebook does not put them in this HTML.
A string returns one dict (or one list of posts). A list returns one result per page, in order. A failed page is None.
page_social_accounts is a map of network to link, for example {"Instagram": "https://www.instagram.com/meta"}. Page likes are often missing from the public HTML. page_business_hours is the open/closed line Facebook sends with the page, not the Monday–Sunday grid.
Installation
uv add facebook-pages-scraper
pip install facebook-pages-scraper
pip install facebook-pages-scraper --upgrade
This repo uses uv:
uv sync --group dev
Parameters
| Parameter | Default | What it is |
|---|---|---|
url |
required | One page URL or username, or a list of them. |
proxy |
None |
Optional HTTP/HTTPS/SOCKS5 proxy if this IP is rate-limited. |
concurrency |
4 |
Async list only. Max pages fetched at once. |
proxy stays None unless you need one. Examples:
http://user:pass@host:port
https://host:port
socks5://user:pass@host:port
Usage
Sync — PageInfo
from facebook_page_scraper import FacebookPageScraper


def main():
    # Optional. Examples:
    #   proxy = "http://user:pass@host:port"
    #   proxy = "https://host:port"
    #   proxy = "socks5://user:pass@host:port"
    proxy = None

    url = "https://web.facebook.com/pizzaburgbd"

    try:
        page = FacebookPageScraper.PageInfo(url, proxy=proxy)
        if page:
            print(page)
        else:
            print("Error: no page data")
    except Exception as e:
        print(f"Error occurred: {e}")


if __name__ == "__main__":
    main()
Async — PageInfoAsync
import asyncio

from facebook_page_scraper import FacebookPageScraper


def main():
    # Optional. Examples:
    #   proxy = "http://user:pass@host:port"
    #   proxy = "https://host:port"
    #   proxy = "socks5://user:pass@host:port"
    proxy = None

    url = "https://web.facebook.com/pizzaburgbd"

    try:
        page = asyncio.run(FacebookPageScraper.PageInfoAsync(url, proxy=proxy))
        if page:
            print(page)
        else:
            print("Error: no page data")
    except Exception as e:
        print(f"Error occurred: {e}")


if __name__ == "__main__":
    main()
Async batch
Pass a list. Up to concurrency pages run at once.
import asyncio

from facebook_page_scraper import FacebookPageScraper


def main():
    # Optional. Examples:
    #   proxy = "http://user:pass@host:port"
    #   proxy = "https://host:port"
    #   proxy = "socks5://user:pass@host:port"
    proxy = None

    urls = [
        "https://web.facebook.com/pizzaburgbd",
        "https://web.facebook.com/NASA",
        "https://web.facebook.com/Meta",
    ]

    try:
        pages = asyncio.run(
            FacebookPageScraper.PageInfoAsync(urls, concurrency=4, proxy=proxy)
        )
        for page in pages:
            if page:
                print("Page:", page["page_name"])
            else:
                print("Error: no page data")
    except Exception as e:
        print(f"Error occurred: {e}")


if __name__ == "__main__":
    main()
FacebookPageScraper.PageInfo(urls) also accepts a list (sync, one page after another). For many pages, async batch is the better call.
PagePostInfo and PagePostInfoAsync take the same url, proxy, and concurrency arguments. A string returns the latest post as a one-item list. A list of pages returns a list of those lists.
Disclaimer
Facebook's Terms of Service and Community Standards prohibit unauthorized scraping of their platform. This package is intended for educational purposes, and you should use it in compliance with Facebook's policies. Unauthorized scraping or accessing Facebook data without permission can result in legal consequences or a permanent ban from the platform.
By using Facebook Pages Scraper, you acknowledge that you have the right to access the data you are scraping, and that you are solely responsible for how you use this package. The developers of this tool are not liable for any misuse.
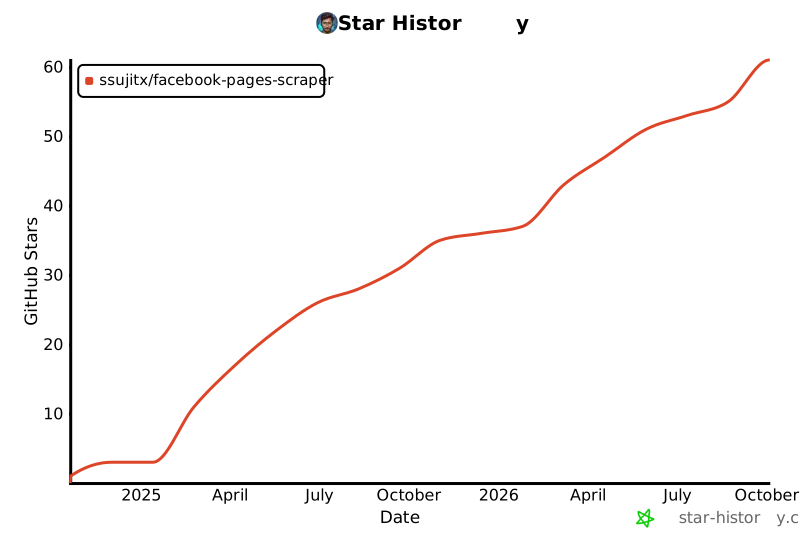
Star History
1 maintainer

Metadata
1 maintainer
Release files for facebook-pages-scraper 0.0.9
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| facebook_pages_scraper-0.0.9.tar.gz | 10.9 kB | Without provenance | Details for facebook_pages_scraper-0.0.9.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| facebook_pages_scraper-0.0.9-py3-none-any.whl | Python 3 | none | any | Details for facebook_pages_scraper-0.0.9-py3-none-any.whl |
Total release size: 24.7 kB
Release files / facebook_pages_scraper-0.0.9.tar.gz
| Download URL | facebook_pages_scraper-0.0.9.tar.gz |
|---|---|
| Size | 10.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
05b8dca03e18e89beb153377ee36f1548e121e774de6c210dee19480cc5092f9
|
|
BLAKE2b-256 checksum How to use checksums |
3ff4ddaf233a89aed996c97425d4474cd99fda3f0f36e12aae36cca49e6f026c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.6 {"installer":{"name":"uv","version":"0.13.6","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / facebook_pages_scraper-0.0.9-py3-none-any.whl
| Download URL | facebook_pages_scraper-0.0.9-py3-none-any.whl |
|---|---|
| Size | 13.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
003cc1d807fcc007f3c586927db2f750b27504eb8d23df085dc5cf6b1e900021
|
|
BLAKE2b-256 checksum How to use checksums |
99a323f199eb893bfe9b3b9d540e5e4c403b7c0bb802525c498f8f4a05bdc3da
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.6 {"installer":{"name":"uv","version":"0.13.6","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Security for facebook-pages-scraper 0.0.9
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














