
 FairMedFM




FairMedFM measures the fairness of any binary classification or segmentation model. Give it your model's predictions and the group of each sample, and it reports how performance differs across groups: AUC, accuracy and calibration gaps, equal opportunity, equalized odds, and Dice disparities. The metrics come from the FairMedFM benchmark of 20 medical imaging foundation models, but they work for any model and any data.
Pip package: fairness metrics for any model
pip install fairmedfm
import fairmedfm as fm

fm.auc_gap(y_true, y_score, sensitive_features=group)            # largest minus smallest group AUC
fm.equalized_odds_score(y_true, y_score, sensitive_features=group)
fm.dice_gap(dice, sensitive_features=group)                       # segmentation
Each metric works like sklearn.metrics: arrays in, one number out. y_true and y_score are your model's
labels and outputs, and group is any attribute you want to compare across (sex, age group, hospital, scanner,
skin tone, ...). Lists, NumPy, pandas and PyTorch all work; labels can be class names (pos_label=), scores can be
probabilities, logits or predict_proba/softmax output. The package needs only NumPy, pandas and scikit-learn, and
its numbers match the FairMedFM paper. Documentation: nanboy-ronan.github.io/FairMedFM-page/docs/.
All metrics at once, as pandas tables, for several attributes:
report = fm.evaluate(y_true, y_score, sensitive_features=df[["sex", "age"]], bins={"age": [40, 60]})
report.summary     # one row per attribute: auc-gap, worst-auc, acc-gap, ece-gap, eod, eo, ...
report.by_group    # every group's sample count and metrics
report.to_json("fairness.json")
During training, log a fairness metric next to the loss:
probs = torch.softmax(model(x_val), dim=1)     # tensors on any device are fine
wandb.log({"val_auc_gap": fm.auc_gap(y_val, probs, sensitive_features=sex_val)})
In scikit-learn model selection (scikit-learn 1.4+, metadata routing):
sklearn.set_config(enable_metadata_routing=True)
scorer = make_scorer(fm.auc_gap, response_method="predict_proba", greater_is_better=False)
cross_validate(model, X, y, scoring=scorer.set_score_request(sensitive_features=True),
               params={"sensitive_features": group})
Segmentation from Dice scores or directly from masks (arrays, or .npy, .png, .nii.gz files):
fm.evaluate_segmentation(group, pred_masks=pred_masks, true_masks=true_masks).summary
From the command line, for prediction files, optionally joined with a separate metadata file:
fairmedfm score predictions.csv --sensitive group
Image and NIfTI masks and Parquet tables need pip install "fairmedfm[io]".
Metrics
| Task | Function | Report column | Definition |
|---|---|---|---|
| Classification | overall-auc, overall-acc, overall-bce, overall-ece |
AUC, accuracy, binary cross-entropy and expected calibration error (10 bins) on all samples | |
| Classification | worst_group_auc |
worst-auc |
Lowest group AUC |
| Classification | auc_gap, accuracy_gap, bce_gap, ece_gap |
auc-gap, acc-gap, bce-gap, ece-gap |
Largest minus smallest group value |
| Classification | equal_opportunity_difference |
eo |
Largest minus smallest group true positive rate |
| Classification | equalized_odds_score |
eod |
1 - (TPR gap + TNR gap) / 2; 1 means equal rates |
| Segmentation | mean_dice, max_dice |
Mean Dice over all samples; best group mean Dice | |
| Segmentation | worst_group_dice, dice_gap |
min_dice, delta_dice |
Worst group mean Dice; best minus worst |
| Segmentation | dice_std, dice_skewness |
std_dice, skewness_dice |
Standard deviation of group means; (1 - min_dice) / (1 - max_dice) |
| Segmentation | equity_scaled_dice |
es_dice |
Equity-scaled Dice: mean_dice / (1 + std_dice) |
Accuracy, eo and eod use the decision threshold with the best overall F1; report.by_group also reports
every metric at threshold 0.5. Attributes can have any number of groups; a classification group with only one
label is reported but left out of the gaps. For multi-class models, pos_label evaluates one class against the
rest. To run the benchmark itself with the built-in foundation models,
install fairmedfm[cls] or fairmedfm[seg] and use fairmedfm run (see Installation).
Table of Contents
- Pip package: fairness metrics for any model
- Abstract
- Key Findings
- Companion Benchmark: MedVLMBench
- Structure
- Schedule
- Installation
- Data
- Notebook Tutorial
- Running Experiment
- Citation
Abstract
The advent of foundation models (FMs) in healthcare offers unprecedented opportunities to enhance medical diagnostics through automated classification and segmentation tasks. However, these models also raise significant concerns about their fairness, especially when applied to diverse and underrepresented populations in healthcare applications. Currently, there is a lack of comprehensive benchmarks, standardized pipelines, and easily adaptable libraries to evaluate and understand the fairness performance of FMs in medical imaging, leading to considerable challenges in formulating and implementing solutions that ensure equitable outcomes across diverse patient populations. To fill this gap, we introduce FairMedFM, a fairness benchmark for FM research in medical imaging. FairMedFM integrates with 17 popular medical imaging datasets, encompassing different modalities, dimensionalities, and sensitive attributes. It explores 20 widely used FMs, with various usages such as zero-shot learning, linear probing, parameter-efficient fine-tuning, and prompting in various downstream tasks -- classification and segmentation. Our exhaustive analysis evaluates the fairness performance over different evaluation metrics from multiple perspectives, revealing the existence of bias, varied utility-fairness trade-offs on different FMs, consistent disparities on the same datasets regardless FMs, and limited effectiveness of existing unfairness mitigation methods.
Key Findings
- Bias is pervasive: All 20 evaluated medical FMs exhibit measurable fairness disparities across sex, race, and age.
- Utility–fairness trade-offs vary: No single FM dominates both accuracy and fairness — the best-performing model is often not the fairest.
- Dataset effect dominates model choice: Disparities on the same dataset remain consistent regardless of which FM is used, pointing to data-driven rather than model-driven bias.
- Mitigation has limited impact: State-of-the-art debiasing algorithms provide only marginal fairness improvements.
Companion Benchmark: MedVLMBench
Evaluating capability of medical VLMs? See our companion benchmark MedVLMBench — the first unified benchmark covering 30+ generalist and specialist VLMs (LLaVA, MedGemma, Qwen2-VL, o3, Gemini 2.5 Pro …) on VQA, diagnosis, and captioning tasks.
FairMedFM and MedVLMBench form a two-part evaluation suite for medical foundation models — capability and fairness, measured on the same models and datasets.
| FairMedFM | MedVLMBench | |
|---|---|---|
| Focus | Fairness across sex, race, age | Capability: accuracy, AUROC, VQA scores |
| Model paradigm | Discriminative FMs (CLIP, SAM variants) | Generative VLMs + discriminative models |
| Tasks | Classification, Segmentation | VQA, Diagnosis, Captioning |
| Scale | 20 FMs · 17 datasets | 30+ VLMs · 14 datasets |
Models evaluated in both: BioMedCLIP · MedCLIP · PLIP · SigLIP · MedSigLIP · CLIP · BLIP · BLIP2 · PubMedCLIP
Datasets in both: HAM10000 · CheXpert · MIMIC-CXR · FairVLMed10k · GF3300 · PAPILA
Structure
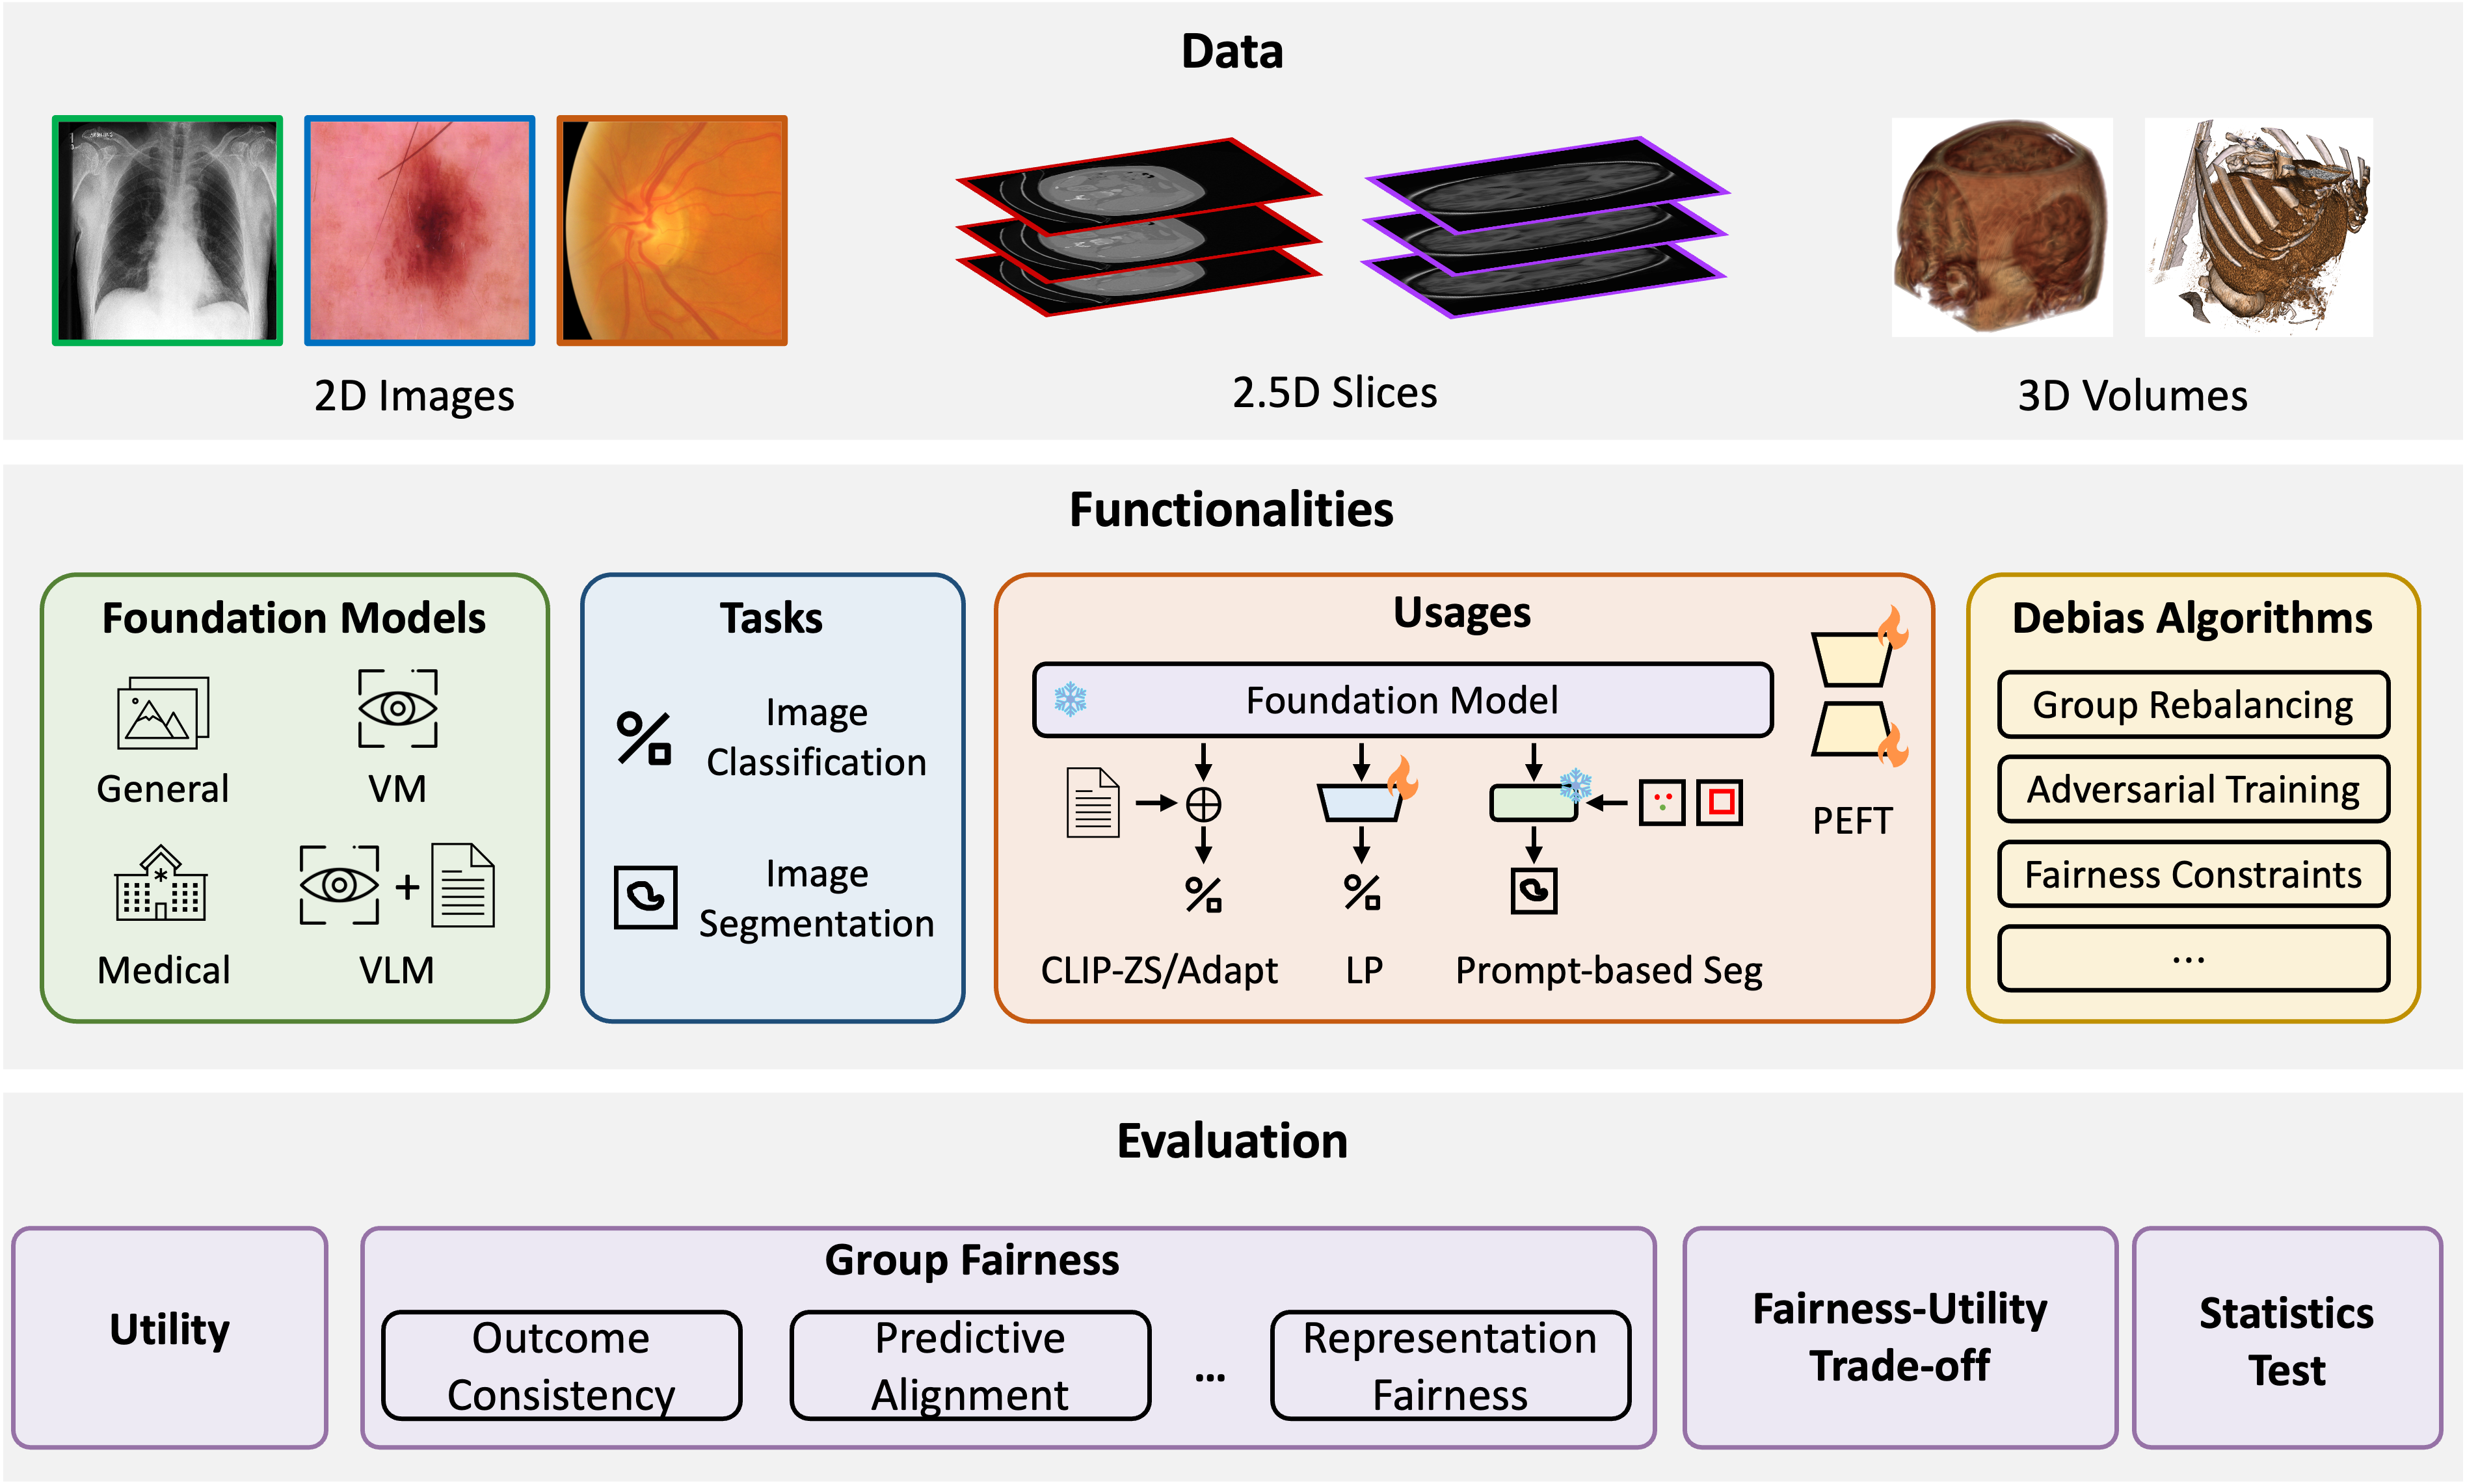
FairMedFM captures comprehensive modules for benchmarking the fairness of foundation models in medical image analysis.
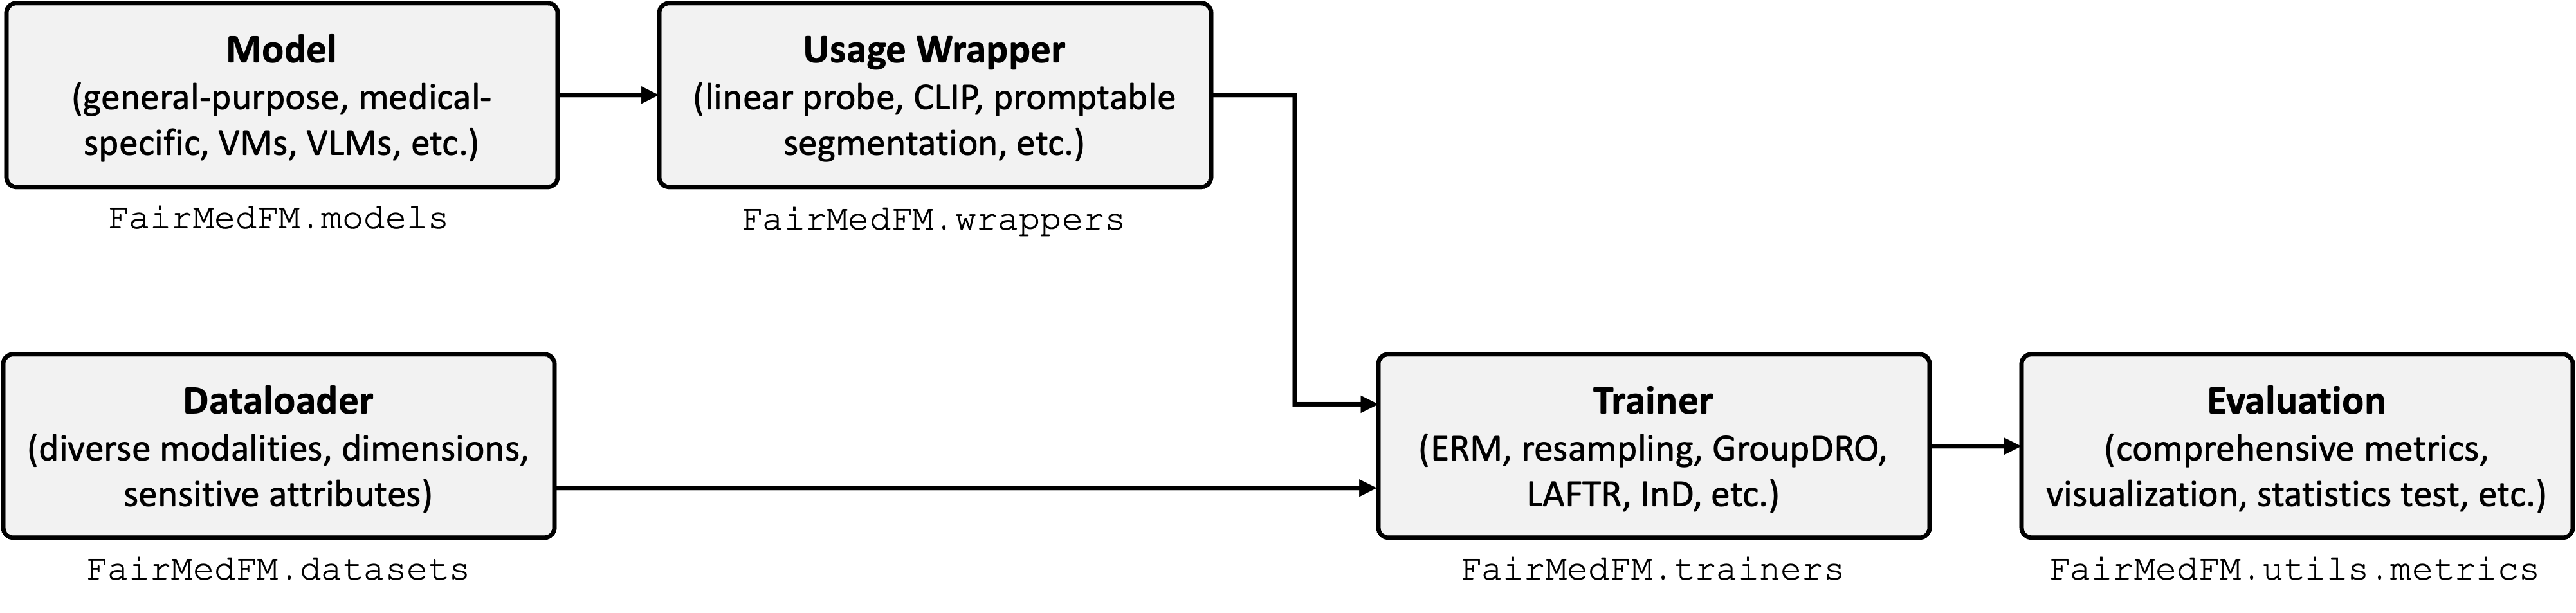
- Dataloader: provides a consistent interface for loading and processing imaging data across various modalities and dimensions, supporting both classification and segmentation tasks.
- Model: a one-stop library that includes implementations of the most popular pre-trained foundation models for medical image analysis.
- Usage Wrapper: encapsulates foundation models for various use cases and tasks, including linear probe, zero-shot inference, PEFT, promptable segmentation, etc.
- Trainer: offers a unified workflow for fine-tuning and testing wrapped models, and includes state-of-the-art unfairness mitigation algorithms.
- Evaluation includes a set of metrics and tools to visualize and analyze fairness across different tasks.
| Tasks | Supported Usages | Supported Models | Supported Datasets |
|---|---|---|---|
| Image Classification | Linear probe, zero-shot, CLIP adaptaion, PEFT | CLIP, BLIP, BLIP2, MedCLIP, BiomedCLIP, PubMedCLIP, DINOv2, DINOv3, AIMv2, RAD-DINO, RETFound, C2L, LVM-Med, MedMAE, MoCo-CXR, PLIP, SigLIP, SigLIP2, MedSigLIP, MedGemma, UNI2-h, Virchow2, Prov-GigaPath, CONCH, Merlin | CheXpert, MIMIC-CXR, HAM10000, FairVLMed10k, GF3300, PAPILA, BRSET, COVID-CT-MD, ADNI-1.5T |
| Image Segmentation | Interactive segmentation prompted with boxes and points | SAM, MobileSAM, TinySAM, MedSAM, MedSAM2, SAM2, SAM3, MedicalSAM3 (box), SAM-Med2D, FT-SAM | HAM10000, TUSC, FairSeg, Montgomery County X-ray, KiTS, CANDI, IRCADb, SPIDER |
Newly integrated foundation models (2023-2026)
- General vision: DINOv3 (Meta), SAM2 (Meta — vanilla checkpoint, shares the MedSAM2 build path; point
--sam_ckpt_path/--sam2_model_cfgat the official SAM2.1 weights/config), SigLIP2 (Google), AIMv2 (Apple)- Medical VLM: MedGemma (Google — feature extraction via its SigLIP-based vision tower)
- Pathology foundation models (new domain for this repo): UNI2-h (Mahmood Lab), Virchow2 (Paige), Prov-GigaPath (Providence), CONCH (Mahmood Lab, vision-language)
- Ophthalmology: RETFound (Nature, 2023/2024) — pairs naturally with the existing PAPILA/GF3300 eye datasets
- 3D CT: Merlin (Stanford, 2024) — volumetric CT feature extractor for ADNI/COVID-CT-MD/KiTS-style 3D data
Gated repos (request access on the model page, then
huggingface-cli login/ setHF_TOKEN): DINOv3, MedGemma, UNI2-h, Virchow2, Prov-GigaPath, CONCH, RETFound. Not covered byfairmedfm[cls]/[seg]: SAM2 needs thesam2package; CONCH needspip install git+https://github.com/Mahmoodlab/CONCH.git; Merlin needspip install merlin-vlm. SAM3 / MedicalSAM3 (2D): These use the official SAM 3 image model API. SAM3 supports the existing point and box prompts; MedicalSAM3 currently supports boxes only. Meta's package requires Python 3.12+, PyTorch 2.7+, and a compatible CUDA setup, so use a separate environment if the main FairMedFM environment is older. Download Medical SAM3'scheckpoint_2D.ptseparately. Neither checkpoint is part ofpretrained.zip. RETFound checkpoints: unlike the other gated models here, RETFound ships raw.pthfiles (not atransformers-loadable repo) — download manually after access is granted and pointconfigs/models/RETFound.json'spretrained_pathat the local file, the same convention used for MedMAE/MoCo-CXR/C2L.Not integrated (previously miscredited in this table): SAM-Med3D, FastSAM3D, and SegVol were listed here before but had no corresponding code anywhere in the repo. We looked into adding them: SAM-Med3D is loadable via the third-party
medimpackage, and SegVol viaAutoModel.from_pretrained("BAAI/SegVol", trust_remote_code=True), but both expose custom, undocumented inference APIs (3D sliding-window prompting,forward_test()with joint text/point/box prompts) that don't match this repo'sencode()/decode()segmentation wrapper contract (seewrappers/sam_model.py,wrappers/medsam2.py). Wiring them in correctly needs a new wrapper/trainer path built against their actual source, not just their README — left as follow-up work rather than shipped half-verified. FastSAM3D additionally has no documented Python inference API at all.
Schedule
-
Release the classification tasks.
-
Release the segmentation tasks.
- 2D dataset + 2D SAMs
- 3D dataset + 2D SAMs
- 3D dataset + 3D SAMs
-
Release more models
-
Release the preprocessed datasets for classification.
-
Release examples and tutorials.
Evolving
Your are welcome to post your thoughts about updated features and we will try to make this repo evolving as the development of more FMs.
Installation
To score your own model's predictions, pip install fairmedfm is all you need (see
above). To run the benchmark with the built-in foundation models:
-
Install the benchmark runner (Python 3.10+). Install PyTorch for your CUDA version first if needed.
pip install "fairmedfm[cls]"   # classification: linear probing, CLIP zero-shot and CLIP adaptation
pip install "fairmedfm[seg]"   # segmentation with SAM-family models (includes [cls])
A few models need packages that are not on PyPI: BLIP/BLIP2 (
salesforce-lavis, which pins older dependencies, so use a separate environment), CONCH (pip install git+https://github.com/Mahmoodlab/CONCH.git), Merlin (pip install merlin-vlm), SAM2 (sam2) and SAM3 (sam3). The runner reports which package is missing. -
Work in a directory that holds your data and checkpoints. Dataset and model configs refer to
./data/...and./pretrained/...; aconfigs/folder in the working directory overrides the packaged configs.wget https://object-arbutus.alliancecan.ca/swift/v1/86581f3bb67c4c04bbccbcb839de730a/rjin/pretrained.zip unzip pretrained.zip && rm -f pretrained.zip
-
Run an experiment with
fairmedfm run(examples under Running Experiment).
To use the environment from the paper instead, clone the repository and create the conda environment
(Python 3.8); python main.py then runs the same experiments as fairmedfm run:
git clone https://github.com/FairMedFM/FairMedFM.git && cd FairMedFM
conda env create -f environment.yml && conda activate fairmedfm
Our notebook tutorials also contains how to setup the environment in Colab.
Data
You can either download our pre-processed data directly (see next section) or pre-process customized data your self. However, not all dataset we used permit us to release the data on our end (e.g., dataset like MIMIC and ADNI requires the user go through their data usage application first). In such case, we cannot provide the download link of our preprocessed dataset for them, but we have the original dataset downloading link and our pre-process scripts released.
Preprocess data on your own
We provide data preprocessing scripts for each datasets here. The data preprocessing contains 3 steps:
- (Optional) preprocess imaging data.
- Preprocess metadata and sensitive attributes.
- Split dataset into training set and test set with balanced subgroups (for classification only).
Our data is downloaded uisng the following links.
Classification Dataset
| Dataset | Link |
|---|---|
| CheXpert | Original data Demographic data |
| MIMIC-CXR | MIMIC-CXR |
| PAPILA | PAPILA |
| HAM10000 | HAM10000 |
| OCT | OCT |
| OL3I | OL3I |
| COVID-CT-MD | COVID-CT-MD |
| ADNI | ADNI-1.5T |
Segmentation Dataset
| Dataset | Link |
|---|---|
| HAM10000 | HAM10000 |
| TUSC | TUSC |
| FairSeg | FairSeg |
| Montgomery County X-ray | Montgomery County X-ray |
| KiTS2023 | KiTS2023 |
| IRCADb | IRCADb |
| CANDI | CANDI |
| SPIDER | SPIDER |
Use Our Pre-processed Data
We offer data downloading through the S3 link. We are working to build this feature now.
Classification Dataset
| Dataset | Link |
|---|---|
| CheXpert | Requires application on original data provider. |
| MIMIC-CXR | Requires application on original data provider. |
| PAPILA | PAPILA |
| HAM10000 | HAM10000 |
| OCT | Waiting for more storage resources |
| OL3I | Waiting for more storage resources |
| COVID-CT-MD | Waiting for more storage resources |
| ADNI | Requires application on original data provider. |
Notebook Tutorial
We offer some examples of how to use our package through the notebook.
| Feature | Notebook |
|---|---|
| Linear Probing |  |
| CLIP Zero-shot and Adaptor | |
| Segmentation | |
Running Experiment
Run fairmedfm run --help or see parse_args.py for all options; in a source checkout, python main.py accepts the same arguments. The documentation covers working directories, configs, outputs and every model.
Classification
We provide an example of running a linear-probe (classification) experiment of the CLIP model on the CheXpert dataset to evaluate fairness on sex.
fairmedfm run --task cls --usage lp --dataset CXP --model CLIP --sensitive_name Sex --method erm --total_epochs 100 --warmup_epochs 5 --blr 2.5e-4 --batch_size 128 --optimizer adamw --min_lr 1e-5 --weight_decay 0.05
Segmentation (2D SAMs)
We also provide an example of using SAM with center point prompt on the TUSC dataset to evaluate fairness on sex.
fairmedfm run --task seg --usage seg2d --dataset TUSC --sensitive_name Sex --method erm --batch_size 1 --pos_class 255 --model SAM --sam_ckpt_path ./weights/SAM.pth --img_size 1024 --prompt center
For the newer 2D models, install the official sam3 package in a compatible environment with pip install git+https://github.com/facebookresearch/sam3.git, then run one of:
# SAM3: downloads Meta's gated checkpoint after Hugging Face access is granted.
fairmedfm run --task seg --usage seg2d --dataset TUSC --sensitive_name Sex --method erm --batch_size 1 --pos_class 255 --model SAM3 --img_size 1024 --prompt center

# MedicalSAM3: use the 2D Medical SAM3 checkpoint (not its 3D V2 checkpoint).
fairmedfm run --task seg --usage seg2d --dataset TUSC --sensitive_name Sex --method erm --batch_size 1 --pos_class 255 --model MedicalSAM3 --sam_ckpt_path /path/to/checkpoint_2D.pt --img_size 1024 --prompt bbox
The existing segmentation trainer is single-image only (--batch_size 1). Box and point prompts are derived from the ground-truth mask, so results are interactive segmentation scores, not unprompted segmentation scores. The new adapters restore the dataset's normalized BGR tensors to RGB pixels before SAM3 preprocessing.
MedicalSAM3 keeps detections above confidence 0.1 and uses the highest-scoring mask; an empty detection produces an empty mask. Run python -m pytest -q tests/test_sam3.py for checkpoint-free regression checks. These cover image conversion, prompt geometry, mask selection, empty detections, and checkpoint loading; actual checkpoint inference still needs validation in a SAM3-compatible environment.
Acknowledgement
We thank MEDFAIR for their pioneering works on benchmarking fairness for medical image analysis, and Slide-SAM for the SAM inference framework.
License
This project is released under the CC BY 4.0 license. Please see the LICENSE file for more information.
Citation
If you think our project is helpful and love our project, it's nice if you can cite us. Such supports will help us secure resources for further developing similar projects.
@article{jin2024fairmedfm,
  title={FairMedFM: Fairness Benchmarking for Medical Imaging Foundation Models},
  author={Jin, Ruinan and Xu, Zikang and Zhong, Yuan and Yao, Qiongsong and Dou, Qi and Zhou, S Kevin and Li, Xiaoxiao},
  journal={arXiv preprint arXiv:2407.00983},
  year={2024}
}
If you also use our companion benchmark MedVLMBench for capability evaluation, please cite:
@article{zhong2025can,
  title={Can Common VLMs Rival Medical VLMs? Evaluation and Strategic Insights},
  author={Zhong, Yuan and Jin, Ruinan and Li, Xiaoxiao and Dou, Qi},
  journal={arXiv preprint arXiv:2506.17337},
  year={2025}
}
1 maintainer

Metadata
1 maintainer
Release files for fairmedfm 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| fairmedfm-0.4.0.tar.gz | 108.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| fairmedfm-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 232.6 kB
Release files / fairmedfm-0.4.0.tar.gz
| Download URL | fairmedfm-0.4.0.tar.gz |
|---|---|
| Size | 108.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ae485abe30f442b3ead782bc8f47d72c7bd1d06b7dabdb348a343a8556253f3a
|
|
BLAKE2b-256 checksum How to use checksums |
1a39d369bbcc3a517dd7a44a4c3ac0cb6b712141a791fcb263b97f7e1d5c7630
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency logRelease files / fairmedfm-0.4.0-py3-none-any.whl
| Download URL | fairmedfm-0.4.0-py3-none-any.whl |
|---|---|
| Size | 124.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b86c1356b08493744f57c2d05bc63e01ce0190143d08bbf76eb340392f7bb922
|
|
BLAKE2b-256 checksum How to use checksums |
4532793a9c9d3cee7a8ebcc24d6907256bea9500a62f7af7b586a0a686e1a352
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency log













