
Catch event-loop blocking in FastAPI and see which requests were in flight.


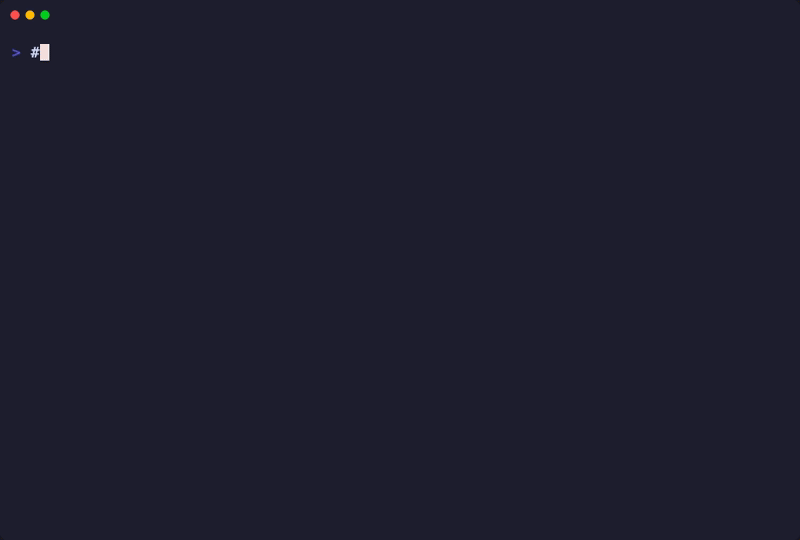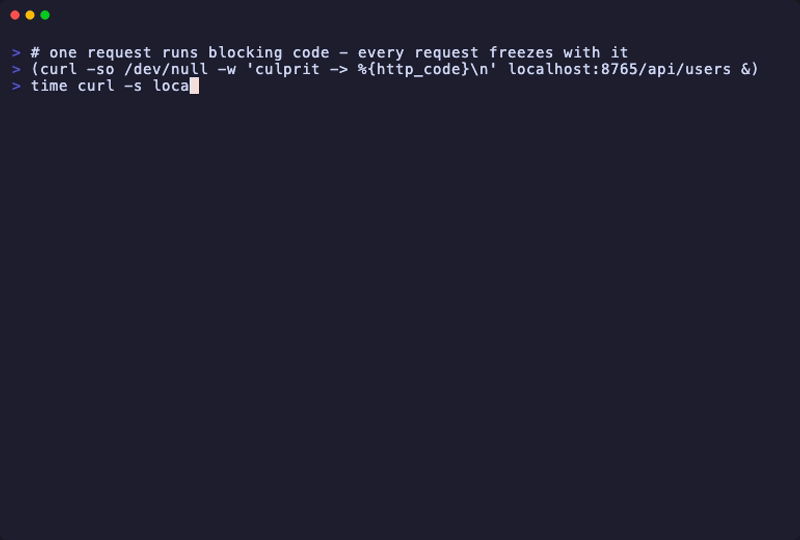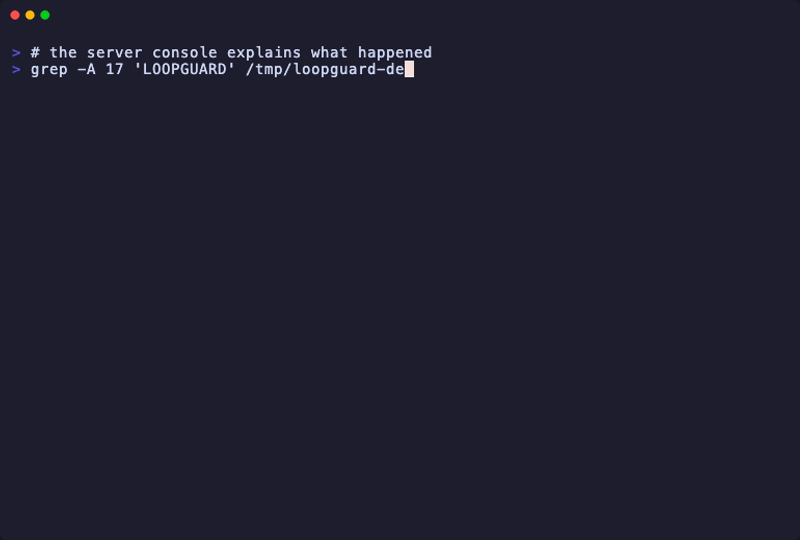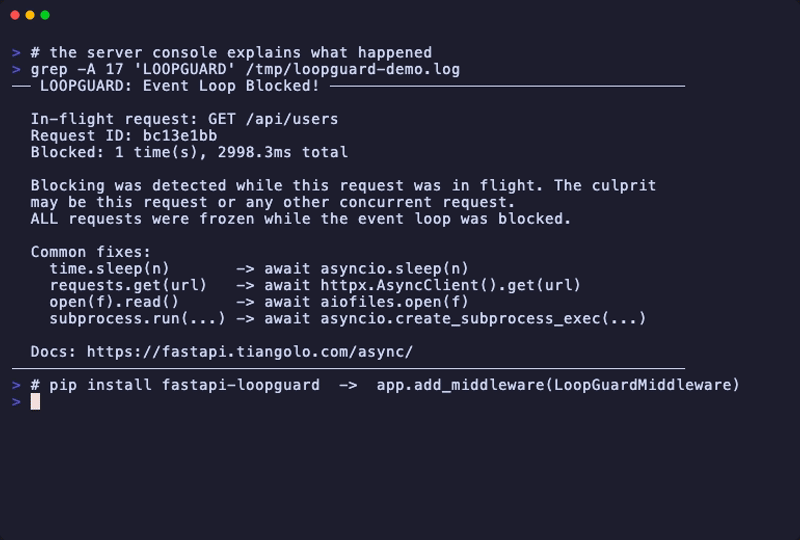
When something blocks your event loop (via time.sleep(), blocking I/O, or CPU work), LoopGuard detects it and narrows it down to the requests that were in flight when the loop stalled. The sentinel measures loop lag, so it cannot name the single guilty handler — it reports every request that was active during the stall.
Install
pip install fastapi-loopguard
Quick Start
# app.py
import asyncio
import time

from fastapi import FastAPI
from fastapi_loopguard import LoopGuardMiddleware

app = FastAPI()
app.add_middleware(LoopGuardMiddleware)


@app.get("/slow")
async def slow():
    time.sleep(0.5)            # blocking call inside async def: freezes the loop
    await asyncio.sleep(0.05)  # stands in for a real await (DB, HTTP, ...)
    return {"status": "ok"}
Serve it with whatever ASGI server you already use — uvicorn is the usual one
for FastAPI (pip install uvicorn, or pip install "fastapi[standard]").
LoopGuard does not depend on it.
uvicorn app:app --reload
The default mode is warn, so the request still succeeds and the diagnostic
headers say what the loop did:
$ curl -i http://127.0.0.1:8000/slow
HTTP/1.1 200 OK
server: uvicorn
content-length: 15
content-type: application/json
x-request-id: 59cb0aa5
x-blocking-count: 1
x-blocking-total-ms: 498.40
x-blocking-detected: true
x-loopguard-warning: blocking-detected

{"status":"ok"}
The console gets a matching banner for each request that was in flight during
the stall. What happens next is up to enforcement_mode.
The detection threshold is measured at startup, not fixed at
fallback_threshold_ms. Calibration usually settles below that 50 ms fallback
— 10 ms at the defaults — which is why an idle app can log a sub-50 ms
Event loop blocked ... (no active request) line; see
Detection Tuning
for the formula and how to change it.
Blocking calls, and what to write instead
time.sleep(n)           # -> await asyncio.sleep(n)
requests.get(url)       # -> async with httpx.AsyncClient() as client: await client.get(url)
open(path).read()       # -> await asyncio.to_thread(Path(path).read_text)
subprocess.run(cmd)     # -> proc = await asyncio.create_subprocess_exec(*cmd); await proc.wait()
tokenizer.encode(text)  # -> await asyncio.to_thread(tokenizer.encode, text)
That is the same list LoopGuard prints in its console banner, returns under
help.common_causes in the strict-mode 503, and writes to hints in
loopguard.json — it is defined once, in src/fastapi_loopguard/hints.py.
The last one is what catches AI services out, along with a sync OpenAI client
(client.chat.completions.create(...), fixed by AsyncOpenAI): a CPU-bound
tokenizer and a sync SDK both look like ordinary calls, and both stop every
other request on the worker until they return.
Enforcement Modes
| Mode | Behavior | x-blocking-* headers |
Use Case |
|---|---|---|---|
"warn" |
Console warnings | Yes, by default | Default |
"strict" |
HTTP 503 + error page | Yes, by default* | Development / CI |
"log" |
Silent logging | Only with dev_mode=True |
Production |
* The 503 itself carries a different set: x-request-id, x-blocking-count, x-blocking-total-ms and x-loopguard-enforcement: strict, but no x-blocking-detected. Strict mode's pass-through responses (no blocking seen) do carry it.
Strict mode 503s every request that was in flight during the stall, not just the one that blocked. The sentinel measures event-loop lag, so it cannot name the guilty handler. With 100 concurrent requests and one of them blocking, the other 99 also get a 503 — same body, same x-blocking-total-ms. That is why strict mode is opt-in, and why dev_mode cannot switch it on.
Streaming responses are a blind spot. Headers and the strict-mode 503 are both decided at http.response.start, which Starlette's StreamingResponse sends before the body generator runs. For StreamingResponse, SSE, and token-streaming endpoints, response headers and strict-mode 503s cannot report blocking that happens after the first chunk is on the wire. The log output and the console banner still report it — the monitor logs each event independently of the response, and "warn" and "strict" check again after the handler returns, which is late enough to see a stall that began mid-stream. One request prints at most one banner.
Each block below is complete on its own — copy one, not all three.
# Development / CI: fail loudly with an educational 503
from fastapi_loopguard import LoopGuardConfig, LoopGuardMiddleware

app.add_middleware(
    LoopGuardMiddleware,
    config=LoopGuardConfig(enforcement_mode="strict"),
)
# Production: silent logging
from fastapi_loopguard import LoopGuardConfig, LoopGuardMiddleware

app.add_middleware(
    LoopGuardMiddleware,
    config=LoopGuardConfig(enforcement_mode="log"),
)
# Production, but keep the diagnostic headers
from fastapi_loopguard import LoopGuardConfig, LoopGuardMiddleware

app.add_middleware(
    LoopGuardMiddleware,
    config=LoopGuardConfig(enforcement_mode="log", dev_mode=True),
)
What You Get
Strict Mode
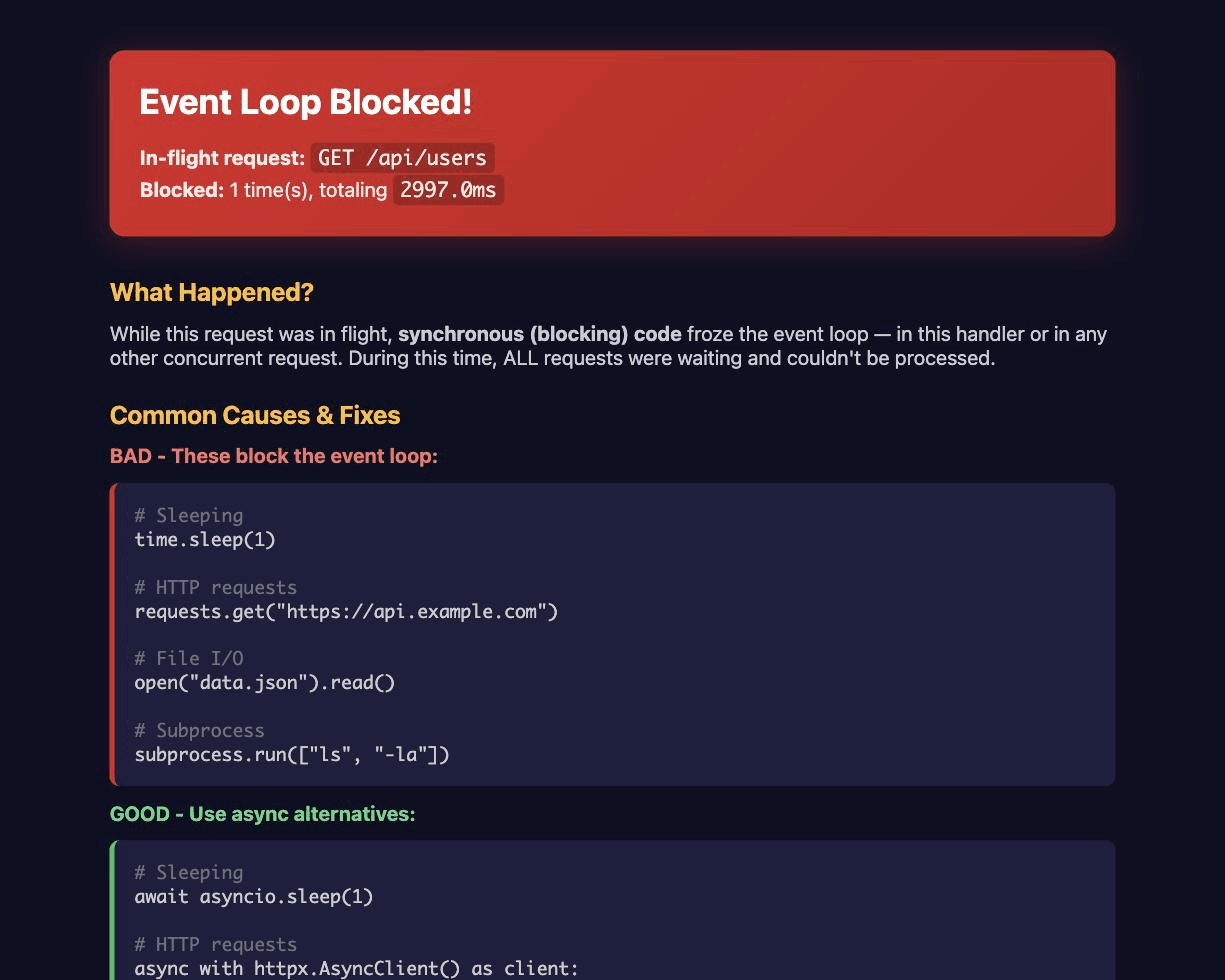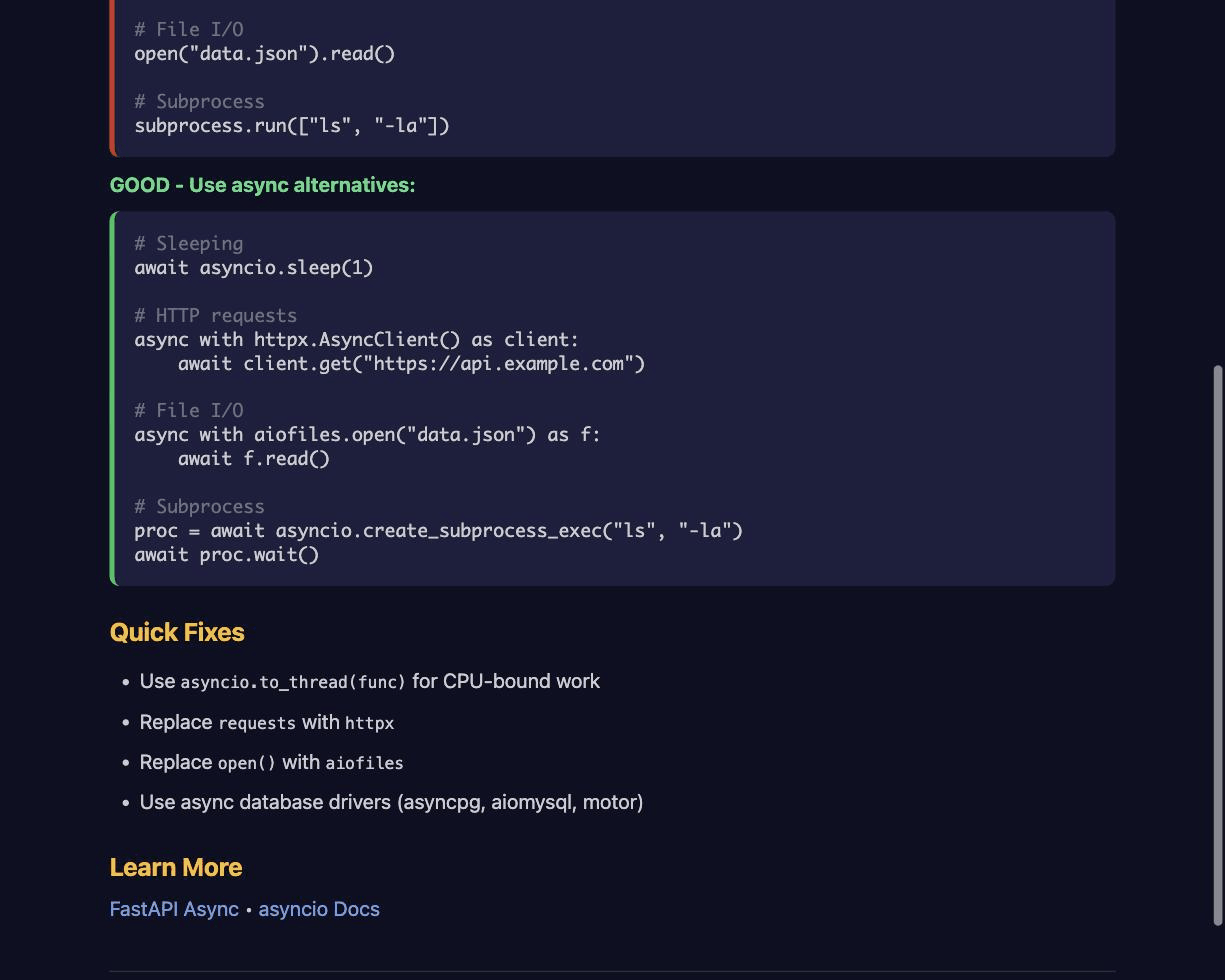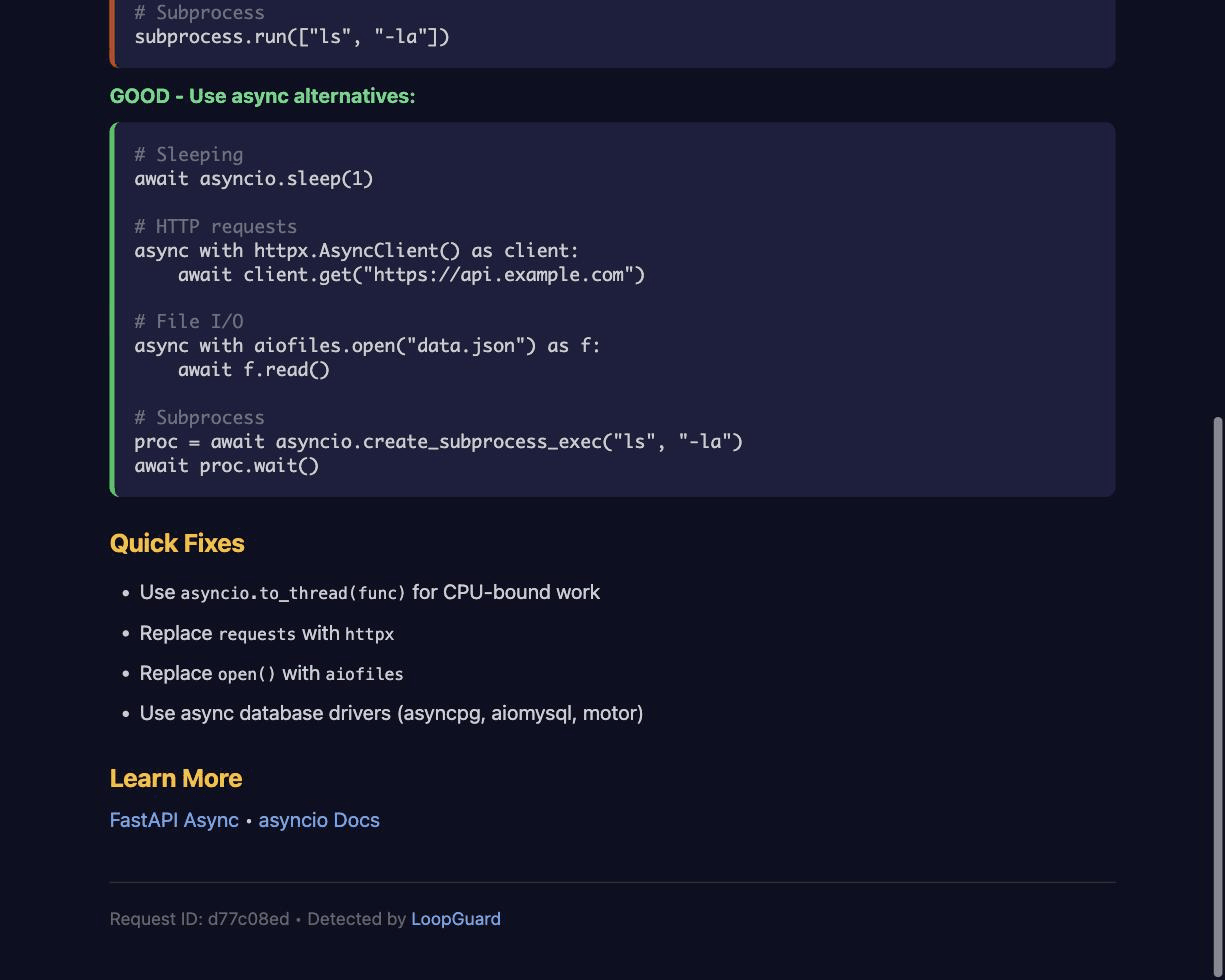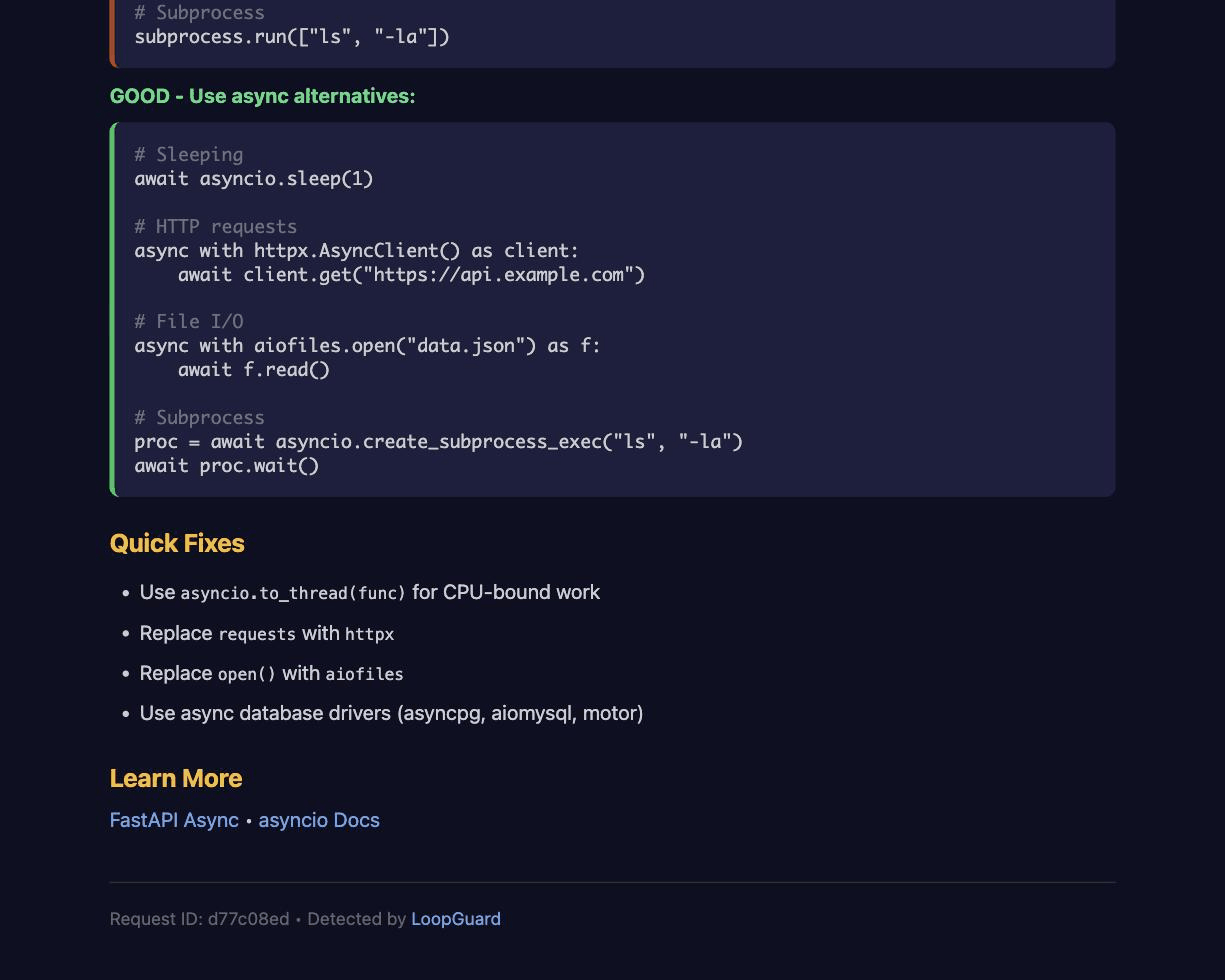
Returns an educational 503 page that explains what went wrong and how to fix it.
The HTML page below is served when the request's Accept header contains
text/html — a browser; curl, httpx and every other API client get the same
report as JSON:
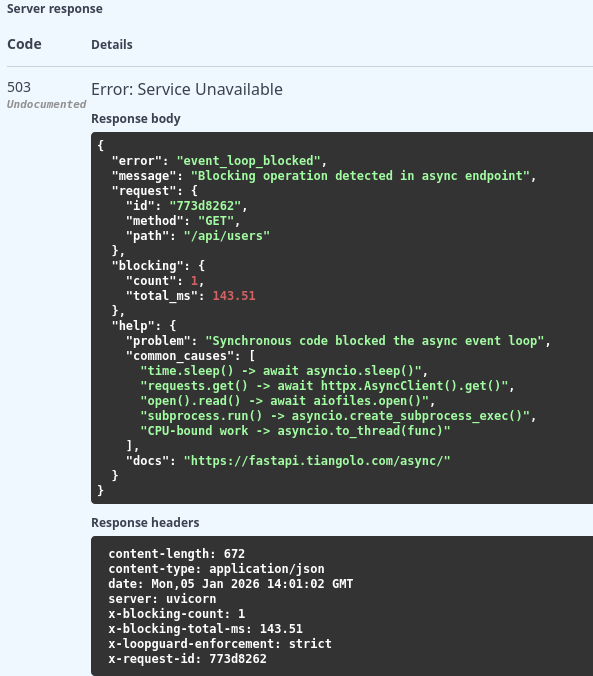
Warn Mode
Adds diagnostic headers to every response for debugging:
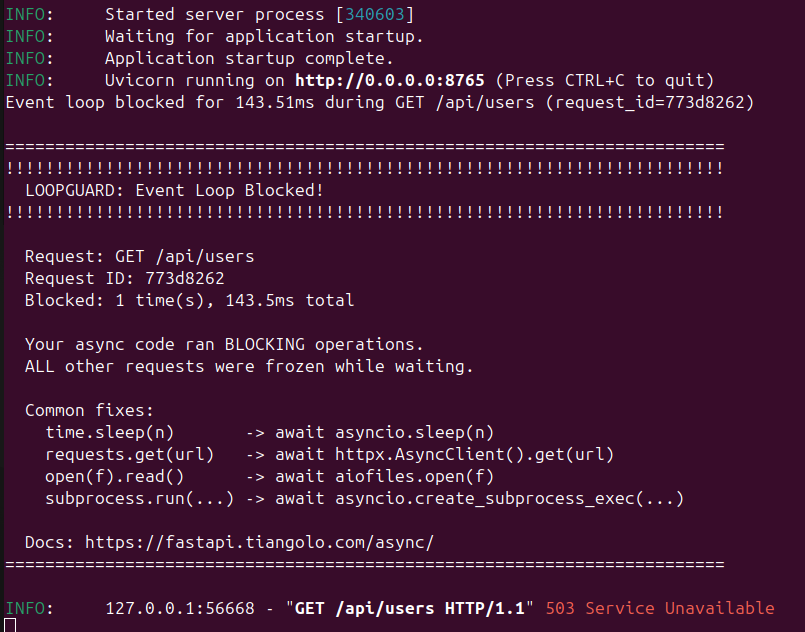
Log Mode
Writes one log line per event, listing the requests that were in flight — plain
text by default, JSON if you install LoopGuard's formatter with
configure_logging(structured=True):
Testing AI-Generated Code
Measured, not assumed: asked for ordinary endpoints with no warning, every one of seven benchmarked models blocked the event loop — 60 of 233 measured samples, GPT-4.1 in 21 of 37 (benchmark, N=5 per task, 2026-08). Adding one sentence — "the endpoint must not block the event loop" — removed every blocking verdict: 0 of 222. The bundled pytest plugin is that sentence, enforced. It turns blocking into a red test and a machine-readable report the agent can fix from, with no per-test annotations.
Async tests need pytest-asyncio (or anyio's pytest plugin) installed — pip install pytest-asyncio — with asyncio_mode = auto set, since pytest-asyncio's default strict mode errors on plain async def tests. loopguard_all_async makes every async test fail on blocking; loopguard_report writes verdicts and fix hints for the agent to loopguard.json:
# pytest.ini
[pytest]
asyncio_mode = auto
loopguard_all_async = true
loopguard_report = loopguard.json
The plugin ships inside the package and auto-registers through pytest's pytest11 entry point — nothing to add to conftest.py — and stays inert until you opt in with loopguard_all_async or a per-test @pytest.mark.no_blocking; docs/AI-HARNESS.md has the full option list, the report schema, the per-test threshold_ms override, the allow_blocking opt-out, a drop-in snippet for your project's agent instructions, and how a test whose event loop clock can't be trusted is reported unmeasured rather than a silently wrong clean.
Known limitations
Two are worth knowing before you wire this into anything:
- Streaming responses are a blind spot. Headers and the strict-mode 503 are decided before a
StreamingResponsebody runs, so blocking after the first chunk never reaches the response — see Enforcement Modes above. The log line and the console banner still report it. - Strict mode 503s every request that was in flight, not only the one that blocked — see Enforcement Modes above. That is why it is opt-in.
FINDINGS.md is the full list, including the design tensions deferred from the 0.5 and 0.6 correctness passes.
1 maintainer

Release files for fastapi-loopguard 0.8.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| fastapi_loopguard-0.8.0.tar.gz | 1.6 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| fastapi_loopguard-0.8.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.7 MB
Release files / fastapi_loopguard-0.8.0.tar.gz
| Download URL | fastapi_loopguard-0.8.0.tar.gz |
|---|---|
| Size | 1.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9100f511ee40a7f1e1b1e2c6b31b6b84beda9560061e080d1935d5d2ef2dcee3
|
|
BLAKE2b-256 checksum How to use checksums |
f891683f266e37d36ad83f3e0b5eced9b6c2044fb1634de4eb453e239b5fbef1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 12, 2026.
Transparency logRelease files / fastapi_loopguard-0.8.0-py3-none-any.whl
| Download URL | fastapi_loopguard-0.8.0-py3-none-any.whl |
|---|---|
| Size | 44.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3579b52d1b23640ab5c9551222376f1fc6b654f58c4abc996eabdf25d08ebd8e
|
|
BLAKE2b-256 checksum How to use checksums |
e59b15019c63fae2cecee4b7a2c79b87c604e1054f24f8b9ab0f55e219dd3573
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 12, 2026.
Transparency log













