
fde — a framework for Forward Deployed Engineers




Install · Quickstart · Architecture · Worked example · Contributing · PyPI · Website
fde is an open-source framework for Forward Deployed Engineers: it takes a client engagement from a problem statement to a runnable, deployable AI project — with every decision traced to a fact, and every fact traced to a source.
Not an agent framework — the thing that decides whether you need one, picks it as a stack when you do, and grades what it builds.
Forward deployed engineers arrive with incomplete information, a client who may not know what they need, and a deadline. This is the tooling for that: structured discovery and requirements intake, a decision engine that cites its evidence, and code generation that ends in something you can actually deploy — including on-premise, inside a customer VPC, or fully air-gapped.
pip install fde-framework
fde start acme --statement "Extract fields from supplier invoices."
fde ask acme --role admin        # role-scoped discovery interview
fde architect acme               # topology + chosen approaches (rationale lands in ARCHITECTURE.md)
fde build acme --out project     # refuses: eight gates guard the build
# ...verify data access, capture the baseline, name the eval owner (each gate prints its remedy), then:
fde build acme --out project     # code + evals + deploy assets + runbook
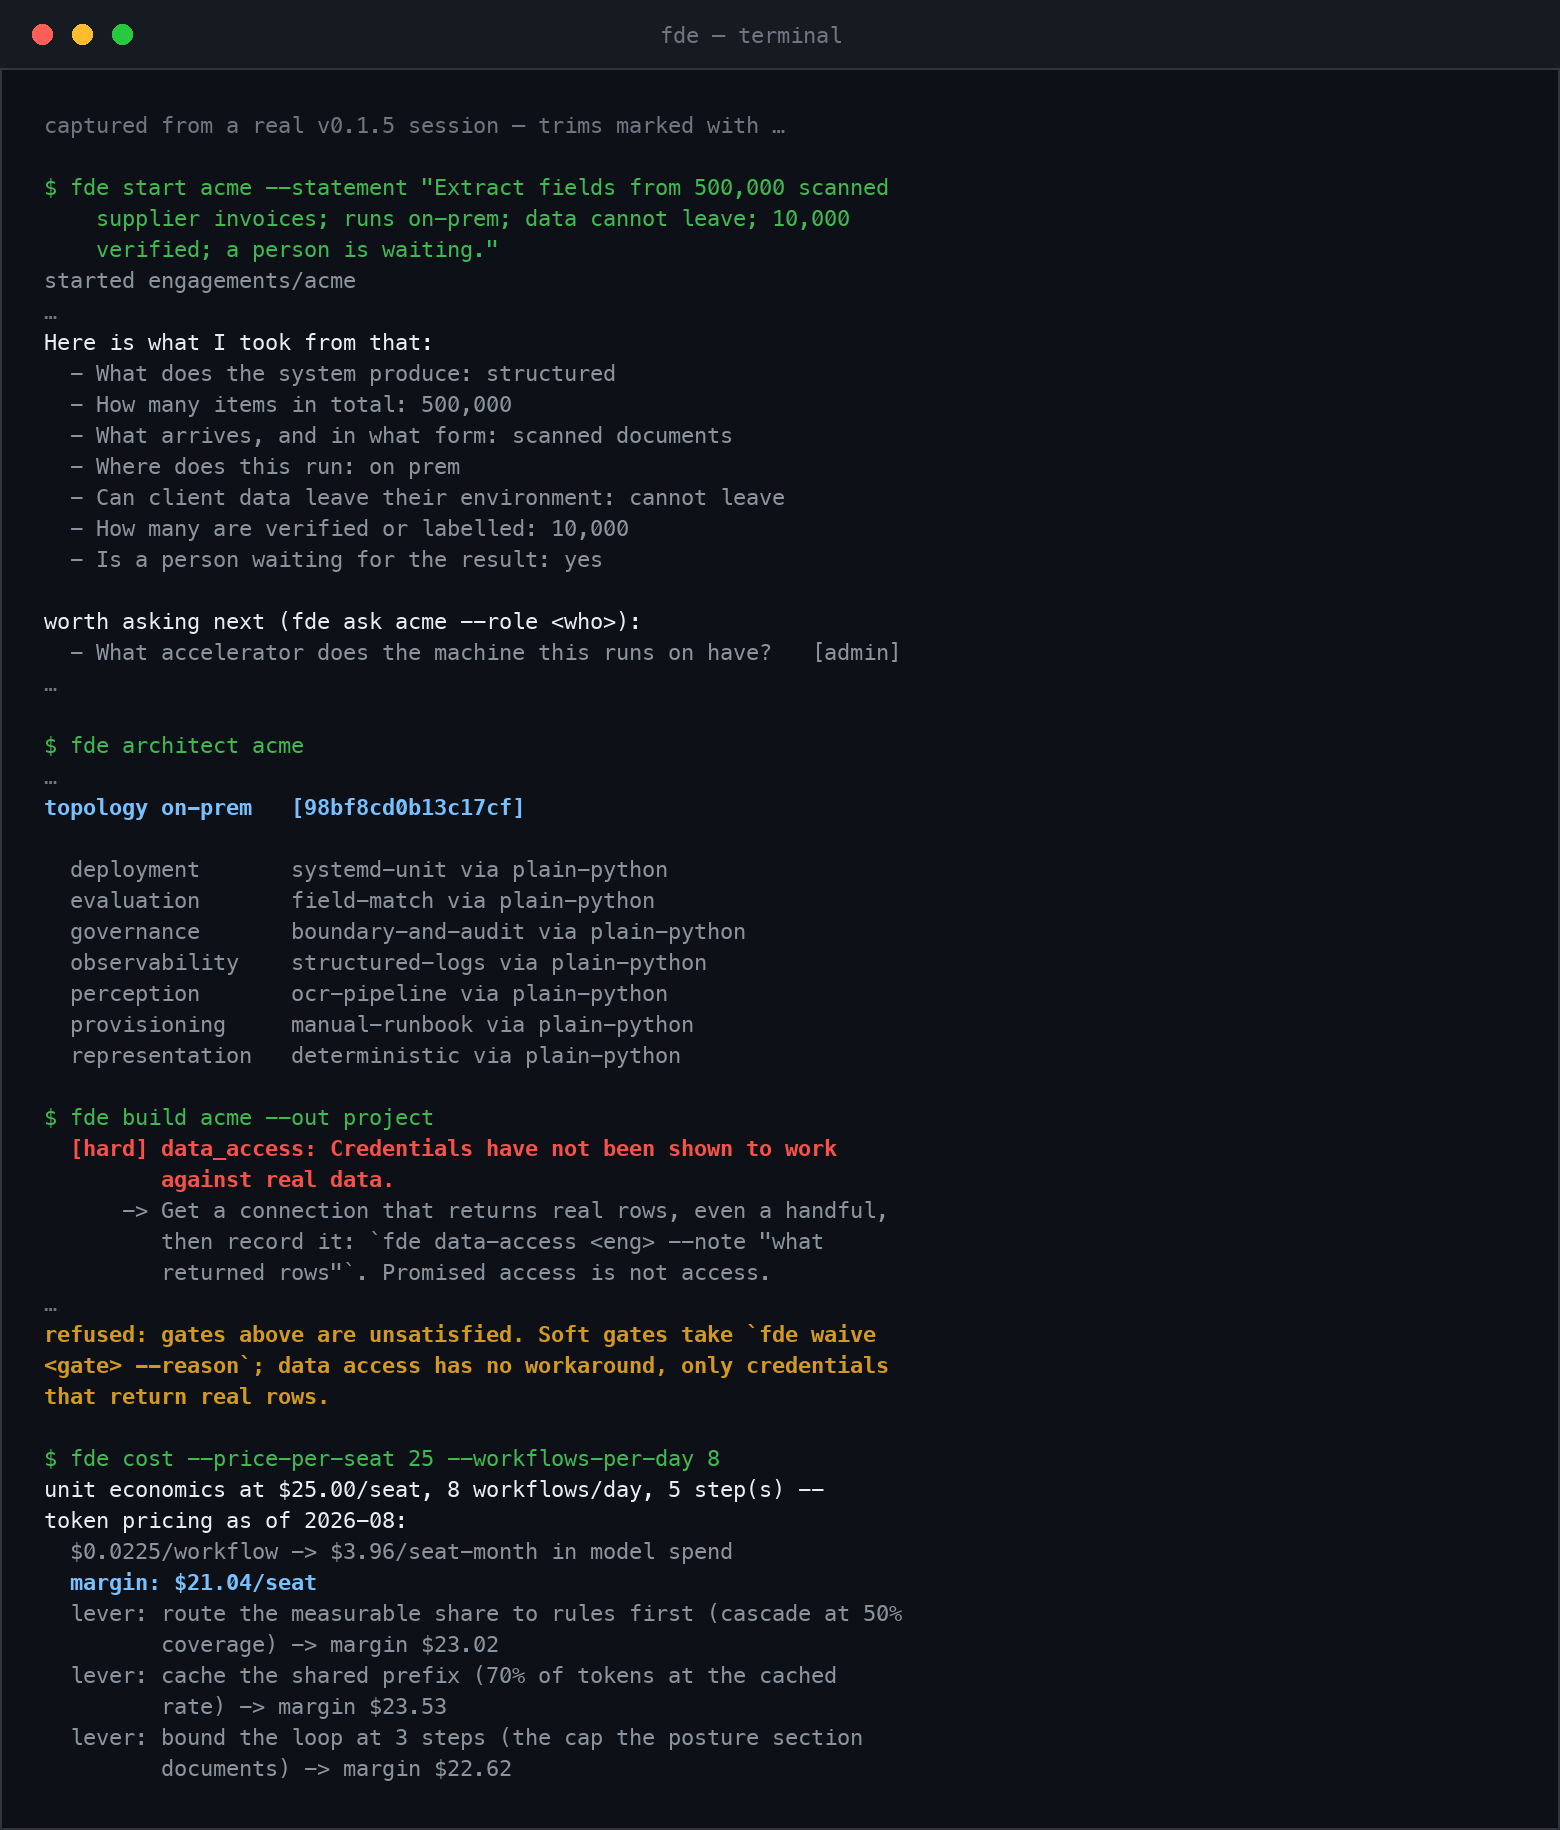
That refusal at the end is the product working: no baseline, no verified data access — no build. The remedies ship with every gate.
What it does
| Discovery that compounds | Prose, PDFs, sample pairs, a role-scoped interview and a hardware scan all feed one profile — provenance decides conflicts, never arrival order, and disagreement between people is surfaced as a finding |
| Gates before building | Eight checks with remedies; verified data access cannot be waived, and every waiver ships in the project's RISKS.md with its reason |
| Decisions with receipts | Simplest applicable approach per component, cited evidence, named rejected alternatives — and fde override records your call and honours it on every later run |
| A real project out | Pipeline in topological order — multi-modal inputs fan out one perception path per modality — fail-closed approval gates and critics, an eval harness CI can gate on — recall@K for the retrieval layer alone where one exists — deploy assets for the substrate that was actually earned, a runbook with a diagnosis walk, SLOs carrying the captured baseline, teardown A decision read off labelled text ships a fitted classifier that must beat the majority; a fine-tuning decision ships its data path -- recorded split, LoRA recipe, before/after on the holdout. |
| Deterministic by design | The decision path never calls an LLM: same profile, byte-identical project — a diff between builds means a decision changed. Model assistance exists only as opt-in commands, and the boundary doctrine governs them |
| Jurisdiction as data | Locale packs preset answers at the weakest provenance and attach dated compliance obligations to the build; they can never change how decisions are made |
| Self-evolution, honestly | Overrides, trigger calibration and anonymised cases are captured per engagement; the corpus grows only through human-reviewed ingestion |
| An engagement, not a build | The stage -- discovery, validation, prototype, pilot, production, adoption, retrospective -- is computed off the record, never declared. A drift check reads the deployed service's journal against the exam and opens an incident that pulls production back to pilot; a value estimate puts the measured system in the client's own figures, every line labelled measured, stated, assumed or derived |
How it fits together
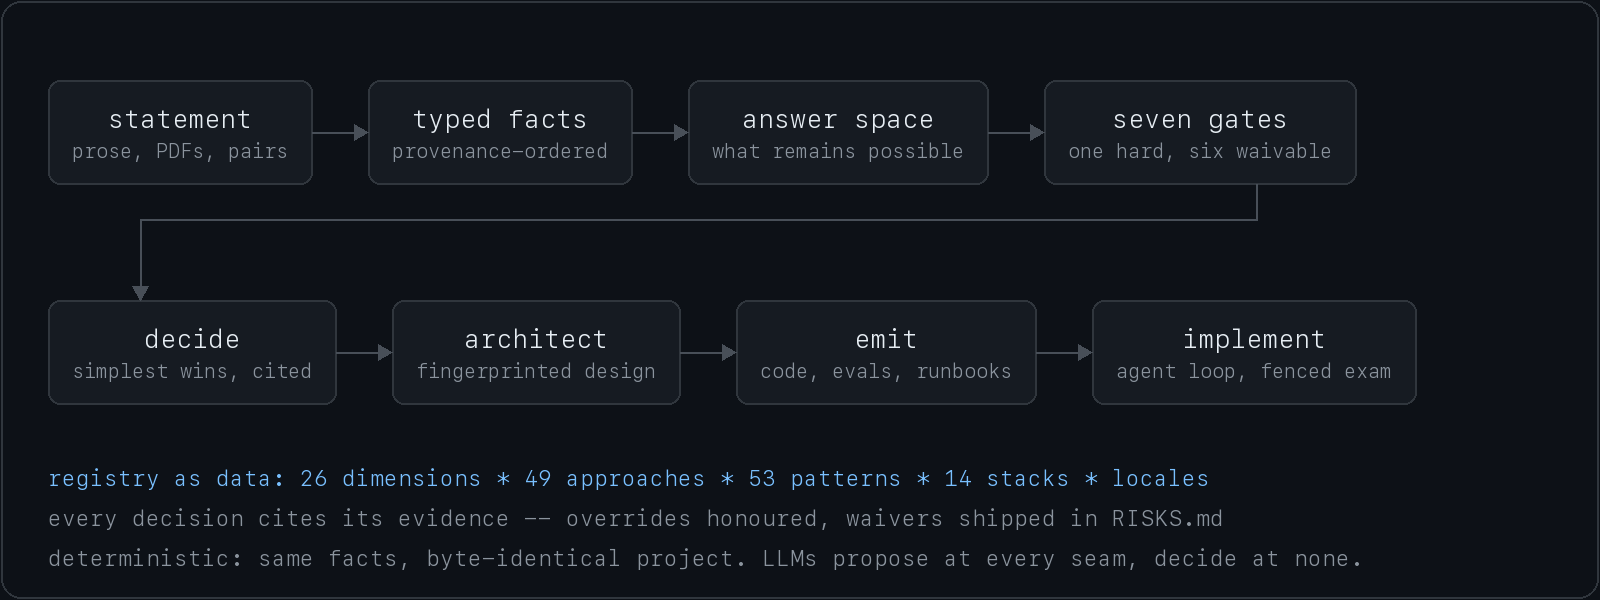
Discovery narrows an answer space; gates decide whether building is honest yet; the decision engine picks the simplest applicable approach per component and cites why; emit writes a project whose exam fails until it is truly implemented. The full design is in ARCHITECTURE.md.
Who this is for
- Forward deployed engineers and solutions engineers delivering AI systems inside client environments, where discovery, deployment constraints and handover matter as much as the model.
- Consultancies and AI delivery teams who want engagement knowledge to compound — every retrospective can enter a shared corpus as an anonymised case.
- Platform teams shipping LLM systems into regulated, on-premise, or air-gapped environments, where "call a hosted API" is not an option and the evaluation has to run where the system runs.
Status: built, demonstrated, unproven
Three different claims, and the differences are the point. Read as a ladder, so nothing here can be over-read:
| Claim | Status | The evidence, and where it stops |
|---|---|---|
| The framework is implemented | verified | 1,252 tests on three Pythons in CI; lint clean; every audit finding pinned as a check before it was fixed |
| A build is reproducible | verified | byte-identical rebuild pinned by test; each public demo carries a Reproduce section and its digests |
| The decisions generalise | partial | four shapes (extraction, freeform QA, a labelled decision, seventy-seven-way routing) on real data; one industry set; fde kb sweep names the shapes nothing serves |
| The deliverable is production-reliable | unverified | no production engagement; the banking operating loop ran on a laptop and its record says so |
| A business outcome moved | unverified | every VALUE.md rests on stated figures; no outcome has been recorded on any engagement |
| An FDE is faster or righter with it | unverified | no comparison against an engineer working without it |
Demonstrated: four complete engagements have run end to end on real
data, all public with every refusal preserved.
fde-demo-receipts —
626 scanned receipts through gates, build, and an agent-driven implement
loop (fde implement, graded against held-out cases the agent never sees)
whose holdout refused an overfit implementation and whose measured plateau
flipped the design from rules to a model, reason on the record.
fde-demo-complaints —
2,034 real consumer complaints through the decision shape: the exam
refused ambiguous ground truth before it existed, the agent posture was
decided from the facts, and the loop finished green with the holdout
passing — the framework's first.
fde-demo-rfc-qa —
freeform QA over 58 real RFCs: 100% recall@10 on real queries, a green
loop, and then the calibration gate refusing its own judge exactly as
the prediction published beforehand said it would (73.7% agreement,
refused; the judge's 89.5% was 26 points of flattery over the hand-graded
63.2%). Six of this framework's releases (0.1.6–0.1.11) shipped from what
these runs found -- and after five independent audit passes reshaped the
emitter (0.1.17–0.1.21), the complaints engagement was built and implemented
again on 0.1.21: green in round 2, holdout 76.7% against the original's
63.3%, the run committed beside the original for comparison. A sixth pass,
widened to the exam, the components and the fine-tuning path, signed off
the freeform shape with conditions and refused the decision shape for
reasons that were the generator's; 0.1.22 answered each as a check first.
A seventh pass found those checks holding and the shape-specific work
stopping short -- a mis-specified baseline, an in-sample exam, a training
recipe that trained unshuffled on a prompt it never served -- and 0.1.23
answered again the same way. 0.1.24 then ran the fine-tuning recipe for
real on a small base model: the adapter learned the house style on cases
it never saw, and the six defects that run exposed in the harness, the
serving path and the comparison are fixed and pinned. An eighth pass gave
the decision shape its first sign-off, with conditions, and 0.1.25 met
them: probes on typical cases, label phrases rather than words, a merge
path that trains, a comparison that says what it can claim. A ninth pass
read the first industry run and the scorecard that measured it, and found
the card measuring self-consistency rather than fitness; 0.1.27 gave it
fitness rows -- the generalisation gap, an external exam a memoriser cannot
pass, the engagement's own error-rate bar -- and gave the routed decision
an abstain path and a reason on every answer.
fde-demo-banking —
an industry use case: support intent routing for a retail bank over
13,083 real messages and seventy-seven queues (Banking77). The framework's
own reading of a seventy-seven-way decision, its brief parser, its label
rule and one governance template each failed on it and were fixed before
a number was quoted; the finished deliverable is an assist-mode router
that abstains and says why, at 90.2% on what it routes with 18% handed to
a person, scored on a 3,036-case holdout and the vendor's own test split,
with fde scorecard saying which rows measure fitness and which measure
self-consistency.
Built: the pipeline exists end to end — intake (prose, documents, sample
pairs, role-scoped interview, hardware scan) → fact log with provenance →
permutation space → eight gates → decide → architect → build (code, evals,
deploy and ops assets, RISKS.md, COMPLIANCE.md) → retro and case
capture. Overrides are honoured on the next run, trigger observations feed
calibration, and a reviewed case can enter the corpus. 1160+ tests; nine
fresh-eyes audit passes, every finding resolved and the fix pinned as a
regression test; CI gates on the suite, lint, and a sanitisation scan of
the tree and its history; the evidence corpus is anchored to publicly
documented production deployments; every decision is reproducible from its
inputs.
Unproven means exactly one thing: no production engagement has yet run
through it start to finish. The proof loop is wired and waiting — fde retro captures measured outcomes, human-reviewed cases grow the corpus,
and rule revision begins when there are retrospectives to revise against,
not before. Pretending earlier would be borrowing rigour rather than having
it.
What that means for you today: the generated projects are real and the decisions are defensible, but you are an early adopter, not a reference customer — and the first measured retrospectives will be worth more to this framework than any feature.
Side by side. BENCH.md
reads the same figures off all four records with fde bench: stage, the
out-of-sample rows on each card, the gap, incidents. The banking run is the
one where the whole operating loop has run in public -- two field streams
through the delivered build, a drift incident opened and closed on the
record, a value document -- and its
README
says what the deployment was (a laptop) and what the campaign was (a
drill).
| Engagement | Stage | Card | Holdout | On the answered | External |
|---|---|---|---|---|---|
| receipts | pilot | 17/22 | 56.7% on 30 | 56.7% | -- |
| complaints | pilot | 17/22 | 73.9% on 46 | 75.6% | -- |
| rfc-qa | prototype | 16/23 | 30.0% on 10 | 30.0% | -- |
| banking | production (a laptop, attested as such) | 23/24 | 77.5% on 3,036 | 86.6% | 75.8% on 3,079 |
Two rules
Every intake surface — prose, interviews, scans, sample pairs, the client's existing stack — emits facts into one profile, and two rules make that safe. Arrival order never decides anything — provenance does, and it is dimension-dependent: a measurement outranks anything said about the environment, while a stated requirement outranks a measurement, since you cannot detect a latency budget. And two people disagreeing is a finding, not a conflict to resolve; the dimension is left unresolved and reported, because the gap between what a sponsor believes and what a user experiences is usually the most valuable thing discovery produces.
The full pipeline those rules feed — space pruning, decomposition, the seven gates, decision, emission — is in ARCHITECTURE.md.
What it will not do
Recommend a tool because it is fashionable. plain-python is a first-class
option in every pattern, and the schema rejects any pattern that omits it. A
two-step linear workflow should not get a graph framework, and the framework has
to be able to say so.
Reach for a container by default. Deployment substrate is a ladder from a systemd unit through to Kubernetes. For a single-node on-prem deployment serving one model to a team with no container competence, rung zero is the right answer.
Assume a jurisdiction, sector, topology or stack. Everything is a discovered parameter with a sensible default. A locale pack may pre-set values on dimensions that already exist and attach obligations to the build; it may never introduce a new dimension, because geography changes what you must produce, not how you decide.
Guess. Every claim carries evidence, a date, and a re-derivation rule. Where the framework has no evidence, it says so — undecidable components ship as modules that raise with the reason attached, never as silent gaps.
Install
Prerequisites: Python 3.11+.
pip install fde-framework          # the registry ships inside the wheel
fde start acme --statement "..."   # works from any directory
Extras: pip install "fde-framework[documents]" for PDF/docx intake, [llm]
for the hosted-model reader path.
Or from source (contributors — a local ./framework outranks the packaged copy):
git clone https://github.com/atulkapoor/fde-framework.git
cd fde-framework
python3 --version   # must say 3.11+; an older python3 makes pip backtrack for ages instead of failing fast
python3 -m venv .venv && .venv/bin/pip install -e ".[dev,documents]"
Or with uv: uv venv && uv pip install -e ".[dev,documents]"
Optional extras
| Extra | Installs | For |
|---|---|---|
documents |
pypdf, python-docx | fde frame --file brief.pdf — PDF and Word intake |
dev |
pytest, ruff | running the test suite and linter |
The core needs none of them: plain-text intake, the decision engine and the build work with zero optional dependencies, which is deliberate — an air-gapped install should not drag in what it will not use. A missing reader refuses by name and says exactly what to install.
File types
| Intake | Formats |
|---|---|
| Read as text | .txt .md .rst .csv .json .yaml |
With documents extra |
.pdf .docx |
| Refused by name | .doc .pptx .xlsx (and anything unrecognised) — reading a container's bytes as text produces facts from noise, which is worse than reading nothing |
| Sample pairs | .jsonl — {"id", "input", "output", "verified"} per line |
Try it
fde start acme --statement "Extract fields from supplier invoices."
fde ask acme --role admin        # bare names resolve to ./engagements/acme
fde status acme                  # gates, gaps, disagreements
fde architect acme               # the design, with rationale
fde build acme --out project     # refuses until gates clear

fde scan acme                    # what this hardware runs
fde cost --requests-per-day 500000 --model-b 70   # dated fleet sizing

fde kb validate   # parse and cross-link the registry
fde kb gaps                        # what the corpus is missing
fde kb sweep                       # profiles no approach can serve
kb validate is strict, because CI runs it and a warning nobody reads is not a
check. --lenient exists for the hour when you are mid-way through authoring
content and the links do not resolve yet.
A complete worked engagement — real transcript, synthetic client — lives in examples/invoice-extraction.
What a build emits
project/
├── app/                  # components, pipeline, controls, boundary check
│   ├── components/       #   implementations or honest scaffolds — never silent gaps
│   ├── pipeline.py       #   topological order; approval gates before anything mutative
│   ├── controls.py       #   fail-closed gates & critics — when anything mutative was decided
│   ├── boundary.py       #   imported at startup when data may not leave
│   ├── contract.py       #   RefusedInput: forbidden input is refused, never guessed at
│   └── llm.py            #   the one model touchpoint — when a decision needs a model (boundary-gated)
├── evals/                # golden / edge / adversarial sets from the client's own pairs
│   ├── harness.py        #   fails CI until implemented; judge-based when the evaluation decided judged
│   ├── retrieval.py      #   recall@10/50 of the retrieval layer alone — when retrieval answers ranked queries
│   ├── acceptance.md     #   blind UAT protocol for the client's own judges, with the exam record
│   ├── manifest.json     #   split seed, holdout share, SHA-256 of every eval file and the holdout
│   └── load.py           #   p95 against the stated budget (when one was stated)
│   ├── shapes.py         #   the one envelope every step reads and writes; refusals at the door
│   ├── service.py        #   the HTTP edge: identity, request ids, framing, readiness, drain
│   └── ledger.py         #   append-only audit + idempotency keys under STATE_DIR — when anything is outward
├── tests/                # the deliverable's own model-free smoke: contract, fence, empty-exam refusal
├── train/                # when fine-tuning was decided: recorded split, LoRA recipe, before/after on the holdout
├── deploy/               # the substrate that was earned, its full install path, + TEARDOWN.md for all of it
├── ops/                  # runbook (first-five-minutes commands up top), diagnosis walk, SLOs, rollback
├── ARCHITECTURE.md       # scope read-out, decisions, tools & alternatives, agent posture
├── RISKS.md              # every waived gate and overridden recommendation
└── COMPLIANCE.md         # jurisdiction obligations, when a locale pack was applied
Emitted quality is a pinned property, not a promise: the framework's own
test suite emits projects across representative architecture shapes and
holds every emission to the operational contract — every environment
variable the code reads is documented, everything the systemd unit demands
is created by a shipped installer, CI has a lane that goes green without a
model, the smoke test passes on a fresh emission, the code is lint-clean,
the payload path composes end to end and refuses garbage at the door, a
caller cannot forge a result, a hostile document or a long query costs
milliseconds, the journal stays one JSON line per event under threads, an
error closes its connection, a bad corpus file is skipped and counted, the
boundary refuses an endpoint outside it, the ledger survives a restart and
a torn line, a stopword cannot cite a document and a one-document corpus
still answers, compaction cannot drop a live key, every eval entry point
honours the boundary, an oversized corpus refuses the boot with one line,
readiness degrades rather than denies on a stray file, and the service
carries a request id on every answer, a truncated query is never a silent
miss, two processes cannot both reserve one key, a decision read off
labelled text ships a fitted classifier that refuses to serve a constant,
refuses an exam that changed since the build, beats the majority on the
holdout and says which of its scores are in-sample, the exam's probes and
edges come from cases the baseline was not fitted on and each steering
probe says what it steers toward, an uncalibrated judge is red until asked
for by name, a fact learned from a person is marked asserted rather than
established, and a fine-tuning decision ships a recipe that trains on the
prompt it serves -- and the deliverable ships its own edge tests, which
its CI runs. Eight independent audit passes took it from "every request
500s" to a sign-off with conditions on the decision shape. A quality finding lands there as a check before
it lands anywhere as a fix (tests/test_acceptance.py,
tests/test_finetune.py). And the claim is
measurable per build: fde scorecard <project> --holdout <file> --external <file> runs what the deliverable can prove about itself and writes
SCORECARD.md with a verdict that is a count of rows, never an adjective,
and says which rows measure fitness and which measure self-consistency.
After the build: the engagement's operating loop
fde build used to be where the framework stopped. An engagement does not
stop there, so the record now carries the rest of it, and every part of it
is either computed from evidence or attested by a named person -- never
declared by the tool.
fde stagecomputes where the engagement stands. Each stage is a set of criteria the record shows or does not: a statement; gates passing or waived, pairs seeded, a holdout drawn, data access attested; a build with its exam; a scorecard whose out-of-sample rows hold and whose edge answered a valid request; a deployment on record with no open incident; an adoption figure measured in the field; a retrospective captured as a case. Every transition is appended tolifecycle.jsonlwith its evidence, so time-to-pilot and every reversal can be read back.fde driftreads the deployed service's journal -- the sameansweredlines the emitted service writes -- and compares abstention, decision mix, errors and margins against the exam and the last scorecard. Past a threshold it opens an incident on the record and exits 1. An open incident pulls production back to pilot;fde incident closeneeds a note saying what was done.fde valuewritesVALUE.md: the automated share and its accuracy from the holdout row, hours and money from the recorded baseline, build and run costs from the caller, payback, and a Wilson interval on the accuracy. Every line says what it rests on, so the number is argued row by row.fde deployedandfde outcomeare attestations: where it runs and who put it there; adoption, time to first value, whatever the client measured.fde outcomesprints what the record shows without anyone's opinion -- transitions, days to pilot, loop rounds, reversals, incidents.fde stakeholdersmaps the engagement's people as the record shows them: which of the five roles has been heard (every session carries the role and, when given, the name), who signed what (--byon data-access, security-review, waive, deployed, outcome and incident close), which roles were never asked, and what is on the record with nobody's name on it.fde stakeholder addnames the people who have not spoken yet. It is a map, not a contact list.fde importturns a client export --.csv,.tsv,.jsonl,.json, with the client's column names -- into the pairs the intake reads, and reports what it kept, skipped for an empty side, dropped as a duplicate, and counts as verified. Nothing is verified unless the caller says which column and value means a person checked it.fde benchreads the same figures off every engagement record, side by side: stage, the out-of-sample rows on its card, the gap, incidents, days to pilot.BENCH.mdis the four public demos, computed this way.fde historyprints every dated entry on the record in order, the undated ones above it, one line each -- the page to read when picking an engagement up.fde outcome-contractis the eighth gate: owner, metric, its value today, its target, how it is measured and over what window. Nobody builds until somebody has agreed which number the system exists to move, or waived that with a reason that ships in RISKS.md. The adoption stage then reads the contracted metric back from what was measured in the field.fde debtis the decision debt: everything the engagement rests on that nobody has settled -- a gate still failing, a waiver standing in for a condition, a fact the framework guessed or a person merely said where a measurement was possible, two people disagreeing, an attestation with no name on it, a role never asked, an incident open, a component nothing serves -- each with an owner, what blocks on it, and its age.fde nextnow says what hangs on the question it asks: the evidence already on record for that dimension, every candidate answer tried, and the decisions that turn on it -- so the question is asked knowing why.fde stop-whenrecords what evidence would stop the engagement --answered_accuracy < 0.88,abstain_rate > 0.25,adoption < 0.4-- over figures the record measures: the scorecard's out-of-sample rows, the field journal, the outcomes recorded in the field. A triggered condition makes STOP the engagement's stage, on the record with the trigger and the threshold, until the condition is restated with a reason, the build is changed and scored again, or the case is captured. A figure the record has not measured leaves its condition unjudged and says so.
What this still is not: a live connector to a ticketing or data system (an export is the interface, and the only one testable without a client's credentials); a benchmark corpus (four public demos are four rows, and the bench says so); collaboration beyond a git-native record with names on it. Each waits for engagements that have not happened yet.
The full lifecycle, copy-paste
Everything below runs from an empty directory after pip install fde-framework:
fde start acme --statement "Extract fields from scanned supplier invoices; \
data cannot leave; 200,000 documents, 8,000 verified; a person is waiting."
# plays back the typed facts it read, and the three questions worth asking next

fde ask acme --role eval_owner       # answer what discovery still needs
fde status acme                      # facts by scope, gates, % settled

cat > baseline.yaml <<'YAML'
volume: {value: 20000, unit: docs/month, definition: invoices received by AP}
cycle_time_per_unit_seconds: {value: 300, unit: s, definition: arrival to posted}
labour_hours_per_week: {value: 35, unit: h/week, definition: AP team keying time}
rework_rate: {value: 0.1, unit: ratio, definition: entries corrected after post}
exception_rate: {value: 0.07, unit: ratio, definition: routed to a human queue}
error_rate: {value: 0.04, unit: ratio, definition: wrong amount or vendor posted}
business_metric: {value: 9, unit: days, definition: mean days payable outstanding}
sampled: {n: 40, method: random invoices across two months}
YAML
fde baseline acme --file baseline.yaml
fde data-access acme --note "read replica returned 14 real rows"
fde security-review acme --note "client infosec walked the data paths"
fde ask acme --role eval_owner       # or: fde waive acme client_readiness --reason "..."

fde build acme --out project         # refuses until the gates truly pass
python project/evals/harness.py      # red: empty until pairs are seeded, then red until implemented -- that's the exam
fde implement project                # drive a coding agent until it's green
fde scorecard project --holdout engagements/acme/artifacts/holdout.jsonl   # measure it

fde stage acme --project project     # where it stands, computed off the record
fde deployed acme --note "runs in the client VPC; platform team put it there"
fde drift acme --journal service.log --project project   # the field against the exam
fde incident acme close inc-001 --note "holdout re-scored; pairs redrawn"
fde outcome acme --metric adoption=0.62 --note "support lead's dashboard, week 3"
fde value acme --project project --hourly-cost 40        # VALUE.md, line by line
Python API
The CLI is a thin layer; everything is importable. The registry loads from the installed wheel, so this runs anywhere:
from fde.architect import architect
from fde.intake.prose import parse_prose
from fde.models.profile import Profile
from fde.registry import default_root, load_registry

registry = load_registry(default_root())

profile = Profile()
profile.ingest(parse_prose(
    "500,000 scanned invoices; data cannot leave; 10,000 verified; "
    "a person is waiting; structured records out.", registry))

design = architect(profile, registry)
print(design.topology)                    # customer-vpc
for component, decision in sorted(design.decisions.items()):
    if decision.approach:
        print(component, decision.approach, decision.rationale)
Every decision object carries its rationale and its rejected alternatives —
the same receipts the emitted ARCHITECTURE.md prints.
Common commands
fde start <name> --statement "..." |
begin an engagement |
fde frame <eng> --file brief.pdf |
prose or documents → facts, played back for correction |
fde frame <eng> --reader llm --endpoint http://localhost:11434 |
a local model proposes what the deterministic reader missed, at weakest provenance |
fde samples <eng> --file pairs.jsonl |
input/output pairs → contract, metrics, golden/edge/adversarial evals (--sensitive <field> marks fields for masking) |
fde ask <eng> --role admin |
role-scoped interview, ordered by what changes the design |
fde ask <eng> --role admin --scope non_functional |
one scope axis at a time — the dedicated NFR pass |
fde scan <eng> |
measure the hardware, and get a local-model plan sized to it (runtime, judge, coder) |
fde next <eng> |
The single best next action, judged from everything recorded — ask it any time |
fde status <eng> |
gates, gaps, waivers, disagreements |
fde baseline / data-access / security-review / waive / restate |
satisfy or knowingly waive a gate |
fde cost --price-per-seat 25 --workflows-per-day 8 |
unit economics with the levers priced; --requests-per-day N --model-b B for dated fleet sizing |
fde kb suggest --file brief.md --endpoint http://localhost:11434 |
mine a brief for recogniser gaps — proposed, never applied |
fde kb export-training <eng> --out train.jsonl |
(brief, facts) pairs — the fine-tune flywheel, kept with the engagement |
fde reuse <eng> <stack> |
record what the client already operates, so reuse can beat adoption |
fde locale <eng> eu-gdpr |
jurisdiction pack: presets plus obligations emitted as COMPLIANCE.md |
fde architect <eng> |
the design, rationale and rejections |
fde build <eng> --out project |
emit; refuses while gates block |
fde implement project/ |
drive a coding agent until the emitted evals pass, inside guardrails |
fde scorecard project/ --holdout <file> |
measure production grade: every property the deliverable can prove, with the number, in SCORECARD.md |
fde stage <eng> |
where the engagement stands, computed from the record; transitions appended to lifecycle.jsonl |
fde deployed <eng> --note "..." |
attest the deployment: where it runs and who put it there |
fde drift <eng> --journal <log> |
the field against the exam: abstention, mix, errors, margins; opens an incident and exits 1 when it moved |
fde incident <eng> list | close <id> --note "..." |
incidents on the record; an open one holds the stage at pilot |
fde outcome <eng> --metric adoption=0.62 / fde outcomes <eng> |
outcomes measured in the field; what the record shows without opinion |
fde value <eng> --hourly-cost 40 |
VALUE.md: the measured system in the client's figures, every line measured, stated, assumed or derived |
fde stakeholders <eng> / fde stakeholder <eng> add --name --role --stake |
who has been heard, who signed what, which roles were never asked |
fde import <eng> --file tickets.csv --input body --output queue --verified-when checked=yes |
a client export into pairs, with a report; then fde samples |
fde bench <eng>=<project> ... |
the same figures off every record, side by side, in BENCH.md |
fde history <eng> |
every dated entry on the record in order, one line each |
fde outcome-contract <eng> --owner --metric --baseline --unit --target --method --window |
the eighth gate: which number this system exists to move, from what to what, measured how, by when |
fde debt <eng> |
decision debt: what nobody has settled, with an owner, what it blocks, and its age |
fde stop-when <eng> --when "answered_accuracy < 0.88" |
what evidence would stop the engagement; judged against the record, exit 1 and a STOP stage when triggered |
--by "<name>" on data-access, security-review, waive, deployed, outcome, incident close |
the signer's name on the record; the stakeholder map points at entries without one |
fde triage --statement "..." --statement "..." |
rank candidate problems by what discovery can already decide |
fde override --component X --choose Y --because "..." |
your call, recorded and honoured |
fde observe / retro |
record trigger firings; capture the case |
fde kb validate / gaps / sweep |
registry health, work items, dead zones |
Why not RAGAS or TruLens?
Deliberately. Their headline metrics are judge-scored, and an uncalibrated judge is the failure mode this framework has now measured first-party: a local judge inflated results by 26 points before the calibration gate refused it (the run is public). The emitted evals are seeded from the client's own verified examples, stdlib-only — they run inside an air gap and hand over with zero dependencies — reference-based with discrete verdicts, and no judged number is quoted before the judge beats a human-agreement bar against the named eval owner. If your team wants RAGAS or TruLens dashboards alongside, point them at the same golden pairs — the JSONL is the same shape. The gate a delivery is graded on stays calibrated, or stays silent.
Troubleshooting
no registry here — you passed --registry/--root at a directory that
holds no registry. Drop the flag (the corpus ships inside the package) or
point it at the framework/ of a source checkout.
build refuses with gates listed — that is the point. fde status
names each gate and its remedy; soft gates take fde waive <gate> --reason,
data access takes only credentials that returned real rows.
A component module raises UndecidedComponent — nothing could be
decided for it; the raise message names the unanswered question. Answer it
and rebuild — holes are loud here, never silent.
fde kb sweep shows undecidable profiles — some are honest
contradictions (data cannot leave + nobody to operate). fde architect on
that profile names the conflicting facts.
The evaluation harness fails CI — it evaluates the emitted pipeline; it fails until the components are implemented end to end. A gate that cannot say no is not a gate.
Design
The registry under framework/ is data, not code. Adding a stack, a pattern, a
locale or a case is a file, never a change to src/. That constraint is enforced
by tests, and it is the thing that keeps the framework general rather than
gradually becoming one consultancy's tooling.
Patterns are separated from stacks because patterns are stable for years and the libraries implementing them churn in months. A pattern says what; one realization per stack says how, as a template plus a claim to satisfy a typed interface. Swapping the stack changes the emitted code and not the architecture, and there is a test asserting exactly that.
FAQ
What is a Forward Deployed Engineer? An engineer who works inside a client's environment to deliver a working system — part solutions architect, part implementer, part translator between what a client asks for and what they need. The role is common in AI companies shipping into enterprises; this framework encodes the craft of running such an engagement well.
Does the framework itself call an LLM? No. Intake parsing, decision-making and code generation are deterministic — the same profile always produces the same project, so a diff between two builds means a decision changed. LLMs appear in the generated systems where the profile justifies one, behind interfaces that make them swappable.
Does it work air-gapped? Yes, by design. The framework runs from plain files with no server or network dependency, the registry knows which stacks can run inside an air gap, and the offline-evaluability gate refuses a design whose metric cannot run where the system runs.
How is this different from a project template? A template gives everyone the same starting point. This decides — from discovered facts, with cited evidence and named rejected alternatives — and then generates. Two clients with different constraints get different architectures, and the document explains why.
How does it improve over time? Every engagement captures its overrides (when the FDE chose differently), trigger calibration (did predicted graduations fire?), and an anonymised case. Cases enter the corpus only after human sanitisation review; rules are revised only when a corpus of outcomes exists — capture now, revise later, never pretend.
What does "self-evolving" mean here, concretely?
Three recorded signals — overrides, trigger observations, case outcomes — and
a human-gated path from a retrospective into the shared knowledge base.
Nothing in framework/ changes by itself; the corpus grows, and revision
against it is a deliberate, evidenced act.
Privacy
Everything runs from plain files on your machine. The default path makes no network calls, has no telemetry, and never transmits engagement content anywhere — it works on a plane and inside an air gap, and a text editor is always a legal way into its state. Discovery, decisions, and builds never call an LLM.
Four commands are the deliberate exceptions — each opt-in, each governed by the boundary doctrine (hosted models refused unless the engagement states data may leave; local endpoints always allowed):
fde frame --reader llm— a model proposes facts, at the weakest provenancefde kb suggest— mines a brief for recogniser gaps, proposing (never applying) vocabularyfde implement— drives a coding agent you name- the judge-based eval harness in generated projects whose evaluation
decided
judged(LLM_ENDPOINT, hosted path refused inside a boundary)
Nothing calls a model silently, and fde scan recommends a local model
sized to your hardware so none of it needs to leave the machine.
Engagement directories (client facts, baselines, gate state) are excluded from version control by construction and enforced in CI — along with credential patterns, personal-data patterns, and a check that no unreviewed case can ever be committed.
Team setup
The registry is the shared asset; engagements are private working state.
- Share
framework/— fork or clone it as your team's knowledge base. Every dimension, approach, stack and case is a markdown file; review registry changes like code, because they decide architectures. - Never commit
engagements/— client facts stay local. The repository's own.gitignoreand CI sanitisation gate enforce this shape; keep it in yours. - Grow the corpus deliberately —
fde retrocaptures a case,fde kb ingest-caselands it assanitization: pending, a human reviews it for anything identifying, and onlyreviewedcases can be committed. One reviewed case per delivered engagement compounds fast.
Roadmap
- Rule revision from outcomes — capture is wired end to end; revision deliberately waits for a corpus of measured retrospectives rather than pretending a handful is evidence.
- More locale packs and stacks — both are data; contributions enter against CONTRIBUTING.md's contract (and the code of conduct).
- Language, channel, and device axes — six of twenty industry test statements named regional languages, low bandwidth, or basic devices; the honest wiring (per-language evaluation, SMS/IVR serving approaches, safeguarding governance) is a corpus milestone, not a checkbox.
- Scale words — "millions of applications", "tens of millions of players": refusing to guess a number from "millions" is doctrine, and a better answer than refusal is still owed.
- Capability-verb extraction — "update the claims system of record"
implies an integration no regex can count; the LLM reader proposes facts
today, and component hints are its natural next job.
The honest gaps list lives in the tool itself:
fde kb gapsandfde kb sweepreport what the corpus is missing and which profile shapes no approach can serve yet.
Documentation
| I want to… | Read |
|---|---|
| Run the whole lifecycle once | The full lifecycle, copy-paste |
| See a real transcript with expected output | Worked example |
| Understand the moving parts | ARCHITECTURE.md |
| Understand a gate that just refused me | fde status <eng> — every gate names its remedy and its clearing command |
| See complete engagements on real data, refusals preserved | fde-demo-receipts · fde-demo-complaints · fde-demo-rfc-qa · fde-demo-banking |
| Pick a local model with receipts | Local models, measured |
| Add a dimension / approach / template | CONTRIBUTING.md — incl. the template context table |
| Use it as a library | Python API |
| Report a vulnerability | SECURITY.md |
| See what changed | CHANGELOG.md · Releases |
Development
Set up as in Install → from source (python3.11+), then:
.venv/bin/pip install -e ".[dev,documents]"
.venv/bin/pytest -q          # 1160+ tests, ~ 100s
.venv/bin/ruff check src tests
The registry is data: most contributions are a markdown file in framework/
plus a test that pins the behaviour. CI additionally runs a sanitisation sweep
over the tree and history.
Community
Questions and engagement war stories → Discussions. Bugs and corpus gaps → issues (the forms ask for evidence, the way the framework does). Conduct → CODE_OF_CONDUCT.md.
License
Apache 2.0 — chosen for the explicit patent grant, because enterprise legal review is a real gate for the audience this is for.
Contributing
See CONTRIBUTING.md. The short version: contributions enter against a contract, and client material never enters this repository — only patterns re-expressed in the framework's own words. Sanitisation is enforced in CI: allowed paths only, history checked, credential and personal-data patterns, and no unreviewed case can be committed.
1 maintainer

Release files for fde-framework 0.1.32
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| fde_framework-0.1.32.tar.gz | 589.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| fde_framework-0.1.32-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.1 MB
Release files / fde_framework-0.1.32.tar.gz
| Download URL | fde_framework-0.1.32.tar.gz |
|---|---|
| Size | 589.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d444283cd90137a5560520bb76f102be02c0c09e6363bfec16f8d0fd97d16426
|
|
BLAKE2b-256 checksum How to use checksums |
471962337d15a8b236c3b74b3edb98cbcfc944517d2bce203b95660f049bda40
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency logRelease files / fde_framework-0.1.32-py3-none-any.whl
| Download URL | fde_framework-0.1.32-py3-none-any.whl |
|---|---|
| Size | 534.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8dfefed57f16ea6009753330cb441800b9e4963e8edb537e95bb5e6600e0f7d4
|
|
BLAKE2b-256 checksum How to use checksums |
5f63eea3422bc5f80501cb07f0b8fcc2d8d8757319eee57883a83cefb3e9acfe
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency log













