
FDet - Deep Learning Face Detection



The fdet is a ready-to-use implementation of deep learning face detectors using PyTorch.

You can use it directly in your code, as a python library:
>>> from fdet import io, RetinaFace

>>> detector = RetinaFace(backbone='RESNET50')
>>> detector.detect(io.read_as_rgb('path_to_image.jpg'))
[{'box': [511, 47, 35, 45], 'confidence': 0.9999996423721313,
  'keypoints': {'left_eye': [517, 70], 'right_eye': [530, 65], 'nose': [520, 77],
                'mouth_left': [522, 87], 'mouth_right': [531, 83]}}]
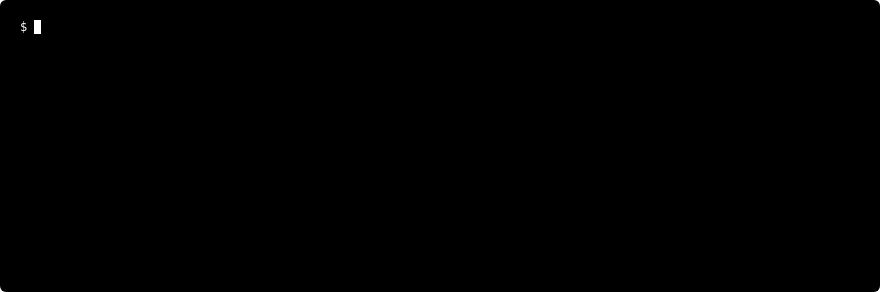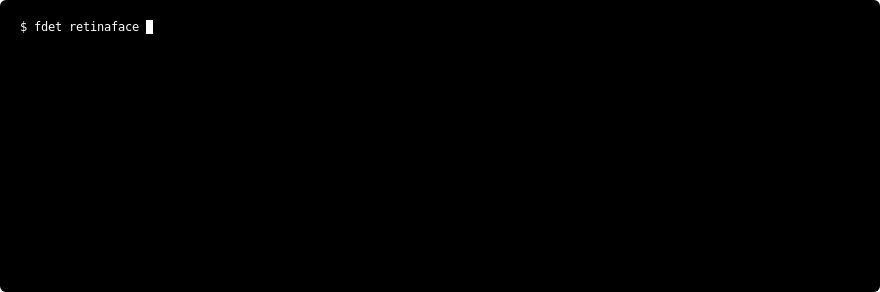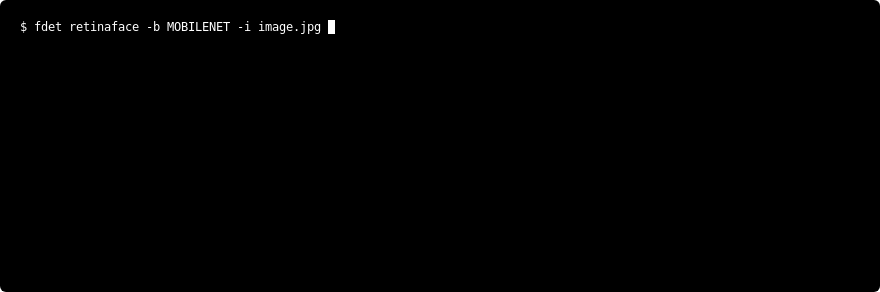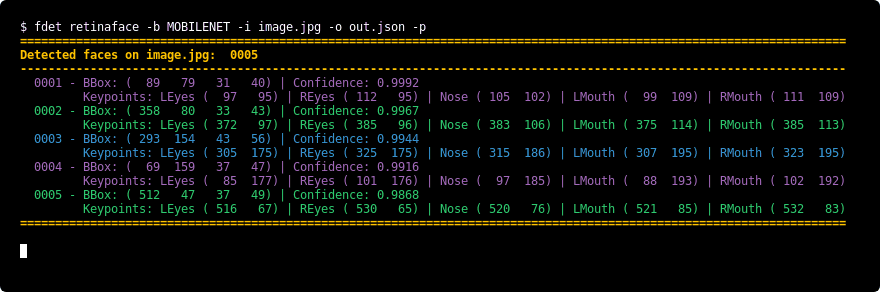
Or through command-line application:
fdet retinaface -b RESNET50 -i path_to_image.jpg -o detections.json
Features
Currently, there are two different detectors available on FDet:
- MTCNN - Joint face detection and alignment using multitask cascaded convolutional networks [zhang:2016]
- RetinaFace - Single-stage dense face localisation in the wild. [deng:2019]. You can use it with two different backbones:
- MobileNet: Fast and light-weighted model (achieves high FPS)
- Resnet50: A medium-size model for better results, but slower.
Despite the availability of different implementations of these algorithms, there are some disadvantages we found when using them. So we create this project to offer the following features, in one package:
- ⭐ Real-time face detection;
- ⭐ Support for batch detection (useful for fast detection in multiple images and videos);
- ⭐ Ease of use through python library or command-line app;
- ⭐ Provide a unified interface to assign 'CPU' or 'GPU' devices;
- ⭐ Multiple GPU's support;
- ⭐ Automatic on-demand model weights download;
- ⭐ Compatible with Windows, Linux, and macOS systems.
Installation
-
You need to install PyTorch first (if you have a GPU, install PyTorch with CUDA support).
-
Then
fdetcan be installed through pip:
pip install fdet
Python Library Usage
If you want to use fdet from python, just import it,
from fdet import MTCNN, RetinaFace
and instantiate your desired detector, with its respective parameters:
-
MTCNN(thresholds, nms_thresholds, min_face_size, cuda_enable, cuda_devices)thresholds(tuple, optional): The thresholds fo each MTCNN step [default: (0.6, 0.7, 0.8)]nms_thresholds(tuple, optional): The NMS thresholds fo each MTCNN step [default: (0.7, 0.7, 0.7)]min_face_size(float, optional): The minimum size of the face to detect, in pixels [default: 20.0].cuda_enable(bool, optional): Indicates wheter CUDA, if available, should be used or not. If False, uses only CPU processing [default: True].cuda_devices(list, optional): List of CUDA GPUs to be used. If None, uses all avaliable GPUs [default: None]. Ifcuda_enableis False, this parameter is ignored.
-
RetinaFace(backbone, threshold, nms_threshold, max_face_size, cuda_enable, cuda_devices)backbone(str): The backbone model ['RESNET50'or'MOBILENET'].threshold(tuple, optional): The detection threshold [default: 0.8]nms_threshold(tuple, optional): The NMS threshold [default: 0.4]max_face_size(int, optional): The maximum size of the face to detect, in pixels [default: 1000].cuda_enable(bool, optional): Indicates wheter CUDA, if available, should be used or not. If False, uses only CPU processing. [default: True].cuda_devices(list, optional): List of CUDA GPUs to be used. If None, uses all avaliable GPUs. [default: None]. Ifcuda_enableis False, this parameter is ignored.
The detector classes listed above have two methods to perform the face detection:
Singe-Image Detection Example
The following example illustrates the ease of use of this library to detect faces in a single-image using MTCNN and to create an output image with all detected faces drawn.
>>> from fdet import io, MTCNN
>>>
>>> detector = MTCNN()
>>> image = io.read_as_rgb('example.jpg')
>>>
>>> detections = detector.detect(image)
>>> print(detections)
[{'box': [511, 47, 35, 45], 'confidence': 0.9999996423721313,
  'keypoints': {'left_eye': [517, 70], 'right_eye': [530, 65], 'nose': [520, 77],
                'mouth_left': [522, 87], 'mouth_right': [531, 83]}}]
>>>
>>> output_image = io.draw_detections(image, detections, color='white', thickness=5)
>>> io.save('output.jpg', output_image)
The detector returns a list of dict objects. Each dict contains three main keys:
'box': The bounding box formatted as a list[x, y, width, height];'confidence': The probability for a bounding box to be matching a face;'keypoints': The five landmarks formatted into adictwith the keys'left_eye','right_eye','nose','mouth_left','mouth_right'. Each keypoint is identified by a pixel position[x, y].
The io.read_as_rgb() is a wrapper for opencv cv2.imread() to ensure an RGB image and can be replaced by:
image = cv2.imread('example.jpg', cv2.IMREAD_COLOR)
image = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)
Batch Detection Example
The library is also capable of performing face detection on image batches, typically providing considerable speed-up. A batch should be structured as list of images (numpy arrays) of equal dimension. The returned detections list will have an additional first dimension corresponding to the batch size. Each image in the batch may have one or more faces detected.
In the following example, we detect faces in every frame of a video using batchs of 10 images.
>>> import cv2
>>> from fdet import io, RetinaFace
>>>
>>> BATCH_SIZE = 10
>>>
>>> detector = RetinaFace(backbone='MOBILENET', cuda_devices=[0,1])
>>> vid_cap = cv2.VideoCapture('path_to_video.mp4')
>>>
>>> video_face_detections = [] # list to store all video face detections
>>> image_buffer = [] # buffer to store the batch
>>>
>>> while True:
>>>
>>>     success, frame = vid_cap.read() # read the frame from video capture
>>>     if not success:
>>>         break # end of video
>>>
>>>     frame = cv2.cvtColor(frame, cv2.COLOR_BGR2RGB) # convert to RGB
>>>     image_buffer.append(frame) # add frame to buffer
>>>
>>>     if len(image_buffer) == BATCH_SIZE: # if buffer is full, detect the batch
>>>         batch_detections = detector.batch_detect(image_buffer)
>>>         video_face_detections.extend(batch_detections)
>>>         image_buffer.clear() # clear the buffer
>>>
>>> if image_buffer: # checks if images remain in the buffer and detect it
>>>     batch_detections = detector.batch_detect(image_buffer)
>>>     video_face_detections.extend(batch_detections)
Command-line Usage
Credits
The FDet was written heavily inspired by the other available implementations (see credits).
The current MTCNN version was implemented with the help of Davi Beltrão.
References
-
[zhang:2016]: Zhang, K., Zhang, Z., Li, Z. and Qiao, Y. (2016). Joint face detection and alignment using multitask cascaded convolutional networks. IEEE Signal Processing Letters, 23(10), 1499-1503. (link to paper)
-
[deng:2019]: Deng, J., Guo, J., Zhou, Y., Yu, J., Kotsia, I. and Zafeiriou, S. (2019). Retinaface: Single-stage dense face localisation in the wild. arXiv preprint arXiv:1905.00641. (link to paper)
License
1 maintainer

Metadata
1 maintainer
Release files for fdet 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| fdet-0.2.1.tar.gz | 26.5 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| fdet-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 51.9 kB
Release files / fdet-0.2.1.tar.gz
| Download URL | fdet-0.2.1.tar.gz |
|---|---|
| Size | 26.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fc8645eff7b90661f16187da12a9ff24a73ce1fdb103ed500254dad9ce9aca11
|
|
BLAKE2b-256 checksum How to use checksums |
cf5f0a55d882ca91724c8ec83c725c73f0cb45fcef0235b97b1cbbc1050bfce0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.5.0.1 requests/2.23.0 setuptools/41.2.0 requests-toolbelt/0.9.1 tqdm/4.46.0 CPython/3.8.2
|
Release files / fdet-0.2.1-py3-none-any.whl
| Download URL | fdet-0.2.1-py3-none-any.whl |
|---|---|
| Size | 25.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
dcd04e2658a0aafc52c61c289f354a20002e3ee48b33efcf4a8c86b59a917977
|
|
BLAKE2b-256 checksum How to use checksums |
108dff18917a2ef1c3d8f0596f18a6f81a451b23541ad9c436dd366e7e857ffa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.5.0.1 requests/2.23.0 setuptools/41.2.0 requests-toolbelt/0.9.1 tqdm/4.46.0 CPython/3.8.2
|
Security for fdet 0.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














