

feedback-manager


Framework-agnostic feedback management and agent learning: capture, correlate, store, route, resolve, and learn from feedback, for LangChain, LangGraph, and custom agents.
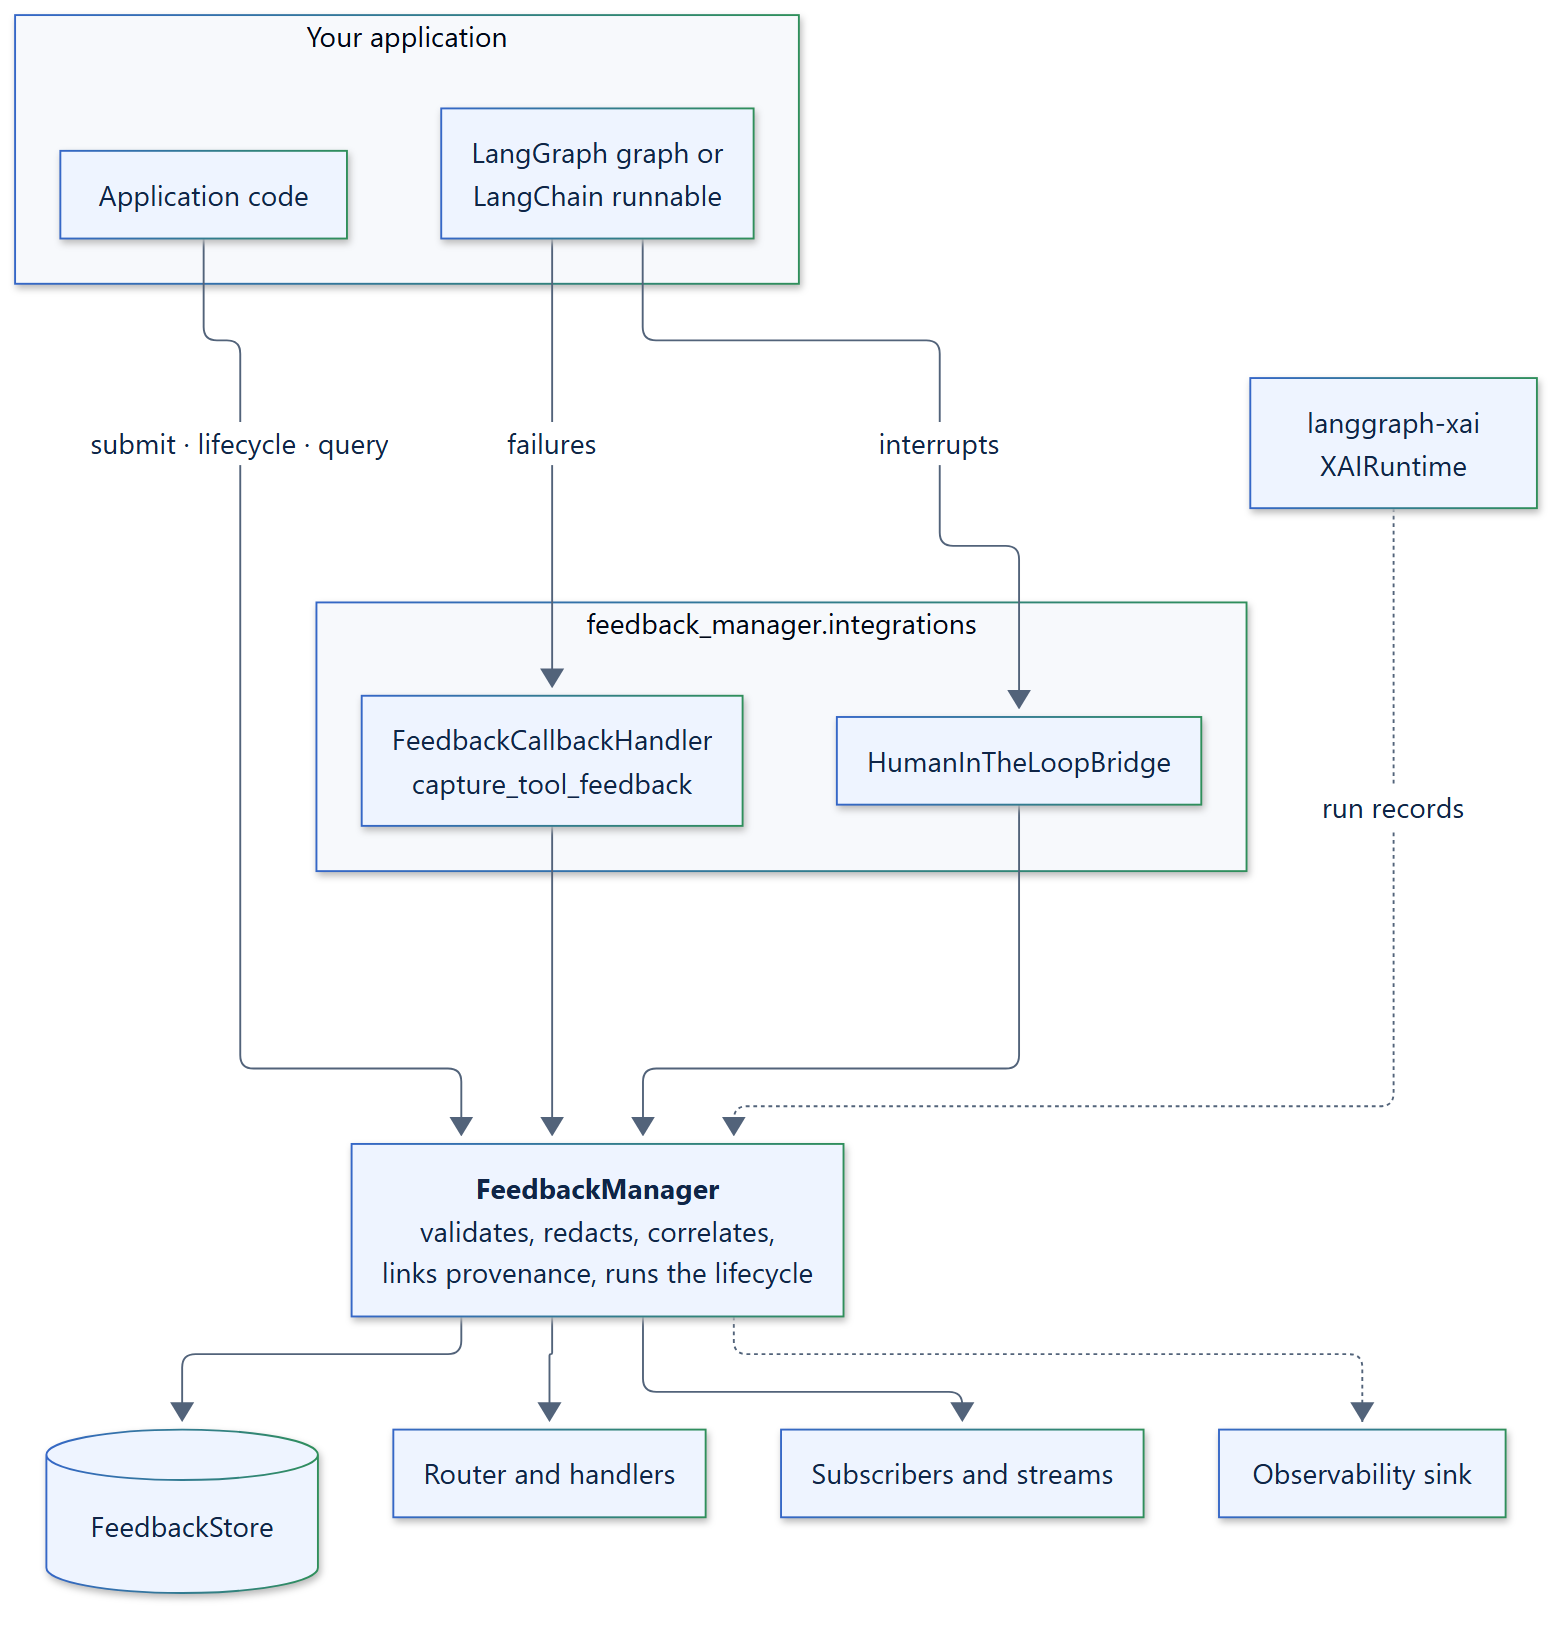
Agent applications constantly receive feedback: a reviewer approves a refund,
a user corrects an answer, a tool times out, an evaluator scores a response.
feedback-manager turns each of them into a validated, queryable record that
knows which run, node, tool call, or interrupt it is about, groups it with
related feedback, routes it to your handlers, and tracks it through an explicit
lifecycle until it is resolved. Your agent framework keeps owning execution;
feedback-manager owns the feedback about it. Framework integrations are
adapters around a framework-neutral core, so the same package works with
LangChain, LangGraph, custom Python agents, and future frameworks.
Why feedback-manager
A support agent drafts a refund reply. A reviewer corrects it, a tool times out on the next run, and an evaluator scores the answer low. Today that feedback usually ends up scattered:
- Feedback lives in many places. Corrections sit in a UI database, tool errors in logs, evaluator scores in a tracing tool, and approvals inside the agent framework's interrupt state.
- It is detached from what it is about. A score without the run, node or tool call it refers to can't be acted on or audited.
- Nobody owns its follow-up. Feedback is recorded but never acknowledged, handled or resolved, and concurrent workers overwrite each other's updates.
- Agents repeat the same mistakes. The lesson in a correction never reaches the next run, or it reaches it unreviewed and unscoped.
How feedback-manager addresses each one:
| Problem | What feedback-manager does |
|---|---|
| Feedback in many places | One immutable, typed event for corrections, approvals, tool failures, evaluator scores and interruptions, captured where they happen |
| Detached from its subject | Every event carries its target and execution context, is correlated with related feedback, and links to agxai provenance |
| No owner for follow-up | Routing to your handlers, and an explicit lifecycle whose transitions are compare-and-set, so concurrent updates never overwrite each other |
| Repeated mistakes | A learning engine turns scoped feedback into versioned lessons that only reach an agent after human review and explicit activation |
feedback-manager doesn't run your agents or replace your tracing. Your framework keeps owning execution, LangSmith and OpenTelemetry keep showing what ran, and agxai records why it was decided; feedback-manager manages the feedback about all of it.
Highlights
- Captured where it happens. A LangChain callback handler records tool,
model, retriever and node failures once, with the thread, node and tool call
they happened in. A bridge records LangGraph human-in-the-loop requests and
decisions around
interrupt()andCommand(resume=...). - An explicit, race-free lifecycle. Feedback moves through a validated state machine, retried submissions are idempotent, and an optional durable change journal supports crash recovery.
- Learning that stays reviewable. Automatic, scoped background learning builds candidate lessons with evidence and confidence. Human review and explicit activation are separate from feedback approval, and original feedback is never rewritten.
- Hybrid retrieval. Structured, vector (LanceDB), graph (LadybugDB) and hybrid retrieval over learned artifacts. Vector and graph records are rebuildable hints: every result is revalidated against the current artifact, its review state and its scope.
- Isolated from failures. A failing handler, subscriber, router or observability sink never loses stored feedback. Choose per stage whether a failure is logged or raised.
- Extensible through ABCs. Subclass
FrameworkAdapterfor Agno, CrewAI or your own loop, andFeedbackStore,VectorStore,GraphStoreorEmbeddingProviderfor your infrastructure. Every agxai, LanceDB and LadybugDB component can be injected, andfeedback_manager.testingchecks your implementations against the contracts. - Small and typed. The core depends on agxai, Pydantic and structlog, ships type hints, and is tested on Python 3.12 to 3.15 with 100% statement and branch coverage.
Installation
pip install "feedback-manager[langchain]"   # with LangChain and LangGraph
pip install feedback-manager                # core only, for any other framework
Optional extras:
| Extra | Adds |
|---|---|
langchain |
LangChain and LangGraph capture, human-in-the-loop bridge and learned-context injection |
lancedb |
LanceDBVectorStore for vector and hybrid retrieval |
ladybugdb |
LadybugGraphStore for graph and hybrid retrieval |
otel |
OpenTelemetryObservabilitySink |
all |
Every extra above |
The lancedb and ladybugdb extras need Python 3.14 or earlier until those
databases publish Python 3.15 wheels.
Quickstart
A person corrects a generated answer. The correction is recorded against the answer and its conversation, taken through its lifecycle and queried back:
import asyncio

from feedback_manager import (
    ExecutionContext,
    FeedbackManager,
    FeedbackQuery,
    FeedbackTarget,
    FeedbackTargetType,
)


async def main() -> None:
    manager = FeedbackManager()

    # A person corrects a generated answer in conversation "support-7".
    feedback = await manager.submit(
        source="human",
        category="correction",
        target=FeedbackTarget(type=FeedbackTargetType.GENERATION, id="gen-42"),
        payload={"corrected_text": "Canberra is the capital of Australia."},
        execution_context=ExecutionContext(thread_id="support-7"),
    )
    print(f"{feedback.status}: correlated by {feedback.correlation_id}")

    # Take it through its lifecycle once the correction is applied.
    await manager.acknowledge(feedback.feedback_id)
    await manager.mark_handled(feedback.feedback_id)
    resolved = await manager.resolve(feedback.feedback_id, resolution={"applied_to": "faq"})
    print(f"{resolved.status}: {resolved.resolution}")

    # Query it back, like any other feedback.
    for event in await manager.query(FeedbackQuery(correlation_id="support-7")):
        print(event.source, event.category, event.target.id, event.status)


asyncio.run(main())
Output:
received: correlated by support-7
resolved: {'applied_to': 'faq'}
human correction gen-42 resolved
Record every tool, model and node failure of a LangChain or LangGraph agent, without changing your error handling:
from feedback_manager.integrations.frameworks.langchain import FeedbackCallbackHandler

await graph.ainvoke(inputs, {"callbacks": [FeedbackCallbackHandler(manager)]})
The quickstart walks through it step by step.
Learn from feedback
Two corrections with the same lesson become a candidate. It reaches the agent only after a person reviews it and it is activated:
from feedback_manager.learning import ArtifactScope
from feedback_manager.learning.engine import LearningEngine
from feedback_manager.learning.signals import LearningSignalExtractor
from feedback_manager.retrieval import RetrievalRequest
from feedback_manager.storage.artifacts import InMemoryArtifactRepository

scope = ArtifactScope(tenant_id="example-tenant", agent_id="research-agent")
engine = LearningEngine(InMemoryArtifactRepository())
signals = [LearningSignalExtractor().extract(event, scope=scope).signal for event in corrections]

candidate = (await engine.process(signals)).artifacts[0]
await engine.request_review(scope, candidate.artifact_id)
await engine.review(scope, candidate.artifact_id, reviewer="example-reviewer", approved=True)
await engine.activate(scope, candidate.artifact_id)

result = await engine.retrieve(
    RetrievalRequest(scope=scope, agent_id="research-agent", task="validate results")
)
print(result.as_context())
Output:
Improvement: Search, validate results, then execute.
Search, validate results, then execute.
In production, FeedbackManager queues learning jobs for a background learner
instead; see
background learning and recovery
and hybrid retrieval.
Your own framework
The core never imports an agent framework. LangChain and LangGraph share one
adapter, a dependency-free adapter covers hand-written loops, and other
frameworks implement FrameworkAdapter. Program against the ABC and the same
agent-side code works for all of them:
from feedback_manager.integrations import FrameworkAdapter


def wire(adapter: FrameworkAdapter, manager, engine):
    extractor = adapter.context_extractor()
    classifier = adapter.failure_classifier()
    bridge = adapter.human_in_the_loop(manager)
    injector = adapter.context_injector(engine)
    return extractor, classifier, bridge, injector
See the custom framework guide.
Your own database
Feedback is kept in memory by default. Subclass FeedbackStore and pass it to
FeedbackManager; feedback_manager.testing.FeedbackStoreContract checks your
store against the contract:
from feedback_manager import FeedbackManager
from feedback_manager.contracts import FeedbackStore


class MyStore(FeedbackStore):
    async def create(self, feedback): ...
    async def get(self, feedback_id): ...
    async def transition(self, feedback_id, status, *, expected, resolution=None): ...
    async def query(self, query): ...


manager = FeedbackManager(store=MyStore())
See the SQLite store and bring your own components.
Benchmarks
Each operation timed 1,000 times with the default in-memory stores:
| Scenario | p50 ms | p95 ms |
|---|---|---|
submit, learning off |
0.13 | 0.21 |
submit, learning on |
0.21 | 0.37 |
lifecycle: acknowledge, handle, resolve |
0.15 | 0.29 |
retrieve, structured, 50 lessons |
21.0 | 30.5 |
retrieve, hybrid with LanceDB, 50 lessons |
102.1 | 132.3 |
Measured on one machine; see Benchmarks for the method, memory use and how to reproduce.
Examples
Complete programs in examples/,
each exercised by the test suite:
- Human correction
- Human-in-the-loop approval
- Tool failure
- Provenance with agxai
- Custom agent
- Background learning with LanceDB and LadybugDB
- PostgreSQL store
Documentation
Full documentation: feedback-manager.readthedocs.io
Three Agent Skills
teach coding agents such as Claude Code, Codex, Cursor and GitHub Copilot to
use feedback-manager correctly. feedback-manager integrates it into your
application, feedback-manager-learning makes agents learn from feedback, and
feedback-manager-extend writes adapters and stores for your infrastructure:
npx skills add smuniharish/feedback-manager
feedback-manager follows semantic versioning. Changes are listed in the changelog.
Contributing
Contributions are welcome. See CONTRIBUTING.md for the development setup and checks, CODE_OF_CONDUCT.md for community standards, and SECURITY.md to report a vulnerability.
License
Apache License 2.0. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for feedback-manager 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| feedback_manager-0.1.2.tar.gz | 2.1 MB | Without provenance | Details for feedback_manager-0.1.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| feedback_manager-0.1.2-py3-none-any.whl | Python 3 | none | any | Details for feedback_manager-0.1.2-py3-none-any.whl |
Total release size: 2.2 MB
Release files / feedback_manager-0.1.2.tar.gz
| Download URL | feedback_manager-0.1.2.tar.gz |
|---|---|
| Size | 2.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
40a8f41fe08fc6ec495bb65eed069ba93cfae000b0a3a1bcf9043eff18a9ec9f
|
|
BLAKE2b-256 checksum How to use checksums |
41341529eea4884392150748e83eb18a058ef76821e8c3ef8b9c648a6eb2d77c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.6 {"installer":{"name":"uv","version":"0.13.6","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / feedback_manager-0.1.2-py3-none-any.whl
| Download URL | feedback_manager-0.1.2-py3-none-any.whl |
|---|---|
| Size | 169.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8fffac54752491cbd3713ef595313cbd76b2e8ae80757a46560942347e16d4d9
|
|
BLAKE2b-256 checksum How to use checksums |
bef54c1f17630d15f57b334ea93c1d82d2e29bc0991ed923993adfc3072358c9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.6 {"installer":{"name":"uv","version":"0.13.6","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Security for feedback-manager 0.1.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














