
FinanceBench RAG Agent


A multi-agent RAG system for role-based access-controlled financial document Q&A. Achieves 72.7% correctness pass rate on the public FinanceBench benchmark using selective agentic retrieval, a BGE cross-encoder reranker, and a self-hosted LLM observability stack.
Evaluation results
Evaluated on the FinanceBench benchmark (150 questions across 32 companies):
| Metric | Value |
|---|---|
| Correctness pass rate | 72.7% (109/150) |
| Refusal rate | 6.7% (10/150) |
| RAGAS faithfulness | 0.747 |
| DeepEval faithfulness | 0.844 |
| DeepEval contextual recall | 0.768 |
Per-slice pass rate: lookup 68.6% (n=86), multi-hop 84.6% (n=13), calc 76.5% (n=51).
The correctness judge is a Claude Sonnet 4.6 + structured-prompt setup calibrated to Cohen's κ = 0.932 against an 89-question hand-labeled set with an adversarial leniency guard. Full methodology, per-judge scores, and reproduction commands in docs/evaluation.md.
Comparison with published systems on FinanceBench
| System | Approach | Accuracy |
|---|---|---|
| Mafin 2.5 / PageIndex | Vectorless reasoning over hierarchical document tree | 98.7% |
| DANA | Domain-aware neurosymbolic agent with deterministic operators | 94.3% |
| GPT-4-Turbo · long context (128k) | Whole-document prompting | ~79% |
| Claude-2 · long context (100k) | Whole-document prompting | ~76% |
| This project | Multi-agent RAG with selective research-agent subgraph + RBAC + HITL | 72.7% |
| FinanceBench paper baselines | Vector retrieval + GPT-4 / Llama-2 | 38–43% |
| GPT-4-Turbo · top-k vector RAG | Standard retrieval, no agent | ~19% |
Long-context approaches score higher but are not enterprise-deployable — 10-K filings frequently exceed 128k tokens, and whole-document prompting is impractical at scale due to latency and cost. The 72.7% here is measured on a production-shaped pipeline (fixed institutional corpus, batched retrieval, RBAC at the storage layer, HITL on high-stakes outputs).
Demos
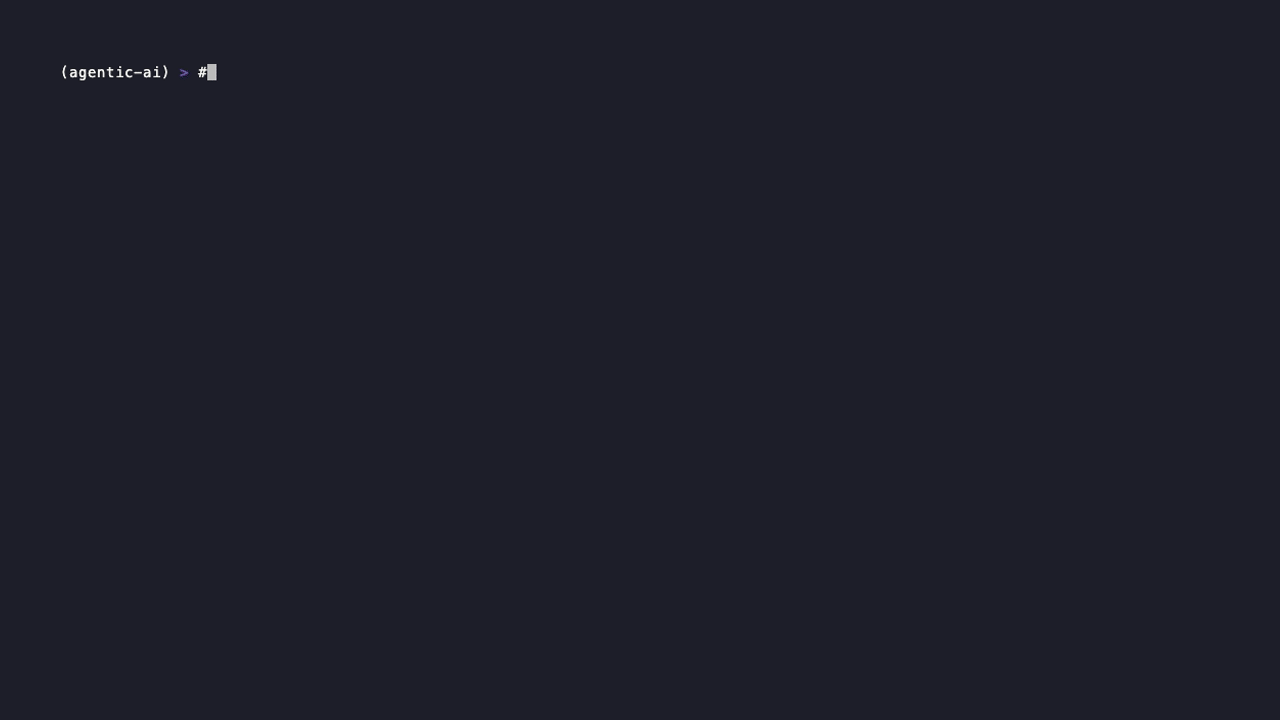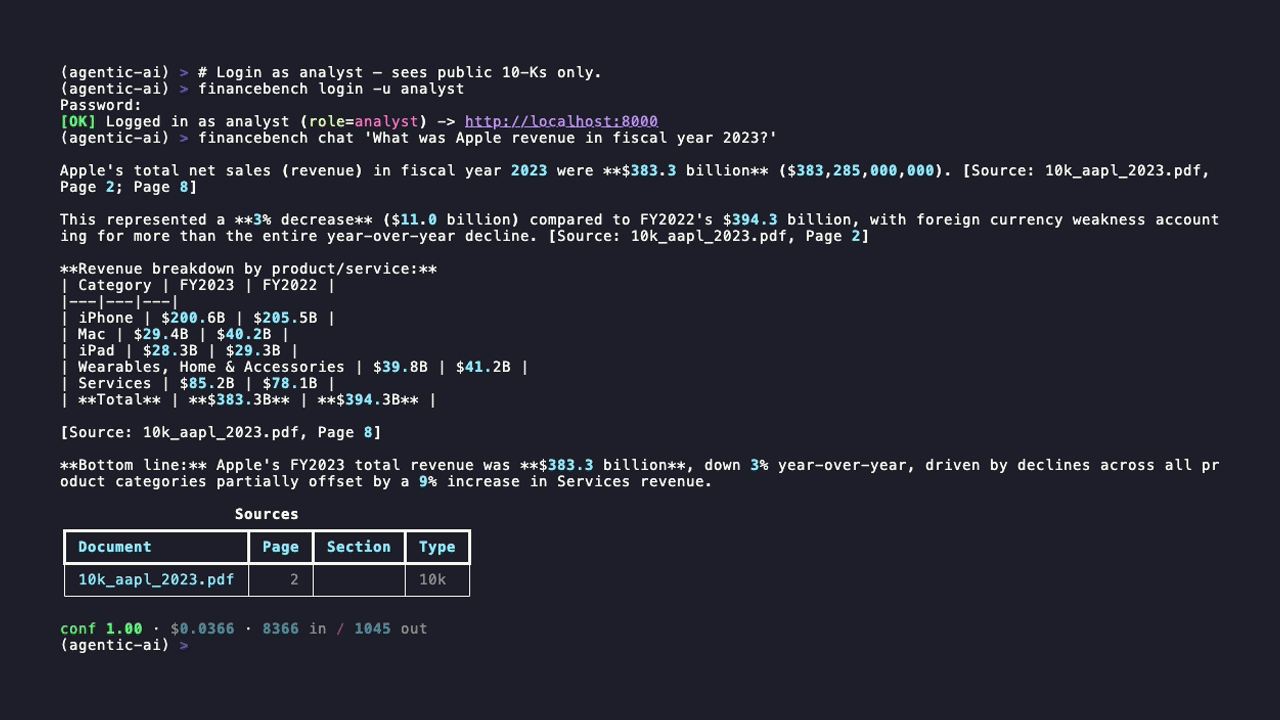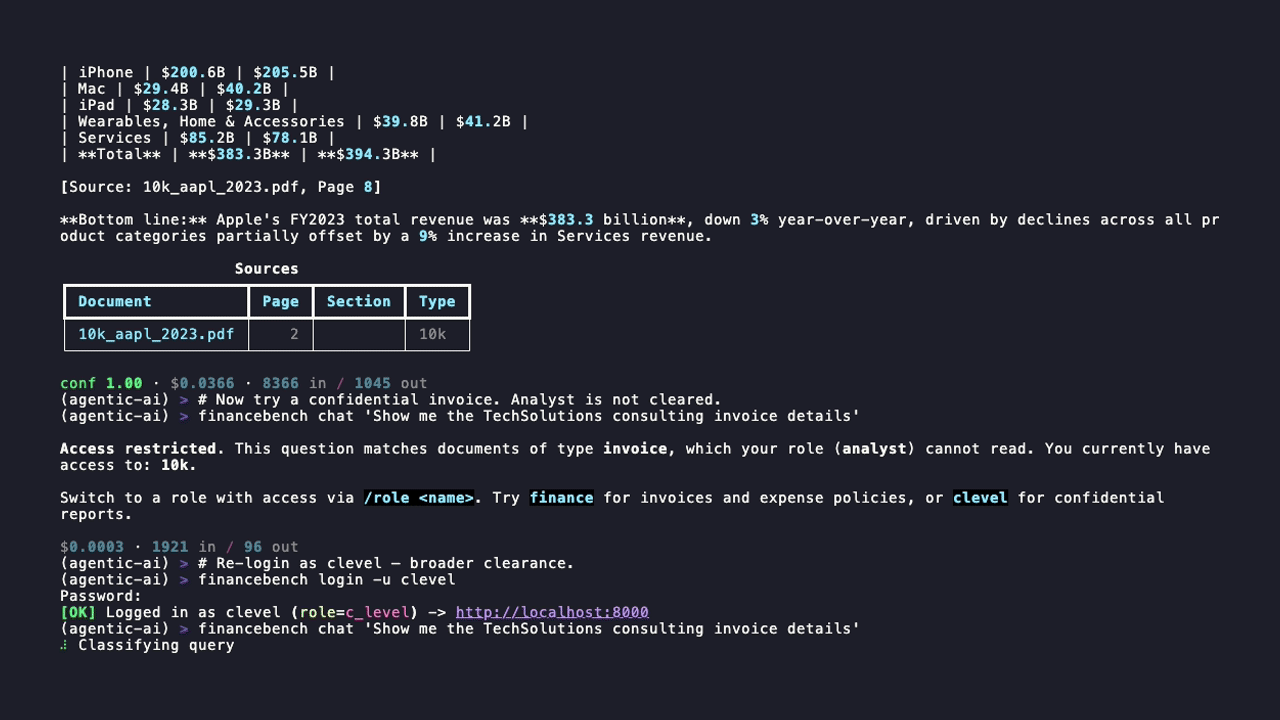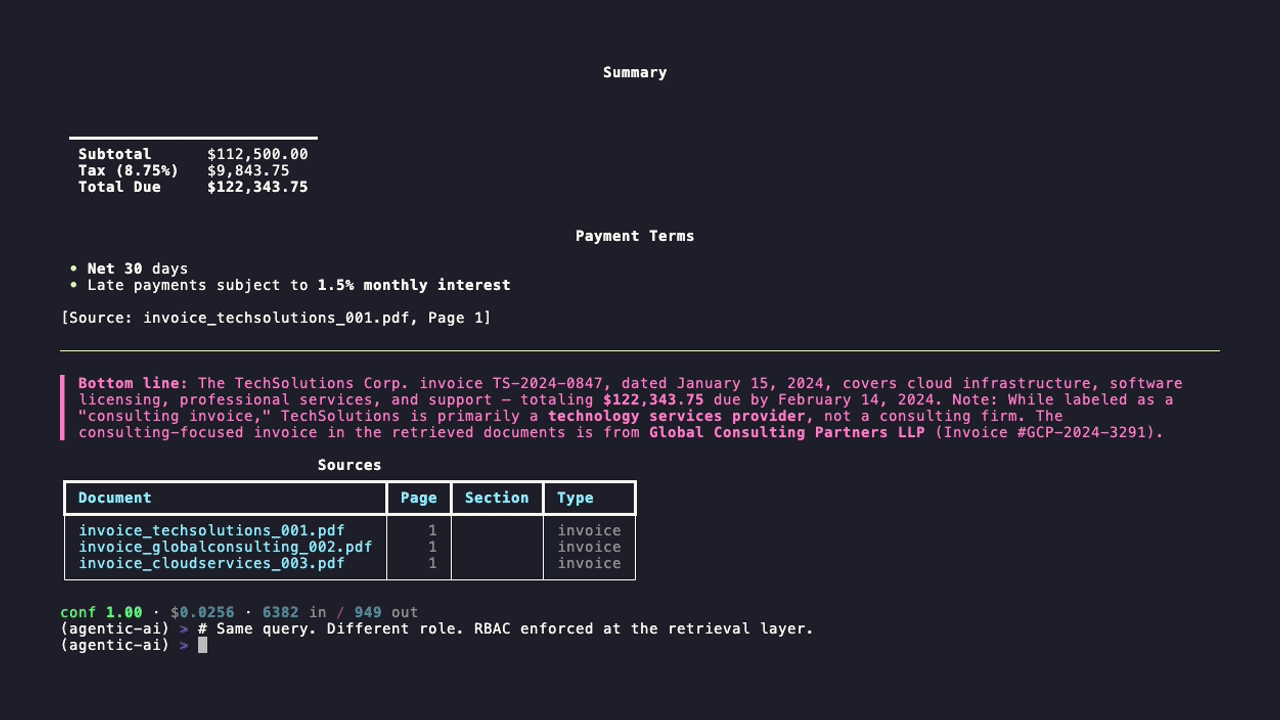
Role-based access control
An analyst is refused a confidential invoice; a c-level re-login unlocks the same query — access enforced at the retrieval layer.
Human-in-the-loop approval
Finance is blocked at the $100K gate; an admin approves in a second terminal and the answer is released back — multi-party, across sessions.

Conversation memory
Follow-up questions resolve against thread history — "And Microsoft?" is rewritten using the prior turn.

Try it
pip install financebench-rag-agent
financebench setup                    # brings up the 4-service docker stack, seeds 8 sample PDFs
financebench login -u analyst         # password analyst123
financebench chat
The full 360-PDF FinanceBench corpus is published as a pre-vectorized snapshot on the Hugging Face Hub — voyage-finance-2 embeddings plus chunked text and a manifest — so anyone can seed the entire benchmark in minutes and skip ~$5-15 of embedding cost and ~30 min of ingest:
financebench seed --from-hf cmpunkmannu/financebench-voyage-finance-2-embeddings
Architecture

A router classifies each query as a simple lookup or research-required. Simple lookups take the fast direct path (retrieval → BGE reranker → grader → Claude generator); research queries enter a multi-turn subgraph that decomposes the question, retrieves per sub-question, grades sufficiency, and synthesizes a final answer. RBAC is enforced at the Qdrant payload-filter level — agentic queries cannot bypass access control. High-stakes answers (above a per-role dollar threshold) pause via LangGraph's interrupt() for multi-party human approval, with state checkpointed to Postgres so the workflow survives container restarts.
Tech stack
- Backend — FastAPI · LangGraph · Qdrant · PostgreSQL · Redis · PyJWT
- Client —
financebenchCLI: typer · rich · prompt_toolkit · httpx-sse · token-streaming over SSE - LLMs — Claude Sonnet 4.6 · gpt-4o-mini · Llama 3.3 (via Groq, optional)
- Retrieval — OpenAI text-embedding-3-small or voyage-finance-2 · BGE-reranker-v2-m3 cross-encoder
- Observability — self-hosted LiteLLM proxy + Langfuse v3 + Redis semantic cache (full stack only)
- Safety — Microsoft Presidio PII detection · LLM Guard · LLM classifier (3-layer cascade)
- Evaluation — RAGAS · DeepEval · custom LLM correctness judge
Known limitations
- Not deployed to production — runs locally via
docker compose up -d. No public URL or live traffic. - CLI is the canonical client today. A Next.js web frontend is in progress in
web/but not wired into the deployment story. - Below the top-published systems (Mafin 2.5 at 98.7%, DANA at 94.3%) — see comparison table above for context.
Running from source
git clone https://github.com/Rishabhmannu/financebench-rag-agent.git
cd financebench-rag-agent
pip install -e ".[backend,dev]" && cp .env.example .env   # backend extras + dev tools
financebench setup                                         # docker compose + seed corpus
For self-hosting the full 11-service stack (LiteLLM + Langfuse), upgrade flows, and production hardening, see docs/deploy.md and docs/upgrade.md.
Documentation
- docs/cli.md — CLI reference, slash commands, multi-party HITL workflow
- docs/deploy.md — Self-host: stack profiles, env vars, backup, hardening
- docs/upgrade.md — Upgrade cookbook by change type
- docs/evaluation.md — Methodology, results, reproduction
- docs/engineering-log.md — Engineering decisions and tradeoffs
- docs/setup.md — Test accounts, environment, dev commands
- docs/architecture.md · docs/api-reference.md · docs/rbac-matrix.md · web/README.md
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for financebench-rag-agent 0.3.5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| financebench_rag_agent-0.3.5.tar.gz | 2.1 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| financebench_rag_agent-0.3.5-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.3 MB
Release files / financebench_rag_agent-0.3.5.tar.gz
| Download URL | financebench_rag_agent-0.3.5.tar.gz |
|---|---|
| Size | 2.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fb761605439a881773b870ebe640ec8618675b8d968d91f6ad30bccf51ba2ee4
|
|
BLAKE2b-256 checksum How to use checksums |
c7ce240ee6860f30583401bc90906030e79acb1f489ba73c32e7da7fafa44c67
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 6, 2026.
Transparency logRelease files / financebench_rag_agent-0.3.5-py3-none-any.whl
| Download URL | financebench_rag_agent-0.3.5-py3-none-any.whl |
|---|---|
| Size | 228.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b9c384ea140c889b67b7c91ffff672e9db30fb92fb9a2b325febc655754d0b8c
|
|
BLAKE2b-256 checksum How to use checksums |
5dc80b55992209ca1b56551e5f81a63696402493a36e9291903c0e493132b6aa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 6, 2026.
Transparency log













