
Flash-Aurora

Inference and serving for Microsoft Aurora and other geospatial foundation models. A request takes an analysis cube in and writes NetCDF or GeoTIFF out. The tensors keep a lat/lon layout, so the engine uses shape-specialized kernels, named mixed precision (bf16_mixed@fp32 by default), and a job-level GPU scheduler rather than an LLM serving loop.
Walkthrough slides · Tutorial · Benchmark tables
Install
pip install flash-aurora
From source:
git clone https://github.com/CatManJr/Flash-Aurora.git
cd Flash-Aurora
uv sync
Set CUTE_DSL_ARCH when the CuTe kernels need an explicit GPU architecture (sm_89 on RTX 4090, sm_120a on Blackwell). The published measurements use PyTorch 2.14.0, Triton 3.8.0, and CuTe DSL 4.7.1, which uv.lock pins. If PyPI is slow, point uv at a mirror with UV_DEFAULT_INDEX or a local uv.toml; keep the committed uv.lock on the official index.
Quick start
from datetime import datetime
from pathlib import Path

from flash_aurora import AuroraEngine, DataDownloader

engine = AuroraEngine.from_preset(
    "era5_pretrained",
    asset_root=Path("/path/to/assets"),
    inference_precision="bf16_mixed@fp32",
)
downloader = DataDownloader.from_preset(
    "era5_pretrained",
    asset_root=engine.config.asset_root,
)
request = downloader.ingest_request(
    datetime(2023, 1, 1, 6),
    time_index=1,
    download=True,
)
batch = engine.prepare(request, rollout_steps=4)
forecasts = list(engine.rollout_stream(batch, steps=4))
engine.release_gpu(move_model_to_cpu=True)
engine.close()
Scheduler loopback, two-GPU placement, and the notebook index: docs/tutorial.md.
What it does
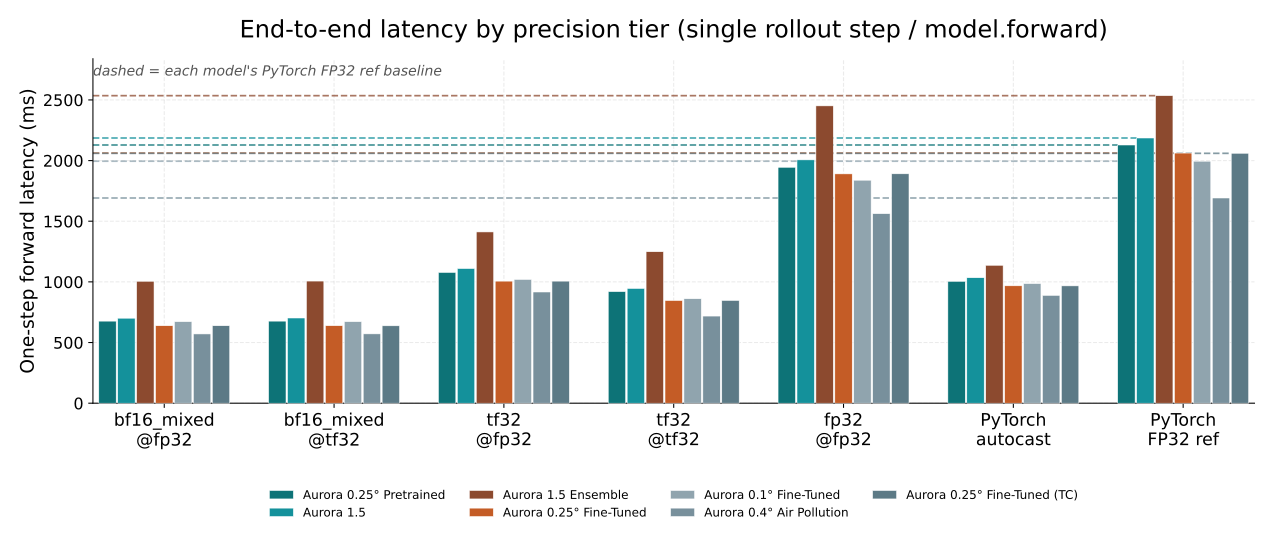
Production mixed precision is faster than unfused FP32 and stays closer to that twin than framework autocast. One forward step on RTX PRO 6000 Blackwell, measured with PyTorch 2.14.0 and CuTe DSL 4.7.1, is about $680$--$1000,\mathrm{ms}$ with a TF32 Perceiver (bf16_mixed@tf32) and about $830$--$1150,\mathrm{ms}$ with an FP32 Perceiver (bf16_mixed@fp32), versus about $1.9$--$2.5,\mathrm{s}$ for unfused FP32. Aurora 1.5 ensemble is the slow end of both ranges, because its stochastic MLP stays on the tier's TF32 matmul. Each bar is a separate process (--isolate-tiers).
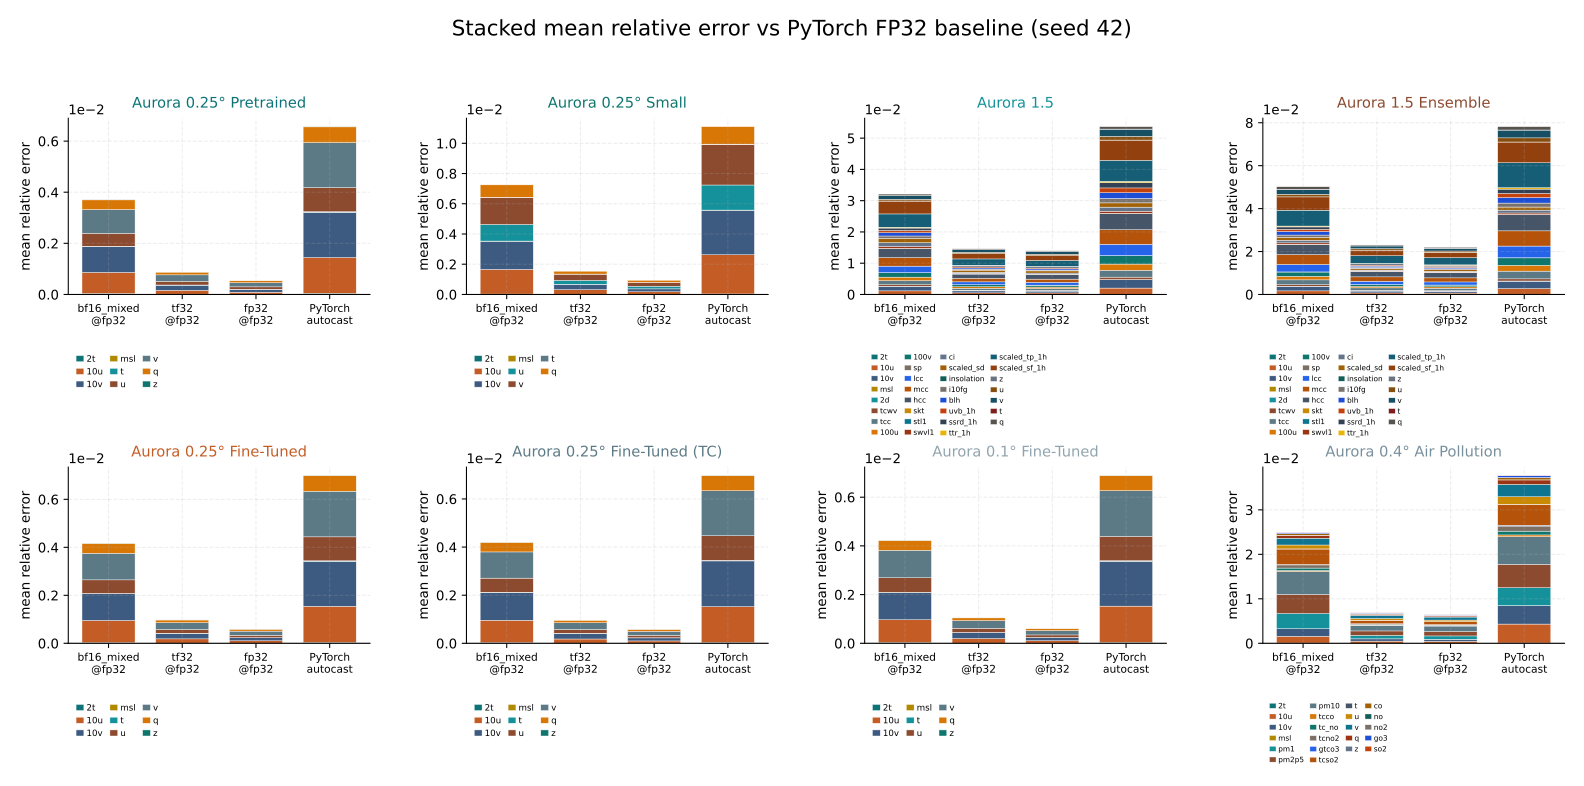
Recommended tiers stay within per-variable tolerances versus the unfused FP32 reference (seed 42). The one exception is bf16_mixed@tf32 on aurora_v1p5_ensemble, where scaled_tp_1h is about $1.1\times$ the tolerance. bf16@* is not a production path because the full BF16 GEMM path corruptted
the prediction in experiments.
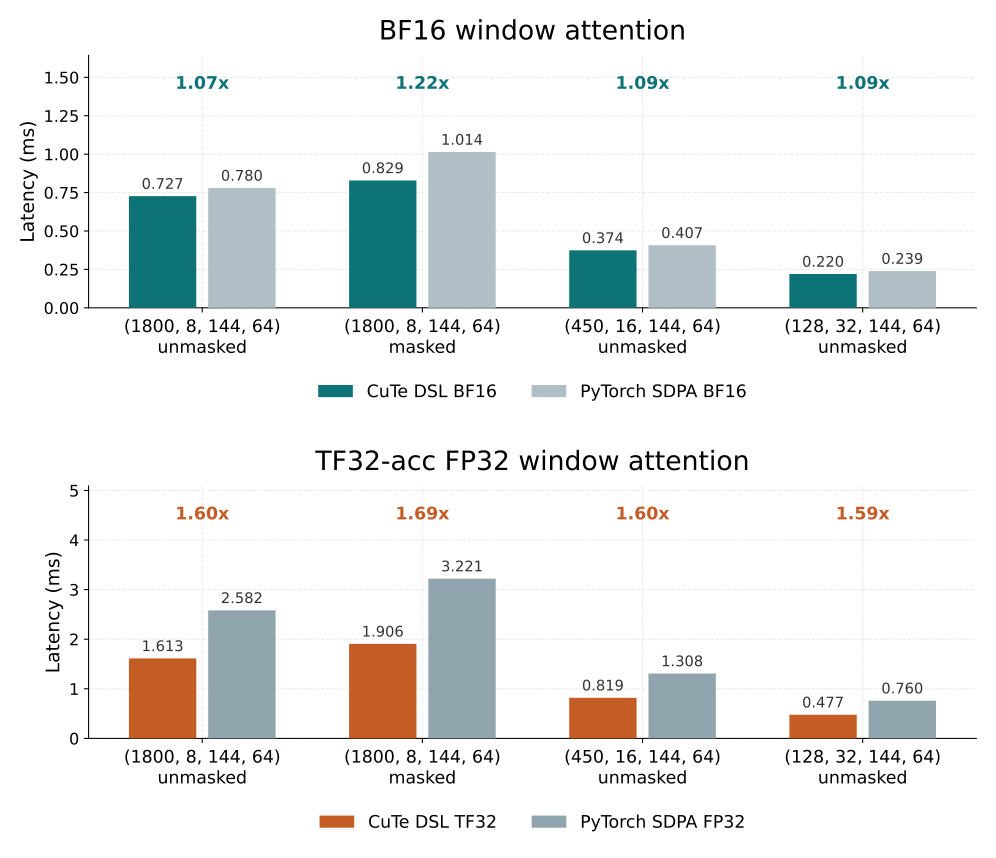
Window-attention kernels are short-window CuTe DSL (N = 144 on the default $0.25^{\circ}$ encoder), not a generic LLM attention stack.
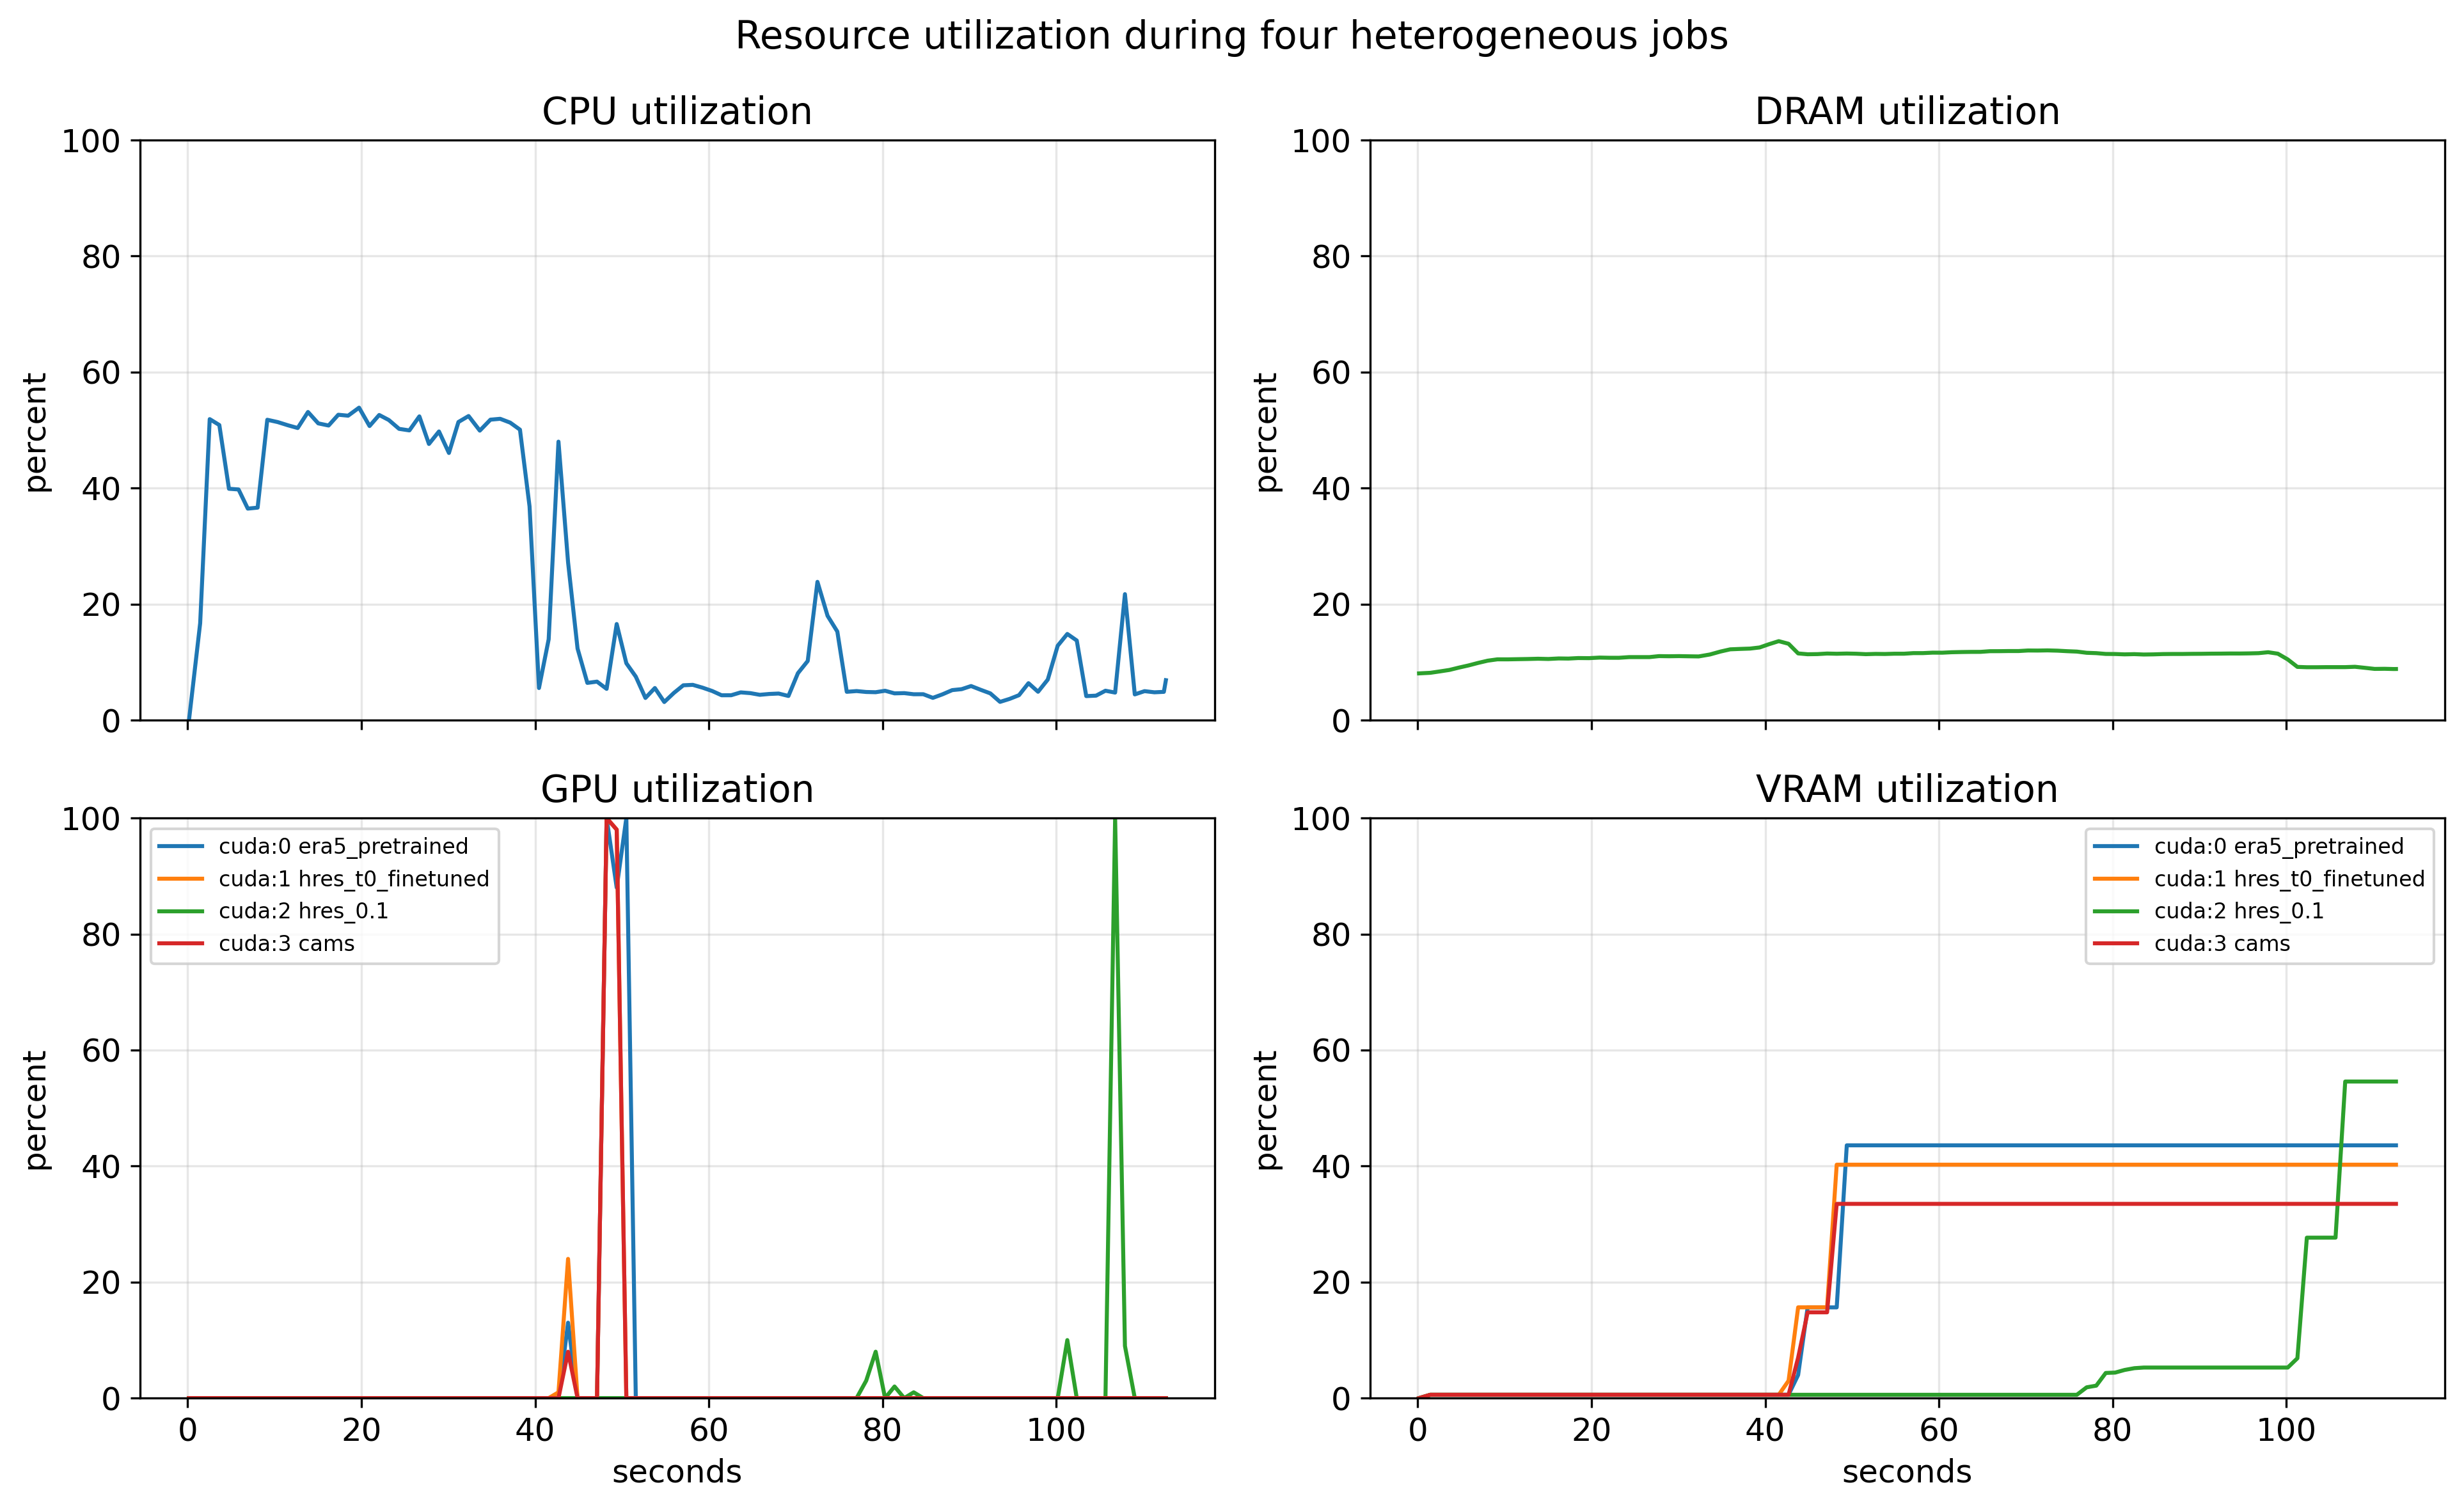
Serving is one GPU per job. A ZeroMQ coordinator fills idle workers; it does not batch tokens inside one forward. Scheduler notebooks.
| One job per worker | Refill while hres_0.1 is pending |
|---|---|
 |
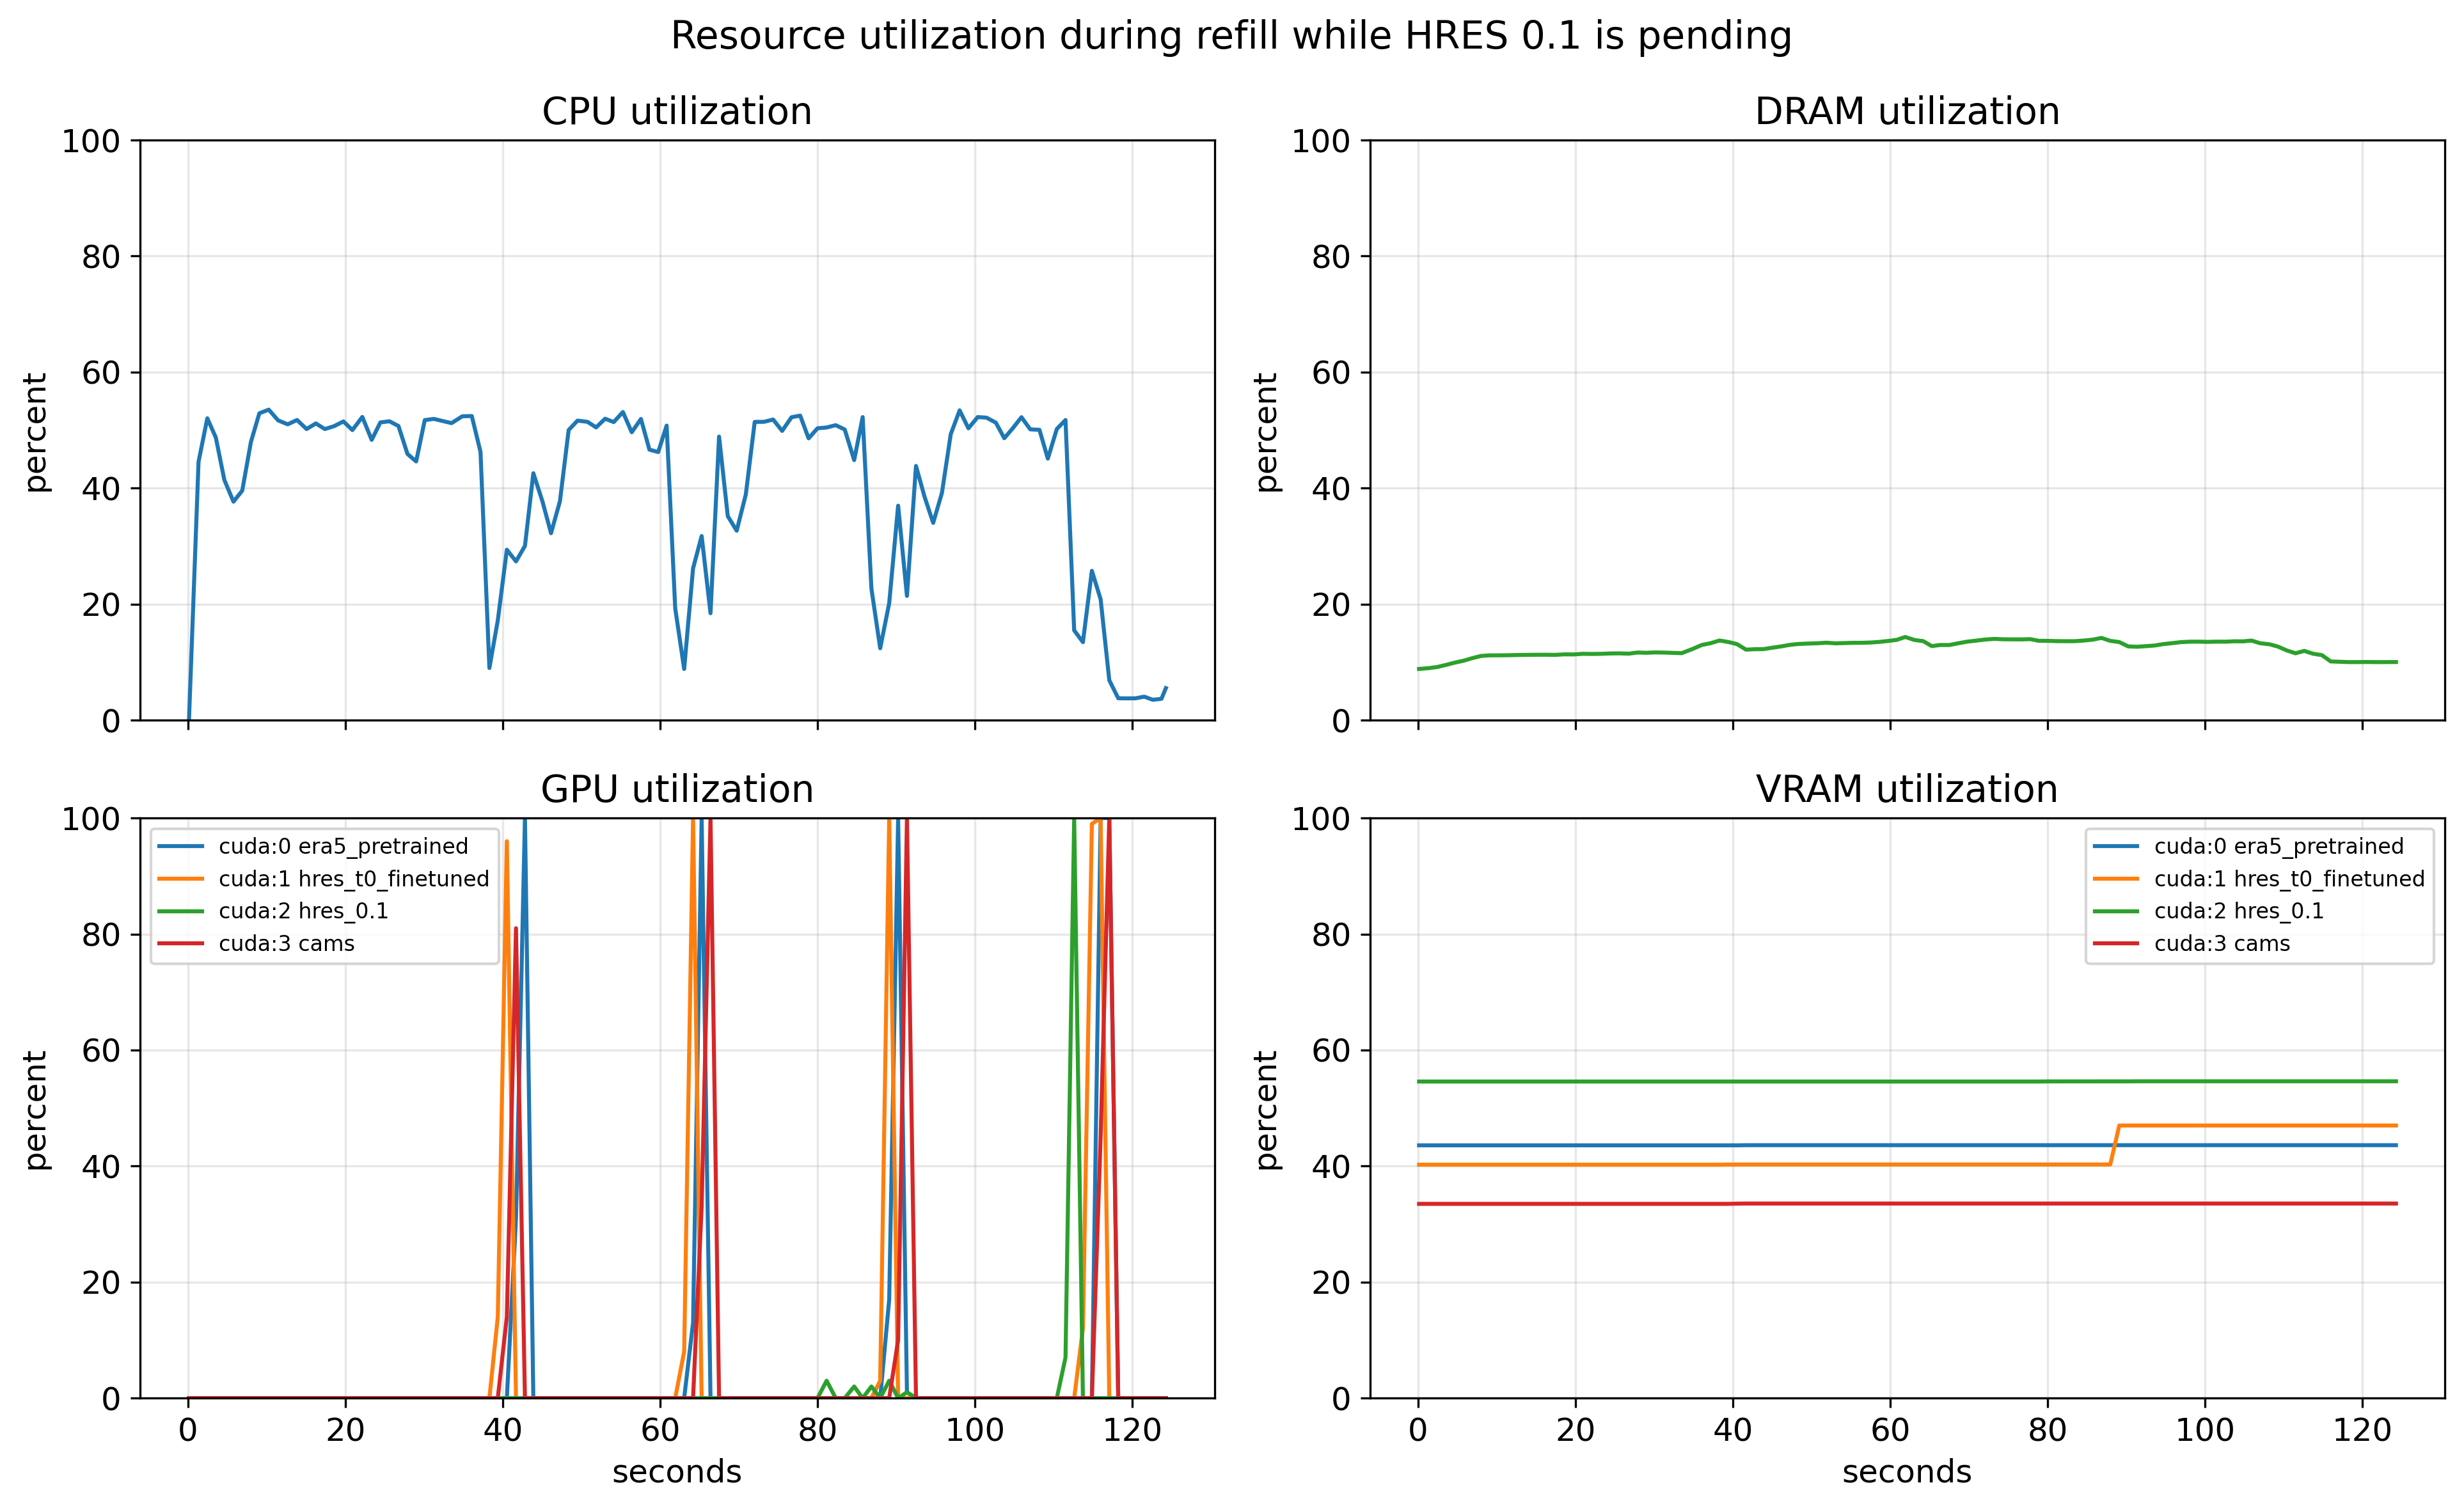 |
A preset that does not fit one GPU can run encoder / backbone / decoder on two devices in the same process (DistributedConfig). ROI export clips on the egress path so a region of interest does not require a global dump.
Presets
| Preset | Grid | Source |
|---|---|---|
era5_pretrained |
$721 \times 1440$ | CDS ERA5 |
aurora_v1p5 / aurora_v1p5_ensemble |
$721 \times 1440$ | CDS ERA5 (extended) |
small_pretrained |
$400 \times 800$ | CDS ERA5 |
hres_t0_finetuned / tc_tracking |
$721 \times 1440$ | WeatherBench2 HRES |
hres_0.1 |
$1801 \times 3600$ | IFS analysis |
cams |
$451 \times 900$ | CAMS |
wave |
$721 \times 1440$ | WB2 + MARS |
wave usually needs a hand-placed MARS cache; see example_wave.ipynb. Notebooks for every preset are listed in the tutorial.
License
MIT. Aurora code is derived from Microsoft Aurora (MIT), frozen at v1.8.0, with Aurora 1.5 from tag v2.0.1. Kernel files under flash_aurora.models.ops follow their per-file headers (including NVIDIA BSD-3-Clause where noted).
Bodnar et al., A Foundation Model for the Earth System, Nature (2025). doi:10.1038/s41586-025-09005-y. Upstream docs: microsoft.github.io/aurora.
1 maintainer

Metadata
1 maintainer
Release files for flash-aurora 0.1.5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| flash_aurora-0.1.5.tar.gz | 32.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| flash_aurora-0.1.5-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 32.4 MB
Release files / flash_aurora-0.1.5.tar.gz
| Download URL | flash_aurora-0.1.5.tar.gz |
|---|---|
| Size | 32.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
85185671c5b9a4bbad0b6b578677760218396cfa6e3be7202d3fe7aa93c05c57
|
|
BLAKE2b-256 checksum How to use checksums |
d081036f4b52cfabd507a310eea2b682856d02f44011c003861d22fecdce8672
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.20 {"installer":{"name":"uv","version":"0.12.20","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / flash_aurora-0.1.5-py3-none-any.whl
| Download URL | flash_aurora-0.1.5-py3-none-any.whl |
|---|---|
| Size | 379.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fd9f07758cc05e637e3f82945138d1bb06efc61c71b408ea390cbc4bf06ff873
|
|
BLAKE2b-256 checksum How to use checksums |
b2fed7d3327028e9cb6ba9b3a18a3666588a755b92d84442f6a6aaf34cd39890
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.20 {"installer":{"name":"uv","version":"0.12.20","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














