
FlashHead
vLLM Plugin for Fast Language Model Head Inference
The dense classification head accounts for up to 60% of parameters in small LLMs and roughly half of decode-step compute. FlashHead replaces it with a two-stage retrieval pipeline—up to 2.0x model-level inference speedup while maintaining accuracy—training-free and hardware-friendly. FlashHead integrates via vLLM's official vllm.general_plugins entry point: no source patches, no custom Docker image.



FlashHead: Efficient Drop-In Replacement for the Classification Head in Language Model Inference
The standard LM head computes a dense matrix multiplication $h_t × W_{vocab}$ at every decode step, scoring all Vocabulary tokens regardless of relevance. FlashHead reframes this as a two-stage retrieval problem over clustered token embeddings: first identify which regions of vocabulary space are relevant, then score only those candidates.
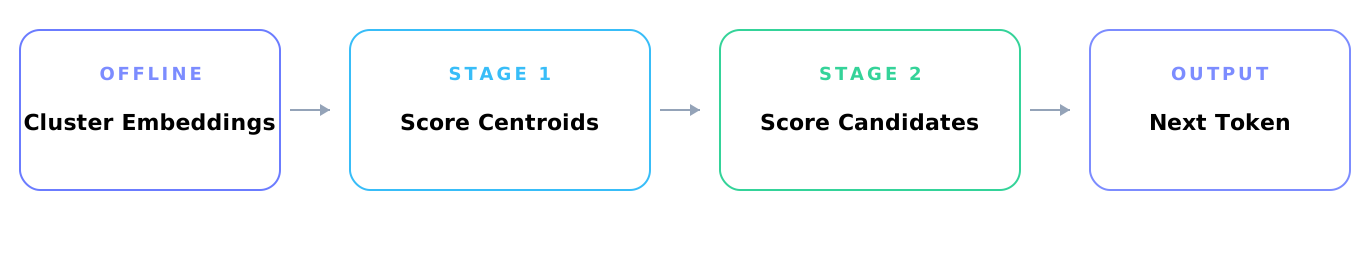
⚡ Key Tradeoff A dense head scores 128,256 tokens per step (for a 128K vocabulary). With c = 8,016 clusters and p = 256 probes, FlashHead scores only 8,016 + 256 × 16 = 12,112 tokens, a 10× reduction in scored tokens, while multi-probe retrieval maintains near-perfect recall of the correct next token.
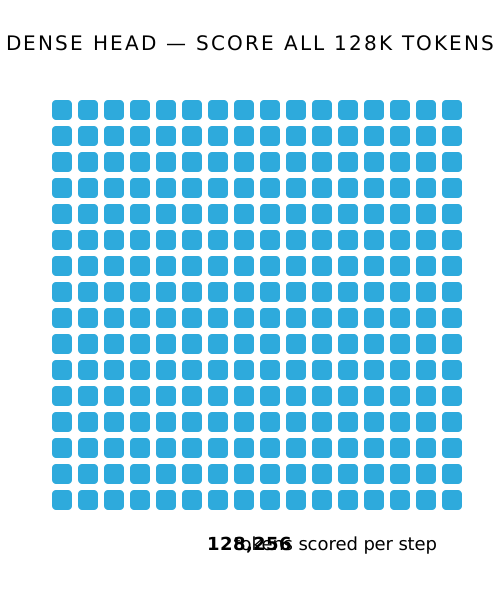
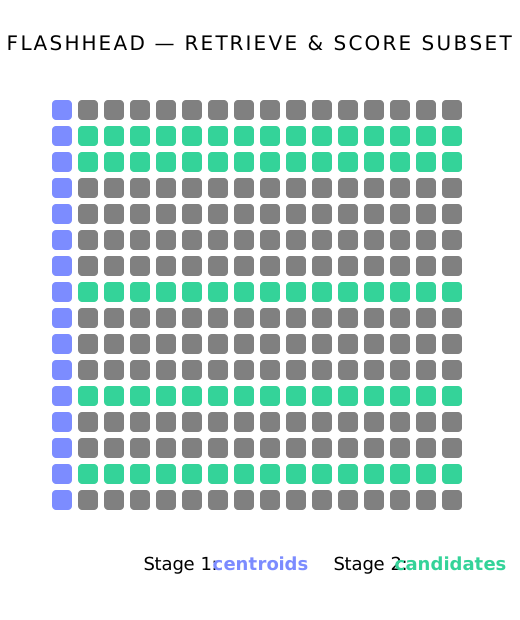
Note. The offline clustering step runs once per model and adds zero overhead at inference time. Both stages use contiguous memory access patterns for GPU and edge accelerator efficiency.
Four key ideas (see paper)
-
Equal-sized Clustering Token embeddings grouped into balanced clusters for predictable memory access and stable latency. Unlike hierarchical softmax, cluster sizes stay uniform; critical for GPU and edge accelerators.
-
Multi-Probe Retrieval Instead of committing to a single cluster, FlashHead probes multiple centroids - beam search over vocabulary space. Near-perfect recall with far fewer evaluations.
-
Full Decoding Support Supports both greedy and sampling decoding. For sampling, clusters are selected proportionally to centroid probabilities, preserving the output distribution.
-
Selective Quantization Stage 1 (coarse centroid scoring) runs in low precision; Stage 2 preserves accuracy. The head's quantization weakness becomes a structural advantage.
📦 Installation
Prerequisites: Python 3.10+ and vLLM >= 0.14.0
pip install flash-head
That's it. The plugin is discovered automatically by vLLM at startup. ✨
Install from source
git clone https://github.com/embedl/flash-head.git
cd flash-head
pip install .
🚀 Usage
⌨️ CLI
# FlashHead activates automatically for compatible models
vllm serve embedl/Cosmos-Reason2-2B-W4A16-Edge2-FlashHead \
    --host 0.0.0.0 --port 8000 \
    --gpu-memory-utilization 0.75 \
    --max-model-len 8192

# Disable without uninstalling
FLASHHEAD_ENABLED=0 vllm serve ...
🐍 Python
from vllm import LLM, SamplingParams

llm = LLM(
    model="embedl/Cosmos-Reason2-2B-W4A16-Edge2-FlashHead",
    trust_remote_code=True,
)
outputs = llm.generate(
    ["Explain quantum computing."],
    SamplingParams(max_tokens=50),
)
print(outputs[0].outputs[0].text)
The model's config.json contains "flash_head_cache_dir": "flash_head_assets" which signals FlashHead to activate. Standard models without this field are completely unaffected.
🔧 vLLM Plugin Integration
- Discovery vLLM discovers the
flash-headplugin via thevllm.general_pluginsentry point at startup - Patching
register()is called in every process, intercepting logits computation, sampling, and speculative decoding - Inference The worker lazily constructs the FlashHead module on GPU from the model's clustering cache
🛡️ Safety
FlashHead models use a custom architecture name (e.g., FlashHeadQwen3VLForConditionalGeneration). Without the plugin installed, vLLM does not recognize the architecture and refuses to load the model. Users cannot accidentally run at reduced speed.
| Scenario | Behavior |
|---|---|
| Plugin not installed | ❌ vLLM errors: architecture not supported |
Plugin installed, FLASHHEAD_ENABLED=0 |
⏸️ Clean disable, model loads without FlashHead |
| Plugin installed, enabled | ✅ FlashHead loads on GPU, full speedup |
🏗️ Supported Architectures
See most recent architectures in _FLASHHEAD_ARCHITECTURES:
_FLASHHEAD_ARCHITECTURES = {
    "FlashHeadLlamaForCausalLM": "vllm.model_executor.models.llama:LlamaForCausalLM",
    "FlashHeadQwen3ForCausalLM": "vllm.model_executor.models.qwen3:Qwen3ForCausalLM",
    "FlashHeadQwen3VLForConditionalGeneration": "vllm.model_executor.models.qwen3_vl:Qwen3VLForConditionalGeneration",
    "FlashHeadQwen3_5ForCausalLM": "vllm.model_executor.models.qwen3_5:Qwen3_5ForCausalLM",
    "FlashHeadQwen3_5MoeForCausalLM": "vllm.model_executor.models.qwen3_5:Qwen3_5MoeForCausalLM",
    "FlashHeadQwen3_5ForConditionalGeneration": "vllm.model_executor.models.qwen3_5:Qwen3_5ForConditionalGeneration",
    "FlashHeadQwen3_5MoeForConditionalGeneration": "vllm.model_executor.models.qwen3_5:Qwen3_5MoeForConditionalGeneration",
    "FlashHeadGemma3ForCausalLM": "vllm.model_executor.models.gemma3:Gemma3ForCausalLM",
}
📤 Publishing FlashHead Models
For the safety check to work, FlashHead models should use this config.json structure:
{
  "architectures": ["FlashHeadQwen3VLForConditionalGeneration"],
  "model_type": "qwen3_vl",
  "flash_head_cache_dir": "flash_head_assets"
}
architecturesuses theFlashHead*prefix so vLLM rejects the model without the pluginmodel_typestays standard so vLLM can resolve the base model classflash_head_cache_dirpoints to the clustering cache directory- Do NOT include
auto_map—the plugin handles registration
🗺️ Roadmap
- ✅ Core FlashHead plugin for vLLM (greedy decoding)
- ✅ Balanced clustering with multiprobe retrieval
- ✅ Inference-time sampling across full vocabulary
- ✅ Quantized model support
- 🔄 Speculative decoding: Full FlashHead integration with vLLM's speculative decoding pipeline (in progress)
- 🔄 EAGLE draft proposals: FlashHead-accelerated draft generation for EAGLE speculative decoding (in progress)
- ⬜ Additional model architectures
- ⬜ Benchmarks on additional edge platforms (Qualcomm, AMD, Intel, ...)
💡 Want a feature? Open an issue!
🤝 Contributing
We welcome contributions, feedback, and collaboration. Whether you're interested in adding support for new architectures, improving performance, or integrating FlashHead into your own inference stack—we'd love to hear from you.
- Report issues Bug reports and feature requests help us improve. Open an issue.
- Submit PRs Code contributions for new architectures, optimizations, or bug fixes.
- Research collaboration Working on efficient inference, vocabulary approximation, or edge deployment? Reach out.
- Model contributions Publish FlashHead-optimized models to the HuggingFace collection.
- Benchmarks Run FlashHead on your hardware and submit results to the Edge Inference Benchmarks space.
📂 Project Structure
flash-head/
├── src/flash_head/
│   ├── __init__.py              # Plugin entry point (register)
│   ├── _version.py              # Package version
│   ├── flash_head.py            # Core clustering-based head
│   ├── loading.py               # Model/asset loading from HF Hub
│   └── patches/                 # vLLM runtime patches
│
├── pyproject.toml
└── LICENSE
📖 Citation
If you use FlashHead in your research, please cite:
@article{tranheden2026flashhead,
  title={FlashHead: Efficient Drop-In Replacement for the Classification Head in Language Model Inference},
  author={Tranheden, Wilhelm and Ahmed, Shahnawaz and Dubhashi, Devdatt and Matthiesen, Jonna and von Essen, Hannes},
  journal={arXiv preprint arXiv:2603.14591},
  year={2026}
}
License
Free for non-commercial use within the Embedl Community License (v.1.0).
Interested in FlashHead?
Enterprise licensing, custom model optimization, and engineering support available.
models@embedl.com • embedl.com
© 2026 Embedl AB. All rights reserved.
Metadata
Release files for flash-head 0.1.10
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| flash_head-0.1.10.tar.gz | 39.1 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| flash_head-0.1.10-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 76.1 kB
Release files / flash_head-0.1.10.tar.gz
| Download URL | flash_head-0.1.10.tar.gz |
|---|---|
| Size | 39.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5ea587ee56c2dfafdcbf279025b9568c428b53091640a7e70ef56cf65a85c809
|
|
BLAKE2b-256 checksum How to use checksums |
97a9f1bcac50f3b078d46a2753140221d40127af0823eaa0cd073d30fe0826e1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Apr 29, 2026.
Transparency logRelease files / flash_head-0.1.10-py3-none-any.whl
| Download URL | flash_head-0.1.10-py3-none-any.whl |
|---|---|
| Size | 37.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1963dbd9dff90b2a6faf99f35214f21cc29c0fe3aec5cda49929d4e911d0be6f
|
|
BLAKE2b-256 checksum How to use checksums |
3e2f4b6669604a8b5d3c36270bd79123e8e3dce48ae4e34e1a72faed182ce3d3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Apr 29, 2026.
Transparency logSecurity for flash-head 0.1.10
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for flash_head-0.1.10.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Apr 29, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














