
🇷🇺 Русский · 🇬🇧 English
frameproof
Your coding agent did not watch that video. It guessed.


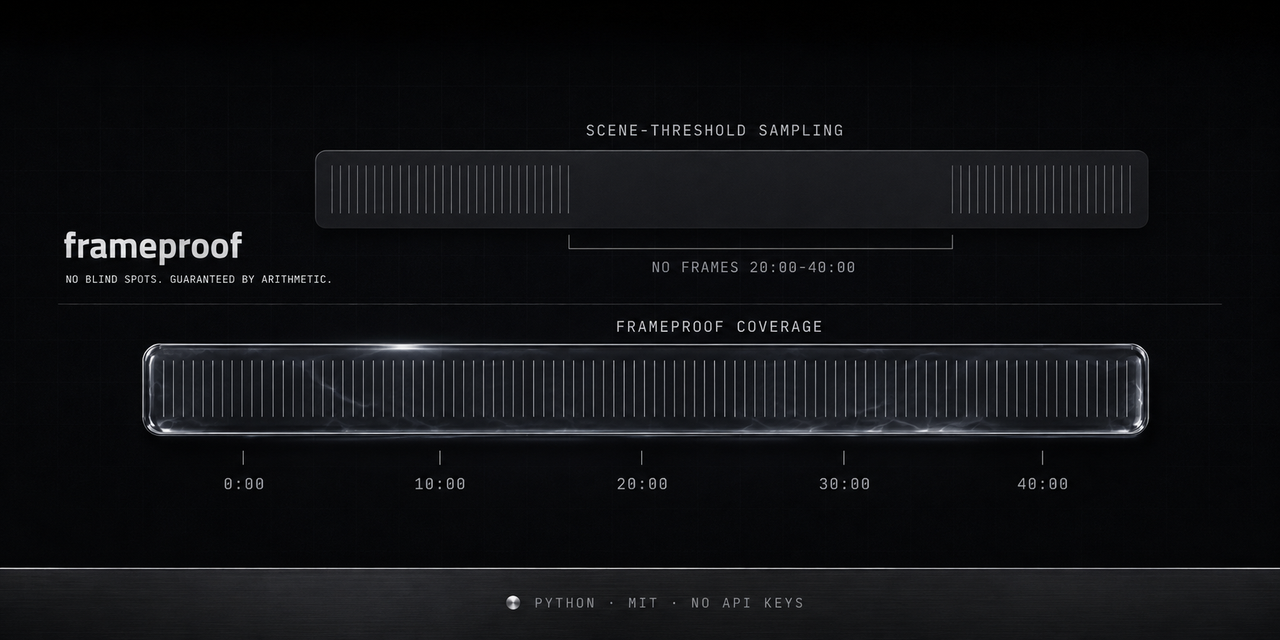
Coverage guaranteed by arithmetic · every screen claim carries a checkable tag · no API keys, ever.
What it does
Ask Claude Code to "watch this tutorial" and it samples frames on a scene-change threshold. On a screencast that threshold cannot fire. A tool may warn that coverage is sparse, but it will not tell you WHERE the hole is — so the agent cannot tell "few frames" from "no frames for twenty minutes straight".
frameproof builds an index instead: frame ↔ timestamp ↔ spoken line. It searches
speech and on-screen text, hands over pictures only when asked, and can audit its
own answer afterwards.
   video   YouTube · Kinescope · Loom · Zoom recording · local mp4
     │
     ▼
  ┌──────────────────────────────────────────────────────────────┐
  │  index    per-cell change detection (not a global threshold) │
  │           + speech anchors ("look here", "see this")         │
  │           + gap fill on a grid — no stretch over --max-gap    │
  │           + OCR on a separate full-resolution copy            │
  └──────────────────────────────────────────────────────────────┘
     │
     │   index.json · segments.jsonl · frames.jsonl · frames/*.jpg
     │
     ├─► search   [9:57 / f0050] screen: OpenRouter • cheaper direct
     │            ⚠ 1 gap near your hit: 15:00–18:00          no images
     │
     ├─► frames   [18:38 / f0097] frames/f0097.jpg (1196 tokens)
     │                                        images — this one only
     │
     └─► verify   FRAME_NOT_FOUND · TIME_MISMATCH · NEVER_OPENED
                                    six checks, zero model calls
pip install frameproof
frameproof index "https://youtube.com/watch?v=..." --ocr
Why the threshold cannot work
ffmpeg's scene filter measures the mean delta across the whole frame. Measured on
ffmpeg 8.0.1 with real terminal colours (#cccccc on #1e1e1e, 640×360):
| what changed on screen | scene score | threshold 0.3 |
|---|---|---|
| one full-width line of text | 0.0579 | no |
| three lines | 0.149 | no |
| half the screen | 0.745 | yes |
Real glyphs cover 10–15 % of a line's area, so a typed command scores around 0.006 — off by a factor of about 40. Lowering the threshold does not help: what rescues a screencast buries a fast-cut video under thousands of frames.
frameproof measures the fraction of changed pixels per grid cell, calibrated
against each cell's own baseline. A cell that moves constantly — the presenter's
webcam, a running timer, a cursor — is suppressed automatically. A cell that stays
quiet most of the video and then changes is an event. The median tells those apart,
not the amplitude: a slide and a terminal change in bursts against long stillness,
a camera changes continuously.
The guarantee
No stretch of the timeline is left without a frame for longer than --max-gap
seconds (15 by default). When the detectors stay silent, frames are placed on a
grid — _fill_gaps() in select.py. Thinning down to the frame cap physically
cannot break it: in _thin() a frame whose removal would produce new_gap > max_gap
is skipped by continue and never considered.
And when the guarantee cannot be met, the tool says so:
покрытие: 97 % — 2 участка без кадров (57 с). НЕ утверждай, что показано на экране в них.
    БЕЗ КАДРА  25:30 – 25:59   (29 с)
Silent blindness is worse than an honest "I did not look here".
The benchmark, losing row included
One 38-minute screencast tutorial, one local file for every run. The competitor is run
with its own code: bench/claude-video is a clone of their repository, commit
83da59f, calling their own extract_scene_or_uniform and extract_keyframes with
default values.
| tool / mode | frames | max gap | % of runtime >30 s without a frame | time |
|---|---|---|---|---|
claude-video balanced (default) |
17 | 20:51 | 98 % | 48 s |
claude-video efficient (default) |
50 | 5:52 | 86 % | 1 s |
claude-video efficient, cap and dedup removed |
473 | 0:07 | 0 % | 1 s |
| frameproof (default) | 228 | 0:14 | 0 % | 52 s |
Read the third row as written. Their own engine, with two flags removed, covers the timeline better than we do — 7 seconds against our 14 — and does it in one second against our fifty-two. Hiding that would be less interesting than printing it.
The claim we do make is narrow: those 473 frames require knowing which two flags to turn off. Our number is what the first command produces.
On information pulled off the screen it is a tie, not a win:
| mode | frames | reliable on-screen terms | per frame | "clean" text |
|---|---|---|---|---|
claude-video efficient, no cap |
473 | 814 | 1.7 | 77 % |
| frameproof | 220 | 789 | 3.6 | 88 % |
Same knowledge, half the pictures. Their frames land on the encoder's keyframe
boundaries; ours land where the thought on screen finished. Their extra terms are
largely 512-pixel garbage — ctficial, wwtoinlhor — which their own docs concede:
"default 512; bump to 1024 only if the user needs to read on-screen text".
Tokens, same video:
| claude-video | frameproof | |
|---|---|---|
| show every frame | 473 × 209 = 98,857 | 228 × 1196 = 272,688 |
| one pointed question ("which command at 4:12") | 25,840 — fixed | 3,192 |
claude-video prints the whole transcript and every frame always; there is no way
to pay less. Break-even is around 20 frames shown per session — past that, we cost more.
Two footnotes to the tables above, both also in bench/RESULTS.md.
Why 228 in one table and 220 in the other. They are two different runs. Coverage was measured with the current tool, which places speech anchors whenever a transcript exists and yields 228 frames. The OCR pass is older and ran over a 220-frame set; dividing its 789 terms by today's 228 frames would mix two measurements. Re-running OCR on the fresh set would make the density 3.5 instead of 3.6, which changes nothing in the conclusion.
The "time" column is indicative only. The saved run in bench/hermes.json reports
51.6 s and 55.8 s where the table says 48 and 52: timing depends on the machine and its
load and does not repeat day to day. Frame counts and gaps do repeat — measure those.
Full method and every caveat: bench/RESULTS.md.
Who this is for
| you are | the pain | what you get |
|---|---|---|
| A developer having an agent watch a tutorial for an unfamiliar tool | The agent confidently names a command that was never on screen, and checking costs more than doing the work yourself | Every screen claim carries [MM:SS / fNNNN], and frameproof verify checks it with arithmetic — including "the frame exists but was never shown to the agent" |
| A reviewer or news creator covering other people's videos | Citing a video means watching all of it and typing timestamps by hand; a transcript retelling lies exactly where it matters — numbers, UI, code on screen | Search runs over speech AND on-screen text (SQLite FTS5 trigrams, so inflected languages just work); a frame loads only for the moment you name — 3,192 tokens against 25,840 |
| Someone studying from a paid course on Kinescope | yt-dlp refuses the host — the extractor request has been open since 2022, and handing it the manifest makes it estimate 96 GiB for a 121 MB lecture |
Our own fetch: the server honours any byte range, downloaded in 32 MB chunks with resume. End-to-end run on an 82-minute lecture: 497 frames, 100 % coverage |
| Whoever writes up calls and internal meetings | An NDA Zoom recording cannot be uploaded to Groq or OpenAI — which is exactly where competing tools send the audio. And a call is not only sound: the screen share, the table, the diagram | Zero API keys. Subtitles come free from yt-dlp; when there are none, transcription runs locally. For a local file the network is never touched — after index, search and frames work with it unplugged |
| Support and QA triaging a customer's screen recording | Twenty minutes of screencast and "it broke somewhere here". The scene threshold cannot fire on a screencast, so automation returns three frames from the intro and outro | Per-cell change detection against each cell's own baseline: a new terminal line clears the 0.015 threshold comfortably, while a twitching webcam or cursor is masked as noise |
| A technical writer needing screenshots from someone else's demo | A screenshot without a timestamp proves nothing, and a frame from mid-animation is useless — the line is half-typed, the slide is still sliding in | The frame is taken after the picture settles (quiet threshold 0.004): the last frame of a burst carries the most finished text. Hence 3.6 reliable terms per frame against 1.7 |
| Whoever has to check someone else's write-up — editor, compliance, supervisor | An LLM summary looks equally convincing whether it is right or invented, so verifying means watching the video yourself | Two layers. Mechanical: verify catches an invented frame, a drifted timestamp, a moment inside a coverage gap, a quote absent from the frame's OCR. Semantic: a blind subagent sees ONLY the frame and the claim, and its job is to refute |
Install
pip install frameproof          # core
pip install "frameproof[net]"   # + yt-dlp for links
pip install "frameproof[mlx]"   # + fast local transcription on Apple Silicon
frameproof doctor               # what is available, what is missing
frameproof install              # install the skill into Claude Code
npx skills add edvardgrishin27/frameproof -g # Codex, Cursor, Copilot, others
We have not verified this outside Claude Code. The
SKILL.mdformat is portable and the manifests are in place, but we will not claim support we did not test — see CLAIMS.md.
Requires ffmpeg. Everything else is optional and degrades gracefully.
No API keys, ever.
Three commands, on purpose
| command | what it does | images |
|---|---|---|
index |
builds the index, prints coverage | none |
search |
searches speech and on-screen text, and names the gaps next to what it found | none |
frames |
returns images | yes — the only one |
This is a split at the command level, not advice in the documentation. If search could return pictures, the savings would vanish on the first query: a 1280×720 frame costs about 1196 visual tokens, while the transcript of an hour is about 50 KB. Most questions are answered without loading a single image.
frameproof search "openrouter" --out ~/.frameproof/hermes
# [9:57 / f0050] screen: ... OpenRouter • дешевле напрямую ...

frameproof frames --at 18:38 --out ~/.frameproof/hermes
# [18:38 / f0097] ~/.frameproof/hermes/frames/f0097.jpg  (1196 токенов)
#
# 1 кадр, примерно 1196 визуальных токенов.
Search is substring-based, over trigrams: memor finds "memory" and "memories" alike,
and Russian case endings stop mattering. Queries shorter than three characters (AI,
v2) are below trigram resolution, so a direct line scan handles those. No vector
index, no external service.
Search tells you where it could not look
A hit is an answer. It is not the whole answer if part of the recording has no frames
at all, so search ends with the gaps sitting near the hit:
[12:30 / seg#1] speech: цена подписки двадцать долларов

1 совпадение. Ни одной картинки не загружено.

⚠ рядом с найденным 1 участок без кадров: 15:00–18:00
  Ответ мог быть и там. Проверьте: frameproof report --out ~/.frameproof/hermes
gaps_near_hits() measures distance from every gap to the nearest hit, so this is a
caveat about YOUR answer, not general statistics: a gap forty minutes away from
everything you found stays quiet.
Two speed tiers
frameproof index <url> --fast     # 1 second
frameproof index <url>            # 32 seconds, frames land better
--fast takes candidates from keyframes instead of decoding the whole video.
Measured on the same 38-minute tutorial:
| mode | frames | reliable on-screen terms | per frame | time |
|---|---|---|---|---|
--fast |
231 | 672 | 2.9 | 1.1 s |
| default | 225 | 789 | 3.5 | 32 s |
The fast tier returns 85 % of the information for 3 % of the time. The trade is honest: frames land where the encoder put a keyframe, not where the thought on screen finished.
The frame budget scales with duration instead of being a constant: a one-minute clip gets 40, a 38-minute tutorial 231, a three-hour lecture 600.
A citation you can check
[18:38 / f0097] is not decoration. It points at a row of the index, and arithmetic
checks it:
frameproof verify answer.md --out ~/.frameproof/hermes
✗ [20:00 / f9999] The memory architecture diagram is on screen.
      FAIL  FRAME_NOT_FOUND: no frame f9999 in the index — the reference is invented
✗ [5:00 / f0097] Here he opens the router settings.
      FAIL  TIME_MISMATCH: the tag says 5:00, frame f0097 was taken at 18:38
?  [29:31 / f0160] A list of ten skills is shown.
      WARN  NEVER_OPENED: the frame exists but was never requested —
            the claim was made without looking
Six checks, zero model calls: does the frame exist · does the timestamp match · does the moment fall in a coverage gap · was the frame ever served to the agent · does the quoted string appear in the frame's OCR · does it appear in nearby speech.
NEVER_OPENED is possible only because serving and indexing are separate: _log_served()
appends every delivered frame id to served.jsonl. A tool that dumps all frames into the
context by default cannot know this about itself.
A blind second look
Meaning is beyond arithmetic. For that there is a separate subagent that sees only the
frame and the claim — not the user's question, not the author's reasoning, not the rest
of the answer. It is declared with tools: Read and its job is to refute.
frameproof verify answer.md --out <index> --plan # tasks carrying no context at all
It runs only when explicitly asked. Refuted claims are flagged, not deleted: measured adversarial panels raise false alarms on up to a third of correct claims, so the call stays with the human. This is a tool for a person, not an automatic filter.
Kinescope
A Russian video host carrying courses and webinars. yt-dlp cannot fetch it: the
extractor request has been open since 2022 and the page returns "Unsupported URL".
Handing it the manifest directly does not help either — 1243 "segments" point at one
file through byte ranges, and the downloader reads media while ignoring mediaRange.
Measured on an 82-minute lecture: yt-dlp estimated 96 GiB for a video that weighs
121 MB (yt-dlp#12687).
So the fetch is our own, and it is simpler: the server honours any range asked of it, so the whole file is addressable directly.
frameproof index "https://kinescope.io/embed/<id>" --ocr
Some videos sit behind a signed link: without expires and sign the manifest returns
403 in DASH and HLS alike. Pass the URL whole, parameters included; if it has none, they
are looked up on the player page. Downloads run in 32 MB chunks with resume — the server
drops a single large request, and a partial file survives both the drop and a restart.
Audio sits in the manifest under a different shape — BaseURL plus byte ranges — and is
fetched alongside the video. DASH carries no subtitles, but some videos have a ready
track in the HLS manifest of the same video: when one is found it is used and the audio
is not downloaded at all. Auto-generated tracks are flagged as such — the host serves
ASR, and ASR is wrong sometimes.
ClearKey-encrypted videos are refused out loud rather than half downloaded: decryption
needs mp4decrypt from Bento4, a separate binary we do not ship.
On YouTube: when the server answers 403 for the chosen format — which happens per
format, not per video — the tool walks the remaining ones down to lower resolution.
Updating yt-dlp helps too, and the tool warns when the installed version is more than
four months old. If every format returns 403, YouTube is asking for a login, and
--cookies-from-browser <browser> uses a live session — that is access to your account,
not an anonymous download, so keep a separate one for it.
Off the Mac
Two places grew up on a MacBook: text recognition went through Apple Vision, and local transcription through mlx-whisper on Apple Silicon. Both doors now open outward, with the core untouched.
# your own recognizer: takes image paths, prints "path<TAB>text"
frameproof index video.mp4 --ocr --ocr-command "python ocr_windows.py"

# your own subtitles instead of transcription — .vtt, .srt or .json3
frameproof index video.mp4 --subs speech.srt
--ocr-command is the same contract the internal Swift binary already speaks, simply
exposed. On Windows 10 and 11 the built-in offline Windows.Media.Ocr fits it directly:
no keys, no install. Reply in UTF-8; a system-ANSI reply is accepted too, but UTF-8 is
the contract.
On resolution. Display frames are scaled down to --width (1280 is a token-cost
decision), and small interface text does not survive that: the same frame of a GitHub
page yielded one word at 1280 and full filenames and commit lines at 2560. Recognition
therefore runs on a separate full-resolution copy that is deleted right after, controlled
by --ocr-width. What you show stays cheap.
Use in Claude Code
After frameproof install, just ask: "watch this video and tell me which command he
shows at 4:12". The skill enforces one rule the agent cannot skip:
Never claim what was on screen without having seen a frame. Every statement about the screen carries a
[MM:SS / fNNNN]tag so a human can check it.
Every headline claim is tied to a command that checks it: pytest -k потолок — that a
missed guarantee is stated out loud; pytest -k скринкаст — that transitions are caught
where the threshold is blind; pytest -k голова — that a constantly moving camera is not
a transition; pytest -k токен — that the token formula matches six control values from
Anthropic's official table.
Honest limits
The full list is in CLAIMS.md. The short version:
- One author, 24 stars. claude-video has 16,696 and 1,681 forks; claude-real-video 2,114; watch-skill 330. If this author stops, there is nobody to pick it up.
- The benchmark is one video, and of the class most favourable to us: a screencast guide, where the gap is widest by construction. On an edited video with frequent cuts the scene threshold works fine and the difference collapses. We have not measured that and will not claim otherwise.
- Their best mode beats us on coverage — 0:07 against 0:14, in 1 second against 52.
- On-screen information is a tie, not a win: 789 reliable terms against 814. We win on density, which is price for the same knowledge, not more knowledge.
- The default is slow: 32–52 seconds against their 1.
--fastcloses that (1.1 s) at the cost of 15 % of the information. - Cheaper only up to a point: break-even is around 20 frames shown per session.
Anyone paging honestly through a whole video pays more here. Contact-sheet packing,
which neighbours use for exactly that case, is not wired up:
contact_sheet()exists inextract.pybut no command calls it (grep -rn contact_sheet). We have never measured what it would save, so no number is claimed here. - Untested outside Claude Code. Portable format, manifests in place, no live run on Codex, Cursor or Copilot.
- Grew on a MacBook. Apple Vision for OCR, mlx-whisper for local transcription.
The doors out are open (
--ocr-command,--subs) andWindows.Media.Ocrfits the contract, but that was verified by a stranger over email, not by our CI. watch-skill runs Windows CI on every push. - Kinescope rests on one public video — no encryption, no signature. Chunked download over a signed link has never run live: the person who held such a link hit a 410 before reaching it. ClearKey videos are refused on principle.
- The blind reviewer is noisy — a third false alarms on correct claims. It never runs on its own and never deletes anything. Selling it as "automatic verification" would be a lie.
- The niche is deliberately narrow. Neighbours cover things we do not: speaker
diarisation, a
--from/--towindow inside a long call, contact-sheet packing, live streams, an MCP server, REST, LangChain and CrewAI adapters, a web UI. We are three commands in a terminal. - The CLI speaks Russian (
покрытие: 97 %,кадров не нашлось) while this README is in English. For a Russian-speaking audience that is a feature; for everyone else it is friction, better said here than discovered in an issue.
Russian documentation: README.md
MIT
1 maintainer

Release files for frameproof 0.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| frameproof-0.7.1.tar.gz | 144.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| frameproof-0.7.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 242.0 kB
Release files / frameproof-0.7.1.tar.gz
| Download URL | frameproof-0.7.1.tar.gz |
|---|---|
| Size | 144.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a3e83d15cceca26b91252abca4edae11918c0cf7ec825a299a10781a12914f67
|
|
BLAKE2b-256 checksum How to use checksums |
f68f7687495505a3de7ed55c7e836930b6eb82d9c649daa14620f9b369c4fc70
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / frameproof-0.7.1-py3-none-any.whl
| Download URL | frameproof-0.7.1-py3-none-any.whl |
|---|---|
| Size | 98.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
dc0bea09cce45cb9b81ae1862c8d32c614aba32f77725a3e0e1031a7a08e7f24
|
|
BLAKE2b-256 checksum How to use checksums |
0c5366b2de8db694ed29c97f20726439a4f9e127fb1b416458a4815afda0609f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency log













