


A fork of upstream Gefen that fixes critical gaps in the shipped release, adds modern-architecture support, and closes the loss gap to AdamW.
Gefen is intended to be a drop-in replacement for the AdamW optimizer for memory-efficient training. It keeps the familiar AdamW training recipe while cutting optimizer state to ~1 byte per parameter (measured 1.01 B/param) — an 8× reduction versus classic fp32 AdamW state, about 6.5 GiB saved per billion parameters, while maintaining AdamW-level loss. The reduced memory footprint enables training larger models and larger batch sizes for added throughput. Gefen-X (fused) currently out-performs AdamW-8bit and AdamW-4bit in throughput, memory, and loss, while staying competitive with the bf16-state fused AdamW baseline's loss at roughly a quarter of the optimizer memory.
Fork Highlights:
- Fine-tuning and pre-training — upstream Gefen was validated for pre-training; this fork makes it a drop-in optimizer for fine-tuning: full fine-tune (FFT), LoRA, and QLoRA, with a VRAM sizing guide.
- New: matches AdamW's loss out of the box at about a quarter of its optimizer memory (default
factored_v_2d). See Benchmarks and the factored-v lever. - Works on modern decoders (Qwen3, Llama-3, Mistral). Upstream loses its memory advantage on these architectures (≈9 B/param — worse than AdamW); this fork keeps the intended ≈1 B/param.
- Validated across 2026 architectures — two dozen modern LLMs, VLMs, and image/video/audio media-gen models full-fine-tuned on 24 GB GPUs, plus 20-30B MoEs via LoRA. See the compatibility matrix.
- ≈2× faster
opt.step()via fused CUDA kernels with validated numerical parity. - Whole-model Muon option (
GefenMuonHybrid) with a selectable AdamW quality backup or ~1 B/param Gefen low-memory backup, plus task-specific SFT and pretraining recipes. - Reliable native checkpoint save/resume and FSDP2 training support — broken or absent in the shipped release; see Distributed Training for the checkpoint compatibility table.
- Hardened against crashes (device/dtype guards, bounds checks, race fixes).
Detailed Fork Improvements (vs upstream)
Capability Upstream v1.1.1 This fork Training regime pre-training fine-tuning — full fine-tune, LoRA & QLoRA, validated across model families and sized per model Loss vs AdamW trails AdamW by ~0.06 matches AdamW via the default factored_v_2d— detailsModern decoders (Qwen3 / Llama-3 / Mistral — SwiGLU + grouped-query attention) uses more optimizer memory than AdamW on these keeps the full ~1 B/param optimizer state (about a quarter of bf16 AdamW's) Learning rate(s) no guidance — silently over-steps documented ~0.6× AdamW, so quality matches AdamW Optimizer-step speed baseline ≈2× faster opt.step()with fused kernelsPeak memory large transient spikes much lower peak — room for bigger models / batches Sharded multi-GPU training (FSDP2) breaks with the fast path works — for plain Gefen and Muon Whole-model Muon 2D weight matrices only GefenMuonHybridtrains the entire modelMuon step efficiency generic momentum hack + redundant dequant gather single-pass bit-exact momentum kernel Save / resume checkpoints can corrupt state or lose tuning on resume native optimizer checkpoints save and resume correctly; distributed checkpoint formats have documented limits Crash safety missing device / edge-case guards guarded against wrong-device, empty-tensor, and race bugs Correctness no fused-kernel tests kernel parity and distributed tests Documentation no Axolotl / fork-install guidance Axolotl how-to + fair loss/speed/memory benchmarks Muon Usage no whole-model recipe or task split measured SFT/pretraining recipes pair quantized Muon with an AdamW backup and document the observed quality/throughput tradeoff; a Gefen backup remains available for minimum state — details Muon (Newton-Schulz) speed fixed 5-step schedule tunable ns_schedule; tuned3 is the balanced SFT choice, while quality-first pretraining retains classic NS5 — detailsLow-precision orthogonalization bf16 only opt-in fp8_nsfor large matrices on newer GPUs, safe fallback elsewhere — detailsSharded Muon under FSDP2 every GPU redundantly repeats the same work sharded_mode="distributed"splits the work across GPUs with identical results on matching GPUs — details
Basic Usage
Installation
pip install gefen-x # imports as `gefen`
[!IMPORTANT] It's
gefen-x, notgefen. This fork publishes asgefen-xand imports asgefen.pip install gefenfetches the upstream package, which does not include the fixes/improvements above.
For development and latest source, install editable from source instead:
git clone https://github.com/thad0ctor/Gefen-X && cd Gefen-X && pip install -e .
The package is pure-Python at install time, the fused kernels (CUDA required) are built on first use via PyTorch JIT (torch.utils.cpp_extension) + nvcc. The first CUDA run takes a few minutes; later runs reuse the cached build keyed on your environment. Force a rebuild with GEFEN_FORCE_REBUILD=1.
Requirements
CUDA toolkit and host compiler compatible with your PyTorch build (the JIT compiles for your GPU's compute capability; set TORCH_CUDA_ARCH_LIST to target arch or a multi-arch build).
Supported versions
| Python | 3.10+ (verified on 3.12) |
| PyTorch | 2.5+ (verified on 2.12 / cu133) |
| Platform | Linux with a CUDA GPU |
The Hugging Face Trainer flow uses transformers and Accelerate, while the data-backed examples also use datasets; these are not core dependencies — install them alongside (pip install transformers 'accelerate>=1.1' datasets). Optional benchmark baselines: bitsandbytes (AdamW-8bit), torchao (AdamW-4bit).
Compatibility
Validated with full-parameter fine-tune smoke tests on 24 GB GPUs across modern LLMs/VLMs and media-generation models — Gemma 4, Qwen3-VL, Mistral 3, MiniCPM-V 4.6, LFM2.5 (+VL), SDXL, Stable Diffusion 3.5, FLUX.1-dev (12B via FSDP2), FLUX.2-klein, Z-Image (6B via FSDP2), Anima, and ACE-Step 1.5 — and on 20-30B MoEs (GPT-OSS-20B, GLM-4.7-Flash) via LoRA adapter training. Per-model results, method, and hardware footprints: COMPATIBILITY.md.
Sizing a GPU? Hardware Requirements gives measured peak VRAM per model size and method (full fine-tune with Gefen vs AdamW, LoRA, QLoRA), plus a per-card rule of thumb for other sizes.
Want a real end-to-end run? See examples/toy-finetune/ — fine-tune a small model in about four minutes on one 24 GB GPU, with a before/after check that makes success obvious.
Learning rate (when porting an AdamW config)
Use ~0.6× your AdamW learning rate (e.g. AdamW at 5e-5 → Gefen at 3e-5). That is Gefen's measured optimum on the models tested (Qwen3 0.6B–8B), and at it Gefen matches AdamW's loss. Don't creep the LR back up toward the AdamW value — Gefen is less tolerant of a too-hot LR than AdamW is.
Better than the heuristic: measure it. The LR finder picks the best LR for your model empirically:
python -m gefen.tools.find_lr --model <path> --optimizer gefen --method sweepSee
tools/README.md.
One knock-on effect: weight decay in AdamW-style optimizers is applied as lr × weight_decay, so scaling lr down to 0.6× also weakens regularization by 0.6×. If your recipe relies on weight decay, scale weight_decay up by the inverse (~1.7×) or retune it.
Background: where the ~0.6× factor comes from
Gefen's compressed optimizer state takes slightly larger effective steps than AdamW on a few small, high-leverage tensors (most sharply the RMSNorm weights, whose whole tensor shares one statistic in the legacy mode). Those tensors set the stability ceiling, which lands the usable LR at ~0.6× AdamW's. The factor is set by the architecture's norm/
head_dimstructure rather than model size — measured across Qwen3-0.6B → 8B (allhead_dim=128) the usable factor stayed in the ~0.57–0.78 band — so re-measure only for a different architecture. The defaultfactored_v_2dsecond moment lands at the same ~0.6× optimum empirically (fair-LR sweep at 0.6B and 1.7B).Measured on a Qwen3-4B full fine-tune: at its own ~0.6× optimum Gefen ties AdamW at 300 and 800 steps with AdamW-like run-to-run spread; forced up to an AdamW-scale LR it lands ~0.3–0.4 worse with ~5× the spread.
Distributed Training
Gefen drops into standard distributed training like any other PyTorch optimizer, with either fused=True or fused=False.
| System | Works with |
|---|---|
| DDP | All optimizers |
| FSDP2 | All optimizers |
| FSDP2 checkpoints | Plain Gefen and Muon approx; resume needs the same GPU count — scope note below |
Muon distributed checkpoints |
Resume on any GPU count, even a single GPU — details |
| DeepSpeed ZeRO 1-3 | Plain Gefen; use FSDP2 or DDP for the Muon family — config note below |
| Megatron-LM | All optimizers, including checkpoint resume — scope |
FSDP2 checkpoint scope. Plain Gefen and Muon
approxsave and resume exactly through PyTorch's standard full-state checkpoint calls, as long as the GPU count and sharding layout are unchanged and every GPU joins the save. Anything outside that scope refuses to load instead of corrupting state — full details.
Mixed precision works out of the box: BF16 and standard AMP behave exactly as with any PyTorch optimizer, and true-FP16 GradScaler training is handled safely — an overflow step changes nothing. FSDP1 FP16 needs torch.distributed.fsdp.ShardedGradScaler.
DeepSpeed ZeRO config. Set
"zero_allow_untested_optimizer": trueand leave the config'soptimizersection unset. With optimizer CPU-offload, also set"zero_force_ds_cpu_optimizer": false— otherwise raw DeepSpeed refuses to initialize, and accelerate-based launchers (axolotl) silently swap in DeepSpeed's own CPU Adam.
Determinism (deterministic)
Set deterministic=True when every GPU replica must produce bit-identical results on matching GPUs. It is off by default (the fastest routing), checkpoints remember the setting, and older checkpoints without it still load. One combination is rejected: plain Gefen with deterministic=True, factored_v_2d=True, and stochastic_round=True together.
optimizer = Gefen(model.named_parameters(), lr=3e-4, fused=True, deterministic=True)
It is an ordinary constructor argument, so it works the same everywhere you build the optimizer: pass it in the Hugging Face Trainer construction, or in axolotl add optim_args: { deterministic: true }.
CUDA Graphs & torch.compile (capturable)
All three optimizers accept capturable=True (same meaning as torch.optim's argument): opt.step() can then be captured in a torch.cuda.CUDAGraph or wrapped in torch.compile(mode="reduce-overhead") — the compiled hybrid step is about 10% faster than eager. Checkpoints stay correct across graph replays. Usage, caveats, and measured numbers: COMPATIBILITY.md.
Benchmarks:
Methodology (settings and environment)
Optimizer comparison on a full fine-tune, with documented task-appropriate learning rates, 2000 steps. AdamW and plain Gefen use their short-sweep fair optima; the Muon row uses the retained balanced-SFT recipe and LR.
You can run these yourself — see
benchmarks/for what each suite measures and how to reproduce the tables/plots (bash benchmarks/optimizer-sweep/run.shregenerates this comparison, with the balanced-SFT Gefen-Muon config applied by default).Testing environment
- Hardware: NVIDIA RTX 3090 (Ampere, sm_86), single GPU per run.
- Software: PyTorch 2.12.0 (cu133), Python 3.12, with Gefen fused CUDA kernels JIT-built for sm_86.
- Models: Qwen3-0.6B and Qwen3-1.7B — full fine-tune (all weights trained, no adapters).
- Regime: bf16 master weights, gradient checkpointing, sequence length 2048, micro-batch 1, Alpaca greedy-packed to 2048-token blocks, 2000 steps, fixed data order, and a 32-example held-out eval.
- Learning rate: AdamW family
5e-5; plain Gefen's short-sweep optimum3e-5; balanced-SFT Gefen-Muon's retained task LR3e-5.- Optimizers:
adamw_bf16= torch fused AdamW ·adamw8bit= bitsandbytes ·adamw4bit= torchao ·gefen_fused=Gefen(fused=True)·gefen_muon= the balanced SFTGefenMuonHybrid(..., backup_optimizer="adamw", fused=True)recipe. "Fused" execution is enabled for every child that supports it.
Full results table (per-optimizer numbers)
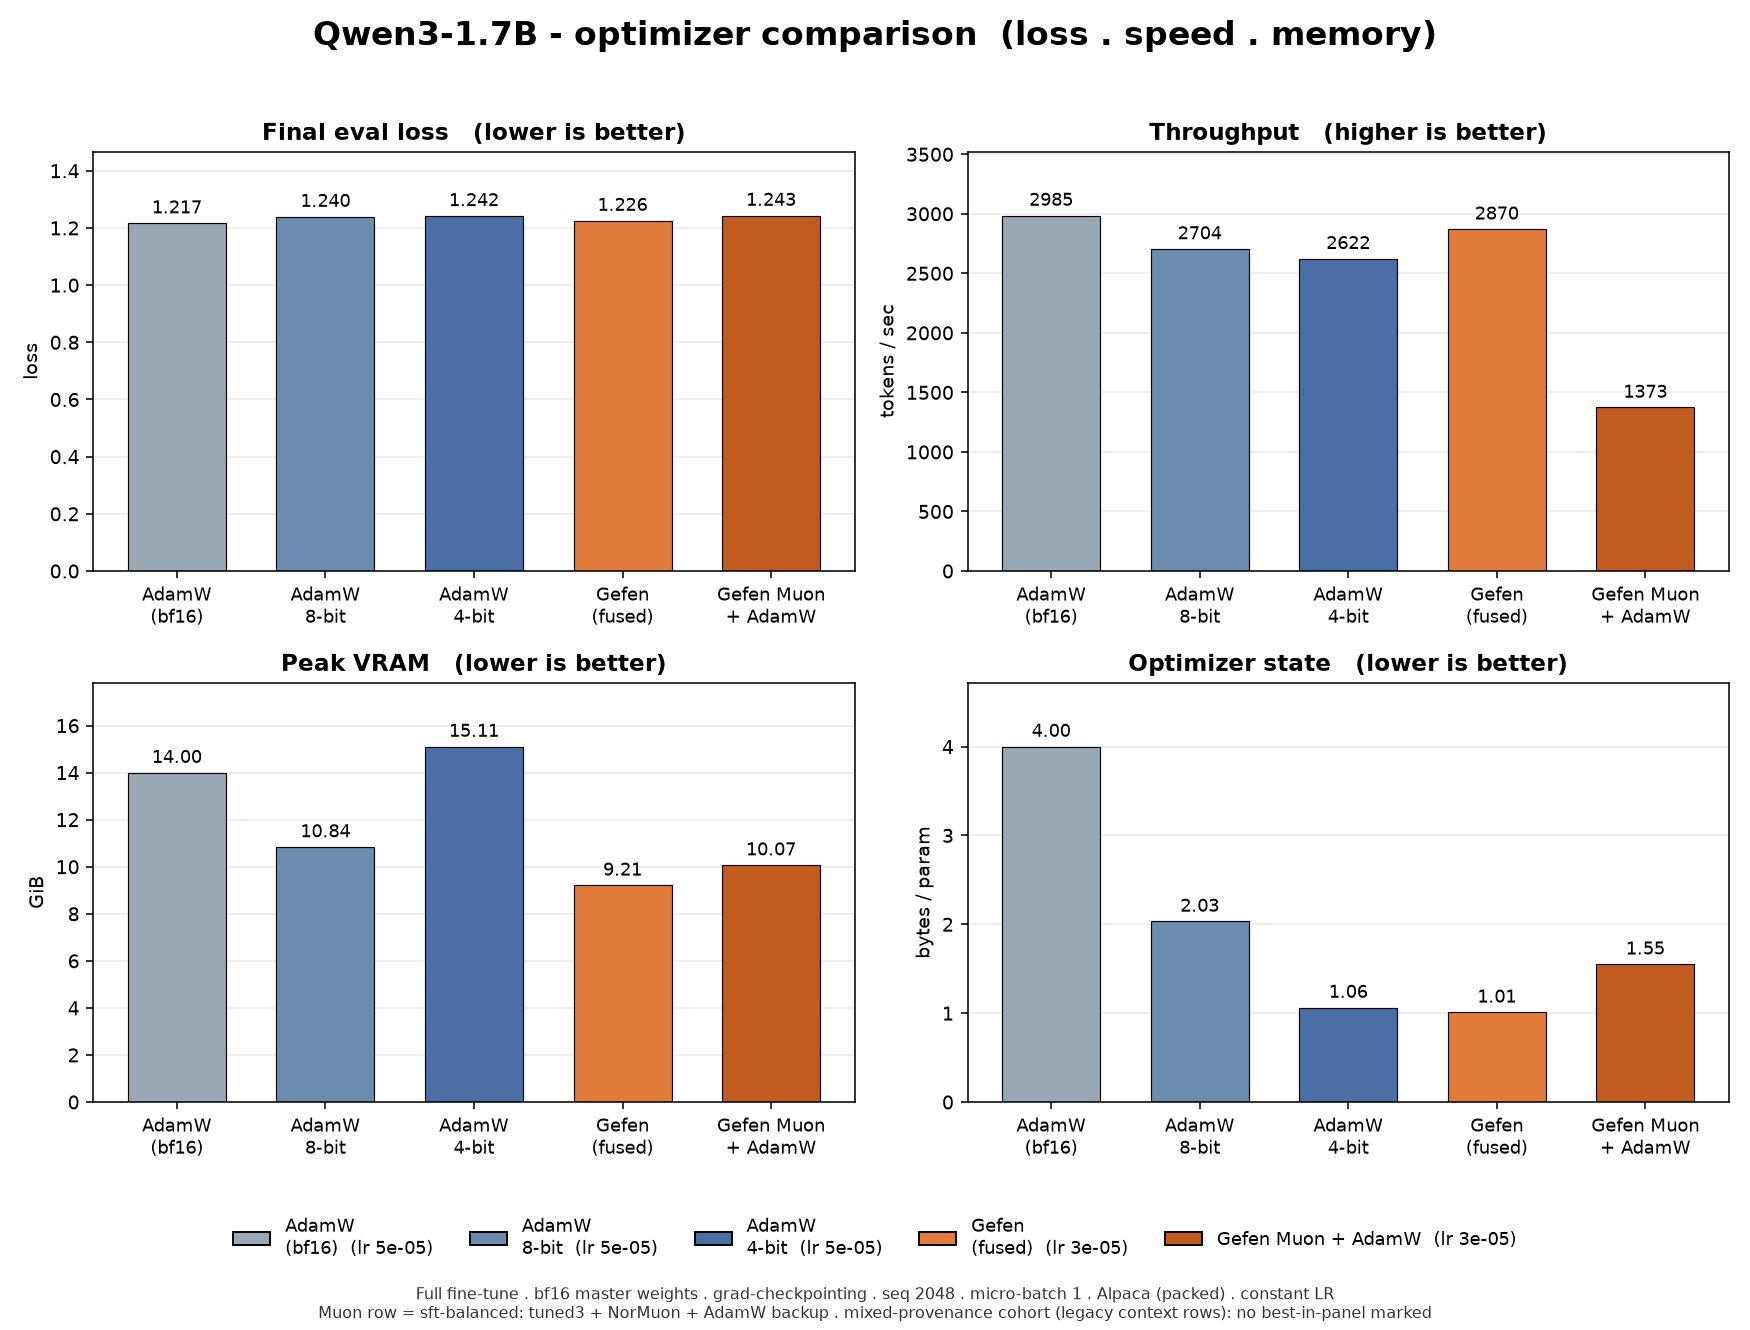
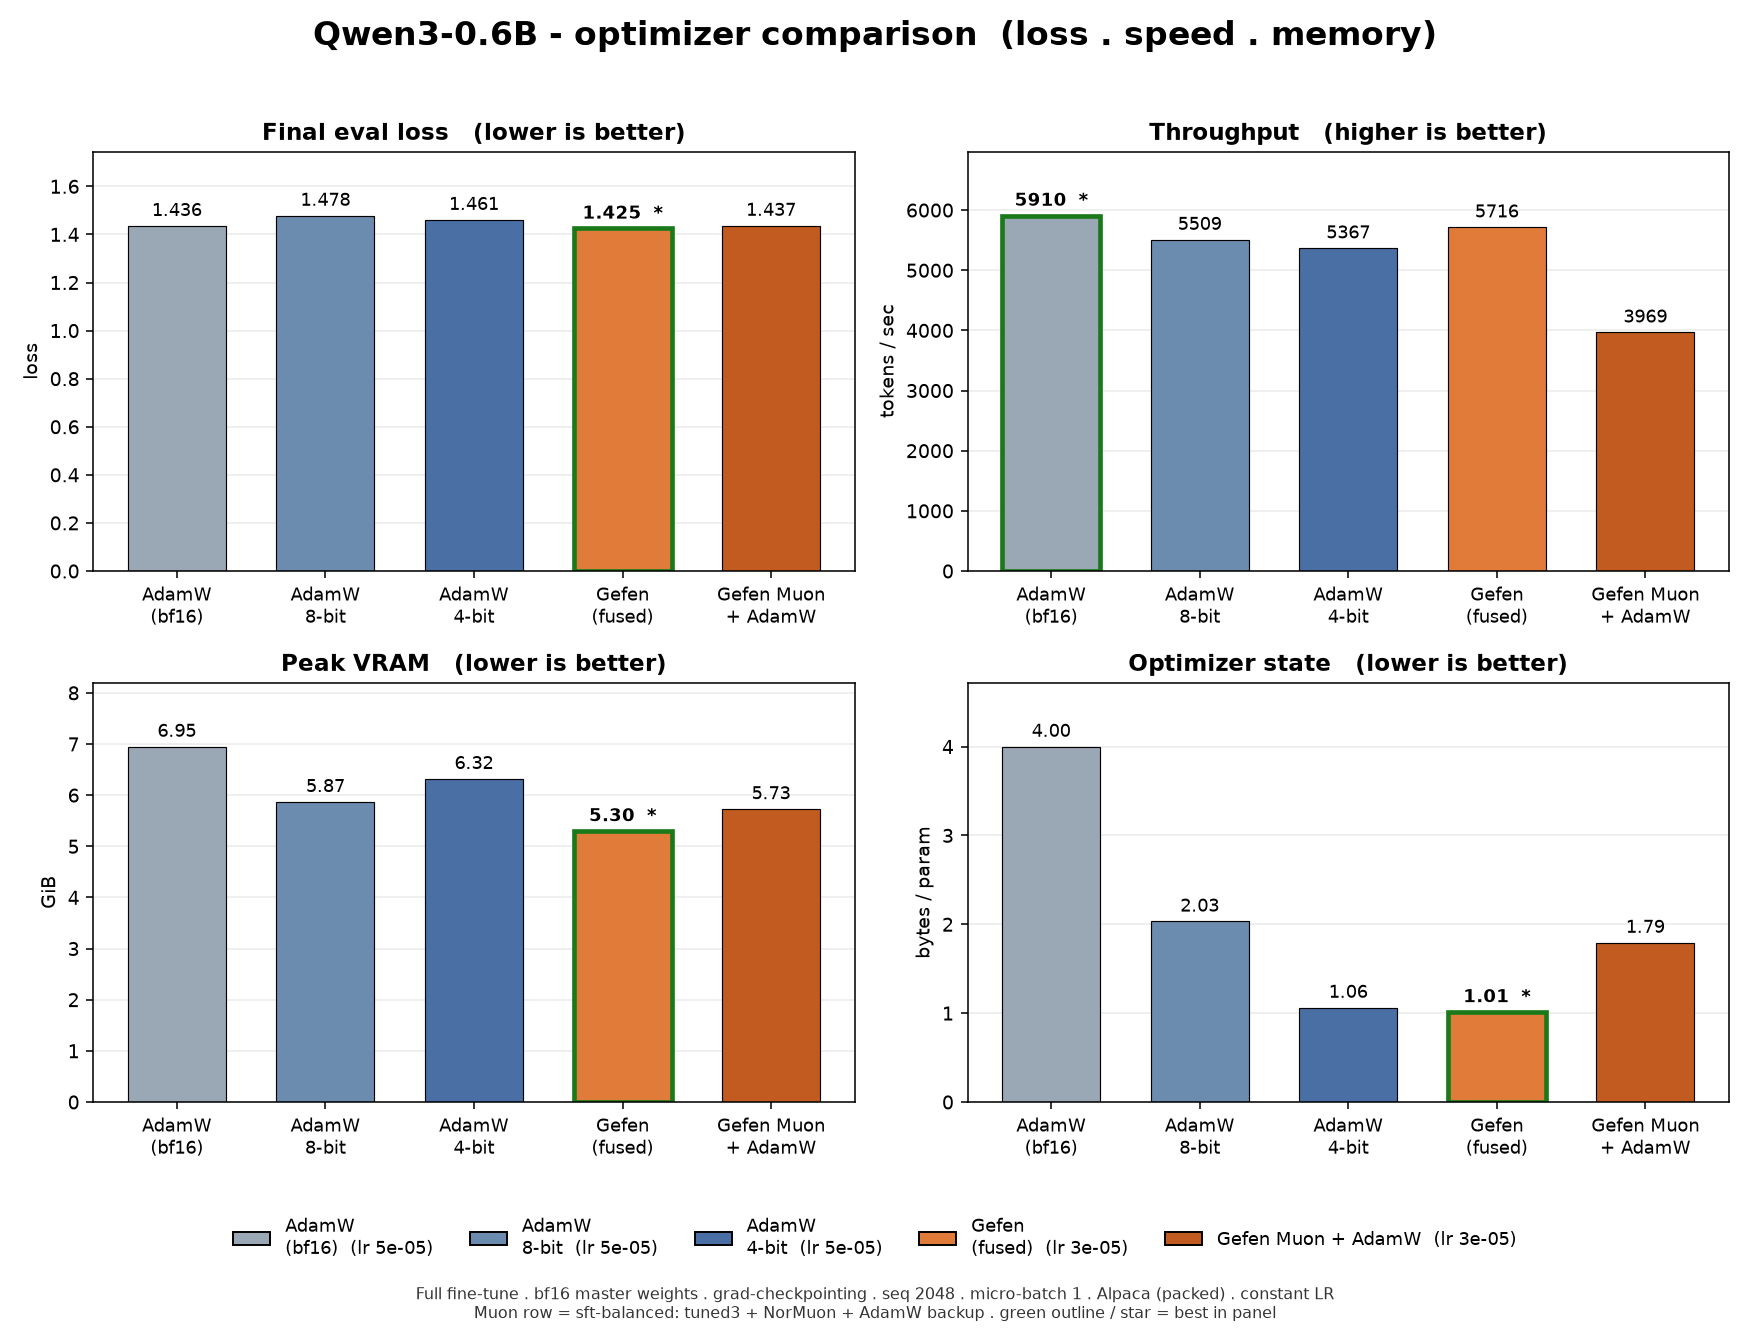
Model Optimizer Provenance LR Eval loss tok/s Peak VRAM (GiB) Opt-state B/param Qwen3-0.6B adamw_bf16 complete 5e-5 1.4360 5910 6.95 4.000 Qwen3-0.6B adamw8bit complete 5e-5 1.4785 5509 5.87 2.033 Qwen3-0.6B adamw4bit complete 5e-5 1.4613 5367 6.32 1.063 Qwen3-0.6B gefen_fused complete 3e-5 1.4251 5716 5.30 1.014 Qwen3-0.6B gefen_muon + AdamW complete 3e-5 1.4368 3969 5.73 1.794 Qwen3-1.7B adamw_bf16 legacy context 5e-5 1.217 2985 14.00 4.00 Qwen3-1.7B adamw8bit legacy context 5e-5 1.240 2704 10.84 2.03 Qwen3-1.7B adamw4bit legacy context 5e-5 1.242 2622 15.11 1.06 Qwen3-1.7B gefen_fused legacy context 3e-5 1.226 2870 9.21 1.01 Qwen3-1.7B gefen_muon + AdamW complete 3e-5 1.2434 1373 10.07 1.550
gefen_fuseduses the shipped defaults.gefen_muon + AdamWis the balanced SFT Muon recipe: tuned3 + NorMuon,backup_optimizer="adamw", and a full-LR backup. The Muon row answers “if I want Muon, how should I run it?”; it is not the fastest or lowest-state optimizer in this table. Use the separate Gefen-backup recipe when minimum optimizer state is the priority.
legacy contextrows lack captured physical UUID, runtime, and source revision. Their raw values remain useful historically, but do not use them for strict loss/throughput deltas against the provenance-complete 1.7B Muon rerun. Best-in-column is marked only in the fully provenance-complete 0.6B cohort; no winner is flagged across the mixed 1.7B block.
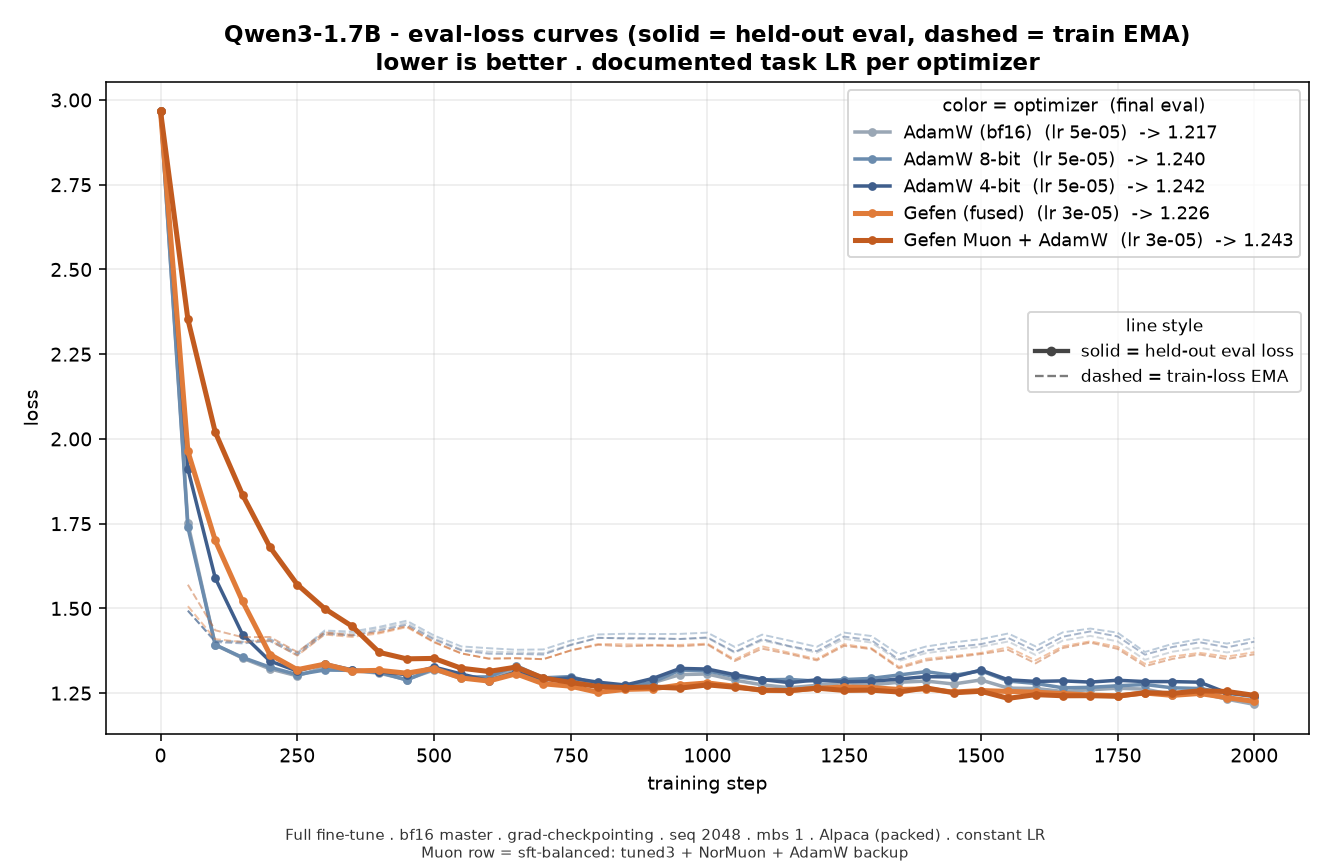
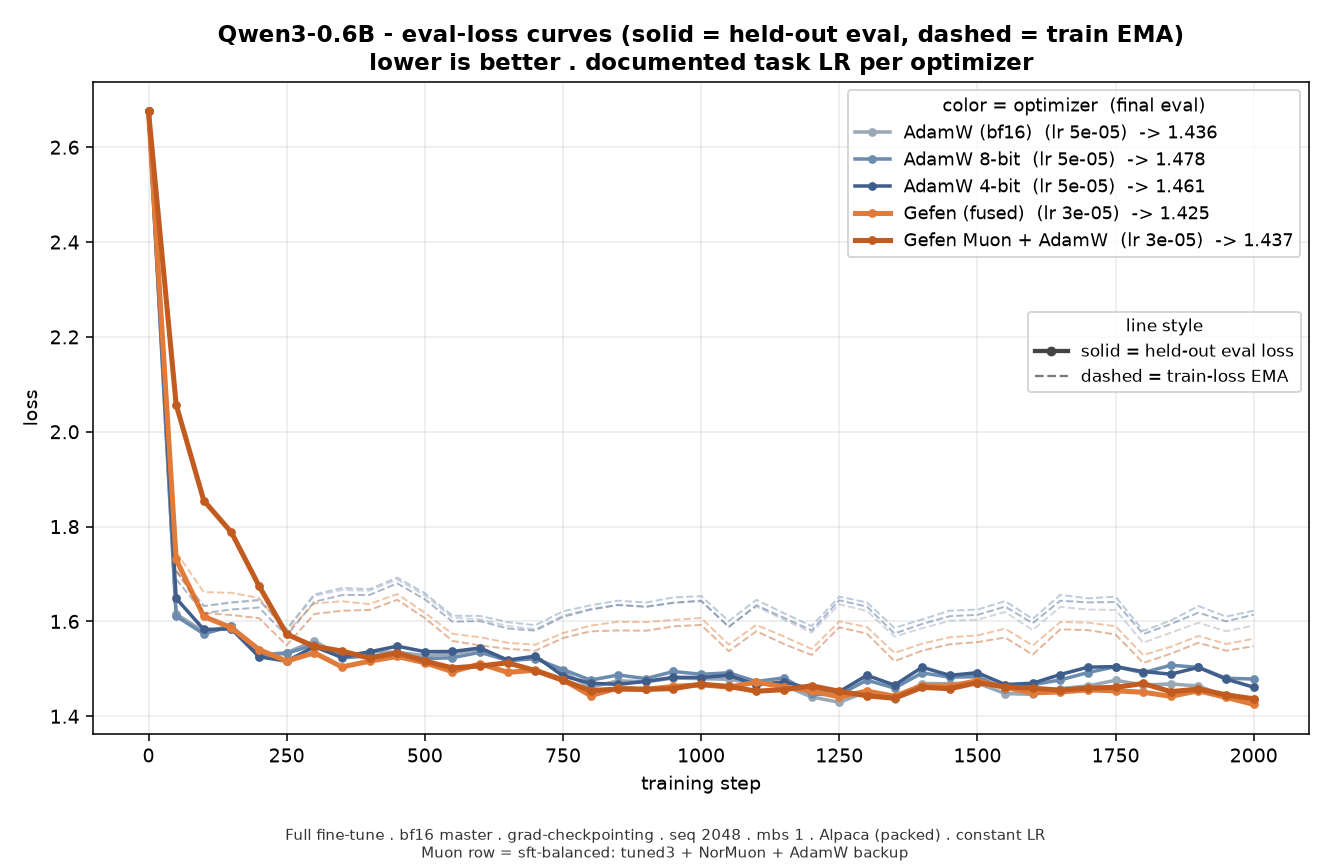
Loss curves — loss over the 2000 steps. For each optimizer (distinguished by color), there are two lines: solid = held-out eval loss (the 32-example validation set, logged every 50 steps — this is the comparison metric in the table above) and dashed = train-loss EMA (exponential moving average of the training loss).
Gefen-fused (with the factored_v_2d default) sits on the AdamW cluster in each retained cohort — best in the provenance-complete 0.6B seed (1.4251 vs 1.4360 for fused AdamW) and a statistical tie within the legacy 1.7B context (1.2257 vs 1.2169; each eval number moves ±0.005–0.007 between reruns, so gaps under ~0.01 are ties). Balanced-SFT Gefen-Muon + AdamW ties fused AdamW at 0.6B (1.4368 vs 1.4360). Its current 1.7B endpoint is 1.2434, but no strict delta against the legacy 1.7B AdamW row is asserted. These are single-seed outcomes, not universal optimizer rankings.
Throughput vs peak VRAM — the speed/memory frontier (upper-left = faster and lighter is better). Gefen-fused holds the lowest-VRAM column at 0.97× fused-AdamW throughput in the complete 0.6B cohort and 0.96× within the legacy 1.7B cohort. AdamW-4-bit has the highest peak VRAM in that legacy 1.7B context despite its small optimizer state (torchao transient buffers).
Why AdamW-4-bit's peak VRAM is high (and Gefen's isn't). torchao's 4-bit step upcasts each parameter's state to fp32 to compute the update ("optimizer step calculations are always done in FP32"), so the peak is set by a transient stack of fp32 buffers sized to the largest tensor — here the tied embedding / LM head — not by the tiny 1.06 B/param packed state. With bf16 master weights the fused-AdamW baseline is already lean, so that fp32 spike pushes 4-bit's peak above even the bf16-state fused AdamW baseline (15.11 vs 14.00 GiB at 1.7B). Gefen keeps the same ~1 B/param state without the fp32 recompute and holds the lowest peak at both measured scales.
Balanced-SFT Gefen-Muon uses less peak VRAM and optimizer state than fused AdamW, but more than plain Gefen because its non-Muon subset keeps conventional AdamW state. Newton–Schulz orthogonalization also makes it the slowest optimizer in this end-to-end table.
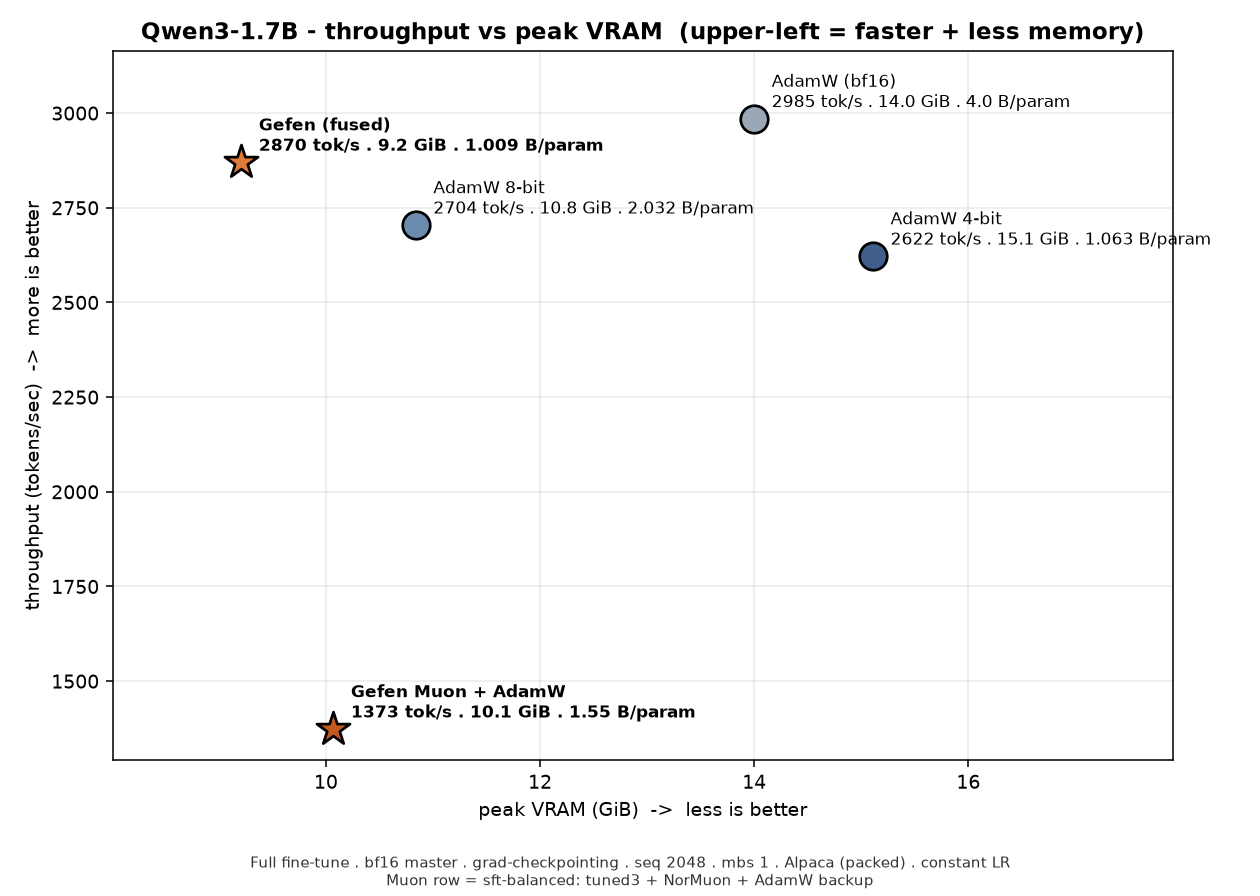
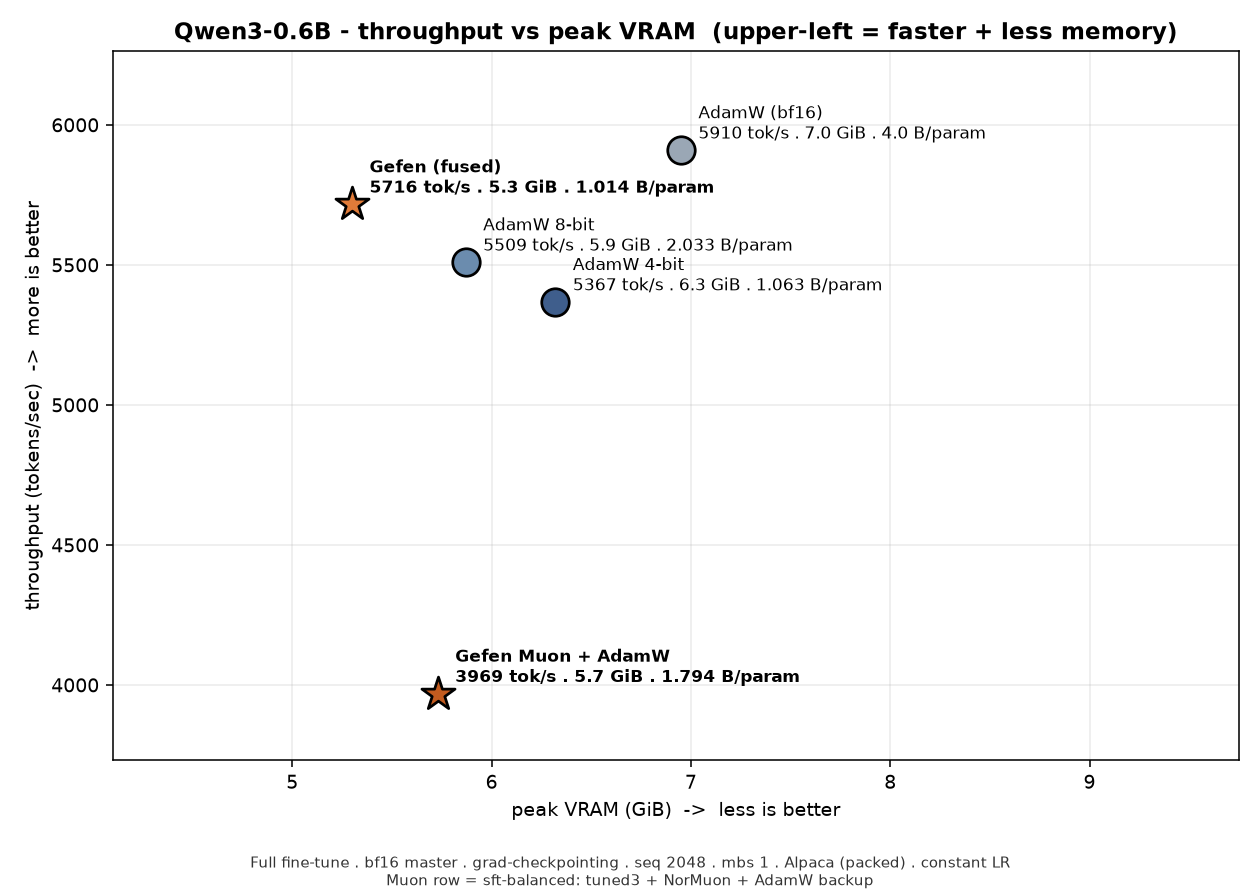
Gefen-fused is the recommended SFT configuration overall: AdamW-level loss with the lowest peak VRAM and the lowest optimizer state in each retained cohort, at 0.97× AdamW's speed in the complete 0.6B comparison and 0.96× within the legacy 1.7B context. (AdamW-4-bit's optimizer state is also small, but its peak VRAM is the highest in the legacy 1.7B results because of transient buffers — Gefen is the real memory winner.)
Gefen-Muon + AdamW is the balanced recipe when you specifically want Muon-style updates: it ties fused AdamW's loss at 0.6B while using 55% less optimizer state, but it is 33% slower. The complete 1.7B Muon row records 1.2434 eval loss, 1373 tok/s, and 1.550 state B/param; the non-Muon 1.7B rows are legacy context, so cross-cohort speed and loss percentages are intentionally not claimed. For minimum-state Muon, use the Gefen backup recipe below; otherwise plain Gefen-fused is the stronger SFT default.
Review the raw runs: per-cell training logs (step-by-step loss, throughput, VRAM) in docs/benchmarks/logs/ · aggregated metrics as CSV and JSONL.
Gefen-X Integrations:
Using Gefen with Axolotl
Axolotl trains with Gefen through two native optimizer names, added by axolotl-ai-cloud/axolotl#3808 (install axolotl from that PR until it lands in a release):
optimizer: gefenx— the core quantized AdamW drop-in (Gefen).optimizer: gefenx_muon— the whole-model Muon hybrid (GefenMuonHybrid): Muon on 2D hidden weights plus a selectable Gefen or AdamW backup for embeddings / LM head / norms / biases.
Install
gefen-x(pip install gefen-x), not the PyPIgefen— which is upstream Gefen, without this fork's fixes (the modern-archperiod==1memory fallback, the ~2× fused kernels, the Muon hybrid). See Installation.
gefenx — memory-efficient AdamW drop-in (recommended):
optimizer: gefenx
learning_rate: 6.0e-6    # ≈0.6× your AdamW LR — Gefen takes larger effective steps
bf16: true
optim_args:
  fused: true            # ≈2× faster opt.step; validated numerical parity (default)
  factored_v_2d: true    # Adafactor-style 2D 2nd moment — matches AdamW loss (default)
gefenx_muon — whole-model Muon hybrid (balanced SFT):
optimizer: gefenx_muon
learning_rate: 3.0e-5    # tune for your model/data; this is the retained SFT LR
bf16: true
optim_args:
  fused: true
  backup_optimizer: adamw
  backup_lr: 3.0e-5      # full LR for embed / head / norms in the balanced recipe
  ns_schedule: tuned3
  normuon: true
  sharded_mode: exact    # "distributed" splits Newton-Schulz across GPUs under FSDP2
The Axolotl factory currently defaults to the low-memory Gefen recipe. To select it explicitly, change the balanced block above to:
optim_args:
  fused: true
  backup_optimizer: gefen
  backup_lr: 1.5e-5      # 0.5 × learning_rate
  backup_1d_period_one: true
  ns_schedule: tuned3
  normuon: true
For quality-first pretraining, keep the AdamW backup at full LR and set ns_schedule: standard plus normuon: false. In every recipe, adjust_lr_fn="match_rms_adamw" keeps Muon updates on the AdamW LR scale.
How config maps: learning_rate, weight_decay, adam_beta1/adam_beta2, and adam_epsilon forward to the selected constructor. Under optim_args, fused and deterministic apply to both optimizer names; factored_v_2d is gefenx-only; and backup_optimizer, backup_lr, ns_schedule, normuon, and sharded_mode are gefenx_muon-only. String values are coerced to type. For plain Gefen, measure the LR instead of relying only on the ~0.6× heuristic: python -m gefen.tools.find_lr --model <path> --optimizer gefen --method sweep — see tools/README.md.
| Lever | axolotl config | Notes |
|---|---|---|
| Select Gefen / Muon hybrid | optimizer: gefenx / gefenx_muon |
core drop-in / whole-model hybrid |
| Muon backup optimizer | optim_args: { backup_optimizer: adamw } |
AdamW for SFT/pretraining quality; gefen for minimum state |
| Fused execution | optim_args: { fused: true } |
selects each chosen optimizer's fused path; Gefen kernels measured ~2× faster opt.step; default on |
| Factored 2D 2nd moment | optim_args: { factored_v_2d: true } |
matches AdamW loss; default on |
| Muon backup LR | optim_args: { backup_lr: <lr> } |
LR for the selected Gefen/AdamW backup; the Axolotl factory defaults to 0.5 × learning_rate, while balanced SFT/pretraining use full LR |
| Sharded Newton-Schulz | optim_args: { sharded_mode: exact } |
exact (default) or distributed (splits NS across GPUs under FSDP2) |
| Determinism | optim_args: { deterministic: true } |
bit-identical GPU replicas on matching GPUs; both optimizer names — details |
| Learning rate | learning_rate: <lr> |
the ~0.6× heuristic applies to plain Gefen; tune Muon by task. Background: Learning rate |
period==1 memory fallback |
on by default in this fork | restores ~1 B/param on modern decoders; module flag MEMORY_SAFE_FALLBACK, not a YAML key |
Hugging Face Trainer
Until native optim="gefen" support is released in Transformers, pass Gefen to the Trainer with optimizer_cls_and_kwargs:
from gefen import Gefen
from transformers import Trainer, TrainingArguments

training_args = TrainingArguments(
    output_dir="outputs",
    learning_rate=3e-5,   # ≈0.6× your AdamW LR — see "Learning rate" above; don't copy an AdamW-scale LR here
    weight_decay=0.0,
)

trainer = Trainer(
    model=model,
    args=training_args,
    train_dataset=train_dataset,
    optimizer_cls_and_kwargs=(
        Gefen,
        {
            "lr": training_args.learning_rate,
            "betas": (training_args.adam_beta1, training_args.adam_beta2),
            "eps": training_args.adam_epsilon,
            "fused": True,
        },
    ),
)
PyTorch
import torch
from gefen import Gefen

device = "cuda" if torch.cuda.is_available() else "cpu"
model = torch.nn.Linear(128, 10).to(device)

# optimizer = torch.optim.AdamW(
optimizer = Gefen(  # Replace AdamW with Gefen:
    model.parameters(),
    lr=1e-3,
    betas=(0.9, 0.999),
    eps=1e-8,
    weight_decay=0.0,
)

inputs = torch.randn(32, 128, device=device)
targets = torch.randint(0, 10, (32,), device=device)

logits = model(inputs)
loss = torch.nn.functional.cross_entropy(logits, targets)
loss.backward()

optimizer.step()
optimizer.zero_grad(set_to_none=True)

print('Finished successfully.')
Extension: Gefen-Muon
GefenMuon adds a Muon-style pseudo-orthogonalization step (Keller Jordan et al., "Muon", 2024) on the first moment (skipping the second moment), then quantizes those first moments to 8-bit with Gefen's partitioning quantization.
Scope — read this first. Like Muon,
GefenMuonoptimizes 2D hidden weight matrices only. It has no code path for embeddings, the LM head, or 1D parameters (norms, biases) — feeding it those will fail or misbehave. For a full model, useGefenMuonHybridbelow, which routes the non-Muon parameters to your selected Gefen or AdamW backup.Pass
(name, param)pairs, not bare tensors.GefenMuonkeys its 8-bit codebook cache on each parameter's name. If you strip the names (e.g.[p for _, p in pairs]) every parameter collapses to the name"none"and the cache is corrupted. Always pass the named pairs through:
from gefen import GefenMuon

# muon_named_params: list of (name, param) for your 2D hidden weight matrices.
optimizer = GefenMuon(muon_named_params, lr=lr)   # note: raw GefenMuon defaults weight_decay=0.1 (the standard Muon recipe), unlike Gefen / the hybrid, which default 0.0
Full models: GefenMuonHybrid
GefenMuonHybrid is the drop-in for training a whole model with Muon. It routes 2D hidden weight matrices to GefenMuon and everything else (embeddings, LM head, norms, biases) to a selectable backup optimizer, behind a single torch.optim.Optimizer interface:
backup_optimizer="gefen"is the backward-compatible default and keeps both halves quantized for the smallest optimizer state.backup_optimizer="adamw"usestorch.optim.AdamWfor the backup parameters; it costs normal AdamW state on that subset but is the measured quality choice for both SFT and pretraining.
Hand it a model and it splits and routes the parameters for you — no manual param lists:
from gefen import GefenMuonHybrid

optimizer = GefenMuonHybrid(model, lr=ADAMW_LR)               # single-argument form
optimizer = GefenMuonHybrid.from_model(model, lr=ADAMW_LR)    # equivalent explicit classmethod
Advanced Usage:
[!NOTE] Advanced tuning levers are available for advanced users. These features are largely experimental in nature and deviate from default settings - often trading tokens/sec throughput for accuracy.
Gefen Muon
Which Muon recipe should I use?
There is no single winner across tasks. The retained RTX 3090 matrix supports three distinct choices. Treat the learning rates below as roles, not universal constants: the SFT run selected 3e-5, while the small pretraining protocol selected 3e-3; tune MUON_LR for your model and data.
SFT: balanced Muon recipe
Use tuned three-step Newton–Schulz plus NorMuon and a full-LR AdamW backup:
optimizer = GefenMuonHybrid(
    model,
    lr=MUON_LR,
    backup_optimizer="adamw",
    backup_lr=MUON_LR,
    ns_schedule="tuned3",
    normuon=True,
    adjust_lr_fn="match_rms_adamw",
    weight_decay=WEIGHT_DECAY,
    fused=True,
)
The retained schedule ablation selected this combination over classic NS5 for SFT. In the curated end-to-end Qwen3-0.6B comparison it tied fused AdamW's loss with 55% less optimizer state, but was 33% slower. The provenance-complete 1.7B Muon run reached 1.2434 eval loss; its non-Muon baselines are legacy context, so no strict cross-cohort loss gap is claimed. This is the recommended way to run Muon for SFT, while plain Gefen-fused remains the stronger overall SFT default on the measured models.
Pretraining: quality first
Keep classic five-step Newton–Schulz, disable NorMuon, and use AdamW on the non-Muon parameters:
optimizer = GefenMuonHybrid(
    model,
    lr=MUON_LR,
    backup_optimizer="adamw",
    backup_lr=MUON_LR,
    ns_schedule="standard",
    ns_steps=5,
    normuon=False,
    adjust_lr_fn="match_rms_adamw",
    weight_decay=WEIGHT_DECAY,
    fused=True,
)
[!NOTE] Classic NS5 won the replicated 33M and 134M pretraining comparisons, so the faster SFT schedule is not promoted as a universal default. The evidence is small-scale and replicated, not a scaling-law claim.
Lowest optimizer memory
Keep the default Gefen backup when capacity matters more than the last quality increment:
optimizer = GefenMuonHybrid(
    model,
    lr=MUON_LR,
    backup_optimizer="gefen",      # constructor default; explicit for clarity
    backup_lr=0.5 * MUON_LR,
    backup_1d_period_one=True,
    ns_schedule="tuned3",
    normuon=True,
    adjust_lr_fn="match_rms_adamw",
    weight_decay=WEIGHT_DECAY,
    fused=True,
)
This keeps both halves on quantized Gefen state and is the low-memory recommendation, not the quality winner. Exact matrix-run figures and protocol are retained in PR #62 rather than a generated report in the repository.
backup_optimizerandfusedare independent. The former selects Gefen or AdamW for non-Muon parameters.fused=Trueselects each chosen optimizer's fused CUDA implementation; it does not mean “use Gefen as the backup.”Manual control. For a custom split,
gefen.split_params_for_muon(model)returns the(muon_named, backup_named)(name, param)lists; pass them as the two positional arguments (GefenMuonHybrid(muon_named, backup_named, lr=...)) and adjust as needed. The single-argument andfrom_modelforms cover the common case.
Muon learning rate — keep adjust_lr_fn="match_rms_adamw" (the default). Muon-native update scaling is not on the same footing as either backup. The default rescale makes an AdamW-scale lr meaningful across the whole hybrid, while muon_lr and backup_lr remain available for deliberate splits:
"match_rms_adamw"(the default) rescales Muon updates to AdamW-equivalent size, so one AdamW-scalelrworks for the whole model.Nonekeeps Muon's native scaling — an AdamW-sizedlrthen under-trains the Muon matrices, and no singlelrsuits both halves. Don't combineNonewith an AdamW-scalelr.
Optional knobs (GefenMuonHybrid):
| Knob | Default | What it does | When to change it |
|---|---|---|---|
backup_optimizer |
"gefen" |
backup for embeddings/head/norms/biases | "adamw" for the SFT/pretraining quality recipes; keep Gefen for minimum state |
backup_lr |
= lr |
learning rate for the selected backup half | full LR with AdamW; ~0.5× lr for the measured low-memory Gefen recipe |
backup_1d_period_one |
False |
per-element 2nd moment on 1D Gefen-backup tensors | True only in the low-memory Gefen recipe; AdamW is already per-element |
ns_schedule |
"tuned3" |
three-step Newton–Schulz for higher throughput — details | keep tuned3 for balanced SFT; use "standard" for quality-first pretraining |
normuon |
True |
free per-neuron 2nd moment on the NS output; recovers tuned3 quality in SFT — details | keep on for SFT; disable for classic pretraining |
backup_2d_period_one |
False |
per-element 2nd moment on a Gefen-backed embedding/LM head — extra memory — details | Gefen backup only; AdamW already keeps per-element moments |
stochastic_round |
False |
unbiased rounding for the 8-bit momentum (free, loss-neutral) | optional |
deterministic |
False |
bit-identical updates on matching GPUs; remembered by checkpoints | enable when replicas must match exactly |
capturable |
False |
CUDA-graph-capturable step(), like torch.optim's capturable — details |
turn on to capture step() in a torch.cuda.CUDAGraph |
It supports step(), zero_grad(), state_dict()/load_state_dict(), and LR schedulers (e.g. torch.optim.lr_scheduler.StepLR(optimizer, ...)) like any optimizer. Because it splits params at construction rather than taking a single iterable, build it yourself and hand it to the Hugging Face Trainer via optimizers= (not optimizer_cls_and_kwargs):
optimizer = GefenMuonHybrid(
    model,
    lr=training_args.learning_rate,
    backup_optimizer="adamw",
    backup_lr=training_args.learning_rate,
    ns_schedule="tuned3",
    normuon=True,
)
trainer = Trainer(model=model, args=training_args, train_dataset=train_dataset,
                  optimizers=(optimizer, None))  # (optimizer, lr_scheduler)
To prove save/resume in a real Trainer run, use benchmarks/trainer_resume/: it compares an uninterrupted run against a save-and-resume run and requires them to match exactly. The run command and covered scope are in COMPATIBILITY.md.
Quality Lever: factored second moment on 2D params (factored_v_2d)
[!NOTE] On by default — this is what makes plain Gefen match AdamW's loss. Set
factored_v_2d=Falsefor the legacy behavior: ~4% faster end-to-end at 1.7B (on par with fused AdamW's throughput), about 0.06 worse eval loss, and a lower best learning rate (2e-5instead of3e-5at the benchmarked scales).
Gefen historically shared one adaptive step size across each block of parameters, where AdamW keeps one per parameter — that granularity difference was the ~0.06 loss gap. factored_v_2d gives every parameter of a weight matrix its own step size by tracking just one statistic per row and one per column (the Adafactor idea) and combining them on the fly inside the update kernel. The stored state is only rows + columns per matrix, so the ~1 B/param memory story is unchanged.
opt = Gefen(model.named_parameters(), lr=0.6 * ADAMW_LR, fused=True) # factored-v is the default
| Gefen (default) | AdamW bf16 | Gefen legacy (factored_v_2d=False) |
|
|---|---|---|---|
| Qwen3-0.6B eval loss | 1.425 | 1.436 | 1.497 |
| Qwen3-1.7B eval loss | 1.226 | 1.217 | 1.286 |
| Qwen3-1.7B tok/s | 2870 | 2985 | 2996 |
| Optimizer state | 1.01 B/param | 4.00 | 1.01 |
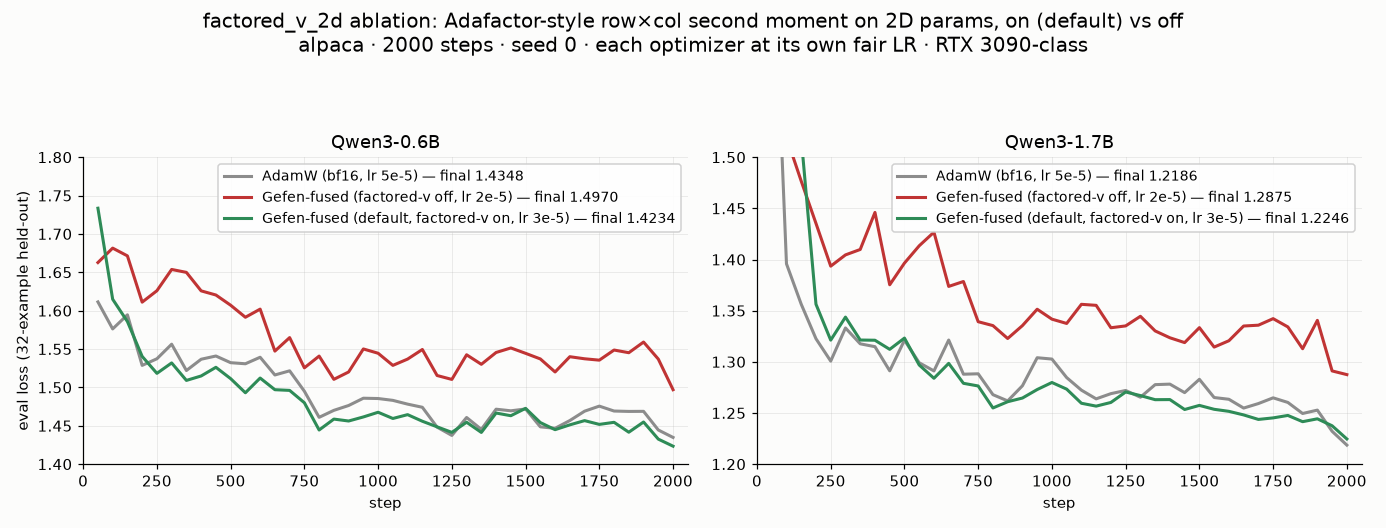
Chart from the original factored-v ablation run. The table combines the current retained optimizer rows with that ablation; current per-cell logs and the retained Qwen3-1.7B legacy-mode log live in
docs/benchmarks/logs/.
Details: validation, checkpoint migration, and limits
- Validated at both scales in the fair-LR regime, with a second-seed replication at 0.6B and a learning-rate sweep at 1.7B (best LR
3e-5~ 0.6× AdamW's, matching Gefen's documented heuristic). The fused kernel computes the per-element step size in registers (no extra temporaries; step transients measured 0 MiB) and is covered bytests/test_gefen_factored_v.py. - Native Gefen checkpoints migrate automatically in both directions (old checkpoints work with the new default and vice versa; the second-moment statistics re-warm briefly and harmlessly). Distributed checkpoints follow the compatibility table.
- With
backup_optimizer="gefen",GefenMuonHybridpins the backup half to Gefen's legacy block-vmean path (the factored-v combination has not been benchmarked). Withbackup_optimizer="adamw", the backup uses conventional per-element AdamW state. Under FSDP2, sharded 2D Gefen params also fall back to the legacy path. - Two sibling experiments from the same investigation ship off by default because they measured no effect:
period_one_substrings(per-element state on name-matched tensors) andcodebook_refresh_every(periodic codebook refit).
Experimental Lever: faster Newton-Schulz (ns_schedule, fp8_ns)
[!NOTE]
GefenMuonHybriddefaults tons_schedule="tuned3"for throughput. Keep it for the balanced SFT recipe; usens_schedule="standard"for quality-first pretraining.fp8_nsis off by default.
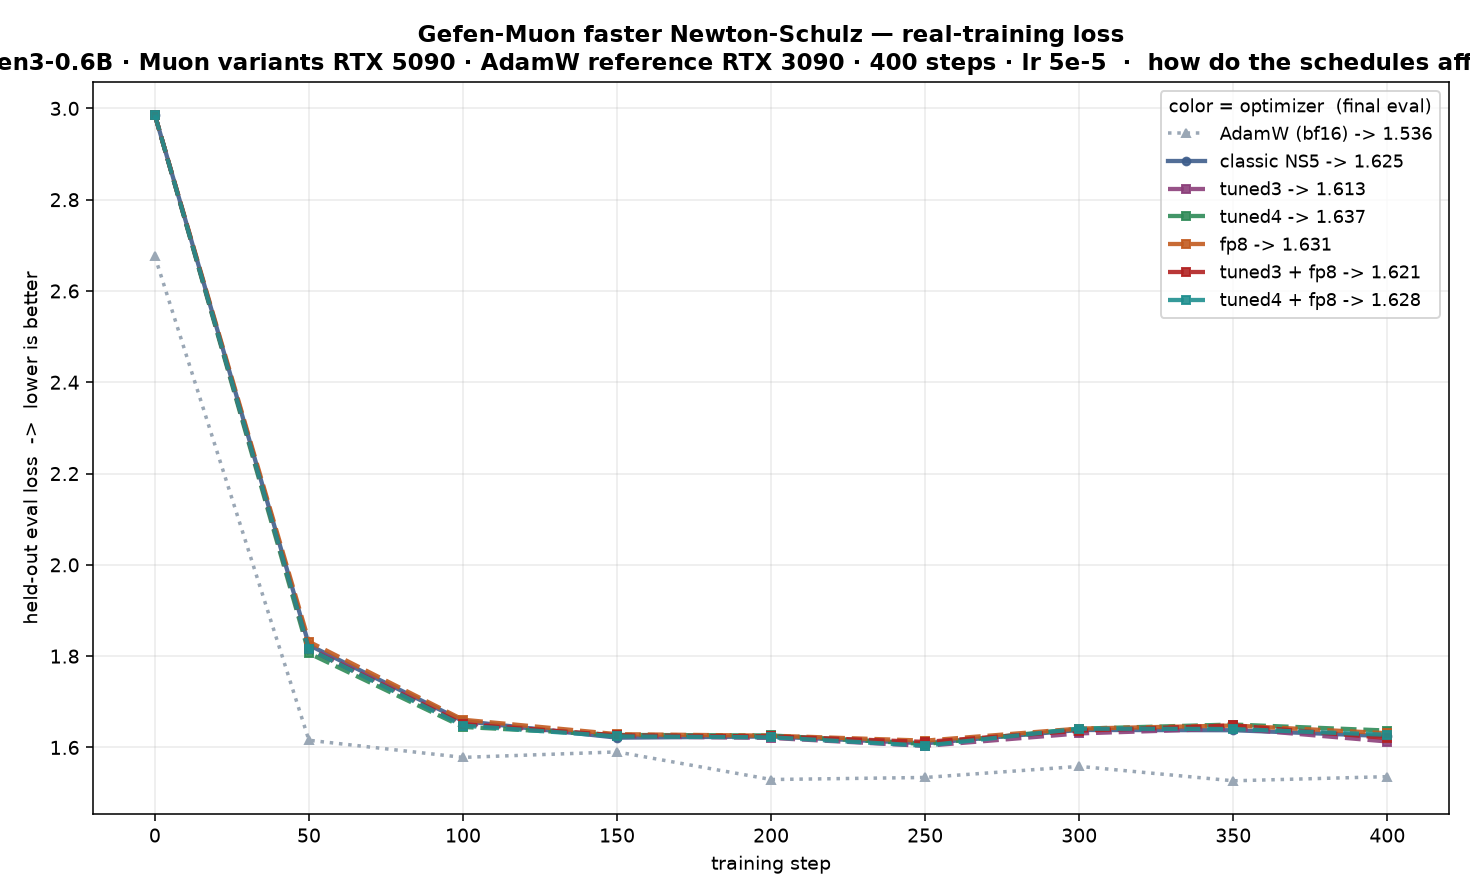
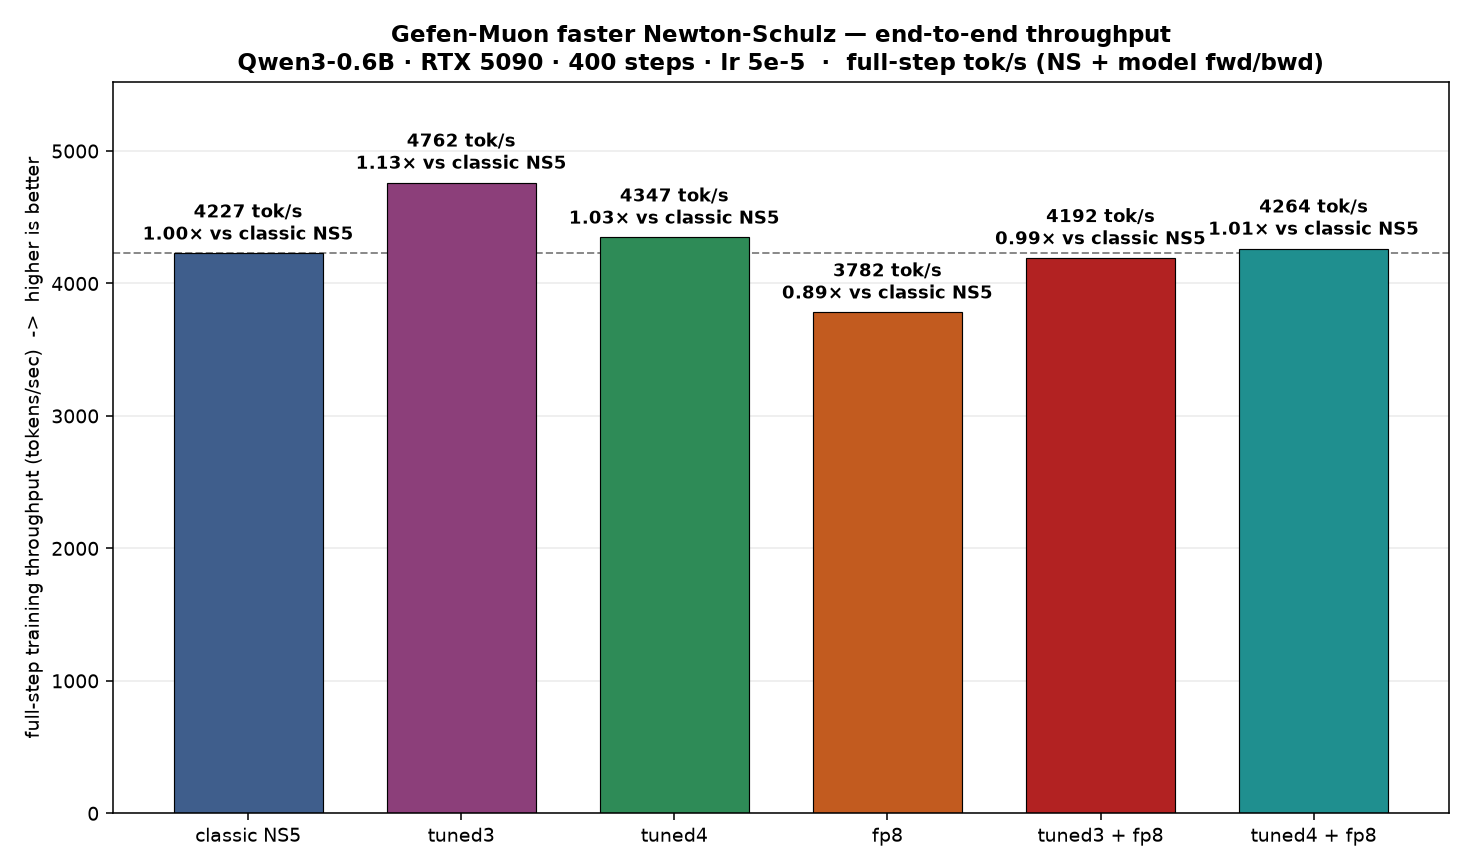
The orthogonalization step is ~90% of a Muon step, so it has two speed levers:
ns_schedule— fewer Newton–Schulz iterations for more throughput."tuned3"(the hybrid default) is ~1.6× faster in the optimizer kernel. It carries a measurable pretraining-quality trade, while adding NorMuon recovers the classic endpoint/tail in the retained SFT run.fp8_ns— run the matrix math in fp8 on GPUs that support it (RTX 40-series/Hopper and newer) for matrices large enough to benefit; everywhere else it silently falls back to normal precision, so it's always safe to enable.
opt = GefenMuonHybrid(
    muon_named_params, backup_named_params,
    lr=5e-5, adjust_lr_fn="match_rms_adamw", fused=True,
    ns_schedule="tuned4",   # "tuned3" (hybrid default, ~1.6x) | "tuned4" (equal-quality, ~1.2x) | "standard" (classic quintic)
    fp8_ns=True,            # sm_89+ large matrices only; a no-op bf16 fallback elsewhere
)
Measured: fp8_ns pays off on larger models (~1.2× end-to-end at Qwen3-4B) and its built-in size gate avoids the penalty on small ones. tuned3 improves end-to-end throughput, but its quality is task-dependent: pair it with NorMuon for SFT, and retain classic NS5 for quality-first pretraining. The exact retained schedule comparison is documented in PR #62.
Quality Lever: per-neuron 2nd moment on the Newton-Schulz output (normuon)
[!NOTE] On by default in
GefenMuonHybrid; free on speed and memory. Disable withnormuon=False.
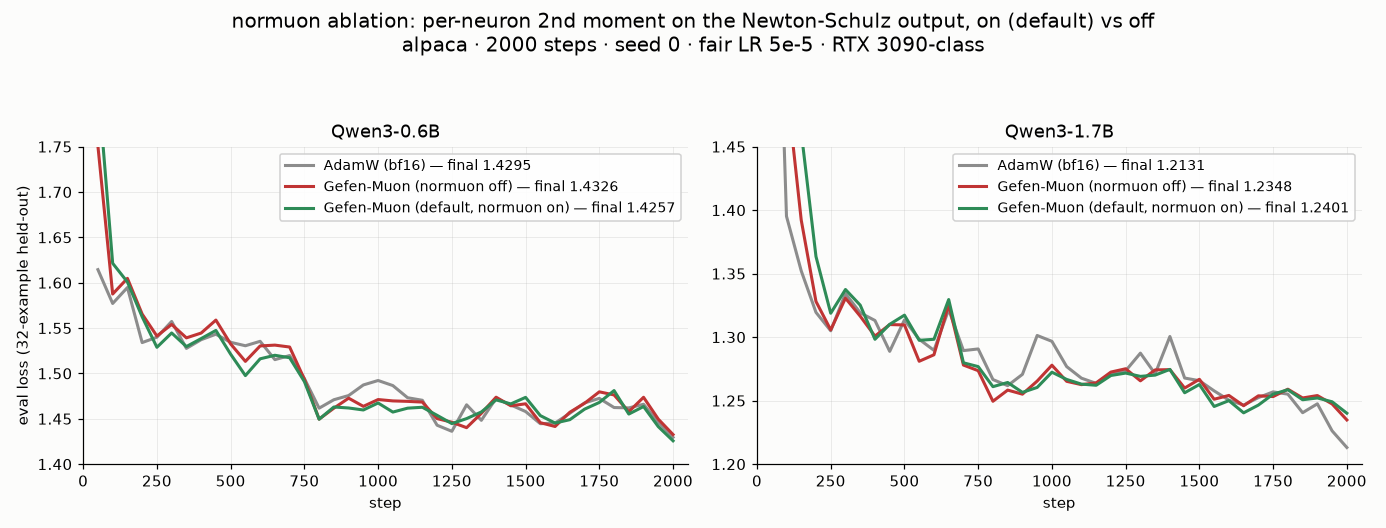
Muon's orthogonalization step leaves some output neurons taking slightly bigger steps than others. normuon (after NorMuon) evens that out by tracking a running average per neuron and normalizing against it — at essentially zero cost in speed or memory.
Measured in SFT: a small, consistent recovery for tuned3, culminating in an endpoint/tail tie with classic NS5 on the retained 2,000-update frontier. The quality-first pretraining recipe instead uses classic NS5 with NorMuon off. A related experiment (cautious=True, sign-agreement masking) clearly hurt and ships off.
Experimental Lever: per-element Gefen-backup state on embed / LM-head (backup_2d_period_one)
[!NOTE] Opt-in, default off. Unlike the levers above, this one costs memory — it's a deliberate loss-for-memory trade.
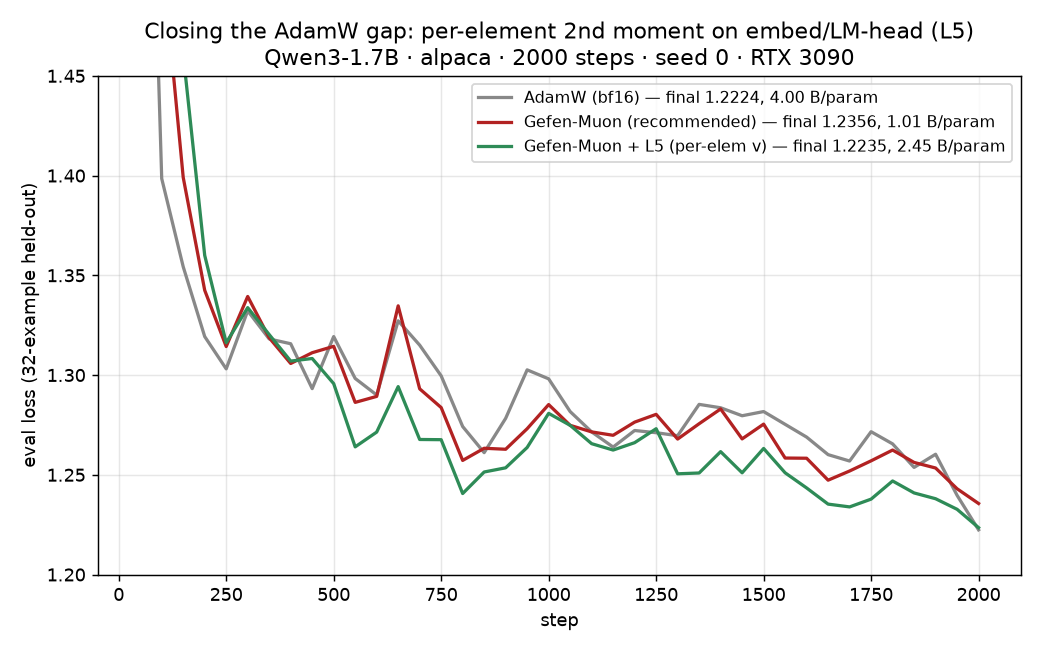
With a Gefen backup, this knob gives embeddings and the LM head full per-element statistics, like AdamW keeps everywhere. It is a deliberate loss/memory experiment and has no effect in AdamW-backup mode because AdamW is already per-element.
opt = GefenMuonHybrid(
    model,
    backup_optimizer="gefen",
    lr=5e-5, backup_lr=2.5e-5, adjust_lr_fn="match_rms_adamw",
    backup_1d_period_one=True,
    backup_2d_period_one=True,   # per-element v on embed/LM-head; costs memory
)
A Qwen3-1.7B sweep closed a small AdamW gap at 2.45 B/param. In the newer controlled matrix, the 2D variants made only small loss changes while clearly increasing state, peak VRAM, and step cost. Leave it off for the low-memory recipe; select the AdamW backup directly when quality is the objective.
A related opt-in, stochastic_round=True, switches the 8-bit momentum to unbiased rounding. It's free and validated but measured loss-neutral, so it stays optional.
Experimental Lever: sharded Newton-Schulz under FSDP2 (sharded_mode)
[!NOTE] Opt-in. Default is
sharded_mode="exact"(single-GPU parity).
Under FSDP2, Muon's orthogonalization needs each full weight matrix, but every GPU only holds a slice. Three strategies:
"exact"(default) — every GPU rebuilds every matrix and does the same work. It matches the single-GPU oracle within the tested BF16 tolerance, but the cross-rank GEMM path is not promised bitwise identical; the work is redundant."distributed"(experimental) — each matrix is assigned by its stable position in the full distributed parameter set to one GPU, which does the work and shares the result. Bit-identical to"exact"on homogeneous GPUs and faster as you add them. Momentum ownership is stable when the active gradient set varies, andstate_dict()collectively gathers owner-local momentum so rank 0 can write a complete checkpoint after all ranks call it."approx"— each GPU works on just its slice. Fastest, but results genuinely differ — an accuracy trade.
from gefen import GefenMuonHybrid

opt = GefenMuonHybrid(
    muon_named_params, backup_named_params,
    lr=5e-5, adjust_lr_fn="match_rms_adamw", fused=True,
    sharded_mode="distributed",  # "exact" (default, parity) | "distributed" (experimental, collective checkpoint) | "approx" (fastest, non-parity)
)
# only takes effect under FSDP2 (DTensor params); no-op single-GPU
"distributed"checkpointing is collective.state_dict()gathers each owner's momentum across ranks, so every rank must call it (as in a standard FSDP full-state-dict flow). Callingstate_dict()on rank 0 only — e.g. a rank-0-only save loop — deadlocks. Save and load also transiently materialize the full unsharded momentum on every rank, so peak memory at checkpoint time approaches"exact"mode's. The saved checkpoint is complete on every rank and resumes under any world size, including a single-process optimizer; incomplete or inconsistent owner state fails closed before any state is touched.
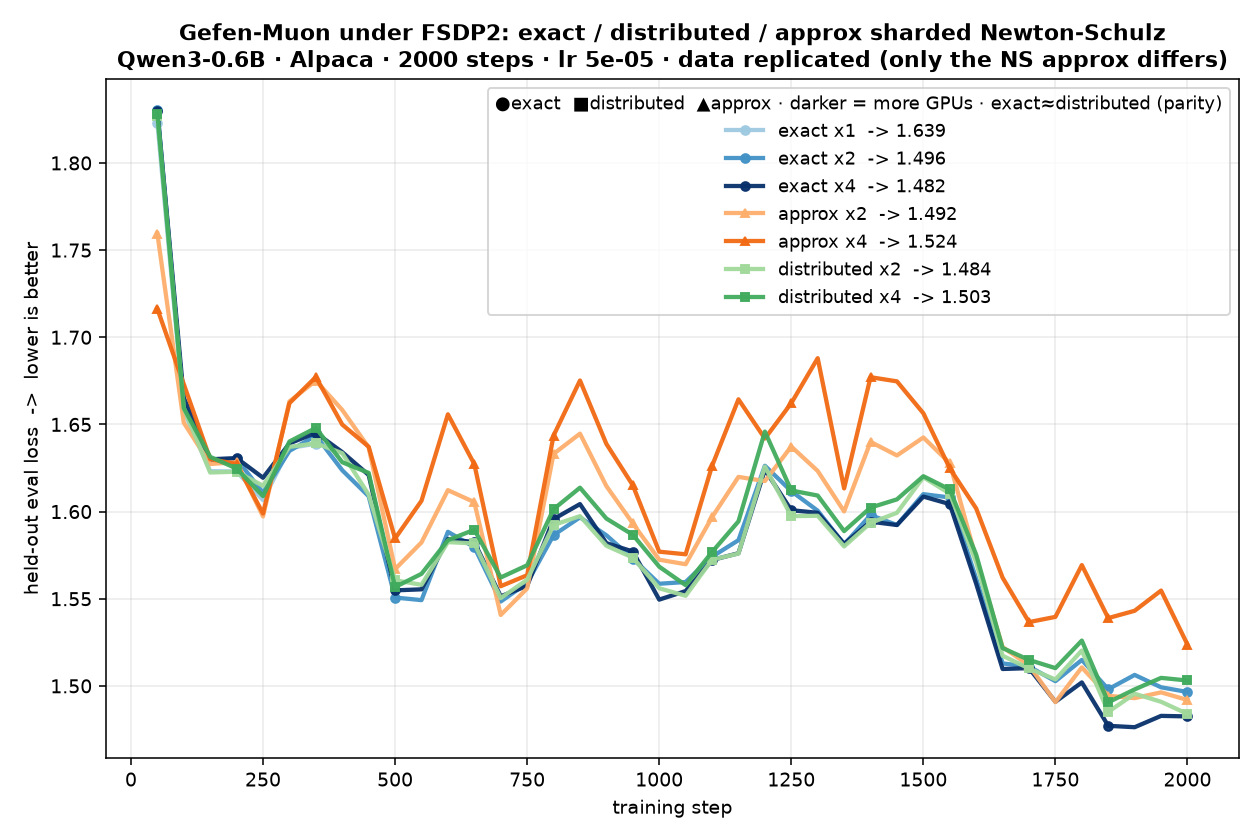
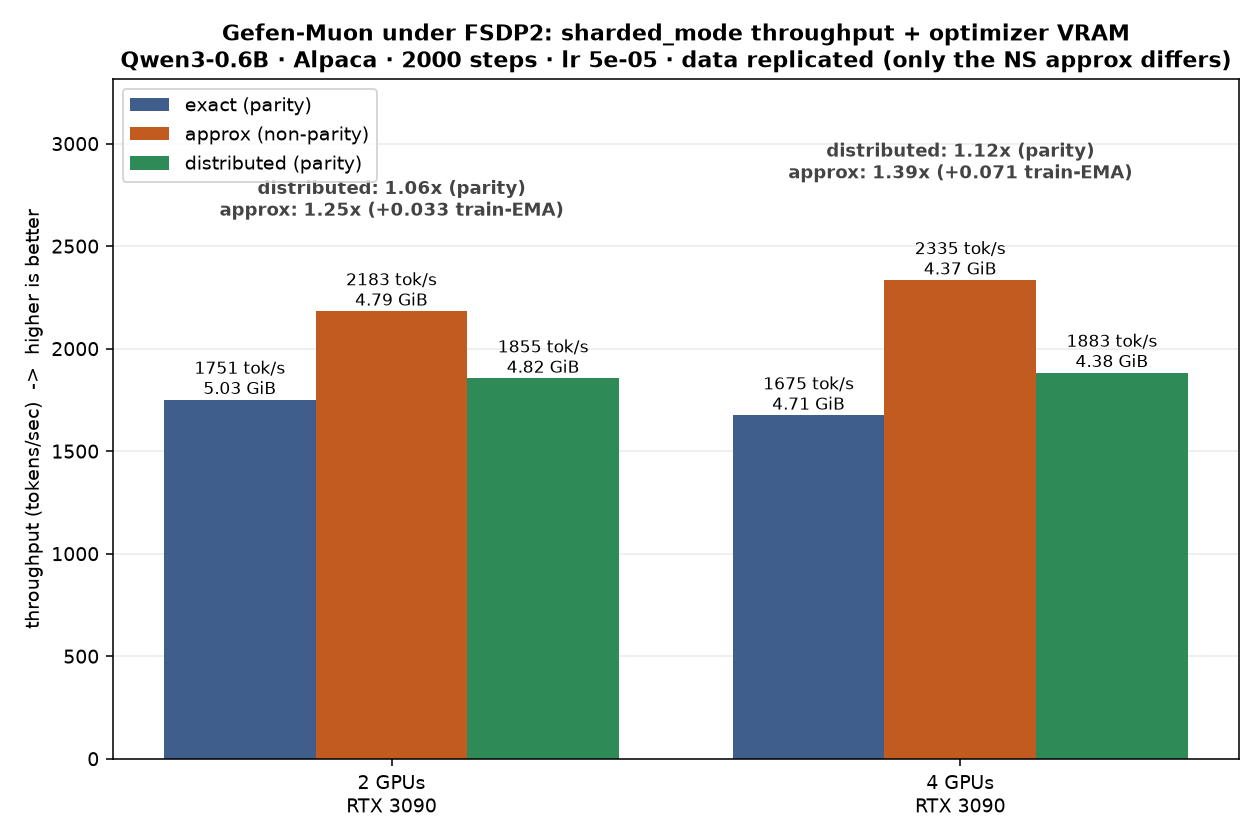
Measured (Qwen3-0.6B, 2 and 4 GPUs): "distributed" matched "exact" in the retained convergence runs while improving throughput by 1.06× / 1.12×; "approx" is faster still (1.25× / 1.39×) but visibly costs training quality, and the cost grows with GPU count. The "distributed" win grows with model size.
Current Gaps and Roadmap:
Param Groups and Integrations
Gefen, GefenMuon, and GefenMuonHybrid preserve the parameter groups you pass to the optimizer, so list-indexed layer-wise LR recipes, per-group LR logging, and state_dict()["param_groups"] see the same group boundaries as conventional torch.optim optimizers. Per-parameter names are stored in optimizer state and mirrored as each group's param_names list for integrations that need name-level routing. Checkpoints from the older one-group-per-parameter layout are migrated on load when the total parameter order still matches and the old per-param hyperparameters can be represented by the new group layout.
Known limitations
- Hybrid checkpoint schema.
GefenMuonHybrid'sstate_dict()uses its own nested{"muon": ..., "backup": ..., "backup_optimizer": "gefen" | "adamw"}layout. Resume from a checkpoint the hybrid itself saved—not one consolidated or converted to the flat torch{state, param_groups}layout. Cross-backend loads are rejected before either child is mutated; legacy untagged hybrid checkpoints are interpreted as Gefen-backed. - FSDP2 optimizer checkpoints don't reshard. Plain Gefen and Muon
approxresume only on the same GPU count and layout; changing either refuses to load. Model weights are unaffected — details. - True-FP16 overflow skips are invisible to Accelerate's
step_was_skippedflag. BF16 and standard AMP are unaffected and are the recommended modes in Trainer/Accelerate.
Troubleshooting
| Symptom | Fix |
|---|---|
| Fused CUDA kernel fails to build on the first step | Gefen auto-falls back to fused=False (pure-PyTorch, slower) with a warning — training continues. Set GEFEN_VERBOSE_BUILD=1 for the full build diagnostic; the usual cause is an nvcc that doesn't match torch.version.cuda. |
| Changed GPU / arch and the kernel misbehaves or won't load | The build cache is keyed on the effective arch list (TORCH_CUDA_ARCH_LIST, or the detected GPU when unset), so a changed arch rebuilds automatically. If you kept an explicit TORCH_CUDA_ARCH_LIST across a GPU change, force a fresh build with GEFEN_FORCE_REBUILD=1. |
| Loss diverges or plateaus high | LR is too hot — use ~0.6× your AdamW LR (Learning rate) or measure it with the find_lr tool. |
| Out of memory | See Hardware Requirements for measured peak VRAM per model size and method. |
| Anything else | Create a New Issue |
Roadmap
| Feature | Status |
|---|---|
| ROCm Support | Planned, pending availability of hardware |
| MLX | Planned, pending availability of hardware |
Credit (Upstream Gefen):
Citation (Gefen Upstream):
If you found this library useful, please consider citing our work:
@article{benedek2026gefen,
  title={Gefen: Optimized Stochastic Optimizer},
  author={Benedek, Nadav and Koren, Tomer and Fried, Ohad},
  journal={arXiv preprint arXiv:2606.13894},
  year={2026}
}
Paper (Gefen Upstream):
Gefen: Optimized Stochastic Optimizer
1 maintainer

Release files for gefen-x 0.4.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| gefen_x-0.4.1.tar.gz | 251.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| gefen_x-0.4.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 482.5 kB
Release files / gefen_x-0.4.1.tar.gz
| Download URL | gefen_x-0.4.1.tar.gz |
|---|---|
| Size | 251.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d1653159fa8a7d28dc06cd46c6ddd4b2d1b91cc4e7dbe7c4d77313a4ad7aaf3a
|
|
BLAKE2b-256 checksum How to use checksums |
df7e6c30da5d9e4cfb459f70ec338c646a61d23398de0362d14a8566dd238e8f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 15, 2026.
Transparency logRelease files / gefen_x-0.4.1-py3-none-any.whl
| Download URL | gefen_x-0.4.1-py3-none-any.whl |
|---|---|
| Size | 230.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
08e8b7c5a0c0e531a8521994b2a2189e7ec1916c31578bdc68efadcf695a38a0
|
|
BLAKE2b-256 checksum How to use checksums |
49b9afe64c4131583156f30493f4c88adb208bdf4d03ef45937fd5ec93df9fd5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 15, 2026.
Transparency log













