
One queryable index of AI security incidents, vulnerabilities, and red-team findings,
normalized onto OWASP LLM/ASI Top 10, NIST AI RMF, and MITRE ATLAS.


🔎 Browse the site · ⚡ Quick start · 📚 Docs · 📝 Cite · 🤝 Contribute
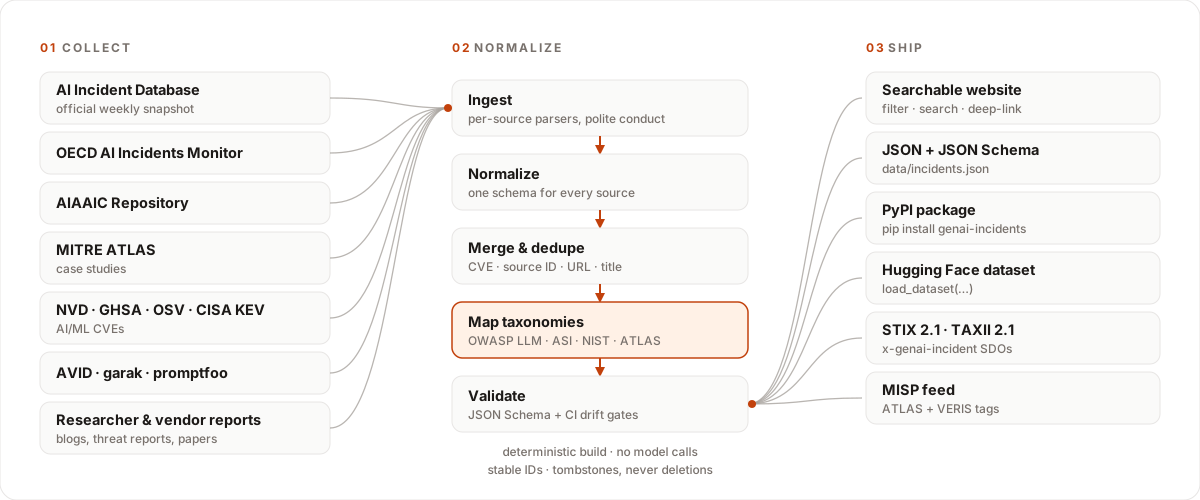
genai_incidents is a consolidated, machine-readable index of publicly disclosed security incidents, vulnerabilities, and red-team findings involving generative-AI and agentic-AI systems. It pulls together AIID, OECD AIM, AIAAIC, MITRE ATLAS, NVD/GHSA/OSV, and researcher and vendor write-ups and maps them onto the same security taxonomies, so you can query and pivot across sources that don't share a schema.
| If you are… | …use it to |
|---|---|
| 🧯 AppSec / threat-intel | triage AI-related CVEs and vendor advisories, and pull the corpus into OpenCTI or MISP |
| 🎯 A red-teamer | scope attack classes against OWASP LLM/ASI and MITRE ATLAS |
| 🔬 A researcher | track incident trends with stable IDs, a DOI, and a published evidence trail |
⚠️ Important — read this before citing a number. genai_incidents is not a complete census of every AI incident. Most taxonomy and severity labels are assigned by deterministic heuristics, not human review. A count like "N incidents tagged LLM01" is a labeling artifact of what the heuristics matched across whichever sources happened to be aggregated — it is not a measured rate of how often that failure mode occurs in the real world. This is the datasheet's own warning, not a paraphrase of it: see Limitations & biases for the full statement and known gaps.
📊 At a glance
| 15,637 incidents |
1,915tier: landmark |
1983–2026 coverage |
6 taxonomies (4 core) |
v2.12.0 built 2026-10-04 |
The landmark tier is the curated, headline-worthy subset (see docs/DATA_DICTIONARY.md's tier field for the exact definition) — cite the landmark count, not the full corpus, when you mean "notable incidents."
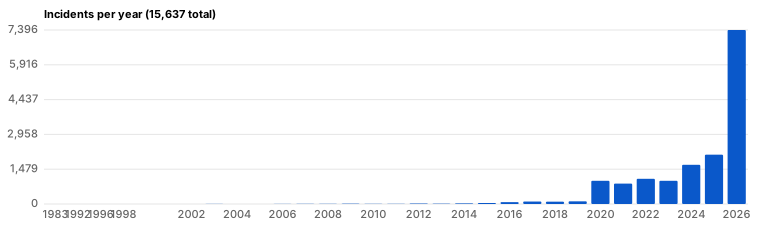
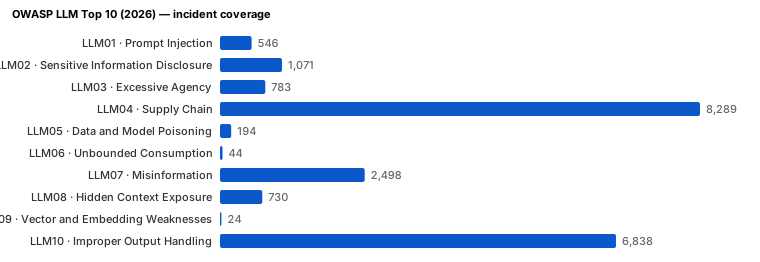
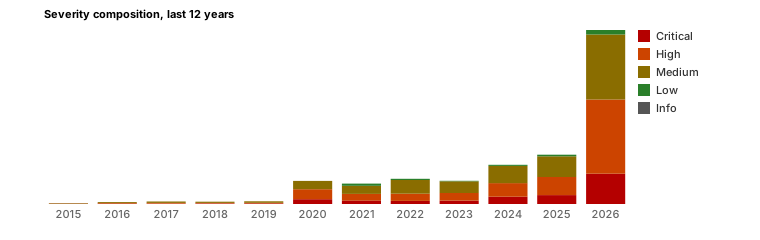
Charts are regenerated on every build. They show what the aggregated sources contain and what the heuristics matched — not real-world rates (see the note above).
👀 Explore it
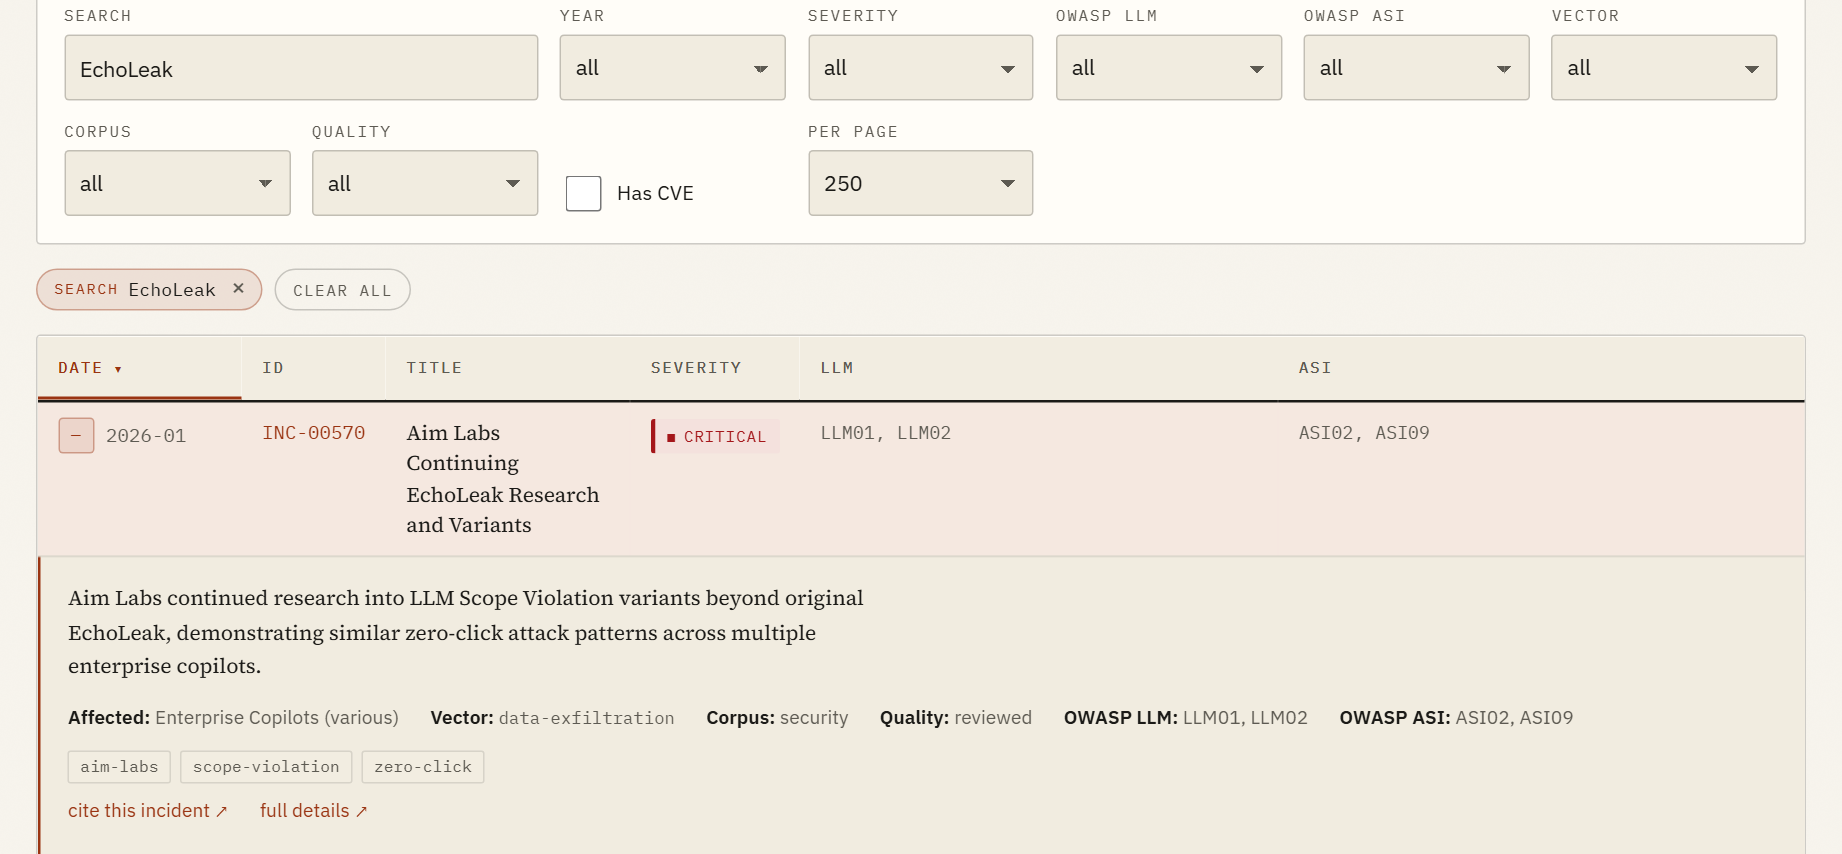
The website: search, filter by year, severity, OWASP code, vector, corpus or quality tier, expand any entry, and deep-link the result. Screenshot taken 2026-09-30.
⚡ Quick start
Python
pip install genai-incidents
from genai_incidents import query, by_cve, resolve_id

for inc in query(severity="Critical", attack_vector="prompt-injection", year=2026):
    print(inc["id"], "-", inc["title"])

print(by_cve("CVE-2026-21520"))   # all incidents that list this CVE
print(resolve_id("INC-00139"))    # follow merge history to the current canonical INC
Hugging Face
from datasets import load_dataset
ds = load_dataset("emmanuelgjr/genai-incidents")
Raw JSON
curl -sL https://raw.githubusercontent.com/emmanuelgjr/genai_incidents/main/data/incidents.json -o incidents.json
Every way to get it
| Channel | Where | Freshness |
|---|---|---|
| 🔎 Website | https://emmanuelgjr.github.io/genai_incidents/ — filterable, searchable, deep-linkable | rebuilt when a push to main touches the corpus or an exporter |
| 📄 Raw JSON | data/incidents.json (full) · data/incidents.min.json (slim) · schema/incident.schema.json |
always current — the authoritative copy |
| 🛰️ STIX 2.1 | https://emmanuelgjr.github.io/genai_incidents/data/incidents.stix.json — x-genai-incident SDOs linked to MITRE ATLAS attack-patterns and CVE vulnerabilitys |
rebuilt when a push to main touches the corpus or an exporter |
| 📡 TAXII 2.1 (static) | https://emmanuelgjr.github.io/genai_incidents/taxii2/discovery.json — a read-only static mirror of the STIX collection (usage + caveats) | rebuilt when a push to main touches the corpus or an exporter |
| 🛡️ MISP feed | https://emmanuelgjr.github.io/genai_incidents/misp/ (Format: MISP Feed) — year-events with genai-incidents:* / mitre-atlas:* / VERIS 1.4.1 veris:* tags |
rebuilt when a push to main touches the corpus or an exporter |
| 📦 PyPI | pip install genai-incidents |
snapshot per release |
| 🤗 Hugging Face | emmanuelgjr/genai-incidents |
snapshot per release |
| 🪪 DOI | 10.5281/zenodo.20248675 (concept DOI — always the latest release; see How to cite) |
per release |
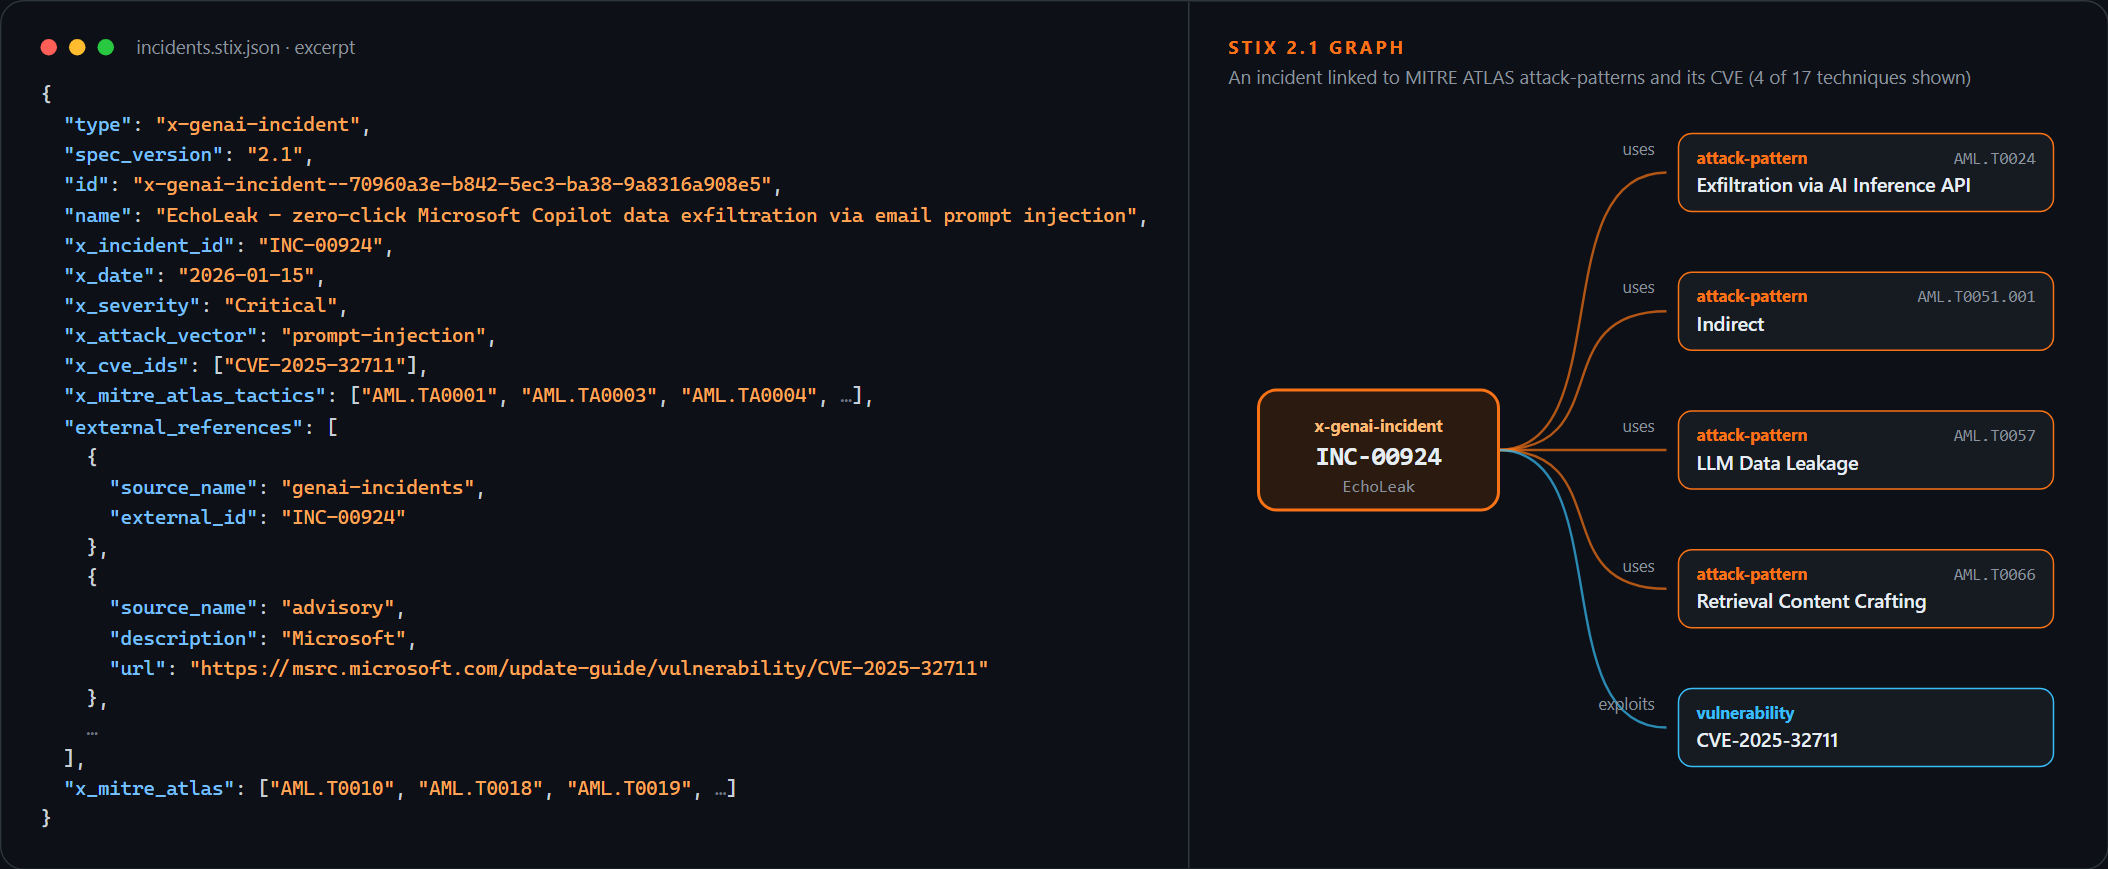
A real excerpt from the published STIX 2.1 bundle (INC-00924, captured 2026-09-30; elided fields shown as …). Each incident is an x-genai-incident SDO linked to MITRE ATLAS attack-patterns and CVE vulnerability objects.
Staleness details per channel — know which build you're getting before you rely on freshness
Every distribution channel ships from the same corpus, but not necessarily the same build of it.
PyPI. The package bundles a snapshot of the slim dataset (incidents.min.json + id_deprecations.json) taken at that release's build time and publishes on a tagged GitHub release (or a maintainer-triggered manual run) — pip install gives you the corpus as of the version you installed, not a live feed. The package's own release version and the dataset's content-vintage are not yet decoupled (that split — data_version distinct from code __version__, with a fetch_latest() to pull current data on demand — is planned but not shipped); today they're the same string. If you need current data, don't assume a pip install a week ago is still current — re-pull, or use one of the other channels.
Hugging Face. Published by make huggingface on each GitHub release (or manually via workflow_dispatch) — refreshed on releases, not continuously. Same vintage characteristics as the PyPI package.
STIX / TAXII / MISP. All rebuilt automatically by the Pages deploy workflow on every push to main that touches the corpus or an exporter script — the closest thing to "live" this project offers, though it is a rebuild-on-push, not a continuous feed. Build any of them locally with make stix / make taxii / make misp.
Raw JSON. data/incidents.json is the authoritative, always-current copy; the site and the STIX/TAXII/MISP exports all build from this file. data/id_deprecations.json resolves citations of merged-away IDs. If you need the current corpus rather than a point-in-time snapshot, pull from data/incidents.json on main (or the site/STIX/TAXII/MISP exports, which build from it), not from PyPI or Hugging Face.
🚨 Latest release
2.12.0 — released 2026-10-04. Three new sources and a retraction mechanism, plus a breaking change to what incident_count means. (1) Wave 1–2 ingest (user-approved): AVID, cvelistV5 (with the huntr CNA slice) and arXiv cs.CR metadata added new entries (mostly vulnerability disclosures, plus a few dozen research papers; counts in the release notes), all quality_tier: auto and tier: feed — machine-selected, not human-reviewed. Most of the CVE entries dated after 2026-06 fill the corpus's own stalled NVD refresh; they are not new-source coverage. EUVD is not ingested (licence outreach pending). (2) 29 entries whose CVEs the CVE Program has REJECTED are now status: retracted (nothing deleted; every INC-* ID still resolves) and 6 more are flagged with rejected_cve_ids. (3) Breaking for some consumers: incident_count now counts only incidents that stand, and the new retracted_count is published beside it — len(incidents) == incident_count + retracted_count, and load_incidents() and the slim JSON include the retracted rows (filter on status). STIX, MISP, TAXII, the Hugging Face export and the site omit them. Also: the STIX/TAXII OWASP LLM source_name is now owasp-llm-top10-2026 (re-import advised), MAL- OpenSSF records are excluded from the OSV path, and ingest redirects are now robots-checked. Known limitations: the OECD/AIID refresh is still frozen, the AIRI Navigator ingest is dead, and a precision audit of the older CVE/GHSA feed is open. See docs/releases/v2.12.0.md for the full disclosure and the re-derivation recipe for every figure. Previous release, v2.11.0 (2026-10-01): a 47-split remediation (board ruling D28) undid a query-string over-merge in normalize_url(), growing the corpus by 301 entries; four IDs were permanently retired (INC-00311, INC-00554, INC-00754, INC-01897) and a fifth, INC-07738, stops resolving to itself via an ordinary merge. Every retired ID still resolves through data/id_deprecations.json (nine pre-tombstone IDs are a known exception, docs/ID_POLICY.md §1.4(a)). Twelve IDs change their resolve_id() answer — if you cached old mappings, re-resolve them — and load_deprecations() values are now str | list[str], so upgrade the package and data together. See docs/releases/v2.11.0.md. Previous release, v2.10.0 (2026-09-18): A silent breaking change for anyone matching on owasp_llm code strings: every code was migrated from the OWASP Top 10 for LLM Applications 2025 edition to the 2026 edition. The code space is identical before and after, so LLM03 is still valid and now means Excessive Agency instead of Supply Chain — nothing errors, nothing fails validation. Concretely: a filter on LLM03 matched roughly eight times as many rows at v2.9.0 as it matches today — the release notes give both exact counts and the command to re-derive them. Data at or before v2.9.0, including its Zenodo deposits, carries 2025 codes; the crosswalk is mappings/owasp_llm_2025_to_2026.json. Also fixed eight weeks of silently-dead weekly refreshes, an 800 KB page truncation that dropped ~38 incidents per run, and the OECD crawl budget. Exactly one corpus row changed, at the time of that cut — INC-11516's description had the query string of an expired pre-signed URL removed. The v2.10.0 release notes are at docs/releases/v2.10.0.md; CHANGELOG.md carries both entries.
✨ How it differs from AIID / MIT AI Risk Repository / AVID
AIID, the MIT AI Risk Repository, and AVID are themselves primary or aggregated incident trackers, and this dataset draws on several of them as upstream sources (see docs/SOURCE_LICENSES.md) rather than replacing them. What this project adds is normalization onto security-oriented taxonomies (OWASP LLM/ASI, NIST AI RMF, MITRE ATLAS) across sources that don't share a common schema. A full side-by-side positioning comparison is planned but not yet written.
Beyond the obvious title/description/severity fields, a few worth knowing about before you build on this data:
- 🔗 Tombstones, never deletions — merged or withdrawn IDs are never dropped; they redirect (or terminate) via
data/id_deprecations.json, so a citation of any ID that carries a tombstone resolves to something, never to silence (9 pre-tombstone IDs are a known exception, andresolve_id()returnsNonefor 8 IDs whose redirect chain ends in more than one live successor, for three different reasons — see the v2.11.0 release notes). Seedocs/ID_POLICY.mdfor the ID-stability commitment. - 🏷️
content_license— a row-level marker on entries whose upstream source imposes its own attribution/share-alike obligation on that specific row, carried through the full JSON, the Hugging Face export, and the STIX bundle (asx_content_license). Its absence means no known obligation, not a guarantee the row is unencumbered. - 🕰️
source_status/source_freshness— whether a row is still emitted by a build and whether the upstream source that fed it is still refreshing are tracked as two separate, independent facts. A committed ingest snapshot keeps re-emitting its rows every build even after the source that produced them goes dark, so a row being present is never itself a freshness claim —source_freshnessis the field that actually says so, and it's published atdata/source_freshness.json. - ✅
quality_tier/confidence— vetting level (curated/reviewed/auto) and a rule-derived confidence tier, so you can filter to only human/assisted-reviewed entries instead of the full heuristic-labeled corpus. - 🧾 A public evidence trail —
docs/audits/is unusual for a dataset repo, and deliberately so: rather than folding a licensing ruling or a data-migration rationale into a doc that then has to be kept perpetually current, each is a dated, standalone record of what was true and why a decision was made — worth a look if you want the reasoning behind a change, not just its result.
Full field reference: docs/DATA_DICTIONARY.md.
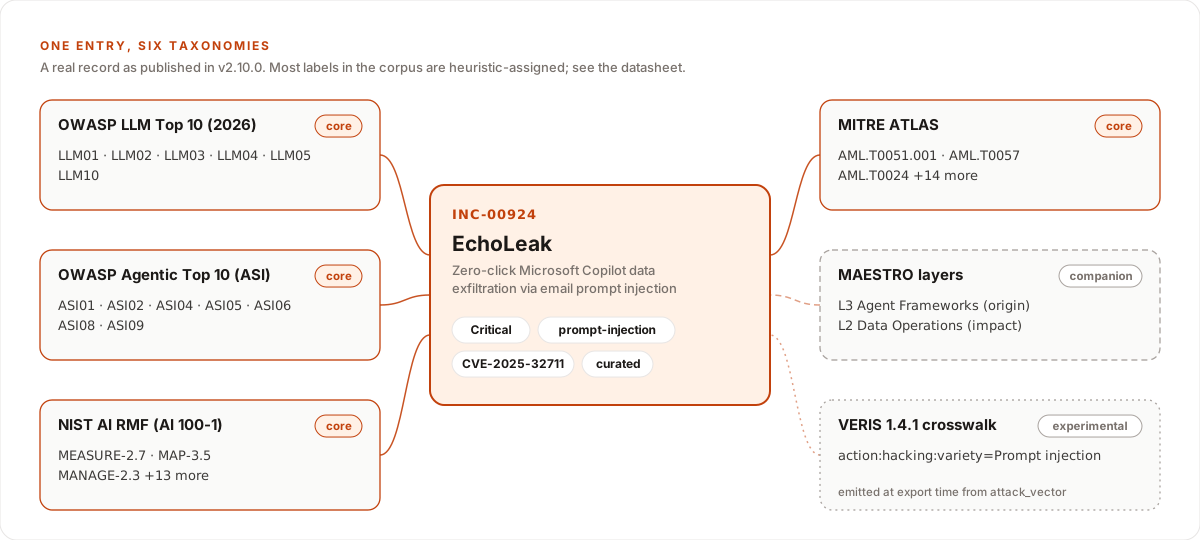
🧭 Taxonomies mapped
| Taxonomy | Codes | Status |
|---|---|---|
| OWASP Top 10 for LLM Applications (2026) | LLM01–LLM10 |
core |
| OWASP Agentic Top 10 (ASI) | ASI01–ASI10 |
core |
| NIST AI Risk Management Framework (AI 100-1) | GOVERN / MAP / MEASURE / MANAGE subcategories |
core |
| MITRE ATLAS | tactics (AML.TA00xx) and techniques (AML.T00xx) |
core |
| MAESTRO architectural layers | L1–L7 |
companion — carried on entries whose upstream source already provides a MAESTRO mapping; not populated on every entry |
| VERIS 1.4.1 crosswalk | veris:* tags in the MISP export |
experimental — a hand-curated crosswalk from attack_vector, emitted at export time only, not a stored per-incident schema field |
See docs/TAXONOMIES.md for a chooser table and the full code lists.
🎯 What counts as an incident?
Every entry must satisfy three gates, defined precisely in INCLUSION.md — the authoritative scope contract this project's own ingesters and reviewers decide against, not a keyword list. In gist (not a substitute for the real thing):
- a real AI-nexus — the AI/ML system is the target, the vector, or a material enabler of harm, not an incidental mention;
- security or safety relevance — a vulnerability, exploit, attack, misuse, or real-world harm, not a feature or benchmark;
- at least one citable primary source.
Broad fairness/bias-only harms with no security primitive are out of scope; see INCLUSION.md for the full definition and worked examples.
🌐 Sources aggregated
Each entry retains links back to the originating advisory, post, or paper. Headline sources: AIID, OECD AIM, AIAAIC, MITRE ATLAS, AVID, NVD / GHSA / OSV / CISA KEV, garak, promptfoo, plus dozens of researcher blogs, vendor threat reports, and academic papers.
Full source list, with per-source handling
- OWASP GenAI Security Project — incident roundups + Top 10 references
- AI Incident Database (AIID) (incidentdatabase.ai, github.com/responsible-ai-collaborative/aiid) — ingested via AIID's official weekly snapshot archive (not per-page scraping); title + structured facts only, no verbatim narrative retained
- OECD AI Incidents Monitor (AIM) (oecd.ai/en/incidents) — cross-listed against AIID via the official AIID-OECD bridge file;
title/summaryare LLM-generated (OpenAI o3-mini) from third-party news of unresolved copyright status, sodescriptionis reduced to structural facts + link and carries a per-entry OECD attribution (decision E21);titleitself remains an open question — seeNOTICE-DATAanddocs/SOURCE_LICENSES.md§1.5 - AIAAIC (aiaaic.org) — AI, Algorithmic, and Automation Incidents and Controversies; a CC BY-SA 4.0 source reduced to title/headline + categorical facts + link (decision D2), with row-level attribution/share-alike honored via a per-entry marker and an open database-right question — see
NOTICE-DATAanddocs/SOURCE_LICENSES.md§1.1 - MITRE ATLAS (atlas.mitre.org, github.com/mitre-atlas/atlas-data) — all case studies parsed from the YAML corpus
- AVID — AI Vulnerability Database (avidml.org)
- CSET-AIID Harm Taxonomy (github.com/georgetown-cset/CSET-AIID-harm-taxonomy) — controlled vocabulary reference
- NVD / CVE.org / GitHub Security Advisories / OSV.dev / CISA KEV — AI/ML/LLM/agent CVEs pulled via REST API across a broad, actively-maintained keyword list
- NVIDIA garak (github.com/NVIDIA/garak) — one entry per LLM vulnerability scanner probe (canonical attack classes)
- promptfoo (github.com/promptfoo/promptfoo) — one entry per red-team plugin/strategy
- ModelOriented/CVE-AI (github.com/ModelOriented/CVE-AI) — XAI-based AI model validation findings
- Researcher and vendor blogs — Embrace The Red, Tenable, Palo Alto Unit 42, Trail of Bits, Aim Security, Noma Security, Wiz Research, Lakera, Invariant Labs, PromptArmor, Pillar Security, Token Security, HiddenLayer, Robust Intelligence, Protect AI, Cato Networks CTRL, Endor Labs, Sysdig, Zenity Labs, JFrog, Datadog Security Labs, Reco, AppOmni, BeyondTrust, Oasis Security, Mindgard, Koi Security, Imperva, Sonar, Oligo Security, OX Security, SentinelOne, Check Point Research, Trend Micro, Tinfoil Security, ZeroPath, Cymulate, MaccariTA, and others.
- Vendor threat reports — Anthropic, OpenAI, Google Threat Intelligence (GTIG/TAG/Mandiant), Microsoft Threat Intelligence (MTAC/MSRC), AWS Security Bulletins, CrowdStrike, Recorded Future.
- Academic papers — selected USENIX Security / NDSS / S&P / CCS / arXiv entries with concrete adversarial PoCs.
If a source is missing or mis-attributed, open an issue or PR. One tracked source is currently stale (MIT AIRI Navigator's public bulk download was withdrawn; the corpus keeps re-emitting its last-fetched snapshot, unshrunk, under a dated hold) — see data/source_freshness.json for the reviewed, published status of every source this project actively monitors.
🧱 Reference
Schema (summary)
See schema/incident.schema.json for the canonical version, and docs/DATA_DICTIONARY.md for the complete field-by-field reference (identity/provenance, quality/freshness, licensing, and evidence fields are not shown below to keep this summary short).
{
  "id": "INC-00001",                 // stable, never-reused ID — see docs/ID_POLICY.md for the padding-width policy
  "source_ids": ["AIID-123", "CVE-2025-..."],
  "cve_ids": ["CVE-2025-..."],
  "cwe_ids": ["CWE-918"],
  "cvss_score": 9.8,
  "cvss_vector": "CVSS:3.1/AV:N/AC:L/PR:N/UI:N/S:U/C:H/I:H/A:H",
  "aiid_id": 1234,                   // canonical AIID numeric ID when applicable
  "title": "...",
  "date": "2025-09",
  "disclosure_date": "2025-10-02",   // separate from incident date when known
  "year": 2025,
  "category": "real-world | research | red-team | vulnerability-disclosure | threat-report | policy",
  "description": "...",
  "attack_vector": "prompt-injection | rce | supply-chain | data-exfiltration | ...",
  "affected": "vendor/product",
  "impact": "...",
  "severity": "Critical | High | Medium | Low | Info",
  "owasp_llm": ["LLM01", "LLM06"],
  "owasp_asi": ["ASI01", "ASI02"],
  "nist_ai_rmf": ["MEASURE-2.7", "MAP-3.5"],
  "mitre_atlas": ["AML.T0051", "AML.T0051.001"],
  "mitre_atlas_tactics": ["AML.TA0004"],
  "maestro_layers": [{"layer":"L3","label":"Agent Frameworks & Tooling","role":"origin"}],
  "mitigations": ["..."],
  "references": [
    {"title":"Vendor advisory","url":"https://...","type":"vendor"}
  ],
  "tags": ["mcp","supply-chain"],
  "added": "2026-05-16",             // stable across re-runs
  "updated": "2026-05-16",           // only bumped when content actually changes
  "quality_tier": "curated | reviewed | auto",   // vetting level — see docs/DATA_DICTIONARY.md
  "content_license": null            // present only when this row owes an upstream attribution/share-alike obligation
}
Repository layout
.
├── data/
│   ├── incidents.json          ← the full, authoritative dataset (use this)
│   ├── incidents.min.json      ← slim variant: id, title, taxonomy mappings, primary reference
│   ├── stats.json              ← the single source of every published count (invariant 6)
│   ├── id_deprecations.json    ← merged/withdrawn ID redirects and tombstones
│   ├── source_freshness.json   ← reviewed registry of which sources have stopped refreshing
│   └── legacy_consolidated.json ← intermediate output from the legacy parser
├── schema/
│   └── incident.schema.json    ← JSON Schema for one incident
├── mappings/
│   ├── owasp_llm_top10_2026.json
│   ├── owasp_llm_top10_2025.json
│   ├── owasp_llm_2025_to_2026.json ← crosswalk for the v2.10.0 code migration
│   ├── owasp_asi_top10.json
│   ├── nist_ai_rmf.json
│   ├── mitre_atlas.json
│   ├── cwe_capec.json
│   ├── cwe_attack_vector.json
│   ├── veris.json
│   └── maestro_layers.json
├── legacy/                     ← original source files (preserved verbatim)
├── ingest/                     ← per-source aggregator outputs (CVE, AIID, ATLAS, etc.)
├── scripts/
│   ├── parse_existing.py             ← parse legacy/ → data/legacy_consolidated.json
│   ├── ingest_external.py            ← parse cloned source repos under ../_external/ → ingest/*.json
│   ├── ingest_aiid_snapshot.py       ← AIID official weekly snapshot (sanctioned bulk channel) → ingest/aiid_full.json
│   ├── scrape_aiid.py                ← RETIRED per-page scrape (kept only as a reused parsing-logic library; disabled in Makefile)
│   ├── ingest_airi_navigator.py      ← MIT FutureTech AI Risk Navigator CSV → ingest/airi_navigator_incidents.json
│   ├── ingest_aiaaic_sheet.py        ← AIAAIC Repository public Google Sheet → ingest/aiaaic_sheet_incidents.json
│   ├── ingest_oecd_aim.py            ← OECD AI Incidents Monitor (large page crawl) → ingest/oecd_aim_full_incidents.json
│   ├── ingest_cve_nvd_expanded.py    ← pull AI-relevant CVEs from NVD/GHSA/OSV → ingest/cve_nvd_expanded.json
│   ├── ingest_cisa_kev.py            ← CISA Known Exploited Vulnerabilities catalog (enrichment only)
│   ├── merge_and_dedupe.py           ← merge legacy + ingest/* → data/incidents.json
│   ├── render_markdown.py            ← data/incidents.json → INCIDENTS.md + data/stats.json + docs/charts/*.svg
│   ├── render_docs_stats.py          ← templates data/stats.json's counts into README/DATASHEET/site/CITATION.cff (invariant 6)
│   ├── check_stats_drift.py          ← CI gate: fails on any doc surface out of sync with data/stats.json, or a hardcoded total
│   ├── export_stix.py / export_taxii.py / export_misp.py / export_huggingface.py  ← format exporters
│   └── validate.py                   ← validate JSON against schema
├── INCIDENTS.md                ← rendered index: unified table, newest-first
├── docs/incidents/<year>.md    ← per-year detail shards linked from INCIDENTS.md
├── docs/audits/                ← dated project decision records (licensing, data, conduct)
├── tests/                      ← pytest suite for merge/render/export/ingest-conduct helpers
├── LICENSE                     ← MIT (covers code in scripts/, schema/, src/)
├── LICENSE-DATA                ← CC-BY-4.0 (covers the dataset under data/) — see Licensing below for exceptions
└── README.md
Regenerating the dataset
pip install -r requirements.txt
make build      # parse legacy, merge + dedupe, render, template doc stats (invariant 6), validate
make test       # pytest tests/
make ingest-all # (heavy: refresh AIID/AIRI/AIAAIC/OECD AIM/NVD from network)
Or run the steps individually:
python scripts/parse_existing.py     # legacy/ -> data/legacy_consolidated.json
python scripts/merge_and_dedupe.py   # legacy + ingest/* -> data/incidents.json
python scripts/render_markdown.py    # data/incidents.json -> INCIDENTS.md + docs/incidents/<year>.md + data/stats.json
python scripts/render_docs_stats.py  # data/stats.json -> templated counts in README/DATASHEET/site/CITATION.cff
python scripts/check_stats_drift.py  # CI gate: fails on drift or an unmarked hardcoded total
python scripts/validate.py           # schema check
Dedupe keys (first hit wins): (a) matching cve_ids, (b) matching source_ids (with AIID-N-OECD canonicalised to AIID-N), (c) matching normalized reference URL, (d) fuzzy title match within ±1 year — (c) and (d) are weak keys and refuse to fire across two entries with disjoint CVE sets. After each merge the indices are reindexed so transitive dupes (entry A absorbs CVE-3, then entry B with CVE-3 already exists → B is merged into A as well) all collapse. Merges union taxonomy mappings, references, tags, CVE/CWE IDs, and source IDs; take the highest severity; prefer the more-specific date (YYYY-MM-DD beats year-only) and reject future-year dates.
added and updated are preserved from the previous output; updated only bumps when an entry's content actually changes. That keeps make build deterministic for CI drift checks.
Adding entries
Two paths:
- Manual: append a properly-shaped object to
data/incidents.jsonand runscripts/render_markdown.py. Ensurereferenceshas at least one resolvable URL. - Automated: drop a JSON array of raw entries into
ingest/<your_source>.json(any reasonable shape — seescripts/merge_and_dedupe.pynormalize_entryfor the field tolerance), then re-run merge + render.
Always run scripts/validate.py before committing.
Taxonomy mapping sources
The mapping files in mappings/ document the controlled vocabulary used in this dataset. They are derived from the original sources:
- OWASP LLM Top 10 (2026): https://genai.owasp.org/resource/owasp-genai-llm-top-10-2026/
- OWASP Agentic Top 10 (ASI / "Agentic AI – Threats and Mitigations"): https://genai.owasp.org/resource/agentic-ai-threats-and-mitigations/
- NIST AI Risk Management Framework (AI 100-1): https://www.nist.gov/itl/ai-risk-management-framework
- NIST AI 600-1 Generative AI Profile: https://nvlpubs.nist.gov/nistpubs/ai/NIST.AI.600-1.pdf
- MITRE ATLAS: https://atlas.mitre.org/
- MAESTRO (companion): https://genai.owasp.org/resource/genai-security-project-maestro/
When a framework releases a new version, update the mapping JSON in mappings/ and re-run merge + validate.
📚 Documentation & policies
| Provenance, composition, limitations (Datasheets for Datasets) | docs/DATASHEET.md |
| Per-source license/ToS audit — every upstream, its terms, this project's remediation | docs/SOURCE_LICENSES.md |
| How the CC-BY-4.0 data grant applies, and where it doesn't | NOTICE-DATA |
| Incident ID stability policy (tombstones, redirects always honored; ID-width decision still pending) | docs/ID_POLICY.md |
| Ingestion conduct — rate limits, robots.txt, identification | docs/INGESTION_CONDUCT.md |
| Field reference | docs/DATA_DICTIONARY.md |
| Taxonomy detail and chooser table | docs/TAXONOMIES.md |
| Scope contract — what's in/out, and why | INCLUSION.md |
| Methodology paper | docs/paper/genai-incidents-methods.md |
| Public evidence trail — dated audits, delta reports, and rulings behind licensing/data/conduct decisions | docs/audits/ |
| Corrections & scope disputes — open a data correction or scope dispute; accepted changes logged in | CORRECTIONS.md |
| Changelog | CHANGELOG.md |
🤝 Contributing
PRs welcome — corrections, missing incidents, and new sources especially. Please:
- Add at least one verifiable URL per entry.
- Map to the four core taxonomies where applicable (MAESTRO and VERIS are not contributor-set — see CONTRIBUTING.md). If unsure, leave the field empty rather than guess.
- Run
scripts/validate.pyandscripts/render_markdown.pybefore opening a PR. - For incidents you authored or first reported, that's totally fine — but please link the canonical writeup.
Found something wrong in an existing entry? Open a data correction or a scope dispute.
⚖️ Licensing
MIT for code (scripts/, schema/, src/genai_incidents/) — LICENSE. CC-BY-4.0 for the dataset and documentation (data/, INCIDENTS.md, mappings/, docs/) — LICENSE-DATA. Neither of those is the whole story:
- Two verbatim text bodies are Apache-2.0, not CC-BY-4.0, and are not relicensed by it: MITRE ATLAS case-study text and NVIDIA garak probe docstrings, each reproduced under its own upstream license with its own attribution requirement that stays attached to that material specifically.
- AIAAIC-derived rows (a CC BY-SA 4.0, share-alike source) carry a row-level
content_licensemarker — machine-readable, naming AIAAIC as the attribution/share-alike target on the specific rows it applies to, mirrored into the STIX export asx_content_license. This is a per-row obligation honored proactively, not a dataset-wide CC-BY-SA carve-out. - The OECD AI Incidents and Hazards Monitor (AIM) is a third upstream source carrying an active content obligation. Its
descriptionfield on AIM-sourced rows is reduced to structural facts and a source link rather than AIM's own LLM-generated summary text, and every AIM-sourced row carries a per-entry OECD attribution citation. Thetitlefield on those same rows is not covered by that reduction and remains a separate, open question. - AIID, despite also being a CC BY-SA source, is a resolved question, not an open one for the population this project ships — the legal analysis concludes no row-level marker is owed there. The two sources reach different outcomes under the same kind of license grant for reasons specific to each maker's legal situs, not because one was treated more carefully than the other.
None of the above is exhaustive, and stating exact per-source row counts here would only drift out of sync with the audit that actually tracks them. NOTICE-DATA and docs/SOURCE_LICENSES.md are the authoritative, currently-maintained accounts of every source's terms, this project's remediation for each, and the current per-source figures — read those, not this summary, before making a decision that depends on the details.
How to cite
- Citing the dataset as a whole (statistics, trend analysis, benchmark construction, or other aggregate use): cite this repository using the preferred citation in
CITATION.cff, or the DOI badge above. - Citing an individual incident: cite that incident's own primary source, not this repository. Every incident entry links to its underlying source(s) in its References section — use that link (or, for AIID-derived entries, the AIID citation URL already shown on the entry) as the citation. Citing genai_incidents alone for a single incident credits this aggregator instead of the reporter, researcher, or outlet who actually surfaced it.
- Concept DOI vs. version DOI: the DOI badge and
CITATION.cff(10.5281/zenodo.20248675) are Zenodo's concept DOI — it always resolves to the latest release, and is the one to cite for general or ongoing use. Cite a release's own version-specific DOI only when deliberately pinning to that exact version (e.g. reproducing a result against a specific snapshot); see that release's own Zenodo record for its version DOI.
1 maintainer

Metadata
1 maintainer
Release files for genai-incidents 2.12.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| genai_incidents-2.12.0.tar.gz | 4.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| genai_incidents-2.12.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 6.1 MB
Release files / genai_incidents-2.12.0.tar.gz
| Download URL | genai_incidents-2.12.0.tar.gz |
|---|---|
| Size | 4.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
10a5478d23fc3beca208e4608576c7b3d183f0be3aee6025f4c85beeff97257a
|
|
BLAKE2b-256 checksum How to use checksums |
92bbbd8cc3462e5689a2e83bf85fb2c29f5fa4bb922339cd145a18809528b269
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logRelease files / genai_incidents-2.12.0-py3-none-any.whl
| Download URL | genai_incidents-2.12.0-py3-none-any.whl |
|---|---|
| Size | 2.1 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6fe047bab3f467bb0efbab8bda406488b1ca4736928a176c8c3c23661d989e90
|
|
BLAKE2b-256 checksum How to use checksums |
af586b89342b2a7130e0bbe9032eecda1472a9f4303903e64ea709d4d6da2e7a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency log













