
This release is a pre-release and may not be stable for production use.
GFFX
GFFX is a portable, general-purpose graphics, geometry, and mesh toolkit for Python 3.10+, differentiable wherever differentiation exists and capable regardless of whether it does. Its design centers on stable tensor-level semantics across autodiff frameworks, a dependency-light C11 CPU core, isolated accelerator providers, compilation and export, and allocation-controlled integration into streaming and edge applications.
The project is pre-release. M1 is complete for the adopted development-readiness
scope: finite generic graphics supply, recorded CPU/CUDA profiles, and the B1
public CPU fitting integration. The experimental 0.2.0a1 Windows CPU package has a separately defined
artifact/runtime scope; M1 does not confer universal release support. See M1 closeout and
development wheels for the artifact boundaries.
The core geometry inventory below is one part of the current camera, scene, animation, shading and image supply. Experimental filtered-renderer qualification remains a separate, unqualified workstream; its reference campaign is paused.
What works today
The development checkout also includes the minimal scene API: typed objects, transform hierarchies, frame-major mesh packing, attribute/material bindings and differentiable transforms. This is an eager PyTorch composition over the existing operations, not a scene editor, file importer or new native renderer.
Thirteen native geometry operations, each with a written acceptance contract and fixtures:
| Group | Operations |
|---|---|
| mesh | face_geometry, vertex_normals, gather_faces, build_edge_topology, sample_surface |
| transforms | transform_points, perspective_divide |
| points | knn, closest_point_on_mesh |
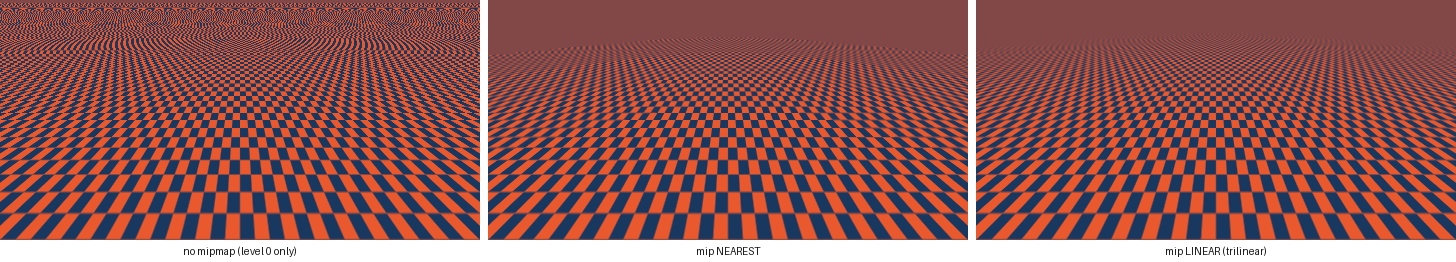
| render | rasterize, interpolate, texture_pyramid, texture |
Gradients for twelve of the thirteen. mesh.build_edge_topology publishes none, because every
one of its outputs is integer topology and there is nothing to differentiate. Differentiability is
a per-operation property rather than a condition of membership: an operation declares its gradient
support by publishing a _backward entry point or by not publishing one, so the absence is visible
when you bind rather than when you first ask for a gradient.
A CUDA provider covering twelve of the thirteen forwards and all twelve backwards, loaded as an
isolated optional plugin. mesh.build_edge_topology has no CUDA forward.
Bitwise CPU/CUDA agreement, not merely closeness, for every operation that can promise it. The
device build passes -fmad=false and each kernel mirrors the host operation for operation rather
than reassociating for speed, so results are compared with memcmp rather than a tolerance. Where
a gradient scatters onto shared geometry the default path reproduces the host's accumulation order
exactly; a faster atomic path exists but is reached only when the caller sets
GFFX_EXECUTION_ALLOW_NONDETERMINISTIC, and it makes no bit-identity claim.
A framework-neutral C11 ABI, usable without Python or any autodiff framework. The figures in
this README were produced by calling it from Python with ctypes and nothing else — see
docs/showcase/.
The working camera implementation is documented in Eager pinhole cameras:
gffx.camera.Camera projects points, reconstructs positions from depth, and batches cameras
using the existing transforms. Its optional in_front_only=True filter keeps behind-camera
rejection separate from mathematical projection validity and visibility. It adds no native
primitive and makes no compilation/export or real-time performance claim.
PyTorch also exposes compositional classic and principled/custom materials, tagged light integration, and explicit tensor colour sources. These are not additional native primitives. Principled shading has separately named, finite-profile float64 budget bundles for CPU and CUDA; the table is shipped package data, not a download. Input/layout, energy and gradient tests do not imply Cycles fidelity, compiled/exported shading, or real-time performance. See the shading implementation and evidence map for what is locally tested and what remains outside this slice.
What does not work yet
- The PyTorch adapter requires PyTorch 2.10 or newer. On an older PyTorch it refuses to load and the Python operation surface is inert. The C ABI remains available.
pip install gffxdoes not install this. Public PyPI releases through0.1.4belong to an inherited prototype with unrelated APIs. This is0.2.0.dev0, available only from a repository checkout or an explicitly supplied artifact.- No published CUDA artifact. The provider is built from source and needs the CUDA toolkit.
- CUDA agreement is measured on one machine, not in continuous integration. No hosted runner has a GPU, so every device claim above comes from manual runs on a single RTX 5090. The hardware lane exists to close this and needs a registered self-hosted runner before it does.
- No JAX adapter, and no public
torch.compile, export, serialization, or streaming operation surface. - No spatial acceleration structure.
points.knnandpoints.closest_point_on_meshare brute force, and the rasterizer costs roughly 2.4 seconds per 1000x1000 frame on CUDA. Correct and reproducible; not real-time. - Shading is still a bounded development implementation. Lobes, built-in lights and classic/principled material compositions are available in the development checkout. The exact bundled principled loss table has separate CPU/CUDA float64 profiles with a 32-entry standalone query limit. Material calls separately support 1024 point/light pairs (8 forward or 4 backward points), under a 64 MiB planning ceiling. Fixed image/reference fixtures do not qualify arbitrary scenes, sustained performance or compilation/export. See material usage and limits. Tangent frames, bump mapping and colour management remain later work.
- No ray tracing or BVH traversal, remeshing, mesh booleans, volumetric rendering, non-triangle
faces, or image decoding.
render.texturesamples a tensor the caller already holds; it opens no file. - Support claims are per combination and measured, not inherited. See measured evidence versus support targets before depending on a platform, Python version, or accelerator.
What it looks like
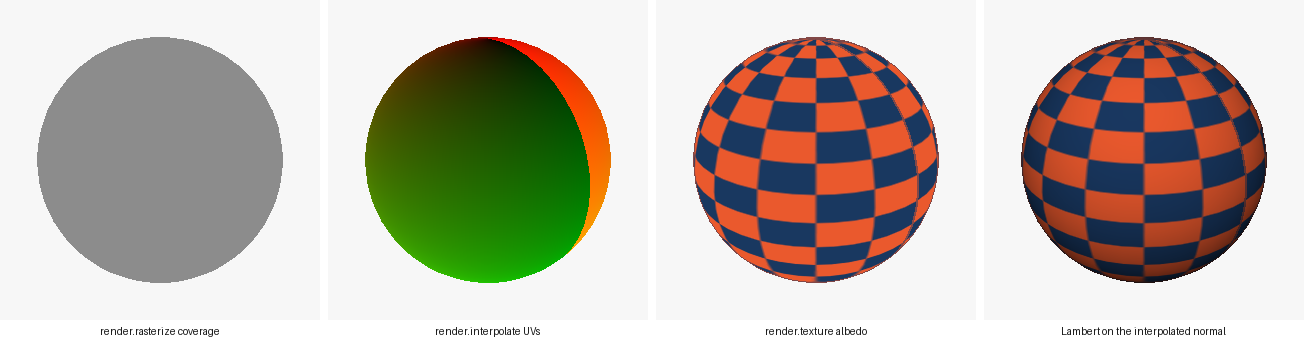
The render chain stage by stage, on a procedurally generated sphere. Every pixel comes from a GFFX operation:
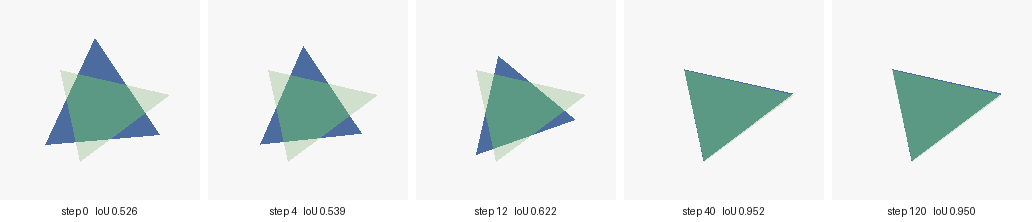
And the property that makes it a differentiable renderer rather than a renderer — gradient descent on vertex positions, driven entirely by the library's own backward passes, until a triangle matches its target:
More figures, with what each one demonstrates, in docs/showcase/.
Install and inspect
The 0.2.0a1 alpha is a Windows x64 CPU wheel with an included optional
PyTorch adapter. Follow the installation guide and
exact alpha profile. Select PyTorch separately when using
autodiff; the base package has no mandatory third-party Python dependencies.
python -m pip install --only-binary=gffx "gffx==0.2.0a1"
This command applies once that version is available on PyPI. The alpha ships no gffx CUDA provider. CUDA-enabled PyTorch can still be used for CPU operations in the explicitly tested combinations; GPU execution has its own development profile. Broader source capabilities described below retain their own evidence.
The stable entry point is always:
import gffx

print(gffx.__version__)
print(gffx.capabilities())       # static; never probes a GPU

# Explicit diagnostic only; may load the optional provider and GPU driver.
print(gffx.cuda.capabilities())
Do not call the full CUDA capability probe from a real-time frame or audio callback.
Documentation
- Installation and optional components
- Source and native builds
- Dependency and vendoring policy
- Measured evidence versus support targets
- Isolated CUDA provider recipes
- The CUDA hardware test lane
- Capability figures and how they are generated
- Testing-dashboard learning pages and dependency-free mathematics
Source boundaries
include/gffx/: public framework-neutral C11 ABI.native/core/: dependency-light runtime and the independent CPU operations.native/cuda/: private optional CUDA provider; no semantics belong here exclusively.adapters/: CPython and autodiff-framework loading/registration glue.src/gffx/: stable dependency-light Python namespace.tests/: ABI, packaging, import, framework-loading, accelerator-isolation, and operation acceptance contracts.docs/showcase/: the figure generators and the figures above.
The pre-foundation source remains recoverable in Git history and on
codex/archive-pre-phase1-20260821. Prototype behavior is unsupported and receives no
compatibility credit toward the new operation contracts.
GFFX is licensed under the MIT License. No third-party source is vendored, and every figure here is generated from GFFX's own primitives with procedurally constructed inputs, so no external asset or dataset is redistributed.
1 maintainer

Metadata
1 maintainer
Release files for gffx 0.2.0a1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| gffx-0.2.0a1-cp310-abi3-win_amd64.whl | CPython 3.10 | abi3 | Windows x86-64 | Details |
Release files / gffx-0.2.0a1-cp310-abi3-win_amd64.whl
| Download URL | gffx-0.2.0a1-cp310-abi3-win_amd64.whl |
|---|---|
| Size | 2.0 MB |
| Tags | CPython 3.10 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
d132d7d2c852feb61eeddfd0eb99082ab7f9ae52f5913220e064d227e0267042
|
|
BLAKE2b-256 checksum How to use checksums |
8d76bdad750719aabc4be072f17a34d07fc3085dc33e43087fb5ba8838ee7960
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency log













