
ggufkit


Fingerprint, verify and visualize GGUF models.
ggufkit answers questions a plain file hash cannot:
- Is this GGUF the same model as that one, even though the bytes differ?
- Did a re-upload change the weights, or only the metadata? Which keys, which tensors?
- Does this file document where it came from well enough to reproduce it?
- How far is this quantization from its source, tensor by tensor, and where inside each tensor?
- Which quantization type did each tensor get?
- What does
blk.17.attn_q.weightactually look like?
It is built on llama.cpp's own gguf Python package, so
every tensor type that package can decode works here too: 31 of them, from F32 and Q4_0
to IQ2_XXS, MXFP4 and NVFP4. Sharded models (-00001-of-00003.gguf) are handled as one model.
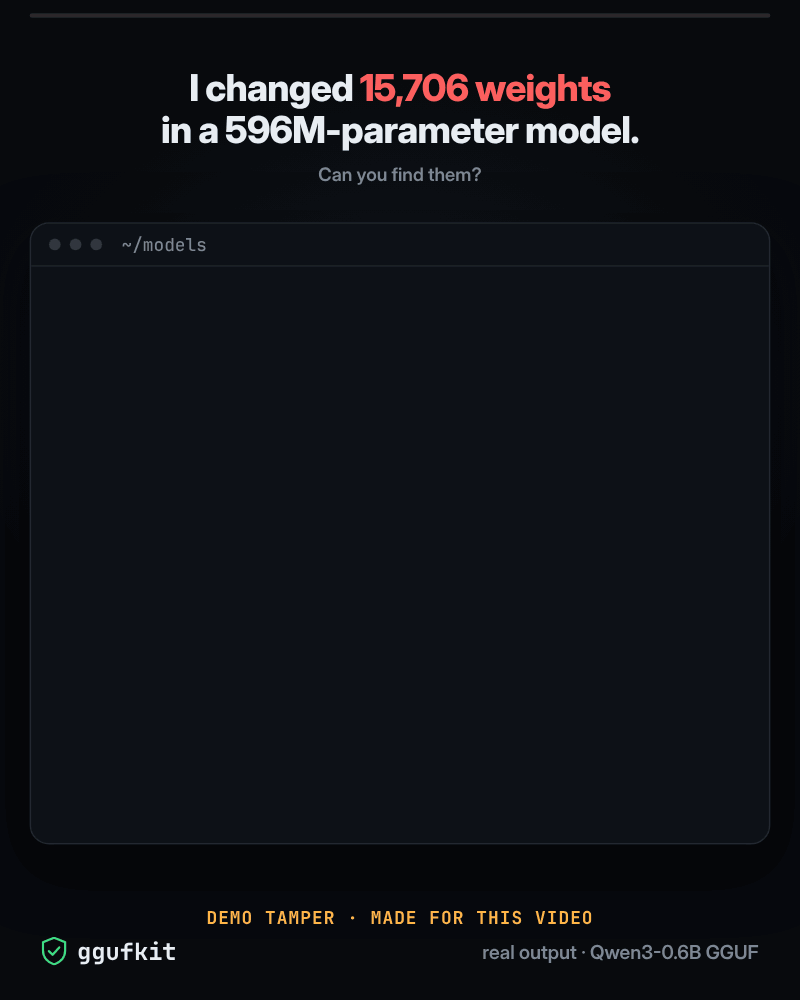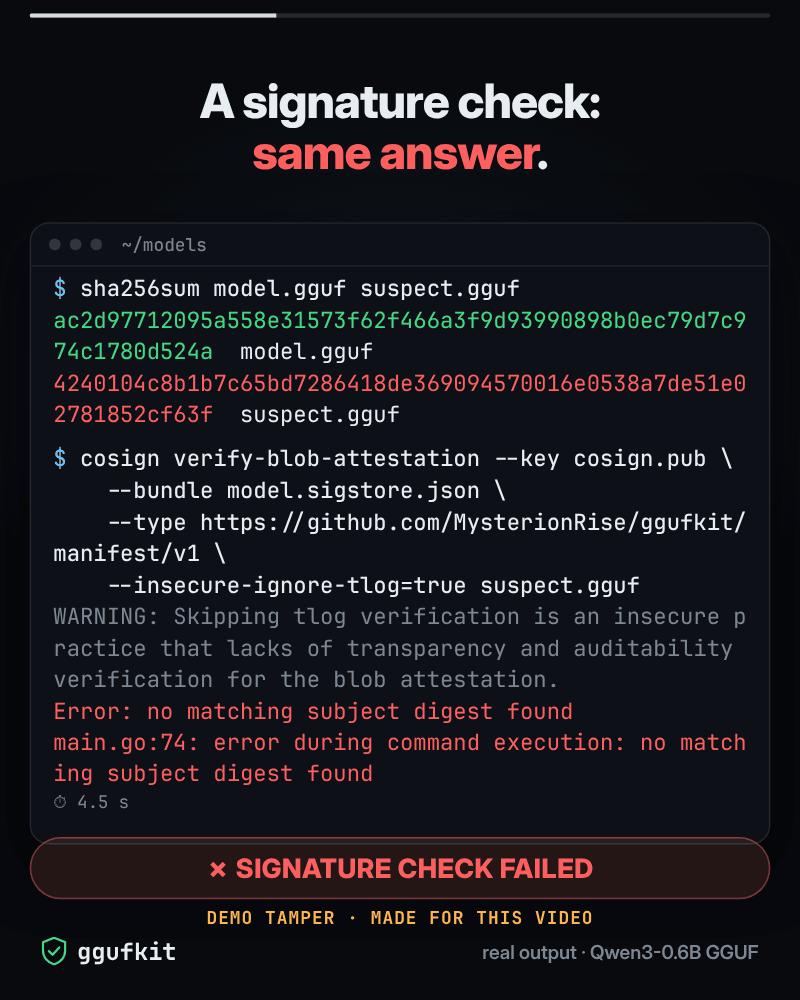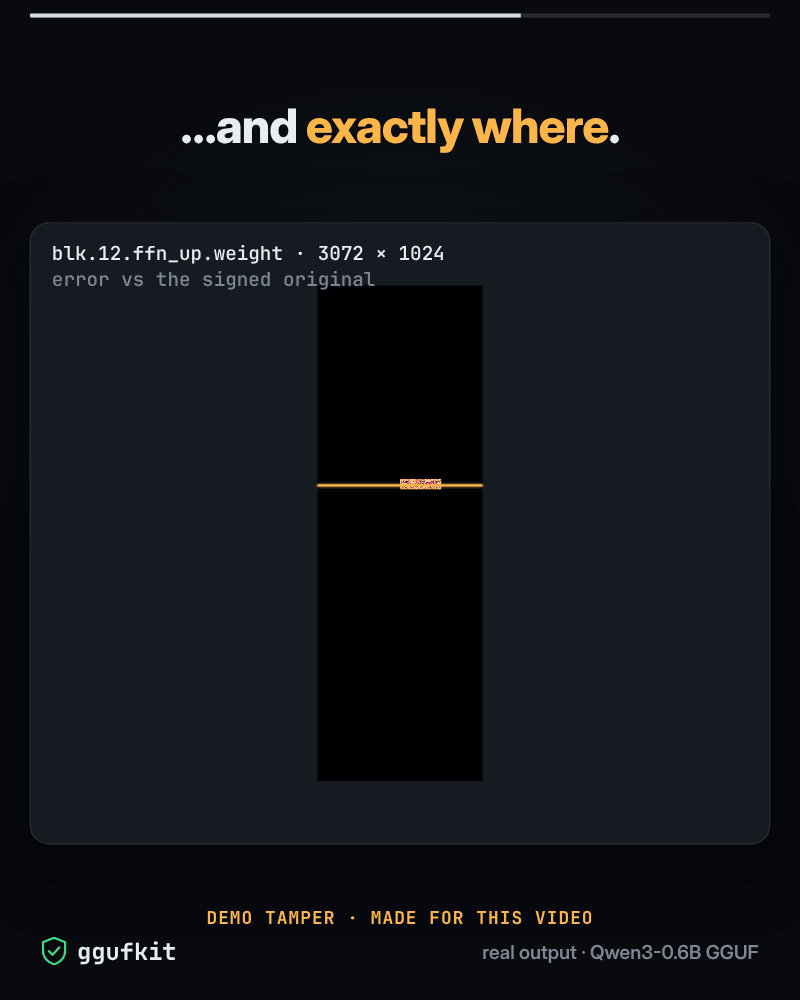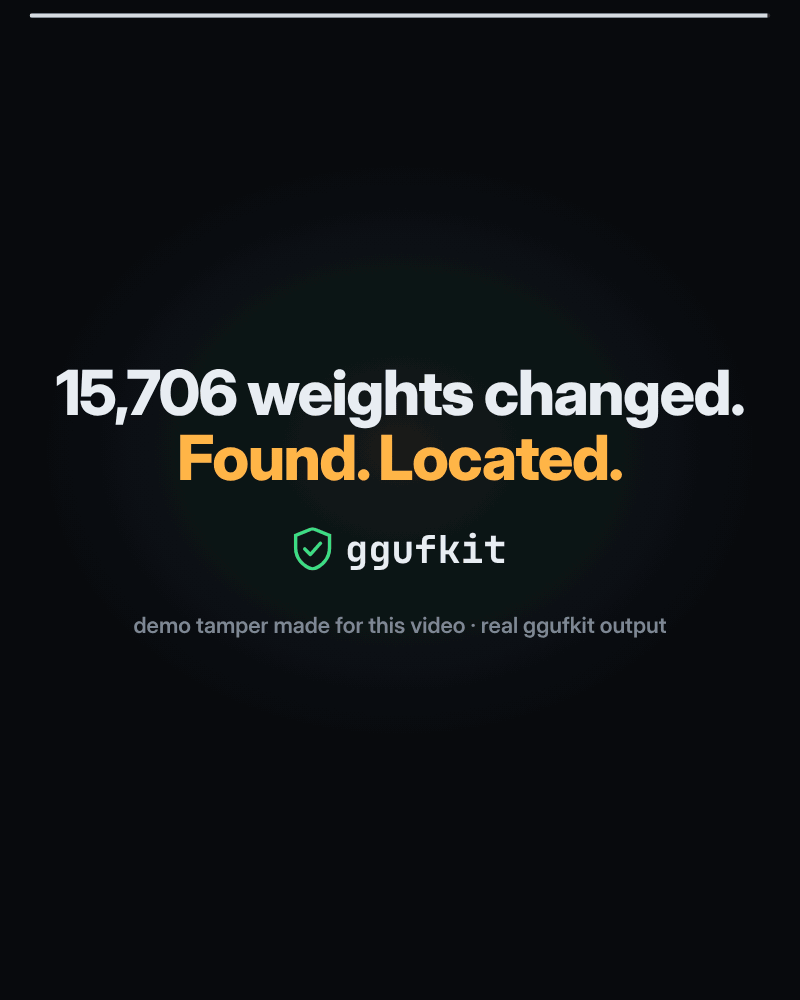
A tamper made for this demo: in one tensor of Qwen3-0.6B's Q4_K_M file, the scale of 64
quantization blocks is multiplied by 1.5, which changes 15,706 weights. A hash and a cosign
signature check both say only that the file differs. ggufkit verify names the tensor, and
ggufkit viz error shows the block. Every frame is the recorded output of the commands on
screen.
Every example below is real output on
unsloth/Qwen3-0.6B-GGUF (Apache-2.0) at
revision 50968a4. scripts/make_readme_assets.py downloads
the three files, checks their sha256 and reruns every command;
scripts/make_demos.py records the animations from the same
files.
Why
Model signing (OpenSSF model-signing, Sigstore) protects the bytes you were given. It breaks the moment someone fixes a chat template in the metadata, and when it breaks it cannot tell you whether the weights changed. It also says nothing about whether a community quantization was faithfully built from the model it names. GGUF's standard metadata has no key for the source checksum, the llama.cpp version or the quantize command, so files do not say how to rebuild them, and Mind the Gap (ICML 2025) showed weights that behave well in full precision and badly after GGUF quantization.
ggufkit gives GGUF files a content identity that survives the edits people legitimately make (docs/FINGERPRINT.md), a provenance record that says what a file claims and what it leaves out (docs/MANIFEST.md), and the tools to check one against the other.
Install
pip install "ggufkit[viz]"
uv tool install "ggufkit[viz]"     # or: pipx install "ggufkit[viz]"
The viz extra pulls in Pillow for image rendering; the core needs only gguf and numpy.
Python 3.11 or newer. python -m ggufkit works as well as ggufkit.
Quick start
Fingerprint a model
$ ggufkit fingerprint Qwen3-0.6B-Q4_K_M.gguf --no-per-tensor
kv           8eb7cd5593931521f2e20641dcb340cf5e9e32a6cafd9b5face98332e53052d9
tensor_info  fb9deeab22c4fb9d0b1cca92f9edb974c1f21c53b1a986cd96144d665f0c65be
weights      7e8be1d0cc3ac473b493058a2976be592d51125772c39e80ab6264215b756de5
overall      155c4d32bd17c6a005e44269e96cf3f0a2b315ca1eb3bc434349aa268b3f975a
spec         ggufkit-fp/1  (32 metadata entries, 310 tensors)
Three digests, three answers:
kv |
tensor_info |
weights |
meaning |
|---|---|---|---|
| same | same | same | the same model |
| differs | same | same | only metadata changed (names, templates, licence text) |
| same | differs | same | tensors retyped or reshaped in place, bytes untouched |
| any | any | differs | tensor bytes changed or moved between tensors, tensors were added or removed, or renamed |
weights binds every tensor's bytes to its name, so swapping the data of two tensors with the
same shape shows up even though no byte was added or lost. verify tells a pure rename apart
from new weights through the per-tensor digests.
Without --no-per-tensor you also get one line per tensor. --json prints JSON, --no-data
skips tensor bytes (instant on any size), --per-kv adds a digest per metadata entry, -j 8
hashes on eight threads. Pass any shard of a split model and
the whole model is fingerprinted; splitting, merging or editing metadata with llama.cpp's
gguf-new-metadata leaves weights unchanged.
Record provenance
$ ggufkit manifest Qwen3-0.6B-Q4_K_M.gguf --file-sha256
manifest     Qwen3-0.6B-Q4_K_M.manifest.json
model        qwen3 Q4_K_M, 310 tensors, 596.05M parameters, 372.65 MiB
fingerprint  155c4d32bd17c6a005e44269e96cf3f0a2b315ca1eb3bc434349aa268b3f975a
provenance   imatrix, quantized_by, repo_url
score        2/9 of what a verifiable file records
gaps         general.source.*, general.license, general.uuid, build_inputs.source_sha256, build_inputs.imatrix_sha256, build_inputs.llama_cpp_commit, build_inputs.quantize_cmd
This file records who quantized it and which calibration data the importance matrix came from, but not which model it was quantized from, its licence, or how to rebuild it.
The manifest is a JSON file: the full fingerprint, file sizes (and raw hashes with
--file-sha256), what the metadata claims about origin and licence, the build inputs you pass
with --input KEY=VALUE, and the list of what a reproducible quantization would record but
this file does not. Its producer can close the build_inputs.* gaps with --input, for
example --input llama_cpp_commit=b8146. Publish it next to the model.
To sign it, --intoto model.intoto.json also writes an in-toto statement, and the manifest
works as a predicate for cosign attest-blob. The tested recipe is in
docs/MANIFEST.md.
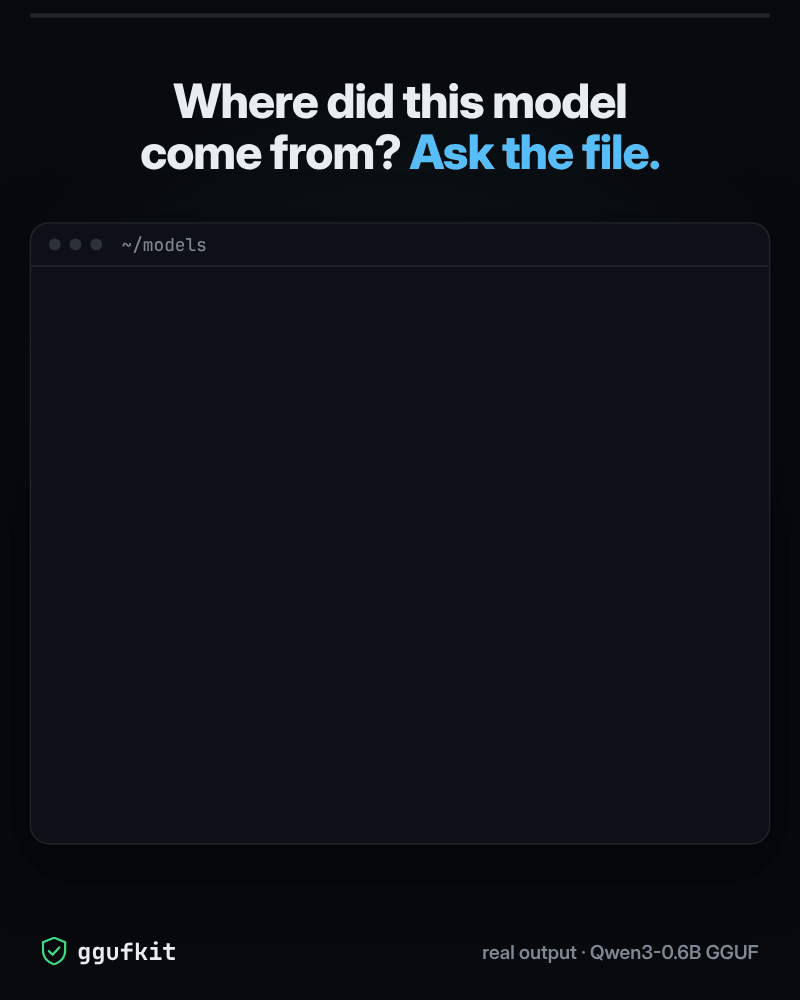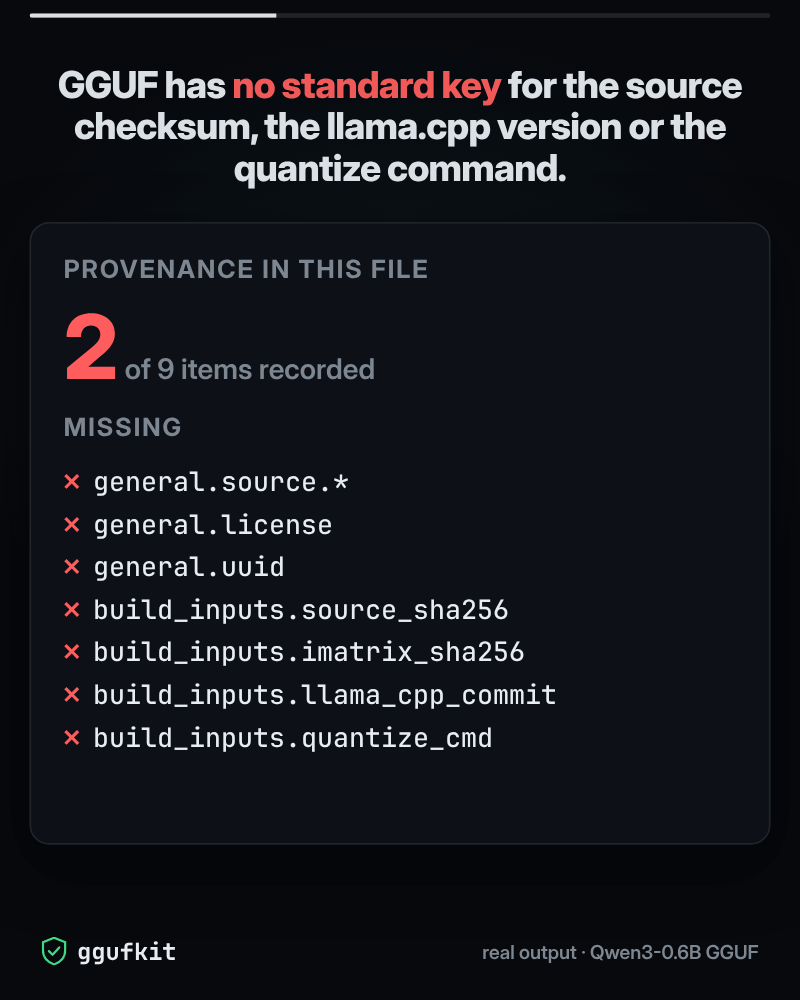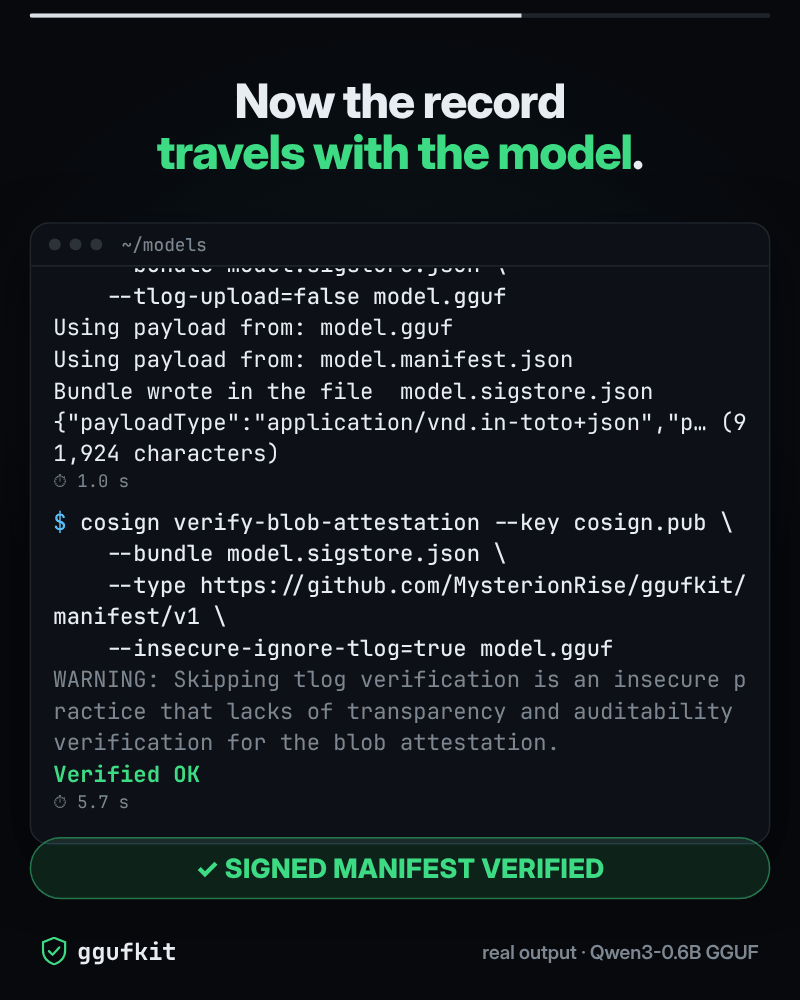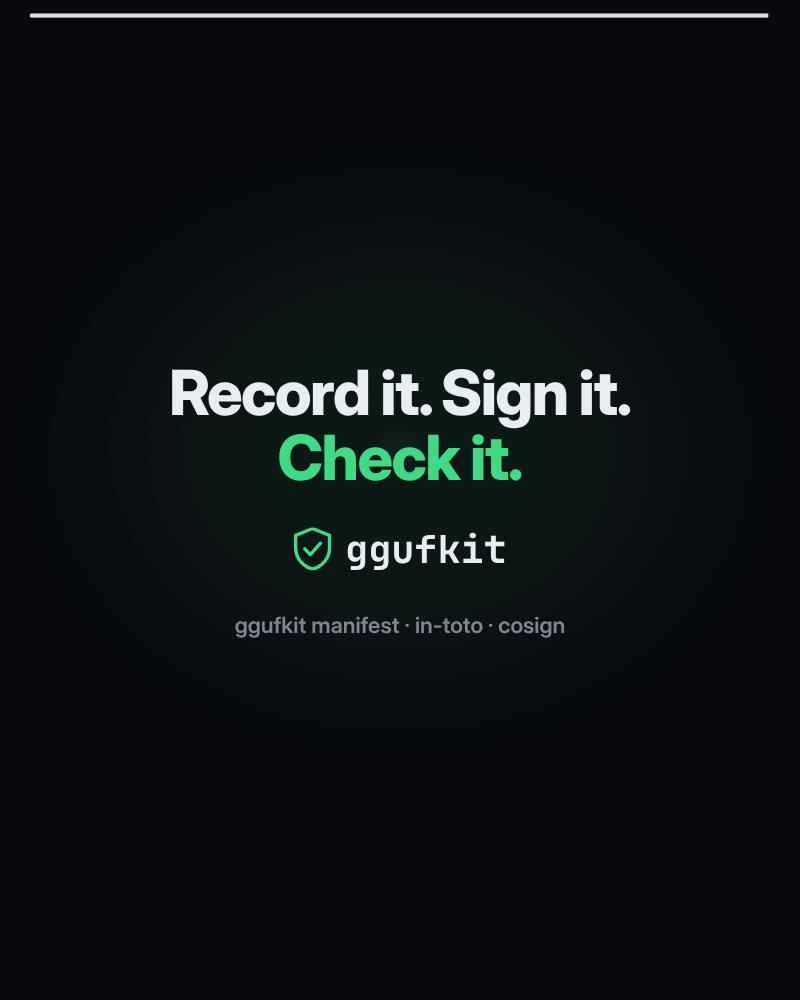
What the file records, then the record signed and checked: ggufkit manifest, cosign attest-blob with the manifest as predicate, and cosign verify-blob-attestation.
Verify
A copy whose name was changed with llama.cpp's gguf-new-metadata, checked against the
manifest of the original:
$ ggufkit verify edited/Qwen3-0.6B-Q4_K_M.gguf --manifest Qwen3-0.6B-Q4_K_M.manifest.json
verdict      metadata-only
kv           differs
tensor_info  same
weights      same
metadata changes:
  ~ general.name
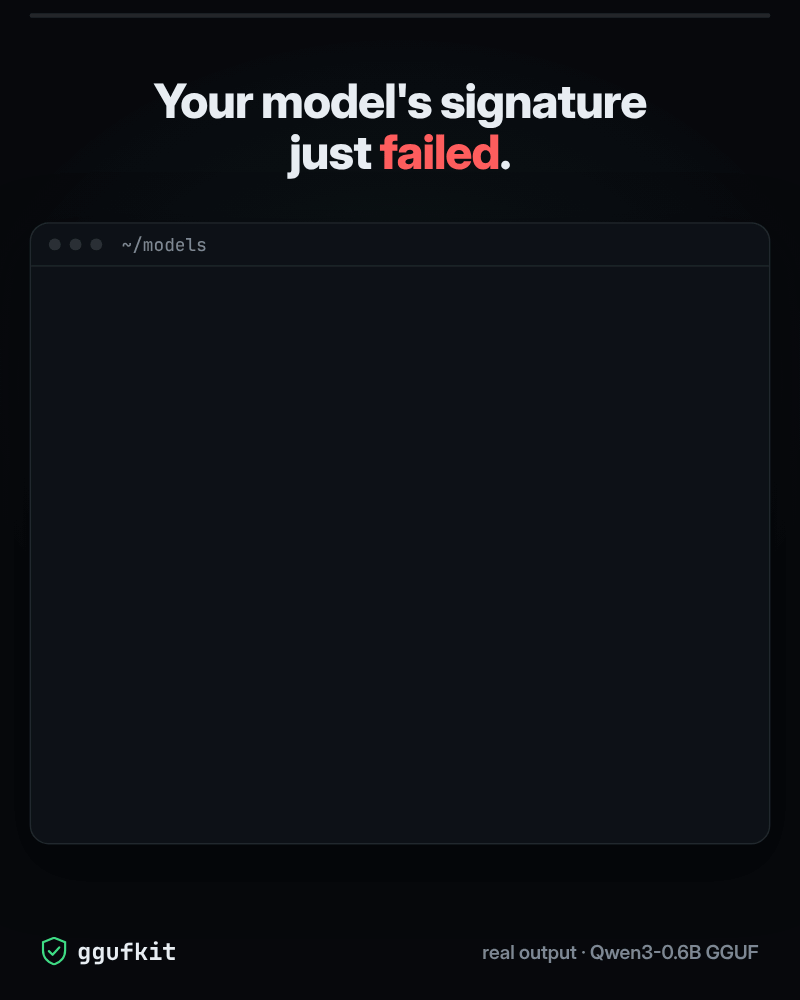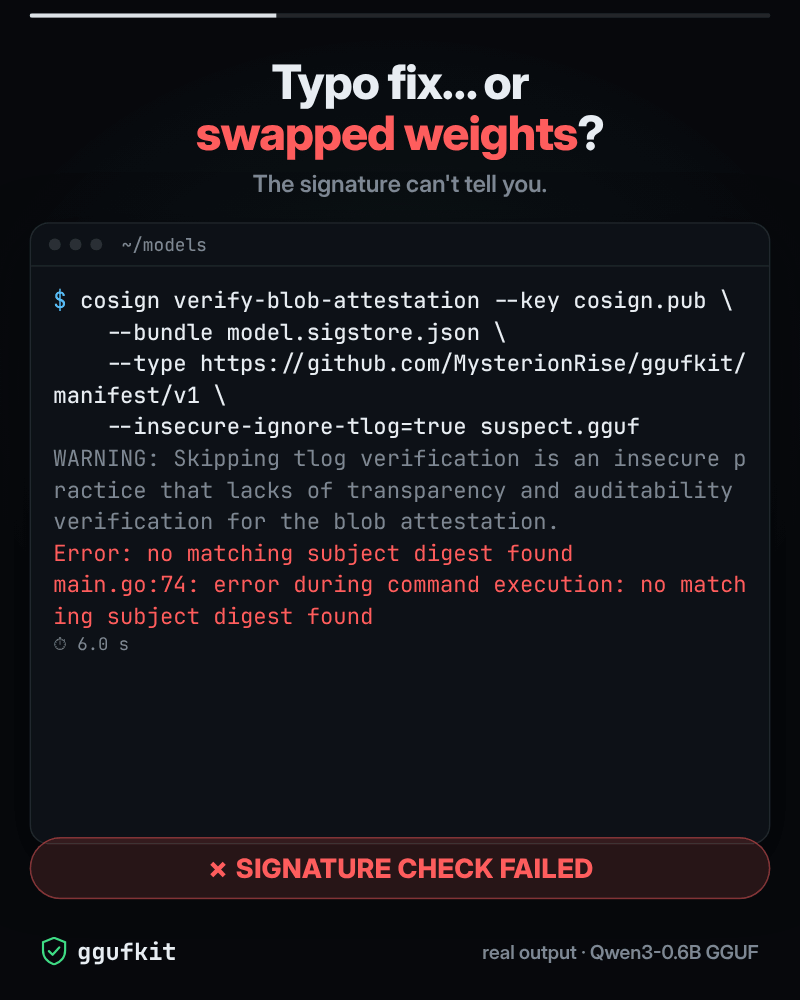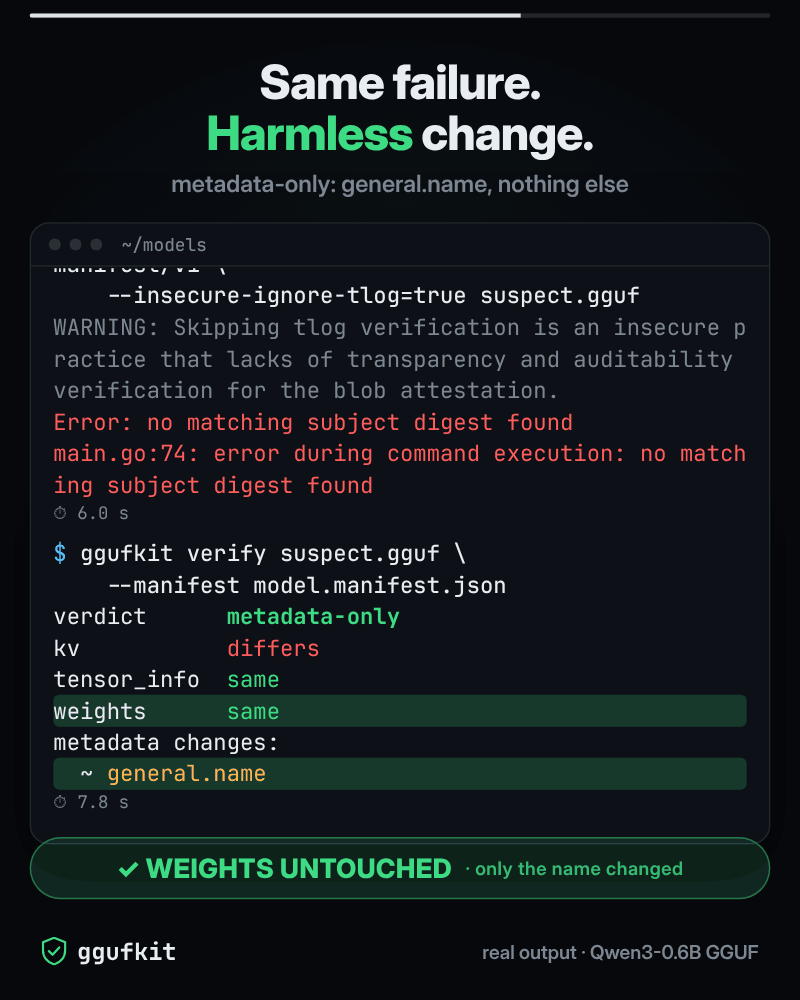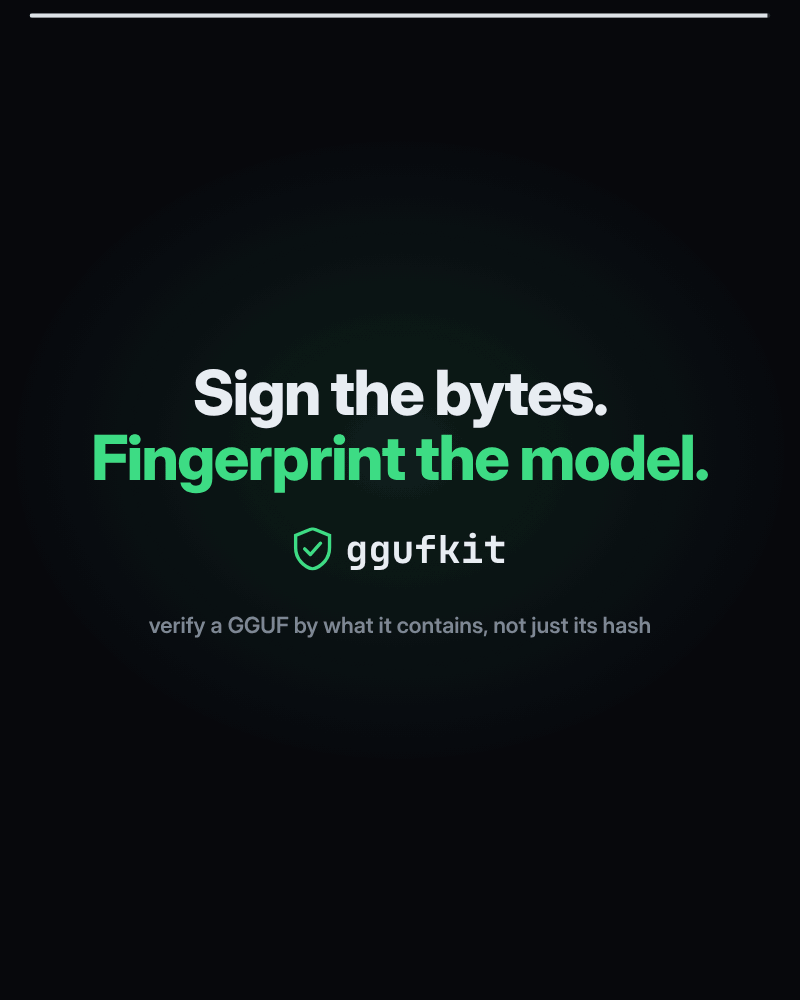
The same edit against a cosign attestation of the original: cosign rejects the file, as it
would for any change, and ggufkit verify says only the name changed. (The demos run
offline, so cosign is told to skip Sigstore's public transparency log; in real use, leave it
on.)
Unsloth's two 4-bit files of the same model, compared directly:
$ ggufkit verify Qwen3-0.6B-UD-Q4_K_XL.gguf --against Qwen3-0.6B-Q4_K_M.gguf
verdict      weights-changed
kv           same
tensor_info  differs
weights      differs
tensor changes:
  ~ blk.0.attn_k.weight  retyped  Q5_K -> Q4_K
  ~ blk.0.attn_q.weight  retyped  Q5_K -> Q4_K
  ~ blk.0.ffn_gate.weight  retyped  Q5_K -> Q4_K
  ~ blk.0.ffn_up.weight  retyped  Q5_K -> Q4_K
  …
kv same: the two files carry identical metadata, down to general.file_type, which says
Q4_K_M in both. Only the tensors tell them apart: 60 of them are stored in a different type.
Verify against a manifest or straight against another file with --against other.gguf. The
verdict is one of identical, metadata-only, tensor-info-only, metadata-and-tensor-info
or weights-changed. The exit status is 0 only for identical, so it drops into CI and
download scripts; --allow-metadata also accepts metadata-only, and --ignore-keys takes
globs for keys you expect to change.
Diff two models
$ ggufkit diff Qwen3-0.6B-BF16.gguf Qwen3-0.6B-Q4_K_M.gguf --no-kv --numeric --top 8
tensors: 197 changed, 0 added, 0 removed (of 310)
  ~ blk.0.attn_k.weight  type, data  [BF16 1024x1024 -> Q4_K 1024x1024]
  ~ blk.0.attn_output.weight  type, data  [BF16 2048x1024 -> Q4_K 2048x1024]
  …
  ~ token_embd.weight  type, data  [BF16 1024x151936 -> Q6_K 1024x151936]
numeric (top 8 by rel_l2):
  tensor                               a -> b                 rmse    max_abs   mean_abs     rel_l2     cosine
  blk.16.ffn_down.weight               BF16->Q4_K         0.001822   0.023621   0.001476   0.076444   0.997074
  blk.19.ffn_down.weight               BF16->Q4_K         0.002015   0.029144   0.001633   0.076084   0.997102
  blk.18.ffn_down.weight               BF16->Q4_K         0.001898   0.024334   0.001547   0.075795   0.997124
  blk.15.ffn_down.weight               BF16->Q4_K         0.001775   0.031386   0.001440   0.075282   0.997163
  blk.16.attn_k.weight                 BF16->Q4_K         0.001789   0.028889   0.001346   0.075218   0.997169
  blk.10.ffn_down.weight               BF16->Q4_K         0.001768   0.021751   0.001437   0.074827   0.997197
  blk.11.attn_output.weight            BF16->Q4_K         0.001742   0.020073   0.001346   0.074776   0.997201
  blk.13.attn_output.weight            BF16->Q4_K         0.001683   0.016928   0.001350   0.074690   0.997207
The whole 596M-parameter comparison takes under a minute. Across the model, tensors stored as Q4_K land at a median relative L2 error of 7.3%, the Q6_K ones at 1.8%.
Metadata entries are shown with their old and new values; tensors are listed as added,
removed or changed (shape, type, data). --numeric decodes both sides and reports error per
tensor, worst first, in bounded memory. --tensor 'blk.*.attn_*' narrows it, --json gives
machine-readable output, and the exit status is 1 when anything differs.
See where quantization loses precision
ggufkit viz error Qwen3-0.6B-BF16.gguf Qwen3-0.6B-Q4_K_M.gguf blk.0.attn_q.weight -o err.png --max-pixels 262144
ggufkit viz error Qwen3-0.6B-BF16.gguf Qwen3-0.6B-Q4_K_M.gguf 'blk.*.attn_q.weight' --match-glob --shared-scale -o imgs/err.png
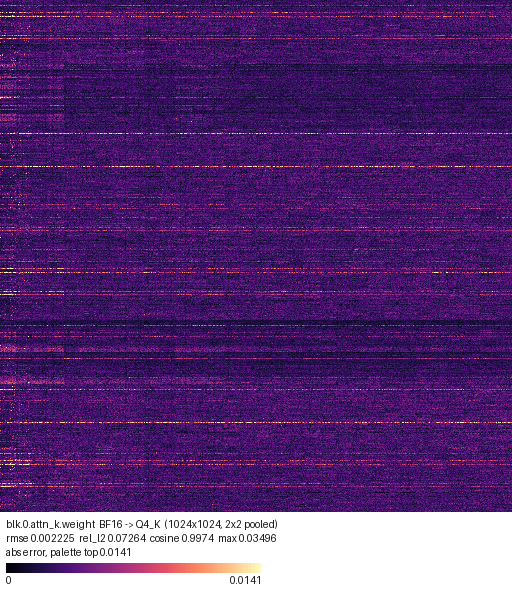
blk.0.attn_k.weight of Qwen3-0.6B, comparing Unsloth's BF16 and Q4_K_M files. Error follows
weight magnitude: bright rows are output channels with large weights, whose 4-bit steps are
coarser (per-row correlation between error and weight magnitude: 0.99).
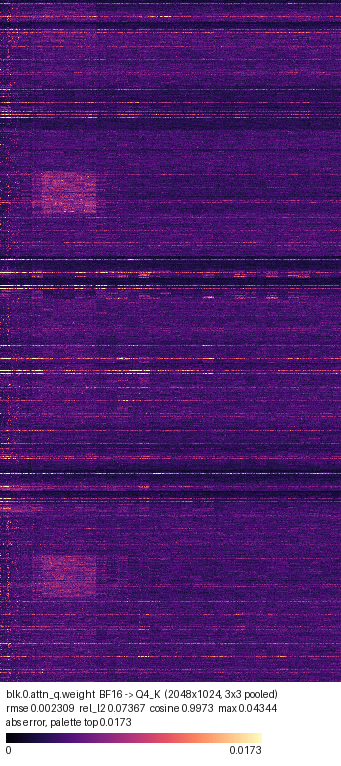
blk.0.attn_q.weight, Q4_K against BF16. Besides the bright rows, a brighter patch stands
out a quarter of the way down, in the rows of attention heads 3 to 5: its weights are about 40%
larger than the tensor's average, and its error about 60% larger.
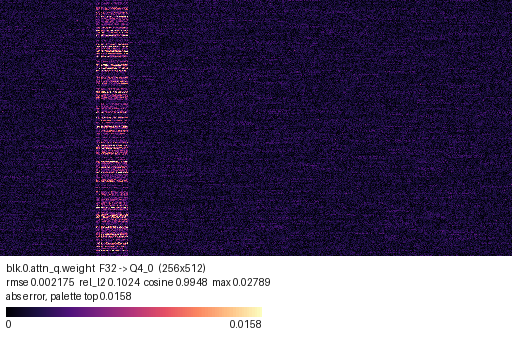
A synthetic illustration of the mechanism, from scripts/make_examples.py: one input channel
with 8x larger weights, quantized to Q4_0. Q4_0 stores one scale per block of 32 weights along
a row, so the outlier stretches the scale of its block and every weight in that band loses
precision.
Each pixel is the error of one weight: absolute by default, --metric rel or --metric signed
on request. Large tensors are pooled down to --max-pixels while they are decoded, and the
default --pool max keeps the worst weight of each pixel visible. The caption gives rmse,
relative L2 and cosine similarity; --shared-scale puts several tensors on one colour scale.
See the quant mix
$ ggufkit viz layers Qwen3-0.6B-UD-Q4_K_XL.gguf
block  attn_norm  attn_q  attn_k  attn_v  attn_q_norm  attn_k_norm  attn_output  ffn_norm  ffn_gate  ffn_up  ffn_down
0      F32        Q5_K    Q5_K    Q6_K    F32          F32          Q4_K         F32       Q5_K      Q5_K    Q6_K
…
3      F32        IQ4_XS  IQ4_XS  Q5_K    F32          F32          Q4_K         F32       IQ4_XS    IQ4_XS  Q5_K
…
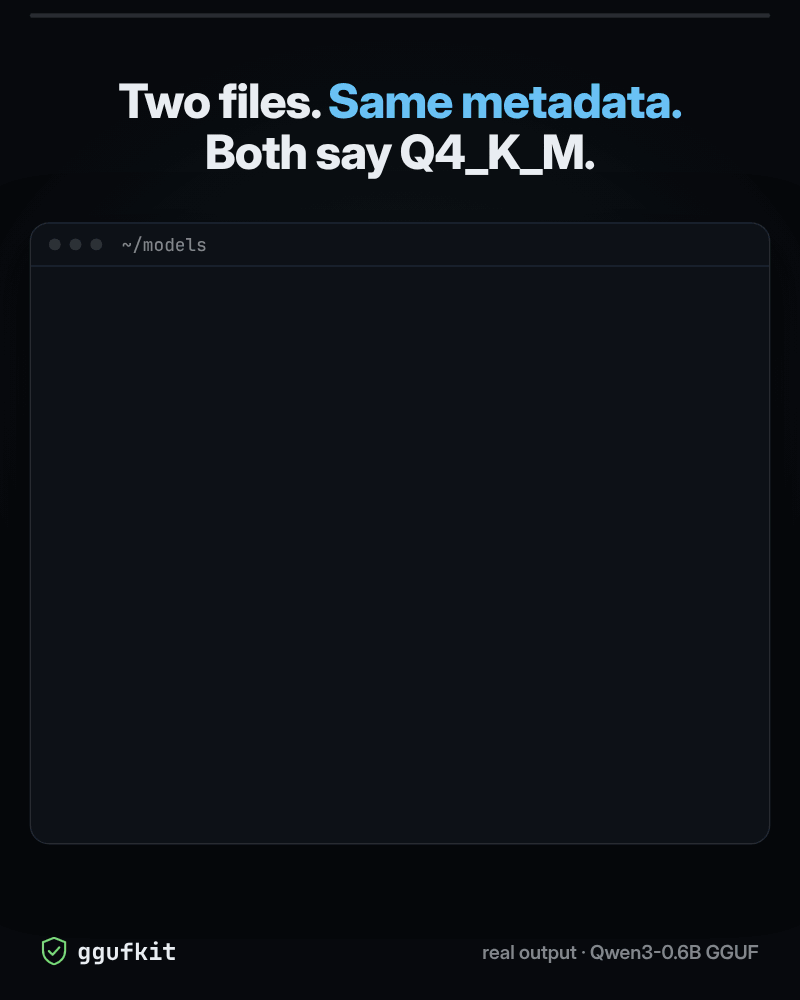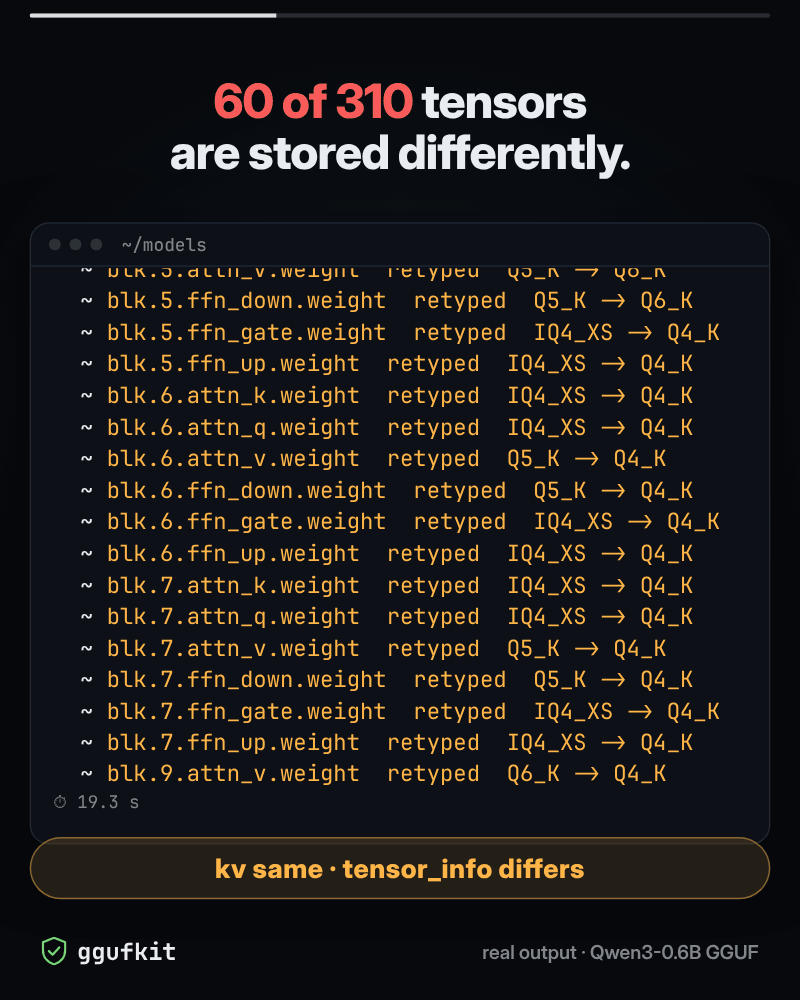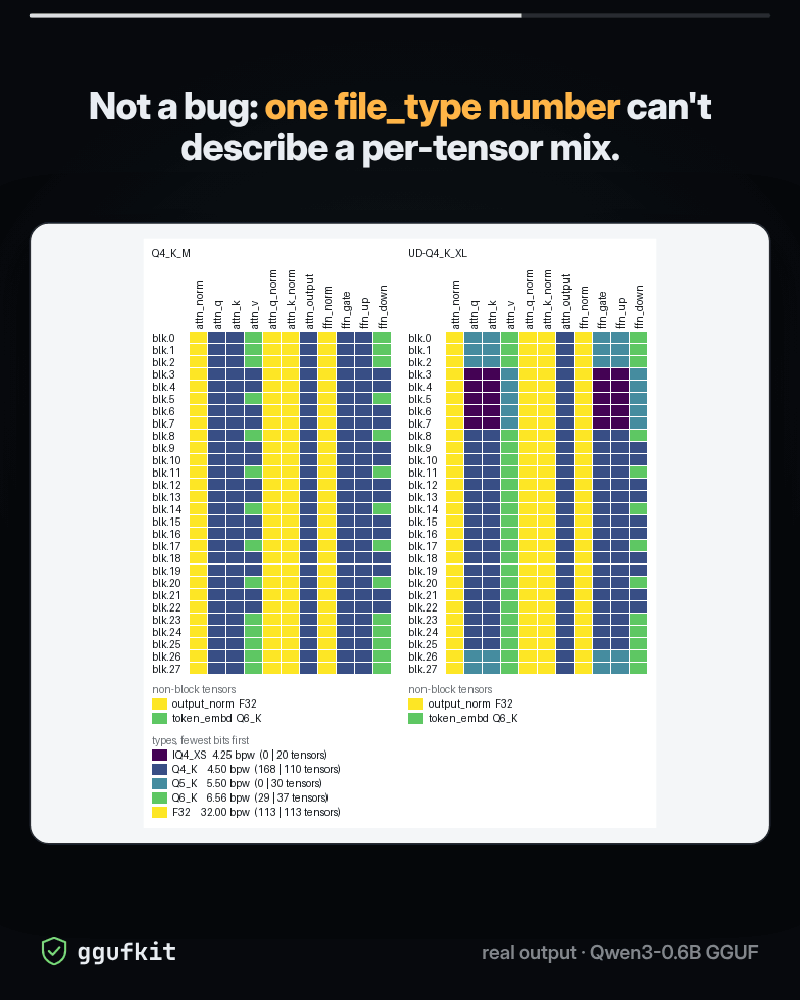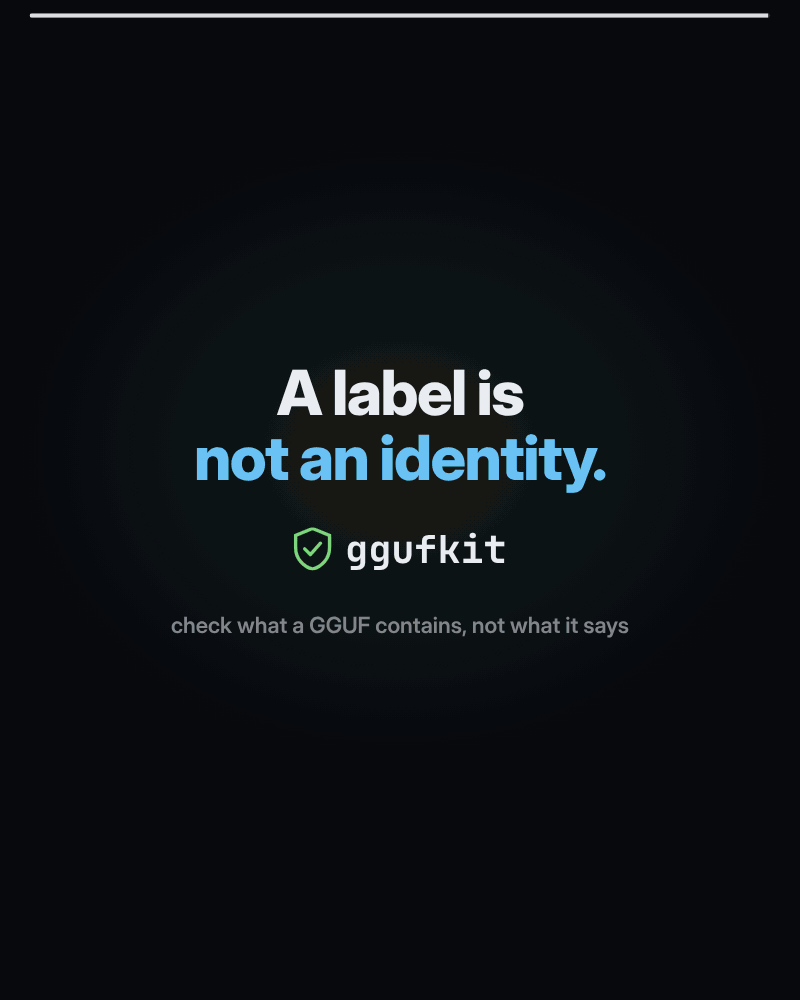
$ ggufkit viz layers Qwen3-0.6B-Q4_K_M.gguf Qwen3-0.6B-UD-Q4_K_XL.gguf -o layers.png
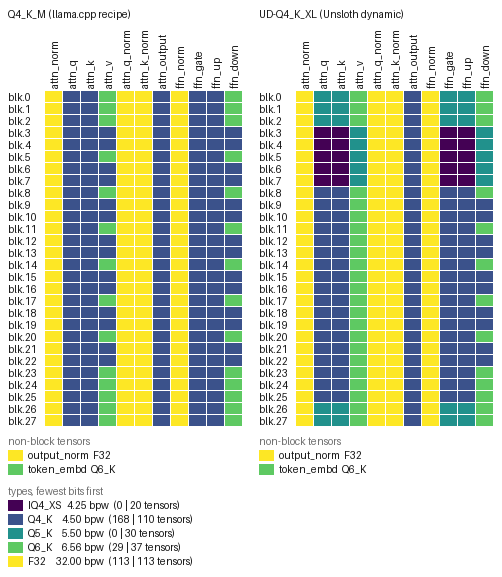
The two 4-bit files from the verify example. llama.cpp's Q4_K_M recipe (left) raises attn_v
and ffn_down to Q6_K in the first three blocks, every third block after that and the last
five. Unsloth's UD-Q4_K_XL (right) uses Q5_K for the first three and last two blocks, IQ4_XS
for blocks 3 to 7, and Q6_K for attn_v outside blocks 3 to 7. The metadata of both files
says Q4_K_M.
One row per block, one column per tensor role, coloured by bits per weight, with non-block
tensors and a legend underneath. Given several models, -o draws them side by side with one
palette, so a colour means the same type in every panel. The text table and --json work
without Pillow.
Stitch metadata onto tensors
ggufkit stitch --metadata tokenizer-fixed.gguf --tensors model.gguf -o model-fixed.gguf
ggufkit stitch --metadata model.gguf -o vocab-only.gguf     # metadata only, no tensors
Look at the weights
ggufkit viz tensor model.gguf blk.0.attn_q.weight -o attn_q.png
ggufkit viz tensor model.gguf 'blk.*.attn_q.weight' --match-glob -o imgs/q.png
ggufkit viz tensor model.gguf token_embd.weight -o embd.png --max-pixels 4000000
Each pixel is one weight: brightness follows magnitude, hue says whether the weight sits well below the mean, well above it, or in between.
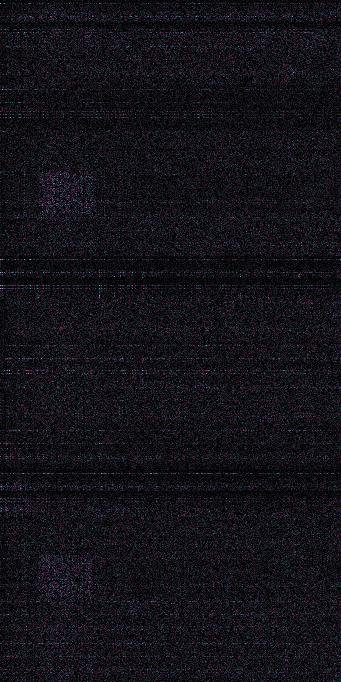
blk.0.attn_q.weight of Qwen3-0.6B in BF16, mean-pooled to 341×682 pixels with
--max-pixels 262144. The brighter patch a quarter of the way down is the group of larger
weights that shows more quantization error in the attn_q error map above.
PyTorch checkpoints work too when torch is installed (--model-type torch).
What this proves, and what it does not
- A fingerprint proves integrity and equivalence: two files hold the same metadata, tensor descriptors and weights, or exactly which part differs. Each tensor's bytes are bound to its name, so moving weights between tensors counts as a change.
- A manifest records claims (where the model came from, who quantized it, how) and makes
missing ones visible. It is only as trustworthy as the place you got it from: whoever can
replace a model can replace a manifest stored next to it. Sign manifests (
--intotoand cosign, see docs/MANIFEST.md) or fetch them from a source you trust more than the download, and check the signature before trusting the verdict. - A passing
verifyalways means the weights were compared. Against a manifest made with--no-data,verifyfails unless you ask for a metadata-only check withverify --no-data. - Neither proves that a quantized file was faithfully built from the model it names, or that
a model is benign. For that, re-quantize the source with the recorded build inputs and
compare:
verify --againsttells you whether you reproduced the file, anddiff --numerictells you how far apart the two are when you did not.
Exit codes
| command | 0 | 1 | 2 |
|---|---|---|---|
verify |
identical (or metadata-only with --allow-metadata) |
any other difference; weights or file hashes that could not be compared | error |
diff |
nothing differs in the compared sections | something differs | error |
fingerprint, manifest, stitch, viz |
done | error |
Errors are a malformed or unreadable file, a malformed manifest, an output file that exists
without --force, or invalid arguments; they print one line starting with error:. Ctrl-C
exits 130, and a closed output pipe 141.
Python API
The same checks are available from Python, on paths:
import ggufkit

fp = ggufkit.fingerprint_file("model.gguf")  # any shard of a split model works too
print(fp.overall, fp.weights)

report = ggufkit.verify_file("download.gguf", against="model.gguf")
if not report.ok(allow_metadata=True):
    raise SystemExit(f"{report.verdict}: {[str(c) for c in report.tensor_changes or []]}")

manifest = ggufkit.create_manifest("model.gguf", file_sha256=True)
ggufkit.save_manifest("model.manifest.json", manifest)
ggufkit.verify_file("model.gguf", manifest="model.manifest.json", file_sha256=True).ok()
fingerprint_file, create_manifest, verify_file, load_manifest and save_manifest
return Fingerprint, Manifest (a typed dict in the documented format) and Report
objects. Every error ggufkit raises for bad input is a ggufkit.GGUFKitError, itself a
ValueError. The names in ggufkit.__all__ are stable: they change only in a major release,
or after a deprecation warning that lasts at least one minor release. The submodules
(ggufkit.fingerprint, ggufkit.verify, …) are the command line's implementation and may
change in any release. import ggufkit loads nothing heavy until you use one of the names.
FAQ
How is this different from sha256sum or the hashes Hugging Face shows? Those hash bytes.
Any change, even fixing one character of a chat template, gives a new hash and no
explanation. A ggufkit fingerprint stays the same under changes that leave the model alone
(metadata order, sharding, alignment, tensor order) and says which part changed when
something did. Keep checking file hashes on download; use the fingerprint to ask whether it
is still the same model.
And OpenSSF model-signing or Sigstore? They prove who published which bytes, and ggufkit does not replace them. It writes the manifest you sign (an in-toto statement, or a cosign predicate), and when a signature check fails, it tells you what changed. The signature demo above shows both side by side.
Does a matching fingerprint mean a model is safe? No. It means the model is the same as the one you compared it with. Whether that one is benign is a separate question.
Will fingerprints change in a later release? No. A file's ggufkit-fp/1 digests stay the
same; a change to what is hashed gets a new spec id, and ggufkit keeps verifying the old one.
Manifests (ggufkit-manifest/1) only gain optional fields. See
docs/FINGERPRINT.md and docs/MANIFEST.md.
Can I use it from Python? Yes: see Python API. The names exported by
import ggufkit are stable, as are the command line, its exit codes, and the fingerprint and
manifest formats. Other implementations of the fingerprint can test against the vectors in
tests/vectors.
Roadmap
- A gallery of error maps and quant maps for popular open models, built from the real files.
- A one-shot "reproduce this quant" check that drives
llama-quantizefrom a manifest.
Development
uv sync --all-extras
uv run pytest
uv run ruff check . && uv run ruff format --check .
uv run mypy
Tests build tiny GGUF files in-process; nothing is downloaded. pytest --update-golden
rewrites the golden fingerprints after a deliberate spec change (bump the spec id too).
Releases are published to PyPI from a vX.Y.Z tag by .github/workflows/release.yml, with
build provenance and PyPI attestations; see docs/RELEASING.md.
Want to help? CONTRIBUTING.md
lists where to start; issues labelled
good first issue
each say what to change and when it's done.
Origins
ggufkit started from KerfuffleV2/gguf-tools
(MIT, 2023): gguf-checksum, gguf-frankenstein and gguf-tensor-to-image. Those commits
are preserved in this repository's history. The checksum tool's idea, hashing metadata,
tensor descriptors and weights separately and independent of their order, is the seed of
the fingerprint specification.
License
MIT. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for ggufkit 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| ggufkit-0.2.0.tar.gz | 98.5 kB | With provenance | Details for ggufkit-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| ggufkit-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for ggufkit-0.2.0-py3-none-any.whl |
Total release size: 162.4 kB
Release files / ggufkit-0.2.0.tar.gz
| Download URL | ggufkit-0.2.0.tar.gz |
|---|---|
| Size | 98.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
53477b3302c4ac2ac5a7ebd7994a0a4f6c225d7f7b9ce18cdc26f33cf79efbb3
|
|
BLAKE2b-256 checksum How to use checksums |
433c28072e3512f239b0f55c99540d9bd02a1ba2cf7f0504406435ce4d0f6532
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logRelease files / ggufkit-0.2.0-py3-none-any.whl
| Download URL | ggufkit-0.2.0-py3-none-any.whl |
|---|---|
| Size | 63.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
04fdb78449d3e43c53fa0439e3ed1fc6d11e8594614bdf6bcf8870332d6fbdaa
|
|
BLAKE2b-256 checksum How to use checksums |
8afa60df1bd7a58457e13f421a79f3df7f06d18409681d27a0c17c3ed1741d25
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logSecurity for ggufkit 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for ggufkit-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














