
👻 GhostPatch
An AI software engineer that understands how your code connects.
Describe a bug, or let it find one. GhostPatch maps the codebase into a live graph, finds the root cause, writes the fix, works out everything the change could break, and proves it: the new tests fail without the fix and pass with it.



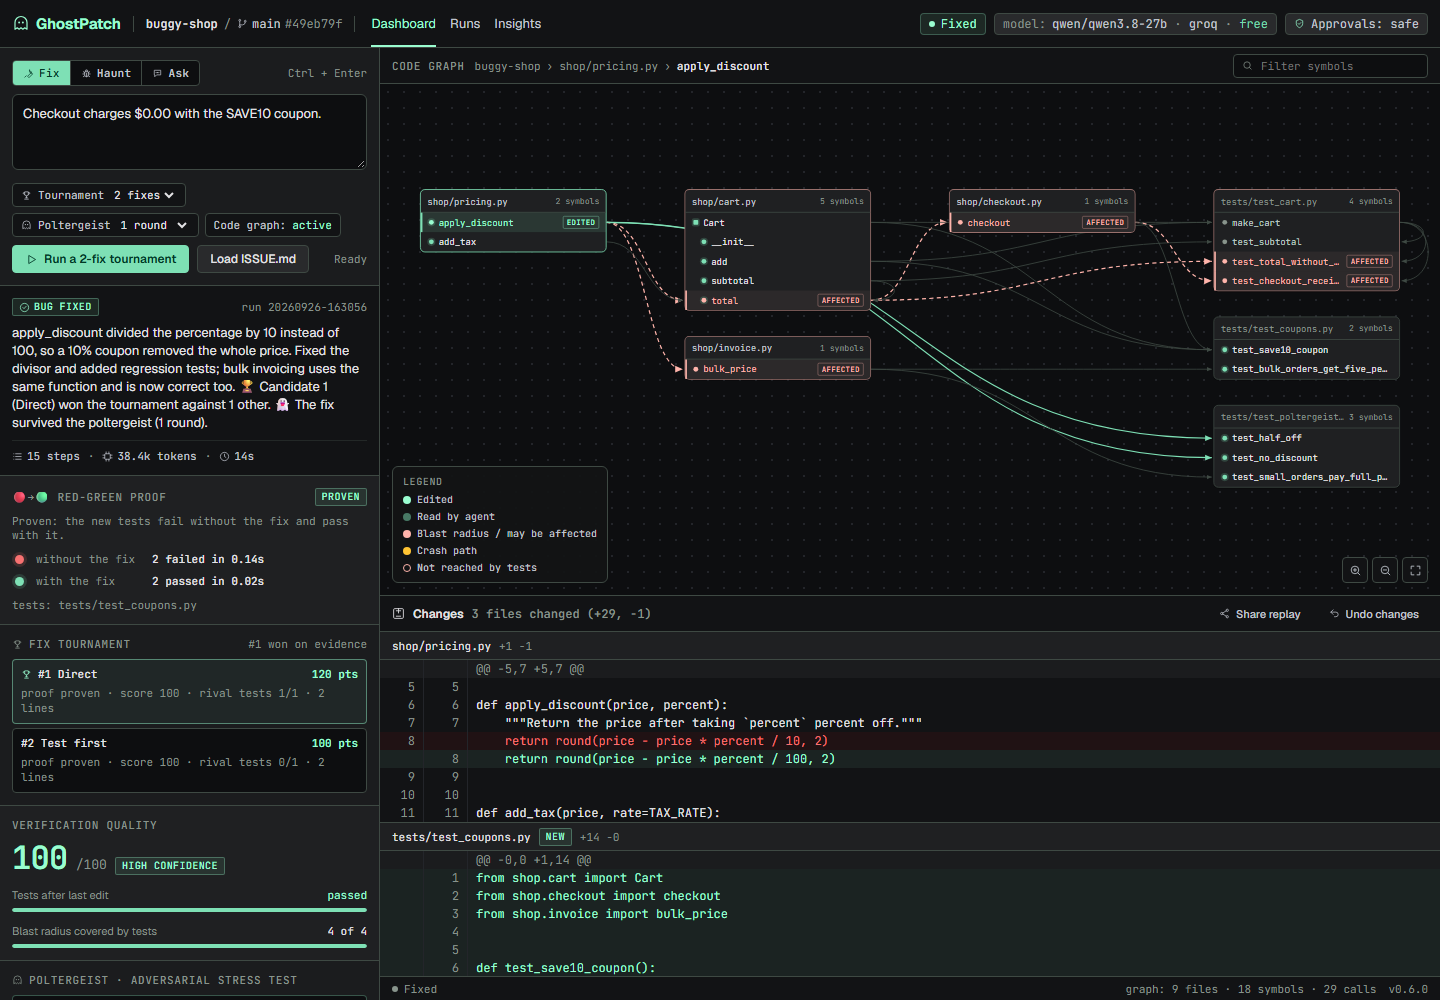
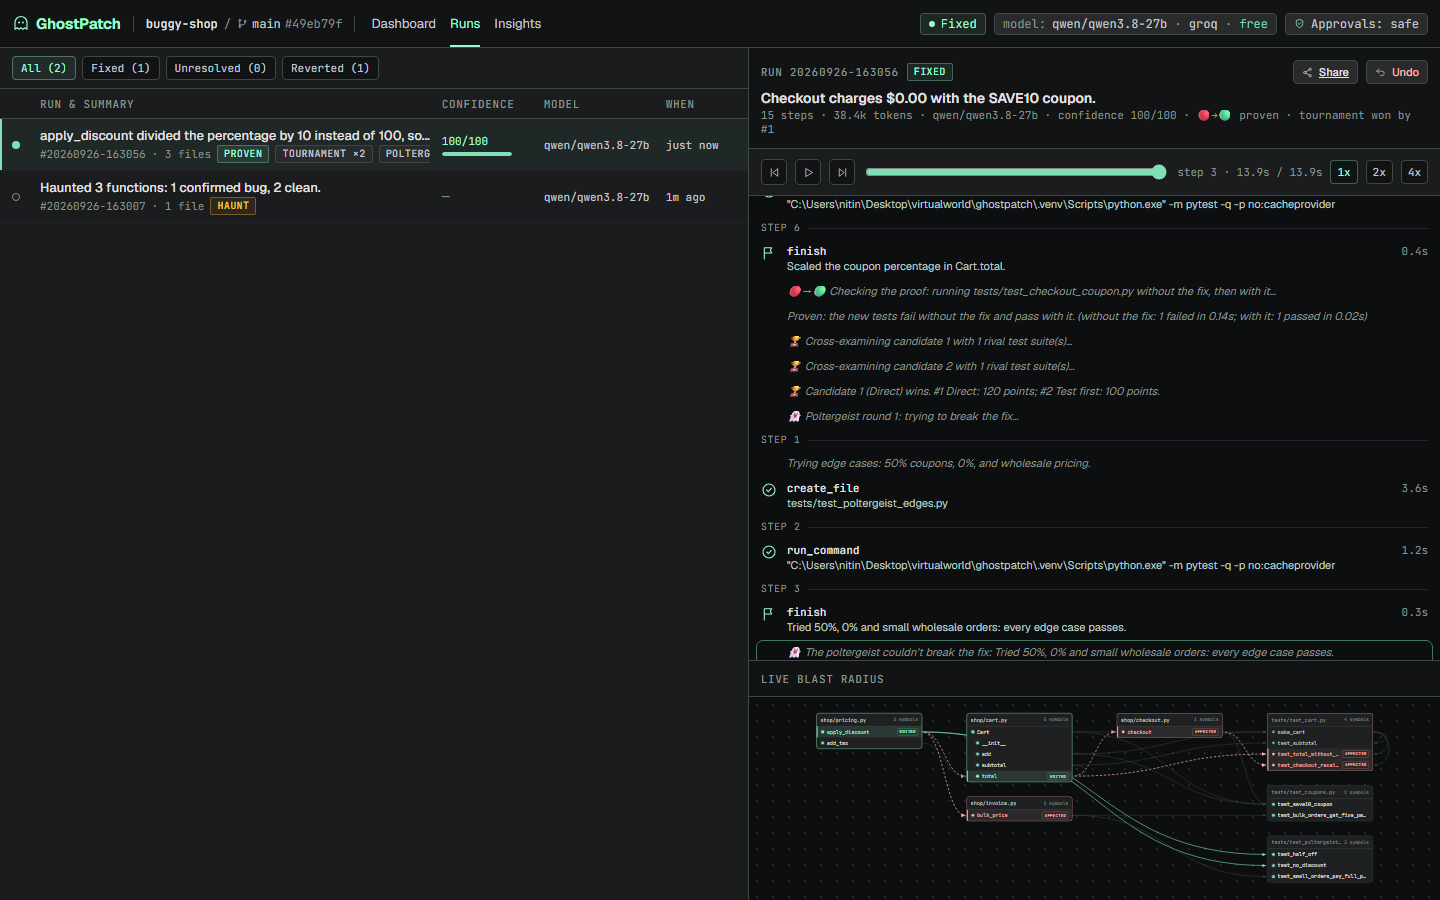
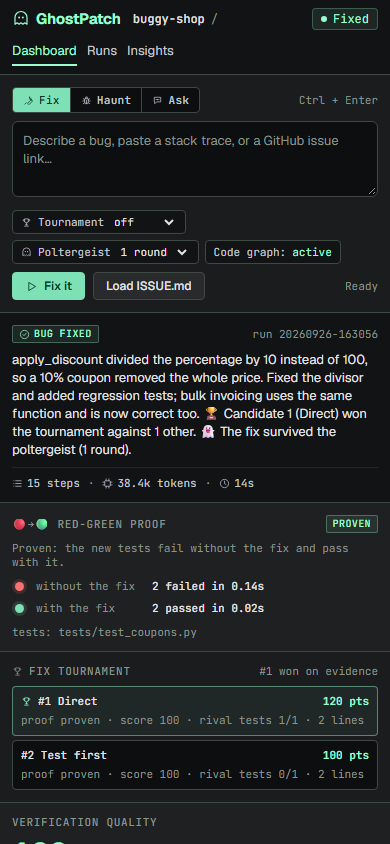
A two-fix tournament on a checkout bug. The winner fixed the root cause and passed its rival's tests; the loser patched the symptom in the cart. The fix is proven red→green, and the poltergeist couldn't break it.
The problem
AI coding agents are good at writing code, but most of them explore a repository the way a newcomer would: by searching text and opening files one at a time. They find the line that looks wrong, patch it, and move on, without knowing what else depends on that line.
That is how a "fix" to a discount calculation quietly changes wholesale invoicing too.
The idea
GhostPatch gives the agent a map before it touches anything.
It parses the codebase into a graph of files, classes, functions, tests and who-calls-what, keeps that graph in sync as files change, and puts it at the centre of the agent's work:
- Calls are linked through imports, module aliases,
self/thisand the types the code states (cart *Cart,Cart cart,let cart = Cart::new()), so the graph knows whichtotal()a call means, not just that something calledtotal. - Before the first step, GhostPatch ranks the code most likely at fault (names and words from the report, quoted messages found in the code, then along the call graph towards the cause) and puts the top suspects' source in the agent's first message. On the benchmark, the buggy function is among those suspects in 31 of 31 cases (first in 18), before the model has read a thing.
- The agent starts every task with an outline of the whole repository.
- It can ask structural questions: where is this defined, who calls it, which tests cover it?
- Every edit is automatically followed by an impact report: what depends on the changed function, how far the change ripples, and exactly which tests to run. The agent gets this whether or not it thought to ask. That matters most with smaller, free models.
Proof, not promises
An AI saying "fixed, and the tests pass" is a claim. GhostPatch checks it itself.
- 🛡 Regression guard. GhostPatch runs the whole test suite before the agent starts and again
after the fix. A test that passed before and fails now goes straight back to the agent ("your fix
broke
test_average"), up to twice. A fix that still breaks something is never called fixed. - 🔴→🟢 Red-green proof. After every fix, GhostPatch runs the new tests twice: with the fix taken back out (they must fail) and with it in place (they must pass). Tests that pass either way prove nothing, and it says so. If the agent wrote no test, a test-only step writes one first, so nearly every fix gets proven.
- 🏆 Fix tournament. With
--candidates 3, independent fixes compete, each with its own strategy: direct, test first, or graph first. They are judged on evidence: their proofs, their confidence scores, and cross-examination, where every fix must also pass its rivals' tests. A patch that only fixes the reported symptom loses to one that fixes the root cause. - 👻 Poltergeist. A second agent that may only write tests then tries to break the winner.
- The proof ships with the pull request: the red and green test results, the confidence score and the tournament table are in its description.
It hunts bugs while you sleep
- Haunt mode (
ghostpatch haunt) finds bugs nobody has reported. It ranks every function by risk (how many places call it, whether any test reaches it, how often its file changed lately) and sends a haunter that may only write tests at the riskiest ones. GhostPatch runs those tests itself, and a skeptic, a separate model call with no stake in the claim, must agree that a failing test reflects what the code is meant to do before the bug counts. Every confirmed bug comes with its failing test as proof, and one click fixes it. - Night shift (
ghostpatch nightshift) works through every open issue labelledghostpatch. It opens a pull request for each fix it can prove, rolls back the ones it can't, haunts for new bugs, and leaves a morning report. On GitHub Actions it runs every night for free. - Label an issue, get a pull request. With the GitHub Action, adding the
ghostpatchlabel to an issue is all it takes.
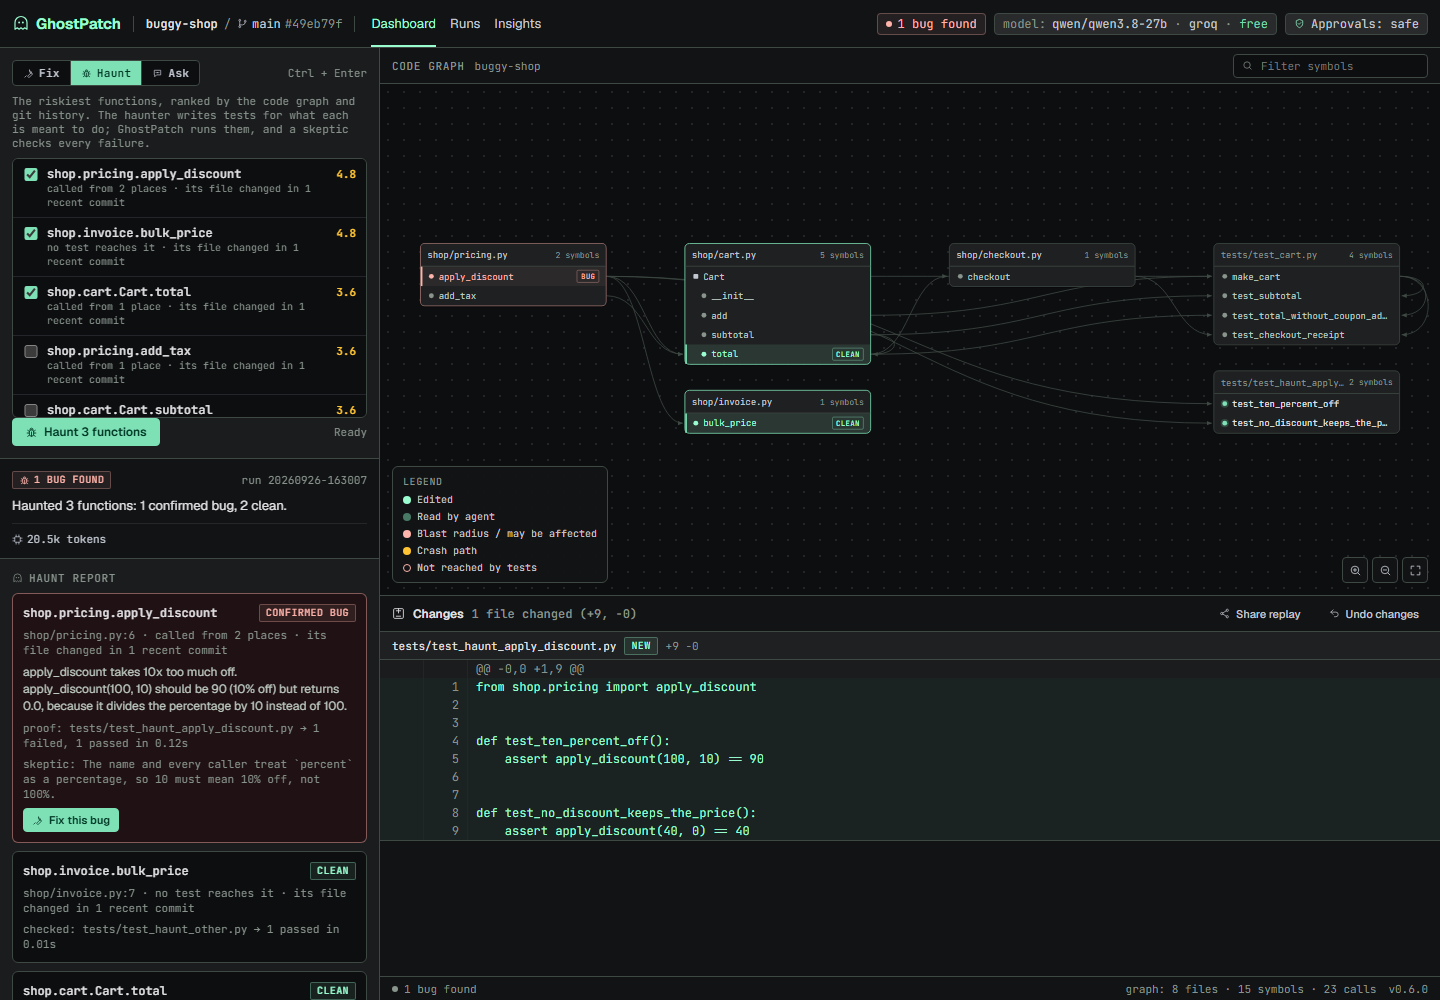
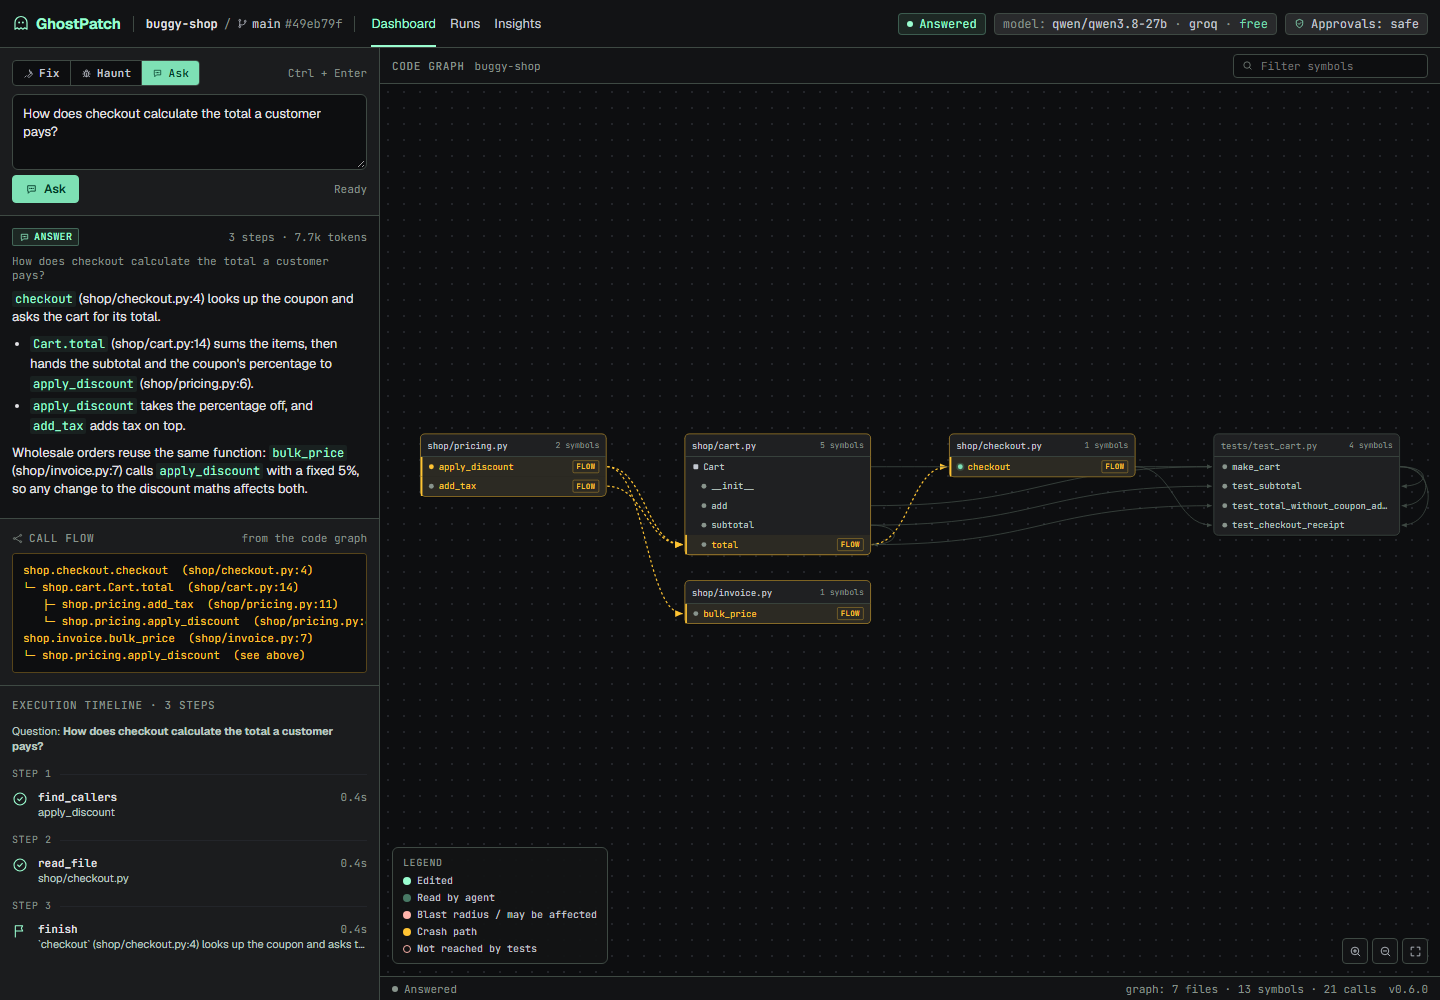
Left: haunt mode found the coupon bug without being told about it. Right: ask mode answers from the code and draws the real call flow.
Ask it anything
ghostpatch ask "How does checkout calculate the total?" answers from the code with a
read-only agent that cites path:line. GhostPatch then draws the call flow between the
functions the answer mentions, taken from the code graph rather than the model's memory, and
highlights it in the dashboard.
See it work
GhostPatch has been tested end to end on three demo projects, using free models:
| Bug | Language | What GhostPatch did | Steps | Cost |
|---|---|---|---|---|
average() returns the wrong mean |
Python | Found the off-by-one slice, fixed it, added 3 tests | 9 | $0 |
| A 10% coupon charges customers $0.00 | Python, 5 files | Traced checkout → cart → pricing, fixed / 10 → / 100, flagged that bulk invoicing shares the function, added coupon tests |
9–13 | $0 |
| Buying 3 mugs only charges for 1 | TypeScript | Fixed the subtotal, flagged the free-shipping rule as affected, added a regression test, ran node --test |
7 | $0 |
What the agent sees right after its edit in the second case, generated by the code graph:
🕸 Code graph: you changed shop.pricing.apply_discount.
Changing 'apply_discount' may affect:
  direct callers:
    shop/cart.py:15  in shop.cart.Cart.total
    shop/invoice.py:11  in shop.invoice.bulk_price
  callers of those:
    shop/checkout.py:7  in shop.checkout.checkout
  tests to run: tests/test_cart.py::test_checkout_receipt, tests/test_cart.py::test_total_without_coupon_adds_tax
Benchmark
bench/ holds 31 realistic bug cases (17 Python, 8 TypeScript, 2 each in Go, Rust and Java). Each is
judged by hidden tests the
agent never sees, and many are traps where fixing only the symptom fails: a helper shared by
receipts and the CSV export, a function that quietly compensates for the bug, a shared default that
must not be mutated. ghostpatch bench --validate checks that every case is sound (its hidden tests
fail on the buggy code and pass with the reference fix).
Where to look first, measured without any model (ghostpatch bench --localize): the function
the reference fix changes is GhostPatch's top suspect in 18/31 cases, in the top 3 in 29/31
and in the top 5 (whose source the agent receives) in 31/31. The six Go, Rust and Java cases were
added after the ranker was written and measured without changing it: five rank the bug first.
End to end with a real model: the first 5 cases, on the free qwen/qwen3.8-27b via Groq (from
before the regression guard and where-to-look were added):
| Case | with graph | without graph |
|---|---|---|
py-calculator |
✅ 7 steps | ✅ 6 steps |
py-deep-merge (trap) |
✅ 6 steps | ✅ 6 steps |
py-mutable-default |
✅ 5 steps | ✅ 7 steps |
py-pagination |
✅ 5 steps | ✅ 6 steps |
py-price-format (trap) |
✅ 4 steps | ✅ 7 steps |
| Solved | 5/5 | 5/5 |
Both settings solved every case so far. With the graph the agent needed 16% fewer steps (27 vs 32)
but used 8% more tokens (75.6k vs 69.9k), because the repository map and impact reports add
context. The remaining cases run as the free daily quota allows: ghostpatch bench --compare
resumes where it stopped, and ghostpatch bench --report prints the table.
ghostpatch bench --full judges GhostPatch's whole fixing session instead of the bare agent
(where to look first, the regression guard, the regression-test writer and the proof). Its first
real run solved py-count-compensated, a trap where a caller quietly compensates for the bug, in
6 steps; the other cases are waiting on the free quota.
The core loop
flowchart LR
    R([Bug report]) --> L[Rank suspects<br/>graph + report]
    L --> B[Baseline:<br/>whole test suite]
    B --> F[Agent fixes<br/>or a tournament]
    F --> G{Regression guard:<br/>anything broken?}
    G -- yes, back to the agent --> F
    G -- no --> T[Write a test<br/>if there is none]
    T --> P[Red-green proof]
    P --> C[Confidence score<br/>and saved run]
Features
🕸 Living code graph. Python, JavaScript, TypeScript, Go, Rust and Java are parsed into symbols
and calls, stored in SQLite and re-indexed incrementally: only changed files are re-parsed. Tests
are recognised the way each language marks them (JS/TS test("adds tax", () => …) blocks, Go
TestXxx functions, Rust #[test] and #[cfg(test)] modules, JUnit @Test methods), so impact
reports name real tests.
🧰 Every language's own tools. GhostPatch runs pytest, node --test / npm test, go test,
cargo test, Maven and Gradle (or the project's mvnw / gradlew), reads which tests failed
from each one's output for the regression guard, and runs just the new tests for the proof: by
package in Go, by --test target or module in Rust, by class in Java. Rust unit tests usually sit
in the file they test, so the proof takes the fix out of that file while keeping the new test in.
🤖 Autonomous agent loop. The agent explores, reproduces the bug, fixes the root cause,
verifies it with the project's own tests and writes a summary. It has 15 tools, from
read_file and replace_lines to impact_of_change and remember.
👻 Live dashboard. ghostpatch serve streams the agent's work to the browser as it
happens: every file read, every edit as a diff, every test run. The code graph lights up in
real time, and commands can be approved or denied with a click.
💸 Free by default. Works with Groq, OpenRouter, Google Gemini and local Ollama models at
no cost, or OpenAI when you want more power. It is built for free-tier realities: it waits out
per-minute limits, switches provider when a daily quota runs out, and shortens old tool output so
each request stays small. Any other OpenAI-compatible server (Ollama on another machine, LM Studio,
vLLM) works too: set GHOSTPATCH_BASE_URL.
⬆ GitHub-native. Point it at an issue link and it reads the issue, fixes it and opens a pull
request that says Fixes #42, committing only its own changes on a fresh branch. It works
through the GitHub CLI, so it never touches a GitHub token.
↩ Undo anything. Every run is recorded with the before-and-after content of each file it
touched. ghostpatch undo, or one click in the dashboard, puts everything back, including
deleting files the run created. It refuses to overwrite edits you made afterwards unless you insist.
More superpowers
| Feature | What it does | |
|---|---|---|
| 👻 | Poltergeist mode | After a fix, an adversarial agent that may only write tests tries to break it, armed with the diff and the fix's blast radius. If it succeeds, the ghost gets its failing tests and fixes the code again. --poltergeist |
| 🧭 | Crash-to-graph tracing | Paste a Python, Node/TypeScript or Java stack trace, or a Go or Rust panic, and it is mapped onto the code graph: the ghost starts from the exact crash path, and the dashboard can animate it. ghostpatch trace |
| 🩺 | Blast-radius PR review | For any change, including pull requests written by people: which functions changed, what else they affect, and which of those no test reaches. ghostpatch review 42 --post |
| 🤖 | CI auto-fixer | When CI goes red, GhostPatch fixes the code, re-runs the tests itself, then opens a pull request. Ships as a GitHub Action. ghostpatch ci-fix |
| 🎬 | Replay and share | Every run is recorded step by step. Export one as a single HTML page with a replay scrubber that anyone can open. ghostpatch share |
| 🕳 | Test-gap map | Every function no test reaches, and one command to have the ghost write tests for them. ghostpatch gaps --write-tests 5 |
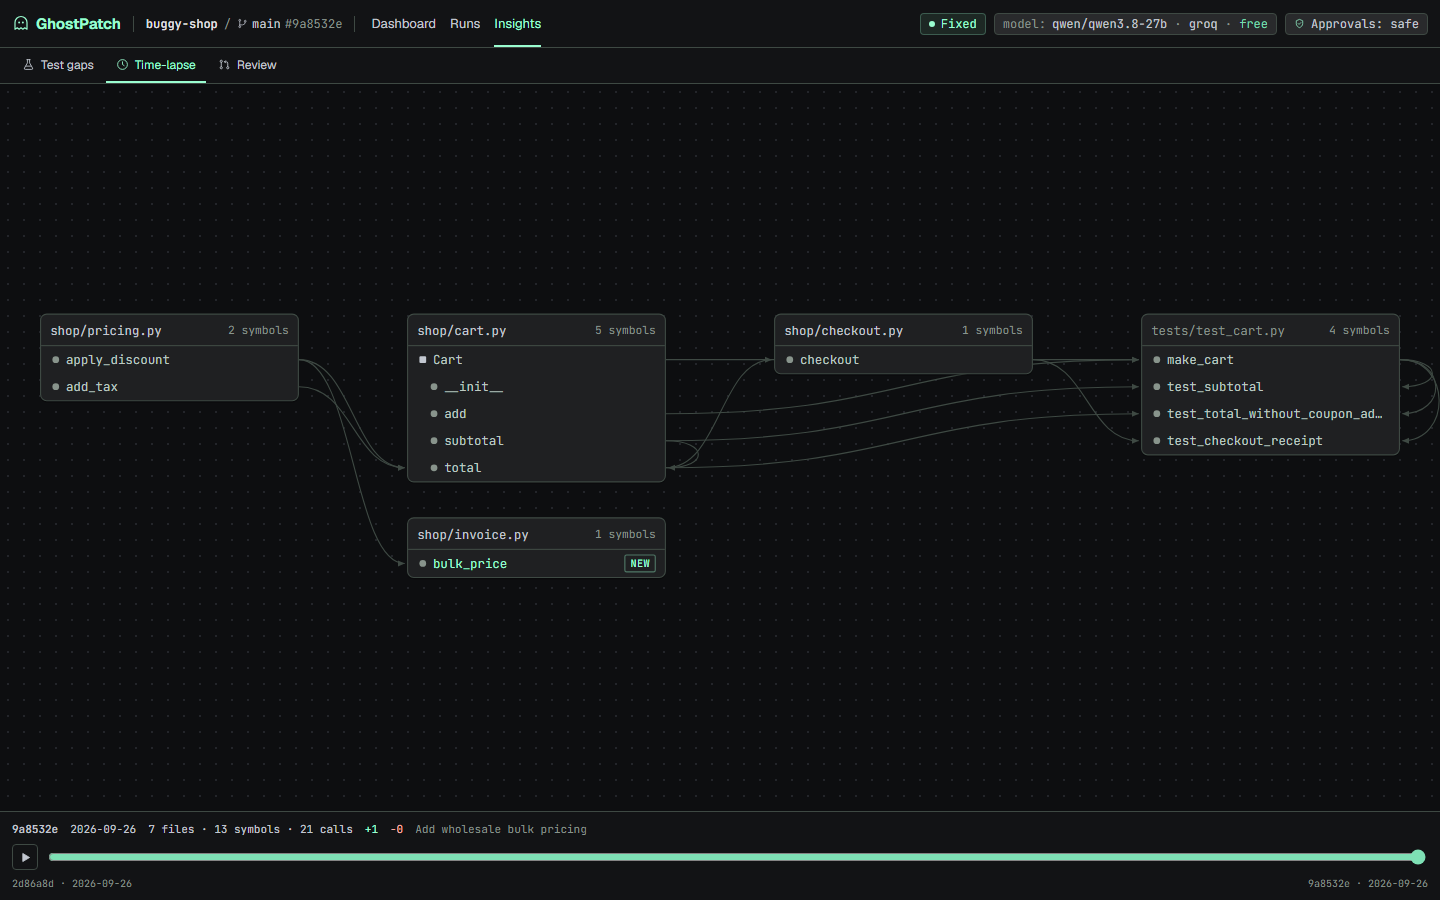
| ⏳ | Architecture time-lapse | The code graph at each of the last N commits, read straight from git, with what appeared and disappeared. ghostpatch timelapse |
| 🔀 | Free-model fallback | When one provider's daily quota runs out mid-fix, it switches to the next free provider and carries on with the same conversation. |
| 🧠 | Repo memory | Team conventions in GHOSTPATCH.md, plus facts the ghost learns as it works, fed into every run. ghostpatch memory |
| 📊 | Confidence score | Every fix gets 0 to 100: did the tests pass after the last edit, and how much of the blast radius do tests actually reach? |
🛡 Safe by design. File access is confined to the repository and nothing is committed or
pushed. Commands follow an approval mode: ask (always ask), safe (recognised test and
read-only git commands run automatically; anything that chains, redirects or substitutes
commands still asks) or all (for sandboxes). The dashboard binds to 127.0.0.1, rejects
cross-site requests and checks the Host header against DNS rebinding.
Architecture
flowchart LR
    U([Bug report]) --> CLI[CLI / Dashboard]
    CLI --> A[Agent loop]
    A <-->|tool calls| LLM[(LLM<br/>Groq · OpenRouter · Gemini · Ollama · OpenAI)]
    A --> T[Workspace tools<br/>read · search · edit · run]
    T --> G[Code graph<br/>SQLite]
    P[Parsers<br/>Python ast · tree-sitter JS/TS] --> G
    T -->|after every edit| I[Impact report]
    G --> I
    I --> A
    A -->|events| D[Live dashboard<br/>Server-Sent Events]
| Module | Responsibility |
|---|---|
agent.py |
The reasoning loop: asks the model for the next action, executes it, feeds back the result |
session.py |
One fixing session end to end: suspects, baseline, the ghost or a tournament, regression guard, proof, confidence, history |
locate.py |
Where to look first: ranks the code most likely at fault |
regression.py |
The regression guard: the whole suite before and after, and what broke |
proof.py |
Red-green proof, and the step that writes a regression test when there is none |
tournament.py |
Competing candidate fixes, cross-examined with each other's tests |
haunt.py |
Risk ranking, the haunter, and the skeptic that confirms each bug |
nightshift.py |
The unattended issue queue, pull requests and the morning report |
ask.py |
Read-only answers and the call flow they describe |
tools.py |
The agent's hands: sandboxed file access, edits, commands, graph queries, impact notes |
graph.py |
The living graph: incremental SQLite index, callers, related tests, change impact |
linker.py |
Links each call to the function it means, by each language's rules (imports, packages, crates, types) |
parsers.py |
Turns Python (ast) and JS/TS (tree-sitter) into symbols, calls and imports |
parsers_typed.py |
The same for Go, Rust and Java, plus the types the code states (cart *Cart, Cart::new()) |
server.py + web/ |
The dashboard: standard-library HTTP server and a dependency-free single-page UI |
providers.py |
One OpenAI-compatible client for every model provider |
Engineering notes
A few problems that shaped the design:
-
Free models are messy. They invent argument names (
line_endforend_line), prefix tool names (repo_browser.read_file), emit malformed JSON, and announce "done" in plain text instead of callingfinish. GhostPatch normalises all of these instead of failing, which is what lets small free models complete real multi-file fixes. -
Models don't always use the tools they're given. Early runs showed a free model ignoring the graph tools entirely. Rather than prompting harder, the impact report is now pushed after every edit, so the graph's knowledge reaches the model regardless.
-
Graph identity has to survive edits. Re-indexing a file gives its symbols new database IDs, so the dashboard tracks highlights by fully qualified name, not by ID.
-
Anonymous test callbacks are invisible to call graphs. In JavaScript,
test("…", () => {…})has no function name, so tests would never appear as callers. The parser turns test and suite blocks into named symbols. -
Matching calls by name is not enough. Every
total()looked like it called every function namedtotal, which made impact reports noisy. Calls are now resolved through imports, module aliases, decorators andself/this; only calls on unknown objects fall back to the name, and are labelled as guesses. In Go, Rust and Java the code states types outright, so a call on a typed parameter or variable is resolved exactly, and calls into the standard library get no link at all instead of a wrong one. -
Each language hides its tests somewhere else. Go runs tests a package (folder) at a time, Rust keeps unit tests inside the source file, and Java needs a class to match its file name. That shaped the proof and the tournament: rival tests are swapped in at their own paths rather than renamed, and a Rust file whose test module changed counts as a test.
-
Macros hide calls. Rust's
assert_eq!(total(&cart), 3)is how tests call code, but to a parser a macro's arguments are raw tokens. They are parsed again as an expression. -
"The tests pass" can hide breakage. An agent often runs only its own new test. The regression guard runs the whole suite before and after, so a fix that breaks something elsewhere is caught and handed back, instead of shipped.
-
No build step, no heavy dependencies. The dashboard is plain HTML, CSS and JS with a hand-written force-directed graph layout, served by Python's standard library.
-
Big repositories expose what small ones hide. On Tokio, a call like
x.new()on a value of unknown type was linked to every method namednew: 609,000 links for 45,000 calls, 2% of them certain, and every edit relinked everything (7 s). Now a name shared by many functions gets no guess, a call links to one overload of a method, a library copied into two folders resolves to the nearest copy, and an edit relinks only the calls it can affect. Measured on real projects:Project Files First index Re-check, no change After one edit Where to look Tokio (Rust) 807 3.9 s 0.02 s 0.10 s 1.7 s Prometheus (Go) 990 7.7 s 0.04 s 0.17 s 4.0 s NestJS (TypeScript) 2,003 3.6 s 0.09 s 0.24 s 1.8 s Django (Python) 2,977 18.9 s 0.36 s 0.80 s 6.6 s Guava (Java) 3,275 21.5 s 0.06 s 1.18 s 9.5 s -
An agent reads text anyone can write. Issues, comments and stack traces can carry instructions. So the ghost can't touch
.git/,.ghostpatch/or.envfiles, its commands run without API keys or GitHub tokens, secrets are redacted from everything GhostPatch publishes, "safe" commands can't reach outside the project, and only maintainers' comments reach it. See SECURITY.md.
Tech stack
Python · SQLite · tree-sitter · OpenAI-compatible APIs (Groq, OpenRouter, Gemini, Ollama, OpenAI) ·
Server-Sent Events · vanilla HTML/CSS/JS with SVG · pytest (313 tests, using a scripted
fake model, a fake OpenAI-compatible server for end-to-end runs of the real CLI, and a fake GitHub CLI,
so the suite needs no API key or network; Go, Rust and Java fixes are tested end to end with the real
go, cargo and Maven) · GitHub Actions CI on Windows, macOS and Linux, including a run of the
GhostPatch Action itself
Roadmap
- Autonomous bug-fixing agent with sandboxed tools
- Living code graph with automatic impact reports
- JavaScript and TypeScript support
- Live web dashboard
- Free model providers
- Undo, run history, approval modes,
initanddoctor - CI on Windows, macOS and Linux
- GitHub integration: issue in, pull request out
- Poltergeist mode, crash tracing, PR review, CI auto-fix, replay, test gaps, time-lapse, fallback, memory, confidence
- Free-tier survival: provider fallback, readable quota errors, shortened history
- Red-green proof, fix tournament, haunt mode, night shift, ask the graph
- Label an issue, get a pull request (GitHub Action)
- Go, Rust and Java
- Security review and hardening; tested on large real-world repositories
- Isolated git worktree for every run
- Public benchmark results on SWE-bench
Running it
New to GhostPatch? The user guide walks through everything step by step: installing, getting free API keys and where they're stored, every screen and command, GitHub automation, and troubleshooting.
pipx install ghostpatch            # or: uv tool install ghostpatch, or pip install ghostpatch
ghostpatch init                    # pick a free provider, paste a key, add a backup key
ghostpatch doctor                  # check everything is ready
ghostpatch serve                   # the dashboard, at http://localhost:8765
Keys are saved once in your user settings, so they work in every project. Free keys: Groq, OpenRouter and Gemini. Setting up two means a run carries on when one provider's daily quota runs out.
| Command | What it does |
|---|---|
ghostpatch serve |
Live dashboard: describe a bug, watch it get fixed, undo with a click |
ghostpatch fix "…" |
Fix a bug from the terminal (@ISSUE.md reads the description from a file) |
ghostpatch fix "…" --candidates 3 |
A fix tournament: three independent fixes compete and the best-proven one wins |
ghostpatch fix <issue link> --pr |
Fix a GitHub issue and open a pull request when the fix is verified |
ghostpatch haunt |
Hunt for unreported bugs in the riskiest functions (--list shows the ranking, --fix fixes them) |
ghostpatch nightshift --approve safe |
Fix every issue labelled ghostpatch, haunt, and write a morning report |
ghostpatch ask "…" |
Ask a question about the code; get an answer and the real call flow |
ghostpatch pr |
Open a pull request for the latest run (or any run) |
ghostpatch history / undo |
List past runs / roll one back |
ghostpatch graph impact NAME |
Ask the code graph what a change would affect (also map, callers, tests, …) |
ghostpatch review [PR] |
Blast-radius review of your changes or a pull request (--post comments on it) |
ghostpatch trace crash.txt --fix |
Map a stack trace onto the code graph, then fix the crash |
ghostpatch gaps |
Functions no test reaches (--write-tests N has the ghost cover them) |
ghostpatch ci-fix --mode pr |
For CI: if the tests fail, fix them and open a pull request |
ghostpatch share / timelapse / memory |
Export a run as HTML / replay the architecture / show what it remembers |
ghostpatch bench --compare |
Run the benchmark with and without the code graph (--full runs the whole session, --localize needs no model) |
ghostpatch workflow nightshift --write |
Add a GitHub Actions workflow (ci, issues or nightshift) to the repository |
ghostpatch init / doctor |
Set up a provider and key / check the setup |
Add --approve safe to let test runs go ahead without asking, and --poltergeist to have every
fix attacked before you see it. In the dashboard, the Setup view shows the model, the fallback
chain, the health checks and the repo memory, and adds GitHub workflows in one click.
On GitHub, for free, add one of these to .github/workflows/ (or run ghostpatch workflow):
fix failing CI,
label an issue, get a pull request or
the nightly night shift.
More detail in CONTRIBUTING.md.
License
1 maintainer

Release files for ghostpatch 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ghostpatch-0.9.0.tar.gz | 279.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ghostpatch-0.9.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 480.8 kB
Release files / ghostpatch-0.9.0.tar.gz
| Download URL | ghostpatch-0.9.0.tar.gz |
|---|---|
| Size | 279.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e8cc99118f62ad876ab3f226dd8b83c61d4d5656ac08321adb48da9ab691c051
|
|
BLAKE2b-256 checksum How to use checksums |
f9c9e4bd4d2202bb03f0a7ce6bd9e49fb3b722f4a9d4c992ca3e4977186e22da
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 27, 2026.
Transparency logRelease files / ghostpatch-0.9.0-py3-none-any.whl
| Download URL | ghostpatch-0.9.0-py3-none-any.whl |
|---|---|
| Size | 201.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6147d00be8a2cfc5a9469aecbf3366a0fc669e7f6a26f62917279a88bee0b38a
|
|
BLAKE2b-256 checksum How to use checksums |
b2f5742fdfa591a616c9ace730a31448221bcfe08681a55562744b76e4af8c6d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 27, 2026.
Transparency log












