
Giga Embeddings 0826 for Apple Silicon — MLX
Run private, local text embeddings for Russian and English semantic search,
RAG, clustering, classification, and similarity on Apple Silicon Macs. This
project provides a native MLX runtime and
three tested Q8 versions of the Giga Embeddings 0826 family—without PyTorch,
a cloud API, or Python code from model repositories during normal inference.
PyPI · MLX models · Original paper · Full MLX benchmark · Latest release
Why this MLX port?
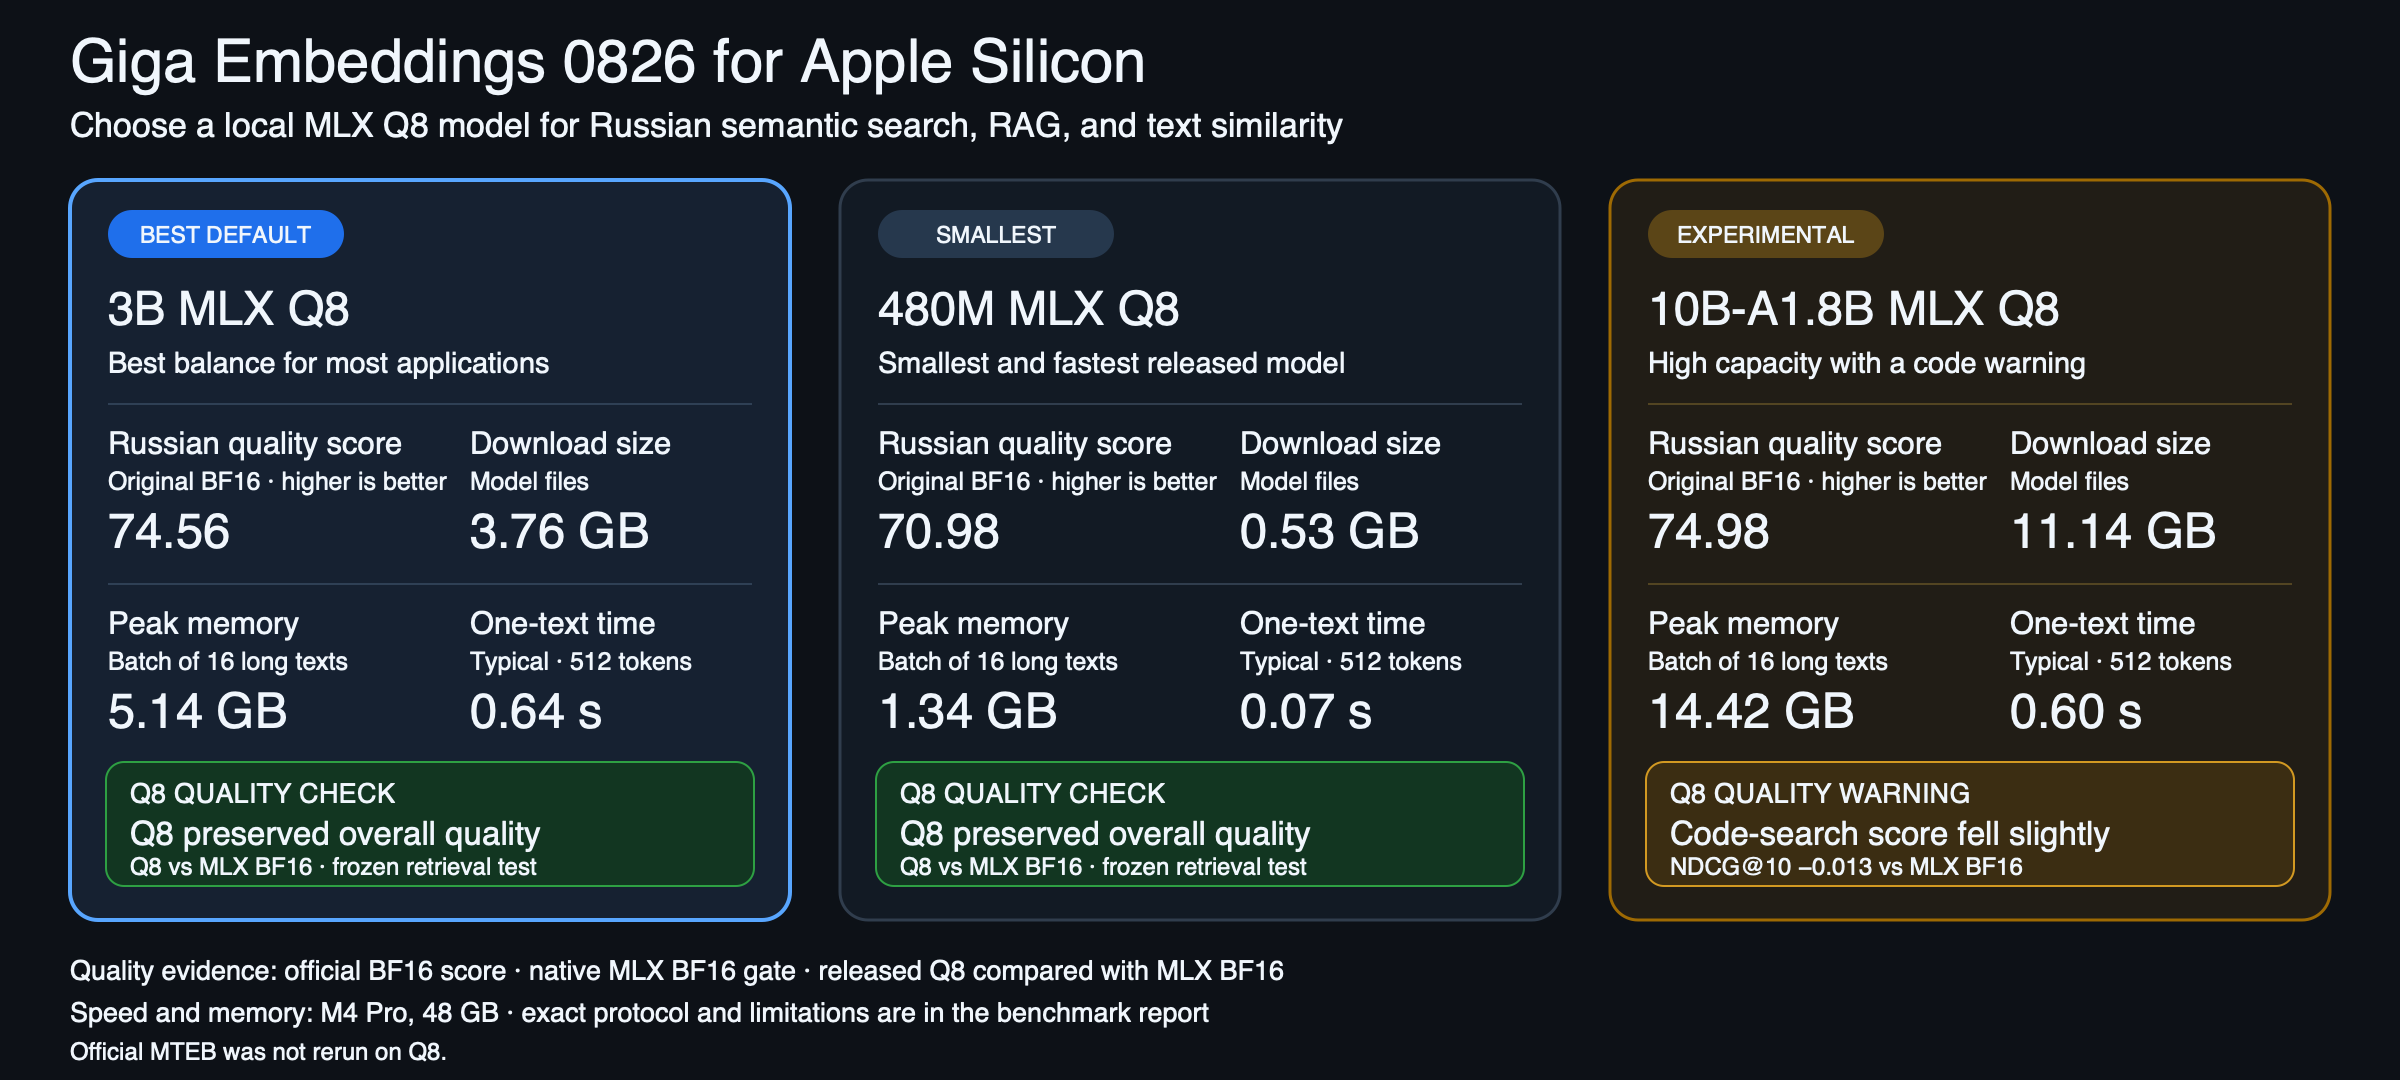
- The original models score from 70.98 to 74.98 on Russian MTEB in the authors' evaluation.
- Our separate tests verify the native MLX BF16 port and measure what changes after Q8 quantization. The released 480M and 3B models showed no aggregate retrieval regression on the frozen evaluation set.
- The recommended 3B model downloads as 3.76 GB and peaked at 5.14 GB of Metal memory in our test, versus 6.31 GB and 7.69 GB for its BF16 baseline.
- A Python API, command-line tool, offline cache, and local OpenAI-compatible
/v1/embeddingsendpoint are included.
This is an independent ai-babai port, not an
official ai-sage release.
Install and try it
Requires an Apple Silicon Mac, macOS, and Python 3.12 or 3.13.
python -m pip install giga-embeddings-mlx
Documents are encoded as-is. Retrieval queries require an explicit instruction:
from giga_embeddings_mlx import load_embedding_model

model = load_embedding_model("default")

documents = model.encode_documents(
    [
        "Москва — столица России.",
        "Париж — столица Франции.",
    ]
)
queries = model.encode_queries(
    "Где находится Москва?",
    instruction="Given a question, retrieve passages that answer the question",
)

scores = queries @ documents.T
print(scores.tolist())
default is the recommended 3B Q8 model. It downloads from Hugging Face on
first use and then reuses the local cache.
Choose an MLX model
| MLX model | Best for | Original Russian MTEB¹ | Our Q8 retrieval check² | Download | Peak memory³ |
|---|---|---|---|---|---|
| 3B MLX Q8 | recommended default | 74.56 | NDCG@10 Δ +0.00181 | 3.755 GB | 5.137 GB |
| 480M Q8 | smallest and fastest | 70.98 | NDCG@10 Δ +0.00289 | 0.525 GB | 1.339 GB |
| 10B-A1.8B Q8 | high-capacity research | 74.98 | aggregate Δ −0.00046 | 11.144 GB | 14.423 GB |
- The original authors' task-macro MTEB score from the Giga-Embeddings paper. It was measured on the original BF16 model, not rerun on our Q8 artifact.
- Q8 minus native MLX BF16 on our separate frozen retrieval set. A small positive value is evidence of no measured regression, not an improvement claim.
- Peak Metal allocation while embedding a batch of 16 texts, each 1024 tokens long, on an M4 Pro with 48 GB unified memory.
The 10B Q8 model passed the aggregate gate, but its code-retrieval NDCG@10
changed by −0.01297. It is deliberately marked as research rather than the
default.
Choose a model without remembering its repository name:
giga-embeddings-mlx models
giga-embeddings-mlx encode "Москва — столица России." --document
giga-embeddings-mlx encode "Где находится Москва?" \
  --instruction "Given a question, retrieve passages that answer the question"
How much original quality is retained?
The original paper reports task-macro MTEB scores over 41 English, 23 Russian, 131 multilingual, and 12 code tasks:
| Original BF16 model | English | Russian | Multilingual | Code |
|---|---|---|---|---|
| 480M | 69.52 | 70.98 | 56.97 | 72.87 |
| 3B | 71.93 | 74.56 | 63.89 | 76.93 |
| 10B-A1.8B | 72.23 | 74.98 | 65.64 | 78.41 |
Source: Giga-Embeddings: Mixture-of-Experts Encoders for High-Throughput Text Embeddings. The paper notes that each model was evaluated once, so sub-one-point differences should be interpreted cautiously.
We did not present the Q8 artifacts as fresh official MTEB submissions. Instead, we tested the two transformations that matter for this port:
| Model family | Original BF16 → MLX BF16 | MLX BF16 → released Q8 | Worst measured Q8 family |
|---|---|---|---|
| 480M | retrieval gate passed | NDCG@10 Δ +0.00289 | +0.00000 |
| 3B | retrieval gate passed | NDCG@10 Δ +0.00181 | −0.00048 |
| 10B-A1.8B | retrieval gate passed | aggregate NDCG@10 Δ −0.00046 | code: −0.01297 |
This evidence supports quality preservation on our frozen Russian, English, code, and multilingual evaluation lanes; it does not turn the local test into an official MTEB run. Full vector, ranking, family, and downstream measurements are in the MLX benchmark report.
Speed and memory in plain language
Measured on a MacBook Pro with Apple M4 Pro and 48 GB unified memory. Each speed result uses 2 warmups and 5 measured repetitions.
| MLX model | Typical time for one 512-token text | Speed for 16 long texts | Peak memory for 16 long texts |
|---|---|---|---|
| 480M Q8 | 0.071 s | 6.38 documents/s | 1.339 GB |
| 3B Q8 | 0.637 s | 0.73 documents/s | 5.137 GB |
| 10B-A1.8B Q8 | 0.597 s | 0.76 documents/s | 14.423 GB |
“Long text” here means 1024 tokens. Tokens are pieces of text used by the model, not necessarily whole words. Q8 reduced disk and peak Metal memory by roughly 25–40% for these releases, but was 12–19% slower than BF16 in the 16-text test. Choose Q8 primarily to fit a useful model on a Mac, not as a guaranteed speed-up.
The complete report includes median and p95 latency, load time, documents/s, tokens/s, process memory, Metal memory, quality deltas, commands, and evidence hashes.
Original BF16 models through MLX
The same runtime can load the exact original BF16 weights without republishing
them under ai-babai:
| Runtime alias | Original model | Download |
|---|---|---|
480m-bf16 |
ai-sage/Giga-Embeddings-instruct-480M-0826 | 1.0 GB |
3b-bf16 |
ai-sage/Giga-Embeddings-instruct-3B-0826 | 6.3 GB |
10b-a1.8b-bf16 |
ai-sage/Giga-Embeddings-instruct-10B-A1.8B-0826 | 21.0 GB |
The MLX Collection contains only the three ready-to-use MLX Q8 artifacts. Original weights remain linked here and in each model card as the source and quality baseline.
Explicit repositories and local artifacts
Aliases, an explicit Hugging Face repository/revision, and a local directory share the same loader:
from pathlib import Path

from giga_embeddings_mlx import load_embedding_model

model = load_embedding_model("480m-q8")
model = load_embedding_model(
    "owner/repository",
    revision="immutable-commit-or-tag",
    cache_dir=Path("models-cache"),
)
model = load_embedding_model(Path("portable-model-directory"))
The built-in aliases resolve to exact verified commits. Human-readable tags identify releases, while immutable commits protect runtime reproducibility.
Cache and offline use
model = load_embedding_model("3b-q8", cache_dir="models-cache")
model = load_embedding_model(
    "3b-q8",
    cache_dir="models-cache",
    local_files_only=True,
)
CLI equivalents are --cache-dir models-cache and --offline. Only remove a
cache directory that you deliberately dedicated to this project; do not delete
the global Hugging Face cache merely to remove one model.
Before loading, the runtime compares artifact size with physical unified memory
using a conservative reserve. Choose a smaller model if the preflight fails.
skip_memory_check=True / --skip-memory-check is an explicit escape hatch for
users willing to accept swap or out-of-memory risk.
Local OpenAI-compatible endpoint
python -m pip install 'giga-embeddings-mlx[server]'
giga-embeddings-mlx serve --model default --served-model-name giga-3b
The endpoint is POST /v1/embeddings. Input without instruction is treated as
a document. A query must provide its instruction explicitly:
curl http://127.0.0.1:8000/v1/embeddings \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "giga-3b",
    "input": ["Где находится Москва?"],
    "instruction": "Given a question, retrieve passages that answer the question"
  }'
The server supports float and base64 output. Dimension truncation is not
supported because the 0826 models do not claim Matryoshka training. One
process serves one model and serializes Metal inference.
Compatibility and limitations
- Apple Silicon/macOS only; use the original runtime elsewhere.
- Maximum sequence length is 8192, but memory grows with batch and text length.
- Q8 is not guaranteed to be faster than BF16 on Metal.
- The 10B Q8 code-retrieval warning is material; prefer 3B for general use.
- This package does not silently truncate embedding dimensions.
- Output-vector
uint8or binary compression is a separate index-storage choice and is not performed by the weight loader. - The local quality benchmark is not an official upstream leaderboard result.
Development, license, and citation
Conversion and evaluation remain developer-facing and are not exposed by the end-user CLI. See CONTRIBUTING.md, docs/EVALUATION.md, and SECURITY.md.
The independent MLX runtime is MIT-licensed. Original model licenses and notices remain attached to their repositories; see THIRD_PARTY_NOTICES.md. Cite the original Giga-Embeddings paper and this software using CITATION.cff.
1 maintainer

Metadata
1 maintainer
Release files for giga-embeddings-mlx 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| giga_embeddings_mlx-0.1.2.tar.gz | 602.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| giga_embeddings_mlx-0.1.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 623.6 kB
Release files / giga_embeddings_mlx-0.1.2.tar.gz
| Download URL | giga_embeddings_mlx-0.1.2.tar.gz |
|---|---|
| Size | 602.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3797987aa9834afbdfab8174f650c056c6885629ef7e3efb9d00eb58e7bbcf83
|
|
BLAKE2b-256 checksum How to use checksums |
49fd21bb8f8b7ad7b48b1afc929333f617130c7e1e47aea7904be9c33f059537
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 26, 2026.
Transparency logRelease files / giga_embeddings_mlx-0.1.2-py3-none-any.whl
| Download URL | giga_embeddings_mlx-0.1.2-py3-none-any.whl |
|---|---|
| Size | 20.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
edb68db281c2b6b3ea16508e0438fc2a071abe51cb8d5ce206a0b12e59dec202
|
|
BLAKE2b-256 checksum How to use checksums |
db9163a6cec50c37aa4473e947563a76f216f4846f57f26052e96c73850e0065
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 26, 2026.
Transparency log













