
GigaAM-Multilingual MLX
English · Русский
Fast, offline speech-to-text for Russian, Kazakh, Kyrgyz, and Uzbek on Apple Silicon. This is an independent native MLX port of GigaAM, based on the official GigaAM-Multilingual model.
PyPI · Hugging Face models · Latest release · Full benchmark
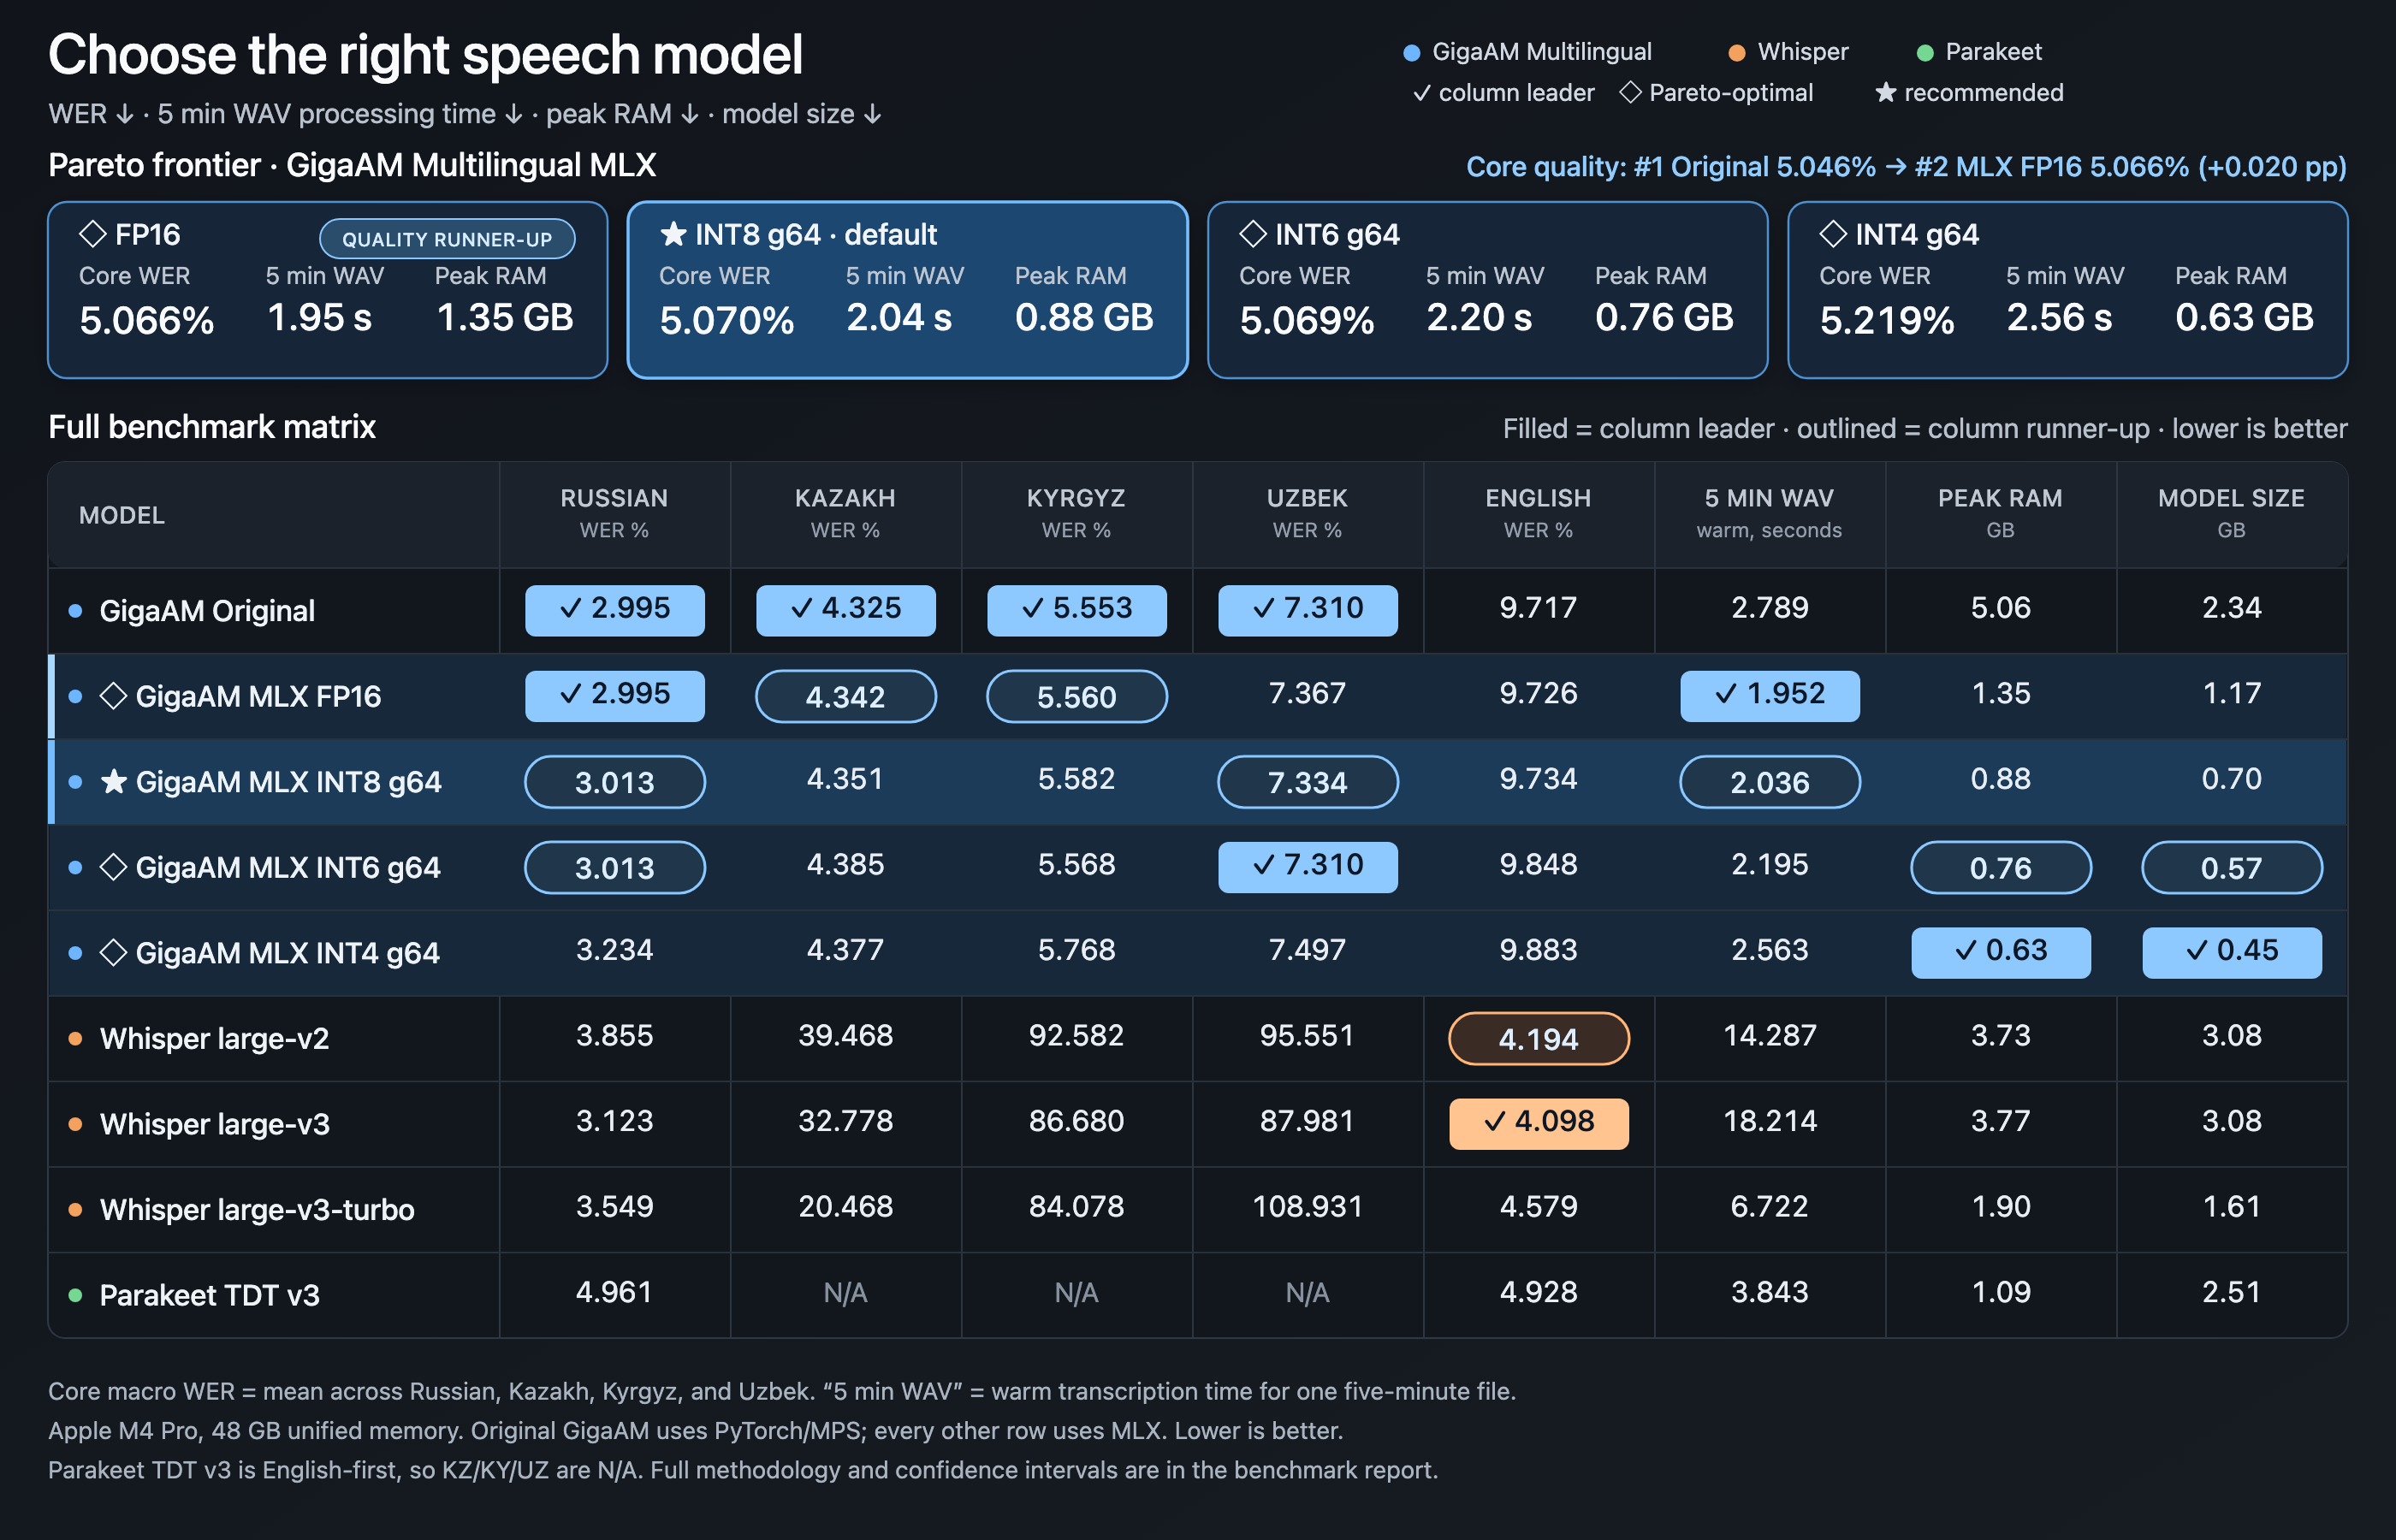
The chart compares WER, five-minute transcription time, peak process memory, and
model size. Filled pills mark column leaders, outlined pills mark runners-up,
◇ marks the Pareto frontier, and ★ the recommended default. Lower is better.
Quick start
Requires an Apple Silicon Mac, macOS 14+, Python 3.12 or 3.13,
uv, and
ffmpeg.
brew install uv ffmpeg
uv tool install gigaam-multilingual-mlx
gigaam-stt meeting.m4a --output transcript.txt
For a uv-managed Python project:
uv add gigaam-multilingual-mlx
pip install gigaam-multilingual-mlx and the long
gigaam-multilingual-mlx transcribe ... command remain supported.
Local transcription server
Use GigaAM MLX with applications that support the OpenAI transcription API:
uv tool install 'gigaam-multilingual-mlx[server]'
gigaam-stt serve
The server is now available at http://127.0.0.1:8000/v1:
curl http://127.0.0.1:8000/v1/audio/transcriptions \
  -F model=whisper-1 \
  -F file=@meeting.m4a
The same endpoint works with the OpenAI Python client (uv add openai):
from pathlib import Path
from openai import OpenAI

client = OpenAI(base_url="http://127.0.0.1:8000/v1", api_key="local")
with Path("meeting.m4a").open("rb") as audio:
    result = client.audio.transcriptions.create(model="whisper-1", file=audio)
print(result.text)
whisper-1 is a compatibility alias; the server still runs GigaAM
Multilingual MLX. It is local-only by default. See the
server guide
for formats, model IDs, network access, configuration, and troubleshooting.
Why this port?
- Native MLX inference without PyTorch, ONNX Runtime, Core ML, or a cloud API.
- Strong measured quality for the four core GigaAM languages, especially Kazakh, Kyrgyz, and Uzbek.
- A 699 MB default model that used 0.877 GB peak process memory in the published five-minute benchmark.
- Local WAV, FLAC, MP3, M4A, and video transcription to TXT, JSON, SRT, or VTT.
On the tested Russian five-minute input, INT8 was 3.30× faster than Whisper v3 Turbo, 7.02× faster than Whisper large-v2, and 8.94× faster than Whisper large-v3. Whisper and Parakeet were better on the English appendix. These are single-machine public-corpus results, not a universal ASR leaderboard; see the full report for confidence intervals, commands, hashes, and limitations.
Model variants
| Variant | Recommended use | Model size | Peak RAM | Hugging Face |
|---|---|---|---|---|
| INT8 g64 | default balance | 699 MB | 0.88 GB | ai-babai/...-int8-g64 |
| FP16 | fastest measured, reference port | 1.17 GB | 1.35 GB | ai-babai/gigaam-multilingual-mlx |
| INT6 g64 | smaller, near-INT8 quality | 573 MB | 0.76 GB | ai-babai/...-int6-g64 |
| INT4 g64 | minimum memory and disk | 447 MB | 0.63 GB | ai-babai/...-int4-g64 |
Choose a variant without remembering its repository name:
gigaam-stt speech.wav --variant fp16
gigaam-stt speech.wav --variant int6 --format json
gigaam-stt models
The runtime downloads immutable model revision v0.1.0 on first use and then
reuses the standard Hugging Face cache.
Common commands
# Subtitles
gigaam-stt interview.mp3 --format srt --output interview.srt

# Output directory; creates transcripts/recording.vtt
gigaam-stt recording.mov --format vtt --output-dir transcripts/

# Machine-readable text, timestamps, revision, and metrics
gigaam-stt sample.flac --format json --output sample.json

# Reuse a downloaded snapshot without network access
gigaam-stt audio.wav --offline

# Move the Hugging Face cache
gigaam-stt audio.wav --cache-dir /Volumes/ML/huggingface
Long inputs are processed in deterministic overlapping chunks. CTC word timestamps are approximate emission times, suitable for navigation and subtitles but not forced alignment.
Python API
import mlx.core as mx
from gigaam_multilingual_mlx import load_model

model = load_model(variant="int8")
audio = mx.zeros((1, 16_000), dtype=mx.float32)
log_probs, lengths = model(audio)
text = model.greedy_decode(log_probs, lengths)[0]["text"]
Local portable model directories are also supported:
load_model("/path/to/model").
Compatibility and limitations
- Supported: Apple Silicon, native ARM Python, macOS 14+.
- M1–M5 are expected to be runtime-compatible; published performance numbers come from one 14-inch MacBook Pro with Apple M4 Pro and 48 GB memory.
- Not supported: Intel Mac, Linux, Windows, or iOS.
- This release uses greedy CTC decoding. It does not provide diarization, training, microphone streaming, or realtime HTTP/WebSocket streaming.
- Accuracy can degrade with noise, far-field speech, overlapping speakers, code-switching, or domains unlike the public evaluation data.
Reproducibility and development
The repository contains pinned public FLEURS manifests, compact benchmark results, and commands for GigaAM, MLX Whisper, and MLX Parakeet. No private audio, model weights, datasets, caches, or raw large benchmark outputs are stored in Git.
Developer-only conversion and evaluation tools use optional dependencies:
python -m pip install 'gigaam-multilingual-mlx[convert,quality]'
python -m gigaam_multilingual_mlx.dev_cli --help
Start with benchmarks/multilingual-v1/README.md
for the protocol and docs/benchmark-multilingual-v1.md
for the results.
Key numbers in text
This compact table is the text alternative to the GigaAM part of the image. Core macro WER averages Russian, Kazakh, Kyrgyz, and Uzbek; lower is better.
| GigaAM MLX variant | Core macro WER | 5-min WAV | Peak RAM | Model size |
|---|---|---|---|---|
| FP16 | 5.066% | 1.952s | 1.350 GB | 1.171 GB |
| INT8 g64 (default) | 5.070% | 2.036s | 0.877 GB | 0.699 GB |
| INT6 g64 | 5.069% | 2.195s | 0.755 GB | 0.573 GB |
| INT4 g64 | 5.219% | 2.563s | 0.626 GB | 0.447 GB |
License and attribution
The MLX port is MIT-licensed. Upstream and dataset provenance is recorded in
THIRD_PARTY_NOTICES.md. Please cite the original
GigaAM-Multilingual work from the upstream model card and this project using
CITATION.cff.
This project is not an official release of the GigaAM authors. Security reports
and contributions are covered by SECURITY.md and
CONTRIBUTING.md.
1 maintainer

Metadata
1 maintainer
Release files for gigaam-multilingual-mlx 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| gigaam_multilingual_mlx-0.2.0.tar.gz | 1.6 MB | With provenance | Details for gigaam_multilingual_mlx-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| gigaam_multilingual_mlx-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for gigaam_multilingual_mlx-0.2.0-py3-none-any.whl |
Total release size: 1.7 MB
Release files / gigaam_multilingual_mlx-0.2.0.tar.gz
| Download URL | gigaam_multilingual_mlx-0.2.0.tar.gz |
|---|---|
| Size | 1.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e77dbdcec4ae17e2ffe23af4b1e30ca2162189e996e959fd4d93a67de93b9270
|
|
BLAKE2b-256 checksum How to use checksums |
76832ea6b5fe9efcd55bd05b729a3e0e5c2588215e006e8d4f0a44c60d523d6e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 16, 2026.
Transparency logRelease files / gigaam_multilingual_mlx-0.2.0-py3-none-any.whl
| Download URL | gigaam_multilingual_mlx-0.2.0-py3-none-any.whl |
|---|---|
| Size | 51.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3fe7cf6ab28148d0843f6d179228bdaa0aa927b6d6d1d16509f395e14a164172
|
|
BLAKE2b-256 checksum How to use checksums |
d6cb1308f14ab1f37eccbf0daf60c0cc539e324a5e26fc133ecfb75e3761aac2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 16, 2026.
Transparency logSecurity for gigaam-multilingual-mlx 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for gigaam_multilingual_mlx-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 16, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














