
⚖️ git-judge-commits
Judge every commit in a range — and catch the ones whose message lies about the diff.




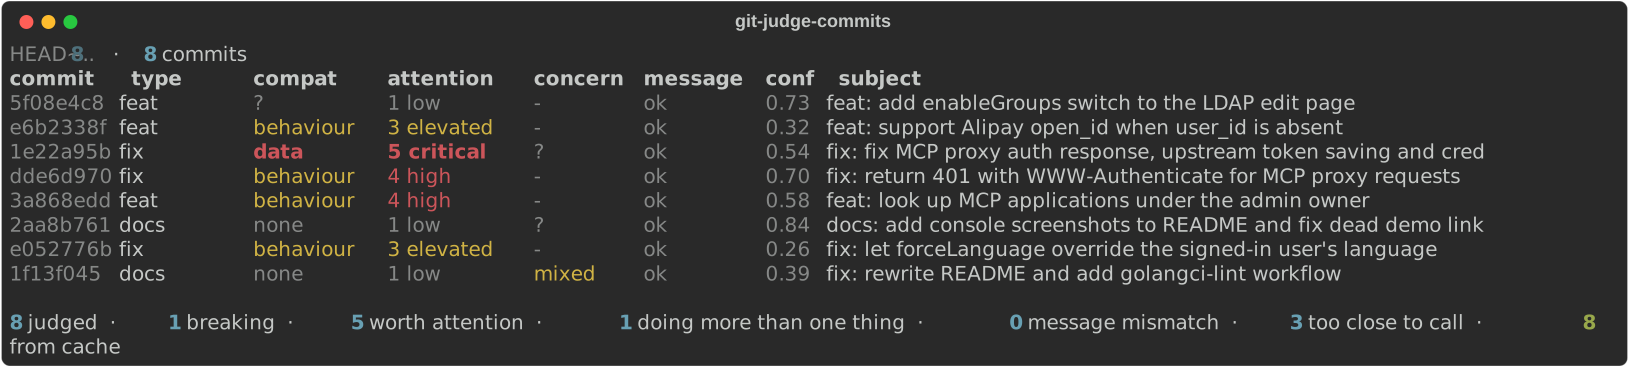
Powered by Jev, TypeSafe's System One model. Jev does not write text — it answers typed questions with calibrated probabilities and nothing else. That is the whole reason this tool works:
- 🔒 It cannot hallucinate a field. Every answer is schema-constrained, so
typeis always one of eleven values and never an invented one. - 🤔 It tells you when it doesn't know. Every answer carries a margin, so a question with no
clear answer prints
?instead of a confident guess. - ⚡ It is fast and nearly free. Five questions per commit, ~700 ms, at $0.042 per million input tokens with output free — so judging a whole branch costs a fraction of a cent.
A general LLM would write you a paragraph about each commit. Jev gives software something it can branch on.
Five questions per commit, each asked independently against the same state:
| Field | Type | Question |
|---|---|---|
compat |
choice | What compatibility does it put at stake? |
worth_attention |
0–5 | How much reviewer scrutiny does it deserve? |
type |
choice | Conventional Commits type, judged from the diff |
single_concern |
yes/no | Does it do exactly one thing? |
message_matching |
yes/no | Is the message a truthful description of the diff? |
compat
| Level | Meaning | Breaking |
|---|---|---|
none |
Nothing observable changes: docs, tests, tooling, formatting | no |
internal |
Restructured, but every caller sees what it saw before | no |
behaviour |
Same interface, different runtime outcome — nobody must change code, but they will notice | no |
interface |
Callers must change code: signature, endpoint, flag, config key or default changed | yes |
data |
Persisted or transmitted format changed; needs a migration or coordinated rollout | yes |
breaking is derived in code from compat, not asked as its own question. Asking it
directly gave a mean confidence of 0.54 across a 25-commit sample — a coin flip — because
"did this break anything?" bundles several unrelated judgements. As a five-way choice the
same sample scores 0.77 mean / 0.89 median, with nothing below 0.2. Most real commits
turn out to be behaviour, which is exactly the case a single boolean had no room for.
📦 Install
uv tool install git-judge-commits
Or run it without installing anything:
uvx git-judge-commits main..feature
pipx install git-judge-commits and pip install git-judge-commits work too. Needs
Python 3.11+.
Then point it at a TypeSafe API key:
export TYPESAFE_API_KEY=...
A .env file in the working directory is loaded automatically, so a key kept there is
picked up without exporting anything.
🚀 Usage
git-judge-commits [REVISIONS | PR-URL] [-C PATH]
REVISIONS is anything git log accepts, so there is no second syntax to learn:
git-judge-commits                        # the whole branch, or last 32 on the default branch
git-judge-commits main..feature          # a range
git-judge-commits v1.2.0..               # everything since a tag
git-judge-commits HEAD~10..              # the last ten
git-judge-commits v1.2.0                 # bare ref means v1.2.0..HEAD
git-judge-commits -C ~/src/other-repo    # like git -C
git-judge-commits --json                 # per-field confidence and rubric scores
🔗 Judging a pull or merge request
Pass the URL. Nothing needs to be cloned first, and it works from any directory:
git-judge-commits https://github.com/django/django/pull/21993
git-judge-commits https://gitlab.com/gitlab-org/gitlab-runner/-/merge_requests/5000
git-judge-commits https://gitlab.internal.corp/team/sub/proj/-/merge_requests/42
GitHub, GitLab (including self-hosted), Gitea and Forgejo all publish a request's head as an ordinary git ref, so there is no forge-specific code here — the URL just resolves to a revision range that the normal pipeline judges.
| Already in that repo? | The ref is fetched into it and the objects you have are reused. Nothing is checked out, no branch is created, and the working tree is untouched — the ref lands under refs/git-judge-commits/ where git branch will not show it. |
| Anywhere else? | A blobless shallow clone is kept under the cache directory and reused. Judging a request in django costs about 780 KB and 8 seconds cold, 3 seconds warm. |
| Finding the base | Taken from the forge when gh or glab is installed and authorised for that host. Otherwise derived with git merge-base, widening the history until the branch point appears. --base REF overrides both. |
| Auth | GitLab's API refuses anonymous callers even on public projects, but the git fetch does not — so public and self-hosted GitLab work with no token at all, using whatever credentials already clone that host. |
Merge commits are skipped as usual, so a branch that merged the target back into itself is judged on its own commits rather than the ones it absorbed.
What it judges when you give it nothing
On a feature branch, it judges everything the branch adds on top of the default
branch — the commits a merge request would contain. Anywhere else (on the default
branch itself, or a branch with nothing ahead of it) it falls back to the last -n
commits.
The default branch comes from origin/HEAD, which is the only thing that actually
knows: guessing main or master gets repos whose default is dev or trunk wrong.
If origin/HEAD is unset it tries origin/main, origin/master, main, master in
turn, and falls back to the last -n commits if none exist. --base REF overrides the
detection.
The chosen range is always printed before the table, so it is never left implicit:
origin/master..HEAD (feat/structured-output) · 1 commit
🕵️ Catching a commit that lies
A commit whose message says docs: fix typo in comment, whose diff changes a function's
behaviour and smuggles in an unrelated helper:
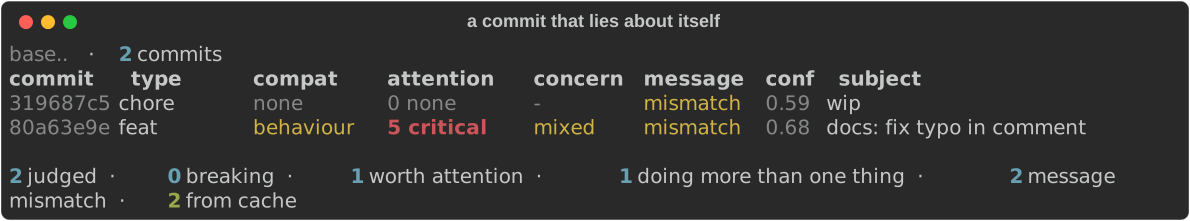
mismatch says the message is not a truthful description of the diff, mixed says the
commit does more than one thing, and 5 critical says look at it before it ships.
Exit codes are listed under Failing a build.
🚦 Failing a build
--fail-on turns verdicts into an exit code, so a pipeline can refuse a branch. Conditions
read the way the table does:
git-judge-commits --fail-on=concern=mixed
git-judge-commits --fail-on=compat=interface,message=nok
git-judge-commits --fail-on='attention>=4'        # quote it: the shell eats >=
git-judge-commits --fail-on='type=feat|fix' --fail-on=breaking
Comma separates conditions, | gives alternatives, and the flag is repeatable. Any commit
matching any condition fails the run.
| Field | Values | Ordered |
|---|---|---|
compat |
none internal behaviour interface data |
yes — least to most disruptive |
attention |
0–5, or none low moderate elevated high critical |
yes |
type |
the eleven Conventional Commits types | no |
concern |
single mixed |
no |
message |
ok nok |
no |
breaking |
yes no |
no |
Operators are =, !=, and on the ordered fields >=, >, <=, <. So
compat>=interface is "interface or worse", which is the same set as breaking.
Shorthands breaking, mixed, mismatch and unsure stand alone.
A suppressed answer never fails a build. If a margin fell below --min-confidence the
table shows ?, and the gate skips it — failing a branch over a coin flip is worse than
missing one. --fail-on=unsure is there for when you want the opposite: fail because
something was too close to call.
A tripped gate always says which condition matched and on which commits, even under -s:
fail-on concern=mixed matched 1:
  1f13f045 fix: rewrite README and add golangci-lint workflow
Exit codes
| Code | Meaning |
|---|---|
0 |
Nothing matched |
1 |
A --fail-on condition matched |
2 |
Bad arguments, or git could not do what was asked |
3 |
One or more commits could not be judged |
🐙 GitHub Action
- uses: thejoeejoee/git-judge-commits@v0
  with:
    api-key: ${{ secrets.TYPESAFE_API_KEY }}
    fail-on: message=nok,concern=mixed
That is the whole thing on a pull_request event. It judges the commits the request
adds, writes them to the job summary as a table, and fails the step if anything matches
fail-on — leave that empty to report without ever going red.
It works with the default actions/checkout. On a pull request the action passes the
request's URL rather than a revision range, so the tool fetches the refs it needs
itself. No fetch-depth: 0, and no surprise when a range turns out to be missing half
its history in a depth-1 clone.
All inputs and outputs
| Input | Default | |
|---|---|---|
api-key |
required | A TypeSafe API key |
revisions |
the pull request | A range or a request URL |
fail-on |
none | Conditions that fail the step |
min-confidence |
0.2 |
Margin below which an answer is reported as unknown |
threshold |
0.5 |
Probability bar for the yes/no questions |
model |
typesafe:jev-latest |
Pin a version once tuned |
limit |
32 |
Most commits to judge |
diff-budget |
16000 |
Diff characters per commit |
exclude |
none | Pathspecs to drop, comma- or newline-separated |
version |
newest | Which release to run |
source |
PyPI | Install from a path or git URL instead |
summary |
true |
Write the job summary |
working-directory |
. |
Where to run |
| Output | |
|---|---|
json |
Path to the verdicts as JSON |
judged breaking mismatched mixed |
Counts, excluding answers too close to call |
failed |
Whether a condition matched |
Or without the action at all:
- run: |
    uvx git-judge-commits "origin/${{ github.base_ref }}..HEAD" \
      --fail-on=message=nok,concern=mixed
🎯 Confidence and the ? gate
Jev's confidence is a margin from the decision threshold, not a probability of being right: 0 means the question was a coin flip for this commit, 1 means certainty. A confident answer can still be wrong.
Any answer whose margin falls below --min-confidence (default 0.2) prints as ?
rather than being asserted, and is left out of the summary counts. --min-confidence 0
reports everything. The conf column is the weakest margin among the answers actually
shown, so a suppressed field does not drag it down.
In --json, every answer is reported regardless, with the full per-field confidence
map, the unrounded worth_attention position under scores, and a low_confidence
list naming the fields the gate would have hidden.
⚡ Caching
Verdicts are cached on disk, so re-running a range costs nothing. A commit is immutable and the questions are fixed, so a cached answer is the same answer.
~/.cache/git-judge-commits/ # honours XDG_CACHE_HOME
Override with --cache-dir PATH or $GIT_JUDGE_COMMITS_CACHE. One JSON file per
verdict, sharded two characters deep; deleting the directory is a safe reset.
What the key covers. A cached verdict is reused only when all of these match:
| In the key | Why |
|---|---|
| The exact state sent | Covers the commit, and anything changing what the model saw — --diff-budget, --exclude |
| The model asked for | typesafe:jev-1.13.0 and jev-latest are separate entries |
--threshold |
It changes the model's yes/no answers |
| A fingerprint of the questions | model.py verbatim, plus this tool's version and pydantic-ai's |
That fingerprint hashes model.py source, not its JSON schema, because the schema
drops enum member docstrings — and those carry the whole compat and attention rubric.
Editing one changes the prompt, so it has to change the key. Hashing the source also
catches edits made between releases, which a version number alone never would.
--min-confidence is not in the key: it only decides what gets printed, so changing
it re-renders cached verdicts for free.
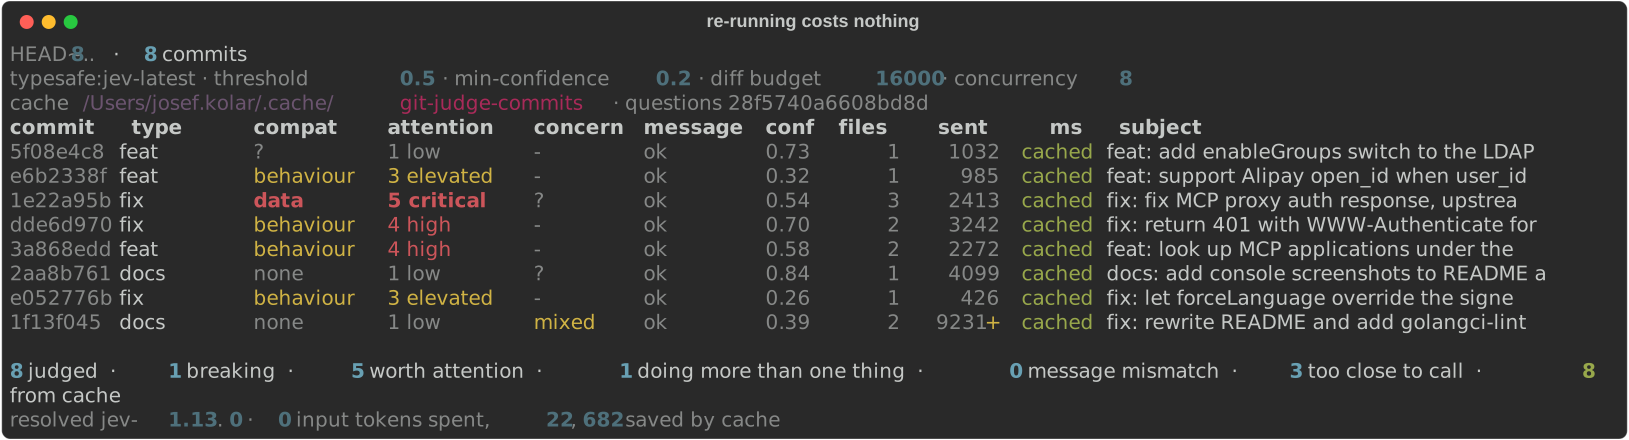
Staleness. jev-latest and jev-preview move when TypeSafe ship a release, which
a key cannot see, so entries for a moving alias expire after 7 days. Pinned versions
never expire. --refresh re-judges and overwrites; --no-cache neither reads nor writes.
🔍 Verbosity
| Level | Adds |
|---|---|
-s |
Nothing but the table. No range line, progress bar or summary — stdout only. |
| (default) | The chosen range, a progress bar while judging, and the summary line. |
-v |
Per-commit files / sent / ms columns, the effective settings, and the resolved model version plus total input tokens. A + after sent means the diff was truncated. |
-vv |
A per-commit breakdown: every question's answer, its margin, and the full probability distribution behind it. |
-vvv |
The exact state JSON sent to the model for each commit. |
-vv is the one to reach for when an answer looks wrong, because it shows what else
the model had in play:
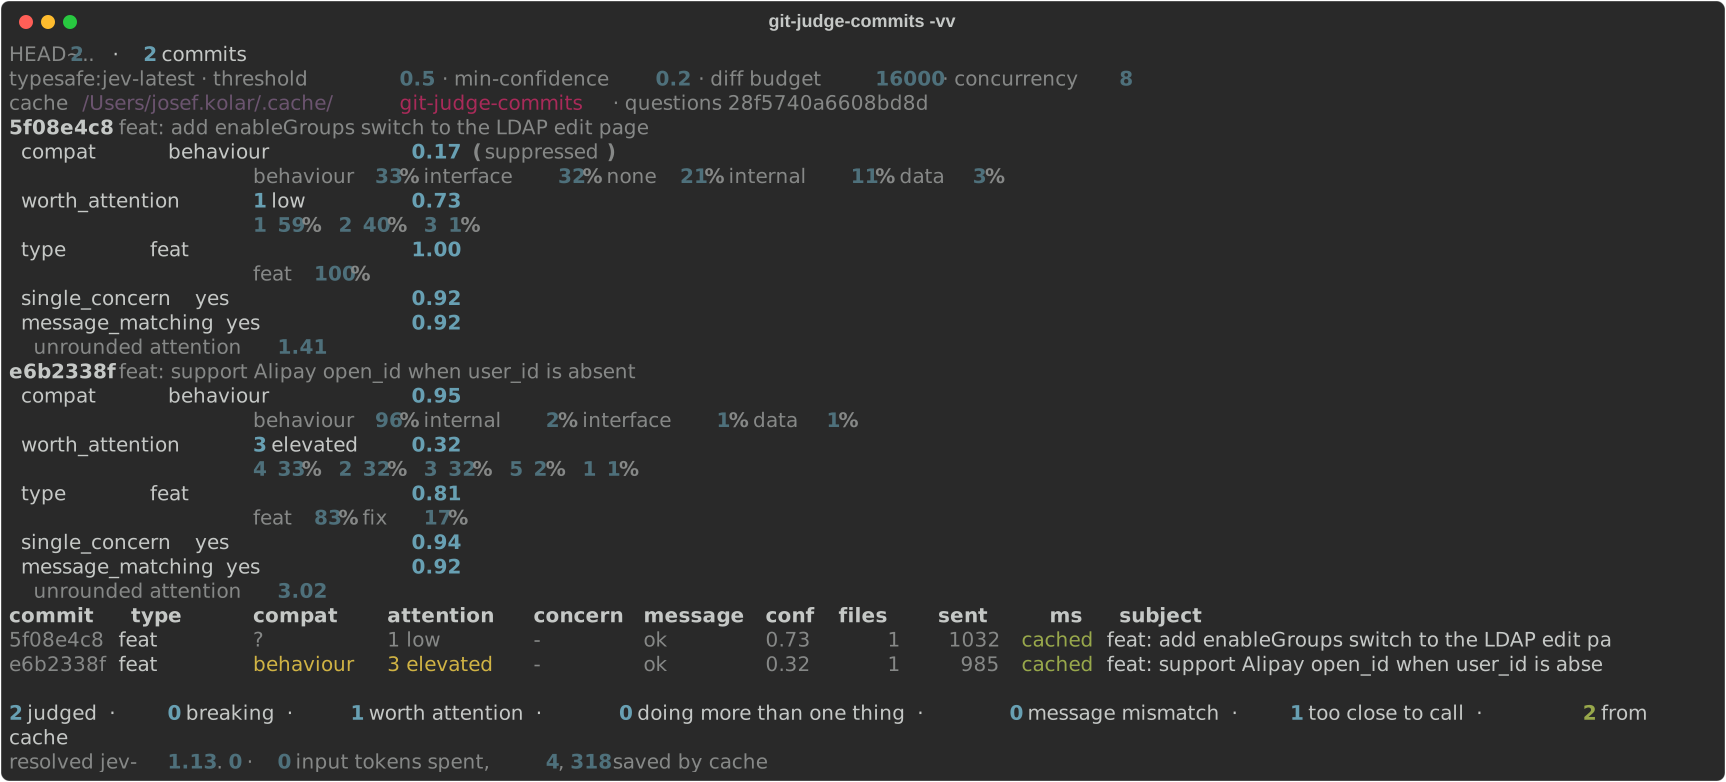
The first commit's compat is a five-way split — behaviour only just beat interface,
33% to 32% — so its margin is 0.17 and the table prints ? rather than picking a winner.
That is the gate earning its keep: the question genuinely has no answer for that commit,
and asserting one would be the misleading thing to do.
Everything above goes to stderr; stdout carries only the table or the JSON. So
git-judge-commits -vv > report.txt still gives a clean table in the file, and
-s is redundant when redirecting.
Options
| Flag | Default | Notes |
|---|---|---|
-C, --repo |
. |
Run as if started here, like git -C |
-b, --base REF |
auto | Compare the branch against this instead of the detected default branch |
-n, --limit |
32 | Cap on commits judged |
--model |
typesafe:jev-latest |
Pin a version once you have tuned thresholds, e.g. typesafe:jev-1.13.0 |
--threshold |
0.5 | Probability bar for a yes on single_concern and message_matching |
--min-confidence |
0.2 | Margin below which an answer prints as ? |
--diff-budget |
16000 | Max diff characters per commit; 0 for unlimited |
-x, --exclude GLOB |
— | Pathspec dropped from diffs, repeatable (e.g. --exclude '*.lock') |
--merges |
off | Include merge commits, which otherwise have no diff to judge |
-j, --concurrency |
8 | Commits judged in parallel |
-v / -vv / -vvv |
— | Progressively more process detail (see above) |
-s, --silent |
off | Table only. Aliases: -q, --quiet |
--no-cache |
off | Neither read nor write the cache |
--refresh |
off | Re-judge and overwrite cached verdicts |
--cache-dir PATH |
XDG | Where verdicts are cached |
-f, --fail-on COND |
— | Exit 1 if any commit matches. Repeatable |
--json / --no-color |
— | Output control |
Run git-judge-commits -h for the full help.
🧩 Design notes
- One judgement per field. Jev returns a low margin on questions that bundle several
factors, so a weak field is a signal the question is badly posed rather than that the
model is unsure. The per-field
confidencemap in--jsonis the tool for finding them. - Policy lives in code, not in the prompt.
breakingis a set membership test overcompat. Change which levels count as breaking without touching the model. - The diff budget is spread evenly across a commit's files rather than truncating the
tail, because an unrelated change smuggled into a commit tends to sit in a file after
the first one — which is precisely what
single_concernandmessage_matchinglook for. - Pin the model version once you have tuned
--thresholdor--min-confidence.jev-latestmoves on release and shifts the margins under you.
🤝 Contributing
See CONTRIBUTING.md for development setup, how the questions are defined, and how to regenerate the screenshots.
📄 License
MIT
1 maintainer

Release files for git-judge-commits 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| git_judge_commits-0.2.0.tar.gz | 28.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| git_judge_commits-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 60.8 kB
Release files / git_judge_commits-0.2.0.tar.gz
| Download URL | git_judge_commits-0.2.0.tar.gz |
|---|---|
| Size | 28.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2f8c78171a4df77368c7bc6801d6549dda5c3d56c1f6caf097c825adaa1cbf25
|
|
BLAKE2b-256 checksum How to use checksums |
656e6dec5a28b066fb83302647fe769da9ac4935f7420449abcbaf2a68cb0515
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency logRelease files / git_judge_commits-0.2.0-py3-none-any.whl
| Download URL | git_judge_commits-0.2.0-py3-none-any.whl |
|---|---|
| Size | 32.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
14aefa887e21654af4fcef3836cafb5a07b23b200fa53fa0b55a63052656b412
|
|
BLAKE2b-256 checksum How to use checksums |
88f26fb367856a686afeeace74d03d4b363cdf043f712a10664e2d955472ca53
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency log













