
glossdex
Glossed locally, indexed by meaning, gated by evidence.
glossdex is private semantic search over a folder of photos and documents. A local model writes a short gloss for every file: a list of independent phrases saying what is in it. glossdex embeds the gloss and its phrases, and at query time it decides how many results the evidence supports. Often that is one or two results. Sometimes it is none.
Most semantic search returns a fixed top 10 whether or not anything matches. Ask a photo library for "a giraffe" and you get ten photos anyway, and a language model fed those ten passages will answer from them. glossdex returns nothing when the collection has nothing like the query. It needs no training, no click logs and no relevance labels for your collection. Nothing leaves your machine.
On the ten sample documents in examples/sample-docs:
$ glossdex search examples/sample-docs "how much is the electricity bill" --describer text-only
 1. match 0.440  words 87%  hydro-bill-june-2026.txt
      matched: Electricity bill for Alex Morgan, 42 Birch Lane.

1 item(s) within the band (score >= 0.396). Showing 1.

$ glossdex search examples/sample-docs "mortgage statement" --describer text-only
Nothing found.

Nothing shown: the best match (0.281) plus keyword evidence (0.000) is below the evidence gate (0.520).

$ glossdex search examples/sample-docs "mortgage statement" --describer text-only --top-k 3   # fixed top-k
 1. match 0.281  words 37%  hydro-bill-june-2026.txt
 2. match 0.268  lease-agreement.md
 3. match 0.257  words 37%  donation-receipt.txt
On 40 sample photos, glossdex shows nothing for "a giraffe", while a fixed top-10 shows ten unrelated photos:
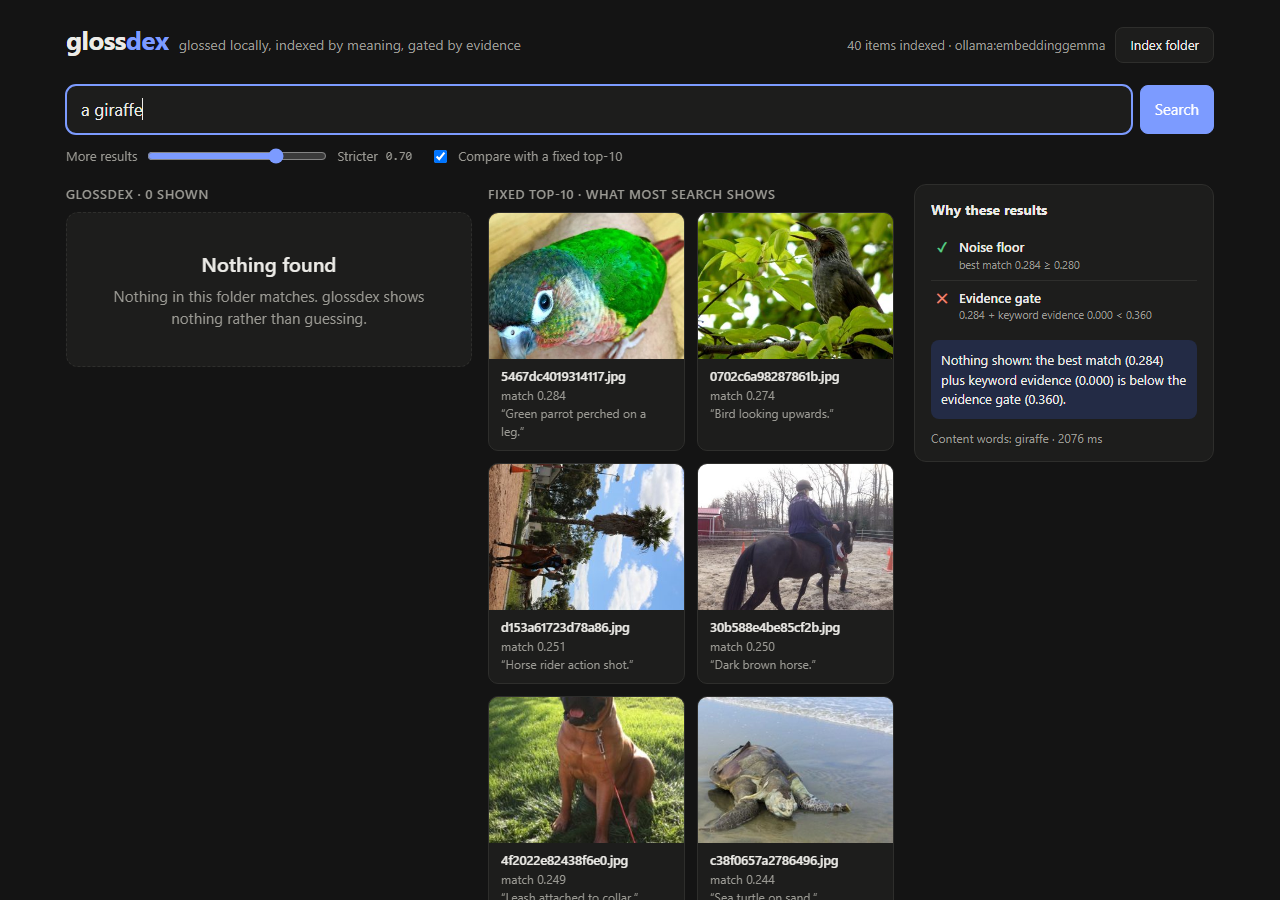
Photos: Open Images V7, CC BY 2.0; credits in docs/SCREENSHOT_CREDITS.md.
When there is an answer, it shows only the answer, and explains why:
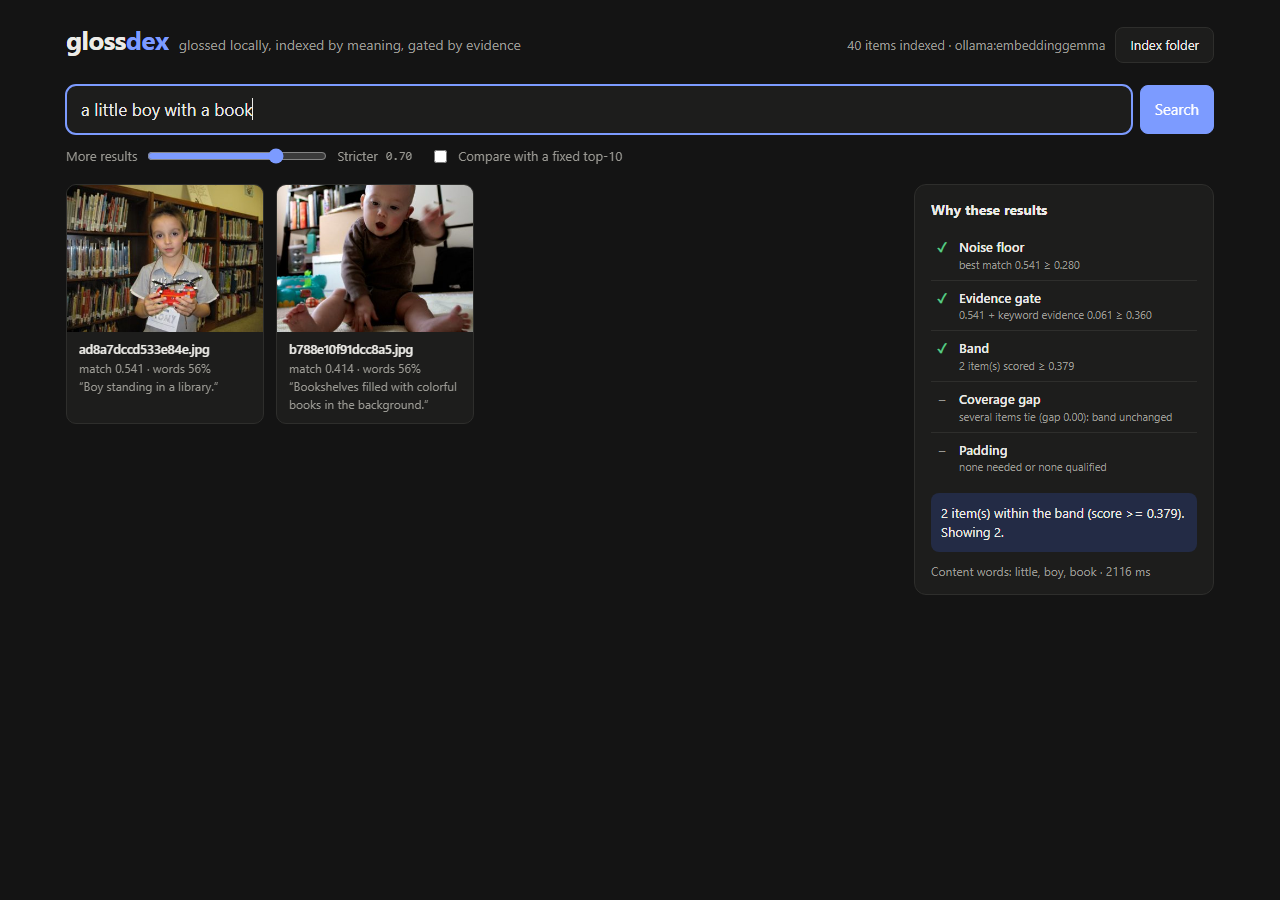
Quick start (about 10 minutes)
You need Python 3.9+ and Ollama.
ollama pull embeddinggemma          # 622 MB, the embedding model
pip install glossdex
glossdex doctor                     # checks Ollama and the models
Documents in one minute, with no language model. Each document's own sentences become its phrases:
git clone https://github.com/miranpoor/glossdex && cd glossdex
glossdex index examples/sample-docs --describer text-only
glossdex serve examples/sample-docs --describer text-only
Your browser opens the glossdex page. Try when does my lease end, my son's doctor visit and
mortgage statement (not in the folder). Move the strictness slider, or tick Compare
with a fixed top-10 to see what conventional search would have shown.
Photos. Add a vision-language model. Gemma 4 E4B reads both images and text:
ollama pull gemma4:e4b                       # about 10 GB; gemma4:e2b is smaller
python examples/get_sample_images.py         # 40 CC BY 2.0 photos from Open Images
glossdex serve examples/sample-images/photos # then press "Index folder"
Describing takes a few seconds per photo on a recent GPU and longer on a CPU. Indexing is incremental: only new or changed files are described.
Your own folder: glossdex serve ~/Pictures/2025 or glossdex serve ~/Documents/scans.
The index lives in a .glossdex/ folder inside the folder you index. Install
glossdex[pdf] to include PDFs.
How it works
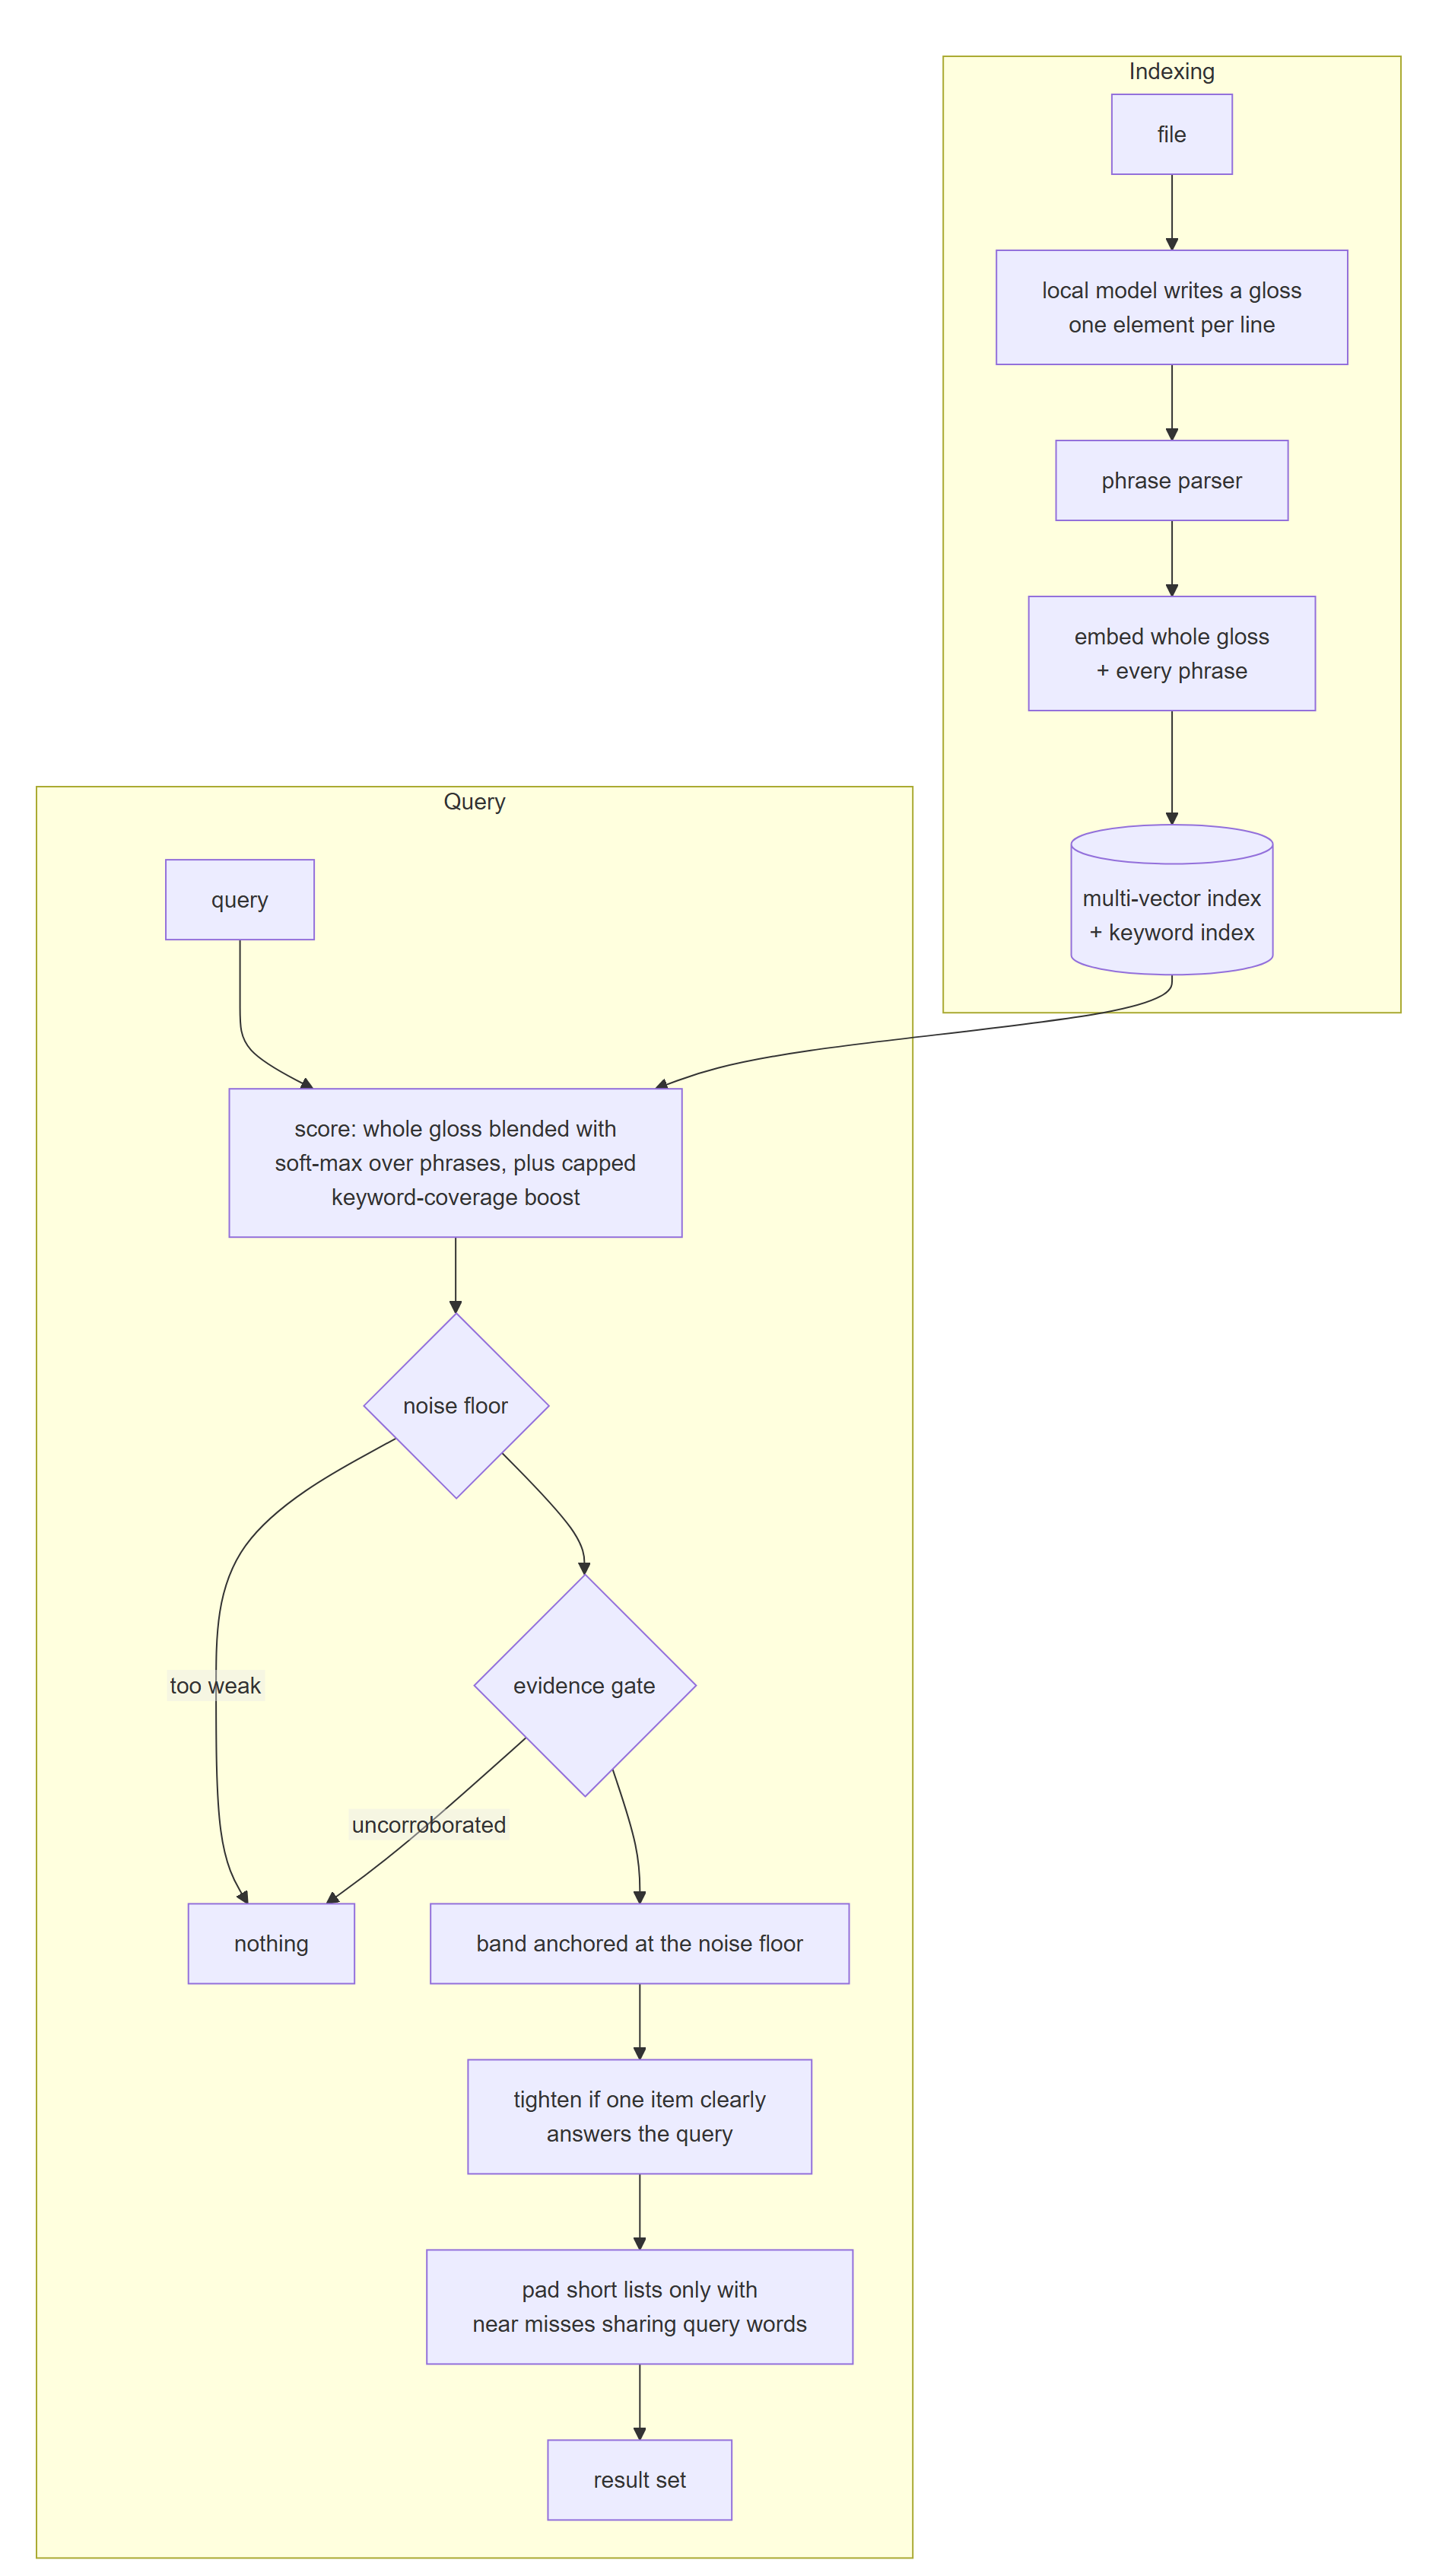
Diagram source: docs/how-it-works.mmd.
- Gloss. A vision-language model (for photos) or a language model (for documents) lists the item's elements as short, independent phrases. Single-concept queries match one phrase strongly. The whole gloss carries the combination of elements that compound queries need.
- Score. Each item's semantic score blends its whole-gloss similarity with a soft maximum over its phrase similarities. A rarity-weighted keyword-coverage boost can promote an item that literally contains the query's words. It applies only to items the embedding already considers related.
- Decide how many. Every threshold is derived from the best semantic score, so keyword
evidence can never raise a threshold:
- Noise floor. If the best match is weaker than unrelated text usually scores, show nothing.
- Evidence gate. A higher bar that keyword evidence can help clear: BM25 from the items that would be shown, plus a bonus if any item contains every query word. It lets a name or a document type through and stops weak, uncorroborated matches. It can permit a list but never lengthens one.
- Band. Keep items within a ratio of the best match, measured from the noise floor rather than from zero, so that weak queries get short lists.
- Coverage gap. If one item accounts for the query's words far better than any other, tighten the band. If several tie, leave it alone.
- Conditional padding. Top up a one-item list only with a near miss that shares query words.
The strictness control moves the band and scales the noise floor, headroom and evidence gate together. At its loosest those three are off and only the band ratio (and any coverage-gap tightening) remains, so "show me more" reaches the ranked items.
See docs/architecture.md for the components and the adapter interfaces.
Python API
from glossdex import Glossdex

gx = Glossdex.for_folder("~/Documents/scans")   # Ollama: gemma4:e4b + embeddinggemma
gx.index()                                       # incremental

res = gx.search("insurance renewal for the Honda")
if res.found:
    for hit in res.hits:
        print(hit.title, round(hit.score, 3), hit.matched)
print(res.trace.verdict)                         # why this many results

gx.search("...", strictness=0.5)                 # lower shows more
gx.explain("...")                                # full ranking before any cutoff
Retrieval-augmented generation that can say "not found"
ctx = gx.context("When is the field trip?", max_chars=6000)
if not ctx:
    answer = "Not found in your documents."      # the model is never called
else:
    answer = llm(f"Answer from these sources, cite [n].\n\n{ctx.text}\n\nQ: ...")
The number of passages in the context is the size of the result set. It varies per question and is not a fixed k. See examples/rag_ollama.py.
Bring your own models and sources
glossdex has three adapter interfaces, all plain Python protocols:
| Adapter | Built in | Implement |
|---|---|---|
| Content source | FolderSource (images, .txt, .md, .pdf) |
items() -> Iterator[Item] |
| Describer | OllamaDescriber, TextOnlyDescriber |
describe(item) -> Description |
| Embedder | OllamaEmbedder, SentenceTransformersEmbedder |
embed_documents(texts), embed_query(text) |
from glossdex import Glossdex, OllamaDescriber, SentenceTransformersEmbedder

gx = Glossdex.for_folder(
    "photos",
    describer=OllamaDescriber(model="gemma4:e2b"),
    embedder=SentenceTransformersEmbedder(),     # pip install "glossdex[st]"
)
Command line
| Command | What it does |
|---|---|
glossdex doctor |
Checks that Ollama is running and the models are pulled |
glossdex index FOLDER [--rebuild] |
Describes and embeds new or changed files, and drops deleted ones |
glossdex search FOLDER "query" [--strictness 0.5] [--top-k 10] [--json] |
Searches, and prints the decision |
glossdex explain FOLDER "query" |
Shows the full ranking with every score, and which items were shown |
glossdex serve FOLDER |
Opens the local web page |
Common options: --vision-model, --text-model, --embed-model, --describer text-only,
--embedder st, --ollama http://host:11434.
Thresholds are per embedding model and kind of content
A similarity of 0.30 means "unrelated" for one embedding model and "a good match" for another. glossdex therefore keeps its thresholds in a profile per embedding model, not per collection. This release ships two profiles for EmbeddingGemma-300M, one for each kind of content:
| Profile | Used for | Chosen automatically when |
|---|---|---|
embeddinggemma-300m |
Short glosses written by a model (photos, and documents described by a model). The configuration that ships in the Memoyad app. | a describer model writes the gloss (the default) |
embeddinggemma-300m/passages |
Raw text passages indexed as written, up to about 1,500 characters each | --describer text-only |
Both rank the same way; the passages profile shows a shorter, more confident list (band 0.90,
evidence gate 0.52, minimum 1 result). Its values were chosen once on three public collections
and then tested, unchanged, on three others (see Benchmark). Pass profile= to
Glossdex to override either.
With another embedding model glossdex still works, but it labels its thresholds uncalibrated and they may cut too much or too little. Profiles for other models are on the roadmap. If you need one now, see COMMERCIAL-LICENSE.md.
Limitations
- Indexing costs a model call per item. Describing an image takes a few seconds on a laptop GPU and longer on a CPU. Pure image-embedding models (CLIP and similar) index far faster. glossdex trades indexing time for result sets that can be trusted, including empty ones.
- The gloss bounds retrieval. If the model never writes "festival", a query about a festival must succeed on meaning alone. A better describer gives better search.
- English vocabulary. The stopword list and the synonym classes are English. A multilingual embedder will match other languages by meaning, but the keyword evidence will not help them.
- Exhaustive search. Scoring is a matrix product over every stored vector. That is fast up to a few hundred thousand phrases. Beyond that, put an approximate nearest-neighbour index in front and apply the result-set stages to its candidates.
Benchmark
On three public text collections from BEIR, glossdex's result sets are compared with dense (semantic), BM25 (keyword) and hybrid search showing a fixed top 5 or top 10, with a similarity threshold (alone and capped at a top k), and with Adaptive-k (Taguchi et al., EMNLP 2025). All systems use the same EmbeddingGemma-300M vectors. Every system's settings, glossdex's included, were chosen once on three other collections.
Task score: F2 of the list shown on answerable queries, and 100 for showing nothing (0 otherwise) on queries the collection cannot answer.
| Test collection | glossdex | Strongest baseline: threshold, top 5 | Ahead by (95% CI) | Best fixed top-k | Ahead by (95% CI) |
|---|---|---|---|---|---|
| SciFact | 70.2 | 56.8 | +13.4 (+9.9 to +17.0) | 42.2 (dense, top 5) | +28.0 (+23.4 to +32.6) |
| NFCorpus | 25.7 | 16.9 | +8.8 (+7.0 to +10.7) | 14.2 (dense, top 10) | +11.6 (+7.8 to +15.4) |
| FiQA | 39.7 | 38.1 | +1.7 (+0.0 to +3.3) | 31.0 (dense, top 5) | +8.7 (+6.4 to +11.1) |
glossdex shows nothing for 96–100% of the questions a collection cannot answer. A similarity threshold chosen on the same development collections also does, but only by showing nothing for 8.5–72% of the questions that do have answers (glossdex: 0.6–22%). glossdex ranks as well as dense retrieval. The protocol, every table, per-query results and the scripts to reproduce them are in benchmarks/beir.
Used in
Memoyad: private, fully on-device search over photos, screenshots and photographed documents for Android (in closed testing on Google Play), built on the same method.
License
glossdex is free software under the GNU Affero General Public License v3.0 (LICENSE). You can use, study, change and share it, including in open-source products and services that are also AGPL. To embed glossdex in a closed-source product or service, a commercial license is available: see COMMERCIAL-LICENSE.md.
Patent pending. The evidence-gated result-set method implemented here is the subject of U.S. Provisional Patent Application No. 64/172,444. See PATENTS.md for what the open-source license grants.
Citing
If you use glossdex in research, please cite it (see CITATION.cff):
@software{iranpour_glossdex,
  author  = {Iranpour, Mehran},
  title   = {glossdex: evidence-gated semantic search over locally generated descriptions},
  year    = {2026},
  version = {0.1.0},
  doi     = {10.5281/zenodo.23269314},
  url     = {https://github.com/miranpoor/glossdex}
}
1 maintainer

Metadata
1 maintainer
Release files for glossdex 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| glossdex-0.1.1.tar.gz | 803.5 kB | Without provenance | Details for glossdex-0.1.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| glossdex-0.1.1-py3-none-any.whl | Python 3 | none | any | Details for glossdex-0.1.1-py3-none-any.whl |
Total release size: 860.3 kB
Release files / glossdex-0.1.1.tar.gz
| Download URL | glossdex-0.1.1.tar.gz |
|---|---|
| Size | 803.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b51a40e942bacfc7599a3b3500b2c3365ebde6e4ccf1d114f15856b2bdc960c6
|
|
BLAKE2b-256 checksum How to use checksums |
fad1eda0c01ad56a2b18ebd690072512f52eb08a221fcb32487380a8fa3e1629
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.10
|
Release files / glossdex-0.1.1-py3-none-any.whl
| Download URL | glossdex-0.1.1-py3-none-any.whl |
|---|---|
| Size | 56.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
641a5bf20fe3ef01c6c9d2484cfe902acb9b664348272485f773ddb34f1ec3a9
|
|
BLAKE2b-256 checksum How to use checksums |
b3cc27fcb6c83d5f8f2cd660c74bf13915a723924c995bf19c30fbb9f480e558
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.10
|
Security for glossdex 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














