
gpkg


GPU package manager. Stop compiling CUDA extensions.
pip install gpkg
gpkg add flash-attn causal-conv1d mamba-ssm
# done. resolved, locked, installed.
The problem
These packages take 20-60 minutes to compile and regularly fail:
| Package | Typical compile time | Common failure |
|---|---|---|
| flash-attn | 25 min | OOM during build, CUDA mismatch |
| flash-attn-3 | 20 min | SM90+ only, rare wheel coverage |
| causal-conv1d | 10 min | Torch ABI mismatch |
| mamba-ssm | 15 min | Cascading causal-conv1d failure |
| natten | 30 min | CUTLASS dependency, arch-specific |
| sageattention | 10 min | Windows build nightmare |
| grouped-gemm | 10 min | MoE stack dependency |
Prebuilt wheels exist across dozens of GitHub repos and pip indexes. Finding the right wheel for your exact python + torch + cuda + platform combo is a scavenger hunt nobody should repeat.
Install
pip install gpkg

# or with uv
uv tool install gpkg

# or from source
git clone https://github.com/Mapika/gpkg && cd gpkg
uv tool install .
Usage
Just add packages
# Auto-detect torch + cuda, resolve wheels, lock, install
gpkg add flash-attn causal-conv1d mamba-ssm

# If no prebuilt wheel exists, it builds from source (optimized)
gpkg add flash-attn causal-conv1d mamba-ssm  # --build-missing is automatic
Resolve without installing
# Explicit versions
gpkg --torch 2.11.0 --cuda 130 flash-attn flash-attn-3 -o pyproject.toml

# Auto-detect torch and CUDA from your environment
gpkg flash-attn causal-conv1d mamba-ssm
Lockfile for reproducible installs
# Write a lockfile with exact versions and URLs
gpkg --torch 2.11.0 --cuda 130 flash-attn causal-conv1d --lock

# Install from lockfile (no network needed)
gpkg install -o pyproject.toml

# Install + sync in one step
gpkg install --sync
Verify your environment
gpkg test flash-attn causal-conv1d mamba-ssm
  ok  torch 2.11.0+cu128  GPU: NVIDIA GeForce RTX 5070 Ti
  ok  flash-attn 2.8.3
  ok  causal-conv1d 1.6.1
  ok  mamba-ssm 2.3.1
See what's available
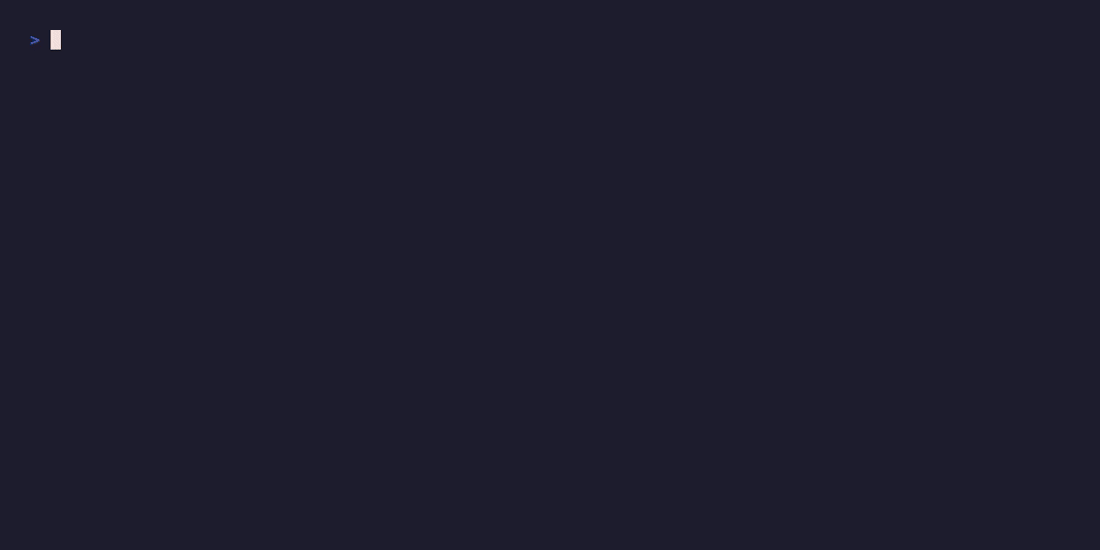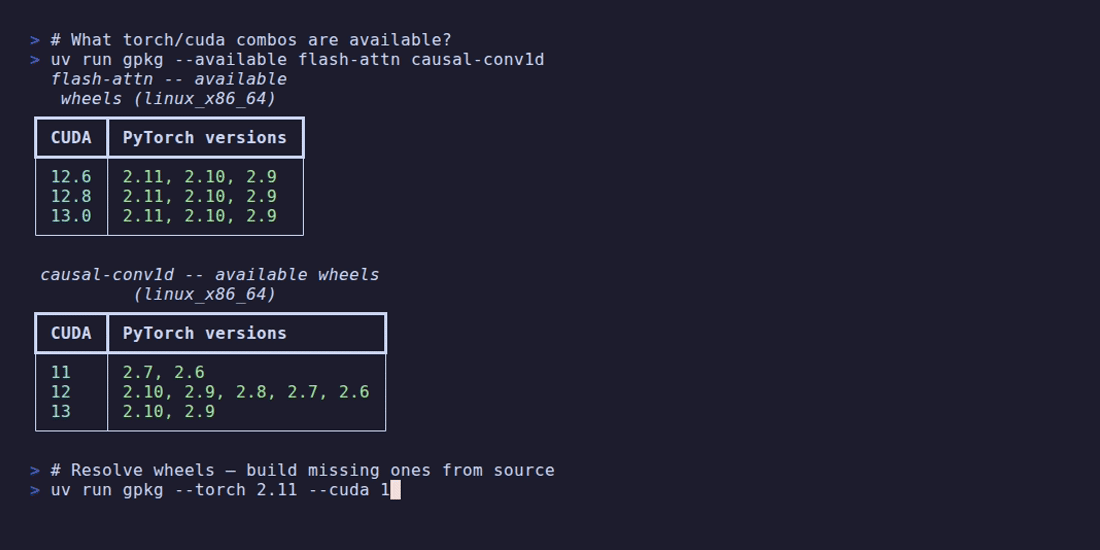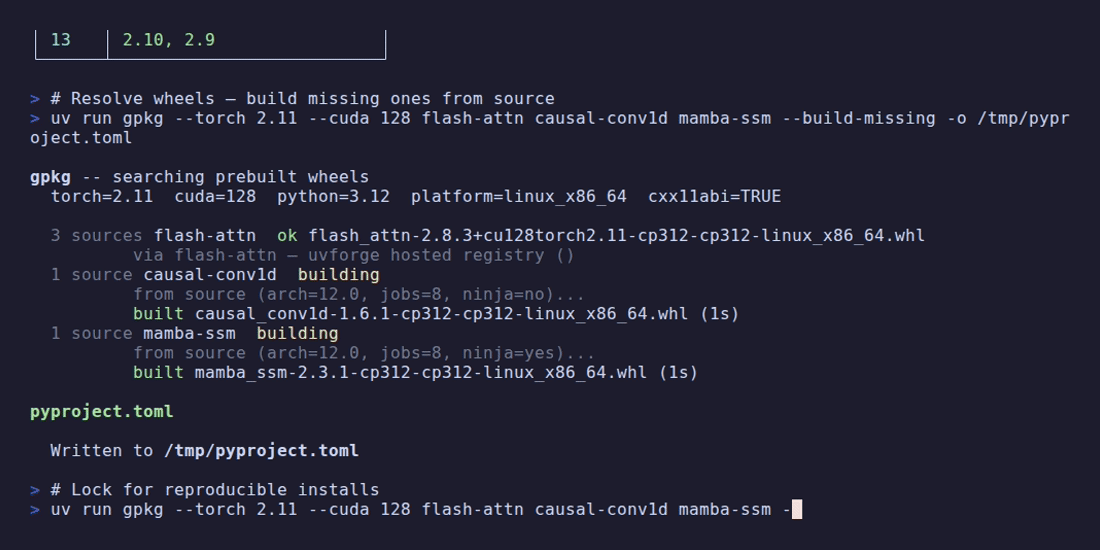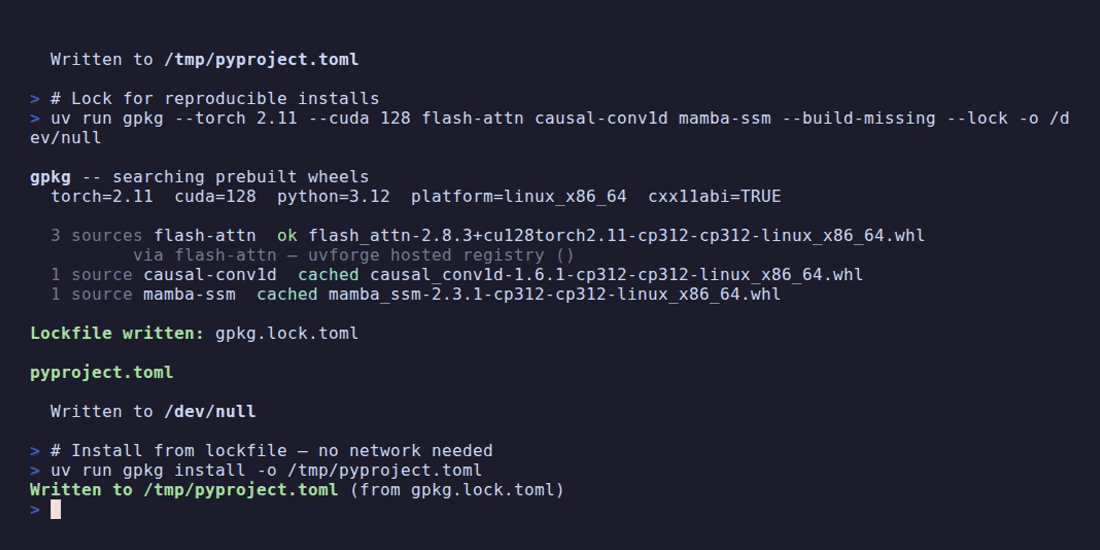
gpkg --available causal-conv1d natten
causal-conv1d -- available wheels (linux_x86_64)
┏━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ CUDA ┃ PyTorch versions        ┃
┡━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━┩
│ 12   │ 2.10, 2.9, 2.8, 2.7    │
│ 13   │ 2.10, 2.9              │
└──────┴────────────────────────┘
Diagnostics
gpkg --explain --torch 2.11 --cuda 130 flash-attn   # why a wheel was/wasn't selected
gpkg --doctor --torch 2.11 --cuda 130 flash-attn     # verify URLs are accessible
Cache management
gpkg --cache-info                    # show cache statistics
gpkg --cache-clean                   # clean all cached data
gpkg --cache-clean --older-than 1h   # clean entries older than 1 hour
When there's no wheel: compile fast
When gpkg add can't find a prebuilt wheel, it automatically builds from source with optimized settings:
- Detects your GPU arch via
nvidia-smi→ builds for only that arch - Uses all CPU cores (capped by RAM to prevent OOM)
- Enables ninja for parallel builds
- Caches the built wheel so you never compile the same package twice
You can also use build-env.sh manually:
source build-env.sh
uv add causal-conv1d    # 5-10x faster than default
How it works
- Checks the hosted registry at
wheels.mapika.devfor cached wheels (fast) - Falls back to GitHub releases API and pip find-links indexes
- Matches wheels against your torch + cuda + python + platform
- Picks the best match per package (latest version, prefers non-manylinux)
- If no wheel exists and
--build-missingis set, compiles from source - Emits a valid
pyproject.tomlwith[tool.uv.sources]pointing at direct URLs
Registry
The registry tracks 9 sources across 7 packages:
| Package | Sources |
|---|---|
| flash-attn | mjun0812/flash-attention-prebuild-wheels, Dao-AILab/flash-attention |
| flash-attn-3 | mjun0812/flash-attention-prebuild-wheels |
| causal-conv1d | Dao-AILab/causal-conv1d |
| mamba-ssm | state-spaces/mamba |
| natten | SHI-Labs/NATTEN |
| grouped-gemm | fanshiqing/grouped_gemm |
| sageattention | woct0rdho/SageAttention, mobcat40/sageattention-blackwell |
Adding a source
Edit src/gpkg/registry.toml and open a PR:
[[sources]]
package      = "causal-conv1d"
description  = "causal-conv1d -- your torch 2.11 builds"
type         = "github"
repo         = "yourname/causal-conv1d-wheels"
wheel_name   = "causal_conv1d-{version}+cu{cuda}torch{torch}-{pytag}-{platform}.whl"
cuda_style   = "full"
scan_tags    = 5
Configuration
| Env var | Purpose |
|---|---|
GITHUB_TOKEN |
Raise API rate limit 60 to 5000 req/hr |
UVFORGE_TOKEN |
Bearer token for private registries |
UVFORGE_TOKEN_<HOST> |
Host-specific token (e.g. UVFORGE_TOKEN_WHEELS_MYCO_COM) |
UVFORGE_REGISTRY |
Override default registry path/URL |
Private registries also support ~/.netrc for credential storage.
CI Usage
- name: Install GPU packages
  env:
    GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
  run: |
    pip install gpkg
    gpkg add flash-attn causal-conv1d mamba-ssm
For machine-readable output:
gpkg --list --json                           # all registered sources
gpkg --available flash-attn --json           # cuda/torch combos
gpkg --torch 2.10 --cuda 128 flash-attn --json  # resolved wheel URLs
Development
git clone https://github.com/Mapika/gpkg && cd gpkg
uv sync
uv run pytest -v
uv run ruff check src/
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for gpkg 0.4.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| gpkg-0.4.3.tar.gz | 1.8 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| gpkg-0.4.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.9 MB
Release files / gpkg-0.4.3.tar.gz
| Download URL | gpkg-0.4.3.tar.gz |
|---|---|
| Size | 1.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f28a5733acfe98c8747bf310af1da373d7a97cdd59142eebde0145f431627fbe
|
|
BLAKE2b-256 checksum How to use checksums |
dfd275a4c29d0a000c59019e272ead5d2444d9b0e56036cacfe63d5f8de2494a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.8.17
|
Release files / gpkg-0.4.3-py3-none-any.whl
| Download URL | gpkg-0.4.3-py3-none-any.whl |
|---|---|
| Size | 31.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f575f3d5cce8e6a198c6b478a158f51cf879e7cc208d37aa6840d108e9920a79
|
|
BLAKE2b-256 checksum How to use checksums |
ebb2d449d2a593a9f2c96021b46386c2606777c14eeee6154dddd9b6a4d6cb41
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.8.17
|
Security for gpkg 0.4.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














