
Train PyTorch on every GPU you can reach.
One Trainer, from your laptop to many machines, faster than Lightning.
Install ·
Quickstart ·
Performance ·
Why GPUlayer ·
AI agents ·
Architecture ·
Docs ·
Examples ·
Changelog
GPUlayer trains PyTorch models with one Trainer that runs the same script in your process,
on several GPUs of one machine, or across many machines: your laptop, workstations, servers,
clusters and cloud VMs. It picks machines and GPUs that can run the job, keeps a distributed
group on the best-connected GPUs and in one zone, starts every process, and brings back
logs, checkpoints and metrics. Against PyTorch Lightning, with the same model, data and
optimizer, it was faster in 10 of 11 GPU benchmarks (NVIDIA and Apple) and in every CPU
benchmark.
NVIDIA CUDA, Apple Metal (MPS) and CPU are validated; AMD ROCm is implemented and awaiting validation on AMD hardware. Under the Trainer is a general job engine, so commands and Python functions in any language or library run the same way. Documentation: gpulayer.dev/docs.
v0.7.0. Tested on CPU, Apple Silicon (PyTorch MPS and MLX) and an NVIDIA Tesla T4, on machines with several GPUs (4× RTX 3070, 2× A100 with NVLink: NCCL across all GPUs of a machine), and on up to 30 machines on Google Cloud. NCCL across machines is implemented but not validated yet; cloud provisioning covers Google Cloud. See Status and roadmap.
Install
pip install gpulayer
That's it. Check what this machine can run:
gpulayer resources detect
To train with PyTorch, install it too: pip install "gpulayer[torch]".
Other ways to install
| Method | Command |
|---|---|
| As a standalone CLI with uv | uv tool install gpulayer |
| Install script (own virtual environment, no sudo) | curl -fsSL https://raw.githubusercontent.com/antonellof/gpulayer/main/install.sh | sh |
| Docker | docker pull ghcr.io/antonellof/gpulayer:0.7.0 (also :0.7.0-torch; see deploy/docker) |
| Kubernetes (Helm) | helm install gpulayer deploy/kubernetes/helm/gpulayer -n gpulayer --create-namespace (see Kubernetes) |
| From source, to run the examples | git clone https://github.com/antonellof/gpulayer && cd gpulayer && pip install -e ".[dev,examples]" |
More in Installation.
Quickstart
import gpulayer.pytorch as glt

trainer = glt.Trainer(max_epochs=5, accelerator="cuda", devices=4, num_nodes=2)
trainer.fit(model, train_loader)          # 2 machines x 4 GPUs, DDP over NCCL
# The same script in this process, as 2-process DDP, or on 2 nodes: only the flags change
python examples/trainer_regression/train.py
python examples/trainer_regression/train.py --accelerator cpu --devices 2
python examples/trainer_regression/train.py --accelerator cpu --nodes 2 --devices 2

# More machines: run this on one of them, then paste the printed `gpulayer join` line on the others
gpulayer up

# See what ran
gpulayer dashboard
Not only PyTorch: any command or Python function runs the same way.
gpulayer submit --accelerator cuda --source ./app -- ./render.sh
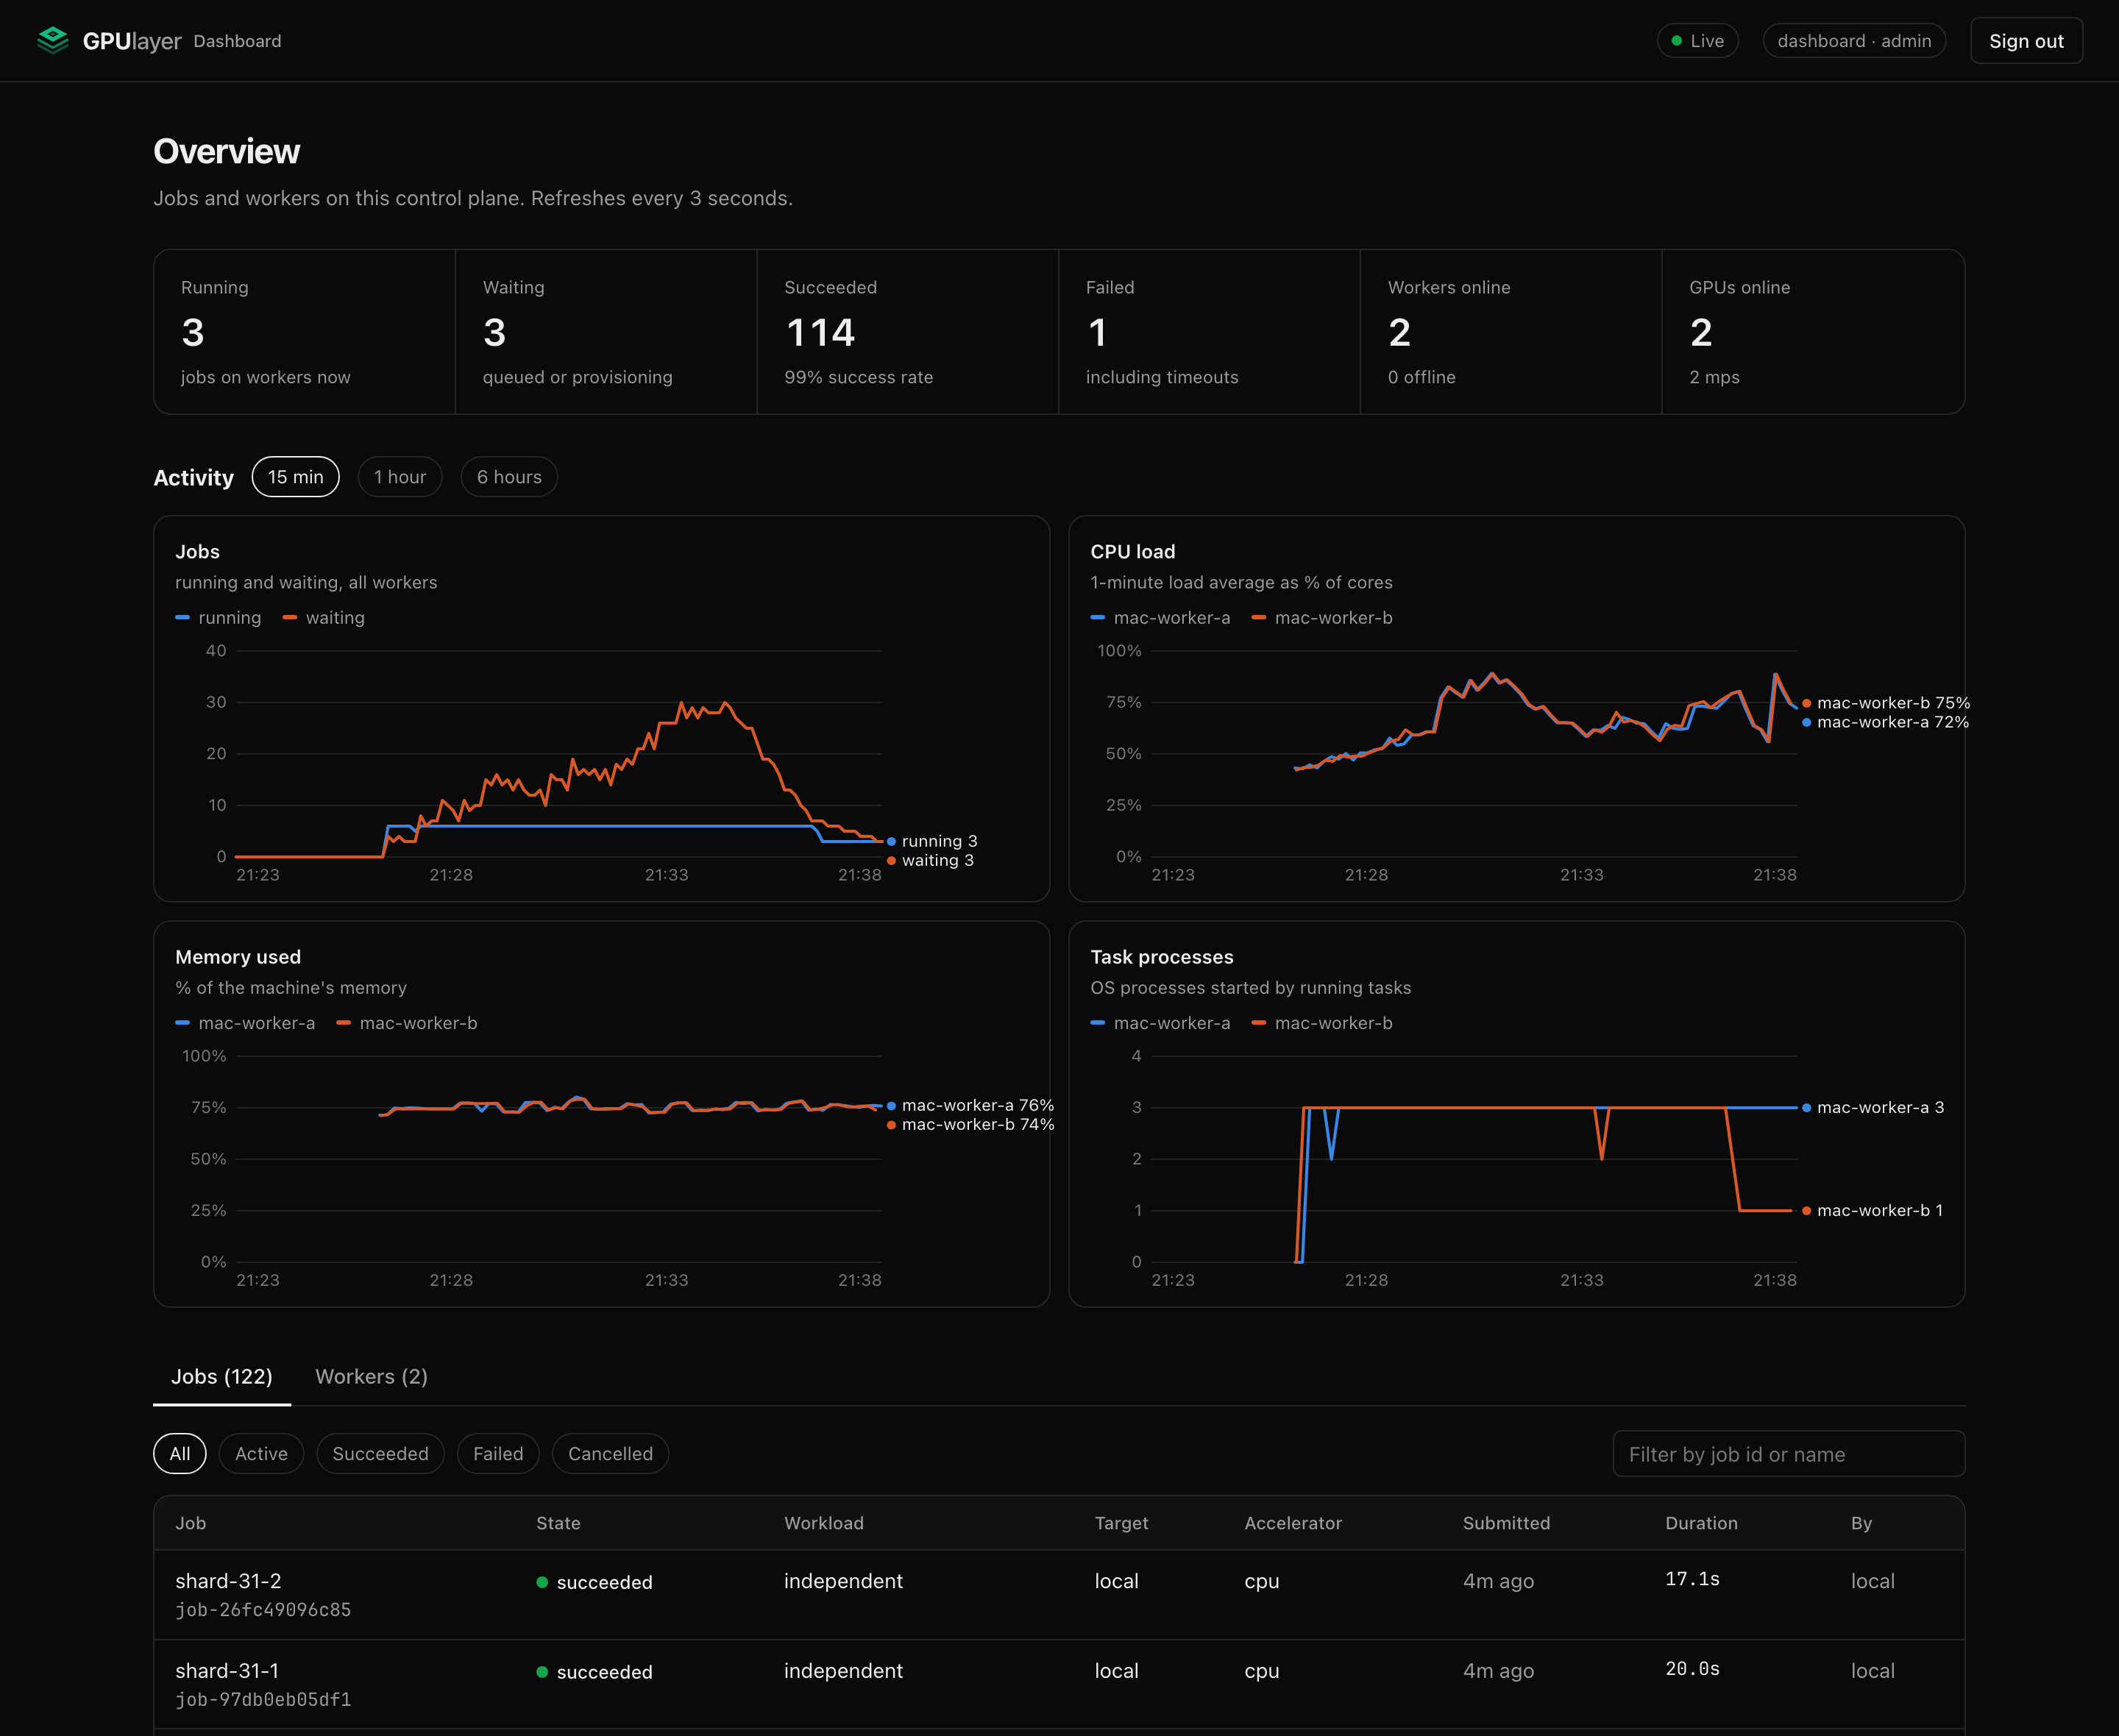
The full quickstart walks through each step with its output.
Performance and comparison
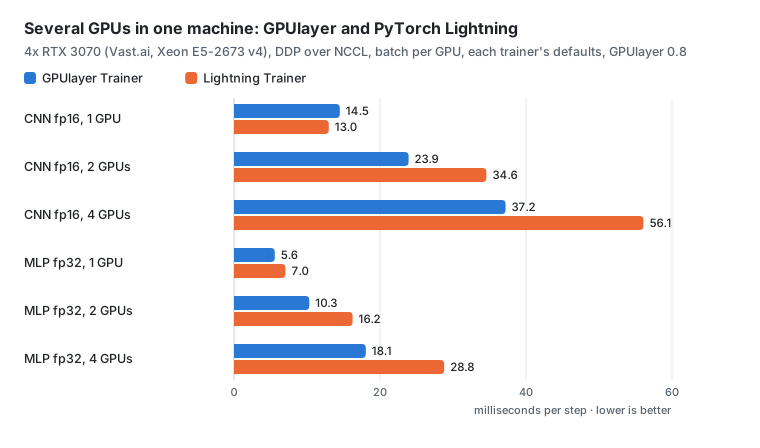
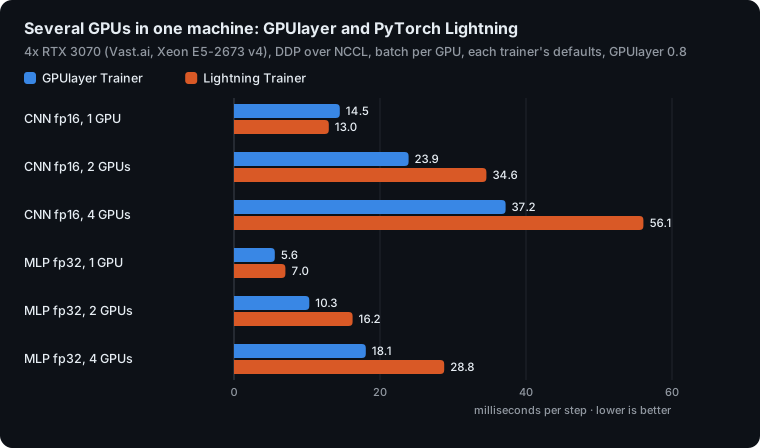
Measured on NVIDIA GPUs against PyTorch Lightning, with the same model, data and optimizer and each trainer's defaults:
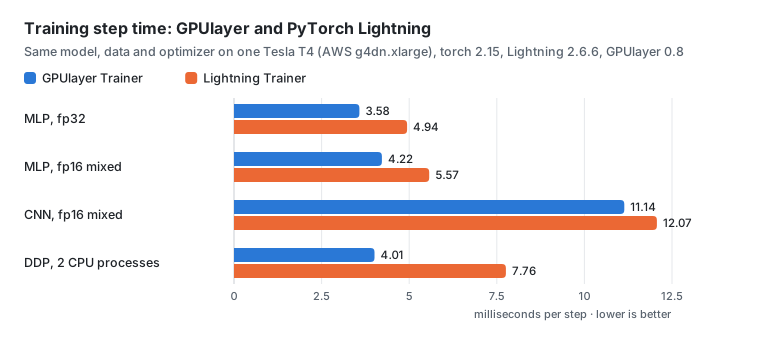
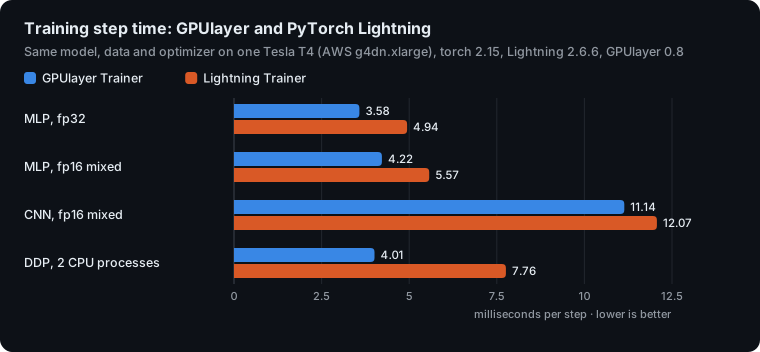
- One Tesla T4: GPUlayer's Trainer is 1.25 to 1.39x faster per step on small models and 1.14x on a compute-bound CNN, and starts 0.1 to 0.7 s sooner.
- 1, 2 and 4 RTX 3070s (DDP over NCCL): GPUlayer is faster in 5 of 6 cases, by 1.11 to 1.76x, with the lead growing with the number of GPUs; the 1-GPU CNN was 1.14x faster with Lightning on that host.
- NCCL across 4 GPUs and over NVLink (2x A100), and the best-connected GPU choice, validated on rented machines.
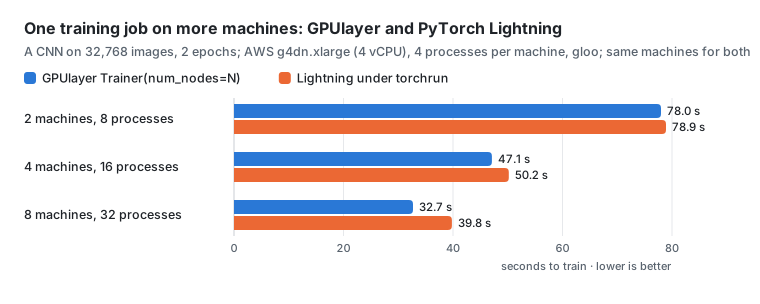
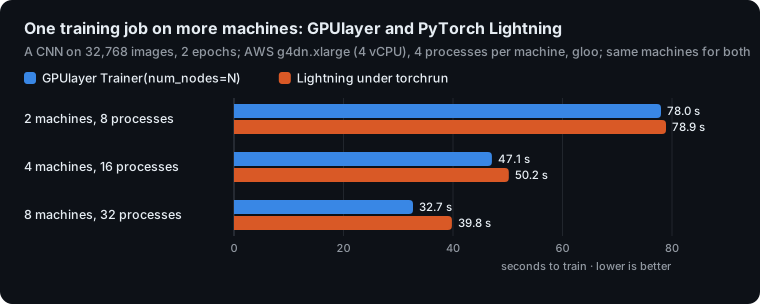
- One training job across machines on CPUs (gloo): GPUlayer trains 11.9% faster than
Lightning under torchrun on 8 machines (50.5 s vs 57.3 s; 5.3% on 4, 1.6% on 2), and it
starts every machine from one
Trainer(num_nodes=N)call. - Placement: the same 4-machine job took 42.5 s when GPUlayer kept it in one zone and 58.8 s when it was spread across two GCP regions (median of five, placed by the scheduler).
- Distributed jobs start 1.1 to 2.3 s faster than through torchrun; tested on up to 16 machines (32 processes) and 30 workers across two GCP regions.
- Across two machines: a distributed job spanning both, fail-fast in 2.7 s, and 55.6 small jobs per second.
Method, all charts and raw logs:
Performance and comparison. Reproduce them
with benchmarks/.
Why GPUlayer
Most GPU code assumes the GPU is on the machine where you run it. With GPUlayer you describe what a workload needs (an accelerator, GPU memory, frameworks) and it runs on a machine that has it, wherever that machine is.
| Situation | Without GPUlayer | With GPUlayer |
|---|---|---|
| Code on a laptop, GPU elsewhere | ssh, copy code, rebuild the environment, tmux, copy results back | gpulayer submit --target remote -- <cmd> |
| Several GPU machines | track free machines by hand; jobs crash on the wrong GPU or library | one queue; each job lands where it can run, or is rejected with the reason |
| NVIDIA servers and Apple Silicon Macs | separate scripts and setup per machine | ask for cuda or mps; one interface |
| Many independent tasks | loops and ad hoc scripts | fn.map([...]) across free GPUs |
| Multi-node training | torchrun on every node with matching ranks and addresses |
Trainer(num_nodes=2, devices=4); the machines are kept in one zone or rack when possible |
On one machine with one GPU, running your code directly is simpler. GPUlayer runs services without a load balancer in front of them, and is not a sandbox for untrusted code. More in Why GPUlayer.
For AI and coding agents
gpulayer mcp is an MCP server, so Claude Code, Claude Desktop, Cursor, Codex and VS Code
agents can list GPUs, submit jobs, wait, read logs and download outputs. An
Agent Skill covers agents that use the CLI.
claude mcp add gpulayer -- gpulayer mcp
See AI and coding agents.
Architecture
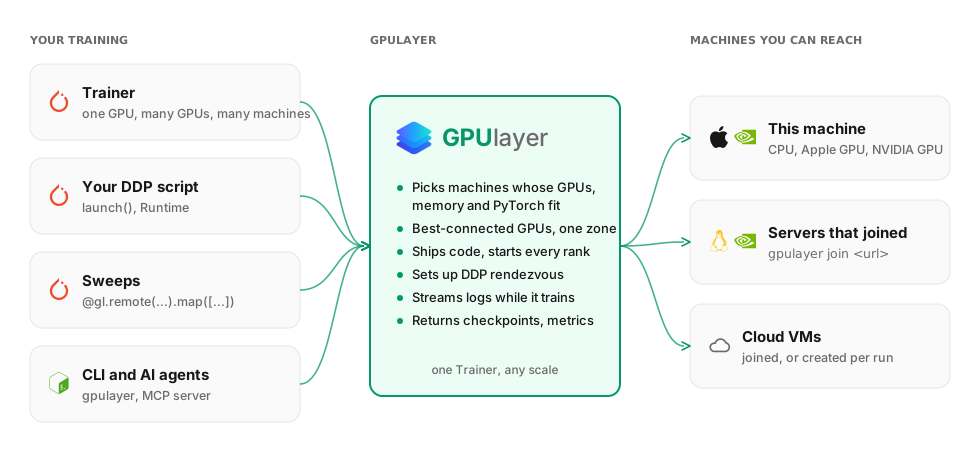
GPUlayer has three parts:
- Clients submit work: the
gpulayerCLI, the Python SDK (@gl.remote,gl.Client), the PyTorchTrainerandlaunch(), and the MCP server for AI agents. A job states what it needs (accelerator, GPU count and memory, frameworks), not which machine to use. - The control plane keeps the job queue, picks a worker for each job and records the
reason when no worker fits. Distributed groups stay in one network group, zone or region
when possible, and multi-GPU jobs get the best-connected GPUs on a machine. It stores code bundles, inputs, outputs and logs, and checks
tokens. For work on one machine it runs inside your process; for several machines it runs
as a server (
gpulayer up). - Workers, one per machine, report their GPUs and installed frameworks, ask the control
plane for tasks, run them as normal processes (one per rank for distributed jobs),
stream logs back and upload outputs. Workers open every connection themselves, so they can
sit behind NAT. A cloud VM is a worker that joined with
gpulayer join.
A job goes from queued to scheduled when a worker fits, then running, and ends as
succeeded, failed, cancelled or timed_out. Frameworks such as PyTorch, JAX, MLX and
CuPy still decide how the computation uses the GPU; GPUlayer decides which GPU runs it. More in
Architecture overview.
Development
uv pip install -e '.[dev,examples]'
.venv/bin/pytest && .venv/bin/ruff check src tests && .venv/bin/mypy src
See Contributing.
License
Apache License 2.0, see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for gpulayer 0.7.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| gpulayer-0.7.0.tar.gz | 2.3 MB | With provenance | Details for gpulayer-0.7.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| gpulayer-0.7.0-py3-none-any.whl | Python 3 | none | any | Details for gpulayer-0.7.0-py3-none-any.whl |
Total release size: 2.5 MB
Release files / gpulayer-0.7.0.tar.gz
| Download URL | gpulayer-0.7.0.tar.gz |
|---|---|
| Size | 2.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
addf1c56adf2e8592d7c432a804f4b204f83b742309f6de980b5611fd00dd142
|
|
BLAKE2b-256 checksum How to use checksums |
362ce13abed4b2f0b0e80e24c1eaf6b7b2dac5251205e7c861a109a4281a529a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 31, 2026.
Transparency logRelease files / gpulayer-0.7.0-py3-none-any.whl
| Download URL | gpulayer-0.7.0-py3-none-any.whl |
|---|---|
| Size | 176.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0aa90214585dc028fe0dd3daa54e15638d75745f758c1f25c48d2ee44e67fa46
|
|
BLAKE2b-256 checksum How to use checksums |
3b23c31fa55b9d2d8f8953284284f3db691435824072398fda86d298e4ea859c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 31, 2026.
Transparency logSecurity for gpulayer 0.7.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for gpulayer-0.7.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 31, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














