
grab-sampler is an efficient PyTorch-based sampler that supports GraB-style
example ordering by Online Gradient Balancing.
GraB algorithm takes O(d) extra memory and O(1) extra time compared with Random
Reshuffling.
Proposed in the paper GraB: Finding Provably Better Data Permutations than Random Reshuffling, GraB (Gradient Balancing) is a data permutation algorithm that greedily choose data orderings depending on per-sample gradients to further speed up convergence of neural network training empirically. Recent paper Tighter Lower Bounds for Shuffling SGD: Random Permutations and Beyond shows that GraB provably achieves optimal convergence rate among arbitrary data permutations on SGD. Observation shows that not only does GraB allow fast minimization of the empirical risk, but also lets the model generalize better on multiple deep learning tasks.
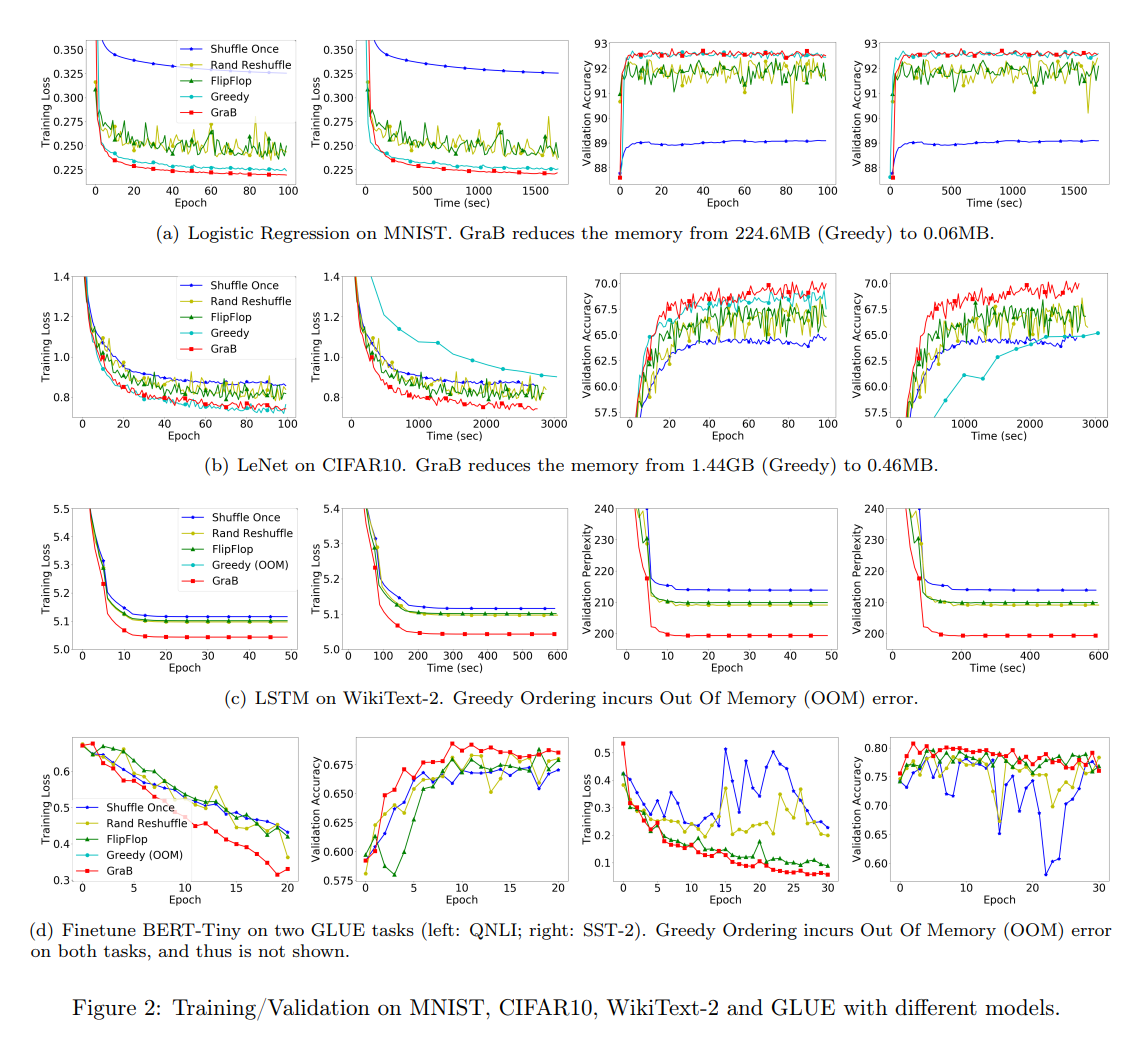
Supported GraB Algorithms
- Mean Balance (Vanilla GraB, default)
- Pair Balance
- Recursive Balance
- Recursive Pair Balance
- Random Reshuffling (RR)
- Various experimental balance algorithms that doesn't provably outperform Mean Balance
In terms of balancing, all of the above algorithm supports
- Deterministic Balancing (default)
- Probabilistic Balancing
Per-sample gradients, PyTorch 2, and Functional programming
GraB algorithm requires per-sample gradients while solving the herding problem. In general, it's hard to implement it in the vanilla PyTorch Automatic Differentiation (AD) framework because the C++ kernel average the per-sample gradients within a batch before it is passed to the next layer.
PyTorch 2 integrates Functorch that supports efficient computation of Per-sample Gradients. Alas, it requires a Functional programming style of coding and requires the model to be pure functions, disallowing layers including randomness (Dropout) or storing inter-batch statistics (BathNorm).
Example Usage
To train a PyTorch model in a functional programming style using per-sample gradients, one is likely to write a script like
import torch
import torchopt
from torch.func import (
    grad, grad_and_value, vmap, functional_call
)
from functools import partial

from grabsampler import GraBSampler

# Initiate model, loss function, and dataset
model = ...
loss_fn = ...
dataset = ...

# Transform model into functional programming
# https://pytorch.org/docs/master/func.migrating.html#functorch-make-functional
# https://pytorch.org/docs/stable/generated/torch.func.functional_call.html
params = dict(model.named_parameters())
buffers = dict(model.named_buffers())

# initiate optimizer, using torchopt package
optimizer = torchopt.sgd(...)
opt_state = optimizer.init(params)  # init optimizer

###############################################################################
# Initiate GraB sampler and dataloader
sampler = GraBSampler(dataset, params)  # <- add this init of GraB sampler
dataloader = torch.utils.data.DataLoader(dataset, sampler=sampler)


###############################################################################


# pure function
def compute_loss(model, loss_fn, params, buffers, inputs, targets):
    prediction = functional_call(model, (params, buffers), (inputs,))

    return loss_fn(prediction, targets)


# Compute per sample gradients and loss
ft_compute_sample_grad_and_loss = vmap(
    grad_and_value(partial(compute_loss, model, loss_fn)),
    in_dims=(None, None, 0, 0)
)  # the only argument of compute_loss is batched along the first axis

for epoch in range(...):
    for _, (x, y) in enumerate(dataloader):
        ft_per_sample_grads, batch_loss = ft_compute_sample_grad_and_loss(
            params, buffers, x, y
        )

        #######################################################################
        sampler.step(ft_per_sample_grads)  # <- step compute GraB algorithm
        #######################################################################

        # The following is equivalent to
        # optimizer.zero_grad()
        # loss.backward()
        # optimizer.step()
        grads = {k: g.mean(dim=0) for k, g in ft_per_sample_grads.items()}
        updates, opt_state = optimizer.update(
            grads, opt_state, params=params
        )  # get updates
        params = torchopt.apply_updates(
            params, updates
        )  # update model parameters
Experiment Training Scripts
- Image Classification ( CIFAR-10, MNIST, etc)
- Causal Language Modeling ( Wikitext-103, OpenWebText, etc)
How does grab-sampler work?
The reordering of data permutation happens at the beginning of each training
epoch, whenever an iterator of the dataloader is created,
e.g. for _ in enumerate(dataloader): internally calls __iter__() of the
sampler and updates the data ordering.
1 maintainer

Release files for grab-sampler 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| grab-sampler-0.1.3.tar.gz | 23.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| grab_sampler-0.1.3-py2.py3-none-any.whl | Python 3, Python 2 | none | any | Details |
Total release size: 63.1 kB
Release files / grab-sampler-0.1.3.tar.gz
| Download URL | grab-sampler-0.1.3.tar.gz |
|---|---|
| Size | 23.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
bdf98f39d16744f029982b969828a3f9ed3e475dbde79155c7b181d7639650ea
|
|
BLAKE2b-256 checksum How to use checksums |
bec0dee2d2f21003b9fc0b09b0964f970c146fa9dc2491707494ca9156a73130
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.10.12
|
Release files / grab_sampler-0.1.3-py2.py3-none-any.whl
| Download URL | grab_sampler-0.1.3-py2.py3-none-any.whl |
|---|---|
| Size | 39.5 kB |
| Tags | Python 2 Python 3 |
|
SHA-256 checksum How to use checksums |
b1184f41a91f1d23710c384f514db810dd7621dd1120ee808720bd16ff3dee69
|
|
BLAKE2b-256 checksum How to use checksums |
5dd998bc9a402aa701e814b6896e8d3d5655d826126495a94adfaa255673dcfe
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.10.12
|














