
Granite Switch — Build AI models like you build software


| Browse adapter functions | Pre-composed Models on HF | Tutorials |
Software is built from libraries — you pick the ones you need, compose them, and ship. Granite Switch brings this to AI models: choose adapter functions for RAG, safety, factuality, and more, compose them into a single model, and deploy with one command. Swap or upgrade any component independently, just like updating a dependency.
An adapter function is a LoRA adapter trained to a specific input/output contract — a score, a decision, a rewritten query — with the output schema enforced at the token level by Mellea. This is what makes them composable as software: each function has a known signature, not just a general-purpose text output.
Small models with the right adapter functions consistently outperform much larger generalist models on targeted tasks. Activated LoRA (aLoRA) makes this practical at scale: all adapter functions share one KV cache, activating on demand — so one deployment serves many capabilities with no memory or latency overhead.
Key Features
- Composable — Combine independently developed adapter functions into one checkpoint, whether IBM's or yours. Swap, upgrade, or customize without retraining.
- Fast — Built on IBM's Activated LoRA technology for efficient KV cache reuse, low latency, and high inference throughput.
- Accurate — Task-specific adapter functions can match and even surpass the accuracy of significantly larger generalist models, while requiring only a fraction of the serving cost. See the adapter function catalog for benchmark comparisons across all 12 adapter functions.
- Inference-ready — Deploy with vLLM for production or HuggingFace for prototyping. Same checkpoint, no conversion step.
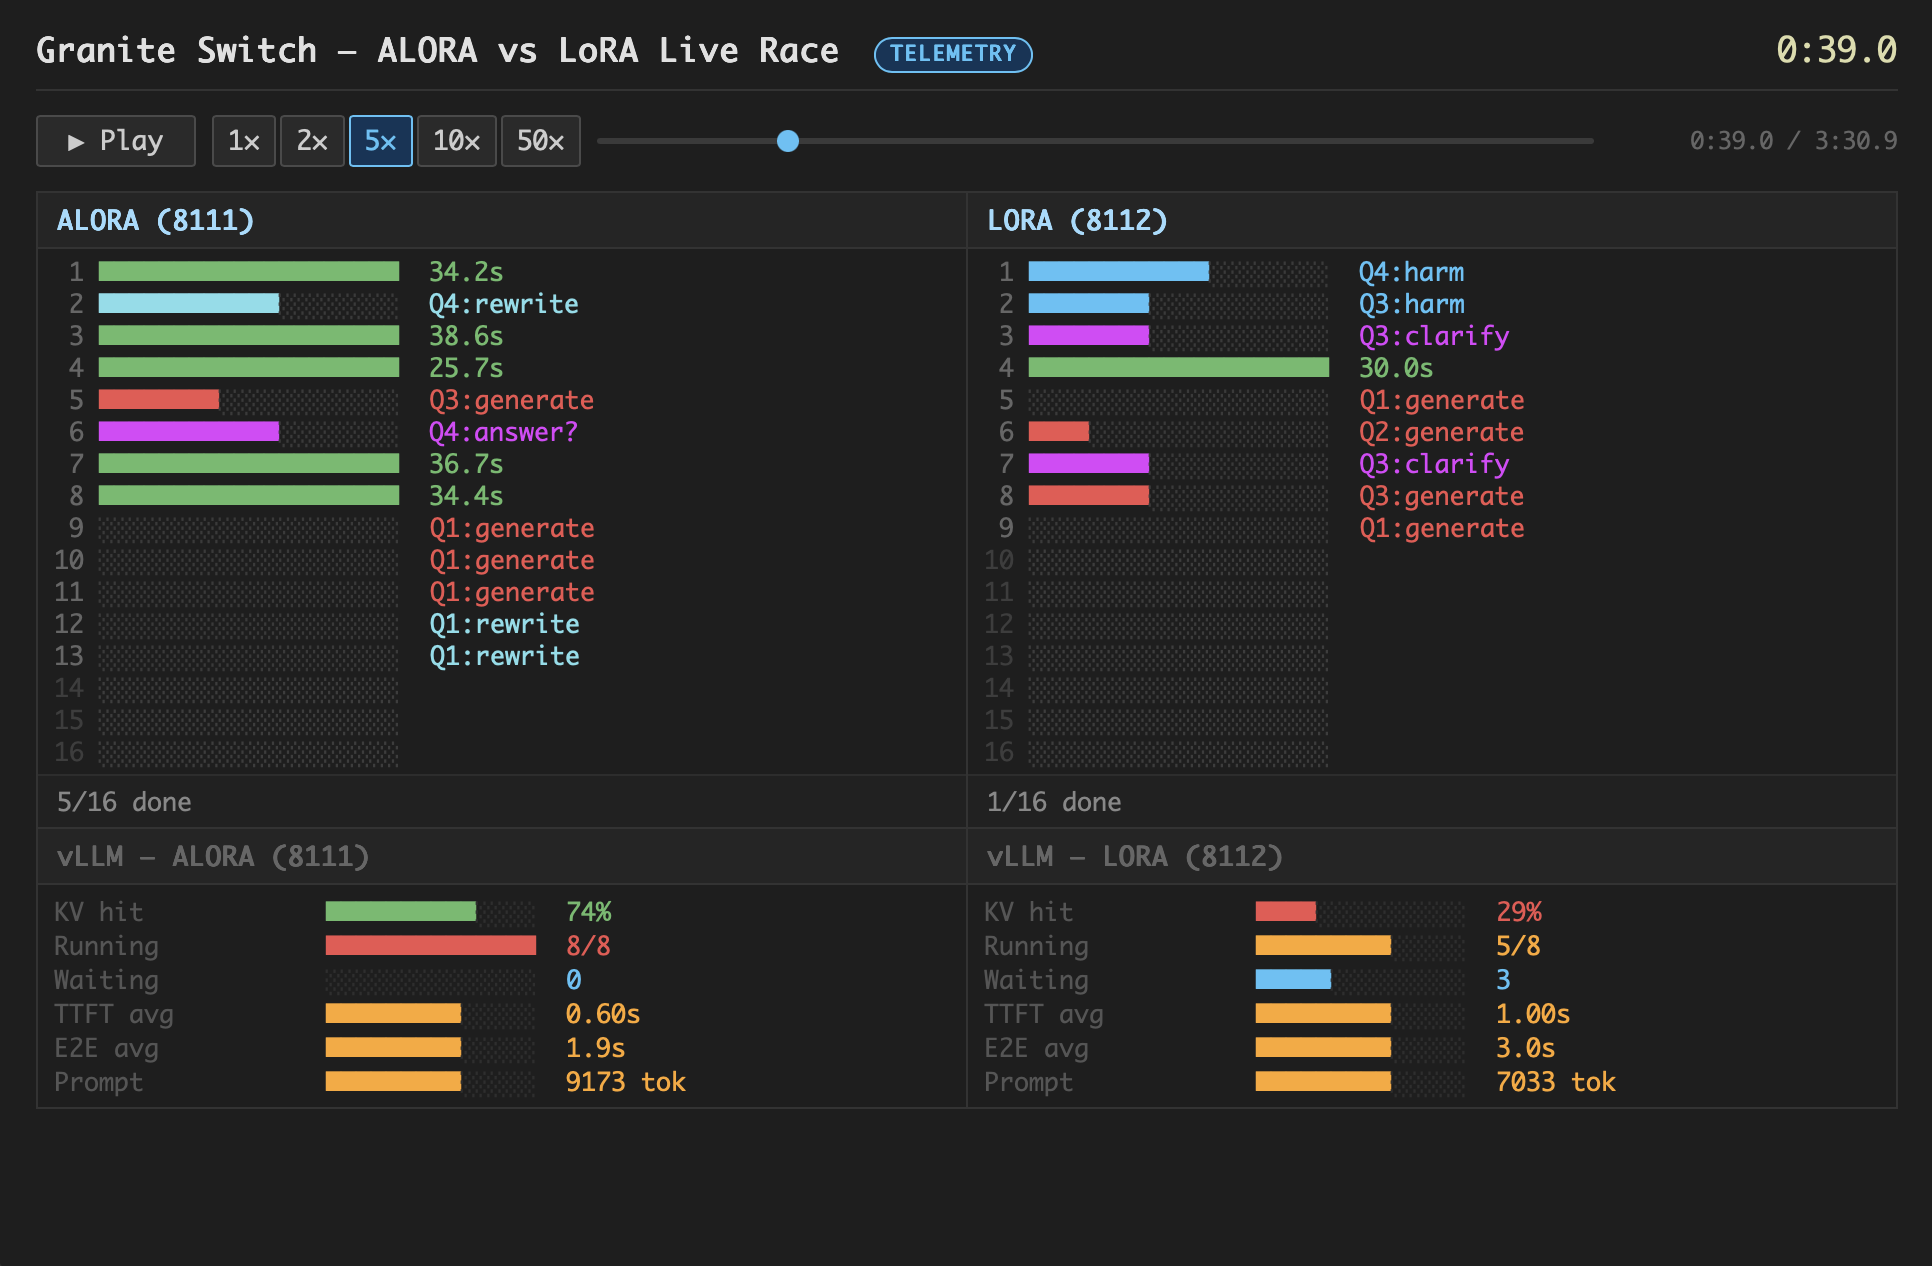
Live race telemetry: aLoRA (74% KV cache hit rate, 5/16 finished) vs LoRA (29% KV hit rate, 1/16 finished) — same model, same hardware, different adapter technology.
Reproduce it yourself on Colab →
Quick Start
Install
pip install "granite-switch[vllm]"
Other install options depending on your use case:
pip install "granite-switch[compose]"   # Compose modular models
pip install "granite-switch[hf]"        # HuggingFace inference
pip install "granite-switch[dev]"       # Everything
Requires Python 3.11+ and PyTorch 2.11+.
vLLM version note:
[vllm]accepts any line from0.26.xto0.30.x. The floor istransformers>=5.16:0.26is the earliest vLLM whose model code handles the transformers-5.13+full_attentionlayer-type rename. One tree serves all five lines — where their APIs differ, the backend checks for the capability rather than the version. All of them require PyTorch 2.11+ (CUDA 13+). To pin a single line for development, use thevllm26/vllm30dependency groups — the two ends of the range, which is also what CI tests on every GPU run.
Compose a Model
Compose a base Granite model with adapter libraries into a single deployable checkpoint:
python -m granite_switch.composer.compose_granite_switch \
  --base-model ibm-granite/granite-4.1-3b \
  --adapters ibm-granite/granitelib-core-r1.0 ibm-granite/granitelib-rag-r1.0  ibm-granite/granitelib-guardian-r1.0 \
  --output ./my-model
Use the adapter function composer to browse available adapter functions, compare benchmarks, and generate a ready-to-run compose command.
This downloads the base model, embeds compatible LoRA adapters (with a preference towards activated LoRA), adds control tokens and a chat template, and produces a model directory that works with both HuggingFace and vLLM.
Or skip composition and use a pre-composed model:
- ibm-granite/granite-switch-4.1-3b-preview
- ibm-granite/granite-switch-4.1-8b-preview
- ibm-granite/granite-switch-4.1-30b-preview
Run Inference
Tip: pre-download the model for faster startup. The first run will download several GB from Hugging Face, which can be slow. To download in advance using the fast transfer backend:
pip install "huggingface_hub[hf_transfer]"
huggingface-cli login                          # one-time, if not already logged in
HF_HUB_ENABLE_HF_TRANSFER=1 hf download ibm-granite/granite-switch-4.1-3b-preview
Subsequent runs will use the local cache automatically.
vLLM + Mellea (recommended):
pip install mellea
python -m vllm.entrypoints.openai.api_server --model ibm-granite/granite-switch-4.1-3b-preview --port 8000
from mellea.backends.openai import OpenAIBackend
from mellea.stdlib.components.chat import Message
from mellea.stdlib.components.intrinsic.guardian import guardian_check
from mellea.stdlib.context import ChatContext

backend = OpenAIBackend(
    model_id="ibm-granite/granite-switch-4.1-3b-preview",
    base_url="http://localhost:8000/v1",
    api_key="unused",
)
backend.register_embedded_adapter_model("ibm-granite/granite-switch-4.1-3b-preview")

ctx = ChatContext().add(Message("user", "Group X people are all lazy."))
score = guardian_check(ctx, backend, "social_bias", scoring_schema="user_prompt")
print(f"social_bias score: {score:.3f}")
# => social_bias score: 0.964
How It Works
With standard LoRA, each adapter is trained against its own KV distribution — so switching adapter functions across complex flow control means discarding and recomputing the KV cache at every step. aLoRA adapter functions are instead trained against a common normalized KV cache, so they can all coexist in a single checkpoint and activate on demand without cross-contamination:
- Control tokens — Each adapter function has a dedicated control token (e.g.,
<guardian>,<query_rewrite>). Placing the token in the input sequence is what triggers activation — the adapter function's LoRA weights apply from that position forward. - KV cache normalization — Because all adapter functions are trained against the same normalized KV cache, they never interfere with each other's internal state. Each activates on top of the shared base KV cache, which is what makes independent development, benchmarking, and composition possible without joint training.
- Prefill reuse — LoRA weights are selected per token position, not per request. Because all adapter functions share the same normalized KV cache, the prefill from earlier steps is reused rather than recomputed — eliminating the main latency cost of multi-adapter complex flow control.
Like functions in a software library, adapter functions can be developed and benchmarked independently or jointly. They compose into one deployable model that contains all capabilities, in analogy to statically linked object code.
Tutorials
New here? Start with a 5-minute notebook and work your way up:
| Notebook | What you'll build | Time | |
|---|---|---|---|
| Hello Mellea | Call adapters through a clean Python API | 5 min |  |
| RAG Flow | Query rewrite + answerability + citations in one model | 30 min | |
| Compose Your Own | Build a custom checkpoint from adapter function libraries | 15 min | |
All notebooks run on Colab. See tutorials/README.md for the full list and guided learning paths.
Ecosystem
Granite Switch is part of a coordinated stack:
- Granite Models — The base models that Granite Switch builds on. Granite 4.1 is available in 3B, 8B, and 30B parameter sizes on Hugging Face.
- Granite Libraries — Pre-trained adapter functions for RAG, safety, and core capabilities, published on Hugging Face. These are the components you compose into a Switch model.
- Mellea — Reliable, testable LLM output for Python. Type hints become schemas, docstrings become prompts, and valid output is enforced at the token level — not retried into existence. Mellea orchestrates Granite Switch adapter functions through an API built for complex flow control, handling control tokens and constrained decoding so you work with typed function calls, not raw tokens.
- Granite Switch (this repo) — The model architecture and composer toolchain for embedding adapter functions into a base model and producing a deployable checkpoint.
Contributing
Granite Switch was started by IBM Research and is developed in the open. We welcome bug reports, feature requests, and pull requests — see CONTRIBUTING.md for guidelines or open an issue.
License
Apache-2.0 — see LICENSE.


Release files for granite-switch 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| granite_switch-0.1.1.tar.gz | 238.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| granite_switch-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 500.1 kB
Release files / granite_switch-0.1.1.tar.gz
| Download URL | granite_switch-0.1.1.tar.gz |
|---|---|
| Size | 238.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0fa6edfb5bb389756661c580ad94d438ec90aa64c9774d2e9a9c000194e80337
|
|
BLAKE2b-256 checksum How to use checksums |
5a68694c414ae487abf7fb97c83c61c86f0aef7e4d86cb2bb79a848cf045fced
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.10
|
Release files / granite_switch-0.1.1-py3-none-any.whl
| Download URL | granite_switch-0.1.1-py3-none-any.whl |
|---|---|
| Size | 261.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a2aa3a9f9a042577b1d6dbe85ed80a0c4fea81ab7b78fc067eead1f1f33673b6
|
|
BLAKE2b-256 checksum How to use checksums |
9ead9b7772d393ccb0d49bb80d4bc3e4f22cb3c6e39f96659b7d11a26a8cd185
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.10
|














