





Groundlens is a proofreader for what your model writes. It marks the words your sources don't back — and shows you what each one should have said. It checks RAG answers for grounding and faithfulness against their retrieved sources, the job people reach for hallucination detection, citation checking, or RAG evaluation to do — and differs in returning marks and evidence for a reviewer rather than a verdict or a score to threshold.
QUESTION    What is the invoice total?
SOURCE      ...the total amount due is 10,000 dollars, payable within 30 days...
ANSWER      The invoice total is 1,000 dollars, due in 30 days.

GROUNDLENS  1,000   nothing supports this.   Closest in invoice.pdf#p1: '10,000'
It never tells you the answer is wrong. It tells you which word to look at, and which document to open. Thirty seconds of human attention instead of five minutes.
How it works
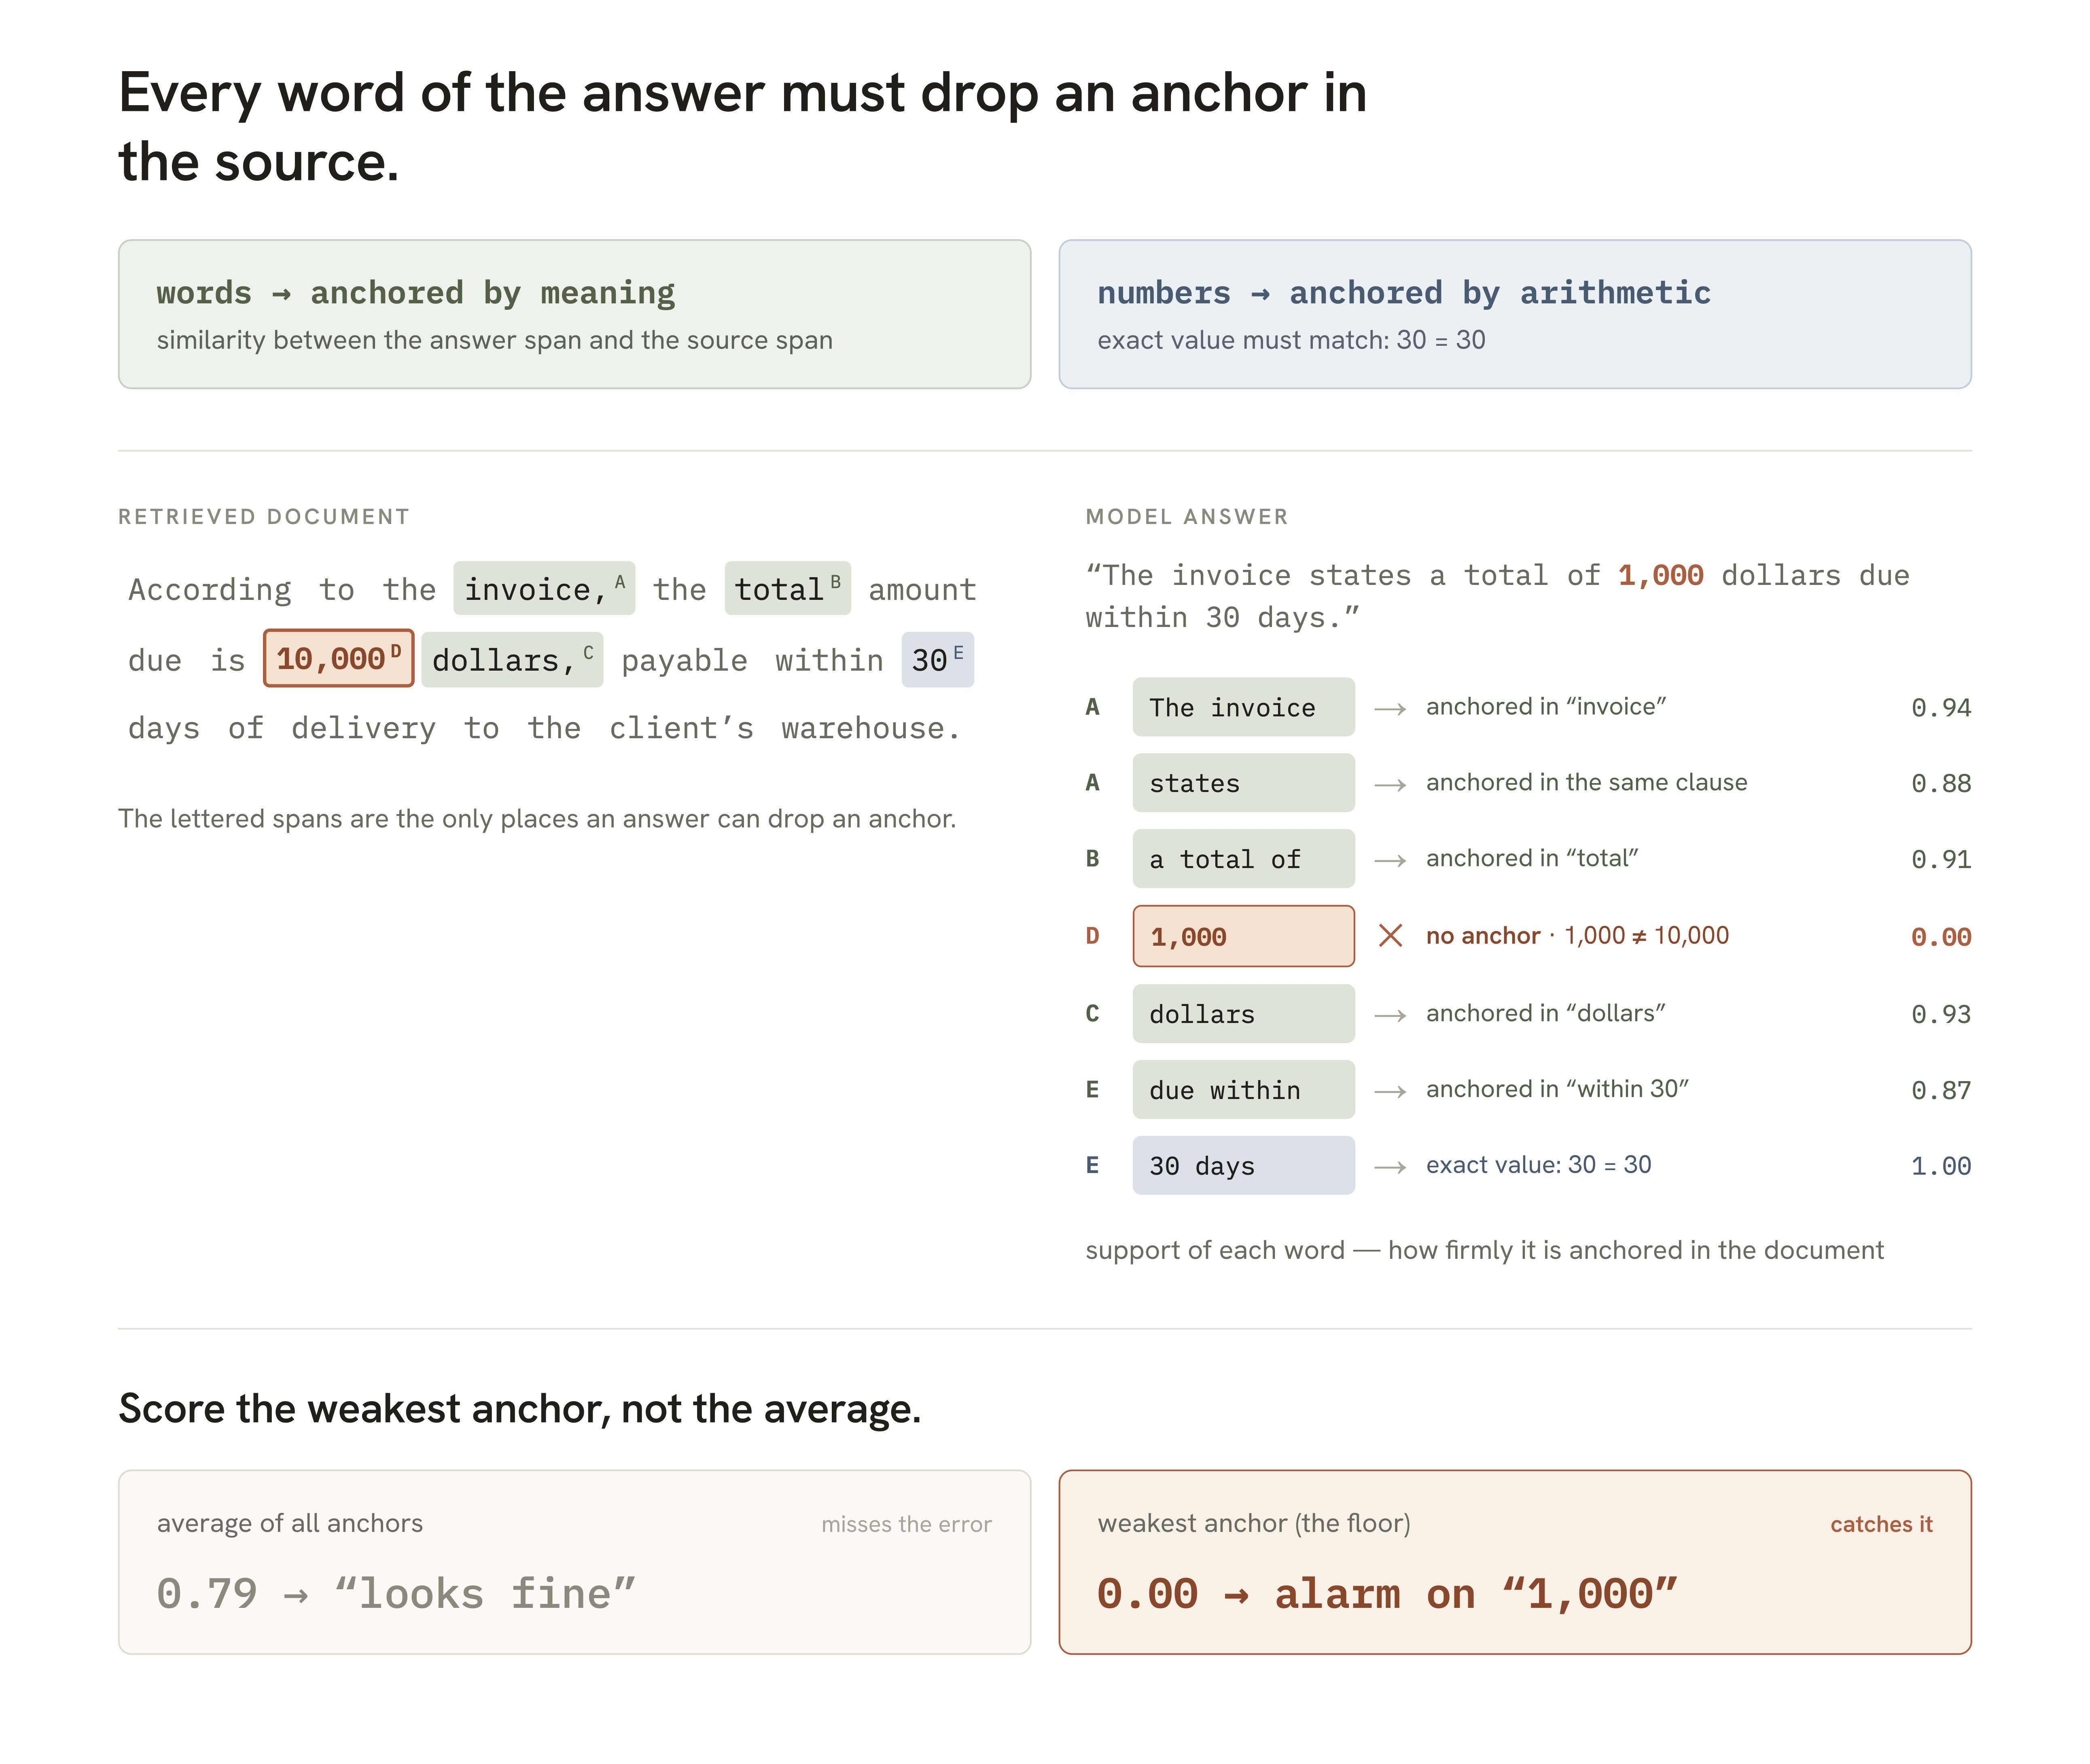
Groundlens approaches words and numbers comparison in two different ways:
| Words | Numbers |
|---|---|
| Words are anchored by meaning. A word's support is the highest cosine similarity it reaches against any word of the sources, using a frozen off-the-shelf encoder — the same kind your retrieval already uses. | Numbers are anchored by arithmetic. The numeral is parsed to a value with formatting normalised — 10,000, 10000, $10,000, 10 000 and (under a declared locale) 10.000 are one number — then checked against every value in the sources. Support is exactly 1.0 or exactly 0.0. Similarity is not allowed to vote. |
Groundlens provide the lowest score as output, not the average. Every token-similarity metric aggregates by the mean, and the mean is where single-token errors go to die.
A practical example: ten is not a hundred
A retrieved document says the total due is 10,000 dollars. The answer says 1,000 dollars. A human catches that instantly, without a finance degree.
Embedding similarity does not. Cosine between the right answer and the wrong one is about 0.99 — the error dissolves into the vector the way a drop of ink dissolves in a pool. An LLM judge does not either: it reads for plausibility, and "the total is 1,000 dollars" is a perfectly plausible sentence about an invoice. A trained span detector does not, because single-digit substitutions are rare in its training labels.
Sentence encoders organise text by vocabulary, topic and structure. Never by truth. A wrong number inside a correct sentence is, to a paraphrase-collapsing encoder, very nearly a paraphrase.
On that invoice, the mean support of the wrong answer is 0.79 — which looks fine. The weakest anchor is 0.00 — which is a mark in the margin.
Operational threshold
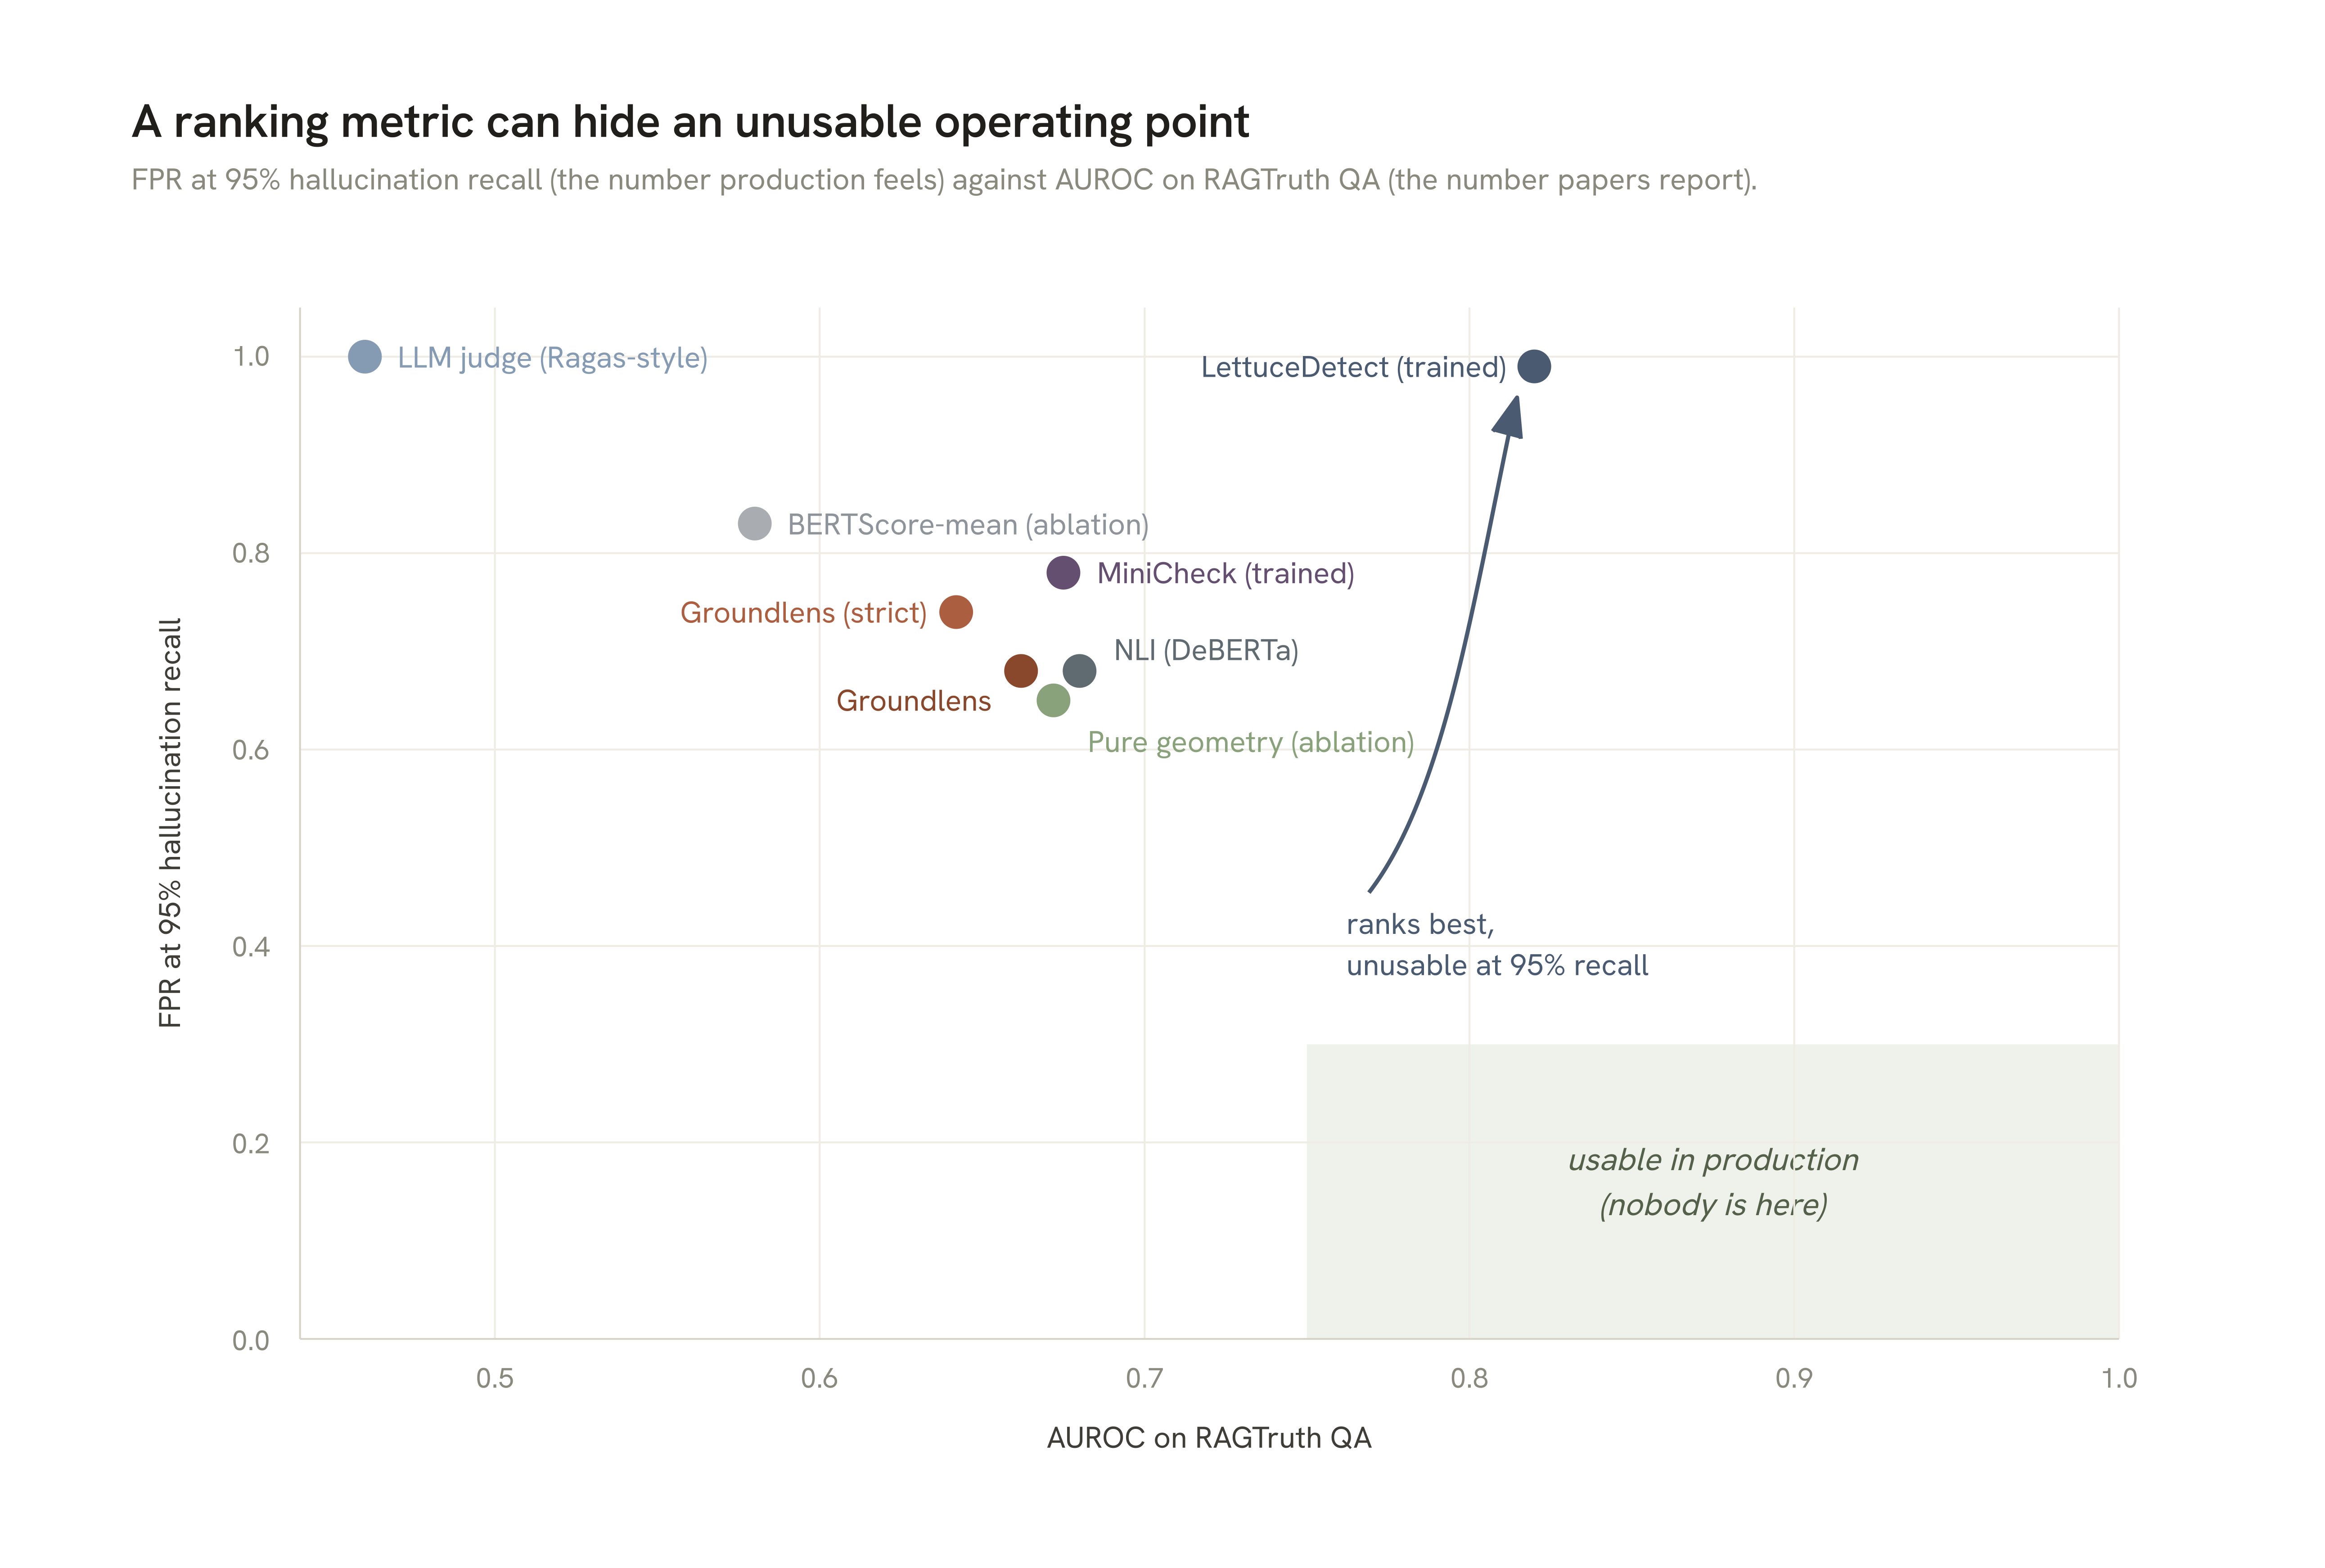
This library has no default threshold. A threshold is a property of a deployment, not of a method. It depends on the encoder, on your data, and on what a false positive costs you compared to a false negative. None of that is known here.
There is a measurement behind the rule. Across the operating-point grid we ran, the best false positive rate at 95 percent recall was 0.65, for every single-pass detector we tested, including this one. At the recall a regulated review actually needs, no fixed cut in that grid is usable. Shipping one would mean shipping a number we already know does not hold.
What groundlens provide is:
- A support score per word, where lower means less supported by the sources.
- Marks with receipts: the word, its span, its support, and the nearest evidence sentence, so a reviewer can check any call in seconds.
- A function
calibrate(), which fits a cut on your own labelled data. It refuses to run on fewer than 200 labelled examples, because below that the cut is noise.
If you need a threshold in your pipeline, run calibrate() on your labelled data:
from groundlens import calibrate

point = calibrate(labelled, target_recall=0.95)
print(point.threshold, point.fpr, point.fpr_ci95)   # read the fpr first
calibrate()needs at least 200 labelled examples, because below that a 95%-recall threshold is estimated from a handful of points.
Install
pip install groundlens              # zero runtime dependencies. Not numpy, not torch
pip install "groundlens[encoder]"   # + the reference sentence encoder
pip install "groundlens[encoder,mcp]"   # + the MCP server, for Claude Desktop and friends
The core install pulls in no package at all, and a CI job fails the build if that ever changes. The previous version installed roughly two gigabytes of deep learning stack before you had done anything.
Quick start
from groundlens import proofread, SentenceTransformerEncoder

answer = "The invoice total is 4.75% payable within 45 days."
sources = [("policy.pdf#p3", "The rate stated in the policy is 3.90% and the term is 30 days.")]

marks = proofread(answer, sources, encoder=SentenceTransformerEncoder(), k=2)

print(marks.report())
#  4.75%   support 0.00    nearest in policy.pdf#p3: '3.90%'
#  45      support 0.00    nearest in policy.pdf#p3: '30'
Every mark carries its receipt:
for anchor in marks.weakest:
    anchor.text            # '4.75%'          the word in the answer
    anchor.span            # (21, 26)         where it sits
    anchor.kind            # 'numeral'        checked by arithmetic, not meaning
    anchor.support         # 0.0              absent from the sources
    anchor.evidence_id     # 'policy.pdf#p3'  which document to open
    anchor.evidence_text   # '3.90%'          what it should have matched
From the shell:
groundlens read --answer answer.txt --context policy.pdf#p3=policy.txt
MCP server
The same proofreader, inside your assistant. Groundlens ships an MCP server, so Claude Desktop, Claude Code, Cursor, VS Code or any other MCP client can check an answer against its sources without leaving the conversation. It runs locally over stdio. No text goes anywhere.
pip install "groundlens[encoder,mcp]"
python -m groundlens.mcp
Then point your client at it. In claude_desktop_config.json — or the equivalent
mcp.json in Cursor and VS Code:
{
  "mcpServers": {
    "groundlens": {
      "command": "python",
      "args": ["-m", "groundlens.mcp"]
    }
  }
}
Use the absolute path to the Python that has Groundlens installed if it is not
the one on your PATH: /path/to/venv/bin/python.
The one tool
find_unsupported_words(answer, sources, k=4, locale="und")
answer |
the model output to check |
sources |
[{"id": "policy.pdf#p3", "text": "..."}]. The id comes back in the findings, so the reader knows which document to open |
k |
how many of the weakest anchors to return |
locale |
how these documents write numbers. es reads 1.234 as 1234, en reads it as 1.234, und keeps both readings |
It returns the weakest anchors with their receipts, the floor, the encoder id and
a sha256 of the finding:
{
  "weakest_anchors": [
    {
      "word": "4.75%",
      "support": 0.0,
      "checked_by": "arithmetic",
      "closest_in_sources": "3.90%",
      "source_id": "policy.pdf#p3",
      "notes": []
    }
  ],
  "floor": 0.0,
  "n_marked": 12,
  "encoder_id": "all-mpnet-base-v2@<revision-sha>",
  "sha256": "..."
}
One tool, on purpose. The previous server advertised three, and that is how one product turns into three stories before anyone has installed it.
There is no verdict and no threshold, here as everywhere else in this library. A
support of 0.00 on a number means that value is absent from the sources. On a
word it means no lexical anchor was found, which is ordinary in a faithful
paraphrase. The server reports the marks; the reader decides.
The encoder loads on the first call, not at startup, and the model downloads once (about 420 MB) the first time it is used.
Limitations
- It cannot verify computed values — "revenue tripled" against a source saying "revenue went from 5M to 15M".
- The word channel checks whether a word is supported by the sources. It does not check that it is attached to the right thing. If an answer says "payable in 30 days" about invoice A and the 30 days belong to invoice B elsewhere in the same context, the word is supported and no mark appears.
- It cannot check reasoning. That belongs to entailment models.
- It inherits your retrieval. If the passage is wrong, so is the answer's grounding.
- Segmentation assumes space-delimited scripts, and warns rather than pretending when the text is largely CJK or Thai.
Reproducibility
-
The numeral channel is exact. Decimal comparison, fixed arithmetic context, locale from an argument and never from
LC_ALL. Byte-for-byte identical on any machine — CI proves it on ten OS × Python combinations underPYTHONHASHSEED=randomand a Turkish locale. -
The lexical channel is a float32 cosine from a pinned encoder revision — not a model name, because a silent re-upload would change every number you ever published. It reproduces to 1e-6 across platforms and the ordering of the weakest anchors is stable. It is not bit-identical between x86 and Apple Silicon, and we make no claim that it is.
-
marks.sha256covers the structure and the numeral supports exactly, and rounds lexical supports to six decimals. Reproducing the hash reproduces the finding, not the last bits of the arithmetic.
groundlens.dev · Docs · PyPI · Contributing · Apache-2.0
Libary developed by Javier Marín, June 2026 (javier@jmarin.info)
1 maintainer

Release files for groundlens 3.0.5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| groundlens-3.0.5.tar.gz | 1.4 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| groundlens-3.0.5-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.4 MB
Release files / groundlens-3.0.5.tar.gz
| Download URL | groundlens-3.0.5.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
747ff47c4ae274832ec12dd2d93662879b1d0ad4f807dc54fe00e535faf34014
|
|
BLAKE2b-256 checksum How to use checksums |
0f61df337fe53bffde77372d159670851777bdc483b1b835fb5452920139c8b6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 23, 2026.
Transparency logRelease files / groundlens-3.0.5-py3-none-any.whl
| Download URL | groundlens-3.0.5-py3-none-any.whl |
|---|---|
| Size | 40.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6cbdcc3807f280ac28514e636d25f13d91b6d205b1ea77fccbde4328c7189227
|
|
BLAKE2b-256 checksum How to use checksums |
cb30bd42b0d53a2796376e0a706c69c118a0a2344853af1dbbc0b17f97cf6a7a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 23, 2026.
Transparency log













