

hal0 turns a Linux box — ideally a Ryzen AI Max+ 395 with 128 GB of unified
memory — into a private, OpenAI-compatible inference appliance. Chat,
completions, embeddings, reranking, transcription, speech and image
generation all answer on one :8080/v1 surface, on hardware you own, with
no per-token bill.
Every inference workload runs as its own podman container under a
hal0-slot@<name>.service unit. hal0-api on :8080 is the sole control
plane — it owns slot state machines, dispatches /v1/* requests to the right
slot port, and serves the dashboard. No shared inference daemon; no extra
process to babysit.
curl -fsSL https://hal0.dev/install.sh | sudo bash
v1.6.5 is the current stable release. A release on the 1.6 line (2026-10-24): FastFlowLM 1.0.10 run from its runner image, privilege hardening, and fixes, with no config-schema migration and an ordinary
hal0 updatefrom any 1.4.x or later box; a 1.3.x box hops through 1.5.0 first. It removes four CLI spellings that had a second name (hal0 agent upgrade hermes --to,hal0 update owui,hal0 agent bootstrap hermes,hal0 uninstall --keep-data/--clean-slate); read the 1.6.5 Breaking notes for the replacements. With Hermes v0.22.4, a chat opened for a non-default profile andhermes chatneed the Hermes gateway running. Since 1.4.0, three changes can break a script or a setup:hal0 updatenow restarts slots whose runner image changed and exits 2 while any still run the old one; exposing a user-installed MCP server to Hermes or the brain profile is refused until hal0 enforces its tool policy; and an installed MCP server that would send its secrets over plainhttp://to another host no longer loads. After updating from before 1.6.0, re-run the installer once to pick up the new Hindsight limits, the Open WebUI client key and the Hermes wrappers. Read the 1.6.0 Breaking and Migrations notes in CHANGELOG.md first. The project has followed semver since v1.0.0; a minor release's Breaking notes flag behaviour changes an operator or a script may notice. Upgrades start at 1.4.0; on anything older, read Upgrading from an older release first.
What 1.6.0 brings: Hermes v0.22.4 (
4d043038) on a uv-managed Python 3.14 release layout, every Hermes profile in Open WebUI and any/v1client, and a memory engine you can point at a local slot or an upstream model. See What's new and Upgrading to 1.6.0.
⚡ The installer is the whole setup. There is no separate first-run wizard afterwards.
install.shasks where models should live, optionally takes a HuggingFace token, seeds every capability slot, downloads the hal0 brain steward model, and starts the API. When it finishes, open the dashboard and assign models to slots.
At a glance
| What it is | One control plane, hal0-api on :8080, turning a Linux box into an OpenAI-compatible inference appliance — chat, embeddings, rerank, transcription, speech and image generation, each capability in its own podman container. |
| Install | One curl | sudo bash line. The installer probes hardware, seeds every capability slot, and starts the API — there is no separate setup wizard to run afterward. |
| Hardware | First-class on AMD Strix Halo (ROCm iGPU + XDNA NPU); Vulkan and CPU fallbacks everywhere else, plus experimental CUDA. See Hardware matrix. |
| Platform | Linux + systemd + podman, including Proxmox LXC. macOS and Windows are not supported today — see Support matrix. |
| Auth | Enforcement is off by default (trusted-LAN posture) — opt in with hal0 auth require on. Once an admin key is configured, a LAN-bound box also gates mutating routes for off-box callers, even with enforcement off (v1.3.0). No TLS termination; front it with a reverse proxy if it's reachable beyond your LAN. |
| Chat UI | OpenWebUI, prewired, on :3001 — zero config. Hermes agent profiles appear in its model picker next to your slots. |
| Updates | Cosign-signed tarball releases via hal0 update, with one-flag rollback. |
If you know Ollama / llama.cpp / Open WebUI / LocalAI, hal0 adds…
| You already know | hal0 adds |
|---|---|
| Ollama — pull a model, run it, hit one local API. | A dedicated slot per capability (chat, embed, rerank, STT, TTS, image) — each its own podman container with its own hardware backend, typed lifecycle, and per-slot logs, instead of one shared runtime doing everything. |
llama.cpp / llama-server — the inference engine itself. |
hal0 runs llama.cpp inside systemd-supervised slots, with a state machine (starting → warming → ready → …), a model registry, automatic hardware-backend selection (ROCm/Vulkan/CUDA/CPU/NPU), and a benchmarking pipeline (hal0 bench) on top of it. |
| Open WebUI — the chat frontend. | hal0 prewires OpenWebUI as the chat surface and is the backend it talks to — hardware probing, slot/model management, and a separate operator dashboard sit underneath, not just the chat window. |
| LocalAI — an OpenAI-compatible gateway over multiple backends. | hal0 adds a live operator dashboard, a hardware probe that drives backend selection automatically, systemd-managed container lifecycle per slot, and a signed self-update path with rollback. |
Screenshots
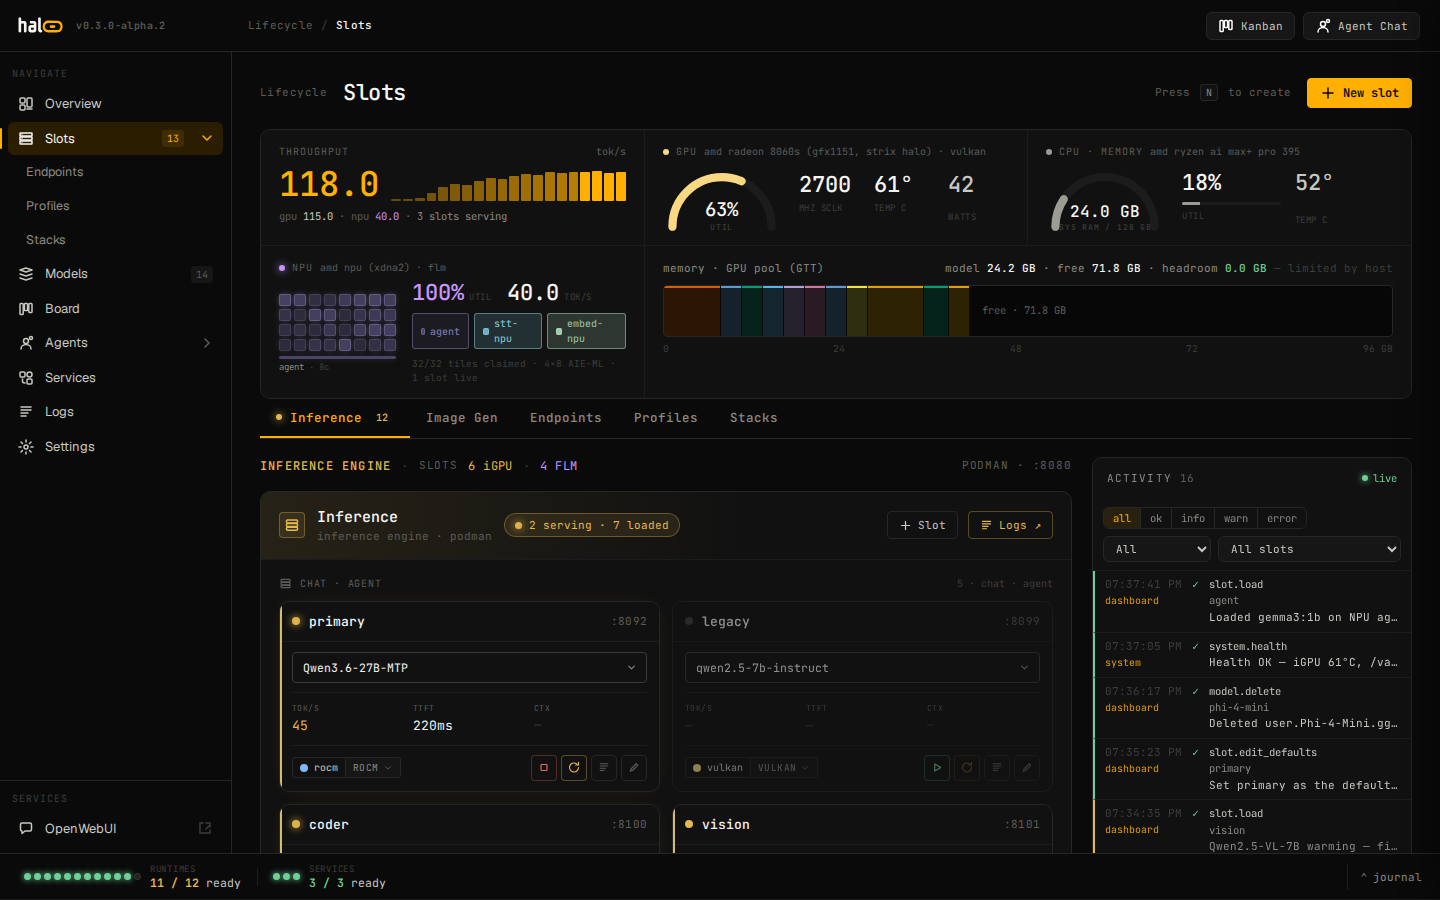 Dashboard — unified-memory hero, at-a-glance health, and live slot rows. |
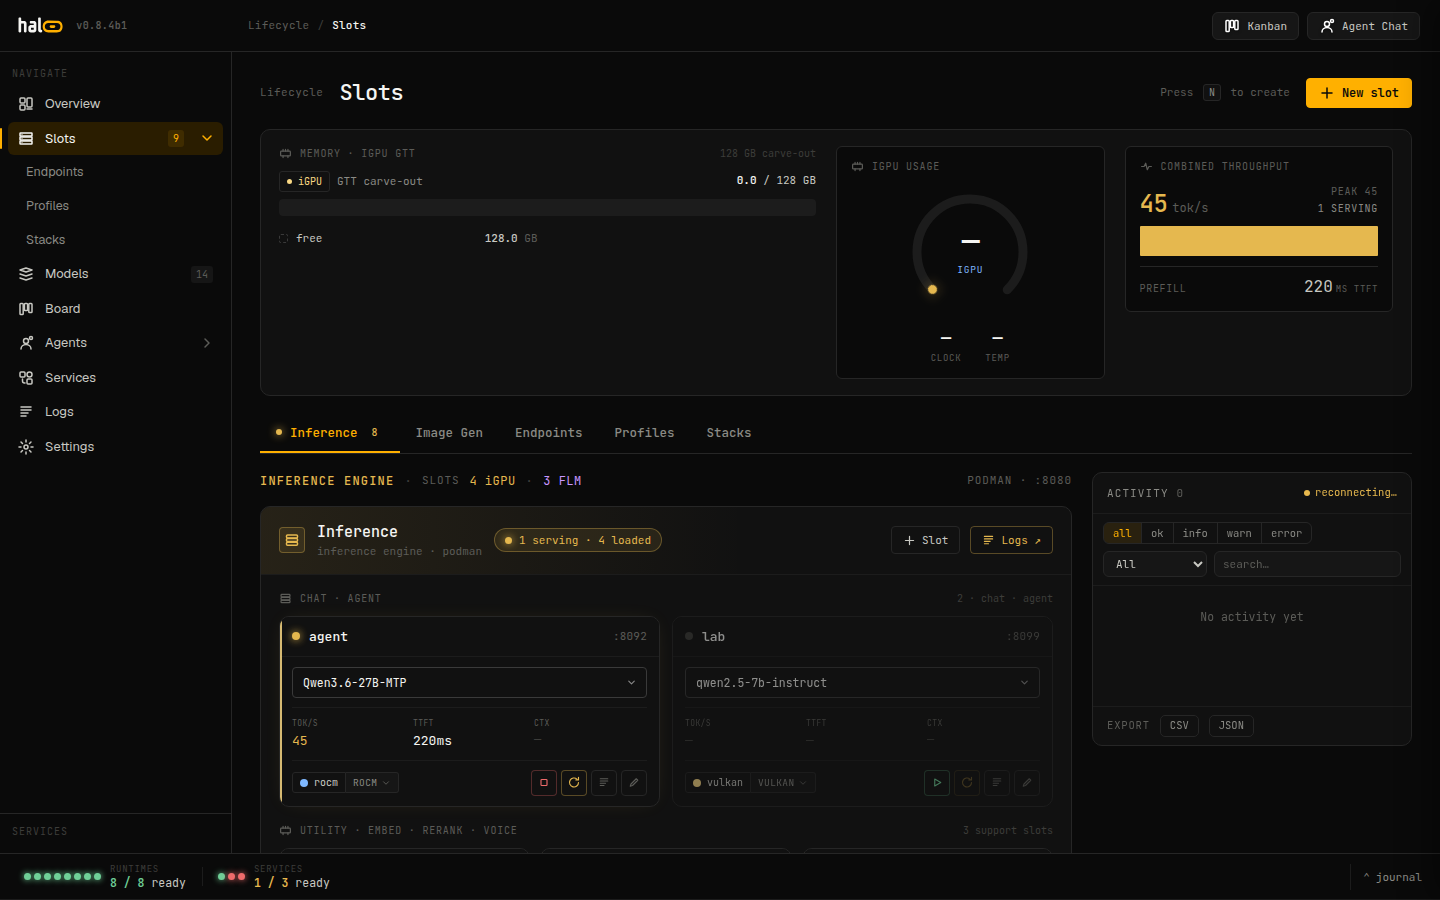 Slots — the inference engine: per-slot models, devices, and live telemetry. |
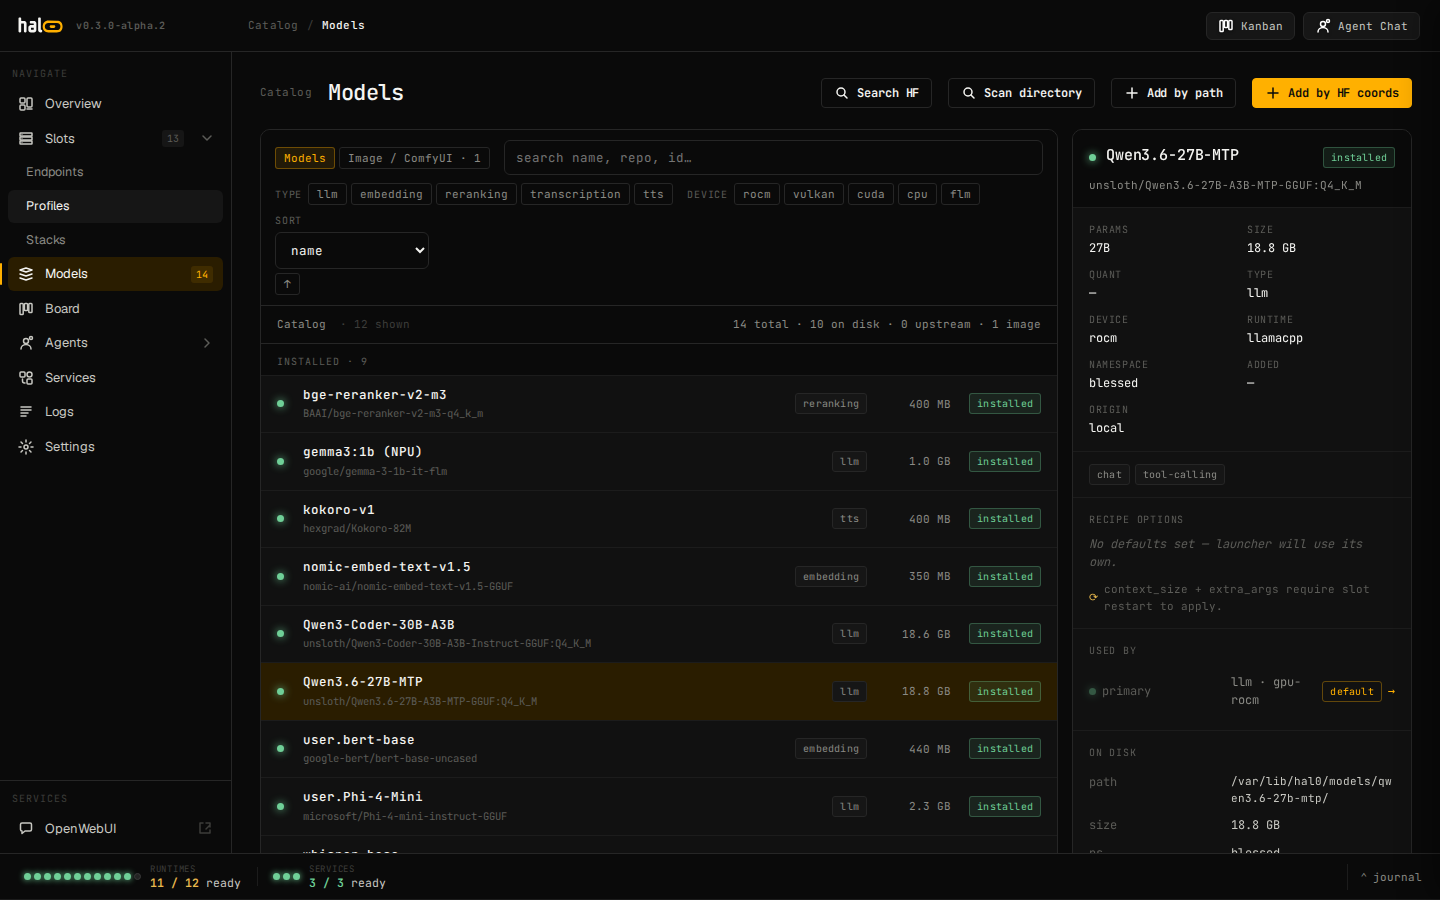 Model registry — catalogue with quant chips and pull status. |
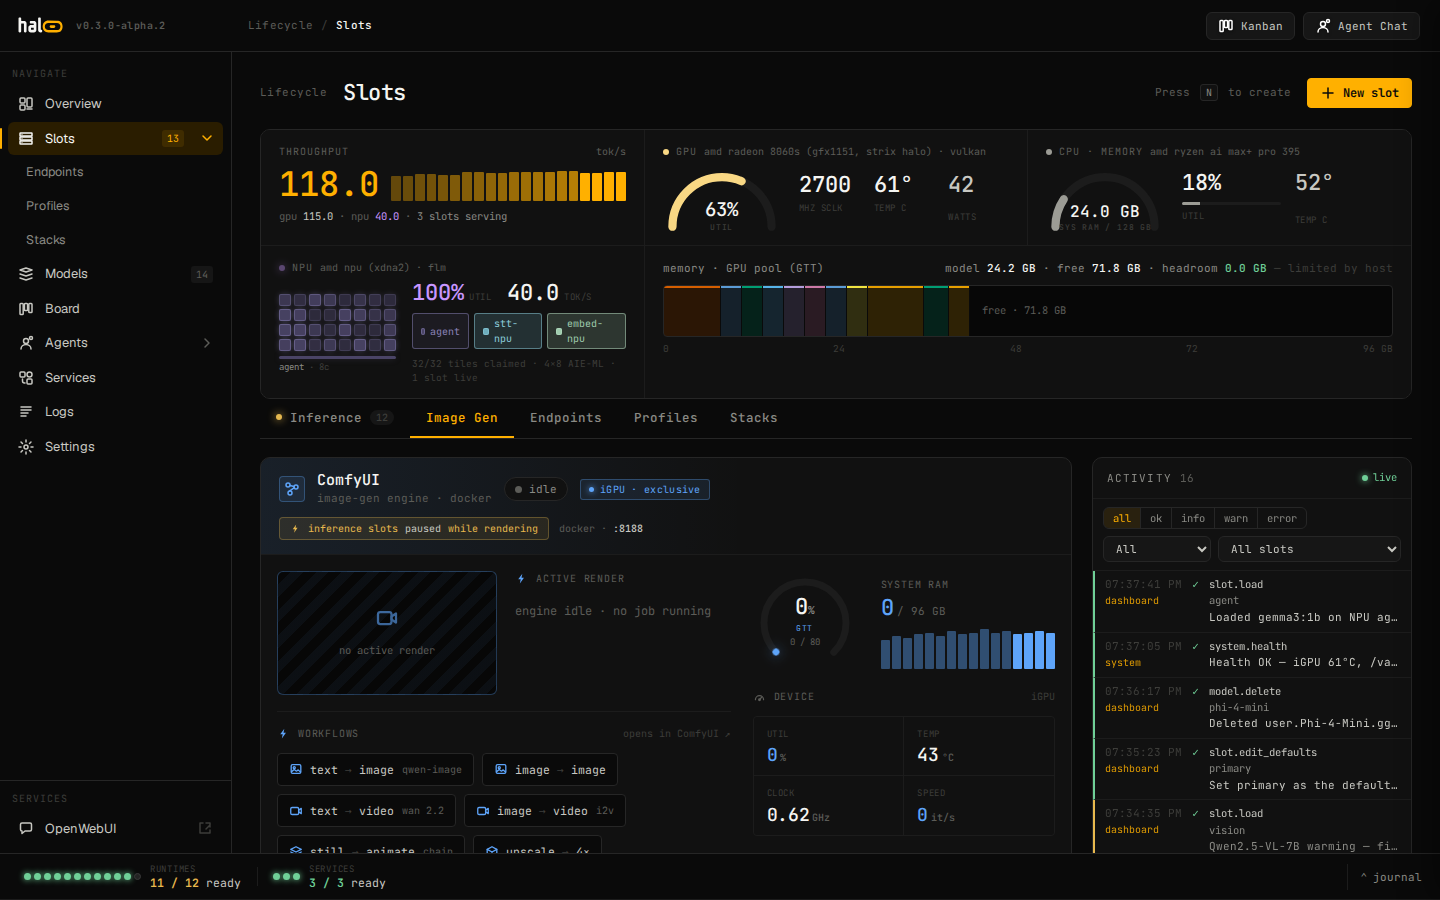 Image generation — ComfyUI queue and GPU gauges. |
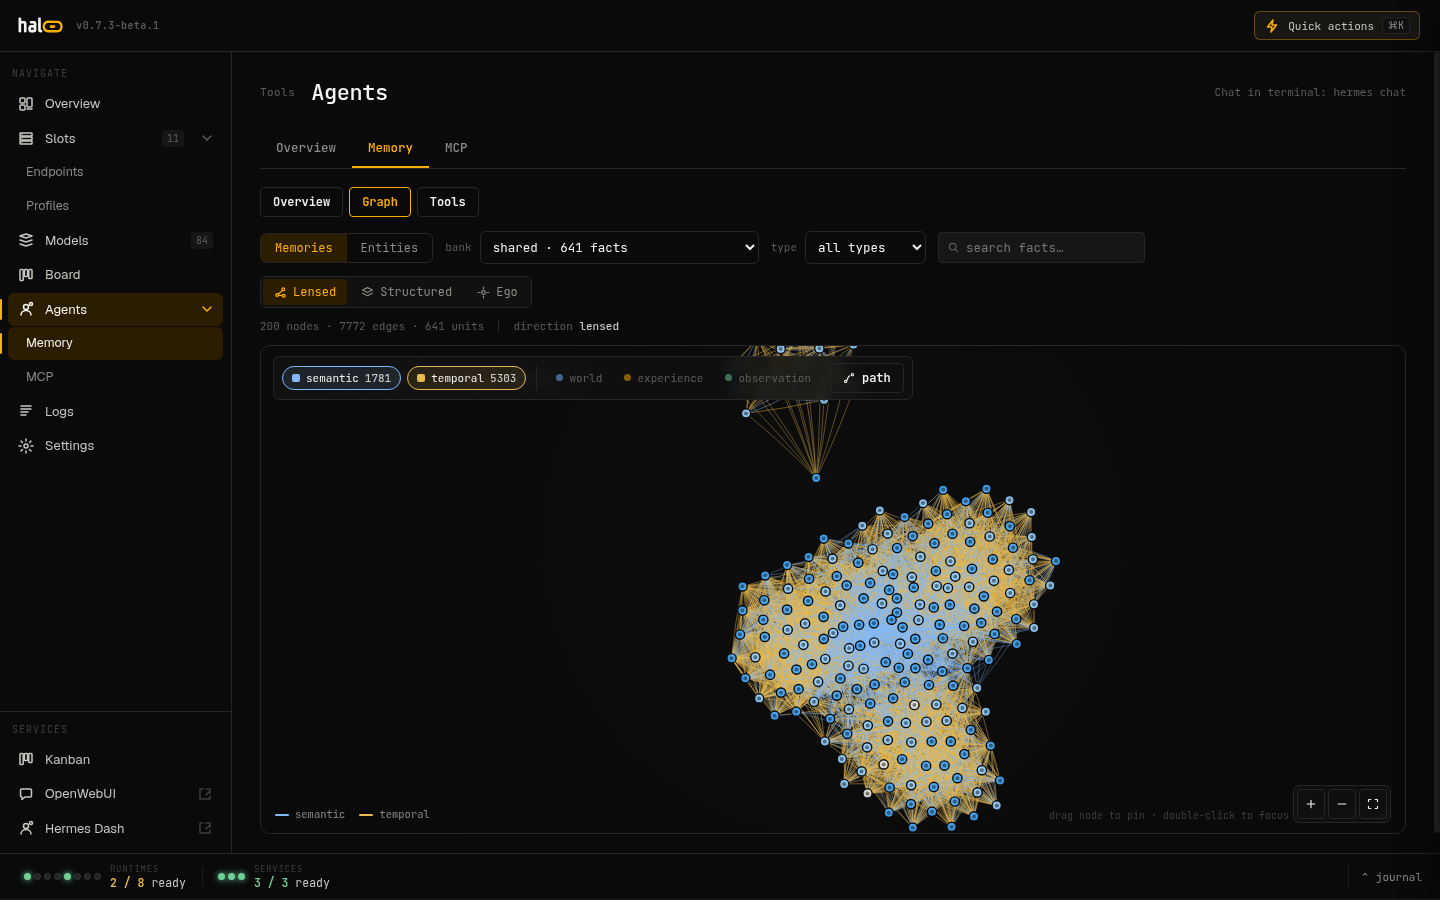 Memory — Hindsight facts and graph extraction. |
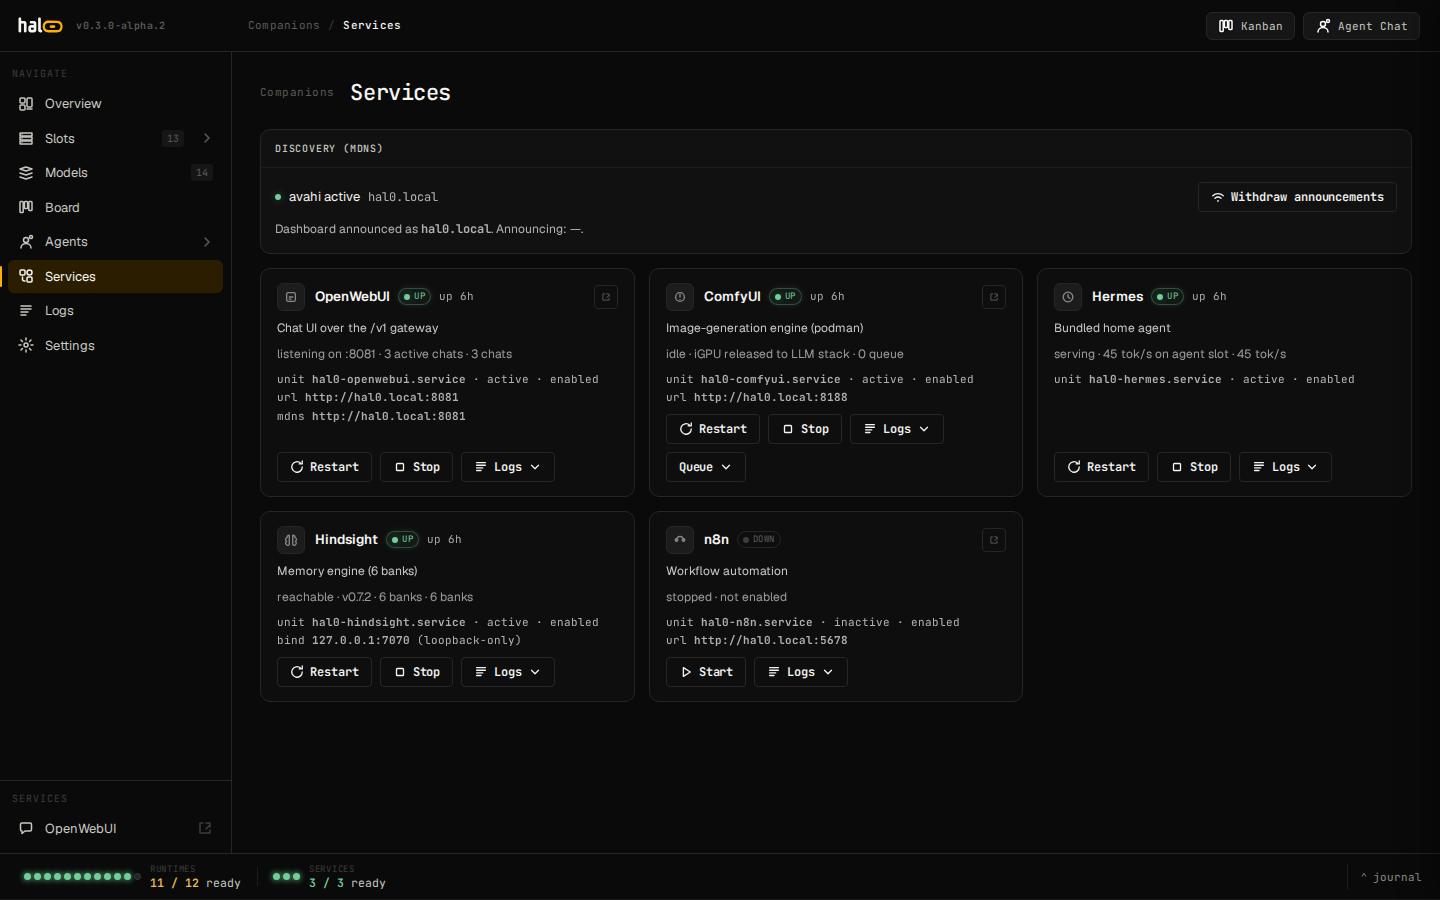 Services — Open WebUI, ComfyUI, Hermes, Hindsight, n8n with mDNS. |
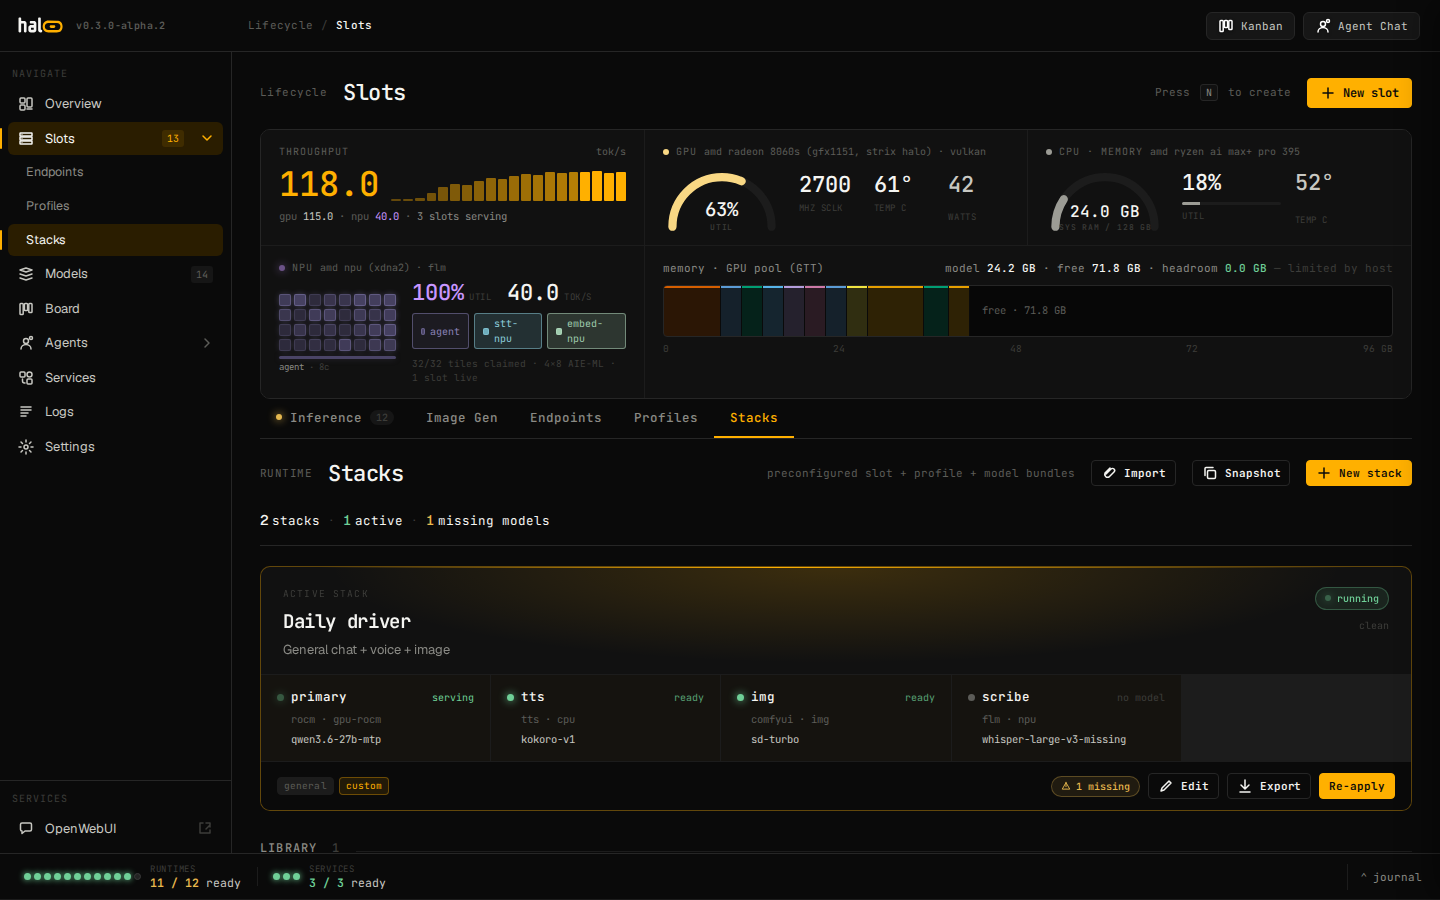 Stacks — declarative slot + profile + model bundles, applied atomically. |
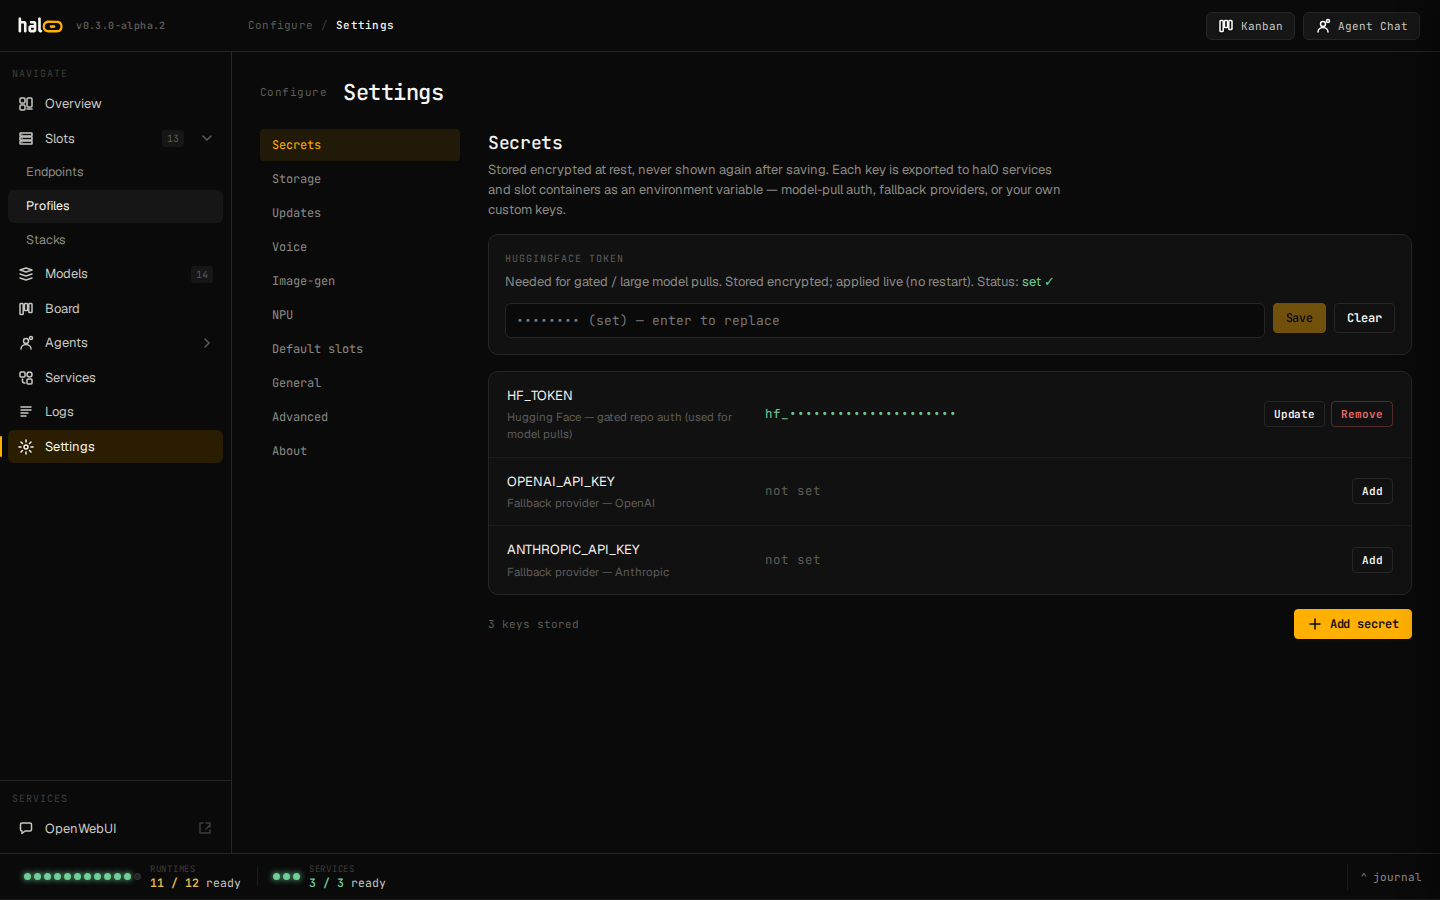 Settings — full hal0.toml parity with an Advanced section. |
More in the docs.
Install
The one-liner
curl -fsSL https://hal0.dev/install.sh | sudo bash
That fetches installer/bootstrap.sh, which needs jq and cosign on the
box. It authenticates the channel manifest before parsing it, sha256- and
Sigstore-bundle-verifies the release tarball, then hands off to
installer/install.sh. Piped through bash it
never prompts. Re-running it is safe: every provisioning step is idempotent
and existing slot configs are never overwritten.
Pick a channel with HAL0_CHANNEL (stable is the default; preview and
nightly are the other two):
curl -fsSL https://hal0.dev/install.sh | sudo HAL0_CHANNEL=preview bash
What the installer actually does
- Pre-flight — systemd, Python 3.12–3.14, x86_64, a container runtime (podman preferred, auto-installed), GPU/NPU device visibility, disk space, free ports.
- Code + venv — a versioned tree under
/usr/lib/hal0/with acurrentsymlink and a shared venv. - Config —
/etc/hal0/withhal0.toml,profiles.toml, the ten curated slot seeds, andapi.env. - Hardware probe — writes
/etc/hal0/hardware.jsonand prints the detected backends. - Brain steward model — pulls the curated
lfm2.5-2.6b(LiquidAI LFM2.5-2.6B-Q8_0, ~2.87 GB, 131k context) and binds it to thebrainslot, so the dashboard's steward chat and its tool calls work out of the box. On an interactive terminal only, it then offers a larger agent model (15–31 GB, size printed first, default No). - ComfyUI share — creates the bind-mount directories the
imgslot needs and seeds custom nodes. - Service start — enables and starts
hal0-api+hal0.target, the Hindsight memory engine, OpenWebUI on:3001, and the bundled Hermes agent. From 1.6.0, Hermes builds its own immutable release under/var/lib/hal0/hermes/releases/on a uv-managed CPython 3.14, so that step needs network access on a first install. hal0 itself needs Python 3.12-3.14; the Hindsight engine venv accepts 3.11-3.14.
Full step list and the complete env-var table:
installer/README.md.
Common install knobs
| Variable / flag | Effect |
|---|---|
--models-dir=PATH / HAL0_MODELS_DIR=PATH |
Put model pulls somewhere other than /var/lib/hal0/models |
HAL0_PORT=9090 |
Bind the API somewhere other than :8080 |
HAL0_CHANNEL=preview |
Install from a channel other than stable |
HAL0_NONINTERACTIVE=1 |
Force flag/env defaults; never prompt, even on a TTY |
HAL0_SKIP_SETUP=1 |
Skip first-run seeding and both model steps |
HAL0_SKIP_BRAIN_MODEL=1 |
Keep the seeding, skip the brain pull (brain stays model-less) |
HAL0_BRAIN_MODEL=<id> |
Force a specific curated brain quant |
HAL0_PULL_AGENT_MODEL=1 / =0 |
Opt in to the big agent pull unattended / force-skip it on a TTY |
HAL0_PY_AUTOINSTALL=1 |
Let the installer install python3.12 when the box has no Python in 3.12-3.14 |
HAL0_SKIP_HINDSIGHT=1, HAL0_SKIP_OPENWEBUI=1, HAL0_SKIP_HERMES=1, HAL0_SKIP_COMFYUI=1 |
Skip individual companion services |
--no-start |
Provision everything, leave services stopped |
--summary-json=PATH |
Write a versioned, machine-readable install summary (see installer/README.md) |
Proxmox VE, one line
On a Proxmox host:
bash -c "$(curl -fsSL https://raw.githubusercontent.com/Hal0ai/hal0/main/scripts/proxmox-ve/hal0.sh)"
Creates an unprivileged Debian 13 LXC and runs the standard bootstrap inside
it. --advanced opens whiptail prompts; every parameter has an env-var
override (CTID, RAM_MB, STORAGE, …). Hardware-agnostic — Strix Halo
passthrough still needs the privileged-LXC recipe. See
scripts/proxmox-ve/README.md.
Uninstall
hal0 uninstall                 # prompts before deleting config + model data
hal0 uninstall --purge         # also wipe /etc/hal0, /var/lib/hal0, the hal0 user and images
First ten minutes
The dashboard is at http://<box>:8080, the API at http://<box>:8080/v1.
Assign models from the dashboard, or from the shell:
hal0 model pull <hf-repo>/<file.gguf>   # resumable, disk-preflighted
hal0 slot load agent --model <id>       # bind a model and start the container
hal0 status                             # system + slot summary
hal0 chat --brain                       # terminal REPL against the steward
Then point any OpenAI-compatible client at the box:
curl http://<box>:8080/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"<id>","messages":[{"role":"user","content":"hello"}]}'
hal0 model pull streams from Hugging Face into the model registry under the
user.* namespace — a disk-space preflight fails fast before a multi-GB
pull, and an interrupted pull resumes via HTTP Range instead of restarting
from zero.
What's new
Shipped in 1.6.0
-
Hermes v0.22.4 on Python 3.14. The bundled agent moves from 0.19.0 to v0.22.4 (
4d043038). Every build (install,reprovision --repair, update) produces an immutable release under/var/lib/hal0/hermes/releases/, health-checked before thecurrentsymlink flips, with a flip-back topreviousif the re-check fails. See Hermes, the bundled agent. -
Hermes profiles in Open WebUI. hal0 registers one pinned upstream per Hermes profile, so
hermes-agentand one model per profile appear in the Open WebUI picker and in/v1/modelsfor any OpenAI-compatible client. -
Every profile gets hal0's tools and memory.
hal0-adminandhal0-memoryare written into each named profile, with a private memory bank per profile. -
Auth revocation. Rotating a key closes open WebSockets with code 4401 and ends SSE streams; an expired session ends its streams too.
-
Python 3.14 in CI. Pull requests run 3.12 and 3.14; the Hindsight engine installs on 3.14 without
--ignore-requires-python. -
Agent chat proxy removed.
/api/agents/{id}/events,/submitand/session/*return 404; chat with Hermes happens in Hermes's own dashboard or through/v1. -
Memory engine on a local slot or an upstream model. Pick it under Engine model on Settings -> Data -> Memory (also on the agents Memory tab) or run
hal0 memory graph enable --model <id>;--localreturns to the local extraction slot. hindsight-api always calls the virtual idhal0/memory, which hal0 resolves per call, so switching needs no engine restart. An Engine running row names the provider and model the engine really loads and flags an override from/etc/hal0/hindsight-llm.env. The bank description under the picker in the Memory workspace is editable in place, and bank ids may contain dots (coding-agent::ultrareview-1.4). -
Terminal off stays off for Hermes side agents. With the terminal disabled hal0 also writes
terminal.backend: hal0-terminal-offinto the Hermes config and every wired profile, soterminalandprocess_manageleave every schema, including the gateway's preview-restart agent. A docker or ssh backend you chose is restored when you turn the terminal back on. Hermes logsUnknown TERMINAL_ENV 'hal0-terminal-off'every 30 s on such a box; that line is expected. -
Hermes gateway awareness. From Hermes v0.22.3 the gateway owns chat for non-default profiles and
hermes chat; with the unit stopped they reportgateway inaccessible. Runsudo systemctl enable --now hermes-gateway. Newhal0 doctor allrows:Hermes gateway unit(fails when the unit file is missing or an unmanagedgateway run --idle-exitruns) andAPI journal read; thehermes-apirow warns instead of failing when you turned the gateway off. -
sudo hal0 agent upgrade pireruns the pinned pi installer and redeploys hal0's two extensions, leaving your own extensions, provider, model and theme alone. -
Upgrade floor is 1.4.0. A 1.3.x box runs
hal0 update --target 1.5.0first, then updates again. See Upgrading from an older release.
Shipped in 1.5.0
- Speculative decoding drafters. A model can carry a drafter file
(DFlash, EAGLE-3, LiLiCorr) that proposes tokens the main model checks in
one pass. Add from Hugging Face lists companion drafters and fit-checks the
pair before anything downloads; from a shell,
hal0 model pull <id> --draft <file>does the same. The profilespeculationfield (auto,off,ngram) replacesmtp. See Speculative decoding: drafters. - Per-lane device pinning. The slot passes
--devicetollama-server(ROCm0,Vulkan0,CUDA0or none). - Runner images on llama.cpp b11716 for
standard,cpuandcuda. - Add from Hugging Face lists quants, not files, and the model pickers are compact.
Breaking changes, migrations and known issues for every release are in
CHANGELOG.md.
Why hal0
Point your editor at your own box. Aim any OpenAI-compatible client at
http://<box>:8080/v1 — Claude Code, Cline, Continue, an SDK, a cron job.
A dedicated coder slot can serve your editor while the agent slot serves
chat, each on its own container, model and flag set.
Retrieval grounded on your data. Embeddings and reranking are
first-class slots, not an afterthought: /v1/embeddings and /v1/rerank
run on the same box as chat, and the bundled Hindsight memory engine turns
conversations into recallable facts behind an MCP server.
Speech and images on the same control plane. Transcription
(/v1/audio/transcriptions), speech (/v1/audio/speech) and image
generation (/v1/images/generations, /v1/images/edits) are the same API,
the same auth posture, the same dashboard — no second stack to operate.
Not another llama-server wrapper. Every workload is a real
systemd-managed slot with a typed lifecycle, persisted state
(/var/lib/hal0/slots/<name>/state.json), SSE status streaming, per-slot
journald logs and a GPU arbiter that keeps image generation from stealing
the iGPU out from under a streaming completion.
Strix Halo native, but not Strix-Halo-only. The probe is UMA-aware on
Strix Halo and falls back to portable parsers (/proc/cpuinfo,
/proc/meminfo, lspci) everywhere else. platform on /api/hardware
resolves to one of strix-halo, wsl2, lxc, proxmox-kvm, kvm,
bare-metal-{nvidia,amd,intel}-gpu or bare-metal-cpu-only, and the
dashboard only labels memory "unified" when it actually is. Slot-fit
warnings size against the real unified pool, not a BAR carve-out.
NPU multi-role via the FLM trio. On Strix Halo with FastFlowLM
installed, a single FLM process inside the hal0-runner-flm container
hosts chat + transcription + embedding concurrently on one AMDXDNA hardware
context — ~2 GB NPU memory, gemma3:1b at ~38.6 tok/s + Whisper-V3-Turbo +
Embedding-Gemma all coresident. hal0 exposes this as one seeded flm slot
(chat-first) whose [npu] table — or the dashboard's NPU drawer — toggles
ASR and embed on the running flm serve. The host-side FLM .deb is
installed for device-sanity probes only; inference runs in the container.
See docs/concepts/strix-halo.mdx.
Faster replies, same answers. Pair a model with a drafter and hal0 fit-checks it before download, reports a drafter the runner image is too old for instead of failing the launch, and shows the acceptance rate per slot.
An agent that lives on the box. The hal0-brain steward drives the platform from the dashboard's top bar, and Hermes/Pi install as real services prewired to the local API and MCP servers.
Reliability bar. Atomic env-file writes. Schema-validated TOML.
Structured error envelopes ({"error":{"code":"slot.not_ready",...}}).
Cosign-verified self-update with one-flag rollback. Priority-ordered
concurrency with active-inference protection — a serving slot cannot be
evicted out from under a streaming request. Privileged operations run
through an allow-listed root seam, never a free-form shell.
Benchmarks
Numbers below are from the public leaderboard at
hal0.dev/benchmarks — 26 models measured end
to end on the reference box (AMD Ryzen AI Max+ 395, Radeon 8060S iGPU,
128 GB LPDDR5X, ROCm 7.2.4), rocm lane, decode and prefill throughput plus
TTFT, speculative accept rate, memory, watts and temperature per run.
| Model | Params | Quant | Decode (tok/s) | Prefill (tok/s) |
|---|---|---|---|---|
qwen3.5-0.8b |
0.8B | q4 | 169.8 | 6,248 |
chadrock3-6-35b-uncensored |
35B MoE | q4 | 102.1 | 890 |
chadrock-35b-ace-saber |
35B MoE | f16 | 100.5 | 903 |
qwen3.6-35b-a3b-crown |
35B MoE | f16 | 84.4 | 873 |
qwopus3-5-4b-coder |
4B | q4 | 85.0 | 889 |
qwen3-4b |
4B | q4 | 61.9 | 1,849 |
gemma-4-26b-a4b |
26B MoE | q4 | 40.9 | 1,336 |
Concurrency and non-LLM lanes, same box:
| Workload | Measurement |
|---|---|
| Chat + embed, concurrent | ~258 tok/s aggregate |
| NPU chat (FLM trio, gemma3:1b) | ~38.6 tok/s in ~2 GB NPU memory |
| TTS — Kokoro (CPU) | ~0.18 real-time factor |
| TTS — Qwen3-TTS (ROCm) | ~0.48 real-time factor (~2.1× realtime) |
Benchmarking is a first-class subsystem, not a spreadsheet: hal0 bench plan|run|results|eval|bundle|upload drives llama-bench/llama-server
under a record schema with a dedup identity key, an in-dashboard Benchmarks
page (roster / runs / evals / run-queue), and regression journaling. Results
never leave the box on their own — hal0 bench bundle writes a
content-addressed, host-redacted archive you can attach anywhere, and
hal0 bench upload publishes one only when you type it. See
docs/reference/model-roster-benchmark.mdx.
What's in the box
- OpenAI-compatible
/v1/*API — chat, completions, embeddings, rerank, audio transcriptions, audio speech, image generations, image edits, models. Drop-in for any OpenAI SDK; point your client athttp://localhost:8080/v1and go. - Slots — each named target carries a
type(llm | embedding | reranking | transcription | tts | image), adevice(gpu-rocm | gpu-vulkan | gpu-cuda | cpu | npu), amodel, plusautoload, an evictionpriorityand an optionaldefault. Ten curated slots (agent,brain,coder,embed,flm,img,qwen3tts,rerank,tts,utility) are seeded into/etc/hal0/slots/<name>.tomlon install and each gates on its own runtime validation at load time — theflmNPU slot simply stays grey without FastFlowLM hardware. Add your own withhal0 slot create NAME --type TYPE --model MODEL. A deliberatehal0 slot deleteis tombstoned, so re-running the installer never resurrects it. - Model owns its tune — the model, not the slot, owns
context_size,extra_args,chat_template,profileand speculation settings. A slot's[model].context_sizeis a ceiling; a model with no stamped tune inherits its profile's template as a floor. - Container runtime — every slot runs as its own podman container under
hal0-slot@<name>.service, bound to a loopback port (8081–8099 + fixed seeds).hal0-apion:8080is the only control plane. See docs/concepts/architecture.mdx. - Hardware-aware probe — detects GPU / NPU / unified memory, writes
/etc/hal0/hardware.json, and surfaces VRAM/RAM fit warnings inline in the slot form and during install. - Dispatcher — registry-aware routing, single-flight, cold-cache prefetch, and upstream fallback (OpenRouter, Anthropic, OpenAI, Google AI Studio, Ollama, custom OpenAI-shaped endpoints). Mix local + remote per-model in one config.
- Dashboard — React 18 + Vite UI for slot/model management, hardware-aware configuration, live logs, system health and a built-in chat page (popout window + reasoning toggle). SSE-backed status and log tail; a Journal panel streams per-slot container logs from journald. Live telemetry — Power & Thermal (GPU clock/temp/power) and per-slot throughput — is on by default. The slots page splits into Inference | Image Gen tabs; the Image-Gen tab operates the ComfyUI container (live GTT/RAM gauges, queue depth, model inventory) with a gated inference ⇄ generation iGPU switchover behind a blast-radius confirm.
- AI Capabilities page — one settings surface for TTS, STT, embeddings, reranking, image generation and the NPU, with per-panel probe-failure surfacing instead of a silent grey Save.
- Stacks — declarative, runtime-switchable model/slot layouts. A
StackConfigis planned into a change set, applied atomically (with rollback) and converged against the live slot set; drift is detected by content hash. Stacks export/import via a checksummed.hal0stack.jsonenvelope, and a live config can be snapshotted back into a Stack. - OmniRouter (8 tools) —
generate_image,edit_image,text_to_speech,transcribe_audio,analyze_image(vision),embed_text,rerank_documents,route_to_chat. Dispatched client-side from any chat slot whose model carries thetool-callinglabel, and filtered per request — a tool only appears in the prompt if its target slot is enabled and its model carries the required labels. - Companion-service management —
/api/servicesis the declarative source of truth for OpenWebUI, Hermes, Hindsight, ComfyUI and n8n: audit-logged systemd lifecycle actions (start/stop/restart/enable/ disable), mDNS.localadvertisement, and a dedicated Services page. OpenWebUI is prewired at:3001with zero config; its Services card shows an Agents chip once Hermes profiles are wired in. - Image generation, day one —
POST /v1/images/generationsvia ComfyUI in theimgslot container (ROCm). The installer seeds theimgslot and its ComfyUI model share. - Atomic self-update with rollback —
hal0 update --channel stable|preview|nightly. Cosign-verified tarballs swap a/usr/lib/hal0/currentsymlink;--rollbackreverts. Staging happens in a root-only directory with the authenticated digest pinned to the very file object the archive is extracted from.
Agents, MCP, and the brain steward
hal0 ships two MCP servers and two bundled agents. The MCP servers
(/mcp/admin for slot / model / capability / config / hardware / log admin,
/mcp/memory for Hindsight-backed long-term memory) are reachable by any
MCP-speaking client — Claude Code, RAG services, your own scripts.
/mcp/admin is ADMIN-tier; /mcp/memory is CLIENT-tier as of 1.0, so a
memory-only agent does not need the platform-admin key. The bundled agents
are Hermes-Agent (service shape, via the hal0-owned hermes wrapper —
hal0-hermes remains a back-compat symlink — connecting to hal0-api at
HAL0_INFERENCE_BASE=http://127.0.0.1:8080) and pi (CLI shape, from
@earendil-works/pi-coding-agent on npm), and both can be installed side by
side. Install either with hal0 agent install <name>. Destructive MCP
calls (model_pull, slot_delete, config_write, …) gate through a header bell + inbox modal
in the dashboard, with CLI parity via
hal0 agent approvals {list,approve,deny}.
The hal0-brain steward is a third, built-in persona wired to the
dashboard's top-bar agent chat — no install step. It drives the platform
through the full hal0-admin catalog (models, slots, stacks,
profiles, settings, upstreams, benchmarks) under a per-persona tool
policy: tools_allowed hides tools, require_approval tightens them, and
a POLICY_NO_LOOSEN floor keeps destructive and secret-bearing tools
(*_delete, config_write, provider_credential_write) always gated — no
persona edit can disarm them. Gated calls pause the turn for inline
approve/deny. A [brain_chat] config gives operators a hard kill switch, a
read-only mode, loop-budget knobs and a slot override (run the steward on
any slot, e.g. hal0/npu) from Settings → Agents / Brain. The seeded
brain model is a native tool-caller, so the steward executes its own calls on
the brain slot out of the box. Binding a larger model to the agent slot is
the optional upgrade path: [brain_chat] tool_model (default hal0/agent)
runs tool rounds there while chat stays on the brain slot, so a runner that
cannot emit parseable tool calls reroutes instead of failing the turn. Set it
to off, none or disabled to route tool turns nowhere.
Hermes, the bundled agent
Hermes is the service-shape agent: it runs as hal0-agent@hermes.service
under the unprivileged hal0 user, pinned to one reviewed upstream commit
(v0.22.4, 4d043038), and talks to hal0-api for
inference, tools and memory. hal0 agent install hermes installs it.
- Immutable releases. Each build (install,
reprovision --repair,upgrade, update) lands in/var/lib/hal0/hermes/releases/<id>/, runs on a uv-managed CPython 3.14, and is checked (imports,hermes --help, an MCP probe) beforecurrentflips. Activation stops the agent and gateway, switches, migrates the Hermes config and restarts; a failed re-check flips back topreviouswithconfig.yamlrestored. Sessions are kept (sessions.auto_prune: false). - Updates are vetted commits.
hal0 update component hermes --target <40-hex sha>accepts only a commit listed inVETTED_HERMES_REFS; version strings are refused. The override stays until--clear-override. - Profiles show up in Open WebUI. hal0 registers one pinned, read-only
upstream per profile that has an API key:
hermesfor the default profile andhermes.<profile>for the rest./v1/modelslistshermes-agentplus one model id per served profile, so Open WebUI, Cline or a curl call can pick one. The request body is forwarded untouched, streaming or not, and a Hermes model never falls back to a slot: if the upstream is down you getdispatch.upstream_unavailable(502). - hal0 tools and memory in every profile. hal0 writes the
hal0-adminandhal0-memoryMCP servers into each named profile, with its own private memory bank. Opt a profile out withhal0: {wire_mcp: false}. - Approvals in the dashboard. Gated tool calls from any profile land in the dashboard inbox, same as the other agents.
- Delegation.
[hermes] delegation_slotin/etc/hal0/agents/hermes.tomlpicks the slot thatdelegate_taskchildren run on (defaultagent). - Desktop pairing.
hal0 agent dashboard-token hermesprints the dashboard session token, which is minted once per install, so a Hermes Desktop remote pairing survives restarts. - Doctor rows.
hal0 doctor allcheckshermes-api(upstream registration),hermes_profiles_mcp,hermes_generation,hermes_delegation_slotandhal0_linger.
Tip for Open WebUI: set its task model to a plain slot model so chat titles and tags do not spend agent turns. Setup details are in docs/guides/open-webui.mdx.
See docs/concepts/agents.mdx, docs/reference/mcp-tools.mdx and docs/guides/run-agents.mdx.
Backends
Each capability runs in its own container, supervised by
hal0-slot@<name>.service. Two things compose to launch a slot: the
runner image (slot-owned — binary plus the optional image_pin; each runner's image is pinned in manifest.json) supplies the engine,
and the profile in the catalog supplies the bench-tuned flag bundle.
Profiles are device-agnostic tune templates; they no longer carry an image.
| Capability | Runner (binary) | Device | Profile |
|---|---|---|---|
| chat | standard (llama-server) |
gpu-rocm, gpu-vulkan |
chat, chat-long-context, dense, moe, thinking, coding, brain |
| chat (NVIDIA, experimental) | cuda (llama-server) |
gpu-cuda |
chat |
| chat (fallback) | cpu (llama-server) |
cpu |
cpu-chat |
| embeddings / rerank | standard (llama-server) |
gpu-rocm, gpu-vulkan |
embedding, reranking |
| chat + STT + embed (NPU) | flm |
npu |
flm |
| transcription | moonshine / the FLM trio above |
cpu / npu |
moonshine / flm |
| TTS | kokoro / qwen3tts |
cpu / gpu-rocm |
kokoro / qwen3-tts |
| image | comfyui |
gpu-rocm |
comfyui |
A device also has a default profile it resolves to when a slot names none —
gpu-rocm, gpu-vulkan and gpu-cuda resolve to chat, cpu to
cpu-chat, npu to flm. The seeded slots override that where it matters:
agent ships on dense, coder on coding, brain on brain,
utility on chat.
The seeded profile catalog is virtual — it lives in code
(SEED_PROFILES) and is overlaid on every load, so a re-tuned seed reaches
every install on upgrade instead of being frozen by a stale on-disk copy.
/etc/hal0/profiles.toml is for your profiles: chat,
chat-long-context, dense, moe, thinking, coding, brain,
embedding, reranking, cpu-chat, flm, kokoro, moonshine,
qwen3-tts and comfyui are immutable seeds you clone under a new name to
customize.
voice.stt switches Moonshine (CPU) ⇄ FLM's whisper-v3:turbo (NPU) and
voice.tts switches Kokoro (CPU) ⇄ Qwen3-TTS (GPU) without reconfiguring
the slot. There is no GPU STT engine — a GPU device resolves to none rather
than silently borrowing a chat profile.
Every seeded chat profile requests -fa auto, so Flash Attention is probed
at startup and falls back cleanly when it cannot be scheduled on its layer's
device. A model with a measured win from forcing it can set -fa on in its
own defaults.extra_args.
The NPU path is opt-in: the installer places a FastFlowLM .deb on the host
(SHA-pinned per distro — Ubuntu 24.04/25.10/26.04 and Debian 13) for
device-sanity probes (flm validate); inference runs inside the
hal0-runner-flm container. With FLM present the installer seeds the flm
slot, and the NPU trio activates once flm validate passes.
Speculative decoding: drafters
A drafter is a small file that proposes the next few tokens so the main model can verify them in one pass: same output, faster replies. It pairs with one model, the way a vision projector does.
-
Get one. In the dashboard, Add from Hugging Face lists companion drafters (
-LiLiCorr,-DFlash,-DFlash2,-DSpark,-EAGLE3,-draft) and checks the fit from the two file headers before anything downloads. From a shell:hal0 model pull <id> --draft <file> [--draft-repo <repo>] hal0 model add <path> --draft <path> hal0 model set <id> --draft <path|none> # none unpairs
-
Choose when it runs. The profile's
speculationisauto(a paired drafter if the runner image can run it, else the model's own MTP heads, else nothing),off, orngram(llama.cpp n-gram lookup, no extra file). -
No crash on a mismatch. A drafter the runner image is too old for (LiLiCorr needs llama.cpp b11669 or newer) is reported on the slot instead of failing the launch, and each slot reports its draft acceptance rate.
-
What to expect. On one Strix Halo box, a 74B-A9B MoE model paired with its LiLiCorr drafter decoded about 1.6x faster with identical output. Speedup depends on the model, the drafter and the prompt, and a drafter that predicts poorly gains little. The slot's acceptance rate tells you whether a pairing is paying off.
Details: Drafters and Speculation in profiles.
For the container-runtime operator reference — service layout, slot TOML fields, profiles, GPU arbiter and day-2 commands — see docs/concepts/architecture.mdx and docs/guides/manage-slots.mdx.
Hardware
Linux + systemd is the only hard requirement
(installer/lib/preflight.sh,
preflight_systemd). macOS and Windows are not in scope for v1.
| Tier | Hardware | Status |
|---|---|---|
| First-class | AMD Ryzen AI Max+ 395 ("Strix Halo") with iGPU + XDNA NPU + 128 GB unified | Reference deployment. All published perf numbers come from this box. |
| First-class | AMD Ryzen AI Max 385 / 390 with 64 GB unified | Same path; small + mid tiers fit, 70B Q4 with shorter context. |
| Experimental | NVIDIA RTX 30/40/50 (10–32 GB) | Dedicated cuda runner — upstream ghcr.io/ggml-org/llama.cpp server-cuda-b<N> image via CDI (nvidia-container-toolkit), with multi-GPU gpu_index pinning on the gpu-cuda device. Auto-falls back to the Vulkan runner when CDI isn't present. /api/backends doesn't yet auto-advertise gpu-cuda. |
| Supported | AMD Radeon RX 7000 / discrete (16–24 GB) | ROCm or Vulkan runner images; same hal0-slot@<name> lifecycle. |
| Fallback | CPU-only x86_64 | cpu runner + cpu-chat profile — the cpu runner image, a CPU-only llama.cpp build (no GPU passed to the container). Usable for tiny models / smoke tests, not the headline experience. |
Day-2 operation
hal0 status                          # system + slot summary
hal0 slot list                       # every slot, state, port, bound model
hal0 slot load agent --model <id>    # bind + start
hal0 slot unload agent               # stop without unbinding
hal0 slot restart agent
hal0 model list                      # the registry
hal0 update --check                  # is there anything newer?
Services and logs:
systemctl status hal0-api
systemctl list-units 'hal0-slot@*'
journalctl -fu hal0-api
journalctl -fu 'hal0-slot@*'
systemctl restart hal0-slot@agent    # restart a wedged slot container
Auth posture
hal0 ships built-in login, sessions and a deny-by-default route classifier,
with three tiers — anon → client → admin. There is no per-user account
system: a browser session is always admin-equivalent, and programmatic
callers use Authorization: Bearer <key> (or ?api_key= for WebSocket
upgrades) against an admin or client key.
Auth ships off by default. A fresh v1.0 install is trusted-LAN-open — the right posture for a homelab appliance — until an operator turns enforcement on:
hal0 auth rotate admin     # mint an admin key into /etc/hal0/api.env
hal0 auth require on       # enforce; takes effect on the next request
hal0 auth status           # show the current posture
hal0 does not terminate TLS or manage a user directory. If it is
reachable from anything you don't physically control, front it with a
reverse proxy that owns TLS — Traefik, nginx, Cloudflare Tunnel. Note that
the optional OpenWebUI companion is a second listener on :3001 that
this auth model does not cover. See
docs/operate/auth.mdx and
docs/concepts/security.mdx.
Proxmox integration (optional)
If hal0 runs inside a Proxmox LXC, the container only sees its own cgroup
slice of memory — other tenants, ZFS ARC and the host kernel draw from the
same physical DIMMs as GPU GTT but are invisible from inside. To surface
that, drop a read-only PVEAuditor API token into the dashboard's
Settings → "Proxmox integration" panel. The unified-memory bar then swaps to
the physical host's DIMM total and adds a muted "Proxmox host" segment for
other-tenant + kernel pressure. The token is sensitive, stored 0600 at
/etc/hal0/proxmox.json, and never echoed back by the API. Bare-metal and
VM installs leave the panel off.
Troubleshooting
Start here: hal0 doctor
hal0 doctor with no subcommand re-runs the installer's own pre-flight
battery against the live host (systemd, Python, container runtime, GPU/NPU
device visibility, disk, ports) and exits with the script's own status code,
so it composes: hal0 doctor && hal0 status.
hal0 doctor                       # re-run installer pre-flight
hal0 doctor --plain               # ASCII-only output (for logs / CI)
hal0 doctor --ports "8080 3001"   # override the port-collision check list
hal0 doctor all is the one to reach for when something is wrong but you
don't know where. It is strictly read-only and rolls every surface up into
one verdict:
hal0 doctor all           # human table
hal0 doctor all --json    # same rows as JSON
It composes the doctor verify report card (API, runners, DNS, capability
slots, memory, OpenWebUI, Hermes) with auth posture, secret-file modes,
model-store integrity, pending migrations, bound slot ports, the
hal0.target boot anchor, the MCP mount probes and the privileged sudo
seams. Exit codes: 0 clean, 1 an actionable failure, 2 critical
(API unreachable, or zero healthy runners). Every failing row names the
follow-up command.
Those follow-ups, and what each one is for:
| Command | What it audits | Repair flag |
|---|---|---|
hal0 doctor verify |
Post-setup report card: live health seams, computed URLs, doc links. --json for machines. Exits 2 only on a critical. |
— |
hal0 doctor perms |
Ownership: Hermes runtime state, the editable checkout's group-share, the canonical path-ownership table. | --fix (needs root), --force/-f to skip the prompt |
hal0 doctor models |
Registry paths vs disk, store/roots agreement, unregistered files in the store, FLM store ownership. | --fix (needs root), --force/-f |
hal0 doctor ports |
Which port each slot bound, collisions, corrupt netavark DNAT rules. | --fix prunes stale DNAT rules |
hal0 doctor profiles |
Dangling slot→profile references and un-pulled runner images. | — (read-only, --json) |
hal0 doctor toolbox-pull |
Every runner image pinned in manifest.json is anonymously pullable from ghcr.io, and its digest matches the pin. |
— (--json, --manifest PATH) |
hal0 doctor logs |
hal0-api's own journal. |
--unit, --follow/-f, --lines/-n, --level, --since |
hal0 doctor bundle |
Writes a redacted support bundle (system / config / diagnostics / logs). | --out DIR, --no-rocm-smi, --include-logs auto|yes|no |
--json on perms and models implies audit-only — --fix is ignored
under it. Both emit stable Diagnosis JSON (HAL0-PERMS-*,
HAL0-MODEL-*) so you can gate a script on a specific finding.
Two more read-only evidence commands:
hal0 system-info    # host / GPU / NPU / runtime evidence
hal0 ports          # port claims across the box
Install troubleshooting
✗ pre-flight failed: port 8080 is already in use. Find the squatter
with lsof -i :8080, then either stop it or move hal0:
HAL0_PORT=9090 sudo bash installer/install.sh
After changing the port, update /etc/hal0/api.env and
/etc/hal0/openwebui.env to match, then
systemctl restart hal0-api hal0-openwebui.
✗ pre-flight failed: less than 20GB free in /var/lib — free space or
redirect model pulls to a bigger disk:
sudo bash installer/install.sh --models-dir=/mnt/large-disk/hal0-models
The installer records this under [models].pull_root in
/etc/hal0/hal0.toml, so subsequent hal0 model pull calls honor it too.
Python too old. hal0 needs 3.12–3.14. Let the installer provision one:
HAL0_PY_AUTOINSTALL=1 (installs python3.12), or point it at an interpreter you already have with
HAL0_PYTHON=/usr/bin/python3.12. The Hindsight engine venv takes 3.11–3.14;
with none present the installer skips it for that run and names
HAL0_HINDSIGHT_PYTHON. Hermes does not use hal0's interpreter: from 1.6.0
it gets its own uv-managed 3.14 (override with HAL0_HERMES_PYTHON).
No container runtime. install.sh sets HAL0_CONTAINER_REQUIRED=1 and
auto-installs podman via the detected package manager — if that is not
possible it hard-fails with the exact one-liner for your distro. A box that
finishes without a runtime would have every slot dead, which is why this one
is fatal during install and only a warning under hal0 doctor.
GPU/NPU devices not visible inside an LXC. Pre-flight prints the exact
Proxmox dev0/gid fix. CPU-only is a valid install and never blocks.
The hermes step failed on a fresh box. First-boot installs can lose the
dpkg lock race to unattended-upgrades (#1584). The step degrades
gracefully — re-run it afterwards:
hal0 agent install hermes
From 1.6.0 the Hermes build also needs network access (it fetches a managed
Python and the pinned release); offline, it refuses and leaves the live
release running. hal0 doctor all names the failing Hermes row (hermes-api,
hermes_profiles_mcp, hermes_generation, hal0_linger, hermes-gateway-unit).
hal0 doctor: AMDXDNA NPU detected but FastFlowLM not installed. The
host-side sanity probe wants the FLM .deb. If you installed on a non-NPU
host and later added the hardware, re-run installer/install.sh to pick up
the prerequisite. If flm validate fails because libxrt-npu2 is
unavailable from your apt sources, the NPU container slot still works —
it bundles its own XRT runtime.
A slot won't load.
systemctl status hal0-slot@<name>
journalctl -u hal0-slot@<name> -n 60
hal0 doctor profiles          # dangling profile ref? un-pulled image?
Usual causes: the runner image hasn't been pulled yet (the first load blocks
on a multi-GB pull — watch the journal), the model named in
/etc/hal0/slots/<name>.toml isn't in the registry (hal0 model list), or
the GPU is held by image mode (the dispatcher returns 503 while the img
slot owns the GPU — stop image mode or wait for idle-restore).
Something bound the port but nothing answers on it. That is usually a stale netavark DNAT rule left by a container that died badly:
hal0 doctor ports          # audit
hal0 doctor ports --fix    # prune the stale rules
Update troubleshooting
hal0 update                       # check + apply if newer
hal0 update --check               # check only, apply nothing
hal0 update -y                    # skip the confirmation prompt
hal0 update --channel preview     # persist a channel, then check
hal0 update --target 1.0.0        # require the manifest to match exactly
hal0 update --rollback            # restore the previous tree
hal0 update --restart-slots       # bounce only slots still on the old launch command
The CLI is a thin client over /api/updates/* — the swap happens in the
daemon, so the same code path runs whether you update from the shell or the
dashboard. After a successful apply the daemon try-restarts hal0-api
itself.
hal0 <version> supports upgrades from >=1.4.0; this box is on <older>
(system.update_upgrade_path_unsupported) — the box is below the upgrade
floor. See Upgrading from an older release.
Something is wedged after an update. Roll the tree back, then look:
hal0 update --rollback
hal0 doctor all
Rollback restores the previous tree from /var/lib/hal0/hal0.previous.
Config and state are not rewound — schema migrations are forward-only.
Treat rollback as a way to get serving again quickly, not as an undo.
Slots still running the pre-update launch command. By design, an update never bounces a slot on its own. Converge them when you're ready:
hal0 update --restart-slots
Filing a bug
hal0 doctor bundle
Writes a new ./hal0-doctor-bundle-<host>-<ts>-<random>/ directory and prints
its path. It holds system, config, diagnostics and logs, with every config dump
redacted (SECRET / TOKEN / PASSWORD / API_KEY / PRIVATE_KEY / ENCRYPTION_KEY /
SALT-named keys). It is read-only and never uploads anything: tar czf it and
attach it yourself. Exit 1 means some probe commands failed — see
commands.tsv inside. --out <dir> must name a new directory or an empty one
you own.
The bundle is private: the directory is 0700 and every file in it 0600.
One made with sudo is owned by root, so archive it with sudo tar czf, or
sudo chown -R "$USER" it first.
Upgrading from an older release
Upgrades start at 1.4.0. hal0 update on an older box stops before it
downloads anything, and re-running the installer over an older install stops
before it changes anything. A box on 1.3.x takes one hop: hal0 update --target 1.5.0, then hal0 update again. A box older than 1.3.0 first steps
through 1.3.0 by running its installer in place, which keeps /etc/hal0 and
/var/lib/hal0, then takes the same hop:
curl -fsSL https://hal0.dev/install.sh \
  | sudo env HAL0_RELEASES_URL=https://github.com/hal0ai/hal0/releases/download/v1.3.0/stable.json bash
hal0 update --target 1.5.0 -y
hal0 update -y
Or reinstall from scratch with sudo bash installer/uninstall.sh --purge,
which deletes /etc/hal0 and /var/lib/hal0, models included, followed by
the normal one-liner.
Upgrading to 1.6.0
1.6.0 follows the same hal0 update path from any 1.x box at 1.4.0 or
later. Four things to know before you take it:
- Hermes rebuilds once, with a short outage. The first update builds a
Hermes v0.22.4 release on a uv-managed Python 3.14 next to the live 0.19.0
one, stops the agent and gateway, switches, and restarts. A box that
cannot reach the network refuses the build and stays on 0.19.0.
hal0 updatealso regenerates the gateway unit and enables systemd linger for thehal0user. - Run one repair if
hermes-agentis missing from Open WebUI. On a box where Hermes was installed before 1.6.0, runsudo hal0 agent reprovision hermes --repaironce so the default profile's API key is mirrored andhermes-agentappears in the picker.hal0 doctorreports this on thehermes-apirow. - Rolling back to 1.5.x leaves the Hermes build failing (
Hermes Python must be exactly 3.12) until you update forward again. Do not edit/etc/hal0/hermes-python.envto 3.12 on 1.5.x. - Profile chat needs the gateway. With Hermes v0.22.4 a chat opened for a non-default profile (such as
hal0-brain) in Hermes's dashboard, and thehermes chatCLI, attach tohermes-gateway.serviceand reportgateway inaccessiblewhile it is stopped. Runsudo systemctl enable --now hermes-gateway. Once v0.22.4 is live,hal0 update component hermes --target d923a5eb...is refused as a downgrade.
The agent chat proxy is gone: /api/agents/{id}/events, /submit and
/session/* return 404.
Migrations left to you
Two migrations are deliberately left to you, because both rewrite state in
ways that want a human deciding when. The slot-flag fold
(hal0 slot migrate-flags) moves per-slot tunes onto their bound model; it
is a dry run until --apply, and --apply refuses while hal0-api or any
hal0-slot@* unit is active unless you add --stop-services. Back up
hal0.db and your slot dirs first, and expect it to refuse the whole run —
rather than write half of it — when slots share a model with divergent
tunes. Slot id-keying (hal0 slot migrate-id-keying) is optional and
reversible; the runtime reads either layout, so run it in a downtime window.
Everything else — schema migrations, the config-load repairs, and the
runner-system conversion (hal0 runner-images migrate, which archives every
file it changes under /var/lib/hal0/backups/ first; see
Manage runner images) — runs
itself. Full breaking-change, migration and known-issue detail is in
CHANGELOG.md.
Project layout
hal0/
├── src/hal0/         # Python package (FastAPI API + capability layer + ContainerProvider + CLI)
│   ├── providers/    # ContainerProvider, FLMProvider, ComfyUI, etc.
│   ├── slots/        # slot manager, state machine, GpuArbiter
│   ├── runners/      # RUNNER_IMAGES — the runner-image registry
│   ├── bench/        # benchmark planner, runner, store, publish
│   └── omni_router/  # client-side tool-calling loop + tool definitions
├── ui/               # React 18 + TypeScript + Vite + Tailwind 4 dashboard
├── installer/        # install.sh (writes /etc/hal0/, systemd units, hal0-api.service)
│   ├── etc-hal0/     # curated slot seeds + operator profiles.toml
│   └── systemd/      # hal0-agent@ template units
├── tests/            # pytest suite (α unit, γ release-gate, δ harness)
│   └── release-validation/   # versioned RC validation kit (lanes, regressions, boxes)
├── docs/             # user docs (mirrored to hal0.dev/docs) + docs/adr/
The model catalog lives in the SQLite registry in /var/lib/hal0/hal0.db —
the single source of truth for HuggingFace coordinates, SHA-256 digests and
curated filenames. Per-leaf symlinks under the models directory redirect to
a separate storage volume when one is in use.
Quick start (development)
# backend
python -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
hal0 serve --reload

# frontend
cd ui
npm install
npm run dev
The API lives at http://127.0.0.1:8080, the dashboard at the Vite dev
server URL (usually http://127.0.0.1:5173).
Roadmap
No dates — items are direction. The closer to the left, the closer to running on your box. Full version at hal0.dev/#roadmap.
Shipped
- Per-slot podman containers — every inference workload in its own
hal0-slot@<name>.service;ContainerProvider+ the runner-image registry replaced the single-daemon model - hal0-brain steward — top-bar agent chat driving the
hal0-admincatalog under a per-persona tool policy, pausing turns on gated tools for inline approve/deny - Model-owned tuning — the model, not the slot, owns context size, speculation settings and launch flags; profiles supply a floor, never an override
- Slot autoload + eviction priority — binding a model no longer implies
a boot start, and pressure eviction orders by
priorityinstead of an opt-in nobody set - Stacks — declarative model/slot layouts applied atomically with rollback, drift detection and a portable export envelope
- In-dashboard benchmarks — the
hal0.benchengine,/api/benchmarks, a Benchmarks page (roster / runs / evals / run-queue), shareable bundles and leaderboard publishing - Upstream model controls — external providers (OpenRouter, Anthropic,
OpenAI, Google AI Studio, Ollama, custom) with reactive CRUD, per-upstream
model filters and an
enabledkill switch across CLI, MCP and dashboard - Companion services, one surface — Open WebUI, ComfyUI, Hermes, Hindsight and n8n from a dashboard Services page with mDNS discovery
- FLM trio NPU packing — chat + ASR + embed coresident on one AMDXDNA
hardware context, toggled from the slot TOML's
[npu]table - GpuArbiter exclusive image mode — ComfyUI gets the iGPU to itself; LLM GPU slots pause and resume automatically
- OmniRouter client-side tool-calling — 8 tools, dynamic per-request
filtering,
route_to_chatcross-slot delegation - GPU generalization — experimental CUDA and per-slot
gpu_indexpinning for multi-GPU hosts alongside the ROCm/Vulkan defaults - Built-in auth — three tiers, deny-by-default route classification, key rotation and enforcement toggling from CLI or dashboard
- Privileged-seam hardening — the root wrapper allow-lists the content of every unit, drop-in and quadlet it writes; update staging is root-only with the verified digest pinned to the extraction handle
- Installer-owned first-run provisioning —
install.shis the single entry point: curated slot seeds, brain steward pull, service start - One model catalog (the SQLite registry), slot-state Prometheus +
EventBus journal,
hal0 mcpCLI with two-way MCP, cosign-keyless self-update with rollback, bundled agents (Hermes-Agent / pi) - Speculative decoding drafters (1.5) — a model carries a drafter file
(LiLiCorr, DFlash, EAGLE-3) and the profile's
speculationfield picksauto,offorngram - Per-lane device pinning (1.5) — the slot passes
--deviceso each lane lands on its own GPU backend - Hermes profiles as
/v1upstreams (1.6) — Open WebUI and any OpenAI-compatible client chat with each Hermes profile, with hal0's tools and memory wired into every one - Hermes release layout on Python 3.14 (1.6) — immutable, health-checked releases with automatic flip-back
- Memory engine on any model (1.6) — the Hindsight engine runs on a local slot or an upstream model through the
hal0/memoryvirtual id, switched without a restart
Soon
- Federated memory — recall across local + remote sources behind one memory surface (the MCP-client side shipped in v0.9)
- Loadout presets — curated model/slot presets you can flash onto a fresh install
- AUR PKGBUILD & Ubuntu PPA — native distro packages on top of the install script; pacman and apt as first-class install paths
- Light mode toggle
Exploring (v1.x +)
- Multi-host federation — a slot mesh across LAN boxes — primary on the
Strix Halo, embed on the workstation, all behind one
/v1/*surface - Fine-tune & LoRA hot-swap — attach and rotate LoRAs against a warm base model without unloading the underlying weights
- Per-model rate limits & budgets — cost-style accounting for local inference; cap a chatty agent without taking the whole box down
- ChatOps adapters — Slack and Matrix bridges as extensions
License
Apache 2.0. See LICENSE.
Contributing
Pull requests from outside contributors are welcome, and a maintainer
reviews each one. For a large change, open an issue first. See
CONTRIBUTING.md for the sign-off requirement, the test
tiers and the review flow. For questions and general chat, join the
hal0 Discord.
This project adheres to the Contributor Covenant
code of conduct. To report a security vulnerability, see
SECURITY.md.
1 maintainer

Metadata
1 maintainer
Release files for hal0ai 1.6.5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| hal0ai-1.6.5.tar.gz | 10.9 MB | With provenance | Details for hal0ai-1.6.5.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| hal0ai-1.6.5-py3-none-any.whl | Python 3 | none | any | Details for hal0ai-1.6.5-py3-none-any.whl |
Total release size: 13.9 MB
Release files / hal0ai-1.6.5.tar.gz
| Download URL | hal0ai-1.6.5.tar.gz |
|---|---|
| Size | 10.9 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a5b4607c7e23bc5e15136e5ff18e7f00b3812df92b7383a4197a88b00078e285
|
|
BLAKE2b-256 checksum How to use checksums |
51c0e9a5e707ae372057c770a7c5dadaf463222bae3afd66c0ad14a5fa546853
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 24, 2026.
Transparency logRelease files / hal0ai-1.6.5-py3-none-any.whl
| Download URL | hal0ai-1.6.5-py3-none-any.whl |
|---|---|
| Size | 2.9 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e07053ae961ce5c750d20a7419424945577cf36c43af386ef0e1d53a58c6a987
|
|
BLAKE2b-256 checksum How to use checksums |
334ff28b20284359b49ea113c13a021dbb1155b3447b6c757e51fecd89723bcf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 24, 2026.
Transparency logSecurity for hal0ai 1.6.5
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for hal0ai-1.6.5.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 24, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














