
Hearthwork
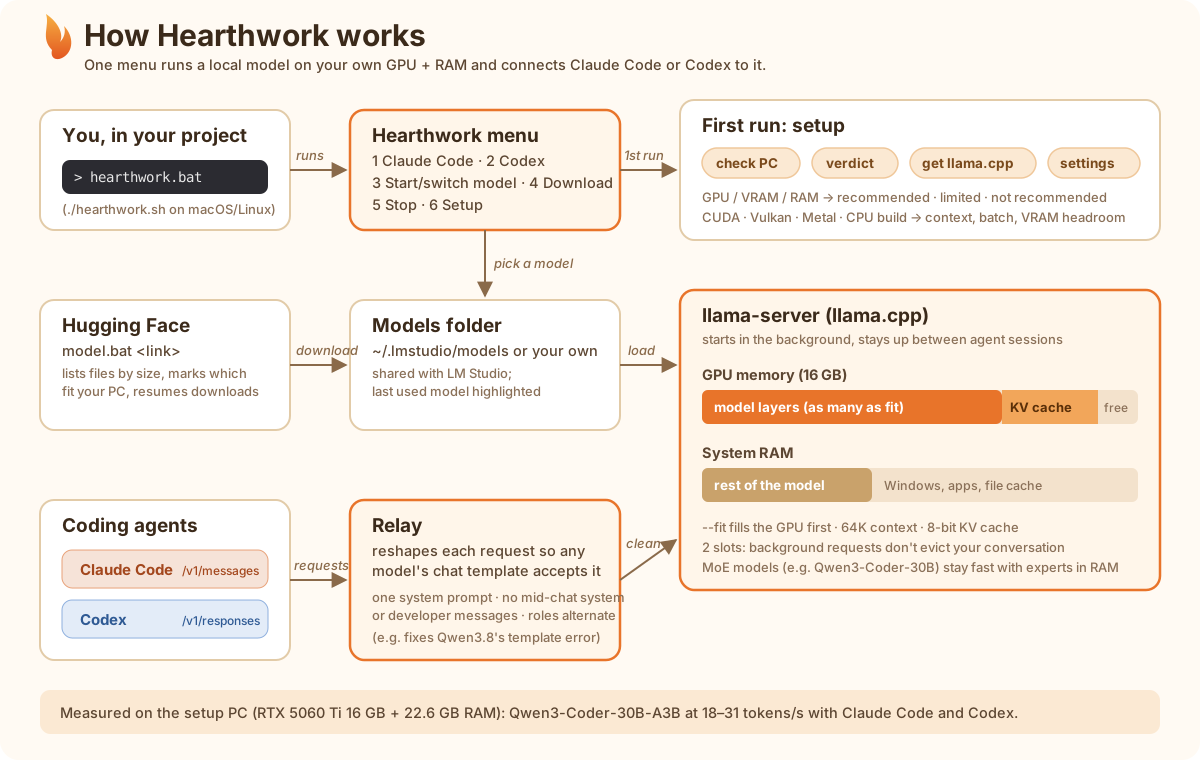
Hearthwork runs a local AI model on your own computer and connects your coding agent to it, from one menu. The model runs on your GPU and RAM, and the agent is Claude Code or Codex. It sets itself up for your hardware, tells you honestly whether your PC is good enough, and handles the small incompatibilities that otherwise break agents on local models.
Works on Windows, macOS and Linux. Needs Python 3.9+ and the agent(s) you want to use; no extra Python packages.
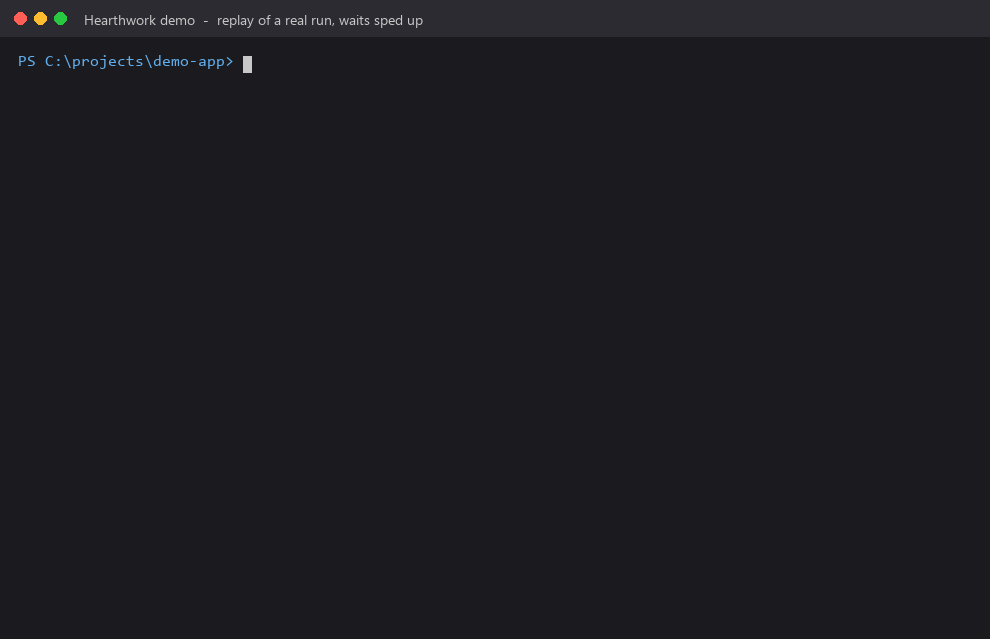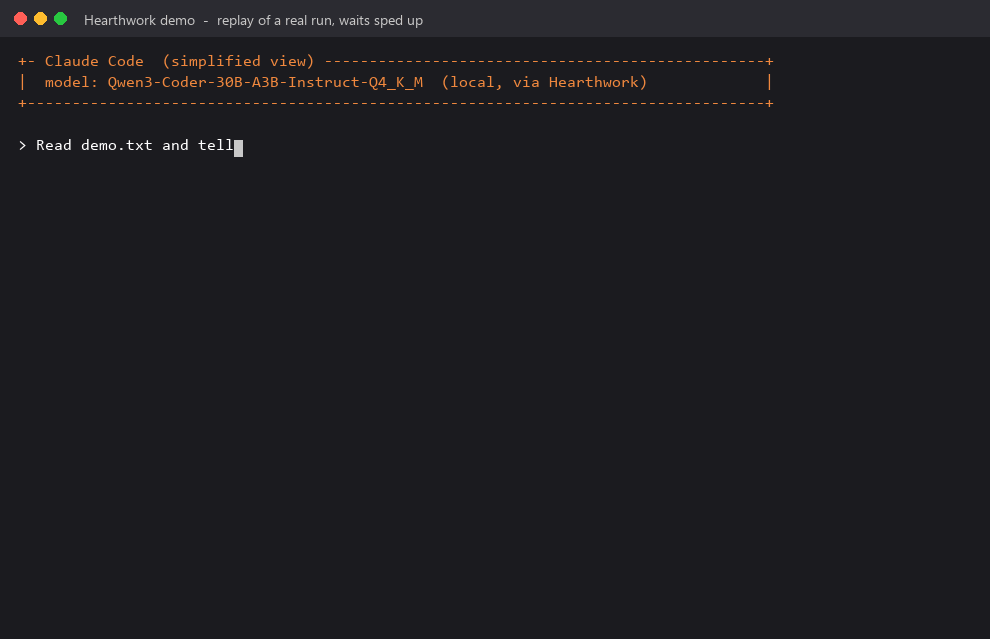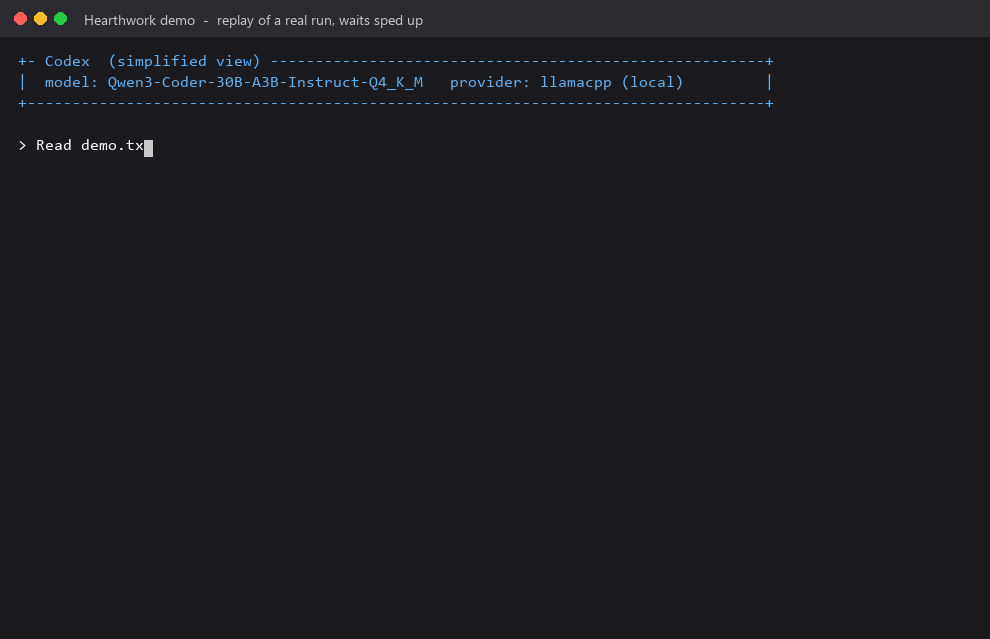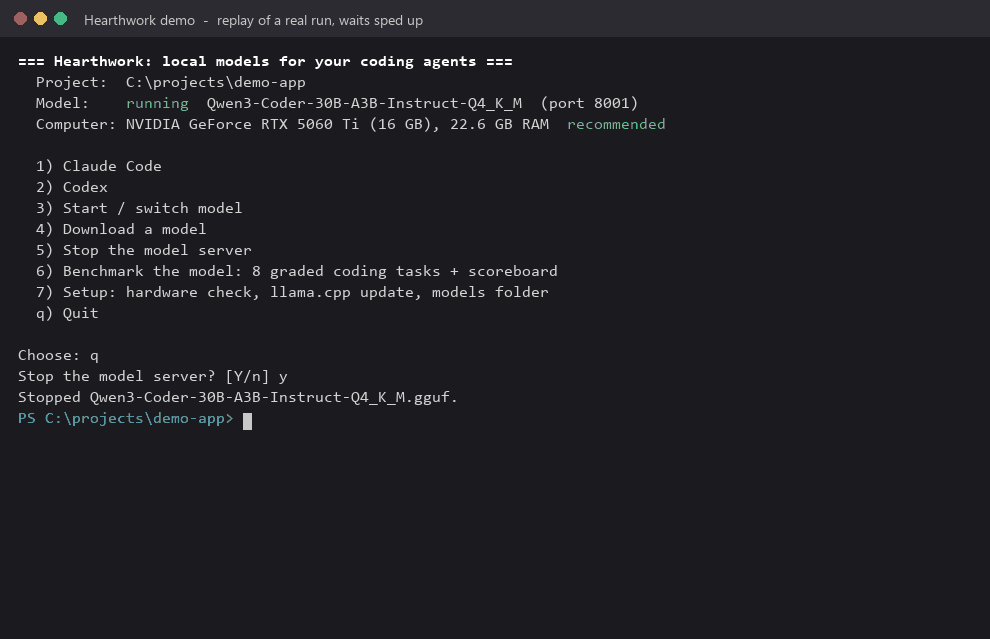
A replay of a real run on an RTX 5060 Ti 16 GB. Waits are sped up, the agent screens are simplified, and paths are shortened.
How it works
Install
uv tool install hearthwork
or pipx install hearthwork. The latest code from GitHub: uv tool install git+https://github.com/BillyMRX1/hearthwork.
This gives you one command, hearthwork. It needs Python 3.9+ and no other Python packages.
- Update:
hearthwork update(oruv tool upgrade hearthwork). - Version and data folder:
hearthwork --version.
Upgrading from the clone version
Earlier versions were run from a cloned folder with .bat/.sh scripts. Those scripts are gone; everything is now the hearthwork command.
- On first run, Hearthwork offers to import an old setup it finds (a folder with
config.jsonandbin/, for example the old clone if you run from it). - Or import it yourself:
hearthwork setup --import <old folder>. - It copies your settings, llama.cpp, prompt caches and benchmark results. The old folder is left as it is.
Where your data lives
Settings, llama.cpp, caches and results are stored per user, outside the install:
| OS | Folder |
|---|---|
| Windows | %LOCALAPPDATA%\hearthwork |
| macOS | ~/Library/Application Support/hearthwork |
| Linux | $XDG_DATA_HOME/hearthwork (default ~/.local/share/hearthwork) |
Set the environment variable HEARTHWORK_HOME to use another folder. Inside it:
config.json: your settings.bin/: llama.cpp.cache/slots/: saved prompt caches.bench/: benchmark results (results.jsonl) and each run's folder (runs/).templates/: chat-template overrides.server.jsonandserver.log: the running model server, and its log on macOS/Linux.
Quick start
From the project you want the agent to work on, run:
hearthwork
The first run sets things up (see below). After that you get one menu:
=== Hearthwork: local models for your coding agents ===
  Project:  C:\projects\my-app
  Model:    running  Qwen3-Coder-30B-A3B-Instruct-Q4_K_M  (port 8001)
  Computer: NVIDIA GeForce RTX 5060 Ti (16 GB), 22.6 GB RAM  recommended

  1) Claude Code
  2) Codex
  3) Start / switch model
  4) Download a model
  5) Stop the model server
  6) Benchmark the model: 8 graded coding tasks + scoreboard
  7) Setup: hardware check, llama.cpp update, models folder
  q) Quit
- Picking an agent starts the model if none is running: you pick it (the last used is highlighted, Enter keeps it), it loads in the background, and then the agent opens in this terminal, in your project folder. Exit the agent to come back to the menu.
- The model server keeps running between agent sessions, so switching between Claude Code and Codex is instant. Both can use it at the same time. On Windows it runs in its own window, which shows its log; on macOS/Linux the log is
server.login the data folder. - On quit it asks whether to stop the server.
- Skip the menu:
hearthwork claude/hearthwork codex.
| Command | What it does |
|---|---|
hearthwork |
The menu above. |
hearthwork claude [args] |
Claude Code with the local model; starts a model first if none is running. Extra arguments go to claude. |
hearthwork codex [args] |
Codex with the local model; starts a model first if none is running. Extra arguments go to codex, e.g. hearthwork codex exec "...". |
hearthwork start [--model X] |
Starts the model server in the background. |
hearthwork stop |
Stops the background model server. |
hearthwork serve [--model X] |
Runs the model server in this terminal; Ctrl+C stops it. |
hearthwork status |
Shows what is running. |
hearthwork model <link> |
Downloads a model from Hugging Face. |
hearthwork bench [--agent claude|codex] [--show] |
Benchmarks the running model through an agent; --show prints the scoreboard. |
hearthwork check [--json] |
Checks whether this PC suits Hearthwork and which models fit (see below). |
hearthwork setup [--update-llama] [--reset] [--import FOLDER] |
Runs setup again. --update-llama gets the newest llama.cpp, --reset starts setup from scratch, --import brings in an old clone-based setup. |
hearthwork update |
Updates Hearthwork itself. |
hearthwork --version |
Prints the version and data folder. |
- Faster first messages: each agent's processed system prompt is saved to
cache/slots/in the data folder when a session ends or the server stops, and restored when the server starts. Measured: the first message after a restart went from 28 s to 13 s (Claude Code) and from 25 s to 17 s (Codex).
Benchmark
hearthwork bench (or menu option 6) drives the running model through Claude Code or Codex in a fresh folder, with 8 prompts in one conversation. It grades each step by checking the files and running the code, not by trusting the agent's reply:
| # | Task | Graded by |
|---|---|---|
| 1 | chat | a reply came back |
| 2 | list files | both files named |
| 3 | read a file | the secret phrase is in the reply |
| 4 | write + run fizzbuzz.py |
running it gives the exact FizzBuzz output |
| 5 | add is_prime + run |
function and docstring exist, FizzBuzz still right, the primes below 30 are printed |
| 6 | fix 3 planted bugs | buggy.py prints 20.0, [9, 5], 0 |
| 7 | write unit tests | test_buggy.py passes. Half points if it copies the functions instead of importing buggy.py |
| 8 | summary | names all 3 files |
- Results are added to
bench/results.jsonlin the data folder. The scoreboard ranks every model and agent you have tried, by score and then time. - Each run's folder stays in
bench/runs/in the data folder, so you can inspect what the agent wrote.
Agents
| Agent | How it connects | Notes |
|---|---|---|
| Claude Code | Anthropic Messages API (/v1/messages) |
Told the real context size, so it compacts in time. |
| Codex | OpenAI Responses API (/v1/responses), as a one-off model provider through -c overrides |
~/.codex/config.toml is not changed. Codex prints "Model metadata ... not found" for any non-OpenAI model; that is expected. |
- Every agent goes through a small relay inside Hearthwork (
src/hearthwork/harnesses.py). It reshapes requests so any model's chat template accepts them. - Why the relay is needed: strict templates (e.g. Qwen3.5/3.8) reject a second system/developer message, unknown roles, or two user messages in a row, and both agents send these. Without the relay, Claude Code and Codex requests failed on Qwen3.8 with "System message must be at the beginning".
- Adding another agent means adding one launch function to
HARNESSESinsrc/hearthwork/harnesses.py.
First run: setup (onboarding)
hearthwork (or hearthwork start) runs setup automatically when nothing is configured yet. It:
- Checks the computer: OS, CPU, RAM, and GPU (NVIDIA / AMD / Intel / Apple) with its memory.
- For AMD/Intel GPUs it reads the GPU's own memory, so integrated graphics aren't mistaken for a real GPU.
- Judges whether a local model is worth it here, and says why:
- RECOMMENDED (continues): a GPU with ≥12 GB and ~26 GB+ of GPU memory + RAM usable for models, or a Mac with ≥32 GB.
- LIMITED (asks; default yes): a 6–12 GB GPU or tight memory. Expect roughly 5–15 tokens/s, or a smaller, weaker version of the model.
- NOT RECOMMENDED (asks; default no, nothing is downloaded): no GPU, an integrated-only GPU, or under ~18 GB usable. Recommends cloud Claude Code instead.
- The reference point is measured: RTX 5060 Ti 16 GB + 22.6 GB RAM ran Qwen3-Coder-30B at 18–31 tokens/s. The thresholds for other hardware are estimates from that.
- Gets llama.cpp. It uses one already in
bin/(in the data folder) or on PATH. Otherwise it downloads the newest official build that matches the hardware:- CUDA for NVIDIA. The CUDA 13 or 12 build is chosen from the driver.
- Vulkan for AMD and Intel.
- Metal on macOS.
- CPU if there is no GPU.
- Asks for the models folder. It finds LM Studio's folder and offers it, so both tools share the same files.
- Picks settings for this hardware: context 64K (32K below ~24 GB GPU memory + RAM), prompt batch size, VRAM headroom, and an 8-bit KV cache.
- Saves everything to
config.jsonin the data folder. If there are no models yet, it suggests one, with the command to download it.
To set up from scratch, for example on another computer, run hearthwork setup --reset (or delete config.json and bin/ in the data folder).
Options
hearthwork start --model <part of a file name>skips the model menu (also forserve).hearthwork start --context Noverrides the context for that run.hearthwork claude --max-output Ncaps the length of each Claude Code reply (default 4096 tokens). Codex has no such setting.- Agent settings stay local:
hearthwork claudeandhearthwork codexonly change settings for that agent process, never your terminal or the agent's own config files.
Downloading models
hearthwork model https://huggingface.co/unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF     (a repo: lists files, you pick one)
hearthwork model unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF                            (same, short form)
hearthwork model https://huggingface.co/<org>/<repo>/blob/main/<file>.gguf            (one file)
- The repo list shows each file's size, smallest first, and whether it fits this computer:
- fits in GPU memory (fastest),
- GPU + RAM (slower; fine for MoE models),
- too big.
- Files are saved to
<models folder>/<org>/<repo>/, LM Studio's layout. - Multi-part models download all their parts.
- Interrupted downloads resume when you run the same command again.
- Gated or private repos: set
HF_TOKEN.
How resources are used
- GPU first. llama.cpp's
--fitputs as much of the model on the GPU as fits, keepingfitTargetMiBfree for the desktop, and runs the rest from RAM. It does this on every start, so it adapts to each model and machine. - Context: it stays at what Claude Code needs, not as large as possible. Claude Code's own prompt is ~20K tokens, so 32K makes it compact after one message. A bigger context than needed only pushes model layers off the GPU and makes it slower.
- Other settings:
- Prompt batch 4096 on 12 GB+ GPUs: a 20K-token prompt took 84 s at 512 and 26 s at 4096.
- 2 slots, so Claude Code's background requests don't evict the conversation's cache.
- The model's RAM part is loaded into RAM rather than memory-mapped from a possibly slow disk.
- Where to change them: the
serversection ofconfig.jsonin the data folder.hearthwork setuprecalculates them. - Not used: speculative decoding. Measured with Qwen3-Coder-30B (MoE, experts partly in RAM): n-gram speculation guessed 92% of the tokens when editing a file, but ran only 2–3% faster (within noise); the simple variant ran 14–19% slower. Verifying several guessed tokens at once routes them through many different experts, and part of those sit in RAM, so verifying costs about as much as generating. It may help when a model fits entirely in VRAM.
Models
- Requirements: any GGUF model works if it supports tool calling (Claude Code reads, edits and runs things through tools) and fits.
- Mixture-of-experts (MoE) models, like Qwen3-30B-A3B, stay fast even partly in RAM.
- Dense models slow down a lot once they spill out of GPU memory.
- Any model's chat template is handled. The relay moves the
systemmessage Claude Code places mid-conversation into the neighbouring user message, because strict templates reject it ("System message must be at the beginning").- Escape hatch for a template broken in some other way: put a fixed copy at
templates/<model file name without .gguf>.jinjain the data folder.
- Escape hatch for a template broken in some other way: put a fixed copy at
Measured on the setup PC (RTX 5060 Ti 16 GB over PCIe 4.0 x4, 22.6 GB RAM, 2026-10-06/07)
Benchmark scoreboard (hearthwork bench: 8 graded coding tasks in one agent conversation; Claude Code in dontAsk permission mode):
| Model (Q4_K_M, all MoE) | Size | Codex | Claude Code |
|---|---|---|---|
| Qwen3.5-35B-A3B | 20.5 GB | 8/8 in 2.6 min | 8/8 in 3.6 min |
| Qwen3-Coder-30B-A3B | 17.3 GB | 8/8 in 4.2 min | 8/8 in 3.9 min |
| GLM-4.7-Flash | 17.1 GB | 8/8 in 4.5 min | 7.7/8 in 3.9 min (one bug left unfixed) |
- Generation speed:
- Qwen3-Coder-30B: 18–38 tokens/s, depending on context length.
- A dense model partly in RAM (Huihui-Qwen3.8-27B Q3_K) managed only ~6 tokens/s.
- Claude Code's auto mode slows local models down. In auto mode, Claude Code asks the model to check every command first. With a local model those checks are slow and can time out and block the command. One GLM-4.7-Flash run took 48.7 min in auto mode and 3.9 min without it.
For comparison, a disk-streaming engine built on AirLLM ran the same Qwen3-Coder model about 10x slower on this PC.
Check your PC first
See whether Hearthwork is worth it on a computer, and which model to use, without installing anything:
uvx hearthwork check
It shows the hardware, the verdict, installed agents, and the best version of each suggested coding model that fits (sizes live from Hugging Face). Once Hearthwork is installed: hearthwork check (add --json for machine-readable output).
1 maintainer

Metadata
1 maintainer
Release files for hearthwork 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| hearthwork-0.2.1.tar.gz | 42.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hearthwork-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 84.3 kB
Release files / hearthwork-0.2.1.tar.gz
| Download URL | hearthwork-0.2.1.tar.gz |
|---|---|
| Size | 42.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
81d72d7bf80baa1d78360d33f6fce4c05a2f19c8f495a70dd0089c5143730b26
|
|
BLAKE2b-256 checksum How to use checksums |
c3f065addca833da6f7c4c860d7c113819daab2736e58b553f291a1c34f1ffa4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.11 {"installer":{"name":"uv","version":"0.12.11","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / hearthwork-0.2.1-py3-none-any.whl
| Download URL | hearthwork-0.2.1-py3-none-any.whl |
|---|---|
| Size | 42.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1b73797cd63b375e9069e688ddb26ffb141170e66da45b3cfd6b540c09ff8ce7
|
|
BLAKE2b-256 checksum How to use checksums |
ee215830942ee012b9588e80702846bf5d2844ccbc826e70bde7f9bdf5ce814a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.11 {"installer":{"name":"uv","version":"0.12.11","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














