
HIDE-deconv
A framework for characterizing cellular remodeling from bulk RNA-seq data through hierarchical cell-type deconvolution.

Key Features
- Bulk RNA-seq cell-type deconvolution using annotated single-cell references
- Hierarchical estimation of cell-type compositions across multiple annotation levels
- Characterization of cellular remodeling across cell populations and biological conditions
- Configurable domain-transfer and library-size correction
- Downstream analysis of deconvolution results, including PCA, UMAP, clustering, survival analysis, and differential composition analysis
- Python API and command-line interface for reproducible workflows
- Supports AnnData based single-cell workflows
- Local execution suitable for secure research environments
For a detailed overview of all features and usage, please read the Userguide
Real world performance: Morandini
As an additional evaluation on real world data, HIDE-deconv was benchmarked on the Morandini bulk RNA-seq dataset using the HaoSub single-cell reference, following the evaluation procedure of the deconvBench framework from Dietrich et al. (2026).
| Method | Pearson R | RMSE |
|---|---|---|
| AutoGeneS | 0.819 | 0.182 |
| BayesPrism | 0.254 | 0.295 |
| Bisque | 0.872 | 0.122 |
| CIBERSORTx | 0.648 | 0.193 |
| DWLS | 0.909 | 0.103 |
| MuSiC | 0.319 | 0.275 |
| Scaden | 0.795 | 0.150 |
| SCDC | 0.468 | 0.239 |
| HIDE-deconv | 0.934 | 0.094 |
HIDE-deconv was evaluated independently (Benchmark scripts). Results for the other methods are taken from Dietrich et al. (2026)
Installation
# Create and activate a new virtual environment (recommended)
python3 -m venv .venv
source .venv/bin/activate

# Install HIDE-deconv
pip install hide-deconv
Necessary Data
- Single-cell data: Annotated AnnData (.h5ad) file with gene names in
adata.var_namesand cell type annotations for each desired layer inadata.obs(at least one layer of cell type annotations is necessary). - Bulk RNA-seq data: CSV file, genes as row index, samples as columns. Gene IDs must match single-cell data.
- Sample sheet (optional): CSV with sample meta-information (e.g., cohort, survival time, event).
- Data Normalization: We recommend to use raw counts for all datasets.
Command Line Workflow
Deconvolution (standard workflow):
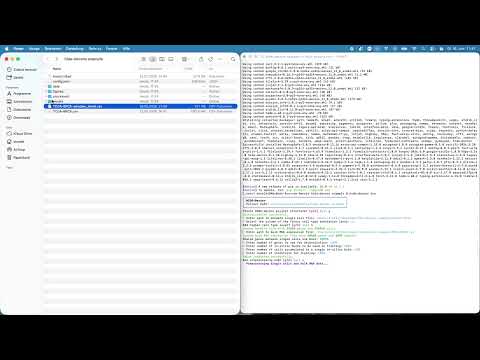
hide-deconv run --path <project_dir>
This initializes the project, preprocesses data, trains the model, and runs deconvolution.
Difference in composition & survival analysis:
hide-deconv analyze diff --path <project_dir>
hide-deconv analyze survival --path <project_dir>
- For difference analysis, the sample sheet must contain columns for sample ID and cohort.
- For survival analysis, the sample sheet must contain columns for sample ID, survival time and event. Values in the event column must be either "1": event occured or "0": no event.
Command overview:
hide-deconv help
This displays a short introduction to the command line interface and gives an overview of all available commands.
Tutorials
Quick Deconvolution API Example
HIDE-deconv contains a "lazy" API for users who want quick access to deconvolution.
import anndata as ad
import pandas as pd
from hide_deconv import deconvolution

adata = ad.read_h5ad("single_cells.h5ad")
bulk = pd.read_csv("bulk.csv", index_col=0) # genes x samples

results = deconvolution(adata, bulk, celltype_cols=["cell_type", "major"]) # Two layer hierarchy
# results = deconvolution(adata, bulk, celltype_cols="major") # Deconvolution only on major level

# results is a list of pandas DataFrames, one per hierarchy layer
# results[0] is the finest layer, results[1] the next coarser layer
If you only pass adata and bulk, celltype_cols defaults to "cell_type".
Extended API Example
For experienced users offers HIDE-deconv a highly customizable API, where they can integrate their own preprocessing steps into the pipeline. An example is given below.
import anndata as ad
import pandas as pd
import numpy as np
from hide_deconv.preprocessing import (
	train_test_split_adata,
	create_reference,
	create_hierarchy,
	create_bulks,
)
from hide_deconv.models import HIDE
from hide_deconv.statistic import run_mann_whitney_u

# 1. Load AnnData
adata = ad.read_h5ad("single_cells.h5ad")

# 2. Split into training and test set
adata_train, adata_test = train_test_split_adata(adata, celltype_col="cell_type", train_frac=0.7)

# 3. Create reference profiles and hierarchy (single layer example)
X_sub = create_reference(adata_train, celltype_col="cell_type")
A_l = [pd.DataFrame(np.eye(X_sub.shape[1]), index=X_sub.columns, columns=X_sub.columns)]
X_l = [X_sub]

# 4. Simulate training bulks
Y_train, C_train = create_bulks(adata_train, n_bulks=1000, n_cells_per_bulk=100, celltype_col="cell_type")

# 5. Simulate test bulks
Y_test, C_test = create_bulks(adata_test, n_bulks=100, n_cells_per_bulk=100, celltype_col="cell_type")

# 6. Initialize and train model
hide = HIDE(X_l, A_l)
hide.train(Y_train, C_train, iter=1000)

# 7. Calculate library sizes on the complete single-cell gene set
library_sizes = (
	adata.obs.assign(library_size=np.asarray(adata.X.sum(axis=1)).ravel())
	.groupby("cell_type")["library_size"]
	.median()
)

# 8. Deconvolution on test data
results = hide.predict(
	Y_test,
	norm=True,
	library_sizes=library_sizes,
)["prediction"]

# 9. Optional: Difference in composition analysis
# (requires a sample sheet with columns 'SampleID' and 'Cohort')

# sample_sheet = read_csv("sample_sheet.csv")
# diff = run_mann_whitney_u(results[0], sample_sheet, sample_id_col="SampleID", cohort_col="Cohort")
Citation
If you use HIDE-deconv, please cite the following preprint.
HIDE-Deconv: A hierarchical deconvolution framework for multiscale characterization of cellular remodeling
Dennis Voelkl, Sarah Bolz, Austin Rayford, Thomas Stevenson, Thomas Sterr, Malte Mensching-Buhr, Nicole Seifert, Julia Arp, Cornelia Schuster, Jana Tausche, Laurenz Engel, Helena U. Zacharias, Michael Altenbuchinger, Franziska Görter bioRxiv 2026.08.24.746754; doi: https://doi.org/10.64898/2026.08.24.746754
License
This project is licensed under the MIT License.
Contact
For questions, support or scientific collaboration:
- Dennis Voelkl: dennis.k.voelkl(at)uib.no
- Franziska Goertler: Franziska.Gortler(at)uib.no
1 maintainer

Metadata
1 maintainer
Release files for hide-deconv 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| hide_deconv-0.4.0.tar.gz | 69.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hide_deconv-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 165.5 kB
Release files / hide_deconv-0.4.0.tar.gz
| Download URL | hide_deconv-0.4.0.tar.gz |
|---|---|
| Size | 69.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
19b55214d7643c58525aef76644edfff0e9079bc862b31804fbe00b08f526a9f
|
|
BLAKE2b-256 checksum How to use checksums |
d283e5a6d72a07ae899222896a58e5ecc01db55d865f9a73fe23529501e9a0b5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 12, 2026.
Transparency logRelease files / hide_deconv-0.4.0-py3-none-any.whl
| Download URL | hide_deconv-0.4.0-py3-none-any.whl |
|---|---|
| Size | 96.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
faa9991b55ac9052cffe92a82ec9f5e8f7d805530cc4577509b8471df92058fb
|
|
BLAKE2b-256 checksum How to use checksums |
749a8633d32f00cb25fe62ce6733847e4293c90c152cc228cb59b9f971d6f9e1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 12, 2026.
Transparency log













