
hindko-tokenizer
The Hindko tokenizer as a Python package. Install it from PyPI and start tokenizing: no repository clone and no download, because the tokenizer file ships inside the package.
Hindko (Northern hno, Southern hnd) is the Indo-Aryan language of Peshawar, Hazara and neighbouring districts of Pakistan, written in Urdu (Perso-Arabic) script. This is a 32,768-id SentencePiece Unigram tokenizer trained on Hindko newspapers, books and web text.
pip install hindko-tokenizer
Quick start
from hindko_tokenizer import HindkoTokenizer

tokenizer = HindkoTokenizer.from_pretrained()

text = "ایہہ بہت کہٹ لوک جانڑدین کہ ڈرامے دی پیدائش کسراں تے کتھے ہوئی آئی۔"
print(tokenizer.tokenize(text))
print(tokenizer.encode(text))
print(tokenizer.decode(tokenizer.encode(text)))   # gives back the same text
What you can do
tokenizer.tokenize(text)          # token strings; "▁" marks a preceding space
tokenizer.encode(text)            # token ids (no special tokens are added)
tokenizer.decode(ids)             # ids back to text
tokenizer.count_tokens(text)      # how many tokens a text costs

tokenizer.encode_batch(texts)     # many texts at once (parallel)
tokenizer.decode_batch(list_of_ids)

tokenizer.vocab_size              # 32768
tokenizer.token_to_id("\n")       # 64
Normalizing input
The tokenizer itself changes nothing in your text. User-typed or pasted text often has extra spaces, invisible characters or Arabic-keyboard letters (ي ك instead of ی ک), and these cost extra tokens. normalize() puts text into the form the tokenizer was trained on:
from hindko_tokenizer import normalize

clean = normalize(raw_text)
ids = tokenizer.encode(raw_text, normalize=True)               # same as encode(normalize(raw_text))
tokenizer = HindkoTokenizer.from_pretrained(normalize=True)    # or switch it on for every call
normalize() is deterministic and idempotent. It is not reversible, so after it decode() returns the normalized text. Do not use it where whitespace must stay exactly as it was. It is the frozen release 1.0.1 used for all training and evaluation text.
Use with Hugging Face transformers
pip install "hindko-tokenizer[transformers]"
hf_tokenizer = tokenizer.to_transformers()
hf_tokenizer(text)["input_ids"]   # the same ids as tokenizer.encode(text)
Load from a file
tokenizer = HindkoTokenizer.from_pretrained("path/to/folder")   # a folder with tokenizer.json, or the file itself
tokenizer.backend                                               # the underlying tokenizers.Tokenizer
Results
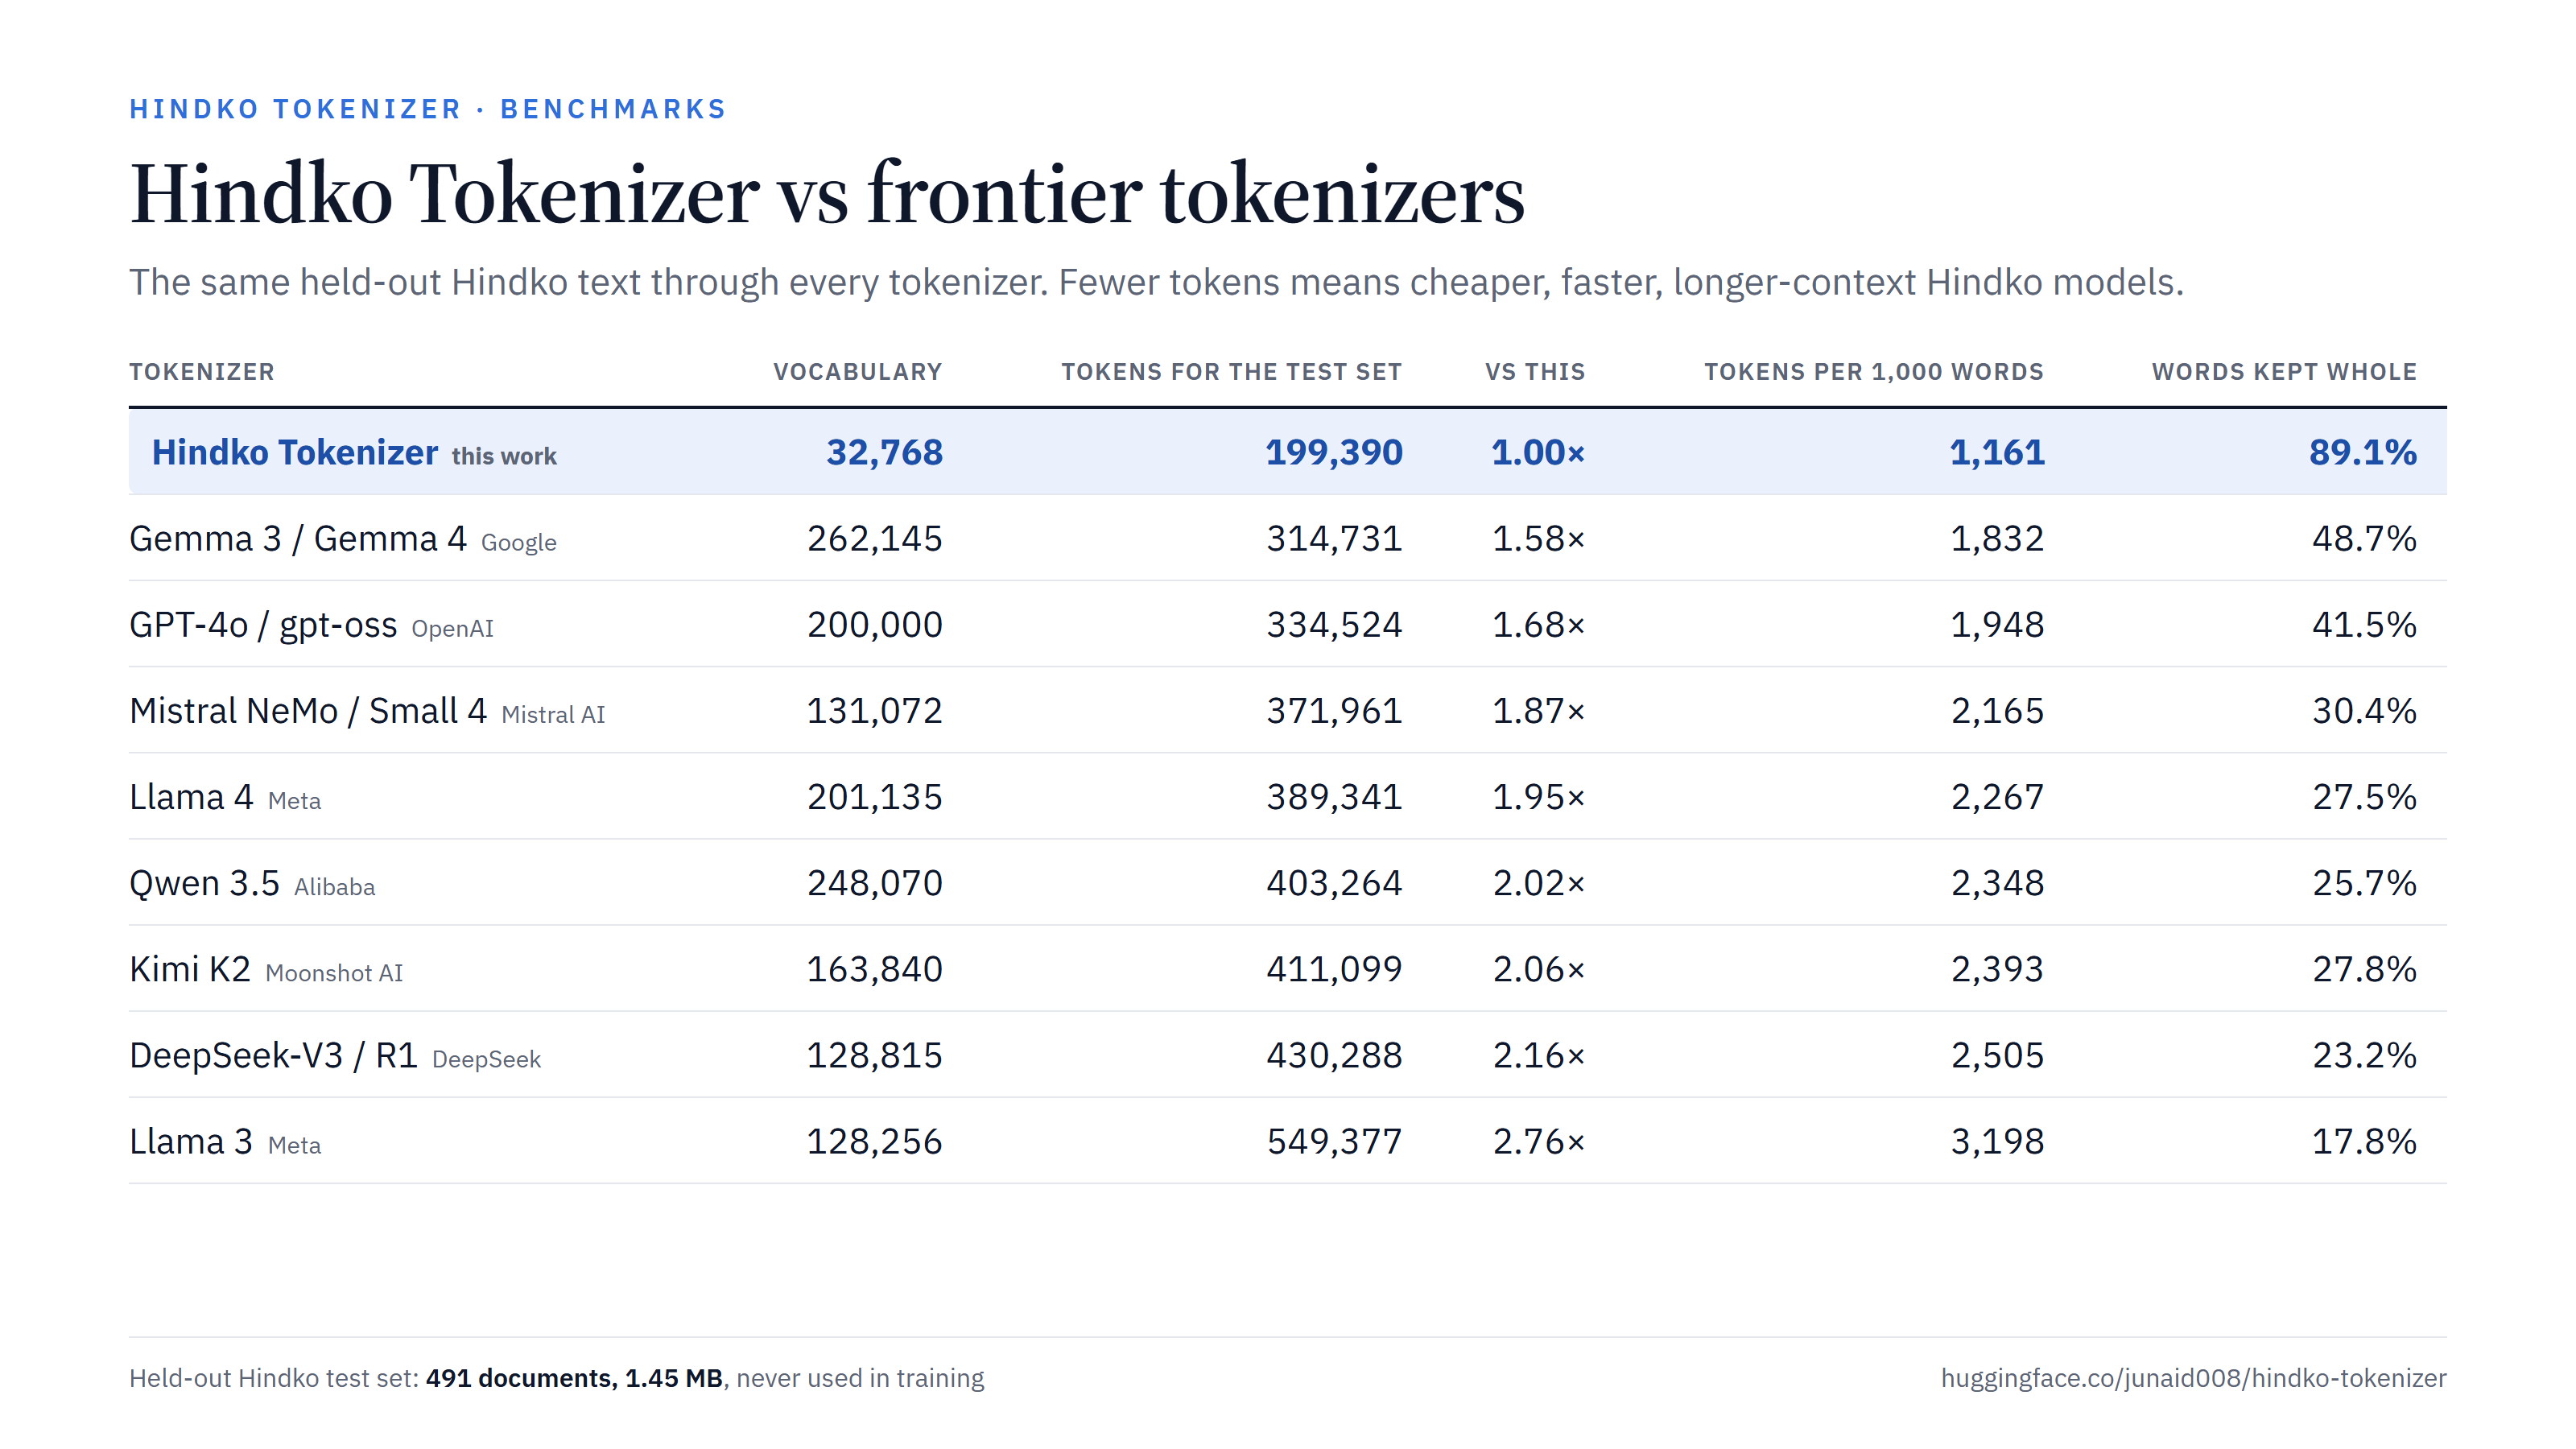
Measured on the held-out test split of the Hindko corpus (details and every source on the model card):
| External comparison | Fewest tokens of the 131 distinct lossless tokenizers compared |
| Nearest external tokenizer | ProximaAI/urnova-95m: this tokenizer uses 16.7 % fewer tokens |
| Frontier tokenizers | 36.6 % fewer tokens than Gemma 3/4, 40.4 % fewer than GPT-4o, 48.8 % fewer than Llama 4, 50.6 % fewer than Qwen 3.5, 53.7 % fewer than DeepSeek-V3 |
These gains apply to a model that is trained or adapted with this tokenizer. The tokenizer cannot be plugged into an existing model such as GPT-4o or Llama.
Links
- Model card, benchmarks and evaluation: huggingface.co/junaid008/hindko-tokenizer
- Source code: github.com/junaidaslam2006/Hindko-Tokenizer
- Hindko text embeddings:
hindko-embeddings
License
CC BY 4.0: free to use, share and adapt, including commercially, with attribution. The license covers the tokenizer and this package, not the texts it was trained on.
1 maintainer

Metadata
1 maintainer
Release files for hindko-tokenizer 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| hindko_tokenizer-1.0.0.tar.gz | 382.5 kB | Without provenance | Details for hindko_tokenizer-1.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| hindko_tokenizer-1.0.0-py3-none-any.whl | Python 3 | none | any | Details for hindko_tokenizer-1.0.0-py3-none-any.whl |
Total release size: 768.6 kB
Release files / hindko_tokenizer-1.0.0.tar.gz
| Download URL | hindko_tokenizer-1.0.0.tar.gz |
|---|---|
| Size | 382.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
389b6e5545f719b4fdd31d8c916c1eb54274c12050cdcc12f712ce50b0b06f29
|
|
BLAKE2b-256 checksum How to use checksums |
4d2b9da7e46c853227b63470aa3a85f0b3ac6687ee7fd32928dc74c9dbbae3a8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.9
|
Release files / hindko_tokenizer-1.0.0-py3-none-any.whl
| Download URL | hindko_tokenizer-1.0.0-py3-none-any.whl |
|---|---|
| Size | 386.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
616adcd592fe815d6c619150f63987b4822fdda846b9f55bc347d8bfe63a090c
|
|
BLAKE2b-256 checksum How to use checksums |
1a52c2395e79dd3a86b7c5ea28d9c0f86c1d07ad9a41f6db8db8076e738b3cb3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.9
|
Security for hindko-tokenizer 1.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













