
MLForge



A reproducible Python toolkit for training, evaluating, benchmarking, and comparing tabular machine-learning models with leakage-safe preprocessing and deterministic cross-validation.
MLForge is a local, library-first workflow built on pandas and scikit-learn. It turns a CSV and an explicit target into inspectable evidence: validated data, fair model comparisons, immutable JSON manifests, trusted-local model artifacts, and schema-checked predictions. It is deliberately small, single-process, and honest about what it does not yet implement.
Quick start
Install the published distribution (the import package and command are both named mlforge):
python -m pip install hivmind-mlforge
mlforge --version
From a repository clone, run the bundled classification benchmark:
mlforge benchmark examples/customer_churn.csv --target churn --metric balanced_accuracy --cross-validation-folds 3 --benchmarks-dir mlbenchmarks
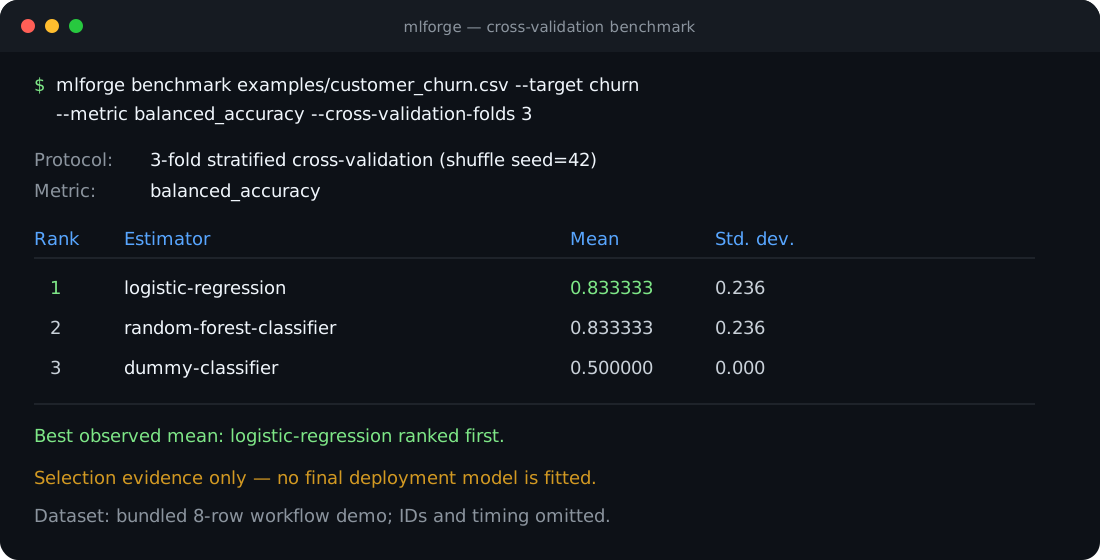
Representative output from the bundled eight-row dataset is shown below. Scores are captured from the real command; run IDs, filesystem paths, and timing are omitted because they vary. The tiny dataset demonstrates the workflow, not estimator quality.
Protocol: 3-fold stratified cross-validation (shuffle seed=42)
Primary metric: balanced_accuracy
Leaderboard:
  1. logistic-regression:        0.833333 +/- 0.236
  2. random-forest-classifier:   0.833333 +/- 0.236
  3. dummy-classifier:           0.500000 +/- 0.000

Best observed mean: logistic-regression ranked first.
Note: cross-validation selects an estimator; it does not fit a final deployment model.
Continue with the complete local workflow tutorial to train, inspect, save, load, and predict with a fitted artifact.
Why MLForge
Model comparison is easy to make convincing and surprisingly hard to make fair. Preprocessing the full dataset leaks validation information. Giving estimators different partitions makes scores incomparable. Unstable tie-breaking makes repeated runs hard to explain. Recording only the winning number discards the evidence needed to audit it later.
MLForge makes those concerns explicit:
| Engineering problem | MLForge boundary |
|---|---|
| Validation data influences imputation, scaling, or encoding | Preprocessing is fitted only on the training partition of each holdout or fold |
| Estimators are compared on different rows | Every estimator receives the same recorded partition fingerprints |
| Equivalent scores produce unstable ordering | Mean, population standard deviation, and estimator ID define deterministic ranking |
| Failed candidates disappear from the report | Expected failures remain visible in terminal immutable manifests |
| A metric cannot be connected to its inputs | Dataset hashes, configuration, seeds, versions, partitions, warnings, and metrics are persisted |
| Serialized models are treated as ordinary data | Safe inspection is separate from explicit trusted pickle loading |
The result is not an experiment-tracking platform. It is a focused reference workflow whose data, modeling, persistence, and trust boundaries are small enough to understand and test.
Core capabilities
Training
- Strict local CSV validation and deterministic profiling.
- Explicit classification or regression task selection.
- Deterministic train/validation splitting and leakage-safe preprocessing.
- Five baseline estimators with task-appropriate held-out metrics.
- Versioned, create-only run manifests with failure evidence.
Artifacts and prediction
- Fitted preprocessing and estimator saved together in a versioned
.mlforgearchive. - Structure, schema, environment, size, lineage hash, and payload checksum inspection without deserializing the model.
- Explicit trusted loading for pickle-based artifacts.
- Exact feature-schema validation, column-order restoration, batch prediction, and atomic CSV output.
Benchmarking
- Dummy, logistic-regression, and random-forest classification baselines by default.
- One shared holdout split, selectable primary metric, deterministic ranking, and fitted in-memory winner.
- A strict aggregate manifest that references every underlying run.
Cross-validation
- Deterministic stratified 2-10 fold classification benchmarking.
- A fresh estimator and fold-local preprocessing pipeline for every training fold.
- Identical ordered fold fingerprints for every estimator.
- Per-fold metrics, arithmetic means, population standard deviations, stability-aware ranking, warnings, timing, and failure location.
- Selection evidence only: no fitted final model and no nested-tuning performance claim.
Reliability guarantees
- Fit after split: no data-derived transformer state is learned from validation rows.
- Comparable evidence: dataset bytes, target, configuration, seed, and exact partitions are recorded and checked before comparison.
- Immutable local history: run, holdout-benchmark, and cross-validation manifests are atomically created and never silently overwritten.
- Bounded input handling: CSV and artifact readers validate structure and enforce documented size limits.
- Fail-closed artifact loading: untrusted, corrupt, incompatible, or structurally invalid artifacts are rejected.
- Reproducible randomness: supported splits and randomized estimators use recorded seeds; random forests use one process.
Numerical results can still change when dependency versions change. Manifests record the exact Python, MLForge, pandas, NumPy, SciPy, and scikit-learn versions so the environment can be reconstructed and interpreted.
Architecture
flowchart LR
    A["CSV + explicit target"] --> B["Validation + fingerprint"]
    B --> C["Profile"]
    B --> D["Holdout split"]
    B --> E["Shared stratified folds"]
    D --> F["Leakage-safe pipeline fit"]
    E --> G["Fresh fold-local pipeline fits"]
    F --> H["Metrics + run manifest"]
    G --> I["Aggregates + leaderboard"]
    I --> J["Cross-validation manifest"]
    H --> K["Trusted-local artifact"]
    K --> L["Schema validation + prediction"]
The CLI is a thin adapter over importable domain APIs. Dataset, pipeline, training, benchmark, run, artifact, and inference modules own their behavior; none depends on a web service, database, or worker. See the architecture document for responsibilities, dependency direction, extension points, and security boundaries.
Python API
The same cross-validation workflow is available as a typed Python API:
from pathlib import Path

from mlforge.benchmarks import (
    CrossValidationConfig,
    LocalCrossValidationStore,
    cross_validate_benchmark,
)
from mlforge.datasets import load_csv
from mlforge.pipelines import CrossValidationSplitConfig

dataset = load_csv(Path("examples/customer_churn.csv"), target="churn")
result = cross_validate_benchmark(
    dataset,
    CrossValidationConfig(
        primary_metric="balanced_accuracy",
        split=CrossValidationSplitConfig(fold_count=3, random_seed=42),
    ),
    store=LocalCrossValidationStore(Path("mlbenchmarks/cross-validation")),
)

print(result.manifest.winner)
print(result.manifest.to_json())
Cross-validation deliberately returns an immutable selection record, not a fitted model. For the
artifact and prediction workflow, see the runnable
examples/train_and_predict.py and the
Python API reference.
CLI
Every command provides --help; user-facing workflows also support --json where structured
output is useful.
| Workflow | Example |
|---|---|
| Profile | mlforge dataset profile DATA.csv --target TARGET --json |
| Train | mlforge train DATA.csv --target TARGET --task classification --estimator logistic-regression --runs-dir mlruns |
| Holdout benchmark | mlforge benchmark DATA.csv --target TARGET --metric balanced_accuracy --runs-dir mlruns --benchmarks-dir mlbenchmarks |
| Cross-validation | mlforge benchmark DATA.csv --target TARGET --metric balanced_accuracy --cross-validation-folds 5 --benchmarks-dir mlbenchmarks |
| Inspect a run | mlforge runs show RUN_ID --runs-dir mlruns --json |
| Inspect an artifact safely | mlforge artifacts inspect artifacts/RUN_ID.mlforge --json |
| Predict from a trusted artifact | mlforge predict artifacts/RUN_ID.mlforge FEATURES.csv --trust-artifact --output predictions.csv |
Use --trust-artifact only after verifying the artifact's source and custody. Inspection and a
matching checksum do not make hostile pickle content safe.
Installation
MLForge supports Python 3.11 and 3.12. Create an isolated environment before installation:
python -m venv .venv
python -m pip install hivmind-mlforge
Activate with .venv\Scripts\Activate.ps1 on Windows PowerShell or
source .venv/bin/activate on macOS/Linux. For a development checkout, install the development
extra instead:
python -m pip install -e ".[dev]"
Validation evidence
The v0.2.1 candidate has a 210-test behavioral suite and enforces a conservative 80% statement
coverage floor (84.66% measured on Python 3.12 during preparation). CI covers Ubuntu on Python
3.11/3.12 and Windows on Python 3.12, with Ruff, formatting, strict mypy, pytest, package builds,
pip check, and installed-wheel smoke tests. Offline real-data tests exercise scikit-learn's breast
cancer and diabetes datasets; separate release validation covers Iris, Wine, and breast cancer
cross-validation workflows.
See release validation for the dataset and clean-package boundaries.
Documentation
- Complete local workflow tutorial
- Python API reference
- Architecture and design boundaries
- Compatibility and versioning policy
- Artifact trust and secure-use guidance
- Release validation
- Maintainer release procedure
- Roadmap and changelog
Development
Run the same quality gate used by CI:
ruff check .
ruff format --check .
mypy src tests
python -m pytest
python -m build
python -m twine check --strict dist/*
python -m pytest includes pytest-cov and fails below 80% statement coverage. The CI build then
installs the wheel into a separate environment and executes scripts/wheel_smoke.py outside the
source tree.
Project structure
mlforge/
|- src/mlforge/          # Importable production package
|  |- datasets/          # Strict ingestion and deterministic profiles
|  |- pipelines/         # Splits, folds, feature roles, and preprocessing
|  |- training/          # Baseline fitting and evaluation
|  |- benchmarks/        # Holdout/CV orchestration, ranking, and manifests
|  |- runs/              # Immutable experiment records and comparison
|  `- artifacts/         # Trusted-local model persistence
|- tests/                # Unit, integration, API, CLI, edge-case, and real-data tests
|- examples/             # Runnable source-checkout workflows and small CSVs
|- scripts/              # Release-tag and installed-wheel validation
|- docs/                 # Tutorial, API, architecture, security, and release guidance
`- .github/workflows/    # Cross-platform CI and trusted release publishing
Current limits and roadmap
MLForge currently supports local, single-process tabular classification/regression, while cross-validation is classification-only. It does not provide final-model fitting, hyperparameter tuning, nested evaluation, an HTTP API, a dashboard, shared storage, distributed execution, a model registry, authentication, deployment, or monitoring.
Milestone 9 service infrastructure remains conditional on real multi-user requirements. Final-model fitting is a separate post-v0.2.1 product decision. The roadmap records these boundaries so planned work is not presented as shipped functionality.
Contributing, security, and license
Read CONTRIBUTING.md for setup, required checks, and pull-request expectations. Report vulnerabilities through the private process in SECURITY.md, and review the artifact security model before loading or sharing model files.
MLForge is available under the Apache License 2.0, including its explicit patent grant.
1 maintainer

Metadata
1 maintainer
Release files for hivmind-mlforge 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| hivmind_mlforge-0.2.1.tar.gz | 142.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hivmind_mlforge-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 228.5 kB
Release files / hivmind_mlforge-0.2.1.tar.gz
| Download URL | hivmind_mlforge-0.2.1.tar.gz |
|---|---|
| Size | 142.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e6f3a6325a558d3cafee5773785a4c19471e5de3f29b02a3552c6c21934f749b
|
|
BLAKE2b-256 checksum How to use checksums |
04df7eebf11fd57ad7b058ef77165f64a27b4dd73c506e78a526cc65b31c3667
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 20, 2026.
Transparency logRelease files / hivmind_mlforge-0.2.1-py3-none-any.whl
| Download URL | hivmind_mlforge-0.2.1-py3-none-any.whl |
|---|---|
| Size | 86.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f8493ef2c23864bf5dcdd2304750f22dd4c9a5756401199da9b1b56f1f118252
|
|
BLAKE2b-256 checksum How to use checksums |
4fdfbb0c9441bf7c5a64fa69efb2634b9f041eae2e3f158b1b922a2f0080d2ac
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 20, 2026.
Transparency log













