
holdline
Hold the line on agent quality. holdline is an eval and regression gate for AI agents. It records what your agent did, checks the trajectory as well as the answer, runs every case several times because agents are not deterministic, measures your LLM judge against human labels before trusting it, and fails the pull request when a change makes the agent measurably worse.
Zero runtime dependencies. Python 3.9+. Works with any agent you can call from Python.
pip install holdline
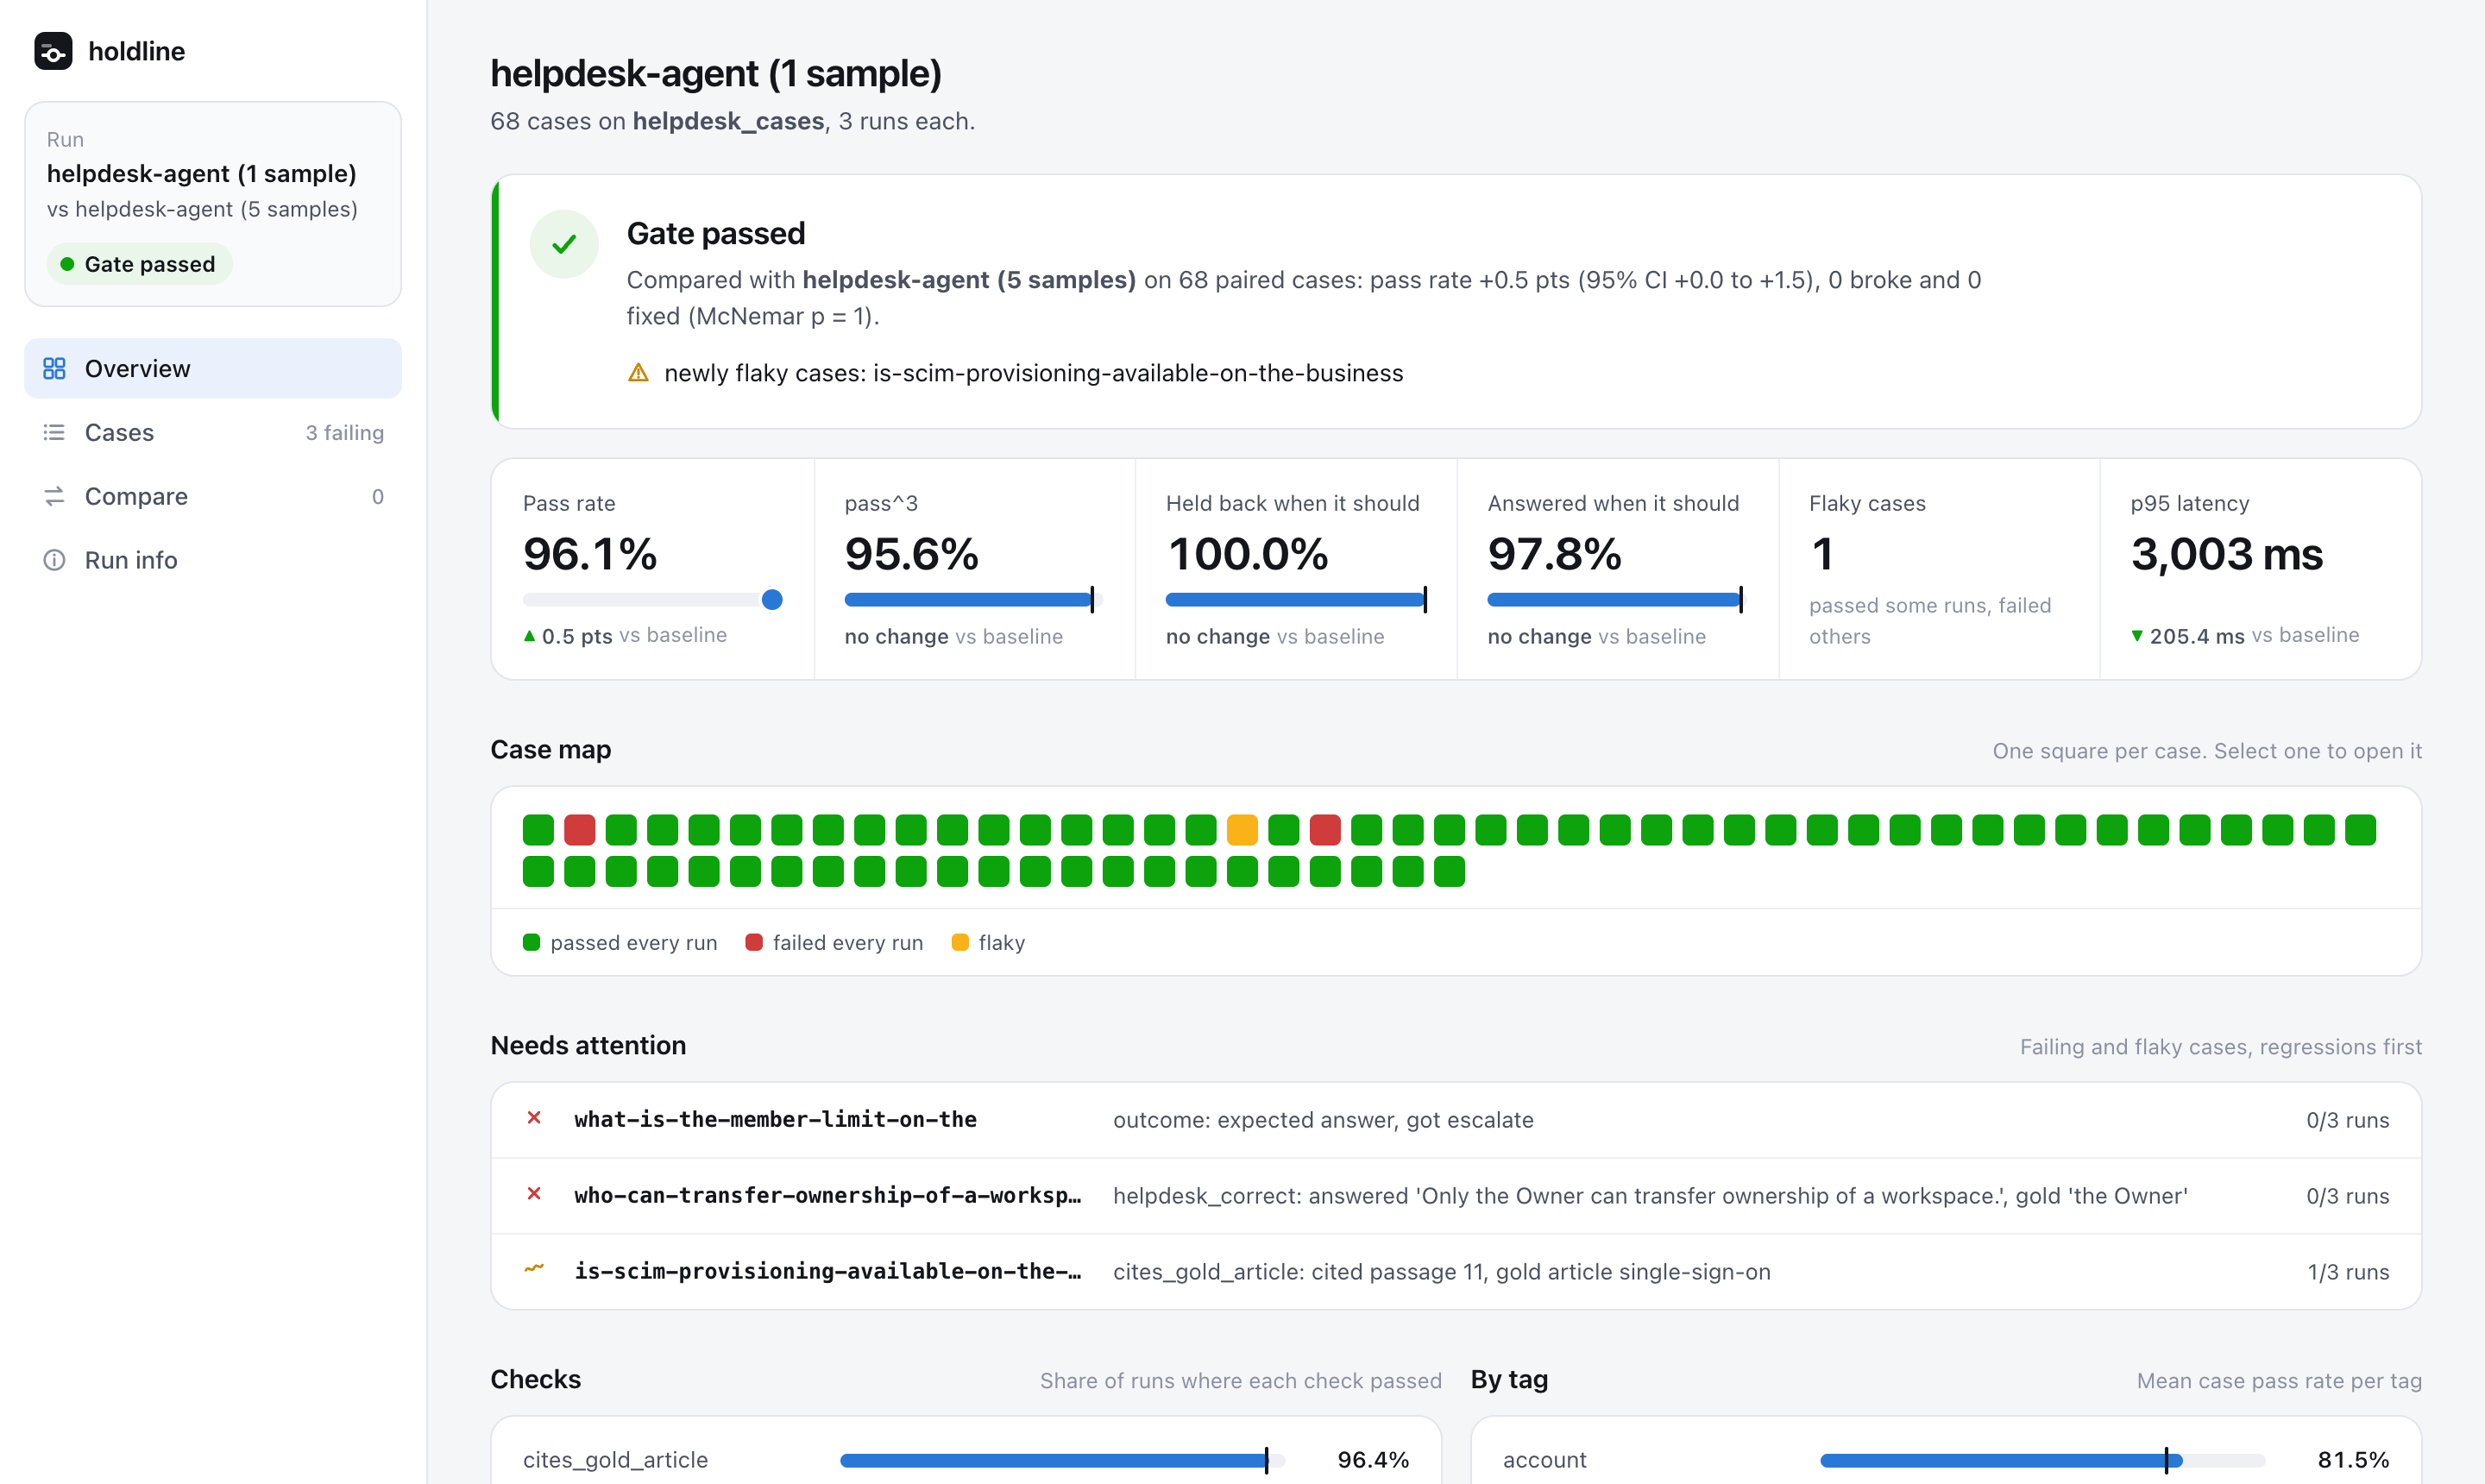
Website and live reports · a real report from the helpdesk-agent run below
Why
Agent changes get shipped on vibes. A prompt tweak looks better on five examples, merges, and quietly breaks the cases nobody re-ran. The usual fixes each miss something:
- Checking only the final answer misses an agent that got the right answer the wrong way: it skipped the policy check, called a tool it should never call, or looped.
- One run per case hides flakiness. An agent that passes 80% of the time looks perfect on one run and broken on the next.
- An LLM judge nobody measured can be lenient exactly where it matters, and an average agreement number can hide a judge that is lenient on one kind of case and harsh on another.
- "Pass rate went from 82% to 79%" says nothing without knowing whether it is noise.
holdline addresses each of these, and puts the answer in CI.
Quickstart
The repo ships a toy refund agent in two versions: agent_v1 follows the refund policy;
agent_v2 is a "helpful" rewrite that refunds whenever asked.
cd examples
holdline run  --suite refund_cases.jsonl --target refund_agent:agent_v1 -k 3 --out v1.json
holdline run  --suite refund_cases.jsonl --target refund_agent:agent_v2 -k 3 --out v2.json
holdline gate --baseline v1.json --candidate v2.json --html report.html     # exits 1
v2 fails the gate. One case is the interesting one: on an in-window refund v2 still gives the
right answer, but it skipped check_policy. Only a trajectory check catches that.
Instrument your agent
import holdline

@holdline.tool                      # every call is recorded: arguments, result, time, errors
def search(query: str) -> list: ...

def my_agent(question: str) -> dict:
    hits = search(query=question)
    holdline.step("llm", "gpt-x", prompt, reply, tokens=812)     # anything else worth tracing
    return {"outcome": "answer", "answer": "..."}                # or "abstain" / "escalate"
Outside a holdline run both are no-ops, so the instrumentation can stay in production code. Traces export as JSONL or OpenTelemetry (OTLP/JSON, GenAI attribute names).
Write cases
One JSON object per line:
{"id": "refund-damaged", "input": "My phone from A200 arrived cracked, refund please",
 "expected": {"outcome": "escalate", "tools_required": ["check_policy"],
              "tools_forbidden": ["issue_refund"]},
 "tags": ["refunds", "uncovered"], "must_pass": true}
expected key |
Checks |
|---|---|
answer, answer_match |
final answer: contains (default), exact, regex, numeric, f1; a list means any of |
outcome |
answer, abstain or escalate: did it hold back when it should, and only then |
tools_required, tools_forbidden, tool_order |
which tools were called, and in what order |
max_steps, max_tool_calls, no_loops |
budgets, and identical calls repeated |
tool_args |
tool arguments against a JSON Schema (type, required, enum, pattern, ranges...) |
rubric |
graded by your LLM judge |
checks |
your own functions, registered with @holdline.check("name") |
Reliability numbers, not one-off scores
With -k 3 every case runs three times. holdline reports the pass rate with a 95% interval
(bootstrapped over cases, since repeats of one case are correlated), pass^k (the chance all k
runs pass: the number that matters when the agent runs unattended), flaky cases, and how often the
agent held back when it should and answered when it should.
Measure the judge before trusting it
holdline calibrate --labels labels.jsonl --html calibration.html --strict
Each label row has the human verdict, the judge's verdict and optionally a group. holdline
reports Cohen's kappa with an interval, the false-pass rate (judge PASS where a human said
FAIL: the error that lets regressions through), bias, and whether the bias changes sign
across groups. In the bundled synthetic example the overall bias is +0.01, which looks
harmless, while the judge is lenient on short answers and harsh on multi-step ones. A single
threshold cannot fix that, and --strict exits 1.
Gate the pull request
The gate pairs cases by id and asks whether the same cases got worse:
- an exact McNemar test on cases that flipped pass to fail versus fail to pass;
- a paired bootstrap interval on the change in pass rate;
- must-pass cases, a minimum pass rate, a floor on holding back, latency and cost budgets.
Small suites cannot prove a regression statistically (4 cases broken and 0 fixed gives p = 0.125), which is why the practical rules exist alongside the test.
# .github/workflows/agent-evals.yml
- uses: Aashan47/holdline@v0.1.0
  with:
    suite: evals/cases.jsonl
    target: my_agent:run
    baseline: .holdline/baseline.json   # a run saved from main
    repeats: "3"
    max-drop: "0.05"
The job summary gets the Markdown verdict; the HTML report is a single self-contained file (no network requests) you can upload as an artifact.
Dogfood: helpdesk-agent
examples/helpdesk/ runs holdline on
helpdesk-agent, a support agent that answers only
from a help centre and escalates the rest, over its 68 labelled tickets.
| Production (5 answer samples) | Candidate (1 sample) | |
|---|---|---|
| Pass rate (68 tickets x 3 runs) | 95.6% (95% CI 89.7 to 100) | 96.1% (95% CI 91.2 to 100) |
| pass^3 | 95.6% | 95.6% |
| Held back on uncovered tickets | 100% (66 of 66 runs) | 100% |
| Answered covered tickets | 97.8% | 97.8% |
| LLM calls per run | 4.4 | 1.69 |
Run on 2026-10-21 with gemini-2.5-flash, the product's shipped escalation threshold, k = 3.
Gate: PASS. 68 paired tickets, 0 broke, 0 fixed (McNemar p = 1.0); one warning: a case became flaky. So the cheaper setting is not measurably worse on this suite, at 62% fewer model calls. The caveat holdline cannot see: on these tickets escalation is driven by the agent's decide step, so the five-sample agreement signal is never stressed. A suite with borderline tickets is needed before shipping that change.
The three failures in the production run show why trajectory checks and grader checks matter:
- Free-plan member limit: the agent escalated a covered ticket (a real over-refusal).
- SCIM on the Business plan: the right answer, citing the pricing article instead of the single sign-on article. An answer-only eval passes it; the citation check does not.
- Transfer ownership: "Only the Owner can transfer ownership of a workspace." against the gold "the Owner". The agent is right; the token-F1 rule fails it for being wordy. That is a grader error, which is the argument for measuring graders before trusting them.
Raw runs, traces and the gate report are in examples/helpdesk/results/.
How it works
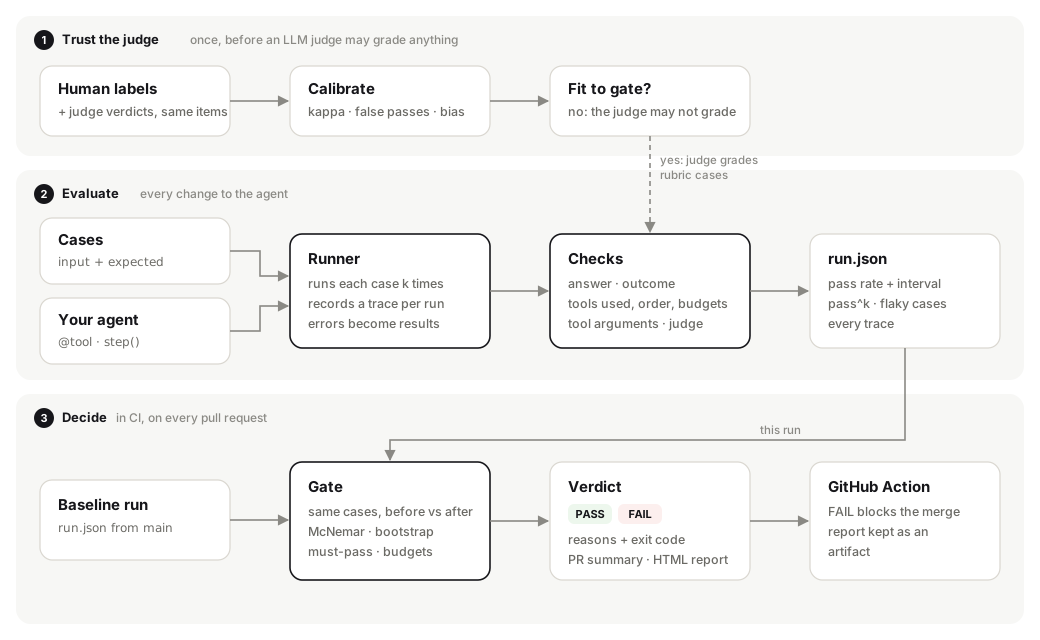
ARCHITECTURE.md explains each part; DECISIONS.md records every design decision and the alternatives considered.
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for holdline 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| holdline-0.1.0.tar.gz | 54.2 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| holdline-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 102.7 kB
Release files / holdline-0.1.0.tar.gz
| Download URL | holdline-0.1.0.tar.gz |
|---|---|
| Size | 54.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
18e6376ae0e896ac081437dd6a0227be26a9a7b955e71e405bdac5a7e7409219
|
|
BLAKE2b-256 checksum How to use checksums |
05290c1e750f1caa06e40db7257aa258208a43462a3d80c65ab249d636ff2ae4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.10
|
Release files / holdline-0.1.0-py3-none-any.whl
| Download URL | holdline-0.1.0-py3-none-any.whl |
|---|---|
| Size | 48.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
17ed0b5810144bc463ff6b02be6630b1f7bbab6e88fdf814417d487166da02e4
|
|
BLAKE2b-256 checksum How to use checksums |
1f03cc406d4ecf4cffd646d4dd9662fe6ab4347864537edf3abce41d10c5fb40
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.10
|
Security for holdline 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














