
Holler
Hold a key. Holler it. It's typed.
Free, offline, push-to-talk dictation for your desktop. Hold a key, speak, release, and your words appear at the cursor in any app. It learns your jargon, understands when you correct yourself mid-sentence, and runs Whisper on your own CPU: no account, no cloud, no subscription.



Contents
- Features
- Quick start
- Requirements and platform support
- Installation
- Using Holler
- Teaching it your words
- Configuration reference
- Command line reference
- Speech models
- Hinglish and Hindi
- Other engines
- Benchmarking on your own voice
- If Hugging Face is unavailable
- How it works
- Privacy and security
- Troubleshooting and FAQ
- Development
- Roadmap
- Contributing, changelog, license
Features
- Works in every app. Text is pasted at your cursor, so it works in editors, browsers, terminals, chat apps and anything else you can type into.
- Private and free. Audio is processed on your machine and never leaves it. There is no account, no usage limit and no telemetry. The only network use is the one-time model download.
- Understands self-corrections. "Meet at 3, no wait, 4 pm" becomes "Meet at 4 pm". "Today is Monday, no no wait, Tuesday" becomes "Today is Tuesday". Fillers such as "um" and "uh" are dropped.
- Learns your words. Add your jargon and names once, or fix a mistake and teach Holler with one chord. "Mach" becomes "Moq" from then on.
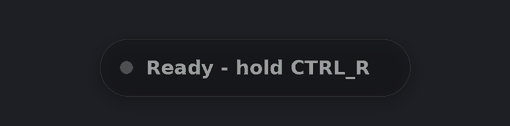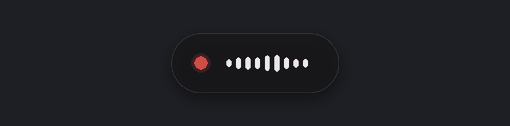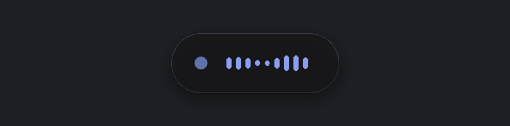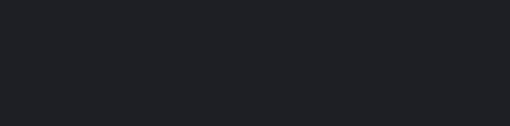
- Stays out of the way. A small always-on-top pill shows a live waveform while you speak and a check mark when the text is in. Idle CPU is near zero, and the model's memory is freed after you stop dictating for a while.
- Resilient model downloads. Downloads resume, fall back to
curl, then to a GitHub mirror, and model weights are checked against known checksums. You can point it at your own mirror or load any compatible Whisper model. - Measure, don't guess.
holler benchscores speech models on your own voice and vocabulary. - Proper install. One
pipcommand, a setup wizard, a settings window, a tray icon and start-on-login.
Quick start
On Windows 10/11 with Python 3.10 or newer (tick "Add python.exe to PATH" in the installer):
py -m pip install holler
py -m holler
The first command installs Holler. The second opens the setup wizard, which checks prerequisites, tests your microphone, lets you pick a hotkey and speech model, downloads the model once, and starts Holler in the background. Then hold Ctrl+Win, speak, and release.
Requirements and platform support
| Platform | Status | Notes |
|---|---|---|
| Windows 10/11 | Supported | Developed and tested here: global hotkeys, the layered status pill, tray icon, paste and start-on-login. |
| Linux (X11) | Experimental | The core (audio pipeline, hotkey logic, Whisper, vocabulary, settings UI) is tested on Linux in CI with a fake keyboard and microphone. Real global hotkeys, paste and the tray have not been verified on a Linux desktop. Details below. |
| Linux (Wayland) | Not supported | Global key capture generally doesn't work under Wayland. Use an X11 session. |
| macOS | Not supported | Untested. Needs Accessibility and Input Monitoring permissions, and the code paths have not been exercised. |
Everywhere: Python 3.10 or newer, a microphone, about 1 GB of free disk for models, and roughly 300 MB of RAM while the default model is loaded (it is freed when idle).
Linux extras: install system packages first, for example on Debian or Ubuntu:
sudo apt install python3-tk libportaudio2 xclip
python3-tk is for the setup and settings windows, libportaudio2 for microphone access and xclip (or xsel) for the clipboard. On Linux the "Win" key is the Super key, which many desktops already use, so choose another chord in Settings (for example ctrl+shift+space or f9) and use the ctrl+shift+v paste mode for terminals. The pill is drawn as a simple always-on-top window instead of the Windows layered pill, and the tray icon needs your desktop's AppIndicator support.
If you try Holler on Linux, please open an issue with what worked and what didn't.
Installation
From PyPI (recommended)
py -m pip install holler
py -m holler
On Linux use python3 -m pip install holler (preferably inside a virtual environment or with pipx) and python3 -m holler.
py -m holler is the one command to remember:
- first time: opens the setup wizard;
- Holler running: opens Settings;
- otherwise: starts Holler in the background (you can close the terminal).
You can also click the tray icon, or use the Holler entry in the Start menu. If holler is on your PATH you can type that instead; py -m holler always works, even when Python's Scripts folder isn't on PATH.
From source
git clone https://github.com/MayankPunghal/holler
cd holler
py -m pip install .
py -m holler
Mind the dot after install: it means "this folder". If you see "You must give at least one requirement to install", the dot is missing.
Optional extras
py -m pip install "holler[parakeet]" # NVIDIA Parakeet engine (see "Other engines")
Update and uninstall
py -m pip install --upgrade holler
py -m holler stop
py -m pip uninstall holler
Your settings, vocabulary, history and downloaded models live in the data folder (%APPDATA%\Holler on Windows, ~/.config/holler on Linux; holler where prints it). Updating or uninstalling never touches it; delete the folder to remove everything.
Using Holler
| You do | What happens |
|---|---|
| Hold Ctrl+Win for about a third of a second, speak, release | The text is pasted at your cursor |
| Quick tap, or a shortcut such as Ctrl+C or Ctrl+Win+Left | Nothing (that's what the hold delay is for) |
| Press Esc while holding | Cancels the recording |
| Fix a mistake by hand, then hold Ctrl+Shift+Win for a moment | Holler learns the correction |
| Click the tray icon | Settings, pause, quit |
The status pill appears while you speak: a live waveform when listening, then "transcribing", and a check mark when the text is in. It also reports a muted or missing microphone instead of silently doing nothing.
What cleanup does (switch off with cleanup: false):
| You say | You get |
|---|---|
| "um so basically uh we should ship it" | "so basically we should ship it" |
| "Meet at 3, no wait, 4 pm" | "Meet at 4 pm" |
| "Today is Monday, no no wait, Tuesday" | "Today is Tuesday" |
"the mach library" (with the replacement mach => Moq) |
"the Moq library" |
Hotkeys. Any key or chord works: f9, scroll_lock, ctrl+win, ctrl+shift+win. The default ctrl+win uses only modifier keys, so holding it never types a character in any app. Use holler keys to see how a key is named. Chords of left-side keys are the safest on laptops, which often lack a Right Ctrl or hide keys behind Fn.
Teaching it your words
Whisper itself doesn't learn, so Holler learns the words around it, three ways:
- Vocabulary tab. Add jargon and names (
xUnit,Kubernetes,Priya) and "wrong → right" corrections. Your vocabulary is also passed to Whisper as hotwords, which biases decoding toward your terms. - Correct, then hold Ctrl+Shift+Win. Dictate, fix the wrong word in that line, leave the cursor on it, and hold the three keys for a moment. They are all modifiers, so nothing is ever typed. Holler compares what it pasted with your fix and remembers it.
- History tab. Pick a past dictation, fix the text and click Learn.
A fix that includes a neighbouring word ("null difference" → "null reference") is learned immediately. A fix to a single ordinary word is learned after you correct it twice, so one odd correction can't break a normal word everywhere.
Moving from an older install? holler import FOLDER merges its keywords.txt and replacements.txt into your current vocabulary.
Configuration reference
Most settings are in the Settings window (open it with py -m holler). Everything lives in config.json in the data folder. Command-line flags on holler run override it for one session.
| Key | Default | Meaning |
|---|---|---|
key |
ctrl+win |
Key or chord to hold while speaking |
hold_ms |
350 |
Hold time before recording starts (0 = instantly) |
teach_key |
ctrl+shift+win |
Chord that learns from the correction on the current line |
engine |
whisper |
Speech engine: whisper, or parakeet (optional extra) |
model |
small.en |
Model name, Hugging Face repo id, or a local folder (see Speech models) |
beam |
2 |
Whisper beam size (higher is slower, slightly more accurate) |
lang |
auto | Language code such as en or hi (English-only models ignore it) |
initial_prompt |
empty | Whisper style hint, used for Hinglish (see Hinglish and Hindi) |
device |
system default | Microphone name |
paste |
ctrl+v |
ctrl+v, ctrl+shift+v (Linux terminals) or type (keystroke by keystroke, for apps that block paste) |
enter |
false |
Press Enter after each dictation |
trailing_space |
true |
Add a space after each dictation |
cleanup |
true |
Remove fillers and resolve spoken self-corrections |
log |
true |
Keep a local history of dictations (the History tab needs it) |
overlay / ui |
true / auto |
Show the status pill; ui is auto, pill or classic |
sound |
true |
Start and stop beeps (Windows) |
unload_after |
10 |
Idle minutes before the model's memory is freed (0 = keep loaded) |
extra_keywords |
empty | Comma-separated terms on top of your vocabulary |
model_url |
empty | Your own model mirror (see mirrors) |
mirror_dir |
empty | Also copy every downloaded model to this folder (for maintainers re-hosting models) |
Environment variables: HOLLER_HOME (data folder), HOLLER_MODEL_URL, HOLLER_MIRROR_DIR, HOLLER_SKIP_VERIFY=1 (skip model checksum checks).
Command line reference
| Command | What it does |
|---|---|
holler |
Setup wizard on first run; Settings if running; otherwise starts in the background |
holler run |
Run in this terminal until you close it (what start-on-login uses). Flags: --key, --hold-ms, --teach-key, --engine, --model, --beam, --lang, --paste, --device, --no-overlay, --no-tray, --no-sound, --download-only |
holler setup [--text] |
Setup wizard (--text for a terminal-only version) |
holler settings |
Settings window |
holler start / stop / restart / status |
Control the background instance |
holler autostart on|off|status |
Start with the computer |
holler doctor [--pill] |
Check prerequisites, microphone, model and hotkey, with fixes (--pill plays the pill through its states) |
holler keys |
Print the name of each key you press |
holler where |
Print the data folder |
holler import FOLDER |
Merge vocabulary from an older install |
holler export-model FOLDER [--model NAME | --all] |
Copy downloaded models out, named for re-hosting |
holler bench record|run |
Compare models on your own voice (see below) |
holler --version |
Show the version |
Speech models
Models download once into the data folder. The default balances accuracy, speed and memory.
| Model | Download | RAM | Notes |
|---|---|---|---|
tiny.en |
75 MB | ~120 MB | Fastest, noticeably less accurate |
base.en |
145 MB | ~170 MB | Light and quick; fine for clear speech |
small.en |
484 MB | ~320 MB | Default: accurate on accents and jargon |
medium.en |
1.5 GB | ~1.3 GB | Most accurate English; needs a fast PC |
tiny, base, small, medium |
as above | as above | Multilingual (Hindi, Hinglish, 90+ languages) |
distil-small.en, large-v3-turbo |
330 MB, 1.6 GB | ~250 MB, ~1.7 GB | Experimental |
Using your own model
Holler runs faster-whisper, so it accepts any Whisper model converted to CTranslate2 format: distilled models, fine-tunes for an accent or language, or one you converted yourself. In Settings > Speech model (an editable box) or model in config.json, enter either:
- a Hugging Face repo id such as
Systran/faster-distil-whisper-large-v3, which downloads into the models folder like the built-in ones, or - a folder on your PC containing
config.json,model.bin,tokenizer.jsonandvocabulary.txt(orvocabulary.json).
Names containing .en or ending in -en are treated as English-only.
Hinglish and Hindi
Use a multilingual model (small, medium; the .en models are English only). Whisper decides how to write Hindi words: left on automatic it may output Devanagari or force Hindi words into odd English spellings. Two settings steer it:
lang:en,hi, or empty for automatic.initial_prompt: a short Roman-script sample such asHaan bhai, main kal office aaunga. Meeting ke baad call kar lena, theek hai?It nudges Whisper to write Hindi in English letters.
Which combination works best depends on your voice, so measure it:
py -m holler bench record --set hinglish
py -m holler bench run --set hinglish --models small,small@en+hing,small@hi,medium@en+hing
(@en and @hi set the language; +hing adds the built-in Roman-Hinglish prompt.) Hinglish spelling varies a lot (nahi against nahin), so compare models against each other rather than reading the percentage as an absolute score. India-focused fine-tunes such as Oriserve's Hindi2Hinglish exist, but they are large and not in the CTranslate2 format Holler loads, so they need converting first.
Other engines (optional)
Whisper is built in. NVIDIA's Parakeet TDT is available as an extra:
py -m pip install "holler[parakeet]"
Then pick parakeet under Settings > Speech engine. It is fast on CPU and does not invent text during silence, but it can't take hotwords, so rely on your replacement rules. In the author's own benchmark it was less accurate than small.en on jargon-heavy, Indian-accented English, so run holler bench before switching. Engines are plugins (holler.engines), so adding another is a small class.
Benchmarking on your own voice
Leaderboards don't know your accent or your jargon. Measure instead:
py -m holler bench record                       # read 24 sentences aloud (once; resumable)
py -m holler bench run --models small.en,base.en,small
py -m holler bench run --models small.en,parakeet:nemo-parakeet-tdt-0.6b-v3
It prints word error rate, speed and load time per model and shows the clips each one got wrong. Your vocabulary is included by default (--no-hotwords switches it off; --raw skips replacements and cleanup). How a number is written (404 or "four hundred and four") is not counted as an error. You can add your own sentences as NN.wav plus NN.txt in the bench folder.
Example: one Indian-English speaker, 24 jargon-heavy sentences, CPU laptop. A small sample, so treat differences of a point or two as noise.
| Model | Word error rate | Speed |
|---|---|---|
small.en (default) |
4.9% | 2.5x faster than speaking |
base.en |
5.5% | 7.8x |
| Parakeet TDT 0.6B v3 | 7.9% | 5.6x |
If Hugging Face is unavailable
Holler downloads a model once; after that it runs fully offline. If the download source ever disappears, these fallbacks apply, in order:
- Your own mirror. Set
model_url(orHOLLER_MODEL_URL) to any server hosting<name>/<file>, for examplehttps://my.host/modelsserveshttps://my.host/models/small.en/model.bin. A template with{name}and{file}also works. - Hugging Face.
- The project mirror on this repo's
modelsrelease, with files named<model>-<file>. - Manual install. Put
config.json,model.bin,tokenizer.jsonandvocabulary.txt(or.json) in the model's folder, such as%APPDATA%\Holler\models\small.en\.
Weights of small.en, base.en and small are checked against pinned SHA-256 checksums. A mirror serving different bytes is skipped; Hugging Face itself is trusted, so upstream updates still work. Maintainers can re-host models with holler export-model FOLDER --all or mirror_dir.
How it works
 key chord ──▶ hotkey state machine ──▶ recorder ──▶ speech engine ──▶ cleanup ──▶ paste
 (hold 350 ms)  (taps and shortcuts     (always-open   (Whisper, int8,   (fillers,   (clipboard
                 are ignored)             mic, pre-roll) VAD, hotwords)    self-fix,    + Ctrl+V,
                                                                          vocabulary)  then restore)
| Technique | Why |
|---|---|
faster-whisper, int8, CPU, beam 2 |
Much faster than reference Whisper at nearly the same accuracy |
| Silero VAD | Cuts silence, the main source of hallucinated text ("Thank you.") |
| Temperature 0, no previous-text conditioning | No random fallbacks or repetition loops |
hotwords from your vocabulary |
Biases decoding toward your terms |
| Always-open mic, pre-roll and a short tail | First and last words aren't clipped; no start-up lag |
| Gain normalisation, silence detection | Quiet mics still work; a muted mic is reported, not guessed |
| Rule-based post-processing | Casing, replacements, fillers and self-corrections cost microseconds; no LLM needed |
| Idle unload | The model's memory is freed after unload_after minutes and reloaded while you speak |
Privacy and security
- Audio is processed locally and discarded after transcription. It is never saved or sent anywhere.
- Holler makes no network requests except downloading a model (Hugging Face, the GitHub mirror, or a URL you configure). No telemetry, no accounts.
- A local history of your dictations is kept in
dictation_log.tsvin the data folder so the History tab and learning work. Setlog: falseto stop it, or delete the file. - To type for you, Holler needs a global keyboard hook, which some antivirus tools flag. It only watches for your chord, and the source is in this repository.
- Dictating into an app running as Administrator requires Holler to run as Administrator too (a Windows rule for all keyboard tools).
Report vulnerabilities as described in SECURITY.md.
Troubleshooting and FAQ
Run holler doctor first. It checks every prerequisite, tests the microphone and tells you how to fix what's wrong. Problems are also logged to errors.log in the data folder.
pip installsays "You must give at least one requirement". You left off the dot inpy -m pip install ., or the name inpy -m pip install holler.holleris not recognised. Usepy -m holler.- The hotkey doesn't work in some app. Choose a different chord in Settings. If the app runs as Administrator, run Holler as Administrator too.
- A letter is typed when I use a chord. Your layout treats that combination as a character (Ctrl+Alt is AltGr on many layouts). Use a modifier-only chord such as
ctrl+shift+win. - Nothing is pasted. Try
paste: "type"for apps that block paste, orctrl+shift+vfor Linux terminals. - The pill doesn't show over some app. Known issue: windows that pin themselves to the top (such as Claude Desktop on some setups) can hide it. Dictation still works.
- The model download fails. Holler retries with
curl, then the project mirror. See If Hugging Face is unavailable. - It recorded silence or nothing. The pill says so. Check the microphone in Settings and Windows' privacy settings for microphone access.
- Is it as good as paid dictation tools? Accuracy depends on your voice and vocabulary, which is why
holler benchexists. For many people it is good enough, with the benefit of being offline and free. - Does it use my GPU? Not yet; it is built to be light on CPU.
Development
git clone https://github.com/MayankPunghal/holler
cd holler
py -m pip install -e .
Run the tests (they use a fake keyboard, microphone and Whisper, so they need no audio hardware):
$env:PYTHONPATH="src"
python tests/test_cleanup.py; python tests/test_vocab.py; python tests/test_app.py; python tests/test_models.py; python tests/test_bench.py
CI runs them on Linux and Windows. Project layout:
src/holler/
  cli.py          command line and entry points      app.py       hotkey state machine and pipeline
  keys.py         chords and key names               audio.py     microphone capture
  engines/        speech engines (whisper, parakeet) models.py    catalogue, downloads, mirrors, checksums
  cleanup.py      fillers and self-corrections       vocab.py     vocabulary, replacements, learning
  output.py       paste and clipboard                overlay.py   the status pill
  bench.py        holler bench                       doctor.py    holler doctor
  process.py      background run, autostart          tray.py      tray icon
  config.py       settings                           ui/          setup wizard and settings window
tests/            unit and pipeline tests            docs/        images
Regenerate the pill images with python -m holler.overlay --preview docs.
Releasing (maintainers): update CHANGELOG.md and the version in pyproject.toml and src/holler/__init__.py, then publish a GitHub release tagged vX.Y.Z. The publish workflow builds and uploads to PyPI using trusted publishing.
Roadmap
- Polish for Linux and the "pill over always-on-top windows" issue
- Hinglish mode as a one-click setting, once measured on real voices
- More optional engines (Moonshine, Qwen3-ASR) if
holler benchshows they help - Streaming partial text, GPU support, a Windows installer
Contributing, changelog, license
Issues and pull requests are welcome; see CONTRIBUTING.md. Release notes are in CHANGELOG.md. If Holler saves you time, a star helps others find it.
Built on faster-whisper and OpenAI Whisper (both MIT), with pynput, sounddevice, Pillow, pystray and pyperclip. Licensed under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for holler 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| holler-1.0.0.tar.gz | 83.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| holler-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 158.8 kB
Release files / holler-1.0.0.tar.gz
| Download URL | holler-1.0.0.tar.gz |
|---|---|
| Size | 83.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b822b2ca01f3371adffe8c1f12dc2ca6bb5b6e7b0fbecf3d0fe5a019b3679b0e
|
|
BLAKE2b-256 checksum How to use checksums |
cd9fcef44e08535be3b931242ea41337e98d6ecf5048de16b7c5b3c657fcfbd3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logRelease files / holler-1.0.0-py3-none-any.whl
| Download URL | holler-1.0.0-py3-none-any.whl |
|---|---|
| Size | 75.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
442bfba09e89b1c5b60af093955aab09da6297f81d07c592c66496b7fe88f922
|
|
BLAKE2b-256 checksum How to use checksums |
8dd6f0d26c07899e9c7992e7a0b83d1fe0822516a247ba4f381df128fe524bcd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency log












