
hugpy-media
The media arm of Hugpy (import name hugpy_media). The source tree is at
0.3.4; the installed deb and running service on this host are 0.3.3.
The package does two jobs:
- It is a self-contained arm: the
/mediamedia-intelligence console (a chat-first SPA) and its toolset API (/api/media/*), served by its own service on127.0.0.1:7340. Hugpy Core proxies both. - It provides engine task plugins: runners and request builders for speech
recognition, TTS, embeddings and similarity, keywords, summaries, vision
chat, vision analysis (depth, detection, classification, segmentation), image
generation, ComfyUI, and document/URL extraction. They register with
hugpy_engine.tasks.
The arm contract every arm follows (toolset → Blueprint → standalone server →
arms.d → core proxy) is documented in docs/arms.md. How
the model routes pick and fall back between models is in
docs/execute_prompt.md.
Layout
The package follows the shared imports/ convention. Cross-cutting primitives
live in one cheap layer that never imports a model stack. The model stacks are
cohesive subpackages imported lazily.
src/hugpy_media/
  imports/            shared primitives; importing this pulls in no model stack
    constants.py      ARM_NAME="media", UI_MOUNT="/media/", ML_TASKS (route -> task),
                      env-var NAMES, standalone host/port/env-file, LLM upstream default
    functions.py      have() (find_spec probe), lazy()/first_lazy(), dist_version(), env_str()
    classes.py        MediaError (hosts turn it into {"error": ...})
    init_imports.py   explicit stdlib + shared re-exports, C = constants
  toolset.py          get_toolset() -> {"media": {route: callable}}, get_manifest()
  routes.py           media_bp = register_categories(get_bp("media"), get_toolset())
  serve/__init__.py   standalone server: `hugpy-media serve`
  ui.py               dist_dir() -> the wheel's built SPA (ui_dist/)
  ui_dist/            built @hugpy/media-intelligence-ui (see ui_dist/PROVENANCE.md)
  api.py              back-compat shim: media_bp, ML_TASKS, normalize_ml_kwargs
  plugin.py           register(): the hugpy_engine.tasks entry point (LazyRunner proxies)
  plugin_builders.py  pydantic request builders per task
  extract.py          deterministic document/URL text ingest (path-jailed, SSRF-guarded)
  hooks.py            fleet-worker process/telemetry hooks
  model_battery.py    battery recorder
  comfy/ embed/ imagegen/ keywords/ pdfs/ schemas/ seo/ summarizers/
  text/ tts/ vision/ vision_analysis/ whisper_model/        the model stacks
  chunking.py         shim -> text/chunking.py
Modules import shared pieces through the layer:
from hugpy_media.imports import constants as C, functions as F, MediaError.
tests/test_import_policy.py forbids wildcard imports, so init_imports
re-exports explicitly.
The toolset (media/*, 18 routes)
Every route is GET+POST at /api/media/<route>, with a trailing-slash
variant. Request data (JSON body, else form, else query string) is pruned to
the callable's parameters. The return value comes back as {"result": ...},
and an exception as 500 {"error": "<message>"}. Append ?help to any route
for its parameters. Source: toolset.get_toolset(), verified against the live
GET /api/media/manifest.
| Route | Parameters | What it does | Backend |
|---|---|---|---|
health |
none | {"ok": true, "arm": "media", "version": ...} |
local |
capabilities |
none | per-amenity {task, ready, extra} from a find_spec probe of local extras; also pool |
local |
manifest |
include_optional |
get_manifest(): arm, version, ui, per-route target/description/inputSchema |
local |
upload |
multipart file (+ form fields) |
saves under UPLOADS_HOME (default $DEFAULT_ROOT/uploads) and returns {path, name, size} |
local |
extract |
path | file | image_path |
text from PDF (pdfplumber/PyPDF2), DOCX/XLSX (extract extra) or text files. The path must be under UPLOADS_HOME or DEFAULT_ROOT. |
local |
fetch |
url |
LLM-ready assessment of a public URL. Internal and loopback addresses are refused. Uses abstract_webtools when installed, else requests + bs4. |
local plus outbound HTTP |
analyze |
path/file/url, kind, prompt, model |
one DocumentIntelligence record: extract (fetch for a URL, transcribe for audio/video, vision for images, extract otherwise), then best-effort summarize and keywords. A missing backend records a skipped or error stage instead of failing. |
composite |
transcribe |
path, model |
automatic-speech-recognition |
engine → core /v1/audio/transcriptions |
summarize |
text, model |
text-summarization |
engine → core /v1/summarize |
keywords |
text, model |
keyword-extraction |
engine → core /v1/keywords |
embed |
text, model |
feature-extraction |
engine → core /v1/embeddings |
similarity |
text, model |
sentence-similarity |
engine → core /v1/embeddings |
imagine |
prompt, model |
text-to-image |
engine → core /v1/images/generations |
vision |
image_path | image_b64, prompt, model |
image-text-to-text |
GGUF vision models: engine → core /v1/chat/completions. A transformers row runs in-process (vision + transformers extras). |
depth / detect / classify / segment |
image_path | image_b64, model |
depth, object detection, classification, segmentation | in-process vision_analysis runners (transformers extra) |
The model routes call hugpy_engine.execute_prompt with the task fixed by the
route. Any task the client sends is ignored. model becomes model_key, and
for vision image_b64 becomes images=[...]. The reserved worker pool
HUGPY_ML_POOL is applied unless the task is listed in
HUGPY_ML_GENERAL_ROUTE_TASKS (default image-text-to-text). The result is
model_dump()ed, so it includes ok and the engine's resolution metadata
(task, source, model_key, attempts).
Standalone vs needs core/GPU
- Works with nothing else running:
health,capabilities,manifest,upload,extract,fetch.analyzeworks too for documents and URLs, with its enrich stages recorded as errors when no model answers. - Needs a reachable core (
HUGPY_CORE_URL, defaulthttp://127.0.0.1:7020) and a fleet worker that serves the task:transcribe,summarize,keywords,embed,similarity,imagine, andvisionfor GGUF vision models. The GPU work happens on the worker. The media box needs no torch or whisper for these. - Needs local extras in this venv:
depth,detect,classify,segmentand transformers-frameworkvision. The deb's venv ships none of those extras, so on this host these routes return an{"error": ...}. capabilitiesreports local extras only. A route shownready: falsecan still answer through core when the fleet serves its task.
Chat narration (/v1)
The SPA's chat narration does not use the toolset. It calls the
OpenAI-compatible surface at the origin root: POST /v1/chat/completions
(streamed over SSE) and GET /v1/models.
- Behind core (
http://<core>/media/),/v1/*is core's own surface. - Standalone, the server forwards
/v1/*(streamed) to an upstream. With no reachable upstream it answers503 {"error": {"code": "no_model_backend", ...}}.- 0.3.4 (source): the upstream is
HUGPY_MEDIA_LLM_URL, elseHUGPY_CORE_URL, elsehttp://127.0.0.1:7020, core's loopback relay. Core serves/v1/chat/completionsand/v1/modelsthere. - 0.3.3 (installed here): the upstream is
HUGPY_MEDIA_LLM_URL, defaulthttp://127.0.0.1:52017, the retired local wrapper port. Nothing listens on 52017 on this host, so a standalone/v1/modelson:7340returns that 503, while the same call through core succeeds. SetHUGPY_MEDIA_LLM_URL=http://127.0.0.1:7020in/etc/hugpy/media.env, or upgrade to 0.3.4.
- 0.3.4 (source): the upstream is
Standalone server and CLI
hugpy-media                     # same as `hugpy-media serve`
hugpy-media serve [--host H] [--port P] [--env-file /etc/hugpy/media.env]
serve loads the env file without overriding the environment. It then builds
abstract_flask.get_Flask_app(name="hugpy-media", routes=hugpy_media.routes, url_prefix="api") and adds:
- the SPA at
/media/with history fallback (/→302 /media/). A build withoutui_distanswers500with the reason. - the
/v1/*forwarder.
It then runs Flask's threaded server. get_Flask_app also adds
/api/endpoints, /endpoints and /prefixes, and writes its audit log
hugpy-media.log to the working directory.
curl -s 127.0.0.1:7340/api/media/health
curl -s -X POST -H 'Content-Type: application/json' -d '{"url":"https://example.com"}' 127.0.0.1:7340/api/media/fetch
curl -s -F file=@notes.pdf 127.0.0.1:7340/api/media/upload      # -> {"result": {"path": ...}}
curl -s '127.0.0.1:7340/api/media/vision?help'
Environment
| Variable | Default | Effect |
|---|---|---|
HUGPY_MEDIA_HOST / HUGPY_MEDIA_PORT |
127.0.0.1 / 7340 |
bind address of serve |
HUGPY_MEDIA_ALLOWED_ORIGINS |
unset (CORS allows all origins) | comma-separated CORS origins |
HUGPY_MEDIA_LLM_URL |
unset → HUGPY_CORE_URL → http://127.0.0.1:7020 (0.3.4); http://127.0.0.1:52017 in 0.3.3 |
upstream for the standalone /v1/* forwarder |
HUGPY_ML_POOL |
unset | reserved worker pool for the model amenities |
HUGPY_ML_GENERAL_ROUTE_TASKS |
image-text-to-text |
tasks that skip the reserved pool |
DEFAULT_ROOT |
from hugpy_platform (the deb sets /var/lib/hugpy-media) |
storage root: uploads, and the extract jail |
HUGPY_CORE_URL |
http://127.0.0.1:7020 |
engine: catalog, bindings and relays (see execute_prompt.md); in 0.3.4, also the /v1 fallback upstream |
The file /etc/hugpy/media.env (KEY=VALUE) is optional. The deb does not
create it, and the unit reads it through EnvironmentFile=-.
Debian package
BUILD_PYTHON=/usr/bin/python3 packaging/debian/build.sh     # -> build/debian/hugpy-media_<ver>_amd64.deb (Python 3.12)
sudo apt install ./build/debian/hugpy-media_<ver>_amd64.deb      # 0.3.3 is the newest deb built so far
build.sh bundles offline wheels for hugpy-media and its private siblings
(hugpy-platform and hugpy-engine, built from the local source tree) and
their public dependencies. Since 0.3.4, hugpy-storage is no longer bundled.
The 0.3.3 deb bundled it as a base dependency. It then asserts that the wheel contains
ui_dist/index.html and that the abstract_flask wheel is in the bundle.
postinst:
- creates the
hugpy-mediasystem user and/var/lib/hugpy-media; - builds
/opt/hugpy-media/venvoffline; - writes
/usr/share/hugpy/arms.d/media.json; - writes and starts
hugpy-media.service, withWorkingDirectory=andDEFAULT_ROOT=set to/var/lib/hugpy-media.
Core then proxies /api/media/* and /media/* to the service. The arm is not
installed into core's venv. postrm removes the unit and the arms.d file. On
purge it also removes the venv, the state, /etc/hugpy/media.env and the user.
For host-level steps see docs/install.md and
docs/operations.md.
Dependencies
Runtime (pyproject.toml, 0.3.4): hugpy-platform>=0.3.0,
hugpy-engine>=0.3.2, flask>=2, abstract_flask, abstract_essentials,
pydantic>=2, requests, beautifulsoup4, PyPDF2, pdfplumber, pillow.
hugpy-storage is not a base dependency since 0.3.4. It moved to the
local extra. The local in-process inference runners (transformers, embed,
keywords, vision, imagegen) resolve weights lazily through
hugpy_storage.download_models.ensure_model, and those runners need the torch
extras anyway. import hugpy_media never imports hugpy_storage, and the arm
deb (fleet mode, where the GPU work happens on workers) does not need it.
Extras (each model stack is imported only inside its runner): audio
(openai-whisper), imagegen, embed, transformers, vision, extract
(python-docx, openpyxl, ...), keywords (keybert), comfy, local
(hugpy-storage), tts (chatterbox-tts; opt-in only, because it conflicts with
the rest), all (every extra except tts, including local), and test.
Entry points
| Group | Name → target |
|---|---|
console_scripts |
hugpy-media → hugpy_media.serve:main |
hugpy.arms |
media → hugpy_media.routes:media_bp |
hugpy.toolsets |
media → hugpy_media.toolset:get_toolset |
hugpy_engine.tasks |
media → hugpy_media.plugin:register |
Engine plugin
hugpy_media.plugin.register() registers these (task, framework) pairs with
hugpy_engine.tasks, using LazyRunner proxies so registration imports no
model stack:
automatic-speech-recognition,text-to-speech,text-summarization,text2text-generation,keyword-extraction,feature-extraction,sentence-similarity,image-text-to-text,text-to-imageandimage-to-imageontransformers;text-to-imageandimage-to-imageoncomfy;document-extractionandurl-extractionon any framework;- the four vision-analysis tasks on
transformers.
Tasks in the engine's TASK_ROUTES table (speech recognition, TTS,
summarization, keywords, embeddings, image generation) are relayed to core,
not run by these plugin runners, in an arm process. The runners serve
in-process callers such as a worker.
UI
The SPA source is ui/media_intelligence_ui.
Its build is copied into src/hugpy_media/ui_dist/, and the provenance is in
ui_dist/PROVENANCE.md.
Downloads and feature gallery
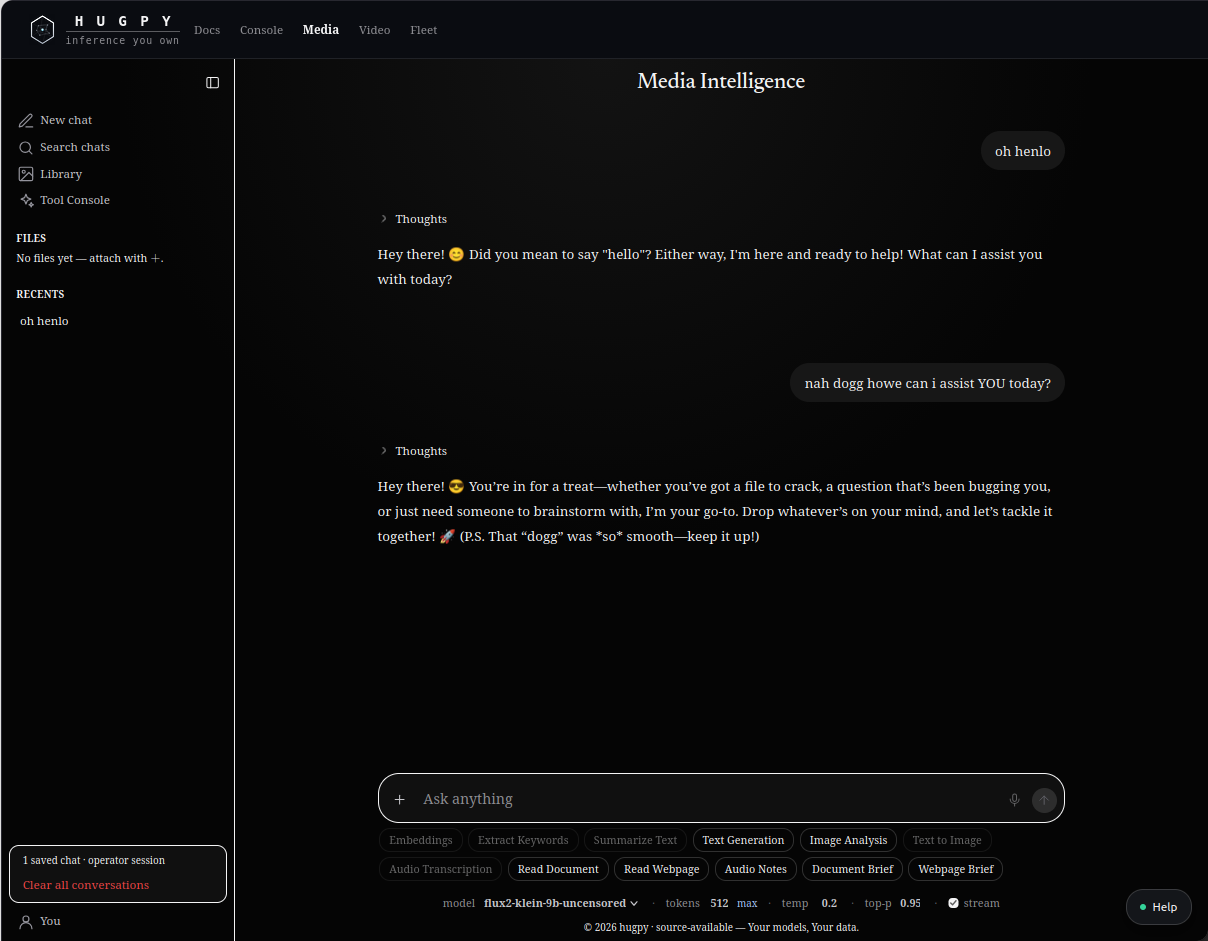
Get the Debian packages, architecture details, SHA-256 checksums and installation commands from Hugpy Downloads. The feature gallery shows the console, Agent, Station, Media and Video interfaces. Screenshots reflect the versions captured; the current interface may differ.
Media workspace
Conversations alongside file, image, audio and document task controls.
1 maintainer

Metadata
1 maintainer
Release files for hugpy-media 0.3.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| hugpy_media-0.3.6.tar.gz | 337.7 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hugpy_media-0.3.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 668.8 kB
Release files / hugpy_media-0.3.6.tar.gz
| Download URL | hugpy_media-0.3.6.tar.gz |
|---|---|
| Size | 337.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
25a76e1967a5ce3ffc2c02152ee8d865df7060c8ae849385143b8f634b36abb1
|
|
BLAKE2b-256 checksum How to use checksums |
401c6325552f440c8ae5591e2366aa184259284c49b339b74aea3c1a59b582e5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / hugpy_media-0.3.6-py3-none-any.whl
| Download URL | hugpy_media-0.3.6-py3-none-any.whl |
|---|---|
| Size | 331.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c73c3d9899b808910086706d5ca10e1130b422d96825f4bba6c136955b7cd02f
|
|
BLAKE2b-256 checksum How to use checksums |
7e34cbf768789d452b425934ebca97047919d083aa306f9187e909cca0596eab
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Security for hugpy-media 0.3.6
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














