
Hybrid Recursive Ladder
Query planning for bucket-limited time-series APIs. Aggregate long ranges with a handful of source requests instead of thousands of per-bucket queries.
Languages: English · 简体中文 · 日本語 · 한국어 · Español · Français · Deutsch · Português · Русский · العربية · हिन्दी
Algorithm spec · API reference · Benchmarks · Related work · Public disclosure · Docs index


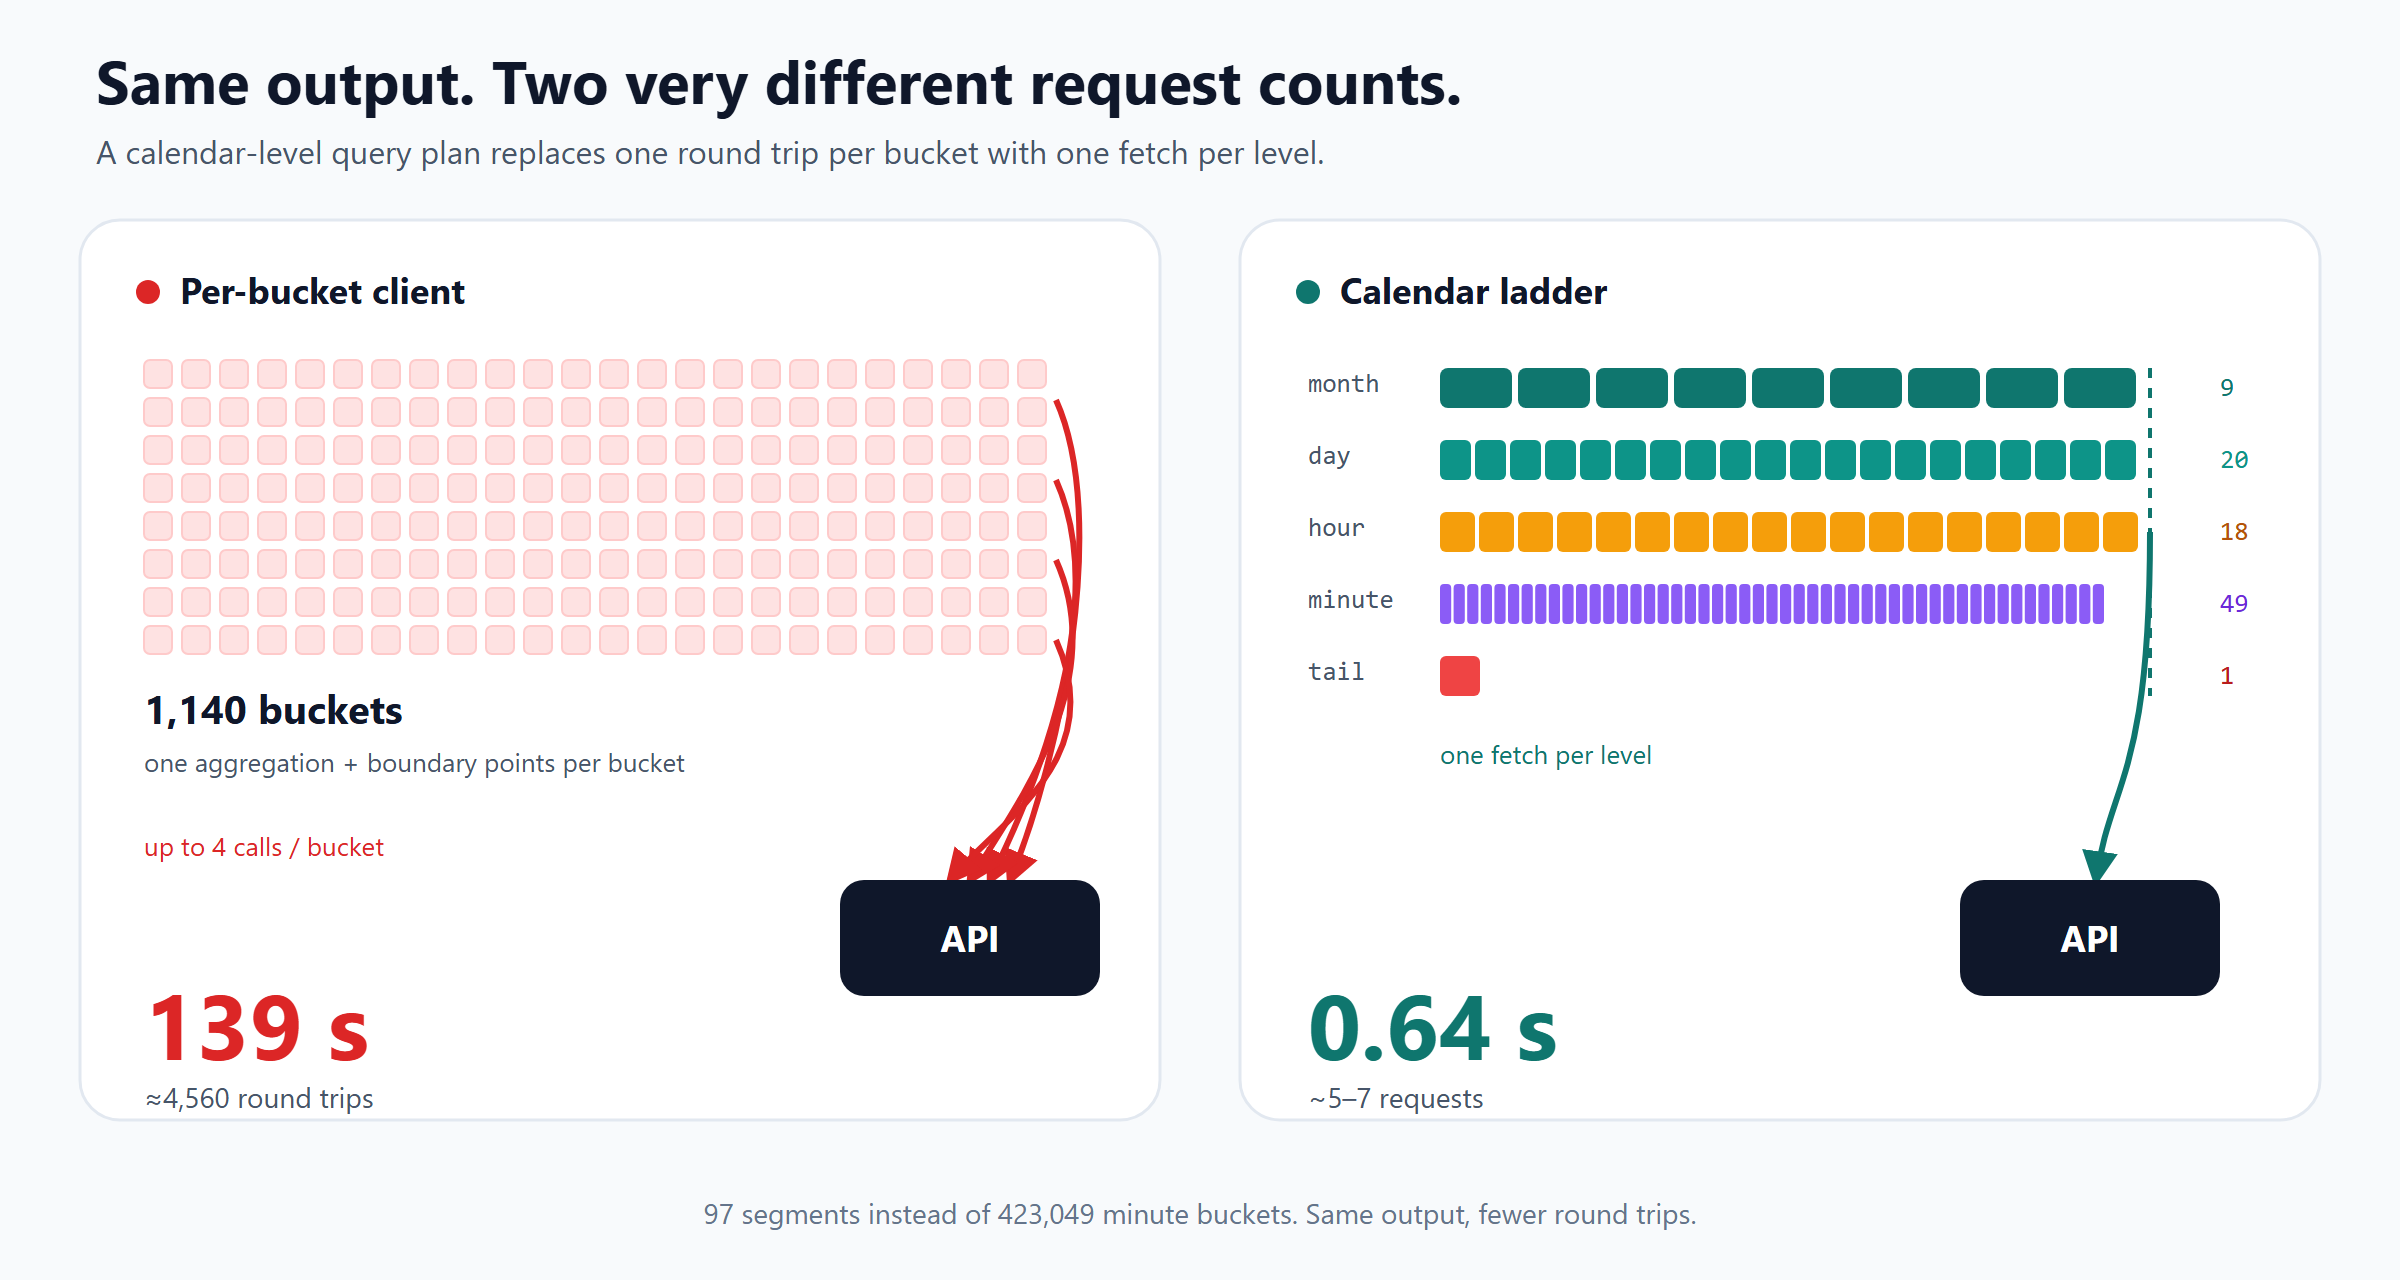
Same output granularity. The per-bucket client pays one round trip per row; the ladder fetches each level once.
Why this exists
Most time-series APIs charge you per request, per bucket, or per round trip. A naive "one query per statistical bucket" client turns a two-day minute-level range into 2,880 buckets, each needing up to four HTTP calls. In a production ThingsBoard deployment, 1,140 buckets took 139 seconds over a VPN.
The bottleneck is not arithmetic. It is the number of network round trips.
Three obvious fixes all sacrifice something:
| Fix | What it costs |
|---|---|
| Ask for one coarse interval | Loses the per-minute or per-day rows the dashboard needs |
| Pre-aggregate (continuous aggregates, rollup tables) | Requires write access to, or control of, the source |
| Paginate | Same number of pages, plus more boundary cases |
The ladder takes a different route: keep the output granularity, but stop fetching one request per output unit. A source that can return an interval aggregate over a contiguous run can fill many output segments in one request.
How it works
- Decompose
[start, end)into complete calendar units, from month down to the configured finest level. Emit only complete units; push the partial left and right edges to the next finer level. - Group adjacent segments only when they need the same fetch level. Hours and minutes can share a minute-level run; months and days cannot.
- Fetch each maximal contiguous run once at the next finer aggregation: months as days, days as hours, hours as minutes, minutes as minutes.
- Fold the returned buckets into the output segments locally.
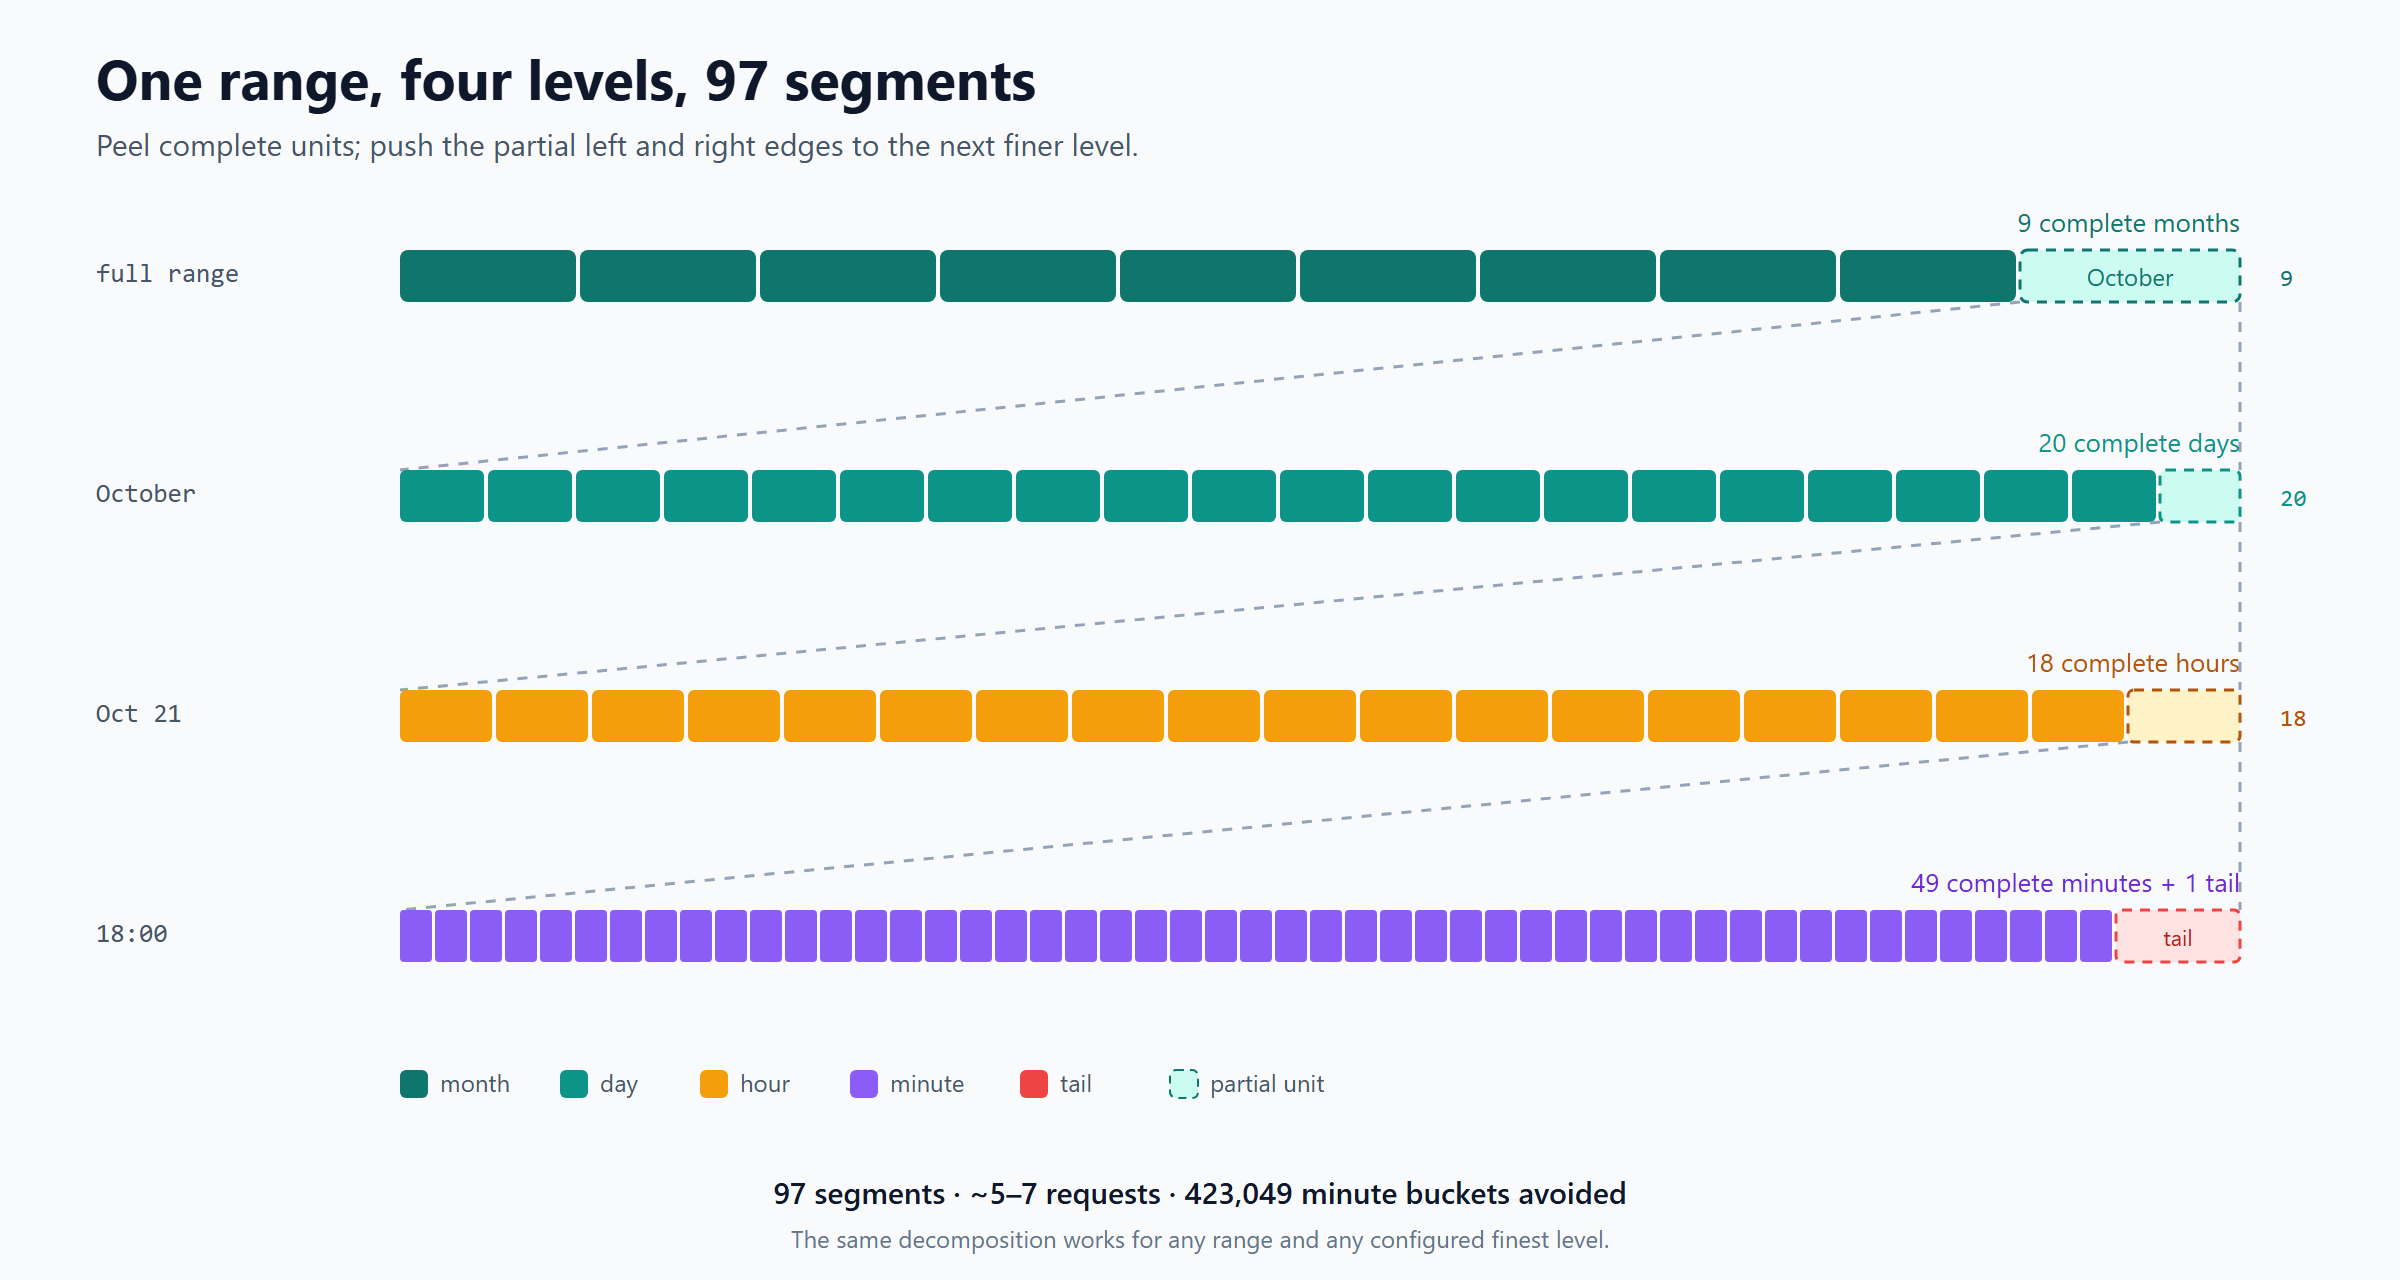
For 2026-01-01 00:00:00 → 2026-10-21 18:49:59, that is 97 segments instead
of 423,049 minute buckets. A typical 10-month query needs roughly 5–7
aggregation requests.
Rules
- Left-closed, right-open —
[start, end). - Complete units only — a month/day/hour/minute is emitted at its level only when it lies entirely inside the range.
- Recursive edges — a partial edge is pushed to the next finer level; a sub-minute remainder becomes its own tail segment.
- Local calendar — boundaries use the configured IANA timezone (default
Asia/Shanghai). - Tiling — segments are ordered, contiguous, non-overlapping, and their
union is exactly
[start, end).
Request bound
For a fetch run of duration T at bucket size Δ, with K buckets per request:
requests(run) = ceil(T / (K * Δ))
Fine-grained work is confined to the two partial units at the edges. For the
default hierarchy, N <= N_month + 639; recursion depth is at most 4. The
request count is O(N_month / K + 1) — it grows with the coarse units, not with
the number of minute buckets. The formal propositions are in
docs/algorithm.md §5.3–5.5 (中文).
Quick start
pip install hybrid-recursive-ladder

hybrid-ladder demo
hybrid-ladder decompose --start 2026-01-01 --end 2026-10-21T18:49:59
The demo builds synthetic 15-minute data, decomposes a 120-day range, materializes half of it, runs a local-first mixed query, and verifies that the totals match. No database, no network, no configuration.
Optional extras:
pip install "hybrid-recursive-ladder[thingsboard]"   # ThingsBoard source (httpx)
pip install "hybrid-recursive-ladder[postgres]"      # local store (psycopg 3)
pip install "hybrid-recursive-ladder[api]"           # FastAPI HTTP API
pip install "hybrid-recursive-ladder[mcp]"           # MCP server
pip install "hybrid-recursive-ladder[all]"           # everything
The core decomposition has zero third-party dependencies (only tzdata for
reliable IANA time zones on Windows).
Usage
| Form | Entry point | Best for |
|---|---|---|
| Python library | from hybrid_ladder import ... |
embedding in a service or pipeline |
| CLI | hybrid-ladder ... |
ad-hoc inspection, scripts, cron |
| HTTP API | hybrid-ladder serve |
language-agnostic integration, async tasks |
| MCP server | hybrid-ladder mcp |
AI agents and MCP-compatible clients |
| Agent skill | skills/hybrid-recursive-ladder/ |
Claude/ZCode-style skill installation |
Python library
from hybrid_ladder import LadderEngine, MemorySource

source = MemorySource()
source.add("device-1", "energy", [(ts, 1.0) for ts in range(0, 86_400_000, 60_000)])

engine = LadderEngine(source)
result = engine.sum([("device-1", "energy")], 0, 86_400_000)

print(result.grand_total)                 # 1440.0
print(result.rows[0].segments[0].label)   # 1970-01-01 00:00
print(result.rows[0].empty_count)         # 0
The engine depends on two small protocols: TimeSeriesSource (interval_agg,
raw_series) and PointStore (sum_ranges, series, coverage,
upsert_points, ...). Built-ins: MemorySource/MemoryStore,
ThingsBoardSource, PostgresStore. See
docs/architecture.md (中文) to add another source.
CLI
# Demo data
hybrid-ladder sum --series demo-chiller-1:energy --start 2026-01-01 --end 2026-02-01

# ThingsBoard, local-first
export HL_TB_URL=https://tb.example.com
export HL_TB_TOKEN=...
export HL_PG_DSN='postgresql://user:pass@127.0.0.1:5432/telemetry'
hybrid-ladder sum --source thingsboard --series <device>:<key> \
  --start 2026-01-01 --end 2026-10-21T18:49:59 \
  --mode mixed --materialize

# Verify and repair the local copy
hybrid-ladder verify --source thingsboard --series <device>:<key> --start ... --end ...
hybrid-ladder repair --source thingsboard --series <device>:<key> --start ... --end ...
HTTP API
hybrid-ladder serve --port 8000
# OpenAPI docs: http://127.0.0.1:8000/docs
curl "http://127.0.0.1:8000/v1/decompose?start_ts=1767196800000&end_ts=1792512599000"

curl -X POST http://127.0.0.1:8000/v1/ladder/sum \
  -H 'content-type: application/json' \
  -d '{"series":[{"entity":"demo-chiller-1","key":"energy"}],
       "start_ts":1767196800000,"end_ts":1777564800000,"mode":"tb"}'
# → {"code":0,"data":{"task_id":"...","async":true}}

curl http://127.0.0.1:8000/v1/tasks/<task_id>
The API uses {"code":0,"data":...} on success and {"code":1,"detail":...} on
error. Every endpoint is in docs/api.md (中文).
MCP server
pip install -e ".[mcp]"
hybrid-ladder mcp
Tools: ladder_meta, ladder_decompose, ladder_sum, ladder_verify. With no
configuration it serves demo data, so an agent can try it immediately. Example
client configuration:
{
  "mcpServers": {
    "hybrid-ladder": {
      "command": "hybrid-ladder",
      "args": ["mcp"],
      "env": {
        "HL_SOURCE": "thingsboard",
        "HL_TB_URL": "https://tb.example.com",
        "HL_TB_TOKEN": "...",
        "HL_PG_DSN": "postgresql://..."
      }
    }
  }
}
Agent skill
Copy skills/hybrid-recursive-ladder/ into
your agent's skills directory (for example ~/.claude/skills/ or
~/.zcode/skills/). The skill teaches the agent when to use the ladder, how to
call the CLI/API, and how to interpret null vs 0.0 and source.
Local-first mode
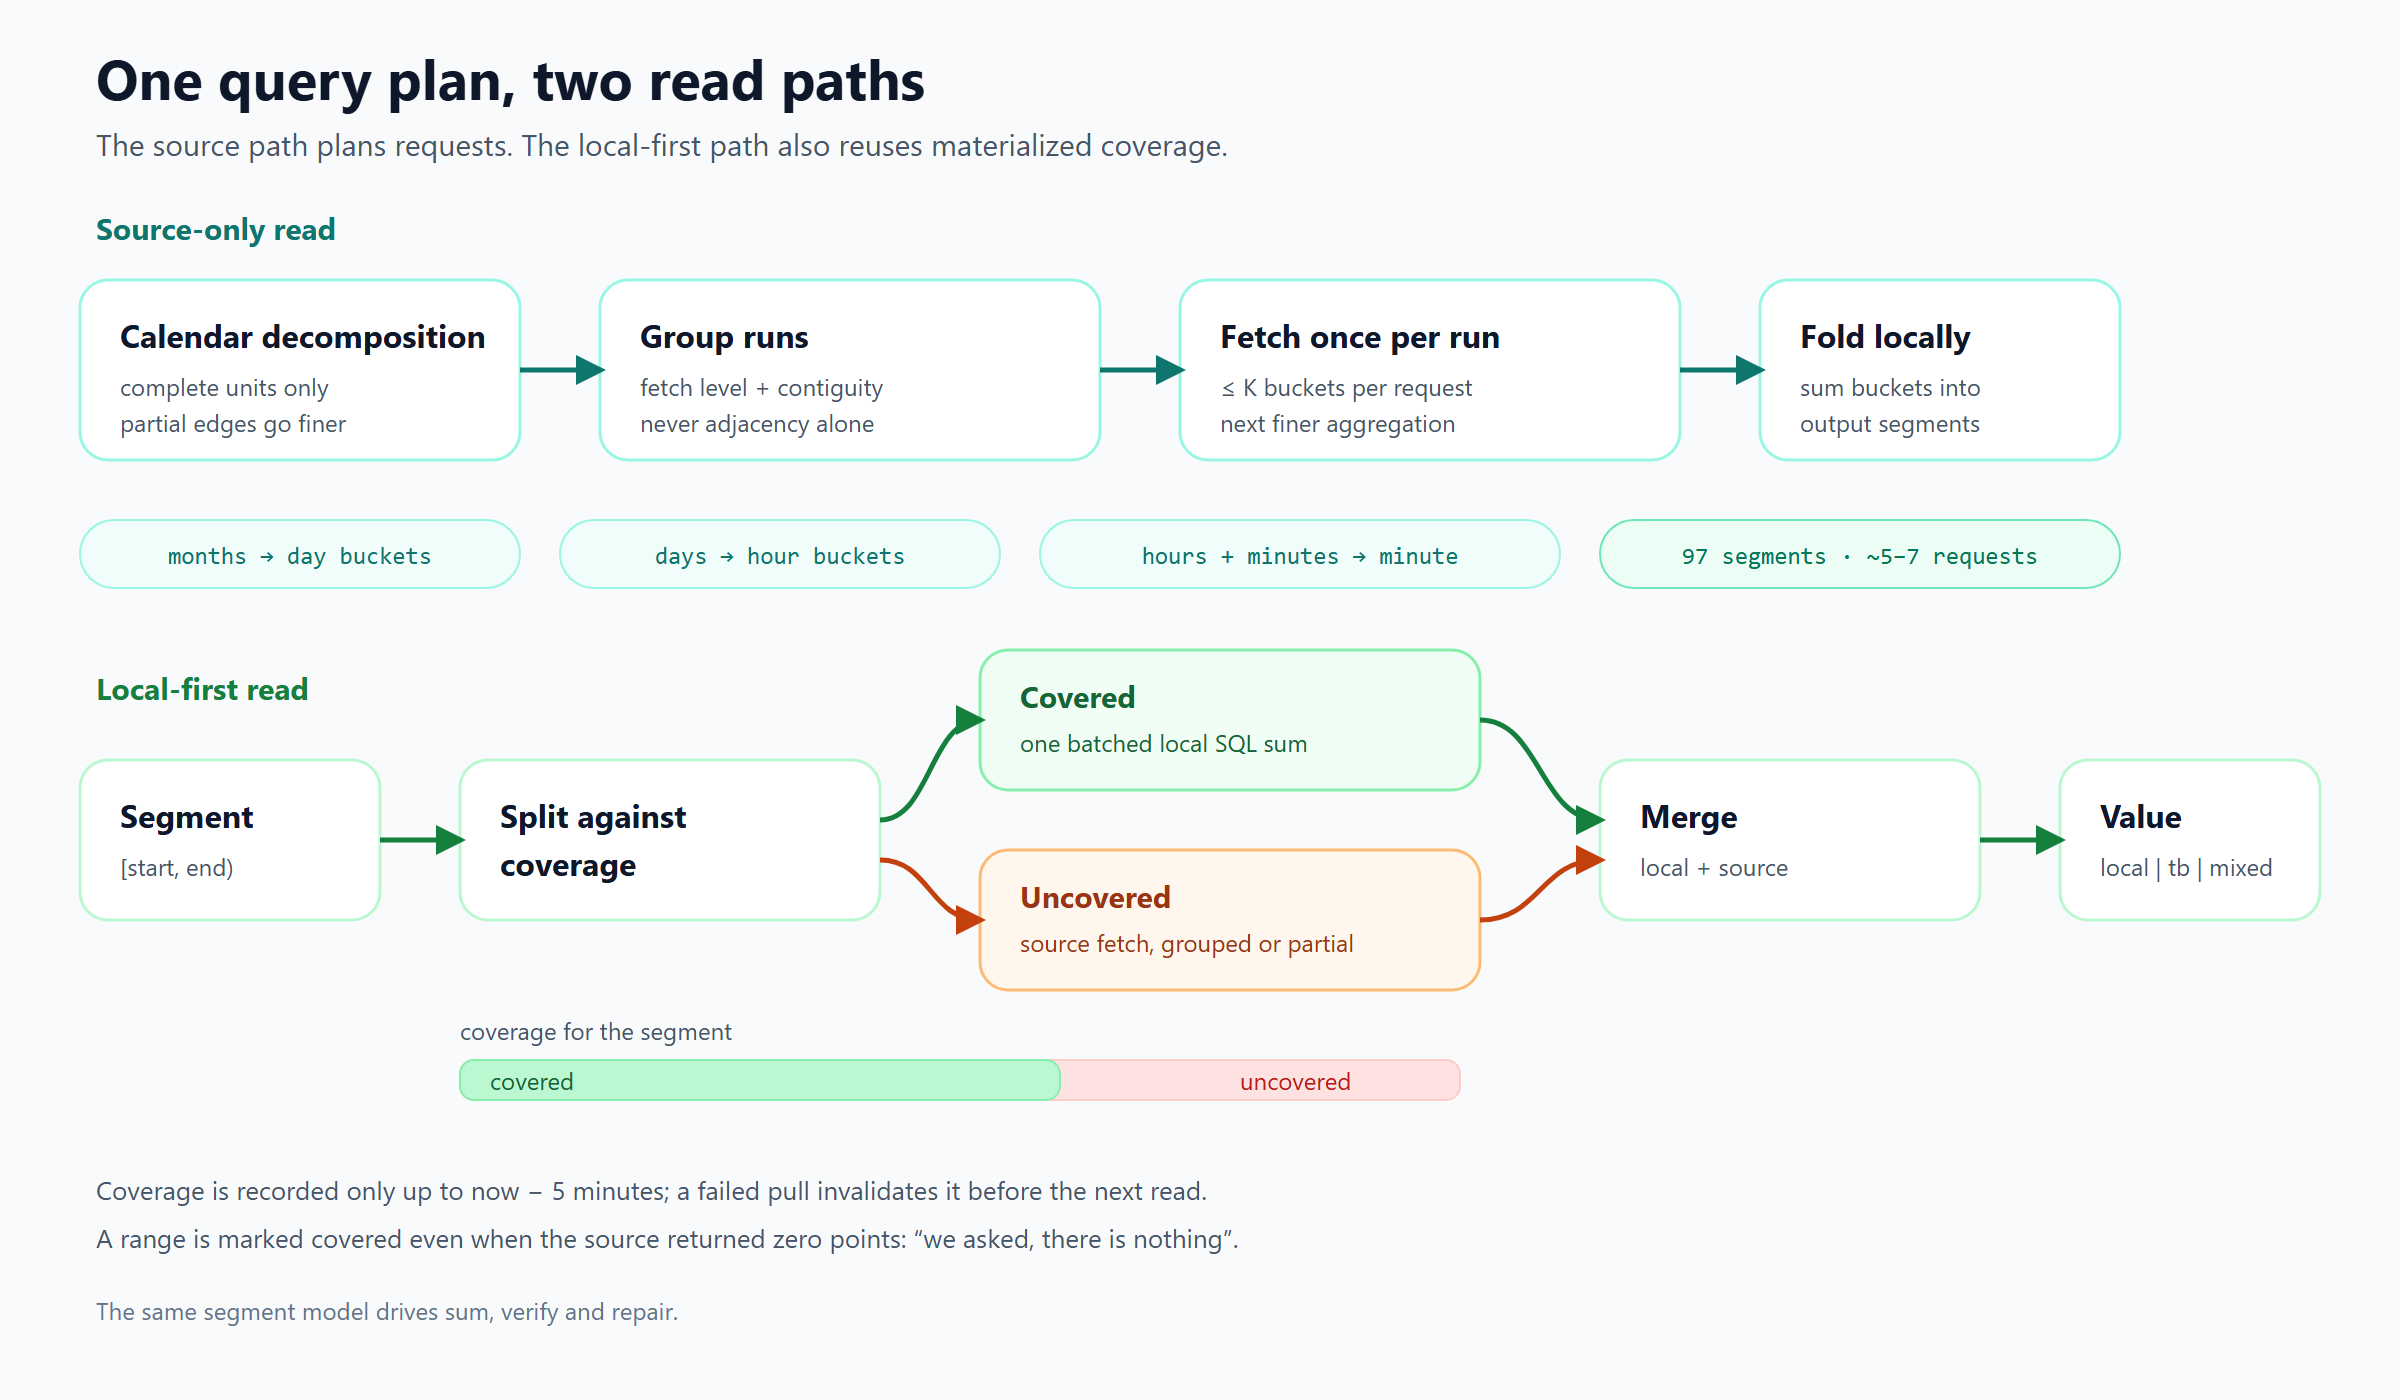
When you have a local point store, the same segments are split against materialized coverage. Covered parts come from one batched local query; uncovered parts come from the source; a partially covered segment fetches only the missing slice.
from hybrid_ladder import LadderEngine, MemoryStore
from hybrid_ladder.sources.thingsboard import ThingsBoardSource

source = ThingsBoardSource("https://thingsboard.example.com", token="...")
store = MemoryStore()               # or PostgresStore("postgresql://...")
engine = LadderEngine(source, store)

# Pull raw points once; coverage is recorded.
engine.materialize([("device-id", "energy")], start_ms, end_ms)

# Repeated queries read local data and fetch only uncovered sub-ranges.
result = engine.sum_mixed([("device-id", "energy")], start_ms, end_ms)
print(result.source, result.source_counts)   # "local" / "mixed" / "tb"
print(result.rows[0].tb_ranges)              # ranges still missing locally

# Compare with the source, then repair if needed.
report = engine.verify([("device-id", "energy")], start_ms, end_ms)
if report["diff_segments"]:
    engine.repair([("device-id", "energy")], start_ms, end_ms)
Coverage is recorded only up to now - 5 minutes; the in-flight tail is never
trusted. A range is marked covered even when the source returned zero points
("we asked, there is nothing"). Before a rewrite, its coverage is cleared — a
failed pull cannot leave stale coverage pointing at incomplete data.
Verify compares the source (authority) with the local store segment by
segment, drilling only differing segments down to points (added / removed /
changed). Repair deletes the local range and re-pulls it from the source
in transaction-sized windows, then re-marks coverage.
Guarantees and limits
| Value | Meaning | Render as |
|---|---|---|
null |
no samples in the segment | — |
0.0 |
samples exist and sum to zero | 0 |
| number | sum of the samples | the number |
Every segment carries cnt (observed points/buckets), expected (buckets the
segment should contain, for source segments) and source (local, tb,
mixed, empty, uncovered). A low cnt relative to expected means sparse
data; the sum is still arithmetically correct, just based on fewer points.
Guarantees
sumis exact: the sum of all segments equals the sum of the source's points in the range. No approximation, no sampling.- Segments tile the range exactly; no zero-length segments.
nulland0.0are distinct everywhere.- Materialization is idempotent; overlapping runs cannot duplicate a timestamp.
- The algorithm only reads the source. It never writes to ThingsBoard.
Limits
- Sum only in v0.0.6.
avgneedssum+countweighting;meter_deltaneeds the first value of every segment (ThingsBoard has noFIRST), so those rules are not on the ladder yet. - Data completeness ≠ arithmetic correctness. Missing samples make the total
lower than the physical total;
cnt/expectedexpose this but do not impute. - ThingsBoard limits: ~700 buckets accepted, 800 rejected (the docs' 1000 is
unreliable); the adapter defaults to 500. Raw series are capped at 10,000
points per request.
COUNTcollapses duplicate points in the same minute. - In-process tasks are lost on restart; results are recomputable and materialized data is not lost.
- DST zones: calendar boundaries are supported, but fixed-size source
buckets mean day/hour folds are designed for fixed-offset zones such as
Asia/Shanghai. Usehourorminutefetching around DST transitions.
Historical fixes and version notes live in CHANGELOG.md.
Performance
From a production ThingsBoard deployment (numbers vary by network and data density):
| Query | Segments | Source requests | Time | Result |
|---|---|---|---|---|
| 2 days, minute level | 69 | ~4 | 0.64 s | 2,217,024.0 (matches 2,566 raw points) |
| 1 year, day level | 42 | ~4 | 1.18 s cold / 0.20 s warm | 36,012,018.25 |
| 10 months, mixed levels | 97 | ~5–7 | sub-second | 423,049 minute buckets avoided |
| Local read, 42–90 segments | — | 0 | 9–19 ms | one SQL statement |
| Mixed read (3 local + 1 source) | 4 | 1 | 0.31 s | equals source-only |
See docs/benchmarks.md (中文) for methodology and caveats.
Positioning and prior art
This is a query-planning method for deployments where you can read an interval-aggregation endpoint but cannot write to or reconfigure the source. It is not a new time-series database, and not a new general theory of aggregation. It composes calendar mixed-radix decomposition, canonical interval decomposition, roll-up and multi-resolution aggregation.
The closest systems are RRDtool/Whisper (multi-resolution archives), BTrDB (hierarchical time-partitioned summaries), TimescaleDB hierarchical continuous aggregates, and Druid period granularity. Query-side systems such as Prometheus and Grafana choose one uniform step; the ladder plans multiple calendar levels in one query.
See Related work and positioning (中文) for the full comparison, the historical algorithms, and the defensible novelty statement. The method is published as a public disclosure (中文); a technical article walks through the production benchmark and the request-count argument.
Project, development and roadmap
Project layout
src/hybrid_ladder/
  core.py          pure decomposition, folding, coverage splitting
  engine.py        source/mixed/local reads, materialize, verify, repair
  models.py        Segment, SeriesRef, LadderConfig, QueryResult
  protocols.py     TimeSeriesSource / PointStore
  sources/         memory.py, thingsboard.py
  stores/          memory.py, postgres.py
  api.py           FastAPI app
  cli.py           hybrid-ladder CLI
  mcp_server.py    MCP tools
  tasks.py         in-process task registry
  demo.py          deterministic demo data
tests/             unit + API + adapter tests
docs/              algorithm, architecture, API, benchmarks, prior art
skills/            agent skill package
examples/          runnable examples
git clone https://github.com/MagicSquarekey/hybrid_recursive_ladder_algorithm.git
cd hybrid_recursive_ladder_algorithm
python -m venv .venv && source .venv/bin/activate   # Windows: .venv\Scripts\activate
pip install -e ".[dev]"
ruff check .
pytest
Optional PostgreSQL integration test:
export HL_TEST_PG_DSN='postgresql://user:pass@127.0.0.1:5432/testdb'
pytest -m integration
Roadmap: avg and meter_delta rules; InfluxDB / Prometheus / ClickHouse
adapters; Celery/RQ task backend; OpenTelemetry metrics; PyPI trusted publishing.
Citation
@software{hybrid_recursive_ladder_2026,
  author  = {MagicSquarekey},
  title   = {Hybrid Recursive Ladder: Query Planning for Bucket-Limited Time-Series APIs},
  year    = {2026},
  version = {0.0.6},
  license = {MIT},
  doi     = {10.5281/zenodo.23683292},
  url     = {https://github.com/MagicSquarekey/hybrid_recursive_ladder_algorithm}
}
Version DOI: 10.5281/zenodo.23683292.
Concept DOI for all versions: 10.5281/zenodo.23556605.
CITATION.cff provides the same metadata for GitHub's
"Cite this repository" button.
License
MIT © 2026 MagicSquarekey
1 maintainer

Metadata
1 maintainer
Release files for hybrid-recursive-ladder 0.0.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| hybrid_recursive_ladder-0.0.6.tar.gz | 2.3 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hybrid_recursive_ladder-0.0.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.3 MB
Release files / hybrid_recursive_ladder-0.0.6.tar.gz
| Download URL | hybrid_recursive_ladder-0.0.6.tar.gz |
|---|---|
| Size | 2.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
70baa0a66019f523abd080f524ef65f6fb1b890425e8484f758299663bc93c39
|
|
BLAKE2b-256 checksum How to use checksums |
a28f877f78bdcde6e74dc6005bd0b313d35d32ddcd76b02041b8acace82d00fd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.9
|
Release files / hybrid_recursive_ladder-0.0.6-py3-none-any.whl
| Download URL | hybrid_recursive_ladder-0.0.6-py3-none-any.whl |
|---|---|
| Size | 53.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1b9c6d7ec25409c46f460289a6f60b3f4e6c472de6ebde5816f54c1071f6a217
|
|
BLAKE2b-256 checksum How to use checksums |
f68a343fb375539ec2547667191523dbab6a05f0caacaee829c7f2ccd39f09e2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.9
|
Security for hybrid-recursive-ladder 0.0.6
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













