
ICA Lens
ICA Lens interprets language-model activations with Independent Component Analysis. It is substantially more compute-efficient to fit than an SAE dictionary and supports base and instruction-tuned language models.
Documentation · 中文文档 · Paper · Model collection
Get started
pip install icalens
Load a published Lens and analyze text:
from icalens import ICALens

lens = ICALens.from_pretrained("sida/icalens-gpt2-small-pile10k")
result = lens.analyze("She deposited the check at the bank.", layer=6)
result
In Jupyter or Colab, the final result expression displays an interactive
token-level analysis:
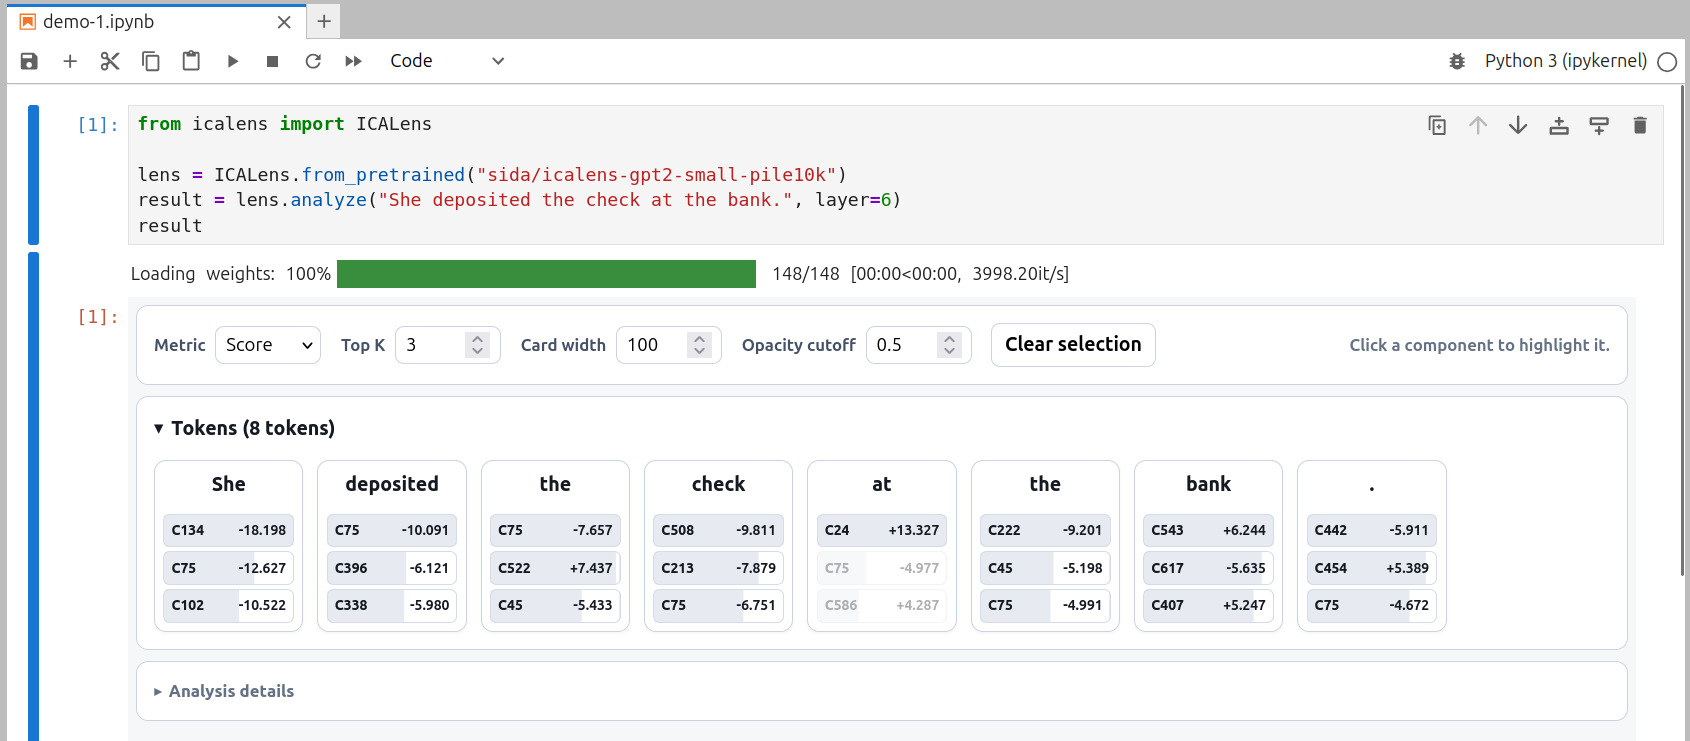
Use signed ICA scores or switch the explorer to per-token component energy. Save the same view as a standalone HTML file with:
result.to_html("analysis.html")
The first analysis loads the language model and requested Lens layer. Later
calls on the same lens reuse the model in memory. device="auto" uses CUDA
when available and otherwise uses the CPU.
Analyze conversations
Instruction-tuned models accept completed conversations using the standard
{role, content} format:
lens = ICALens.from_pretrained("sida/icalens-qwen3.5-2b-ultrachat-1m")
result = lens.analyze(
    [
        {"role": "user", "content": "What is the most interesting science?"},
        {"role": "assistant", "content": "Physics."},
    ],
    layer=16,
)
result
Chat templates are applied automatically, and template tokens and message turns are grouped in the interactive result.
Steering
Generate normally or clamp a signed ICA coordinate during generation:
messages = [{
    "role": "user",
    "content": "If you had to pick one, what is the most interesting science? Be brief.",
}]

baseline = lens.generate(messages, max_new_tokens=16)
steered = lens.generate(
    messages,
    layer=5,
    clamp=(188, -20.0),
    max_new_tokens=16,
)
Component labels, signs, and suitable targets must be established empirically for the exact Lens and layer. See the steering tutorial for the reproducible inspection and calibration workflow.
Fit a Lens
Run a small GPT-2/Pile-10k example with the installed CLI:
icalens fit text \
  --model openai-community/gpt2 \
  --dataset NeelNanda/pile-10k \
  --layers 6 \
  --token-budget 1000 \
  --max-iter 20 \
  --output icalens-output/gpt2-demo
Fit an instruction-tuned model from UltraChat conversations:
icalens fit chat \
  --model Qwen/Qwen3.5-2B \
  --dataset HuggingFaceH4/ultrachat_200k \
  --layers 12 \
  --token-budget 100000 \
  --output icalens-output/qwen-demo
ICA Lens includes a PyTorch FastICA implementation and does not depend on SciPy or scikit-learn. Blockwise fitting and layer-at-a-time capture support larger token collections while bounding memory use.
Profile every fitted layer
After fitting, profile the components against a representative corpus:
icalens profile \
  --lens icalens-output/gpt2-demo \
  --layers all \
  --dataset NeelNanda/pile-10k \
  --split train \
  --max-tokens 10000
Profiles add sign statistics, high-energy examples, and logit-lens tokens to the existing Lens directory. They help label and inspect components without changing the fitted directions.
Publish to Hugging Face
Authenticate with hf auth login, set HF_TOKEN, or add a .env file in the
current directory containing a write-enabled token:
HF_TOKEN=hf_...
Then publish the saved Lens as a Hugging Face model repository:
icalens publish \
  --lens icalens-output/gpt2-demo \
  username/icalens-gpt2-demo
The artifact records the analyzed model, activation site, fitted layers, preprocessing, component profiles, and fitting and profiling provenance. Individual layer and profile files are downloaded lazily when a published Lens is used.
Learn more
The documentation covers:
- Getting started
- Text and chat
- Component profiles
- Scores and energy
- Steering
- Reconstruction
- Fitting and publishing
- Python API
The repository also contains compact notebooks in demo/ covering
text analysis, conversations, reconstruction, fitting, and steering.
Authors
Citation
@article{liu2026icalens,
  title={ICA Lens: Interpreting Language Models Without Training Another Dictionary},
  author={Liu, Sida and Han, Feijiang},
  journal={arXiv preprint arXiv:2606.11722},
  year={2026}
}
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file icalens-0.3.1.tar.gz.
File metadata
- Download URL: icalens-0.3.1.tar.gz
- Upload date:
- Size: 7.3 MB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
6be572d162e309b18886f554c29ebf20751e54f6b3a1952cf3537a0eb1e7150e
|
|
| MD5 |
6baf4dfb760462b5c4b084720831f435
|
|
| BLAKE2b-256 |
657c38e15d61e73f4b759bc30413806f8982be9da4a47b7537f506989d49d96e
|
Provenance
The following attestation bundles were made for icalens-0.3.1.tar.gz:
Publisher:
release.yml on liusida/icalens
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
icalens-0.3.1.tar.gz -
Subject digest:
6be572d162e309b18886f554c29ebf20751e54f6b3a1952cf3537a0eb1e7150e - Sigstore transparency entry: 2436083422
- Sigstore integration time:
-
Permalink:
liusida/icalens@c810bdc6eedaf4502c4ce87f2edc9a72bdb9e778 -
Branch / Tag:
refs/tags/v0.3.1 - Owner: https://github.com/liusida
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@c810bdc6eedaf4502c4ce87f2edc9a72bdb9e778 -
Trigger Event:
release
-
Statement type:
File details
Details for the file icalens-0.3.1-py3-none-any.whl.
File metadata
- Download URL: icalens-0.3.1-py3-none-any.whl
- Upload date:
- Size: 60.5 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
310d16989df1cc313b1be42d01e39723db152698bb9040a68f2ec26d41b88e46
|
|
| MD5 |
c11335244af4ca81d08e0bdd9df28f5c
|
|
| BLAKE2b-256 |
660a59dc5a03b095124b898b339f105f40b7d3432fbee20ad5d7dd3c84db74b8
|
Provenance
The following attestation bundles were made for icalens-0.3.1-py3-none-any.whl:
Publisher:
release.yml on liusida/icalens
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
icalens-0.3.1-py3-none-any.whl -
Subject digest:
310d16989df1cc313b1be42d01e39723db152698bb9040a68f2ec26d41b88e46 - Sigstore transparency entry: 2436085027
- Sigstore integration time:
-
Permalink:
liusida/icalens@c810bdc6eedaf4502c4ce87f2edc9a72bdb9e778 -
Branch / Tag:
refs/tags/v0.3.1 - Owner: https://github.com/liusida
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@c810bdc6eedaf4502c4ce87f2edc9a72bdb9e778 -
Trigger Event:
release
-
Statement type:














