
Jev Rankkit
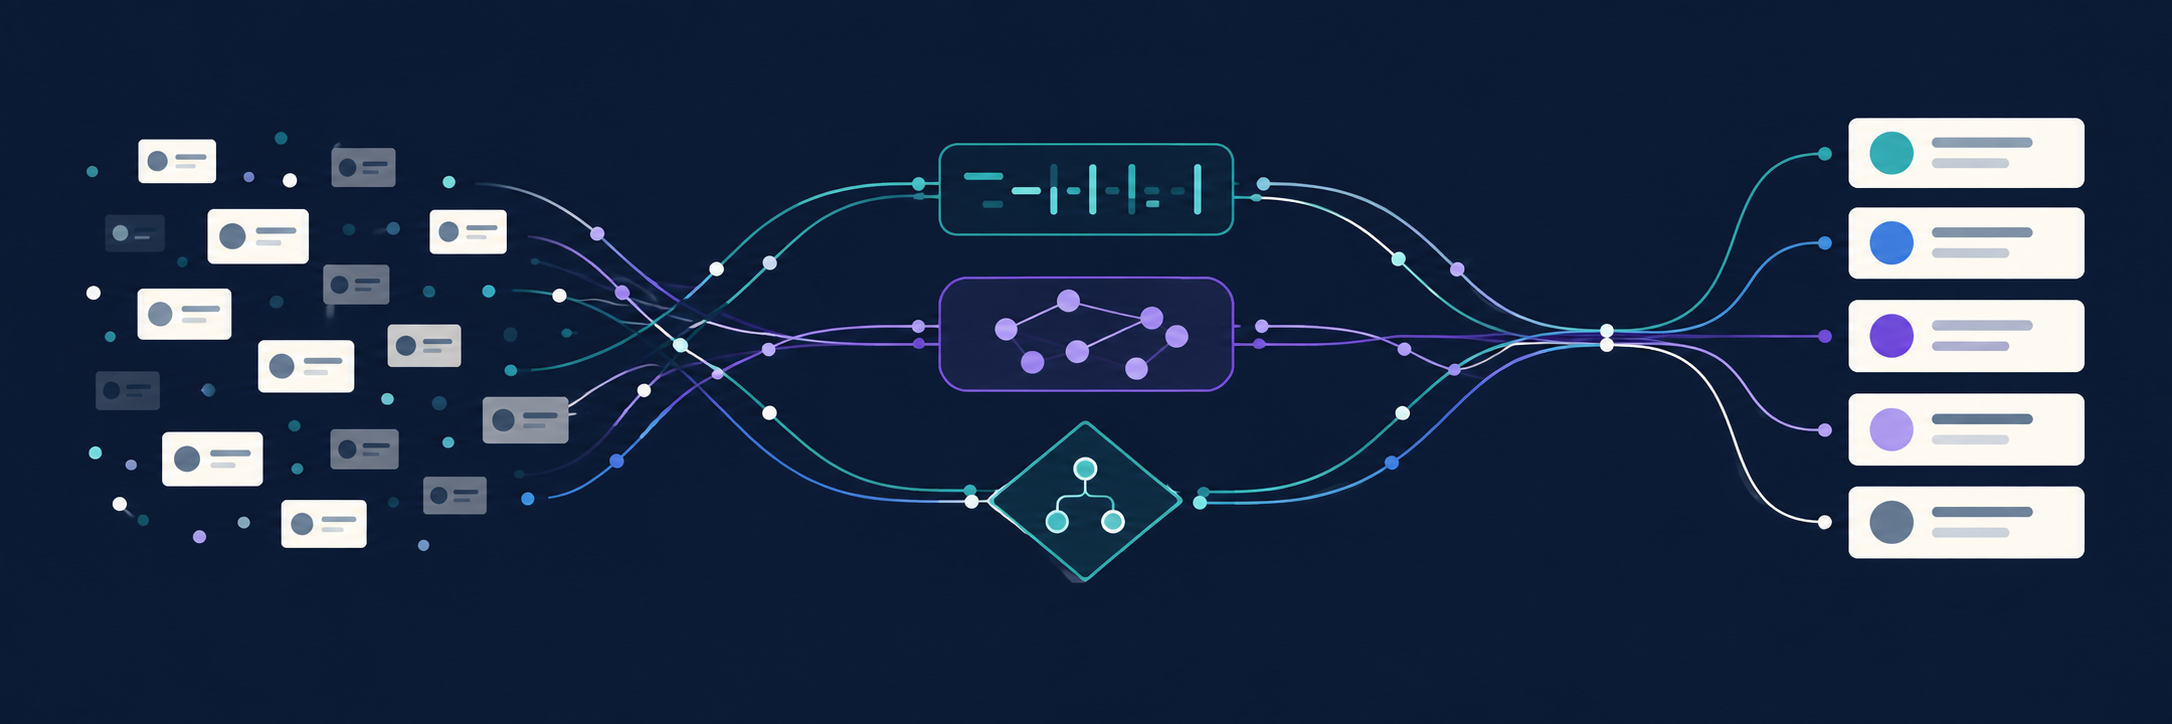
Universal, type-safe reranking for RAG, search, agents, entities, and arbitrary Python objects.
pip install jev-rankkit
For development from a checkout, use pip install -e . or uv sync --group dev.
from jev_rankkit import Reranker

response = Reranker().rerank_sync(
    query="vector search database",
    candidates=["Cooking notes", "Vector database guide", "SQL reference"],
    top_k=2,
)
for result in response.results:
    print(result.rank, result.item, result.score)
Why this exists
Applications rank more than documents: retrieved chunks, products, entities, memories, tools, SQL objects, and graph candidates all need selection. Jev Rankkit keeps original Python objects intact while combining deterministic scores and optional model judgments in one inspectable response. It does not perform retrieval or require an LLM for every stage. The research and architecture explain the tradeoffs.
Installation
The core has no runtime dependencies. pip install 'jev-rankkit[jev]' adds HTTP transport for the TypeSafe AI Jev backend; set TYPESAFE_API_KEY before making a call. pip install 'jev-rankkit[embeddings]' adds optional Sentence Transformers support and may download model weights on first use. For editable installs, use pip install -e '.[jev]' or pip install -e '.[embeddings]'. Integrations with LangChain, LlamaIndex, Qdrant, Pinecone, Elasticsearch, and OpenSearch need only the SDKs your application already uses; Jev Rankkit's adapters do not import them.
Quick start
The example above runs offline with deterministic lexical ranking. For Jev, use async with Reranker(model="typesafe:jev-1.13.0", strategy="auto") as reranker: and await reranker.rerank(query=..., candidates=..., top_k=5). The result includes .results, .stats, .execution_plan, .status, and .coverage. See basic example.
Generic reranking
await reranker.rerank(query=..., candidates=..., top_k=...) accepts a finite sequence. top_k=None requests full ordering; top_k=0 returns without projection or a provider call. Duplicates remain distinct occurrences and equal scores preserve input order. Strings work directly; other types supply text_fn or CandidateAdapter. Results return the same objects by identity.
RAG
Retrieve candidates first, rerank the fixed pool, then build the generator's context from selected results. The RAG example shows a mock vector search returning 50 passages and a top-five context. rerank_documents(...) projects common page_content, text, content, or body fields; reranker.rerank_documents(...) is the bound equivalent. Measure answer quality and evidence support as well as ranking metrics.
Entity reranking
rerank_entities(...) projects name, description, and summary when present. Give ambiguous mentions their surrounding context in the query. Entity example.
Agent/tool reranking
rerank_tools(...) projects tool names and descriptions. It also works for MCP tool descriptors; rank them before placing a shortlist in the agent context, then enforce tool permissions independently. Tool/MCP example. Agent memory, SQL schemas/tables/columns, and knowledge-graph nodes/edges/paths use the same generic engine.
Custom objects
No inheritance is required. Pass text_fn=lambda item: f"{item.name}\n{item.description}"; optional metadata_fn, id_fn, and eligible_fn keep projection, display IDs, and authorization separate. The original object is never serialized to a provider automatically. Custom-object example. Dependency-free framework adapters cover common retrieval-result shapes.
Custom prompts
RerankPrompt holds system instructions, query and candidate templates, criteria, rubric, domain instructions, few-shot examples, output instructions, and a version used in cache keys. Pass it to the constructor or one call. Candidate content is labeled untrusted and sent in a separate structured field; this reduces, but cannot eliminate, prompt-injection risk. Jev does not currently expose reasoning levels or explanations through this adapter. Prompt example.
Custom metrics
Metrics return normalized utilities in [0, 1]. Built-ins include lexical recall, candidate-pool BM25, embedding cosine similarity, LLM relevance, recency, and bounded numeric metadata. Embedding adapters may expose separate query/document encoders for asymmetric retrieval models. CallableMetric accepts a synchronous or asynchronous Python callback. Synchronous callbacks run in worker threads; cancellation cannot forcibly stop one already running. Cacheable callbacks require a cache_key_fn covering every item/context dependency. Missing metadata fails explicitly rather than being invented by a model. Metric example.
Hybrid ranking
Supply metrics=["lexical", "semantic", "llm_relevance", "authority"] with matching weights={...}. Weights must be finite, nonnegative, and are normalized to sum to one. Semantic similarity requires an explicit embedding backend; authority requires caller-supplied metadata. Hybrid example uses toy vectors and a fake model to demonstrate mechanics, not model quality.
Cascaded ranking
RerankPipeline([BM25Filter(limit=100), EmbeddingReranker(...), JevReranker(limit=5)]) passes survivors between stages and records actual input/output counts. Such pruning is approximate relative to scoring every original candidate with the final stage. Full-order requests reject pruning stages. Listwise ranking requires one bounded group; independent chunks cannot be merged as calibrated scores. RRF and MMR/diversity helpers are available in jev_rankkit.selection. Cascade example.
AutoReranker
AutoReranker chooses a deterministic, pointwise, listwise, or coarse-to-strong route using candidate count, size, top-k, quality mode, budgets, and available backends. response.execution_plan explains the route; await reranker.plan(...) lets callers inspect a prospective plan. Routing thresholds are heuristics requiring domain benchmarks. Offline and zero-model-budget modes avoid remote calls.
Cost optimization
Use cheap filtering before expensive judgments, keep candidate projections concise, set Budget(max_model_calls=..., max_tokens=..., max_cost_usd=...), and inspect usage completeness. Cost can be known, estimated, or unknown; no current provider price is hardcoded. Strict monetary budgets reject a backend without a safe chargeable-cost upper bound. Approximate token estimates cannot guarantee a hard provider bill. Budget example.
Latency optimization
Set RerankerConfig(max_concurrency=..., batch_size=..., timeout_s=...) and a per-call latency budget. The model-call semaphore is shared by concurrent calls on one reranker. Jev transport reuses its connection in an async scope. Cancellation releases outstanding permits. Tune batch sizes with measured provider latency; independent pointwise judgments and shared-context listwise groups have different semantics.
Caching
Caching is opt-in with RerankerConfig(cache=CacheConfig(enabled=True)) or an injected CacheBackend. The built-in MemoryCache is bounded and TTL-aware. Model keys include tenant, authorization revision, query, candidate projection, mode, prompt fingerprint, model identity, and relevant parameters. Backends must declare cache_stable=True for judgment caching; the Jev adapter enables it only for exact numbered revisions. Cache and backend contracts.
Evaluation
await evaluate(reranker, dataset, metrics=[NDCG(k=10), Recall(k=5), MRR()]) scores a fixed candidate pool with position-aligned relevance labels. Precision, HitRate, Success, MAP, custom sync/async metrics, latency, throughput, calls, tokens, cost, and cache hit rate are supported. Unjudged items require an explicit policy; missing provider usage stays unknown. See the evaluation guide and example.
Benchmarks
uv run python benchmarks/compare.py runs an original six-domain synthetic smoke dataset and records measured baseline/BM25 values. Optional embedding and Jev rows stay unmeasured until explicitly enabled; Jev calls may incur charges. This toy set does not establish production quality. Reproduction details and caveats are in benchmark guidance.
Architecture
The core depends on Python's standard library. ModelBackend, EmbeddingBackend, Metric[T], RankingStrategy[T], and CacheBackend isolate providers from ranking algorithms. Prepared candidate views carry original objects, projected text, and stable occurrence IDs. The facade validates scores and IDs, applies selection, and returns typed results and an execution plan. Architecture plan. Pairwise/tournament ranking and advanced Jev tokenizer partitioning remain future work; do not infer support from the generic protocols.
Security
Authorize and filter candidates before ranking. Candidate text is untrusted even when delimited in a prompt; model judgment can still be manipulated, especially in shared-context listwise mode. Use pointwise judgments for hostile corpora and enforce permissions outside the model. The core does not log raw candidate text by default, and tracing events contain counts and timings only. Cache keys are hashed and include tenant and authorization revision, but cached score values still need an appropriate storage policy. Avoid placing secrets in projections or benchmark artifacts.
Production guidance
Use an async scope (async with Reranker(...)) or await reranker.aclose() to release owned clients and drain observer events. Fallback policies are explicit; the default raises errors. Validate quality and shortlist recall on your own held-out data, pin backend/model revisions where possible, and monitor failures, latency, usage completeness, cache behavior, and prompt attacks. The opt-in tests/test_jev_live.py checks the provider contract only when JEV_RANKKIT_LIVE=1 and TYPESAFE_API_KEY are set; it may incur a charge. See the comparison with jev-reranker and audit resolution.
Contributing
The project uses MIT licensing, Python 3.11+, pytest, Ruff, mypy, and python -m build. See CONTRIBUTING.md, CHANGELOG.md, and the examples before proposing API changes. No package has been published from this repository.
1 maintainer

Release files for jev-rankkit 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| jev_rankkit-0.1.0.tar.gz | 1.4 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| jev_rankkit-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.4 MB
Release files / jev_rankkit-0.1.0.tar.gz
| Download URL | jev_rankkit-0.1.0.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e7bcdd2bea597882333a4d21f86939fb0bbd591ddc358cecb5c96e360d05c861
|
|
BLAKE2b-256 checksum How to use checksums |
0e54b644c022d08ffe4dc479d86770ee8614c2e012ae5ef78da8a58cec09c881
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.6.6
|
Release files / jev_rankkit-0.1.0-py3-none-any.whl
| Download URL | jev_rankkit-0.1.0-py3-none-any.whl |
|---|---|
| Size | 62.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5d8639bf38cd746d9868aeb433410604723e3e755446f0487ea5aba9a90ee142
|
|
BLAKE2b-256 checksum How to use checksums |
ca3f8fd2662b8df98abe09aa5381555508d1abeabb81fc5a2682773859553982
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.6.6
|













