
jevcompat
About a hundred servers say they are "Jev-compatible". Nothing said what that means. Now something does.
jevcompat is three things for the TypeSafe System One API (POST /v1/systemone, the API behind Jev):
- SPEC.md: a numbered, testable specification: 48 requirements, each with a level (MUST / SHOULD) and the official source it comes from. Where TypeSafe's docs, OpenAPI file and SDKs disagree (they do, in eight places), it says which wins and why.
jevcompat test URL: runs the spec against any server and shows, for every failure, the request that caused it and the bytes that broke the rule.jevcompat proxy URL: puts a spec-conforming API in front of a server that isn't, fixing what can be fixed and refusing, loudly, what can't.
uvx jevcompat test http://localhost:8000
The finding that matters most: confidence is not portable
Jev's pitch is calibrated confidence: tune a threshold, automate what clears it, and send the
rest to a person. The open servers compute confidence four different ways. We applied each
definition to the same 204 answers recorded in the runs below. At a 0.9 threshold:
- TypeSafe's formula auto-accepts 58% of them.
- Laya's definition accepts 30%. It rejects 56 of the 118 answers TypeSafe's formula accepts.
- decider's definition accepts 10 answers that TypeSafe's formula would send for review.
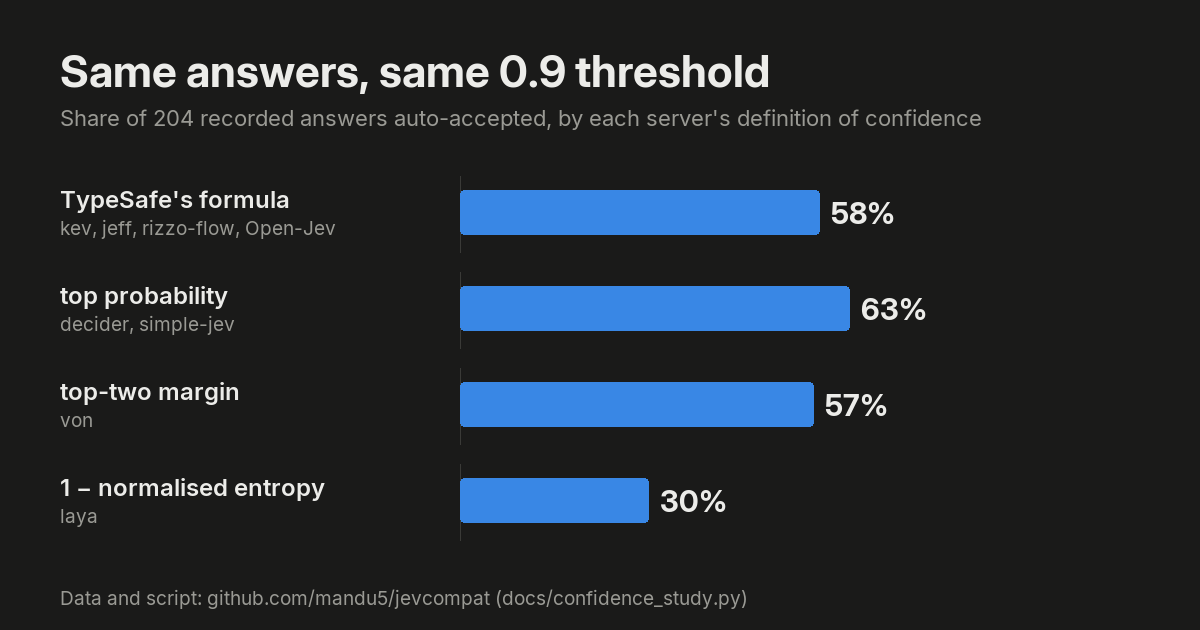
So a threshold tuned against Jev silently changes its automation rate when the same code points
at a "compatible" server. Probabilities are comparable across servers; confidence is not. The
spec pins the formula (confidence.formula), and the proxy recomputes it.
docs/confidence_study.py
reproduces these numbers from the recorded reports.
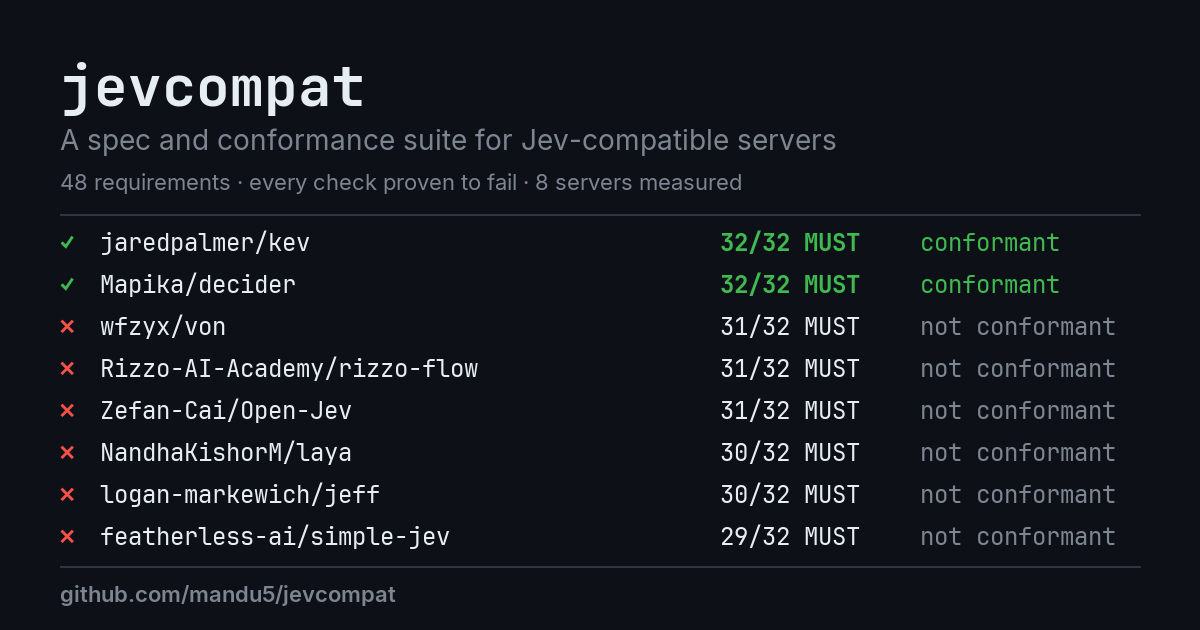
Results: the eight most-starred open servers
Measured on 2026-09-24 on an M1 Pro (16 GB), jevcompat 6a8a543, each server at a pinned commit
with pinned weights. Stars as of that day. Full reports, exact commands and weights:
results/.
| server | ★ | MUST | SHOULD | verdict | what breaks for a Jev client |
|---|---|---|---|---|---|
| jaredpalmer/kev (0.8B) | 5.8k | 32/32 | 10/12 | conformant | - |
| Mapika/decider (0.8B) | 338 | 32/32 | 6/12 | conformant | - |
| wfzyx/von | 571 | 31/32 | 8/12 | not conformant | object or array instructions are rejected |
| Rizzo-AI-Academy/rizzo-flow (1.7B) | 389 | 31/32 | 9/12 | not conformant | more than 26 choice options are rejected |
| Zefan-Cai/Open-Jev (2B) | 284 | 31/32 | 9/12 | not conformant | one-sided noul criteria are rejected |
| NandhaKishorM/laya | 20.1k | 30/32 | 6/12 | not conformant | 128 choice options are rejected; a null legend value the SDK cannot parse |
| logan-markewich/jeff | 230 | 30/32 | 11/14 | not conformant | more than 64 options are rejected; score is not Σ i·p of its own probabilities |
| featherless-ai/simple-jev (0.8B) | 499 | 29/32 | 7/12 | not conformant | "model": "jev-latest" is rejected; more than 50 options are rejected; null legend value |
Across the eight:
-
Two are conformant. Every other one breaks a client written against TypeSafe's docs in one to three ways.
-
Four cannot take the documented 255 options (they stop at 26, 50, 64, or between 64 and 128).
-
confidencemeans five different things. Five of the eight servers differ from the formula TypeSafe documents:- 1 − normalised entropy (laya);
- the top probability (decider, simple-jev);
- the top-two margin (von);
- the score spread divided by L − 1 (kev).
A 0.8 threshold tuned on one of them means something else on the next.
-
In one server, reordering questions moves an answer:
teamgoes from Billing 0.768 to 0.351. Its questions share one encoder pass.
Every failure was checked by hand against the recorded exchange for a jevcompat false positive
(results/REVIEW.md). Doing that on earlier builds found five bugs in
jevcompat itself, all fixed before these runs. The SHOULD column includes jevcompat's own
conventions (x_ prefixes, the confidence formula); the MUST column does not.
Why
Jev's weights are closed and the API was waitlisted, so within nine days of the 2026-09-15 launch there were ~100 open-source servers claiming compatibility. Reading the code of the 26 most-starred:
- only 14 serve
/v1/systemoneat all; confidencemeans five different things: the top probability, the top-two margin, 1 − normalised entropy,max(p, 1−p)on yes/no answers, or undisclosed. A threshold of 0.8 tuned on one server means something else on the next;- the choice limit is 26, 50, 64, 128, 255 or unenforced, though the docs promise 255;
"model": "jev-latest", the official SDKs' default, is ignored, echoed, rejected with 404, or rejected with 422;- invalid requests get 400, 404, 413, 422, 500, 502 or 503. The SDKs retry 5xx.
None of that is visible until your code breaks. The spec makes it visible, and the suite checks it.
What it checks
| § | area | what a server must get right |
|---|---|---|
| 1 | transport | the route, JSON everywhere, GET /v1/models |
| 2 | auth | Bearer keys; and, with auth off, not choking on the header the SDKs always send |
| 3 | requests | string/object/array state; null, object and array descriptions; 2–255 options; 2–10 score levels; any question id; Unicode that round-trips byte-for-byte |
| 4 | responses | the envelope; one answer per id; integer token counts; no NaN; probabilities keyed exactly by option, summing to 1; choice is the argmax; score is Σ i·p; legend echoes the levels; confidence per the documented formula |
| 6 | errors | never a 5xx for a bad request; 422 with detail[] for validation; detail.error_type otherwise |
| 7 | semantics | renaming a question id, adding questions, or reordering them does not change answers (noise-aware: a difference fails only above 3× the server's own repeat-to-repeat variation) |
| 8 | drop-in | the official typesafe-sdk parses every answer type |
jevcompat spec lists all 48. Checks judge the wire contract, not intelligence: a server can be
fully conformant and still give bad answers. For accuracy and calibration, see
JevBench and
sys1bench.
Every check is proven to fail
A conformance suite that never fails is worse than none. jevcompat mock is a reference server
that implements the spec exactly, and it can break any requirement on purpose:
jevcompat mock --list-faults        # 47 faults: every requirement but the SDK check has at least one
jevcompat mock --fault choice-second --fault legend-1-based
The test suite runs every check against the clean mock (must pass), against a noisy mock over many seeds (must never fail; the semantic checks are statistics, and are tested as statistics), and against each fault (the targeted requirement must fail, and a single fault must not smear failures across unrelated MUSTs). If a check could not catch the thing it exists to catch, or blames the wrong requirement, CI goes red.
Use
jevcompat test http://localhost:8000                    # terminal report
jevcompat test URL --key-env MY_KEY                     # server with auth (also runs the auth checks)
jevcompat test URL --json r.json --markdown r.md --badge
The verdict is conformant (every applicable MUST tested and passed; exit 0), not conformant (a MUST failed; exit 1), not tested (the server could not be reached or refused a minimal request; exit 2) or incomplete (nothing failed, but a MUST could not be judged, usually a timeout, which is never counted against the server; exit 3). The output names the requirement, the case, and the exchange:
§4.4 Score answer
  ✗ MUST   score.expectation          score is the expectation of the probabilities
      score-levels:2 answers['anger']: score is 0.9973; the probabilities give Σ i·p = 0.8640
        → POST /v1/systemone {"questions": {"anger": {"type": "score", "instructions": "How frustrated is the customer?", "criteria": ["Calm", "Very angry"]}}, "model": "jev-latest", …}
        ← 200 {"model":"gliformer-large-v1","answers":{"anger":{"type":"score","score":0.9973,"confidence":0.7279,"legend":{"0":"Calm","1":"Very angry"},"probabilities":{"0":0.136,"1":0.864}}},…}
(from the jeff report: score was computed before the probabilities were tempered)
Put a proxy in front of a server
jevcompat proxy http://localhost:8000 --port 8788            # then point clients at :8788
jevcompat proxy URL --upstream-model laya --split             # rename the model; one question per upstream call
The proxy recomputes choice, score, legend and confidence from the probabilities,
reconciles option names that differ only by Unicode normalisation or case, renormalises, fixes
token counts, prefixes extra fields with x_, answers /v1/models, validates requests itself so
bad ones get a proper 422, and hides question ids and order from the upstream so answers cannot
depend on them (--split also rules out any effect of one question on another). What it cannot
fix: a missing or ambiguous option, probability mass on options nobody asked about, a
probability of 1.3, a sum far from 1 (unless you pass --renormalize). It refuses with
502 upstream_error rather than pass through. Each response lists what it changed in
x-jevcompat-fixes. Of the mock's 47 faults, the proxy fixes 38 and refuses 9.
Test your server in CI
- run: my-server --port 8000 &                 # start your server
- uses: mandu5/jevcompat@v0
  with:
    url: http://localhost:8000
The step fails unless the verdict is conformant, writes the report to the job summary, and outputs the verdict and a badge:
Use the mock in your application's tests
jevcompat mock --port 8787 is a spec-exact stand-in for Jev with deterministic answers. Point
TYPESAFE_BASE_URL at it and your CI no longer needs a key, a network, or a waitlist.
FAQ
Is this official? No. It is written from TypeSafe's public docs, OpenAPI file and SDK source, and cites them requirement by requirement. If TypeSafe publishes a conformance suite, this one should defer to it.
Why not test TypeSafe's own API? The suite sends malformed requests on purpose, and TypeSafe's customer terms prohibit security testing. The tool will run against any URL; the published results cover open-source servers only.
Why is confidence.formula only a SHOULD? TypeSafe says clients are "never locked into our
definition" and ships the full probabilities. But a threshold means the same thing across servers
only if the number does, so the spec recommends the formula TypeSafe documents and uses.
My server fails a requirement I think is wrong. Open an issue quoting the requirement id. The spec is a draft; disagreements with evidence are how it gets better.
Development
uv run --extra dev pytest -q # validators, every fault, statistical semantics, preflight, the proxy, the CLI
Design notes: DESIGN.md.
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for jevcompat 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| jevcompat-0.1.1.tar.gz | 65.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| jevcompat-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 116.3 kB
Release files / jevcompat-0.1.1.tar.gz
| Download URL | jevcompat-0.1.1.tar.gz |
|---|---|
| Size | 65.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9116ca848fb7231879c369ca96f8197f3a12dbd616ab047474acf138b7e3ae30
|
|
BLAKE2b-256 checksum How to use checksums |
93b23e4bb24143bcb275fd53a4943c33acb38fcb0e7e0a44e8452fdaca3344f7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logRelease files / jevcompat-0.1.1-py3-none-any.whl
| Download URL | jevcompat-0.1.1-py3-none-any.whl |
|---|---|
| Size | 50.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1bad691aad0722abb0f0b21e62ca1af0e7a7482ee9080c52b556a5112c4e9153
|
|
BLAKE2b-256 checksum How to use checksums |
98605256a94c55468789677fe37146cff3b1c873c7289f4646b2c6ca74bb6805
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency log













