
Jev, distilled on the fly. Same call. Same answers. Your hardware.



Put Jevstiller in front of a repeated Jev classification call. At first every request still goes to Jev. From Jev's own answers — with their full probability distributions — it trains a small local model on your traffic, checks that the model agrees with Jev within a budget you set, and then answers most requests itself. Uncertain or novel input, and a permanent random audit slice, keep going to Jev.
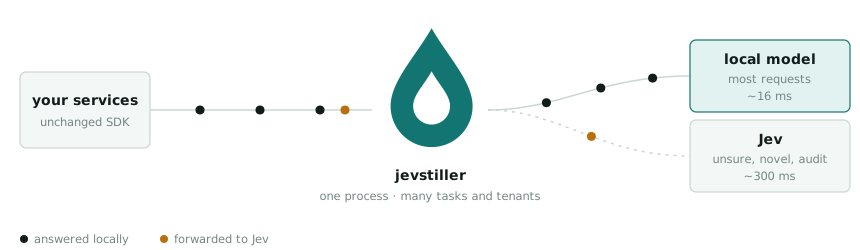
You already call Jev. Run Jevstiller next to your service and point the SDK at it; nothing else changes:
docker run -d -p 8080:8080 -v jevstiller-data:/data ghcr.io/tomerglick57/jevstiller
export TYPESAFE_BASE_URL=http://localhost:8080     # your service keeps its own TYPESAFE_API_KEY
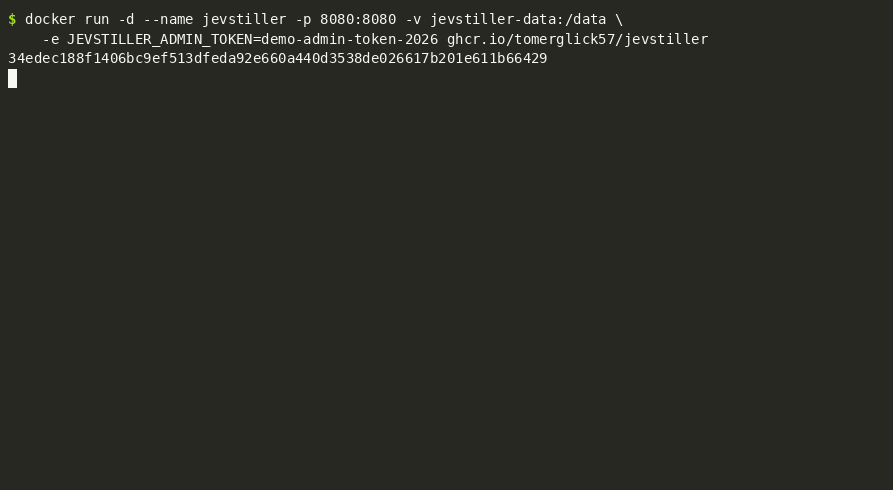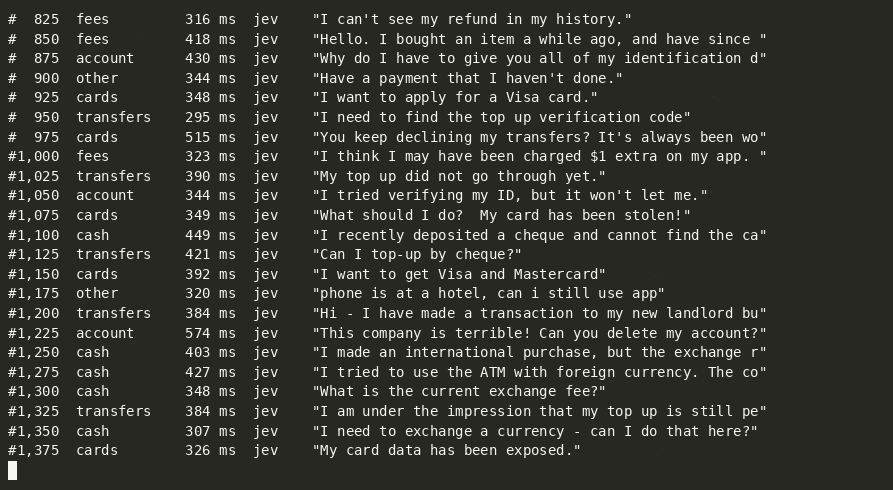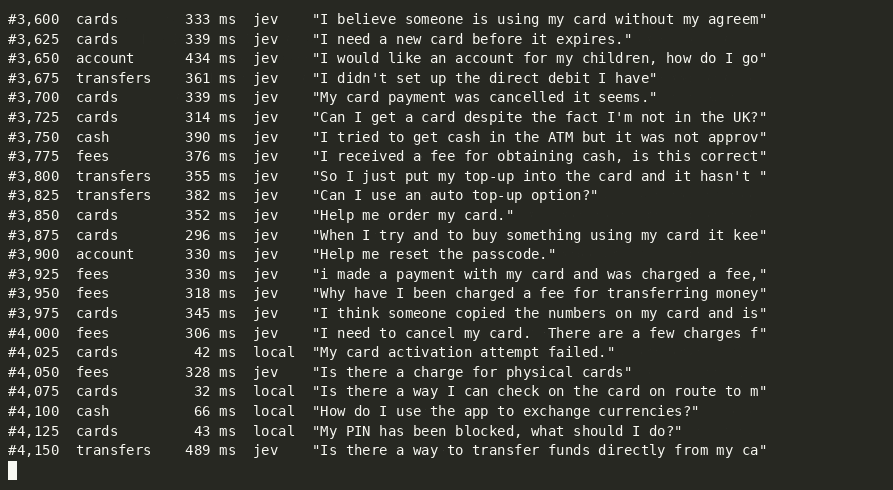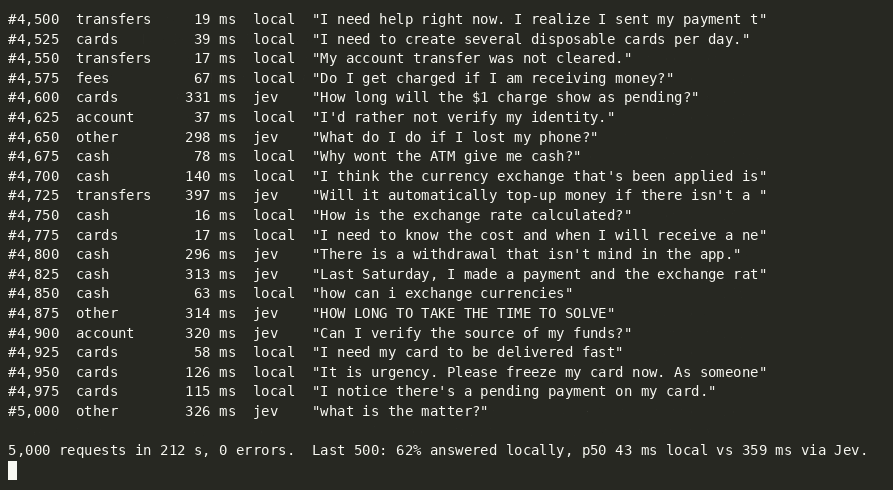
The recording above is examples/proxy_demo.py: 5,000 real customer messages through the unmodified SDK, 8 threads, against live Jev. The local model took over after about 4,000 requests. docker exec jevstiller jevstiller admin status <task> shows the audit agreement behind it (with -e JEVSTILLER_ADMIN_TOKEN=... on the container).
Why
Jev is fast, cheap and typed. It is also ~300 ms away, per answer, at every load we tried (16 to 64 concurrent callers, up to 190 requests/s, p50 300 ms), and it is hosted: every classification is a network call to one vendor, under published rate limits (80 requests and 100,000 tokens a second as of October 2026; 1,200 requests a minute at launch) that TypeSafe adjusts at its own discretion. Jevstiller is for the workload where that hurts: decisions made one after another (an agent loop, a game tick, classify-then-act pipelines), latency budgets in milliseconds, boxes with no egress, or simply not wanting every classification to depend on one external API.
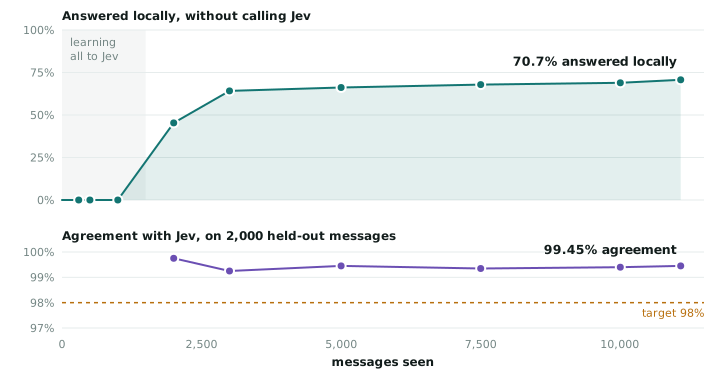
On Banking77 (77 customer-support intents), replayed against Jev's recorded answers, the local model answered 71.9% of held-out messages at 99.50% agreement with Jev (target 98%), taking over most traffic from about 5,000 messages on, and kept Jev's accuracy (78.5% vs Jev's 78.5% on the dataset's labels). The live run of 2026-09-25 gave 70.7% at 99.45%. A local answer takes ~15 ms on CPU (p50), about 20× faster than Jev; one CPU process answers ~130 messages/s, a GPU ~2,000/s.¹
Benchmark
Five public tasks, replayed through the loop with Jev's recorded answers as the teacher (bge-small on CPU, target agreement 98%). Answered locally and agreement are measured on 2,000 held-out rows against Jev; accuracy is against the dataset's own labels, for Jev alone and for the system (student where it answers, Jev elsewhere).
| Task | Answered locally | Agreement with Jev | Accuracy, Jev / system |
|---|---|---|---|
| Banking77, 77 intents | 71.9% | 99.50% | 78.5% / 78.5% |
| CLINC150, 150 intents † | 69.0% | 99.65% | 90.1% / 90.1% |
| AG News, 4 sections | 80.2% | 99.40% | 88.7% / 88.7% |
| TweetEval sentiment, 3 classes | 22.2% | 98.70% | 64.2% / 64.5% |
| TweetEval offensive, 2 classes | 24.1% | 98.80% | 73.8% / 74.2% |
† with rare_classes = "defer": Jev never used one of the task's labels.
Over 100 random splits across the 5 tasks, the calibrated threshold exceeded the 2% budget once; the usual point-estimate rule exceeded it on 6–12 of 20 splits per task.
Coverage tracks how consistent Jev itself is on a task, not how hard the task is: on the tweets Jev agrees with the dataset's labels only 64% and 74% of the time, so the student answers the confident quarter and forwards the rest, and the system's accuracy still matches Jev's. The threshold-rule comparison, what other targets buy, and the one-command reproduction: docs/benchmarks.md.
The contract
You set one number. Jevstiller returns the label Jev would have returned on at least that share of requests:
target_agreement = 0.98 → disagreement budget = 2% of all requests
The routing threshold is chosen on a held-out, IID calibration set so that, with 95% confidence, the share of requests the local model answers and gets different from Jev stays within the budget. It uses an exact finite-sample bound (Clopper–Pearson), testing candidate thresholds strictest-first. It is not tuned by eye, and it is re-verified forever on the audit channel. If the audit shows the contract is broken, everything falls back to Jev automatically.
If your code also acts on Jev's confidence, for example sending answers below 0.6 to review, set that number as the task's confidence_floor. The bound then also counts the requests Jev would have been less sure about than that, and local answers report at least that confidence. See configuration.
Agreement with Jev is not accuracy. If Jev is wrong, the student is wrong the same way. The status report says so next to every number. See DESIGN.md §2.
Install
pip install jevstiller                 # everything: the proxy (`jevstiller serve`), the encoder, the Jev adapter
pip install "jevstiller[gpu]"          # on a GPU machine: adds PyTorch, used automatically when CUDA is present
Python 3.10+. CPU works out of the box; a GPU only speeds up the encoder.
Drop-in proxy: no code changes
Run Jevstiller next to your services and point the Jev SDK at it:
docker run -d -p 8080:8080 -v jevstiller-data:/data ghcr.io/tomerglick57/jevstiller:0.5.1
# or: pip install jevstiller && jevstiller serve --config deploy/jevstiller.toml
export TYPESAFE_BASE_URL=http://jevstiller:8080 # in each calling service; nothing else changes
Services keep their own TYPESAFE_API_KEY; Jevstiller forwards it and never stores it.
- Tasks: every
Choicequestion, and every yes/no (Noul) question, becomes a task, keyed by its exact instructions, criteria and model, so services asking the same question share one local model. For a yes/no question you state the cut-off your code uses (0.5 unless set): docs/coverage.md. - Until a student is ready: requests are forwarded to Jev unchanged, and Jev's responses returned unchanged, until a task's student is trained and has passed its checks.
- After that: the proxy answers what it is sure about in Jev's exact response format (
x-jevstiller-source: localtells you which), but only for keys Jev has accepted. - Always forwarded:
Scorequestions, other endpoints, and anything it does not understand.
Performance of one process (16 vCPU, bge-small on CPU, docs/benchmarks.md):
- Forwarded requests: Jev's latency plus ~1–4 ms, and up to ~585 req/s at 256 concurrent callers.
- Local answers: ~16 ms p50, ~50 ms p99, up to the encoder's capacity (here ~150–340 texts/s depending on text length; a GPU raises it). Beyond that, the excess is forwarded to Jev, so the proxy is never much slower than Jev.
- Memory: ~300 MB with the encoder, plus a few MB per loaded task. Bounded over a 12-hour soak of 0.4.0 at 100 requests/s with ~16 task reloads a second: 300–445 MB throughout, 357 MB at the end, 4.3 million requests with no errors (and a 24-hour run of an earlier build: one hump to 654 MB that receded on its own).
Operations: a TOML config, an admin API and CLI (jevstiller admin ...), Prometheus /metrics, /readyz, JSON logs, jevstiller backup, and a Docker image and Kubernetes manifest. Docs: deploy, operations, the proxy, configuration, security, compatibility. Website: jevstiller.pages.dev.
How it compares
As of September 2026:
- stuntd is the closest project. It is also a local Jev-compatible proxy that learns a head per question (on the Laya encoder) and checks 2% of live traffic. The differences:
- Guarantee: Jevstiller picks its threshold with a finite-sample bound on disagreement over all requests; stuntd uses a point estimate on a holdout.
- Automation: Jevstiller trains, shadow-tests and promotes by itself; stuntd uses
stuntd train/stuntd enable. - Training data: Jevstiller learns from Jev's full probability distributions and gates unfamiliar inputs.
- Question identity: Jevstiller identifies a question by its exact content; stuntd uses its name.
- Keys: Jevstiller answers locally only for API keys Jev has accepted.
- Deployment: Jevstiller serves many tenants from one server, on CPU.
- Where stuntd goes further: it also speaks the OpenAI API, and can answer with no provider at all (zero-shot Laya).
- Distil Labs and cloud "distillation" (Amazon Bedrock, OpenAI, Azure) train a small replacement model from your traffic as a separate job, then swap the whole model. There is no per-request fallback to the large model, no bound, and no Jev API.
- Routers (RouteLLM, Not Diamond, OpenRouter Auto) choose between existing models. Semantic caches (GPTCache, Portkey, jevcache) reuse answers to near-identical inputs. Neither learns to answer new inputs.
- Open Jev-compatible models (Laya, Kev, jeff) replace Jev outright, at lower zero-shot accuracy.
- Research:
- OCaTS (EMNLP 2023), Cache & Distil (ACL 2024) and Online Cascade Learning (ICML 2024) train a student online from an LLM's answers, without a guarantee.
- BARGAIN (SIGMOD 2026) and vCache (ICLR 2026) guarantee agreement with the LLM, but without a student that keeps learning.
- Jevstiller combines the two, with a permanent audit and automatic fallback on top.
Quickstart (library)
Without a key, python examples/quickstart_synthetic.py runs the whole loop on CPU in half a minute with a synthetic teacher standing in for Jev. With Jev (TYPESAFE_API_KEY in your environment):
from jevstiller import Task, Jevstiller, load_encoder
from jevstiller.teachers.jev import JevTeacher

task = Task(
    name="support_router",
    instructions="Which team should handle this customer message?",
    classes={                              # descriptions are sent to Jev verbatim — they are the spec
        "billing":      "Charges, invoices, refunds, payment methods",
        "technical":    "Bugs, errors, integrations, things not working",
        "cancellation": "Wants to cancel, downgrade, or close the account",
        "sales":        "Pre-sales questions, plan comparison, quotes",
        "other":        "Anything that does not fit the categories above",
    },
    target_agreement=0.98,
)

js = Jevstiller(task, teacher=JevTeacher(), data_dir="./jevstiller-data", encoder=load_encoder("base"))

r = js.classify("Please cancel my subscription")
r.label        # "cancellation"
r.confidence   # 0.97
r.source       # "teacher" at first — later "student:v9"

print(js.status().report())
Task: support_router   version 89a7438c2f7d   mode: cascade   audit rate 2%
Production: student:v9   Shadow: -
Requests: 11,083   student 69.8%   teacher 30.2%
Agreement with teacher (audit, n=415): 99.40% [98.46%, 99.84%]   target 98%   OK
  note: agreement with the teacher is not accuracy.
How it works
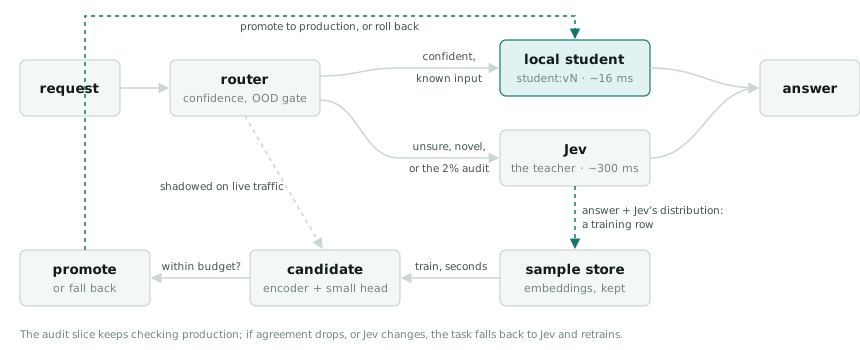
- Encoder: frozen sentence encoder (
bge-small/base/large), ONNX or PyTorch. Embeddings are stored, so retraining never re-encodes. - Student: numpy logistic regression on the teacher's distribution, early-stopped on a validation slice.
- OOD gate: kNN distance in embedding space — unlike anything seen → Jev, whatever the head says.
- Audit channel: a fixed random slice always goes to Jev. The only unbiased view of production, and the price of the guarantee.
- Versions: immutable
student:vNdirectories; promote, roll back, orexport()a standalone bundle.
The full reasoning — including the five loop bugs the first real replay found and how they were fixed — is in DESIGN.md.
Status
Alpha. Validated against live Jev (above).
-
Proxy: the drop-in proxy works end to end with the unmodified TypeSafe SDK.
-
Security: three security audits (12, 15 and 8 findings, all fixed: docs/security.md).
-
Deployment: it runs as a hardened container.
-
Tested under failure and load:
- Jev down, slow or rate limiting.
- A full disk.
kill -9during training.- A 24-hour soak with a silent change in Jev's answers at hour 12, which it recovers from by itself (3.6 million requests, 0.012% errors).
- Load up to 256 concurrent callers.
Results: docs/benchmarks.md.
-
Benchmarked on five public tasks against Jev's recorded answers (above); the full tables and the one-command reproduction are in docs/benchmarks.md.
See DEPLOYMENT_PLAN.md for what is done and what is next.
Documentation:
- DESIGN.md: why it works the way it does.
- docs/deploy.md, docs/operations.md, docs/proxy.md, docs/coverage.md (what is answered locally of Jev's API, and what isn't), docs/configuration.md, docs/benchmarks.md, docs/security.md, docs/compatibility.md (supported SDK and Jev versions, what callers see, versioning).
Not for: tasks with changing class lists (retrain from scratch), non-text input, or volumes too low to ever collect a few thousand examples.
Reproduce the numbers
Jev's answers for every Banking77 message ship with the repository, so the headline result replays without an API key:
git clone https://github.com/tomerglick57/Jevstiller && cd Jevstiller && pip install jevstiller
bash experiments/reproduce.sh      # the Banking77 result above, on CPU, 10-15 minutes: 71.9% coverage at 99.50% agreement, deterministic
python experiments/run.py --dataset banking77 --teacher jev --encoder small     # against live Jev (TYPESAFE_API_KEY)
python experiments/run.py --dataset banking77 --teacher oracle --encoder base   # the dataset's labels as a perfect teacher
Questions and contributing
- Questions: Discussions › Q&A.
- You ran it on a real task: post the status report in Discussions › Show and tell or open a result report. This is the most useful thing you can do for the project.
- Bugs: open an issue. PRs welcome; see CONTRIBUTING.md.
- Security: see SECURITY.md, not a public issue.
License
Apache 2.0 (see LICENSE and NOTICE). Jevstiller is an independent project and is not affiliated with, endorsed by, or supported by TypeSafe. "Jev" is their model; this tool only talks to its public API.
¹ Live run 2026-09-24: 11,083 replayed messages with 2,000 held out, bge-small on CPU; the GPU figure is from an oracle-teacher run with bge-base on an RTX 3090. Every number, with its command: docs/benchmarks.md.
1 maintainer

Metadata
1 maintainer
Release files for jevstiller 0.5.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| jevstiller-0.5.1.tar.gz | 236.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| jevstiller-0.5.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 365.1 kB
Release files / jevstiller-0.5.1.tar.gz
| Download URL | jevstiller-0.5.1.tar.gz |
|---|---|
| Size | 236.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f0a0ed9f7c75400267d4064f761ac626ed102446cd1567e1a7cb1300ebe3a6de
|
|
BLAKE2b-256 checksum How to use checksums |
2f61b344251bae8afd7053c735d242dbb342d98955b6e38fd0d0194fd480ada0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency logRelease files / jevstiller-0.5.1-py3-none-any.whl
| Download URL | jevstiller-0.5.1-py3-none-any.whl |
|---|---|
| Size | 129.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
848ee5e44ca3bfe9d2b93df88adc3f386f7ddd1f5573f154f744956ba9fa3f47
|
|
BLAKE2b-256 checksum How to use checksums |
87c9d4f3023d9fe91dbaaced5480ba8c503f5ac0328817b2517aa3b87a60ec57
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency log













