
jobwatch


Watch the job boards of the companies you care about and get a short, ranked digest of new roles that match you, optionally fit-scored against your resume. jobwatch finds and ranks. It never applies for you.
Watch it with sound (1½ minutes, made from made-up data).
$ jobwatch run
Checked 48 board(s): 9,412 open roles, 37 new.

# jobwatch digest

6 matching job(s). Filtered out: 22 by location, 4 by pay, 5 by title.
Applied today: 1 of 3.

### [Staff Data Engineer](https://jobs.ashbyhq.com/initech/c1)
Initech · Denver, CO, United States; Remote · $230K–$300K · posted today
**Fit 81/100**, must-haves 6/7. Gaps: 3+ years with Kubernetes in production
Keywords: Python, RAG, agents
`ashby:initech:c1`
...
Why company boards
Most tech companies post jobs through Greenhouse, Lever, Ashby or Workable, and most large employers through Workday (some through Eightfold, Oracle Recruiting Cloud, SmartRecruiters or a Jibe careers site), and many small companies through Rippling. Each publishes open roles as public JSON so anyone can build a careers page, with no API key or scraping; Google publishes its own (with YouTube's and DeepMind's) as an XML feed for job sites, Amazon's careers site (amazon.jobs, with AWS) answers its own search in JSON, and Avature careers portals (company career sites on Avature) list every posting in a sitemap for search engines. Hundreds of startups post once a month in Hacker News' "Ask HN: Who is hiring?" thread, which HN's search API serves whole. jobwatch reads those feeds for the companies on your watchlist:
- Complete and fresh: a role appears as soon as the company posts it, not when an aggregator picks it up.
- Pay ranges: read from the board's structured fields where they exist (Lever, Ashby), otherwise from
the posting text. An hourly wage counts as the yearly pay it comes to (2,080 hours), so
$75–$80/hris held tomin_salaryas $156K–$166K. - Polite: one request per company per run on Greenhouse, Lever, Ashby and Workable (a Jibe site: one per 100
roles). A Workday, Eightfold or Oracle board can
list thousands of roles, most of them nothing like yours, so jobwatch searches it for your
filters.titleswords and reads a posting in full only when its title passes your title filters, once: after that, a run costs a few searches per company. Titles written as regexes can't be searched for, so keep a plain word or two ("engineer", "data platform") among them. A board that answers "too many requests" (HTTP 429) is asked again after a pause; a posting it still won't serve is kept without its text and read on the next run. Eightfold boards are read one request at a time; a posting's own "work site" line (days in the office, or how much is from home) decides whether it is remote, and up to 100 stored postings per board are re-read each run until they have it. Google's feed is every role it has, one request (about 20 MB) a run; jobwatch keeps the ones whose titles have yourfilters.titleswords, in the US unless the board isgoogle/any. Amazon is searched like a Workday board, newest roles first and 100 a request, one request at a time; each result has the role's full text, so nothing more is read. It keeps US roles unless the board isamazon/any. A SmartRecruiters board is searched the same way, 24 titles a page, and each posting it reads is one page. An Avature portal's sitemap is one request a run; a posting whose title has yourfilters.titleswords and passes your title filters is read from its page, once, two at a time. HN's Who is hiring is one request to find the thread and one to read it whole. - Within the rules: it reads public APIs meant for this, and follows robots.txt. SmartRecruiters' own API
host asks crawlers to stay away, so jobwatch doesn't use it: it reads the company's public careers site
(careers.smartrecruiters.com, and each posting's page on jobs.smartrecruiters.com), which robots.txt leaves
open. On an Avature portal it reads only the public pages its robots.txt lets robots read (never a link with
qtvc=, never anything behind a sign-in). It doesn't scrape LinkedIn or Indeed, which forbid it.
Install
pip install jobwatch                 # discovery, filters, digest
pip install 'jobwatch[score]'        # + fit scores with shortlist-ai (Claude API)
pip install 'jobwatch[local]'        # + fit scores on-device (Apple Silicon, MLX)
pip install 'jobwatch[mcp]'          # + MCP server for Claude and other assistants
Quick start
In your browser
pipx install jobwatch      # or: pip install jobwatch
jobwatch ui
A page opens on your computer. Add the companies you want to watch (type a name or paste a link to one of their jobs), say what you're looking for, and press Check for new jobs. From there:
- Today: new matching jobs, with pay, how long ago they were posted, keywords, and who you know there.
It leads with today's picks: the top 10 in the order you sort by (best fit, newest or top pay), since
a few good applications a day beat a long list. Show all opens every match, and the search and
company filter always look through all of them. A line says how many you've applied to today against your
pace ("Applied today: 1 of 3"). Queue the ones worth applying to, Skip the rest. While the page is
running it checks the boards by itself every 6 hours (
fetch_everyin the watchlist), and Today says when they were last checked. A job that disappears from its board drops off Today at the next check. Companies to watch, at the side, lists companies whose jobs keep coming in from alerts or Hacker News posts while you don't watch them (see Companies to watch). - Queue: your short list. Apply on the company's site, then press I applied. The pace line counts it: once you reach your 3 for the day it says so, and at 5 that the rest can wait until tomorrow. It's advice; nothing is ever blocked.
- Long lists come in pages (12, 24, 48 or 96 at a time, kept per browser).
- Applications: every job you applied to and where it stands (applied, screening, interviewing, offer, rejected, withdrawn), with the next step and a follow-up day. Those due come first. Filter by status with the chips over the list (or click the pipeline bar), and switch between Cards and a sortable Table. Add an application covers jobs you found elsewhere, such as a referral or a recruiter.
- Settings: the whole watchlist, one card per part, with a bar that jumps to each card and keeps Save in reach: the companies you watch (with each one's name and careers link) and how often to check them; filters (titles, places, departments, pay, age, minimum fit score, and warnings to flag in a posting); keywords; how many picks Today shows and your daily pace; your resume, where fit scores run, their model and the prompt that scores fit; your LinkedIn connections; the chat's model, reply length and instructions; expected pay; job-alert emails from a mailbox; Companies to watch and Skills to build; and the page's theme (system, light or dark) and width (standard, wide or full, for a big monitor). Each setting says in a line what it does, a blank one shows its default, and a bad value is refused with why, leaving the file as it was.
- Ask jobwatch: a chat on Today (about all of today's jobs and your applications) and beside each job's details (about that posting). See Chat.
The page only talks to jobwatch on your own machine. The one exception is a model you choose: with
scoring.backend: claude, fit scores and chat send the posting and your resume to Anthropic (and
drafted prep, your stories too). It's the same
watchlist file and history as the command line, so you can switch between the two.
To have the page always there, even after a restart, on a Mac:
jobwatch service install      # starts jobwatch ui when you log in, and again if it stops
jobwatch service status       # running? where's the log?
jobwatch service uninstall
Running like that, the page keeps Today fresh on its own: it checks every board when it starts (if the last
check, from the page or jobwatch fetch, is older than fetch_every) and again every 6 hours. Each check asks
each board the same as pressing Check for new jobs, and pressing the button while a check runs waits for
that one rather than starting another.
A login item doesn't see variables set in your shell profile, so with scoring.backend: claude the page's
chat and scores need ANTHROPIC_API_KEY given to launchd (launchctl setenv ANTHROPIC_API_KEY ...), or
run jobwatch ui from a terminal instead. The local backend needs nothing.
On the command line
jobwatch init                         # writes an example jobwatch.yaml
jobwatch find "Globex" "Scale AI"   # find each company's board
jobwatch find https://jobs.lever.co/spotify/4f1c2a9e-...   # or paste any job link
find prints a line like Globex: greenhouse:globex (627 open roles). For a Workday company it tries
the usual site names; if that finds nothing, paste a job link from their careers site (it has
myworkdayjobs.com in it) and find reads the board from it: workday:nvidia.wd5/NVIDIAExternalCareerSite.
An Oracle Recruiting Cloud site is found the same way, from a job link with oraclecloud.com/hcmUI/CandidateExperience
in it: oracle:eeho.fa.us2/CX_45001.
A company's own careers page works too (jobwatch find https://careers.acme.com/jobs): find reads it for
links to a board, which is how a board under a name nobody would guess turns up. Add those
entries under companies:, adjust the filters, then:
jobwatch run # fetch every board, then show the digest
Run it daily, for example from cron: 0 8 * * * jobwatch run -o ~/jobs-today.md.
The watchlist
companies:
  - greenhouse:globex
  - lever:spotify
  - {source: ashby, board: initech, name: Initech}
  - {board: ashby:acme, careers: https://acme.example/careers}  # job links go to its own site (see below)
  - workable:acme                                       # apply.workable.com/acme
  - {source: workday, board: nvidia.wd5/NVIDIAExternalCareerSite, name: NVIDIA}  # tenant.wdN/site
  - {source: eightfold, board: acme, name: Acme}      # tenant (or tenant/domain), from a link
  - {source: jibe, board: careers.acme.com, name: Acme}  # a Jibe site's host (job links: /careers-home/jobs/...)
  - rippling:acme                                       # ats.rippling.com/acme/jobs
  - google:google                                       # Google, YouTube, DeepMind in the US (google/any: all)
  - amazon:amazon                                       # Amazon and AWS in the US (amazon/any: all)
  - {source: oracle, board: eeho.fa.us2/CX_45001, name: Oracle}  # pod.fa.region/site, from a job link
  - smartrecruiters:Initech                             # careers.smartrecruiters.com/Initech
  - {source: avature, board: careers.initech.example/careers, name: Initech}  # an Avature portal: host/portal
  - hn:whoishiring                                      # HN's Who is hiring thread (whoishiring/3: last 3 months')

filters:
  titles: ["engineer", "architect"]       # regexes; the title must match one
  exclude_titles: ["intern", "manager"]
  exclude_departments: ["sales"]
  locations: ["remote", "Denver", "Boulder, CO"]
  remote_country: US                      # remote roles must be open in the US ("any" to allow all)
  home_state: CO                          # leave out remote roles open only in other states (or "Colorado")
  min_salary: 200000                      # the top of a listed range must reach this
  require_salary: false                   # true: drop postings without pay
  max_age_days: 30
  min_fit: 70                             # hide jobs whose fit score is below this; unscored jobs still show
  flags:                                  # not filters: a warning on queued jobs whose posting says this
    "active (TS|top secret)": clearance
    "on-?site 5 days": on-site

keywords:                                 # relevance: title hits count double
  LLM: 3
  RAG: 3
  Python: 2
  "re:agent(s|ic)?": 2                    # "re:" prefix = regex

resume: ~/Documents/resume.pdf            # for fit scores
connections: ~/Downloads/linkedin.zip     # who you know at each company (see below)
scoring:
  backend: claude                         # or local (the default)
  # model: ...                            # the model fit scores use; default: shortlist-ai's for the backend
  top: 5                                  # score the 5 most relevant new jobs per digest
  auto: true                              # the page scores every new match in the background
chat:                                     # Ask jobwatch; leave any of these out for its default
  backend: local                          # claude or local; default: scoring.backend
  claude_model: claude-sonnet-5-5
  local_model: mlx-community/Qwen3.5-9B-MLX-4bit
  max_tokens: 1500                        # the longest reply
  max_turns: 24                           # the latest messages of a conversation sent with each question
  # prompt: ...                           # its instructions (Settings > Chat); must keep {today} and {context}
stories: ~/Documents/stories.yaml         # your projects, for drafted prep answers (see Prep sheets)
prep:                                     # drafted prep (`jobwatch prep KEY --draft`), with the chat's model
  max_tokens: 4000                        # the longest draft
  # prompt: ...                           # its instructions; must keep {context}
pay:                                      # expected pay from Levels.fyi: off unless levels is true (below)
  levels: true
  years: 12                               # your years, for a title with no seniority word
  # region: new-york-city-area            # a Levels.fyi location, for remote jobs and ones near you
  ask_over: 10                            # ask this many percent over the level's median base
  round: 5000                             # rounded up to this (0: not rounded)
  today: 15                               # how many of Today's jobs get looked up
suggestions:                              # Companies to watch
  half_life: 30                           # days: a job this old counts half as much as today's
  limit: 10                               # how many companies are listed
learning:                                 # Skills to build
  timeline: quarter
  jobs: 5                                 # example jobs listed with each skill
display:                                  # the browser page
  theme: system                           # system, light or dark
  width: standard                         # standard, wide or full
  today: 10                               # Today's picks, and the digest's length; 0 shows every match
pace:                                     # applications a day: counted on Today and the queue, never enforced
  daily: 3                                # 0 turns it off, for when job hunting is your full-time job
  max: 5                                  # from this many on, the rest can wait until tomorrow
fetch_every: 6h                           # the page checks the boards this often (90m, 1d; off to stop)
Relative paths are resolved from the watchlist's folder. State (which jobs you've seen, applied to or
skipped, and their scores) lives in one SQLite file, by default ~/.local/share/jobwatch/state.db. Settings
shows where it and the cache are; change them in the file (a new state path starts an empty history).
pay: {levels: true, years: 12} (off by default) adds an estimate of a queued or viewed job's level and pay from
the company's public salary pages on Levels.fyi, with a link to the page. The ask it suggests is
pay.ask_over percent over the level's median base, rounded up to pay.round, kept within a posted range. It's meant for personal use: you're
responsible for checking Levels.fyi's terms. What's read stays in the state file and is never put in a digest.
Data: Levels.fyi.
fetch_every (6 hours unless set, at least 1 hour) is how often the browser page checks the boards while it's
open; off (or 0) leaves it to you and jobwatch fetch.
When a company's job pages are offline
Some companies keep listing jobs on their Ashby board while Ashby's own job pages for them say "Page not
found" (they've moved applying to their own site). jobwatch looks at the board's Ashby page once a day while
it fetches. If it's offline, jobwatch fetch warns about that board, and each of its jobs says to apply
through the company's own careers site (on Today, in a job's details, in jobwatch show and to an AI
assistant). Add the company's careers site to the board, {board: ashby:acme, careers: https://acme.example/careers}, and its jobs link there instead. If the page can't be read, nothing changes.
Hacker News' Who is hiring
hn:whoishiring watches the latest monthly "Ask HN: Who is hiring?" thread; hn:whoishiring/3 the last three
(up to 12). It's read from HN's search API (hn.algolia.com), which robots.txt allows: one request finds the
threads and one reads each whole, so a run never asks for a post at a time. Each company's post is one job, named
after its company, with every role its first line names in the title ("Senior Engineer, Designer"; roles
listed further on when the first line has none). The place, remote and pay come from that first line
(Acme | Senior Engineer | Remote (US) | $180k-$220k | link), and the post's text is the description. The job
links to the company's own job page when the post has one (a posting on a board jobwatch reads first, then that
board, then a careers page), else to the post on HN. Boards it links to are noted with the job, not read: a
company whose post passes your filters shows up under Companies to watch, with the board
its post links to when there is one. A post that's deleted or flagged is gone from the thread, so its job closes;
an edited one is read again. Replies, remarks and job seekers' posts aren't jobs. The first line is free text,
so a post written in sentences may come out as "Open roles (see the post)". Posts aren't fit-scored: one lists
several roles, places and links, which a score would read as one job's must-haves; watch the company's board to
score each role.
How locations match
A posting can list several places (London, UK; Remote-Friendly, United States; Austin, TX), and each one
is checked:
remotematches a place that says remote and is inremote_country, or says only "Remote". It also matches a posting whose own remote flag is set and that lists a US location.- With
home_stateset, a remote role open only in some states is left out unless yours is one of them, and one open only in your state ("Remote - Colorado") counts as remote. The states come from the posting's places ("Remote - Texas", or a remote posting that lists only states) and its text ("Remote locations: California, USA; Nevada, USA", "remote in CA, NV, OR or WA", "must reside in one of the following states: ..."). Today's filter bar says why: "remote only in CA, NV, OR, WA". - Any other entry matches as text, so
DenvermatchesDenver, CO, United States.
Fit scores
Keyword relevance is fast and explainable, but it can't tell "uses Kubernetes" from "5+ years running
Kubernetes in production". With resume: set and scoring.top (or --score N), the most relevant new
jobs are scored with shortlist-ai:
- It turns the posting into must-have and nice-to-have requirements.
- It judges each requirement against your resume, with quotes it checks against the resume text.
- It lists the must-haves the resume doesn't show.
Scores are stored per resume file content, so each job is scored once, and again only after you edit your
resume. The local backend takes a minute or two per job, so keep top small.
While jobwatch ui runs, it scores every matching job in the background, most relevant first and one at a
time: when the page starts, after each "Check for new jobs", and after you add a new resume. Today shows
how many are left, and a button brings in the new scores when you're ready (the cards don't move on their
own). A chat reply or a "Score fit" click goes first; background scoring waits for it. It's on by default
with scoring.backend: local. With claude every score is a paid API call, so turn it on with
scoring.auto: true. jobwatch score [--limit N] does the same in the terminal.
A card with no score says why: in line to score (and where), no posting text, the same role scored before
this posting came in, or a failure. A job from an alert email may have only its title: "Add the posting"
takes a link to the company's posting (read when it's on a board jobwatch reads) or the pasted text, and so
does jobwatch mark <key> --url <link>. jobwatch unscored lists them all.
Each score keeps its reasons: every requirement, its verdict (met, partly, missing) and the resume's words
behind it. They're under "Why this score" in a job's details, at the end of jobwatch show <key>, and in
the MCP get_job result. Scores saved before jobwatch kept these have only the summary.
filters.min_fit (the Fit slider on Today's filter bar, and in Settings next to how many picks Today shows)
hides jobs scored below it, counted as "fit" in the hidden roles. Jobs not scored yet still show, since
scoring catches up in the background.
The fit score prompt
Settings → Fit score prompt shows what the model is told: each of shortlist-ai's prompts (reading the
resume, turning a posting into requirements, judging each requirement, counting years), each in a box you can
edit, with "Reset to default". Only the edited ones are saved, as scoring.prompts in the watchlist. The two
request templates must keep their {placeholders}; saving says so if one is missing. An edited prompt
changes scores from then on: scores made with other prompts are set aside and Today's jobs are scored again,
and putting the prompts back brings the old scores back. jobwatch score --show-prompts prints them.
Editing needs a shortlist-ai that takes edited prompts; with an older one they show read-only.
Chat
Ask questions in plain words: "which three should I apply to first?", "what follow-ups are due?", "how well
do I fit this one, honestly?", "what will they ask in interviews?". The chat runs where fit scores do,
unless chat.backend says otherwise:
local: the same on-device model as scoring (pip install 'jobwatch[local]'). Nothing leaves your computer. The first answer waits for the model to load.claude: Claude Sonnet via Anthropic's API (ANTHROPIC_API_KEY). Your question, your resume and the jobs it's about are sent to Anthropic.
Settings → Chat sets the model for each (chat.claude_model, chat.local_model), the longest reply
(chat.max_tokens) and how many of a conversation's latest messages go with each question
(chat.max_turns). Its instructions are there too, folded like the fit score prompts: edit them, or "Reset
to default". Only an edited one is saved (chat.prompt), and it must keep {today} and {context}, where
the date and the jobs it reads go.
It reads today's matching jobs and your applications, or one posting with its fit score and what you sent, plus your resume (the one you sent for that job, when it's kept). It's told to use only your resume for facts about you and to treat posting text as data, not instructions. It has no tools, so it can't change, apply for or send anything.
Under each reply are a copy button and what it took: seconds (and any wait for a background fit score to finish), tokens in and out, and on this computer tokens per second and peak memory. While a reply is on its way, a timer shows how long it's been against how long recent replies took. The download button in the chat's header saves the conversation as Markdown. The same thing works from the terminal:
jobwatch ask "What follow-ups are due this week?"
jobwatch ask --job c1 "What should my resume lead with for this one?"
Skills to build
Which skills do the jobs you're going after ask for that your resume doesn't show, and where can you learn them in the time you have?
jobwatch skills                     # gaps across today's matches and your applications
jobwatch skills --timeline month    # week, month, quarter (default) or any
jobwatch skills --all               # also the skills your resume already shows
The Skills tab in jobwatch ui shows the same, with a timeline switch, and each job's details link to it
from the gaps it lists.
Skills are ranked by demand: how many of your matching jobs mention one, with a must-have that a fit score found missing counting three times. Each comes with:
- curated courses and certifications from the official pages (AWS, Linux Foundation, DeepLearning.AI, Hugging Face, OWASP...), each with a rough time and marked if it's longer than your timeline;
- searches on LinkedIn Learning, Coursera, edX and, for AI skills, DeepLearning.AI;
- with a timeline of a quarter or more, certificate programs at colleges near you.
Fit-score gaps no course closes (a clearance, citizenship, a degree, travel) are listed apart, and so are must-haves asking for years of something: a course gives you something concrete to point to, not the years.
learning:
  timeline: quarter       # week, month, quarter or any
  near: Denver            # for colleges nearby; default: the first city in filters.locations
  jobs: 5                 # example jobs listed with each skill
The chat knows the top gaps too ("what should I learn this month?"), and a job's details list the skills that posting asks for that your resume doesn't show.
The apply queue
Pick the roles worth a tailored application from the digest and queue them. Work through the queue when you have time:
jobwatch queue c1 aaaa-1111 --note "ask for a referral first"   # add (the posting id is enough)
jobwatch queue                             # what to apply to next, oldest first
jobwatch show aaaa-1111                    # full posting text: for tailoring a resume
jobwatch mark applied aaaa-1111 --note "referred by a friend"   # after you submit
jobwatch mark skipped greenhouse:acme:102
jobwatch list --status applied
Queued jobs leave the digest. The queue flags any posting that has since closed, and what to check before
applying: pay below min_salary, a place your filters don't want (a job queued by hand never passed them),
and anything your filters.flags patterns find in the posting. Every fetch notices a watched board's
postings closing; jobwatch check also checks queued jobs and open applications from boards you don't
watch (a LinkedIn job can't be checked: LinkedIn's robots.txt doesn't allow reading its postings):
jobwatch check # closed (or back) since the last check; --all lists the open ones too
The same opening twice
One opening can reach you more than once: from its board and a job-alert email, under a new title, or
reposted under a new req after you applied. Every job a fetch, an alert import or jobwatch add brings in
is compared with the ones you've queued, applied to (or got further with) and skipped, at the same company:
- The same opening: the two share a req or posting id: in the title or posting text ("Req ID: R-0123456", "(482913)"), in the posting's link, or in your note on the other job (its link, "req 482913", or a note that it was reposted as another posting). The job is shown with "Already applied 2026-03-02", or "Reposted: you applied 2026-03-02 (old req …)" when your note says it was reposted.
- Possibly the same: only the title matches, setting aside dashes, a req in the title, "(Remote)" and a seniority word only one of them has. It's shown with "Possible duplicate of your 2026-03-02 application: check it's a different opening". Two postings on one board, two different reqs, or "Senior" against "Staff" are never matched by title.
Nothing is hidden: the job stays in the digest and the queue, with the badge in the browser and the warning
first among the queue's checks, in jobwatch show, and when you queue it (it's queued all the same). To
list every pair you track, without changing anything:
jobwatch dupes # --strong: only the ones sharing an id
Skip the one you don't need with jobwatch mark skipped <key>.
Jobs you found somewhere else
A job from LinkedIn, a job-alert email or a friend goes in the queue with its link. When the link is to a posting on Greenhouse, Lever, Ashby, Workable, Workday, Rippling, Google Careers, amazon.jobs, Oracle Recruiting Cloud, SmartRecruiters or an Avature portal, jobwatch reads the posting from there, so it can be fit-scored and prepped for like any other, even if you don't watch that company. jobwatch never reads LinkedIn (its robots.txt disallows every page), so a LinkedIn job link needs the company and title too; the same job is looked for on the company's own board: found, that's what is tracked, since it's where the application goes; not found, the job is kept with the LinkedIn link and the text you paste. For anything else (a company's own site), give the company and title and paste the posting's text:
jobwatch add https://apply.workable.com/acme/j/A1B2C3D4E5/ --status queued
jobwatch add "Umbrella" "Staff Engineer" --url https://www.linkedin.com/jobs/view/... --text posting.txt --status queued
pbpaste | jobwatch add "Umbrella" "Staff Engineer" --text - --status queued     # the posting from the clipboard
In the browser, press Add a job on the Queue page. Many job sites (LinkedIn's "Apply on company website", job-alert emails) link through to the company's own board: that link is the one to use.
Job-alert emails
The job alerts LinkedIn, Built In, Indeed and other job sites email you can go straight in. Save them from
your mail app (a .eml file each, a folder of them, or an .mbox export) and give them to jobwatch alerts:
jobwatch alerts ~/Downloads/alerts/ --dry-run      # what's in them, nothing recorded
jobwatch alerts ~/Downloads/alerts/                # track the new ones
pbpaste | jobwatch alerts -                        # one message's source, from the clipboard
Each job's title, company, place, pay and link are read from the email, with the tracking taken off the link. LinkedIn, Built In and Indeed alerts each have their own reader; any other sender's is read by its job links. A job that fails your filters on what the email says is kept as it is, so it's known next time, and nothing more is read for it. For the rest, jobwatch looks for the job where the application goes:
- A link to a company's board (Greenhouse, Lever, Workday and the rest) is read from there.
- A job site's link is read only if the site's robots.txt allows it. Built In's job pages are allowed, and their full posting is used. LinkedIn's and Indeed's postings aren't (robots.txt disallows them), so they aren't read: the email's details are used.
- Then the company's own board is looked for: one you watch, or one found by name, as
find_boardwould. If the same job is posted there, that's what is tracked, with the alert's link kept in its notes.
Jobs already tracked are left as they are: the same link, or the same company and title, from a board you
watch or an earlier alert. Each new one remembers where it came from (via linkedin-alert), passes through
your filters, and is in the next digest. Sponsored listings in Indeed alerts have no job id and are skipped.
--no-follow reads no links at all; --all lists every new job, filtered out or not; --format json is for
scripts. In Claude, import_job_alerts takes the messages (their source, or just the HTML) the same way.
jobwatch never asks for your email password. To read alerts straight from your mailbox instead, give it an IMAP account in the watchlist, with the password in an environment variable or the macOS keychain. It's off unless you set it. The mailbox is opened read-only, and messages are read without being marked read:
alerts:
  imap:
    host: imap.gmail.com           # Gmail needs an app password
    user: you@gmail.com
    keychain: jobwatch-imap        # security add-generic-password -s jobwatch-imap -a you@gmail.com -w
    # password_env: JOBWATCH_IMAP_PASSWORD   # or this, instead of keychain
    # folder: INBOX
    # days: 3                      # alerts from the last 3 days
    # senders: [jobalerts-noreply@linkedin.com, builtin.com, jobalert.indeed.com]
jobwatch alerts --imap
Companies to watch
jobwatch only checks the boards on your watchlist, so a company you never added is never checked, however good
its jobs. Alerts show which ones you're missing. Each job that comes in from an alert or jobwatch add, from a
company whose board you don't watch, is noted with its company; so is each new Hacker News post that passes your
filters, when you watch the Who is hiring thread. jobwatch suggest lists those companies, the
ones with the most jobs that pass your filters first (a job from last week counts more than one from last
season: one suggestions.half_life days old, 30 unless set, counts half), suggestions.limit of them (10
unless set; --limit 0 lists all), with a few of their titles and their board:
jobwatch suggest                       # companies to watch, and the board to add for each
jobwatch suggest --add Umbrella        # put its board on the watchlist
jobwatch suggest --dismiss Hooli       # don't suggest it again
After changing your filters, or for HN posts fetched before they were noted, jobwatch suggest --rescan notes
the companies of the open posts already in the state file first (nothing is read from the web; running it again
counts nothing twice).
The board is the one a job was found on when the alert import matched it there (or the one an HN post links
to), else one found under the
company's name the way jobwatch find looks (check its titles: a guessed name can belong to another company).
Each company is looked for once, and what's found, or that nothing was, is kept in the state file. --no-lookup
lists what's known without looking. When no board turns up, give jobwatch find a link to its careers page.
--add rewrites the watchlist the way Settings does, keeping the old one as .bak (comments in a hand-written
file aren't kept). On the page, the same list is on Today with Add and Dismiss; in Claude,
list_suggested_boards gives each company's add_board arguments, and dismiss_suggested_board drops one.
Tracking applications
An application moves through stages: applied, screening, interviewing, offer, and then rejected
or withdrawn. Each can have a next step and a day to follow up. Jobs you found somewhere jobwatch doesn't
watch (a referral, a recruiter, LinkedIn) go in with add, so every application is in one list:
jobwatch add "Umbrella" "Principal Engineer" --url https://... --on 2026-09-14 --note "via a recruiter"
jobwatch add https://job-boards.greenhouse.io/acme/jobs/101 --on 2026-09-20   # read from the link
jobwatch mark screening c1 --next "technical round" --follow-up +7   # or a date: 2026-10-05
jobwatch mark rejected principal-engineer
jobwatch mark umbrella interviewing   # the company is enough when you applied there once
jobwatch mark withdrawn c1 --add-note "recruiter says onsite only"   # adds a dated line; --note replaces
jobwatch mark c1 --add-note "interview Friday 10:30" --follow-up 2026-10-08   # no stage: it stays as it is
jobwatch mark principal-engineer --text posting.txt   # its posting, found later, for scoring and prep
jobwatch applications            # every application, follow-ups due first (alias: apps)
jobwatch applications --due      # only the ones to act on today
The day you applied is kept as an application moves through the stages. --next "" or --follow-up ""
clears a field. An application added by hand with only a company and a title can get its posting's text
later with --text (a copy from a job board, or - to paste it), so it can be scored and jobwatch prep
has something to work from; the posting kept with the application is replaced with it.
Every company on Workday has its own careers site with its own sign-in, so after a few applications it's hard
to remember where each one lives. For a Workday application, jobwatch show, jobwatch applications and
the job's Details link that company's candidate page (.../userHome), where you sign in to see its
status. jobwatch keeps only the link, never a login or password: your password manager saves each company's
login under that company's own address. For one you added by hand whose posting has since come down, give
it the company's careers site (jobwatch mark <key> --url https://acme.wd1.myworkdayjobs.com/Careers)
and the page link follows.
What you sent
Each application keeps what you submitted, as copies:
- the resume and cover letter exactly as uploaded;
- the answers you gave on the form (salary expectation, why this company, notice period...);
- the posting as it read the day you applied.
Tailored resumes get rebuilt and postings change or come down. When a recruiter calls three weeks later, this is what they're looking at. The chat reads it too, so "prep me for the recruiter call" works from what you actually told them.
In the browser, open an application's Details and drop files into What you sent. From the command line:
jobwatch mark applied c1 --attach ~/Downloads/Resume_Initech.pdf
jobwatch attach c1 cover-letter.pdf --answers answers.yaml    # answers.yaml: "Why Initech?: ..." pairs
jobwatch package c1                                         # show it
Packages live in packages/<job>/ next to the state file. Removing a file moves it to .removed/ there
rather than deleting it.
Prep sheets
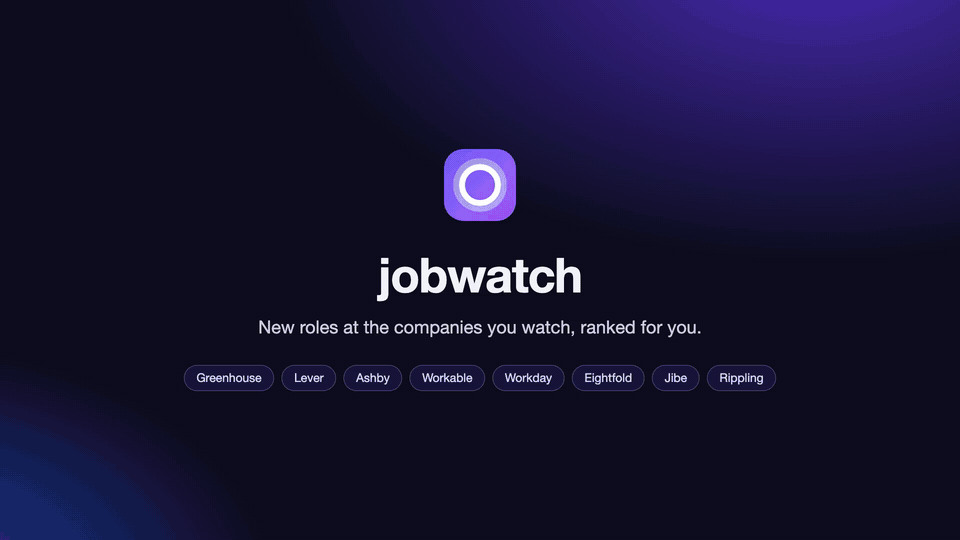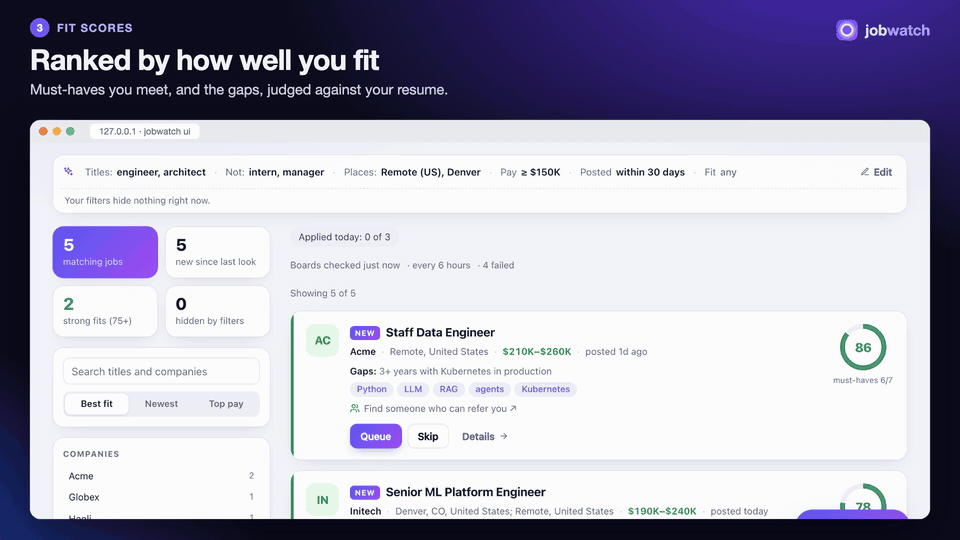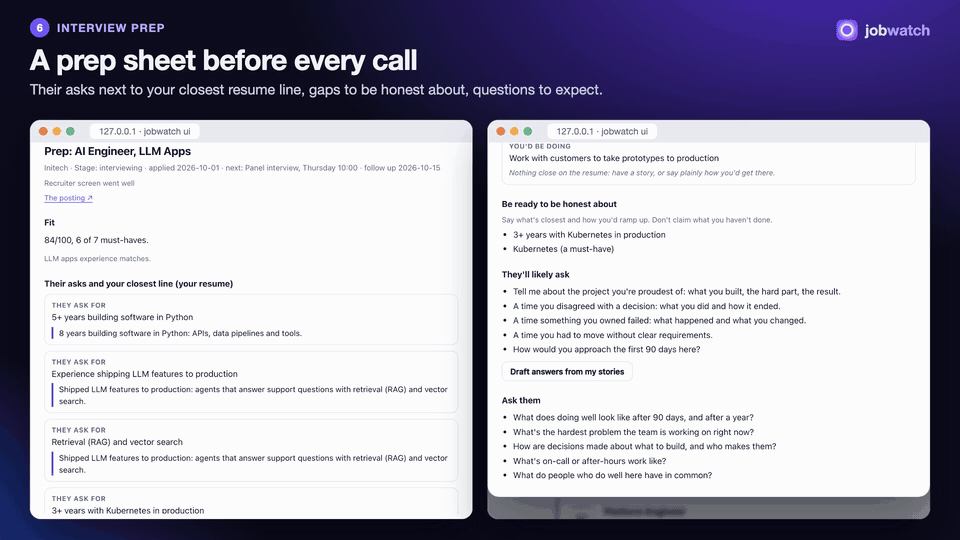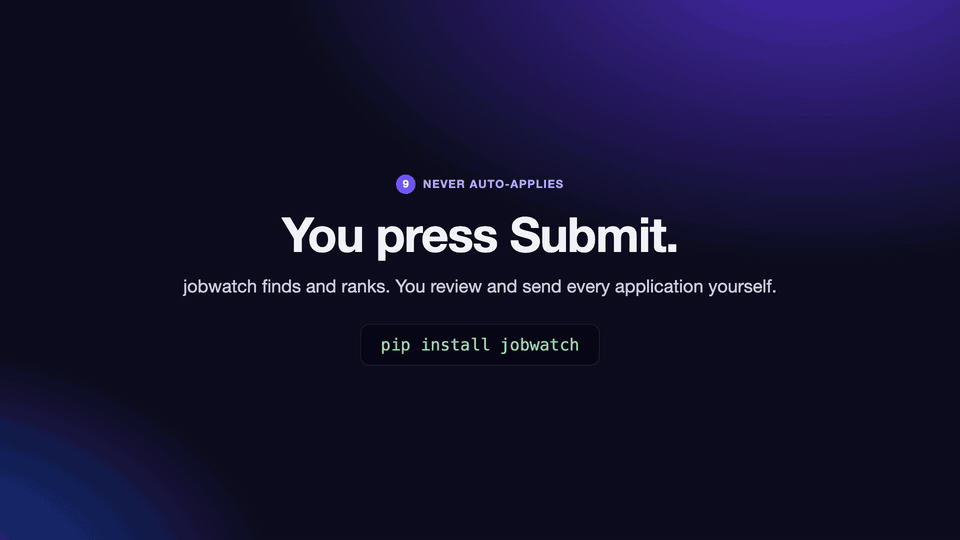
Before a recruiter call or an interview, open the application's Details and press Prep sheet (or run
jobwatch prep c1). One page, ready to print, with:
- the stage, next step and your notes;
- each requirement and responsibility in the posting, next to the line on your resume closest to it (the resume you sent, if you kept it), or a plain "nothing close" so you can prepare a story or an honest answer;
- skills they ask for that your resume doesn't show, with the fit score's missing must-haves;
- what you sent;
- questions to expect and questions to ask, for a screen or for interviews.
Open as page (or jobwatch prep c1 --open) shows it as a standalone HTML page that prints cleanly on Letter
paper; --format html -o prep.html saves that page, and the default --format md prints Markdown.
Nothing on it is written for you: it quotes the posting and your resume. For an application you added by hand,
jobwatch looks for the posting on your watched boards by the requisition id in its title (R0123456,
REQ-4711, Job 20769), so a Workday posting fetched later fills in the sheet.
Drafted answers from your stories
jobwatch prep c1 --draft adds the one part that is written for you, and only from what you've written
yourself: 6 to 10 questions this role is likely to bring up, each with the requirement it probes, and an
answer outline built from your stories and your resume, naming the stories it used. A question none of them
answers says "no story yet", with one honest line: what's closest, and how you'd ramp up.
Your stories are a YAML file you write once and point the watchlist at (stories: ~/Documents/stories.yaml).
Each is a project you'd talk about on a call:
- id: alert-dedupe                    # what answers cite it by
  title: Cut duplicate on-call alerts
  did: Built a Python service that groups alerts about the same incident before they page anyone.
  hard: The teams named the same hosts three different ways.
  result: Pages per week went from 120 to 35 in two months.
  skills: [Python, Kafka]             # optional
examples/stories.yaml has a few more, made up. A mistake in the file (a missing
result, two stories with the same id) is reported with the story and what to fix.
The model is told never to invent experience, numbers, employers or credentials, and its answer is checked anyway before it reaches the sheet:
- an answer citing a story you don't have is dropped;
- a point with a number that's in neither the stories it cites nor your resume is dropped (a number is what you'd repeat word for word, so it isn't just flagged);
- an answer left with no story becomes "no story yet";
- it's cut to length, and a reply that isn't the JSON asked for gives no drafts. The sheet says what was taken out. With no model, an error or nothing usable, it keeps the usual questions: prep never fails because the model did.
It uses the chat's model (chat.backend): local keeps everything on your computer; with claude the
posting, your resume and your stories go to Anthropic. A draft takes a while, so it's kept in the state file
and opening the sheet again reads it; a change to the posting, resume, stories, stage, model or instructions
drafts afresh. Its instructions are drafts.PROMPT, or your own in prep.prompt (keep {context}, where the
posting, resume and stories go); prep.max_tokens (4000) is the longest draft. MCP clients ask for it with
get_interview_prep's draft_answers.
Who you know there
A referral gets read before an application does. Download your LinkedIn data (Settings → Data privacy →
Get a copy of your data) and upload the archive in jobwatch ui, or point connections: at the .zip or
at its Connections.csv. Each digest and queue entry then lists your connections who work there:
You know: Ana Li (Staff Engineer) [messaged 14×, last 2025-03-02]; Bo Chen (Recruiter)
With the full archive, people you actually talk to come first. jobwatch counts the messages you exchanged, recommendations and endorsements, so a close colleague ranks above someone who only accepted a connection request. Only those counts are kept, never your messages. When you know nobody at a company, the page links to a LinkedIn search of your 2nd-degree network there, to find someone who can introduce you.
Companies are matched by name, ignoring suffixes like "Inc." and "Corporation". Your LinkedIn data is only read on your machine.
A digest lists each job once, the top display.today (10) of them, and ends with how many more match;
those stay new for the next digest. Use digest --all for every match, including jobs already shown,
--limit N for another number, or --peek to look without marking them shown. Roles that disappear from a
board are marked closed. The MCP get_digest returns the same top 10 by default, with today's pace.
MCP server
jobwatch-mcp offers these tools to Claude Code or any MCP client:
- Watchlist:
find_board,list_boards,add_board,remove_board,list_suggested_boards,dismiss_suggested_board - New jobs:
fetch_jobs,import_job_alerts,get_digest,get_job,list_jobs,list_skill_gaps - Applying:
mark_job,list_queued_jobs,check_postings,add_application,list_applications,find_duplicates(get_jobandlist_queued_jobsgive each job'sduplicate_of) - What was sent:
save_application_package,get_application_package,get_interview_prep
(0.3.0 renamed them to verb_noun: digest is now get_digest, job_details is get_job, apply_queue is
list_queued_jobs, applications is list_applications, application_package is get_application_package,
interview_prep is get_interview_prep and skill_gaps is list_skill_gaps.) The watchlist comes from
JOBWATCH_CONFIG:
claude mcp add jobwatch -s user -e JOBWATCH_CONFIG=~/jobwatch.yaml -- jobwatch-mcp
jobwatch mcp runs the same server. Without installing anything first,
uv can fetch and run it:
claude mcp add jobwatch -s user -e JOBWATCH_CONFIG=~/jobwatch.yaml -- uvx --with 'mcp>=2.2' jobwatch mcp
It's listed in the MCP Registry as io.github.vinayvobbili/jobwatch.
With a resume tool alongside it (for example resume-kit, whose
resume draft starts a tailored version from a posting), an assistant can work through your queue: read
the posting, tailor the resume from facts you've confirmed, check for a referral, and fill in the
application for you to review. You still press Submit.
Why it doesn't auto-apply
Tools that auto-apply to hundreds of jobs make the process worse for everyone and rarely work for the person using them:
- Recruiters recognize mass applications.
- Some companies cap how many roles one person can apply to.
- Application forms ask legal questions (work authorization, export control, signatures) that you answer yourself.
jobwatch's job is to make sure you never miss a role worth applying to, and to spend your time on those.
Development
python -m venv .venv && .venv/bin/pip install -e '.[dev,mcp]'
.venv/bin/ruff check . && .venv/bin/python -m pytest -q
CI tests on Python 3.10 and 3.13. scripts/check runs the same checks on both locally (it needs
uv, which fetches each Python). git config core.hooksPath .githooks runs it before
every push.
Tests use canned board responses and never touch the network, except the check that every curated course
link still resolves: JOBWATCH_LINK_TESTS=1 pytest tests/test_learn.py. To see how jobwatch ui looks after a change,
scripts/screenshots.py captures every tab in light and dark, at wide, desktop and phone widths, plus the
chat with a canned reply (it needs
pip install playwright && python -m playwright install chromium).
scripts/demo/make-video rebuilds the demo video from made-up data: see
scripts/demo/README.md.
Releases publish to PyPI through Trusted Publishing when a v* tag is pushed, and then to the MCP Registry
from server.json (keep its two versions in step with the package; a test checks).
scripts/release.py 0.2.3 -m "what's in it" does the whole release: it bumps all three versions, runs
scripts/check, commits, tags, pushes, and waits until PyPI and the registry show the new version
(--dry-run shows the bump first).
MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for jobwatch 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| jobwatch-0.5.0.tar.gz | 405.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| jobwatch-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 662.7 kB
Release files / jobwatch-0.5.0.tar.gz
| Download URL | jobwatch-0.5.0.tar.gz |
|---|---|
| Size | 405.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ab6bebdee59007a58c372be75ae342f6578bc410c67343b92e1af23b7cdf524a
|
|
BLAKE2b-256 checksum How to use checksums |
dc8fff8bc5dd60eb451ba900a9830cdb68cfc49f3f13bdce8e94ed723d9858d9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency logRelease files / jobwatch-0.5.0-py3-none-any.whl
| Download URL | jobwatch-0.5.0-py3-none-any.whl |
|---|---|
| Size | 257.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
697345aef9d622815a87609589943faaf5bf35e1253ab078d99d729092d01767
|
|
BLAKE2b-256 checksum How to use checksums |
e0d19d87b384481d17bb808e8334ea7a8a244a39a829b29cc8596db834e9d93f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency log












