
JuL — Just use Less
Typed decisions on your machine, with the model of your choice.
No training, no API, no task learned by heart.



Website · Quickstart · Showcases · Results · Docs
JuL is a Python library that answers typed questions about a piece of text: pick an option
(Choice), say yes or no (Noul), give a score (Score). Each answer comes with a probability. It
has the same API as the SDK of Jev, TypeSafe's hosted decision model.
The model is stopped one step before its first syllable and the answer is read straight out of its hidden states: no monologue, no reasoning trace, no opinion on the matter. It has nothing to say, and it says it in 55 milliseconds.
It runs on your own machines, from a Mac to a Linux server, so you can keep it running 24/7 on your own infrastructure. Your text never goes to a third party and there is no per-call bill. The model weights are downloaded once from the Hugging Face Hub, or loaded from a local path; after that it runs with no network at all.
Why JuL
- Zero-shot: the default model scores 0.857 on Jev's public benchmark (Jev: 0.753) without one example
of its tasks. Its settings were fitted on dev sets the benchmark never touches. On AG News, the one
task embedding models haven't trained on, the default gets 0.90,
wemm-4b0.95 and Jev 0.91. - Close to Jev on typed decisions:
jul-decision-wemm-4b, the default model on PyTorch, answers 0.849 of 2,108 Choice, Noul and Score questions over 12 task families, Jev 0.873, at 97 ms per decision on one A10G GPU (per family). On a bench of 300 typed questions written from scratch (sentiment, finance, support, agent routing, moderation) it answers 0.677, andjul-decision-minicpm5-2b(aliasfast), half its size, 0.680 at 85 ms. - Many options: option vectors are computed once and cached, so adding options barely changes the cost of a call. On Banking77's 72 intents the default model gets 0.87, on a task its training data (MTEB) contains.
- Probabilities you can use: ECE 0.084, so you can automate above a confidence threshold and send the rest to a human.
- Small and fast: 2.6 GB and 55 ms per decision on a Mac.
f2llm-1.7b(converted locally, not published yet) fits in 1 GB and answers in 24 ms. - Replaceable model: we measured 18, and
jul models addwires in a new one without touching your code. - Tunable when you have labels:
autotune(...)takes the default model from 0.857 to 0.897 with 1000 examples, and keeps the head only if it beats zero-shot. - Drop-in for the Jev SDK: change the import and the same code runs on your machines.
jul servespeaks the Jev HTTP protocol for other languages.
Quickstart
# from typesafe_sdk import TypeSafeClient, Choice, Noul, Score
from jul import TypeSafeClient, Choice, Noul, Score

client = TypeSafeClient()                             # jul-decision-wemm-4b, or model="minicpm5-2b"

response = client.system_one(
    state={"ticket": "I was charged twice for my subscription this month."},
    questions={
        "team": Choice(instructions="Which team should handle this ticket?",
                       criteria={"billing": "payments, invoices, refunds",
                                 "technical": "bugs, errors, crashes",
                                 "sales": "pricing, plans, demos"}),
        "is_bug": Noul(instructions="Does the message report a software bug?"),
        "frustration": Score(instructions="How frustrated is the customer?",
                             criteria=["Calm", "Frustrated but civil", "Very angry"]),
    },
)

response.choices["team"].choice           # "billing"
response.choices["team"].probabilities    # {"billing": 0.88, "technical": 0.11, "sales": 0.01}
response.nouls["is_bug"].noul             # 0.12
response.scores["frustration"].score      # 1.15
The model compares your text with each option's description, so write descriptions a colleague
would understand; the key is only the name you get back. noul is the probability of yes, and score
is the expected level on your scale, from 0 ("Calm") to 2 ("Very angry"). AsyncTypeSafeClient has the same API.
Arguments that only make sense for a remote API (api_key, retry, …) are accepted and ignored, so
code written for Jev runs unchanged.
From the shell, use jul ask. Non-Python callers can use jul serve, which speaks the Jev HTTP
protocol (docs/serve.md).
Showcases
Eight demos from jul-showcases, each an idea from jevable.com running entirely on device, for $0.
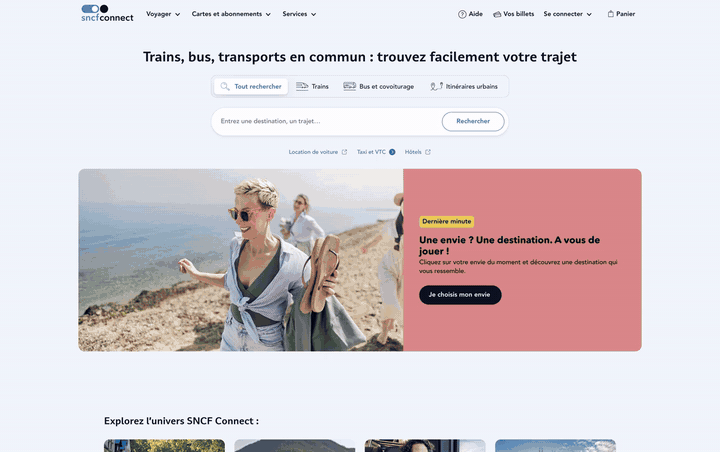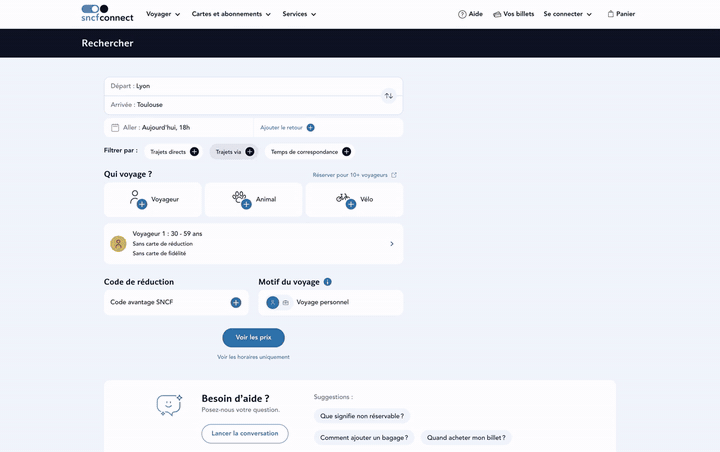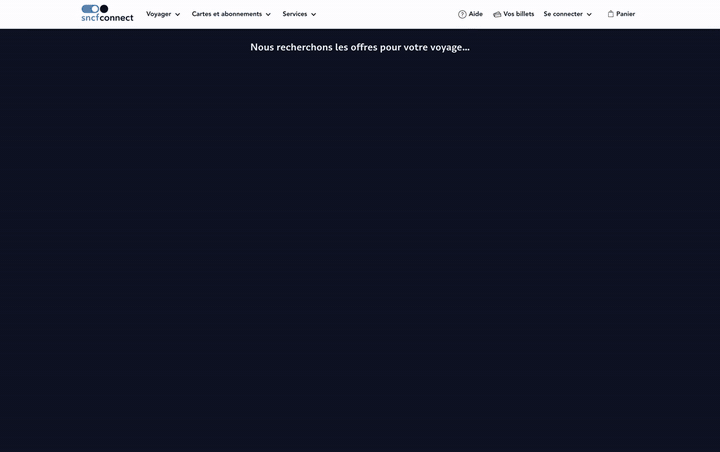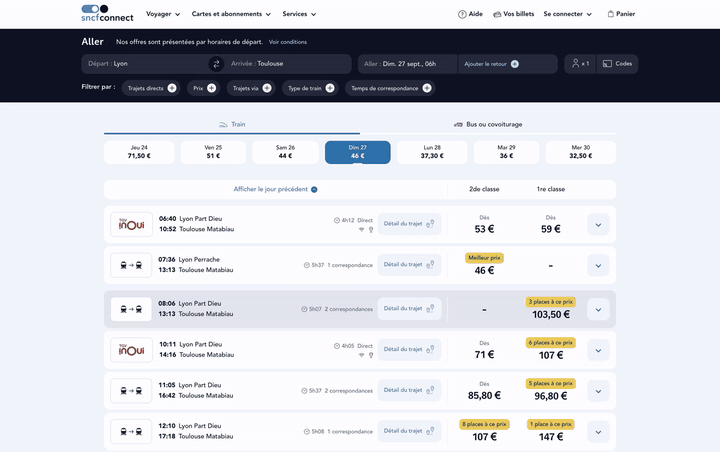 Browser agent on SNCF Connect. JuL picks each action from the page's accessibility tree and the Apple Foundation Model types the city names (macOS 26). Six steps from the homepage to priced results, about 130 ms per decision. |
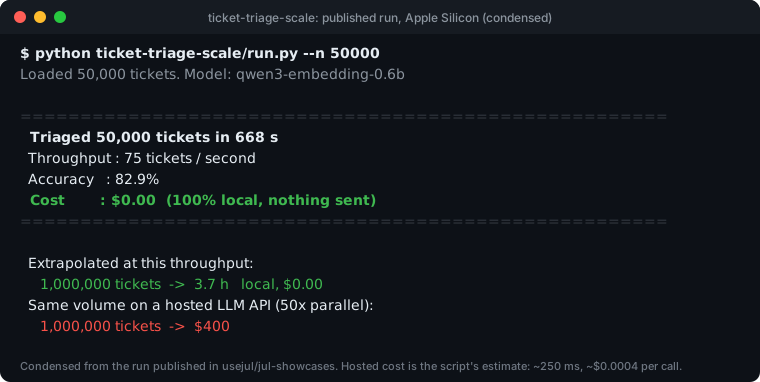 Ticket triage at scale. 50,000 real support tickets routed in 668 s, 82.9% accurate, for $0, with the small qwen3-embedding-0.6b on an Apple Silicon Mac. At
that rate a million take about 3.7 hours.
|
- Browser agent: books a train on SNCF Connect from its accessibility tree.
- QA from the ticket: runs a plain-language acceptance test in a real browser.
- Ticket triage at scale: 50,000 real support tickets in 668 s, $0.
- Ticket triage with autotune: a fast model goes from 82.0% to 96.5% with a head trained in 6.2 s.
- Self-branching form: picks the next question from the answers so far.
- Intent re-ranker: sorts a list by a plain-language intent.
- Notification triage: mutes marketing, keeps OTPs and appointments.
- Prompt difficulty: routes a prompt to fast mode or the full model before it is sent.
Install
pip install jul
jul setup          # picks MLX or PyTorch, installs it, downloads the default model, runs one decision
Python ≥ 3.10. The default model weighs 2.6 GB and is downloaded once from the Hugging Face Hub.
To pick the backend yourself (jul[mlx], jul[torch], jul[onnx]), see
docs/installation.md.
How it works
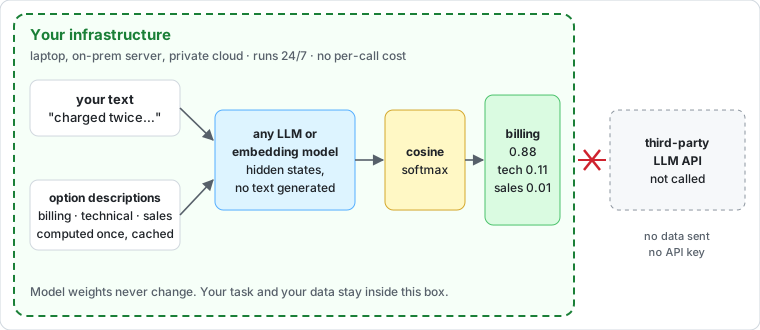
JuL reads the hidden state the model built for your text and compares it with the vectors of your
option descriptions. Your task never reaches the weights, so you can change the options between two calls, or swap the model, without retraining
anything. When it is off on your data, client.autotune(...) fits a small head on labeled examples
and keeps it only if it beats zero-shot in cross-validation
(docs/tuning.md).
Results
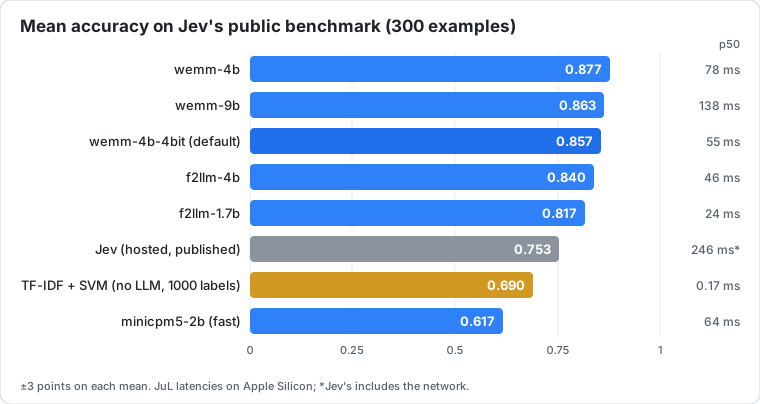
Jev's published benchmark, 300 examples, zero-shot for every JuL model, run with
scripts/bench_jul.py. Each mean is ±3 points. Banking77 and Emotion are in MTEB, which the
wemm-* and f2llm-* models trained on, so AG News is the clean comparison: 0.95 for wemm-4b,
0.91 for Jev, and 0.90 for the default model. The default model's ECE is 0.084 against Jev's 0.156, which is what lets you automate
above a confidence threshold. Every setting was fitted on English, and we haven't tested domains far
from this kind of text (sensor logs, chemistry and so on). Per-task scores, the 18 models measured and
the tuned results are in
docs/benchmarks.md.
Decision bench against Jev
The default model, jul-decision-wemm-4b, is WeMM-Embedding-4B with LoRA adapters that read the question and
the text together (usejul/jul-decision-wemm-4b). The
decision bench asks it 2,108 typed questions over 12 task families, in English and French, with texts
written for the bench and never seen in training. PyTorch bf16 on one A10G GPU, one question per call;
Jev through its API, network included in its latency.
| Family | n | Jev | jul-decision-wemm-4b |
|---|---|---|---|
| emotion | 60 | 0.933 | 0.817 |
| finance | 180 | 0.756 | 0.850 |
| hard negatives | 226 | 0.823 | 0.836 |
| intent | 234 | 0.842 | 0.868 |
| legal | 158 | 0.911 | 0.873 |
| moderation | 179 | 0.877 | 0.804 |
| inference (NLI) | 208 | 0.817 | 0.731 |
| relational | 101 | 0.941 | 0.921 |
| routing | 118 | 0.898 | 0.831 |
| sentiment | 120 | 0.983 | 0.925 |
| support | 294 | 0.898 | 0.864 |
| topic | 230 | 0.917 | 0.891 |
| Choice | 917 | 0.924 | 0.883 |
| Noul (yes/no) | 895 | 0.878 | 0.872 |
| Score | 296 | 0.699 | 0.672 |
| English | 1,254 | 0.871 | 0.862 |
| French | 854 | 0.876 | 0.829 |
| All | 2,108 | 0.873 | 0.849 |
| p50 latency | 655 ms | 97 ms |
A family has 60 to 300 questions, so one row moves by ±4 to ±12 points: read the types and the total first. The bench shares its task families and label sets with the training data (not its texts); on the four label sets of jul's dev, never trained on, the adapters take Choice from 0.707 to 0.730. Emotion is where Jev is furthest ahead, and inference is where the model is weakest. On a Mac (MLX, 4-bit) the adapters are not attached yet: the default model reads every question with the vectors, and the Jev benchmark numbers above are its numbers.
The baseline worth remembering
A TF-IDF + linear SVM, trained on 1000 labeled examples with no LLM at all, scores 0.88 on AG News,
0.76 on Banking77 and 0.43 on Emotion: a mean of 0.690 at 0.17 ms per prediction
(scripts/bench_tfidf.py). It is 11 points behind the default model on Banking77 and far behind on
Emotion, where telling feelings apart takes meaning, not vocabulary. If you have labels and your problem is
sorting by topic or intent, try it first. CI re-measures these numbers on every PR
(numbers.yml, CLAIMED),
so update both together.
Models
| Preset | Size | Jev bench, zero-shot | + autotune, 1000 labels | Notes |
|---|---|---|---|---|
jul-decision-wemm-4b (default, alias accurate) |
10.3 GB bf16 + 0.07 GB adapters (PyTorch); 2.6 GB (MLX) | 0.857 ² | 0.897 ² | built in; WeMM-Embedding-4B with LoRA adapters that read Noul and Choice with the question and the text together (Score on the vectors): 0.849 on the decision bench, Jev 0.873; attached on PyTorch, MLX reads it as wemm-4b-4bit for now |
wemm-4b-4bit |
2.6 GB | 0.857 | 0.897 | built in, vectors only |
minicpm5-2b |
2.7 GB | 0.617 | 0.757 | built in, 64 ms on an M4 Pro |
jul-decision-minicpm5-2b (alias fast) |
5.0 GB bf16 (PyTorch); 1.4 GB (MLX) | — | — | built in; MiniCPM5-2B trained to answer typed questions: a pointer head for Choice and Noul, Score on its own vectors; 0.680 on our hand-written bench (the default: 0.677) at 85 ms; no autotune (decision models) |
e5-small (ONNX, 8-bit) |
0.09 GB | 0.543 | 0.713 (0.790 hybrid head) | encoder, 6 ms per text on an M4 Pro; needs an ONNX export first, see models |
jul-decision-wemm-4b-4bit (MLX, 4-bit) |
2.6 GB (+0.07 GB adapters) | 0.857 ¹ | 0.897 ¹ | the default model with a LoRA cross model on the same weights for Noul and Score (yes/no 0.841 on Kev's typed decisions, against 0.762 with vectors; ~115 ms per yes/no on an M4 Pro); one model in memory, jul models add |
jul-decision-e5-small (ONNX, 8-bit) |
0.09 GB (+0.09 GB cross model) | 0.557 | 0.723 (0.780 hybrid head) | e5-small trained on jul decisions, with a cross model for Noul and Score (yes/no 0.726 on Kev's typed decisions, against 0.579 with vectors); runs in AWS Lambda, jul models add |
¹ Choice questions, the only ones in the Jev benchmark, are read by the vectors of wemm-4b-4bit, which the
adapters leave untouched (switched off, the features are the same): its numbers.
² Measured on MLX, where the default model reads with the vectors of wemm-4b-4bit. On PyTorch its Choice
reading mixes in the adapters; the Jev benchmark has not been rerun there yet.
To use another model, run jul models add <name> --repo <hf-repo>. It fits the layer, center and
temperature on the dev sets. The 18 models we measured, encoders, decision models and every setting
are listed in docs/models.md.
Decisions inside an AWS Lambda
jul-decision-e5-small runs inside an AWS Lambda function, model included in the package: 17 ms per
message and $0.59 per million at 1,769 MB, a 2.4 s cold start, no GPU and no server. Jev is a hosted
API and CLM-8B needs a GPU server; to our knowledge no other typed-decision library puts its model in a
Lambda. It is not a general-purpose endpoint: it is a small model embedded in a function that decides
one precise thing on every event, with the questions fixed at build time, and it should be tuned on
labeled examples of that thing (autotune: 0.557 zero-shot, 0.780 tuned on the Jev bench). jul pack
ships only the model(s) the questions need. Step by step, with the AWS CLI or CDK:
docs/aws-lambda.md.
Documentation
- Installation: backends, devices, batching,
jul setup - Models: presets, the 18 models measured,
jul models add - AWS Lambda: a tuned decision in a Lambda function, step by step (CLI or CDK)
- Adapting to your data:
Context,autotune(...), hybrid heads,jul synth - Deployment:
jul pack, ONNX bundles, AWS Lambda - Serving over HTTP:
jul serve - Command line: every command and file format
- Benchmarks: full results and how to reproduce them
- Development and Publishing
Contributing
Issues, measurements on your own data and pull requests are welcome on
GitHub. pip install -e ".[dev]", then pytest tests (no
model, about 30 s). Tune on the dev datasets and run the benchmark once at the end
(how).
License
Apache 2.0, see LICENSE and
NOTICE. The decision-model format comes from
Kev (Jared Palmer, Apache 2.0) and jul-decision-minicpm5-2b is
MiniCPM5-2B (OpenBMB, Apache 2.0) trained with Kev's
code. JuL follows TypeSafe's public System One API and uses no TypeSafe or Jev code, weights or
outputs.
1 maintainer

Metadata
1 maintainer
Release files for jul 0.5.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| jul-0.5.1.tar.gz | 615.3 kB | With provenance | Details for jul-0.5.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| jul-0.5.1-py3-none-any.whl | Python 3 | none | any | Details for jul-0.5.1-py3-none-any.whl |
Total release size: 816.7 kB
Release files / jul-0.5.1.tar.gz
| Download URL | jul-0.5.1.tar.gz |
|---|---|
| Size | 615.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
42df107eb94039d393502b6f07bda0927efc3d41f4543ad23e47cbc28dfe26d3
|
|
BLAKE2b-256 checksum How to use checksums |
8e097530842b6d0ad726ac1ca92ef614e7003ea0878df1903b5db7ab198eaad8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / jul-0.5.1-py3-none-any.whl
| Download URL | jul-0.5.1-py3-none-any.whl |
|---|---|
| Size | 201.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d0c2ac86e44e30f4ac3a33c7a70a1688e7ab5bfc0c61df41e6772d558809d5eb
|
|
BLAKE2b-256 checksum How to use checksums |
91dca4b1ccac4cd6ec5888adfa2f5a726d173fac346944f1744c4599b3be2572
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logSecurity for jul 0.5.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for jul-0.5.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














