
Jupyter Storage Explorer

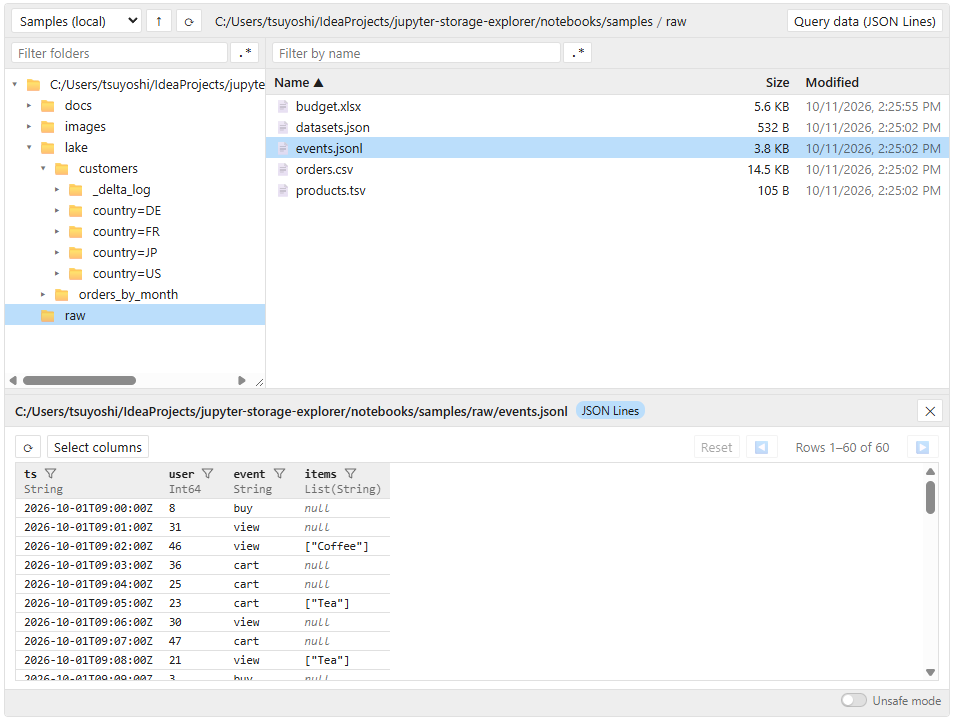
A file explorer for cloud storage and data lakes, right inside your Jupyter notebook, in the spirit of Azure Storage Explorer.
Browse Amazon S3, Azure Data Lake / Blob Storage, Google Cloud Storage, local disks and more; preview Parquet files, Delta Lake tables, CSV, Excel, JSON and other formats; page through, sort and filter tables; get ready-to-run code that loads the data into your notebook; and upload, download, move and edit files without leaving JupyterLab.
Two widgets:
StorageExplorer: the file explorer, with previews and the data browser.DataExplorer: the data browser alone, for a dataframe (pandas, polars, Spark, DuckDB, ...).
Installation
pip install jupyter-storage-explorer
Install the package for your storage too:
| Storage | Package | Address |
|---|---|---|
| Amazon S3 | s3fs |
s3://bucket/path |
| Azure Data Lake / Blob Storage | adlfs |
abfs://container@account.dfs.core.windows.net/path |
| Google Cloud Storage | gcsfs |
gs://bucket/path |
| Local disk, in-memory | (included) | /path, memory:// |
On Azure Data Lake Storage Gen2, pip install "jupyter-storage-explorer[abfs]" and
operations=[AzureDataLakeGen2Operation(), *StorageExplorer.default_operations()] (from
jupyter_storage_explorer.filesystems.abfs) move folders in one step and create empty folders.
Previewing and querying data files needs a data library, e.g. pip install polars deltalake. If one is missing, the
preview tells you what to install.
Quick start
from jupyter_storage_explorer import StorageExplorer

StorageExplorer("s3://my-bucket/data")
The explorer appears as the cell's output. Other examples:
StorageExplorer()  # the current folder
StorageExplorer("abfs://lake@myaccount.dfs.core.windows.net/raw")  # Azure Data Lake
StorageExplorer("s3://my-bucket/data", profile="analytics")  # Amazon S3, with options
StorageExplorer("gs://my-bucket", token="google_default")  # Google Cloud
Options after the address (like profile above) are passed to the storage package, for example to choose credentials.
To browse a dataframe, see DataExplorer. The notebooks folder has a demo of each
widget (storage_explorer.ipynb, data_explorer.ipynb) on sample data made by make_samples.py.
From the JupyterLab launcher
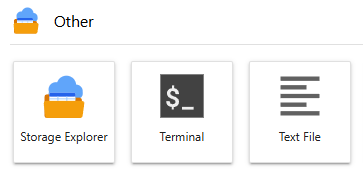
The separate package jupyter-storage-explorer-launcher adds Storage Explorer to
JupyterLab's launcher and command palette, opening the explorer in its own tab on the launcher's folder (the one the
file browser showed):
pip install jupyter-storage-explorer-launcher
What the tab shows is configured with launcher.py files, for the whole system and for each user; see the
launcher's README.
Several storages in one explorer
Give each storage a name; a drop-down on the left of the address bar switches between them, and each one remembers the folder you were in.
StorageExplorer(
    filesystems={
        "Data lake": "abfs://lake@myaccount.dfs.core.windows.net",
        "Raw files (S3)": "s3://my-bucket/raw",
        "Local": "/home/me/data",
    },
)
Using the explorer
- Browse: click folders in the tree or list; ↑ goes up, ⟳ refreshes. Ctrl+click (⌘+click) selects several items. The list shows 100 items per page (◀ ▶ above it).
- Filter: type in the fields above the tree and the list (and in Select columns of the data browser) to show only names containing the text, or matching a regular expression with .*. Case is ignored; ✕ or Esc clears.
- Preview: double-click a file, or Preview (with nothing selected: the current folder, e.g. a Delta Lake table). Tables open in the data browser.
- Right-click: Preview as, Edit, Python code to load the data, Copy, Cut, Paste, Delete, Create a folder, Download to local or to JupyterLab, Copy URL, Add bookmark.
- Bookmarks: ☆ (★ when the folder shown is bookmarked) lists them; click one to open it, right-click it for Copy URL and Delete bookmark. Explorers in the kernel share them (see Remembered states).
- Copy, cut and paste work between storages and between explorers, also in other notebooks: Cut, then Move here, moves files to another storage.
- Drag and drop: drop files from JupyterLab's file browser or your computer to upload them; drag files onto a folder to move them, or onto JupyterLab's file browser to download them (needs the launcher).
- In the background: moving, deleting, pasting and downloading to JupyterLab run while you keep browsing, with their progress above the status bar and Cancel. The list follows as they go.
Unsafe operations
Folder operations need Unsafe mode, turned on with the slider in the status bar:
| Operation | How |
|---|---|
| Move folders | Drag a folder onto another folder, or right-click → Cut, then Move here on a folder. |
| Copy and paste folders | Right-click → Copy, then Paste on a folder. |
| Delete folders | Right-click → Delete (with everything in it). |
Transfer policy
transfer_policy=[...] limits the directions files may be transferred in: copied or moved from one storage to another
(copy or cut, then paste), to or from JupyterLab's file browser, and uploaded from or downloaded to your computer.
Moving and copying within a storage (e.g. dragging files onto a folder) is not a transfer. It is a list of rules,
tried in order; the first whose src and dest regular expressions both match the whole URLs decides, and without
one, files go:
StorageExplorer(filesystems={...}, transfer_policy=[
    {"rule": "allow", "src": r"abfs://lake@acct\.dfs\.core\.windows\.net/public/.*", "dest": ".*"},
    {"rule": "deny", "src": r"abfs://lake@.*", "dest": ".*"},  # nothing else leaves the lake
])
URLs are those of "Copy URL" (local files: their path; the destination: the item's new location). Files on the
Jupyter server through JupyterLab's file browser ("Download to JupyterLab", drag and drop with it) are
jupyterlab://<absolute path>, e.g. jupyterlab:///home/jovyan/x.csv, and files on your computer
browser:///<name>. A pattern left out matches any URL. Items refused are reported, the others done.
This keeps files from going the wrong way by mistake; it is not a security boundary.
Query data
With polars installed (plus deltalake for Delta Lake, fastexcel for Excel), tables open in a data
browser that reads 1,000 rows at a time:
- ◀ ▶ to page, click a column name to sort, its funnel to filter (Null / empty, Range, Contains, Regex).
- Select columns to hide columns, drag a header's edge to resize, Reset to clear filters, ⟳ to reload.
- Live / In memory (top right): query the data itself, or read its first 100,000 rows into memory once and query those (faster, but filters and sorting then apply to those rows only). Data of up to 1,000 rows is always kept in memory.
Filters, sorting, hidden columns, widths and the mode chosen are remembered for the 20 tables queried last (see Remembered states). polars reads the data with the credentials in the environment, not the explorer's options.
Remembered states
Bookmarks and the data browser's settings are kept in an ExplorerStates, shared by the explorers in the kernel, until
it restarts. To keep them in a JSON file, also shared with other kernels (read again when an explorer is created and
before each change), give its path, or an ExplorerStates for other options:
from jupyter_storage_explorer import ExplorerStates, StorageExplorer

StorageExplorer("s3://my-bucket/data", states="~/.jupyter/storage-explorer/states.json")
StorageExplorer("s3://my-bucket/data", states=ExplorerStates("states.json", max_queries=50))
Explorers in the launcher's tabs
use ~/.jupyter/storage-explorer/states.json, so the first example shares their bookmarks.
A bookmark names a storage of the explorer (its name in filesystems, or "default") and a folder; explorers list
those of their own storages.
Supported formats
| Format | Name | Preview | Query data | Load with |
|---|---|---|---|---|
| Delta Lake tables | delta |
First rows | ✓ | polars (with deltalake), PySpark (with delta-spark) |
| Parquet files, and folders of them (e.g. Spark, Hive output) | parquet |
First rows | ✓ | polars, pandas, PySpark |
| CSV, TSV | csv |
First rows | ✓ | polars, pandas, PySpark |
| JSON Lines | json-lines |
First records | ✓ | polars, pandas, PySpark |
| JSON | json |
Collapsible tree | Python, polars, pandas | |
Excel (.xlsx) |
excel |
First rows of the first sheet | ✓ | polars, pandas |
| Markdown | markdown |
Rendered | Python | |
| Text, code, configuration (YAML, SQL, Python, …) | text |
With syntax highlighting | Python | |
| Images (PNG, JPEG, GIF, SVG, …) | image |
Shown | Pillow |
The name identifies the format in CSS (see Customizing icons).
Format options
format_options is one dictionary for all formats; each format uses the options it takes. Options are named after the
library they are for, and the ones for a single format also after the format:
StorageExplorer(
    "s3://my-bucket/lake",
    format_options={
        "polars_storage_options": {"aws_region": "eu-west-1"},
        "pandas_storage_options": {"anon": False},
        "polars_delta_use_pyarrow": True,
    },
)
| Option | Formats | Meaning |
|---|---|---|
polars_storage_options |
delta, parquet, csv, json-lines |
polars' storage_options (object_store's names, not fsspec's), in the preview, the data browser and the polars code. |
polars_credential_provider |
delta, parquet, csv, json-lines |
polars' credential_provider, in the preview and the data browser (not in the code). |
pandas_storage_options |
parquet, csv, json-lines, json, excel |
pandas' storage_options (fsspec's), in the pandas code. |
fsspec_storage_options |
json, excel, markdown, text, image |
fsspec.open's keyword arguments, in the code that reads with fsspec. |
polars_delta_table_options |
delta |
scan_delta's delta_table_options. |
polars_delta_use_pyarrow |
delta |
scan_delta's use_pyarrow. |
polars_delta_pyarrow_options |
delta |
scan_delta's pyarrow_options. |
Storage options that look like credentials are left out of the code. Without storage options, the code relies on the environment's configuration and credentials.
Working with the explorer from Python
explorer = StorageExplorer("s3://my-bucket/data")
explorer
explorer.folder_url  # the URL of the folder shown, e.g. to pass to polars or pandas
explorer.selected_urls  # the URLs of the selected items
StorageExplorer options
| Option | Meaning |
|---|---|
height="400px" |
Height of the tree and list; the preview panel adds its own space below. "fill": as tall as the container, e.g. the launcher's tab. |
max_upload_bytes=10 * 1024 * 1024 |
Largest file you can upload from your computer (default 10 MB; None for no limit). |
download_to_jupyterlab_path="." |
Folder "Download to JupyterLab" copies into, e.g. "~/Downloads"; default: where it runs. To refuse downloads, use transfer_policy. |
filesystems={...} |
Several named storages, as shown above. |
max_browser_items=20_000 |
Folders with more items are filtered, sorted and paged by the kernel, one page at a time, instead of the browser (None: never). |
operations=[...] |
How files are moved, copied, deleted and downloaded, replacing StorageExplorer.default_operations(): e.g. [MyOps(), *StorageExplorer.default_operations()] for server-side copies of your own (see operations.py, and filesystems for the defaults). |
transfer_policy=[...] |
Rules for transfers of files between storages; see Transfer policy. |
states="states.json" |
Where bookmarks and the data browser's settings are kept (a path or an ExplorerStates); see Remembered states. |
format_options={...} |
Options for the formats (see Format options). |
DataExplorer: browse a dataframe
DataExplorer opens the same data browser for a dataframe in your notebook: pandas, polars, PyArrow, DuckDB, Spark,
and the other libraries narwhals supports.
import polars as pl
from jupyter_storage_explorer import DataExplorer, QuerySettings

DataExplorer(pl.scan_parquet("s3://my-bucket/lake/sales/*.parquet"))
DataExplorer(spark.table("sales"), mode="memory")  # read the first rows into memory
DataExplorer(orders_df, settings=QuerySettings(sort="date", descending=True))
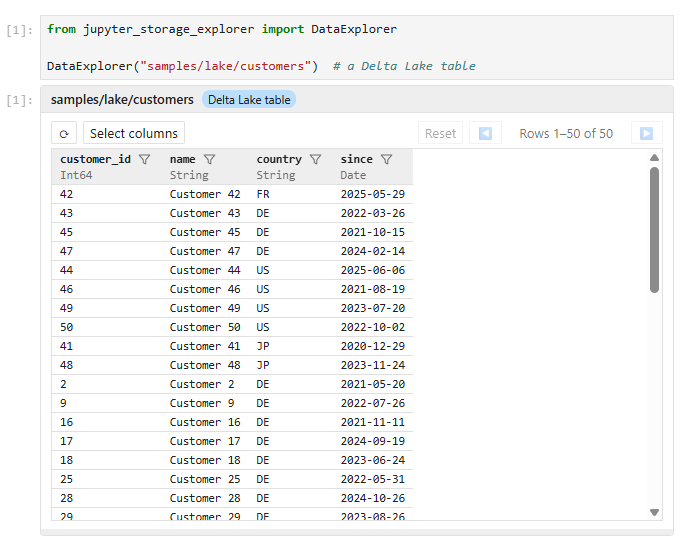
Lazy data starts Live, eager data In memory. Pass a function (lambda: pl.scan_parquet(url)) for ⟳ to
read the data again.
explorer.result() gives the data with the widget's filters, sort order and hidden columns applied, as a dataframe of
the same library (lazy data stays lazy), to continue your analysis in code:
explorer = DataExplorer(pl.scan_parquet("sales/*.parquet"))
# ... filter and sort in the widget ...
explorer.result().group_by("region").agg(pl.col("amount").sum()).collect()
QuerySettings sets the filters, sort order, hidden columns and widths to start with. To keep settings made in the
widget, print them as text and paste them into your code:
explorer = DataExplorer(orders_df)
print(explorer.settings.to_json())  # after filtering and sorting in the widget

DataExplorer(orders_df, settings=QuerySettings.from_json("""
{
    "filters": {"price": {"op": "range", "min": "10", "max": ""}},
    "sort": {"column": "date", "descending": true},
    "hidden": ["comment"],
    "widths": {}
}
"""))
DataExplorer options
| Option | Meaning |
|---|---|
settings=QuerySettings() |
Filters, sort order, hidden columns and widths to start with (see above). |
mode="auto" |
Where queries run first: "auto", "live" (lazy data only) or "memory"; switch in the widget. |
max_live_rows=1000 |
Data up to this size is kept in memory; also the most rows a live query gives if the library cannot skip rows (e.g. Spark). |
max_memory_rows=100_000 |
The most rows read into memory. |
title=... |
Shown above the table (default: the dataframe's type). |
height="400px" |
Height of the table area. "fill": as tall as the container, e.g. a tab (not a notebook cell). |
Requirements
- Python 3.11 or later
- JupyterLab 4. The widgets also show in other Jupyter frontends, but dragging files from JupyterLab's file browser works only in JupyterLab.
- For Query data: a recent polars (tested with polars 2.0).
DataExplorerworks with any dataframe narwhals supports; with polars installed, data in memory is queried with polars, which is faster.
Development
Building from source, the JupyterLab extension, releasing, and customizing the explorer's icons with CSS: see DEVELOPMENT.md.
1 maintainer

Metadata
1 maintainer
Release files for jupyter-storage-explorer 0.7.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| jupyter_storage_explorer-0.7.0.tar.gz | 390.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| jupyter_storage_explorer-0.7.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 583.0 kB
Release files / jupyter_storage_explorer-0.7.0.tar.gz
| Download URL | jupyter_storage_explorer-0.7.0.tar.gz |
|---|---|
| Size | 390.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
606f21f8fd147405cd3d7a30ffc186cb81bef945146af2c8ae790ecb0e0eb6cb
|
|
BLAKE2b-256 checksum How to use checksums |
608fd9d3d6b7548a15b97619b94058b72bdade3ef5a7ab8c9ffb07dba0ec2f1a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency logRelease files / jupyter_storage_explorer-0.7.0-py3-none-any.whl
| Download URL | jupyter_storage_explorer-0.7.0-py3-none-any.whl |
|---|---|
| Size | 192.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
63aceb0dbe99c188e6d83453312b50ec6175a6a395412266dd8b82f81b3663c8
|
|
BLAKE2b-256 checksum How to use checksums |
aadf50f8a839a036d5afefb56e93328ff01b3e4385f56adb63f75a2399c331dc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency log













