
JW SOUP
jwsoup is a simple Python package that scrapes Bible data from the JW.org website. The package provides functionality for scraping Bible verses and saving them in a structured format. It supports scraping data from one or multiple pages, handling paginated content, and storing the results in a Parquet file.
Features
- Scrape Bible verses from individual or multiple pages.
- Clean the scraped verse text to remove unwanted characters.
- Store the scraped data in a Parquet file for further analysis.
- Simple interface with reusable functions.
Installation
To install jwsoup, you can use pip from PyPI:
pip install jwsoup
Alternatively, if you want to install it locally from the source, clone the repository and run the following commands:
git clone https://github.com/sawadogosalif/jwsoup.git
cd jwsoup
pip install .
Usage
Scrape text - Single Page
You can scrape a single page of Bible verses using the scrape_single_page function. This function returns a list of verses and the URL for the next page (if available).
jwsoup.text import scrape_single_page
url = "https://www.jw.org/fr/biblioth%C3%A8que/bible/bible-d-etude/livres/Gen%C3%A8se/1/"
verses, next_url = scrape_single_page(url)

# Print the scraped verses
for verse in verses:
    print(f"{verse[0]}: {verse[1]}")

# Print the next URL
print(f"Next page URL: {next_url}")
Scrape text - Multiple Pages
To scrape multiple pages starting from a given URL, use the scrape_multi_page function. This function will follow pagination and save the scraped data in a Parquet file.
from jwsoup.text import scrape_multi_page

start_url = "https://www.jw.org/mos/d-s%E1%BA%BDn-yiisi/biible/nwt/books/S%C9%A9ngre/1/"
output_dir = "bible_data_moore.parquet"
res = scrape_multi_page(start_url, output_dir=output_dir, max_pages=5, page_sep="books")
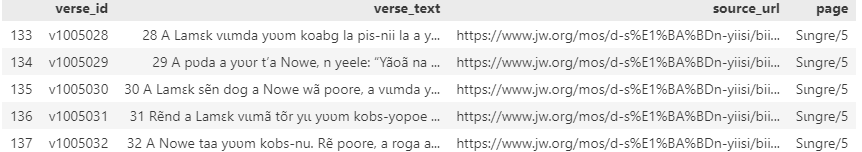
Save Data to Parquet
The scraped data is stored in a Parquet file for efficient storage and querying. You can specify the output file and partition the data by page.
import pandas as pd
pd.read_parque(output_dir).head()
Downloads audios
start_url = "https://www.jw.org/mos/d-s%E1%BA%BDn-yiisi/biible/nwt/books/yikri"
output_dir = "audio_files"
download_audios(start_url, output_dir,max_pages=3)
License
This project is licensed under the MIT License - see the LICENSE file for details.
Author
- Salif Sawadogopro
Email: salif.sawadogopro@gmail.com
Acknowledgments
- Thanks to the
requests,beautifulsoup4,pandas,loguru, andpyarrowlibraries for making scraping and data handling easier. - Thanks to JW for providing an accessible and rich resource of Bible texts in multiple langages
Changelog
[0.0.1] - 2024-11-23
Added
- Initial release of
jw_soup. - Supports scraping of text-based Bible verses from JW.org.
- Extracts individual verses and saves them to parquet files using
pyarrow. - Includes basic error handling and logging with
loguru.
Known Limitations
- Only supports scraping textual data.
- Does not handle multimedia content (audio/video).
- Limited testing for edge cases (e.g., malformed HTML or network interruptions).
[0.0.2] - 2024-11-23
Added
- Typo correction in package descritption
[0.0.5] - 2024-11-24
Added
-
Add project url in setup
-
Fix image rendering in pypi
-
Improve next button parsing
[0.1.0] - 2025-01-10
Added
- Introduce audio dowloaders
- Improve next button parsing
[0.1.1] - 2025-01-11
Added
- Good naming of folder with urllib.parse.quote
1 maintainer

Metadata
1 maintainer
Release files for jwsoup 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| jwsoup-0.1.1.tar.gz | 9.9 kB | Without provenance | Details for jwsoup-0.1.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| jwsoup-0.1.1-py3-none-any.whl | Python 3 | none | any | Details for jwsoup-0.1.1-py3-none-any.whl |
Total release size: 18.3 kB
Release files / jwsoup-0.1.1.tar.gz
| Download URL | jwsoup-0.1.1.tar.gz |
|---|---|
| Size | 9.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fa60d05160279cad8740cfb8c3040373d5970b0451bbc058d697f83cb9d76fc7
|
|
BLAKE2b-256 checksum How to use checksums |
a765b3bda6e5b96b29538a59e89da00147d8b765e1695e3c7c9bedcba7986f6b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.0.1 CPython/3.12.8
|
Release files / jwsoup-0.1.1-py3-none-any.whl
| Download URL | jwsoup-0.1.1-py3-none-any.whl |
|---|---|
| Size | 8.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
64b7f97839a12512d8e2853de40ca89a1854c2d1f1cd237231c2161deb497911
|
|
BLAKE2b-256 checksum How to use checksums |
888d621df90decfb0e3052cd0da7df9ee8ab44085327796b05d435a28917251f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.0.1 CPython/3.12.8
|
Security for jwsoup 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














