
kenze


Big-file data prep that never runs out of memory — an interactive shell and a one-line CLI.
kenze cleans and reshapes data files (CSV, Parquet, JSON) that are too big for
pandas. It's a friendly front-end over DuckDB: DuckDB does
the heavy lifting (streaming, disk-spill, all your CPU cores), kenze makes it
effortless — and auto-configures memory so your job doesn't crash.
No more MemoryError on a file larger than RAM, and no SQL to learn: kenze
processes everything out-of-core, streaming through DuckDB, so you can read,
clean, and reshape a CSV or Parquet file that's bigger than memory on a laptop.
pip install kenze
One name for everything: pip install kenze → the kenze command → import kenze.
The interactive shell
Just run kenze. You land in a live session: load a file once, stack simple
steps (each previews as you go), then run the pipeline to a file or save it
as a reusable recipe. Type / for a live command menu; TAB autocompletes
your file's real column names — and, inside a quoted condition, its real
values:
kenze > f                       <- ghost text finishes it: f`ilter`
kenze > filter ci               <- ...and your column names: filter ci`ty`
kenze > filter city = 'L        <- ...and your actual data: 'L`ondon`
                                   right-arrow takes it

kenze > filter city = '<TAB>    <- or TAB for the whole list
                       +------------------------+
                       | London        600 rows |     <- read from your file,
                       | Paris         300 rows |        counts are exact
                       | Tokyo         100 rows |
                       +------------------------+
kenze > load sales.parquet          # 60M rows, opens instantly
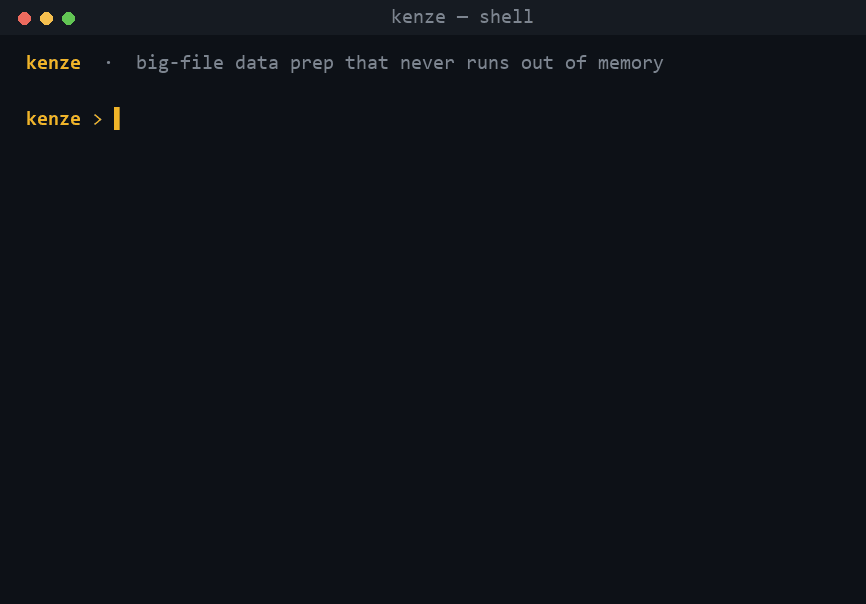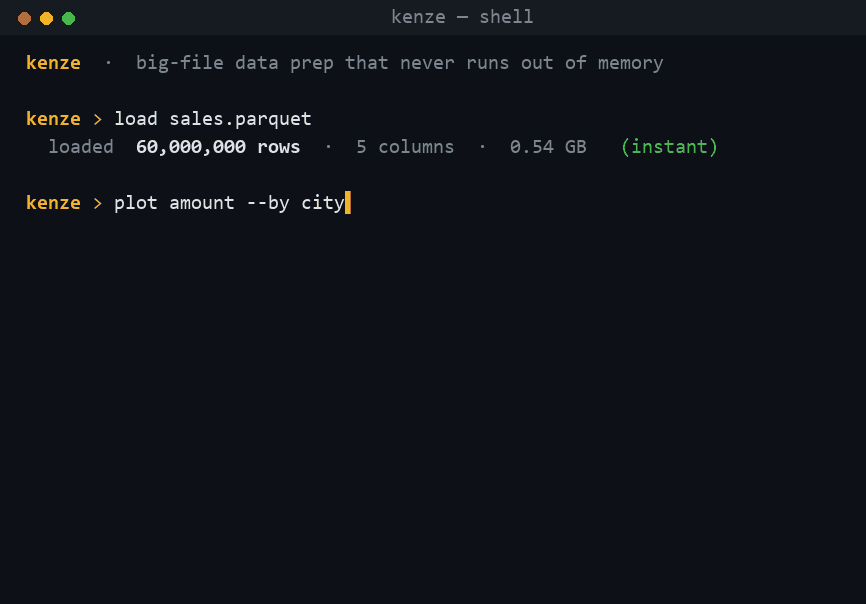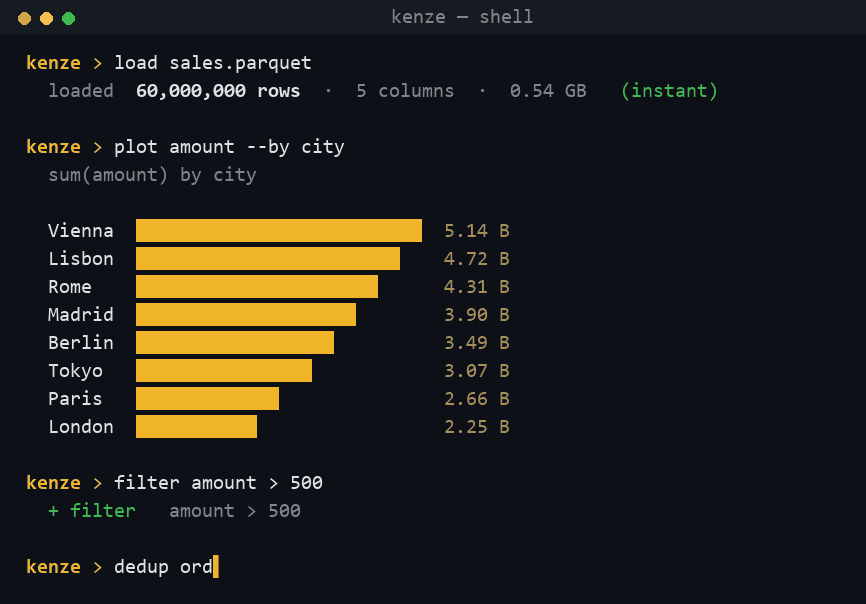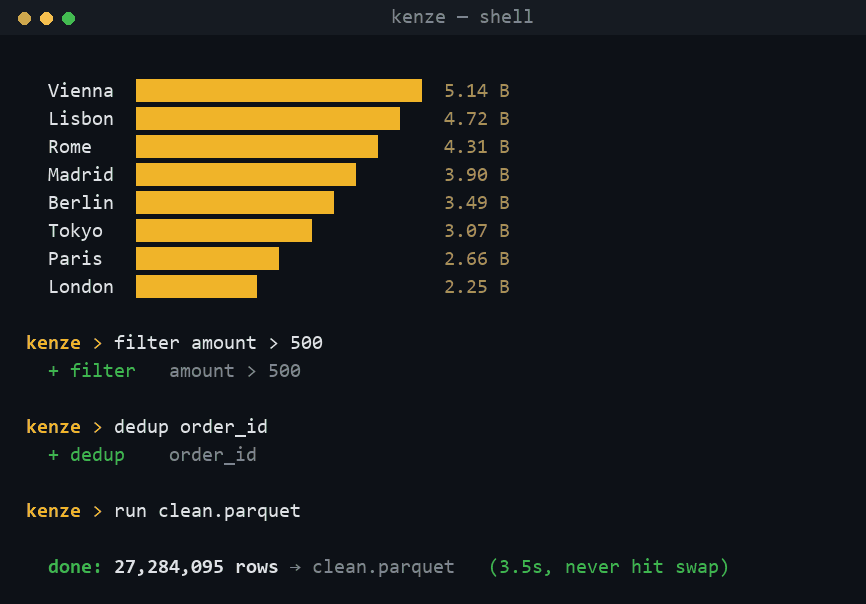
kenze > filter amount > 0           # each step previews live
kenze > plot amount --by city       # ascii bar chart of the live data
kenze > keep id, city, amount
kenze > dedup id
kenze > assert-unique id            # a data-quality guard, checked before writing
kenze > run clean.csv               # streamed through DuckDB, no OOM
It never loads more than it needs, so counts and previews on a 60-million-row file come back in well under a second, and full writes stream through DuckDB with a progress bar. Everything the CLI can do is in the shell — see SHELL.md.
Feature highlights
- An interactive shell (
kenze) with a/command menu, live previews, schema-aware autocomplete, and data-quality guards — plus the same as a one-line CLI for scripts and cron. - Autocomplete that knows your data, not just your columns — ghost text finishes what you type from the first keystroke: commands, column names, file paths, and the real values in your file. TAB shows every value with its exact row count. It follows the pipeline you have built so far, and refuses to list a column with millions of distinct values, telling you what it measured instead.
- Process files bigger than your RAM without crashing — memory is auto-capped and DuckDB spills to disk.
- 40 CLI commands for the everyday work:
keep,drop,filter,rename,cast,fillna,dedup,sample,count,sort,join,diff,pivot,split,partition, and more — no SQL needed. - Count & sort with zero SQL —
kenze count sales.csv city --top 10is a value-counts / group-by (--distinct userfor unique users per group);kenze sort sales.csv --by revenue --desc --top 10orders and keeps the top N. Both chain in the shell pipeline. - Model-ready in one step —
scale,bin,encode,onehot,clip-outliers, and a reproducibletraintestsplit turn a clean file into a model-ready dataset you hand straight to scikit-learn / XGBoost. - See your data —
plot amount --by citydraws an ASCII bar chart or histogram right in the terminal, so you spot skew and dirty data instantly. - Excel in and out — read and write
.xlsxworkbooks natively (convert big.parquet -o report.xlsx), no extra dependency. - GeoJSON in and out —
convert data.csv -o map.geojsonbuilds point geometry from lat/lon columns (auto-detected, or--lat/--lon/--geom);convert map.geojson -o map.csvflattens geometry back to WKT. Handy for prepping map layers. - Client-ready reports —
kenze report data.csv -o out.pdfturns a data file into a styled PDF/HTML report (KPI tiles + a ranked table, auto-fit to your columns);--per-rowmakes one document per row (batch / mail-merge), and--template/--scaffoldlet you bring your own HTML. Needspip install "kenze[report]"; PDF renders with your system browser — no heavy install. - Messy CSVs, handled —
--skip Ndrops junk preamble rows; the shell even auto-detects and skips them for you. - Readable recipes (
.dqfiles) that chain steps into one streaming pass, with${VAR}templating for scheduled jobs. - Read and write the cloud directly —
s3://,gs://,https://— nothing to download first. - A run ledger —
historyshows your recent runs (input → output, rows, time). - Data-quality guards (
assert,assert_unique,assert_not_null), PII masking (mask), schema validation (validate) — a failed check aborts before anything is written.kenze validate data.csv --scaffold schema.jsonwrites the contract for you from a file you already trust, so the gate takes a minute to set up rather than an afternoon of hand-written JSON. - No lock-in —
ejectany recipe to raw DuckDB SQL or Python. - Use it from Python too —
import kenzeand callkenze.sift(...),kenze.sql(...). - Atomic writes and clean, cross-platform output on any terminal.
Why
- It doesn't OOM. Memory is capped to a fraction of free RAM and DuckDB spills to disk instead of dying. Point it at a file bigger than your RAM; it's fine.
- No SQL, no pandas. Simple verbs, or a readable recipe file.
- One streaming pass. A whole recipe compiles to a single query — no intermediate files, so it's fast and light.
- Any format, local or cloud. CSV / Parquet / JSON, plain or
.gz, on disk or ons3:///gs:///https://— auto-detected.
One-liners
kenze profile  sales.parquet                          # schema + row count, instantly
kenze peek     sales.parquet                           # first rows + types + null counts
kenze stats    sales.parquet                           # per-column min/max/nulls/unique
kenze plot     sales.parquet amount --by city          # ascii bar chart in the terminal
kenze plot     sales.parquet amount                    # ascii histogram of a numeric column
kenze check    sales.csv                               # is the file valid? any bad rows?

kenze keep     sales.parquet --cols id,city,amount -o small.csv
kenze drop     users.csv     --cols email,phone    -o clean.parquet
kenze filter   sales.parquet --where "amount > 100" -o big.csv
kenze rename   sales.csv     --map "amount:total"   -o out.csv
kenze cast     users.csv     --types "zip:VARCHAR"  -o out.parquet   # keep leading zeros
kenze fillna   users.csv     --with "city:Unknown"  -o out.csv
kenze mask     users.csv     --cols email,ssn --method hash -o safe.csv
kenze dedup    users.csv     --on id               -o unique.parquet
kenze sample   sales.parquet --n 50000             -o sample.csv
kenze clip     points.parquet --bbox -10,35,5,45    -o region.parquet

kenze join     orders.csv users.parquet --on user_id -o joined.parquet
kenze diff     old.csv new.csv --on id                # added / removed / changed
kenze pivot    sales.csv --on city --values amount --agg sum --group region -o wide.csv
kenze unpivot  wide.csv  --cols jan,feb,mar --name month --value sales -o long.csv
kenze filter   "sales_*.csv" --where "amount>0" -o all.csv   # globs unify schemas
kenze split    sales.parquet --by city -o by_city/    # one file per value
kenze partition sales.parquet --by year -o lake/      # hive year=2026/ folders
kenze convert  sales.parquet -o report.xlsx          # write a real Excel workbook
kenze keep     messy.csv --cols id,amount --skip 3 -o clean.csv  # drop junk preamble

kenze count    sales.parquet city --top 10 -o city_counts.csv        # value-counts, no SQL
kenze count    sales.parquet city --distinct user_id                 # unique users per city
kenze sort     sales.csv --by revenue --desc --top 10 -o top.csv     # order + keep top N

kenze report   summary.csv -o report.pdf --set title="Q1 Review"     # styled PDF report
kenze report   invoices.csv --per-row --format pdf -o docs/          # one PDF per row (batch)

kenze sql  "SELECT *, lag(amount) OVER (ORDER BY ts) FROM 'sales.parquet'" -o out.csv
kenze history                                         # your recent runs
Read or write the cloud directly (nothing to download first):
kenze filter s3://bucket/huge.parquet --where "amount > 0" -o local.csv
Pipe like any Unix tool (use - for stdin/stdout):
cat data.csv | kenze filter - --where "x > 1" -o - | gzip > out.csv.gz
Recipes
Chain steps in a readable .dq file — they run as one streaming pass:
# clean.dq
input:  data/sales_${DAY}.parquet     # ${DAY} filled from --set or the environment
keep:   [id, city, amount]
types:  zip:VARCHAR
filter: amount > 0
fillna: city:Unknown
dedup:  id
sample: 50000
output: out/clean.csv
kenze run clean.dq --set DAY=2026-07-14
kenze recipe                 # show every valid recipe step
kenze eject clean.dq --to sql    # print the raw DuckDB SQL (no lock-in)
Bake data-quality tests right into a recipe — they run before anything is written, so a failed check aborts with no output:
assert:          row_count > 0
assert_unique:   id
assert_not_null: id, email
From Python
import kenze
kenze.sift("big.parquet", "clean.csv", keep=["id", "city"], filter="amount > 0", sample=50000)
rows = kenze.sql("SELECT city, count(*) FROM 'big.parquet' GROUP BY 1")
kenze.profile("big.parquet")
Handy flags
--dry-run— show the compiled query + output schema without running it.--errors bad.csv— quarantine malformed CSV rows to a file (with line/column diagnostics) and keep going.--append— add to an existing csv/json output instead of overwriting.--source-format delta|iceberg— read a Delta Lake or Apache Iceberg table.--memory-limit 8— pin the RAM budget (GB) for reproducible / SLA runs (great for shared CI/Airflow nodes).--temp-dir D:/spill— put disk-spill where there's room.--threads N— cap how many CPU threads DuckDB uses.--skip-bad-lines— ignore malformed rows in a dirty CSV (the row is dropped, not repaired).--no-strict-csv— open a CSV that breaks the standard: mixed line endings, a stray quote. Spark output does this a lot, and--skip-bad-linescan't help — the parser fails before there's a row to skip.--skip N— skip N preamble rows before the CSV header (comment banners, blank lines).--log run.json— write a run manifest (inputs, rows, timing).--no-history— don't record this run in~/.kenze/history.jsonl.- Writes are atomic — a cancelled run never leaves a half-written file.
Hand off to a dataframe
Clean a huge file, then pass the result straight to Polars / Arrow / pandas — no disk round-trip:
import kenze
df = kenze.to_polars("SELECT * FROM 'big.parquet' WHERE amount > 0")   # pip install kenze[polars]
tbl = kenze.to_arrow("SELECT city, count(*) FROM 'big.parquet' GROUP BY 1")   # kenze[arrow]
Commands
profile · peek · stats · plot · check · validate · keep · drop · rename · cast ·
fillna · mask · scale · bin · encode · onehot · clip-outliers · filter · dedup ·
sample · head · clip · convert · join · diff · pivot · unpivot · split ·
partition · traintest · count · sort · report · sql · eject · init · run · recipe · history
Run any of these as a one-liner, or run kenze and do it all interactively — the
shell wraps every command above plus session helpers (open, set, dryrun,
pwd/cd, undo, steps). See SHELL.md for the shell guide.
Documentation
Full docs live in docs/:
| doc | for |
|---|---|
| Python API reference | using kenze as a library (import kenze) — every public function, exact signatures, arguments, returns, examples. |
| CLI reference | every command and flag, the memory model, cloud storage, recipes. |
| Interactive shell | the live kenze session guide. |
| Reports | kenze report — data file → styled PDF / HTML. |
Performance
The whole point of kenze is that it doesn't fall over on files bigger than your RAM. The repo ships a reproducible benchmark that proves it: it generates a large synthetic CSV and runs the same job (filter → group-by → aggregate) with pandas, polars and kenze, each given the same memory budget.
- pandas (eager) tries to load the whole file, blows past the budget, and dies with an out-of-memory error.
- kenze streams the job within the budget — spilling to disk when it has to — and finishes.
Run it yourself:
pip install pandas polars psutil
python bench/benchmark.py --rows 60000000 --mem-gb 3
It prints a markdown table (outcome / wall time / peak memory) and writes
bench/RESULTS.md. The same benchmark runs in CI
(Benchmark workflow),
where the results are uploaded as a build artifact and posted to the run summary.
Where it stops (on purpose)
kenze is one dependency and one machine — that's the whole point. It maxes out your cores and spills to disk so a single laptop or VM can chew through files far bigger than its RAM. It does not run a cluster. If you've genuinely outgrown one machine (multi-terabyte, distributed pipelines with SLAs and lineage tracking), reach for Spark/Dask — kenze is the tool you use before you need those.
Troubleshooting
'kenze' is not recognized / kenze: command not found?
pip installed kenze correctly — the command just landed in a folder that isn't on
your PATH (this affects every pip-installed CLI). Options:
- Use it now, no setup:
python -m kenze --help - Fix it for good: reinstall Python from python.org
with "Add python.exe to PATH" ticked, or use
python -m pipx install kenze.
Feedback, bugs & feature requests
Found a bug, want a new command, or hit something confusing? Open an issue:
github.com/Kenzy-Zero/kenze/issues.
(The shell prints this link too — help.) Pull requests welcome — see
CONTRIBUTING.md.
A GitHub star helps others find kenze.
Every command is covered by a test suite (tests/) that runs on Linux and Windows
across Python 3.9–3.13 (see the CI badge) — including the data-quality guards and
the ML-prep transforms. Run it locally with pip install -e ".[dev]" && pytest.
MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for kenze 0.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| kenze-0.10.0.tar.gz | 103.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| kenze-0.10.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 182.8 kB
Release files / kenze-0.10.0.tar.gz
| Download URL | kenze-0.10.0.tar.gz |
|---|---|
| Size | 103.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a47012e465541b7910fe867434e8e31e6b382acd034ddce321e56e7f761822d9
|
|
BLAKE2b-256 checksum How to use checksums |
5b7dce6aa06915963cfdd81adb878b9591144cfafa343ce6925f5fbefca01fd1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 5, 2026.
Transparency logRelease files / kenze-0.10.0-py3-none-any.whl
| Download URL | kenze-0.10.0-py3-none-any.whl |
|---|---|
| Size | 79.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
beb451d901b927b6cba73ab4cf526746edeef35c6eca4a1f70bf831a804fffbe
|
|
BLAKE2b-256 checksum How to use checksums |
0f2c024801843112c00565b5102b02705c17b27dd36d466e5e0ff5560f3b96bb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 5, 2026.
Transparency log













